TL;DR
In the star schema vs snowflake schema choice, star fits the BI layer; snowflake fits only shared, deep hierarchies. A star schema keeps each dimension in one flat table, so a dashboard query needs fewer joins. A snowflake schema normalizes dimensions into chains, cutting repeated values but adding a join per hierarchy level.
Microsoft recommends the star shape for Power BI and Fabric Warehouse, and Databricks agrees for BI queries. Fabric Warehouse, Databricks and Snowflake do not enforce foreign keys on standard tables, so normalizing cannot guarantee integrity. Many warehouses end up hybrid, so test both shapes on your own engine before you commit.
Key Takeaways
- Use a star schema by default when dashboards, analysts or semantic models query a layer directly.
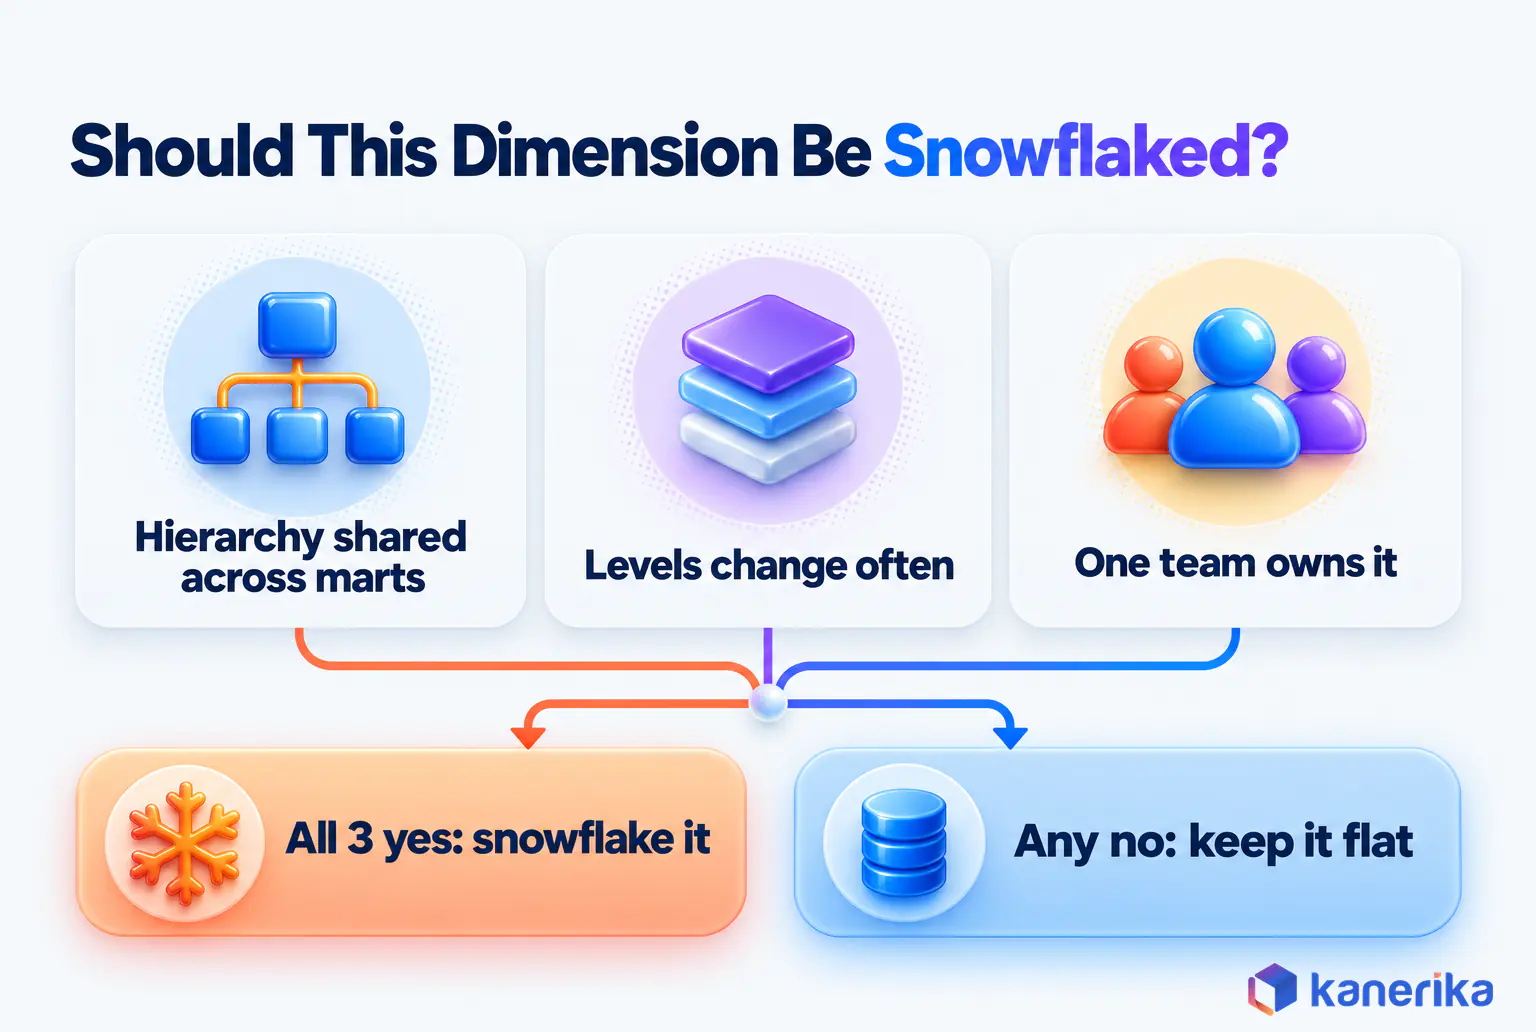
- Snowflake a dimension only when its hierarchy is deep, shared across marts and owned by one team.
- Microsoft’s Power BI guidance says extra model tables cost storage and performance, so flat dimensions usually win there.
- Fabric Warehouse, Databricks and Snowflake standard tables do not enforce primary or foreign keys, so integrity checks belong in your pipelines.
- Slowly changing dimensions are simpler on flat dimensions, where a Type 2 change adds one new row.
- Many enterprise warehouses also run a hybrid: a normalized core underneath and star-shaped marts on top.
One Sales Table, Two Teams Pulling in Different Directions
Picture a retailer with one sales dataset and two teams who depend on it. Finance wants a margin dashboard that opens in a couple of seconds on Monday morning. Merchandising maintains the product hierarchy, and that hierarchy changes market by market as categories are split, merged and renamed.
So finance asks for wide, flat tables that a report can scan with as few joins as possible. Merchandising wants each level of the hierarchy stored once, so one rename does not touch thousands of product rows.
Both requests are reasonable, and they pull the data model in opposite directions. That tension is the whole star schema vs snowflake schema debate in one meeting.
Why the Schema Choice Decides How Fast a Dashboard Answers
A warehouse model has two kinds of tables. Fact tables hold the events you measure, such as order lines, payments or shipments, with numeric values like quantity and net amount. Dimension tables hold the context you filter and group by, such as product, store, customer and date.
Every report question is a trip from a dimension to the facts. “Net revenue by category” starts at the category, filters the products in it and sums their sales rows. The number of tables on that path then depends on the schema you chose. So the design decides how many joins each visual waits for and how much work your pipelines do to keep the tables in step.
The choice therefore belongs to the people who build reports as much as to the data engineers. If you are still deciding where the warehouse itself sits, our guide to data lake vs data warehouse covers that earlier step. After that, the rest of this guide assumes a warehouse or lakehouse gold layer and asks how to shape the tables inside it.
Kanerika Service
Data Engineering Services
Kanerika designs and builds warehouse and lakehouse layers, from ingestion pipelines to dimensional models, with key tests and reconciliation built into every load.
Explore Data EngineeringWhat Is a Star Schema?
A star schema puts one fact table at the center and links it directly to a ring of dimension tables. When you draw it, you get a star. The fact table sits in the middle, with one line out to each dimension and no dimension pointing to another. Ralph Kimball’s The Data Warehouse Toolkit is the standard reference for the pattern. Microsoft cites it in its own star schema guidance for Power BI.
Each dimension row also gets a surrogate key, a plain integer the warehouse assigns. The fact table stores those keys plus the measures, which keeps fact rows narrow even when there are billions of them.
Fact Tables and Grain
Every fact table starts with one sentence that declares its grain, such as “one row per order line per day”. The grain tells everyone what a single row means, which measures can be summed and which dimensions can attach to it.
When teams skip that sentence, problems arrive quietly. For example, a table that mixes daily order lines with monthly targets will double-count revenue the first time someone sums it. Declaring the grain first is the cheapest quality control in dimensional modeling, and it applies to both schemas.
Why the Dimensions Stay Flat
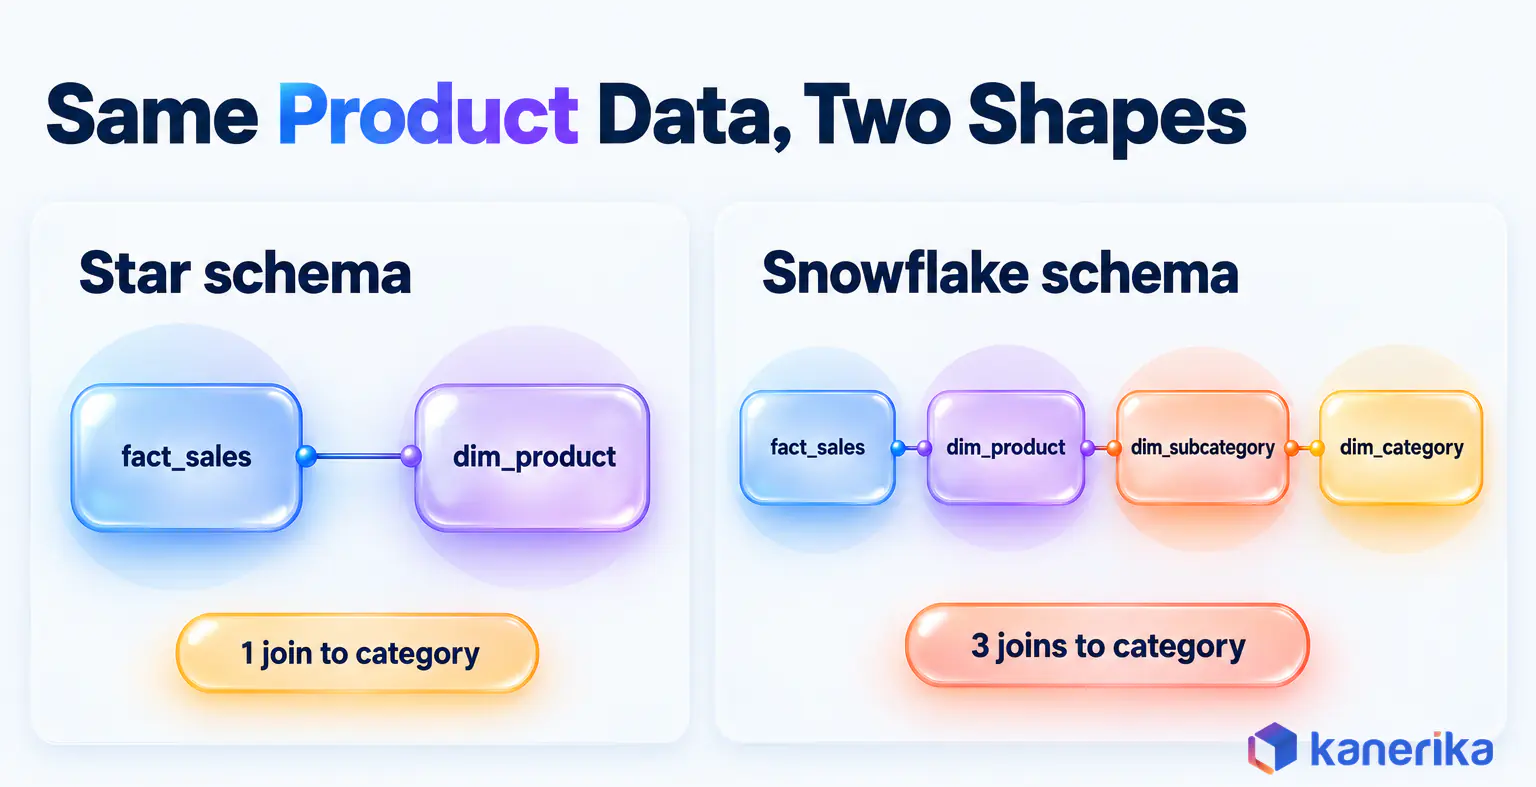
In a star schema, the Product dimension carries everything about a product in one row. Product name, brand, subcategory and category sit as columns side by side. “Running Shoes” and “Footwear” repeat on every running shoe in the catalog.
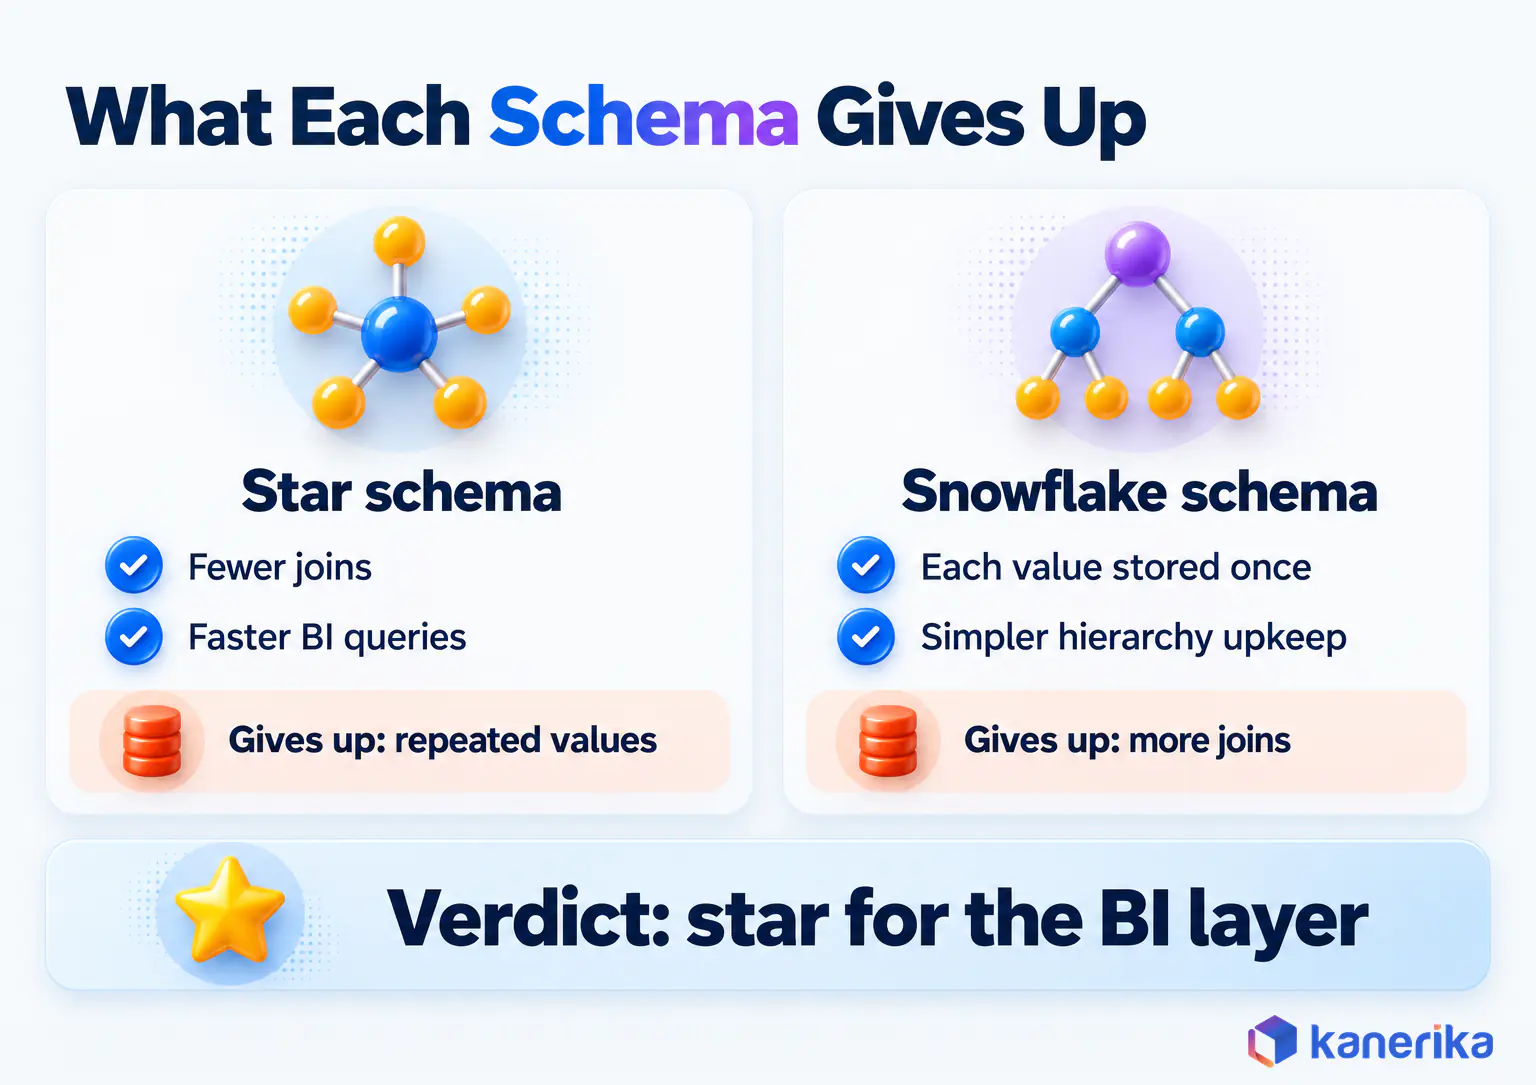
That repetition is deliberate. A report that groups sales by category reads one dimension table and joins it once to the facts. Analysts also see every attribute of a product in one place, which is why self-service users find a star model easier to explore. The cost is redundancy, because a renamed category forces the pipeline to update every product row that carries it.
What Is a Snowflake Schema?
A snowflake schema keeps the central fact table but normalizes some dimensions into chains of smaller tables. Microsoft’s own example uses Adventure Works, where the product dimension is split into DimProduct, DimProductSubcategory and DimProductCategory. Each product row then points to its subcategory, and each subcategory points to its category.
Seen on a diagram, those chains branch outward like the arms of a snowflake, which is where the name comes from. Geography snowflakes the same way: store links to city, city to region and region to country.
The gain is that each value lives once. When you rename “Footwear”, you change a single row in the category table. The loss is distance, since a query that groups by category now walks three tables to get there instead of one.
Snowflake Schema Is Not Snowflake the Platform
The shared name causes real confusion in search results and in meetings. A snowflake schema is a modeling pattern from classic data warehousing. Snowflake, on the other hand, is a cloud data platform that runs star schemas, snowflake schemas or Data Vault models alike. Choosing a platform does not choose the schema for you, and the reverse is also true.
Star Schema vs Snowflake Schema: The Differences Side by Side
The two models store the same facts, so the differences sit almost entirely in the dimensions. The table below compares them on the points that change daily work: joins, storage, pipelines, BI usability and who protects data integrity. Read the rows with your own workload in mind. A row that matters a great deal to a finance dashboard may barely matter to a staging layer.
| Factor | Star schema | Snowflake schema |
|---|---|---|
| Normalization | Denormalized dimensions | Normalized dimensions, often to third normal form |
| Tables per dimension | One | One per hierarchy level |
| Joins for a category-level sales query | One (fact to product) | Three (fact to product, subcategory, category) |
| Redundancy | Repeated attribute values in dimension rows | Each value stored once |
| Storage | Slightly larger dimensions | Slightly smaller dimensions; facts are identical |
| Query speed for BI | Usually faster, fewer joins | Usually slower, more joins to resolve |
| ETL and maintenance | Simpler loads; attribute changes touch many rows | More tables to load in order; changes touch one row |
| BI tool usability | Easy to browse; one table per business entity | Harder for self-service users; more tables to relate |
| Slowly changing dimensions | One new row per Type 2 change | Versioning may be needed at each level of the chain |
| Who enforces integrity | Pipelines and tests | Pipelines and tests on most cloud engines |
| Where they combine | Star-shaped marts on top | Normalized shared hierarchies underneath |
Which Rows Decide the Choice?
Storage surprises first: the gap is small, because fact tables hold nearly all the rows and look identical in both models. Integrity also surprises anyone who expects normalized tables to bring enforced foreign keys, which most modern cloud engines do not provide. A star model asks less of the engine and report builder, while a snowflake model asks less of whoever maintains a shared hierarchy.
One Business Question, Two Schemas: A SQL Walkthrough
Abstract comparisons only go so far, so here is the same question answered against both models. The table names stay consistent: fact_sales, dim_product, dim_store and dim_date in the star, with dim_subcategory, dim_category and dim_region added in the snowflake.
- Define the question and grain. Finance asks for net revenue by product category and region for the third quarter of 2026. The fact table grain is one row per order line per day.
- Write the star query. Category sits on dim_product and region sits on dim_store, so the query needs three joins: product, store and date.
- Write the snowflake query. Category now lives two tables away from the product, and region one table away from the store, so the same answer needs six joins.
- Compare plans and validate totals. Run both queries on production-like data, read the query plans and confirm the totals match to the cent before you trust either model.
Here is the star version. Every attribute the report needs is one hop from the fact table.
-- Star schema: 3 joins
SELECT p.category,
       s.region,
       SUM(f.net_amount) AS net_revenue
FROM fact_sales f
JOIN dim_product p ON f.product_key = p.product_key
JOIN dim_store   s ON f.store_key   = s.store_key
JOIN dim_date    d ON f.date_key    = d.date_key
WHERE d.calendar_quarter = '2026-Q3'
GROUP BY p.category, s.region;
Now the snowflake version. The result set is identical, but the engine has to resolve two extra chains first.
-- Snowflake schema: 6 joins
SELECT c.category_name,
       r.region_name,
       SUM(f.net_amount) AS net_revenue
FROM fact_sales f
JOIN dim_product     p  ON f.product_key     = p.product_key
JOIN dim_subcategory sc ON p.subcategory_key = sc.subcategory_key
JOIN dim_category    c  ON sc.category_key   = c.category_key
JOIN dim_store       s  ON f.store_key       = s.store_key
JOIN dim_region      r  ON s.region_key      = r.region_key
JOIN dim_date        d  ON f.date_key        = d.date_key
WHERE d.calendar_quarter = '2026-Q3'
GROUP BY c.category_name, r.region_name;
Doubling the joins does not double the run time on a modern engine, especially when the dimension tables are small. Still, every extra join is another place for a missing key to drop rows silently. That is also why step 4 checks totals and not just speed.
If the two answers differ, look for an orphaned subcategory or region in the snowflake chain. Quick data profiling on the key columns usually finds it. That is worth finding before any dashboard goes live.
Talk to Kanerika
Not Sure Which Shape Your Warehouse Needs?
Bring one subject area and its slowest dashboard. Kanerika will model it both ways on your engine and show you the joins, compute and reconciliation results side by side.
Talk to a Data Expert →Does the Join Penalty Still Matter on Modern Engines?
Columnar storage, caching and smarter optimizers have shrunk the cost of joining a small dimension. A small category table is cheap to join on any current warehouse. So the old rule that “snowflake is always slow” overstates the problem.
The vendors that build these engines still recommend flat dimensions for BI, though. The reasons go beyond raw join speed. They cover how BI tools filter, how many tables a model holds and how easily people can use it. Databricks puts it plainly: star schemas avoid computationally expensive joins compared with normalized models like snowflake schemas.
Power BI and Fabric Semantic Models
Microsoft’s guidance is direct. With a snowflake design, Power BI loads more tables, which Microsoft calls less efficient from storage and performance perspectives. Filters must also travel longer relationship chains. Its conclusion is that the benefits of a single model table generally outweigh the benefits of several.
Microsoft adds two usability points. A model hierarchy cannot span columns from more than one table, so a snowflaked product chain cannot offer one category-to-product drill path. More tables also crowd the Data pane for authors building visuals like the Power BI card visual, which shows several metrics at once.
In practice, many teams keep a snowflaked source and flatten it inside the semantic model, merging category and subcategory into the product table during load. Teams in an SSAS to Microsoft Fabric migration face the same flattening choice. Our step-by-step star schema build in Power BI shows that process, and our Power BI data modeling best practices guide adds relationships and measures.
Fabric Warehouse, Databricks and Snowflake
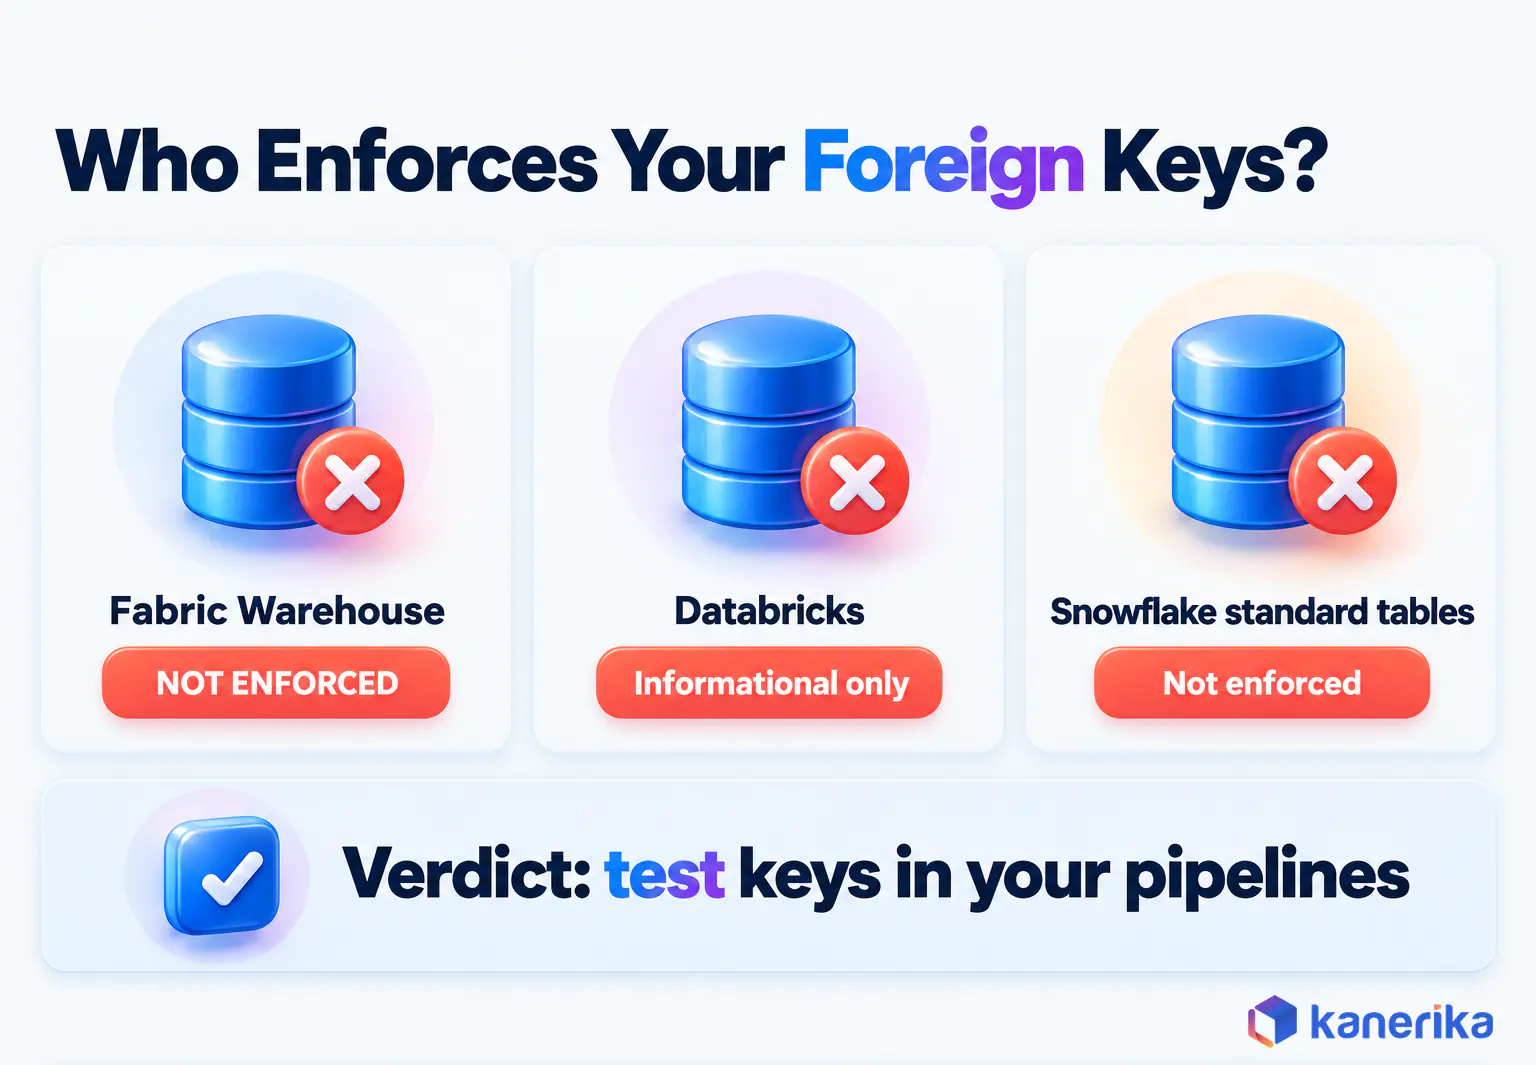
The warehouse engines tell a similar story with one twist. Microsoft calls the star schema a recommended design approach for a Fabric Warehouse. The twist is about keys. None of these engines enforces primary and foreign keys on standard tables, so a snowflaked chain does not buy enforced integrity on its own.
| Engine | What the docs say about keys | What it means for schema choice |
|---|---|---|
| Fabric Warehouse | PRIMARY KEY and UNIQUE only with NONCLUSTERED and NOT ENFORCED; FOREIGN KEY only NOT ENFORCED (Microsoft Learn) | Star is the recommended shape; validate keys in pipelines |
| Databricks | Primary, foreign and unique keys are informational and not enforced; NOT NULL and CHECK are enforced; constraints require Delta Lake (Databricks docs) | Declare keys for the optimizer and tools, test them yourself |
| Snowflake (standard tables) | Primary, foreign and unique keys are optional and not enforced; NOT NULL and CHECK are enforced (Snowflake docs) | Normalizing adds joins without adding enforced integrity |
On Snowflake, declared keys can cut join cost: the optimizer can eliminate an unnecessary join when the primary and foreign keys carry the RELY property. It does so only when the query uses no other columns from the joined table. The docs also warn that results can differ if the data breaks those keys, so set RELY only on keys your pipeline tests.
Snowflake’s hybrid tables behave differently, but they serve transactional workloads rather than BI marts. For analytics, the safe pattern is the same on every engine above. Declare keys so tools understand the model, then prove them with row-count and orphan-key tests in the pipeline. The modeling advice holds whether you are choosing between Microsoft Fabric and Databricks or comparing Databricks, Snowflake and Fabric side by side.
Storage and Cost: What Normalization Really Saves
Normalization was born when disk was expensive, and the storage argument for snowflaking still appears in many comparisons. Look at where the rows actually sit, though. A sales fact table grows with every order line, while the product dimension grows only when the catalog does and the category table stays tiny.
Snowflaking only shrinks the dimensions. Removing repeated category names from a few thousand product rows therefore saves very little next to a fact table that is identical in both designs. Columnar formats also compress repeated values well, which narrows the gap further.
The cost that does grow is compute. Every query against a snowflaked dimension does more join work, so on consumption-priced platforms that work shows up on the bill. Weigh the trade this way:
- Storage saved by snowflaking: small, and confined to dimension tables.
- Compute added by snowflaking: extra joins on every query that touches the normalized levels, repeated across every dashboard refresh.
- Engineering effort: more tables to load in order across your data pipeline architecture, more keys to test and more relationships to document.
For a deeper look at how platforms price storage and compute, see our guide to the cloud data warehouse.
Checklist
Data Engineering Checklist
Plan pipelines, data models, key tests and reconciliation steps before you build, with a step-by-step list for warehouse and lakehouse projects.
Get the Checklist →Star Schema vs Snowflake Schema: Which One Fits Each Workload?
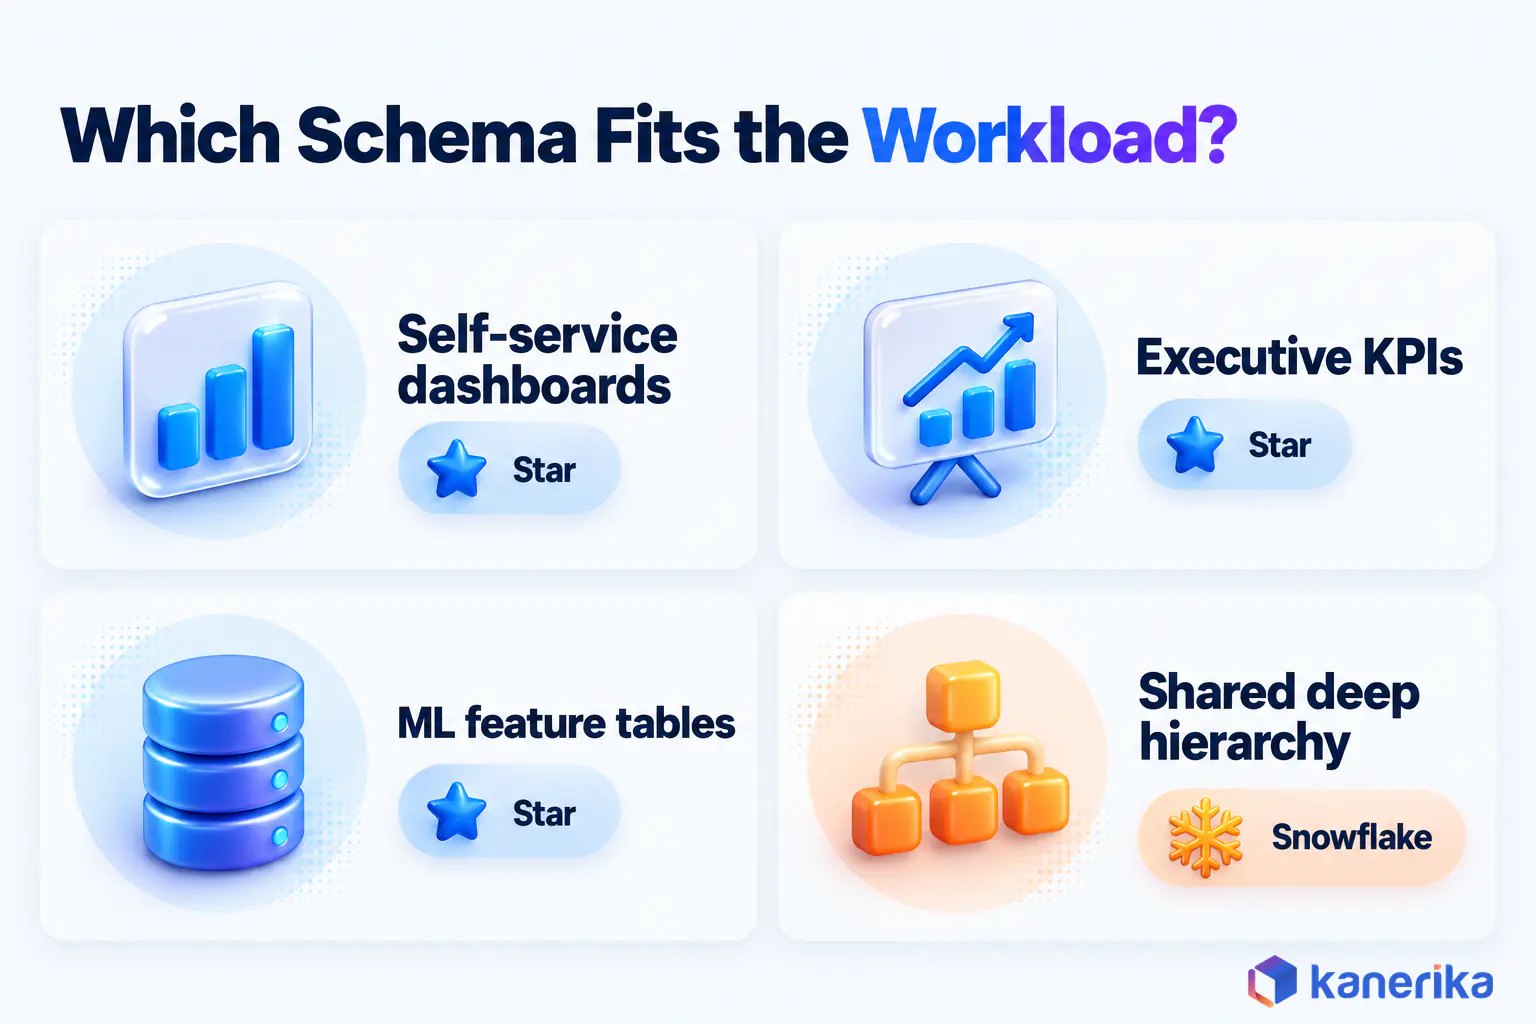
The right answer depends on who queries the layer and how the hierarchies behave. The scenarios below cover the cases that come up most in enterprise warehouses. Each one picks a side, and the hybrid pattern that follows shows how both picks can live in the same warehouse.
| Scenario | Pick | Why |
|---|---|---|
| Self-service Power BI dashboards | Star | Fewer tables to relate, shorter filter paths, easier for business users to browse |
| High-concurrency executive KPIs | Star | Fewer joins per query across many simultaneous users |
| Deep hierarchy or regulated reference data shared across marts, such as geography or a chart of accounts | Snowflake that dimension | One owner maintains and audits each level once, and every mart reuses it |
| Staging or integration layer | Snowflake or fully normalized | Mirrors source systems; nobody reports from it directly |
| Machine learning feature extraction | Star | Flat dimensions need fewer joins to build point-in-time feature rows |
Notice the pattern. Every layer that people or dashboards read directly lands on star. Snowflake wins where a shared, volatile hierarchy has one owner, or where the layer exists to integrate sources rather than to serve reports.
Slowly Changing Dimensions in Each Schema
Dimensions change over time. For example, a store moves region, a product changes category or a customer changes segment. Kimball’s Type 2 technique keeps history by adding a new row with a new surrogate key. It also needs at least three extra columns: a row effective date, a row expiration date and a current row indicator.
On a flat star dimension, a category change means closing one product row and inserting one new row. On a snowflaked chain, by comparison, the same history can require versioning at the product, subcategory and category levels, each with its own dates and keys. Point-in-time reports then have to line up three sets of effective dates instead of one. So teams that need full history on a volatile hierarchy usually find the star version far easier to load and to test.
The Hybrid Option: Normalized Core, Star-Shaped Marts
Many enterprise warehouses refuse the either-or choice. They keep a normalized core where sources are integrated and shared hierarchies are maintained, then publish star-shaped marts on top for reporting. In a medallion lakehouse, that usually means normalized silver tables and star-shaped gold tables, a split our data lake vs lakehouse architecture guide explains.
Two related patterns are worth naming. A galaxy schema, also called a fact constellation, is several star schemas sharing conformed dimensions such as date and product. Data Vault modeling is an alternative for the integration layer, with star marts still serving the reports. In each case the reporting surface stays star-shaped, which is the point of the hybrid.
A Five-Question Checklist Before You Pick
A schema decision is cheaper to get right before the first dashboard ships than after dozens of reports depend on it. These five questions turn the comparison into a decision you can defend to both finance and engineering.
- Who queries this layer? If analysts, dashboards or semantic models read it directly, start from star.
- How deep and how volatile are the hierarchies? A two-level hierarchy that rarely changes belongs flat. A deep hierarchy that changes often and is shared across marts may earn snowflaking.
- How large is each dimension? Redundancy in a dimension of a few thousand rows costs almost nothing. Very large dimensions with repeated text are where normalization saves real space.
- Which BI tool and concurrency targets apply? Power BI and similar tools reward fewer tables, and high concurrency multiplies the cost of every extra join.
- What does a production-like test show? Measure latency, compute consumed and row-count reconciliation for both shapes on your own engine and data.
The last question settles the arguments the first four leave open. Vendor guidance and comparison tables set a starting point, but your own data volumes and query patterns decide the margin. Comparing data modeling tools helps here too, since several generate both shapes from one logical model. Our roundup of data warehouse tools covers the engines themselves.
Mistakes That Undo Either Choice
A well-chosen schema can still fail through a handful of design errors. These show up in star and snowflake models alike:
- Leaving the grain undeclared, so nobody knows what one fact row means.
- Snowflaking by default because the source system happens to be normalized.
- Mixing grains in one fact table, such as daily sales next to monthly targets.
- Building without a proper date dimension and relying on raw timestamps instead.
- Trusting declared keys that the engine never enforces, with no orphan-key tests in the pipeline.
A short design review and a few automated tests catch most of these before launch. Our data warehouse implementation guide also covers where those reviews fit in a delivery plan. If the schema change rides on a move to a new engine, our data warehouse migration guide covers that path.
The star schema vs snowflake schema verdict comes down to who reads the layer, and star wins any layer that people or dashboards query. Snowflake a dimension only when its hierarchy is shared across marts, changes often and has one clear owner. Then prove the choice with a production-like test of latency, compute and reconciled totals on your own engine.
How Kanerika Designs Warehouse and Semantic Models
Kanerika’s data analytics services treat the schema as a decision to test on real workloads. The work follows three stages, and each one has a clear output.
Assess Workloads and Grain
We start with the questions the business asks most often and the people who ask them. That step produces declared grains for each fact table and a list of hierarchies with their owners and change rates.
Design and Test Both Shapes on the Target Engine
When a hierarchy is a real candidate for snowflaking, we model it both ways on the client’s own platform. That may be Microsoft Fabric, Databricks or Snowflake. Query latency, compute and reconciliation results then decide the shape.
Build, Migrate and Validate
Our data engineering team then builds the pipelines, key tests and semantic models, and validates every total against the source before users see it.
One program shows what this looks like at scale. A global manufacturer of thermal management and cooling technologies ran its order lifecycle across three SAP systems. SAP Cloud for Customer, SAP CPQ and SAP S/4HANA gave it no single view of that lifecycle. Kanerika built one governed pipeline on Microsoft Fabric that brought 35+ source tables into one structured foundation. A dedicated bridge linked Opportunities, Quotes and Orders so the lead-to-delivery journey reads as one record.
On top sits a self-updating Power BI report with 50+ governed KPIs. Row-level security follows a four-level hierarchy of region, Sales Organization, Sales Office and Sales Group. Time spent per reporting cycle fell by 60%. That sales hierarchy is exactly the kind of structure this guide weighs: shared across reports, owned by one team and filtered on constantly.
Case Study
60% Less Reporting Effort Across 3 SAP Systems on Fabric
One governed Microsoft Fabric pipeline unified 35+ source tables from three SAP systems, feeding a self-updating Power BI report on 50+ governed KPIs and cutting time per reporting cycle by 60%.
Read the Case Study →Frequently Asked Questions
What is the main difference between star schema and snowflake schema?
A star schema stores each dimension in one flat, denormalized table linked directly to the fact table. A snowflake schema normalizes dimensions into chains of smaller tables, one per hierarchy level. Star needs fewer joins and suits BI reporting. Snowflake removes repeated values and suits deep, shared hierarchies that one team maintains in one place.
Why is star schema better for most BI reporting?
Star schemas give BI tools fewer tables to relate and shorter filter paths, so dashboards respond faster and are easier to build. Microsoft’s Power BI guidance says extra model tables are less efficient for storage and performance. Business users also find flat dimensions easier to browse, because every attribute of a product or customer sits in one table.
What is a real-life example of a star schema?
A retail sales model is the classic example. The fact table holds one row per order line per day, with quantity and net amount. It links directly to Product, Store, Customer and Date dimensions. A report asking for net revenue by category and region joins the facts to just the product, store and date tables.
Can a schema be both star and snowflake?
Yes. Many models are mostly star with one or two snowflaked dimensions, such as geography split into store, region and country tables. Larger warehouses go further, keeping a normalized core for integration and publishing star-shaped marts for reporting. Both patterns then live in the same platform, each serving the layer it suits best.
What are the main components of a star schema?
A star schema has a central fact table and the dimension tables around it. The fact table stores measures such as quantity and revenue, plus foreign keys at a declared grain. Each dimension stores descriptive attributes and a surrogate key. Most models also include a date dimension, which supports time-based filtering, grouping and comparisons.
What are the benefits of using a snowflake schema?
A snowflake schema stores each hierarchy value once, so renaming a category or region changes a single row. That reduces redundancy, makes one team’s ownership of reference data clear and keeps shared hierarchies consistent across marts. It also mirrors normalized source systems, which can simplify integration layers that nobody queries directly for reports.
What are the disadvantages of star schema?
A star schema repeats attribute values across dimension rows, so a category rename must update every product that carries it. Very large dimensions with long repeated text use more storage. Shared hierarchies can drift if several marts each keep their own flat copy. Pipelines must also handle these updates carefully to keep history accurate.
Can you convert a snowflake schema to a star schema?
Yes. You flatten each snowflaked chain by joining its tables into one dimension, so product, subcategory and category become one product table. This can happen in a view, in a pipeline or inside a Power BI semantic model during load. Validate row counts and totals afterwards to confirm that no orphaned keys dropped rows.
Why is it called a snowflake schema?
The name comes from the diagram. When dimensions are normalized into chains, such as product to subcategory to category, the tables branch outward. The diagram then looks like a snowflake. The name describes the shape of the model only. It has no link to the Snowflake cloud data platform, which supports any schema.
Why is it called a star schema?
Drawn as a diagram, a star schema has one fact table in the middle with each dimension table connected directly to it. The lines radiating from the center look like the points of a star. No dimension connects to another dimension, which is what keeps the shape simple and the query paths short.
Why use snowflake schema over star schema?
Choose snowflaking when a dimension has a deep hierarchy that changes often, is shared across several marts and has one clear owner. Geography and charts of accounts are common examples. Snowflaking that dimension keeps each level maintained once. For the reporting layer itself, most teams still flatten those tables into star dimensions before dashboards query them.
Are star and snowflake schemas used for OLAP or OLTP?
Both are OLAP designs, built for analytical queries over historical data in a warehouse or lakehouse. OLTP systems that run daily transactions use highly normalized models designed for fast inserts and updates. A snowflake schema is more normalized than a star, yet it still serves analytics, usually in integration layers or shared hierarchies.
When should you not use a star schema?
Avoid a pure star schema for a staging or integration layer that mirrors source systems, where normalized tables are easier to load and audit. It also fits poorly when a deep hierarchy is shared across many marts and changes often. In those cases, normalize that layer or dimension and publish star-shaped marts for reporting on top.
Which schema is faster for SQL queries?
A star schema is usually faster for analytical SQL because a query reaches each attribute with one join. In the same sales question, a star query used three joins and the snowflake version needed six. Modern columnar engines narrow the gap for small dimensions, so test both shapes on your own engine and data volumes.
Which schema works best in Power BI and Microsoft Fabric?
The star schema works best. Microsoft’s Power BI guidance says snowflake designs load more tables and lengthen filter paths, and that a single model table generally outweighs several. Microsoft also calls the star schema a recommended design for Fabric Warehouse. Teams with snowflaked sources usually flatten them in the semantic model during load.
How do slowly changing dimensions work in star and snowflake schemas?
In Kimball’s Type 2 method, a change adds a new dimension row with a new surrogate key. Effective date, expiration date and current row columns track history. On a flat star dimension, one change means one new row. On a snowflaked chain, history may need versioning at several levels, which complicates loads and point-in-time reporting.
Is a snowflake schema related to the Snowflake data platform?
No. The snowflake schema is a data modeling pattern named after the shape of its diagram. Snowflake is a cloud data platform that runs star schemas, snowflake schemas and Data Vault models alike. Choosing Snowflake as a platform does not decide your schema, and a snowflake schema can run on any warehouse engine.
Is snowflake schema still relevant in 2026?
Yes, for specific jobs. Snowflaking still makes sense for deep hierarchies shared across marts, regulated reference data with one owner and integration layers that mirror normalized sources. For the reporting layer, vendor guidance from Microsoft and Databricks still favors flat star dimensions. Many enterprise warehouses use snowflaked structures underneath and star marts on top.
What is star schema in ETL?
In ETL, a star schema is the target model that pipelines load. Extract jobs pull source data, transforms clean it and assign surrogate keys, and load steps write dimension tables first and fact tables second. The star shape keeps loads simple because each dimension is one table, though attribute changes may update many dimension rows.
Is star schema still relevant in 2026?
Yes. Microsoft calls the star schema a recommended design for Fabric Warehouse and Power BI semantic models, and Databricks recommends it for BI workloads. Columnar engines have reduced the cost of joins, but flat dimensions still give BI tools shorter filter paths and give analysts simpler models. It remains the default choice for reporting layers.
Which is more normalized, star or snowflake schema?
The snowflake schema is more normalized. It splits dimensions into separate tables for each hierarchy level, often reaching third normal form, so each value is stored once. The star schema keeps dimensions denormalized, repeating attributes such as category on every product row. Fact tables look the same in both designs and hold the same measures and keys.
What are the disadvantages of snowflake schema?
A snowflake schema needs more joins for every query that reaches a normalized level, which adds compute and can slow dashboards. It has more tables to load in order, more keys to test and more relationships for BI users to understand. Slowly changing dimensions also get harder, since history may need versioning at each level.
Why is star schema denormalized?
Star schemas are denormalized on purpose to make analytical queries simple and fast. Keeping product name, subcategory and category in one dimension row means a report joins once instead of walking a chain of tables. The trade is some repeated values in dimension tables, which cost little because dimensions are small compared with fact tables.
Which schema is best for a data warehouse?
For most data warehouses, a star schema is the best fit for the layer that people and dashboards query. Snowflake only the dimensions whose deep, shared hierarchy earns the extra joins. Many enterprise warehouses use a hybrid, with a normalized integration core and star-shaped marts on top, tested on their own engine before rollout.