TL;DR
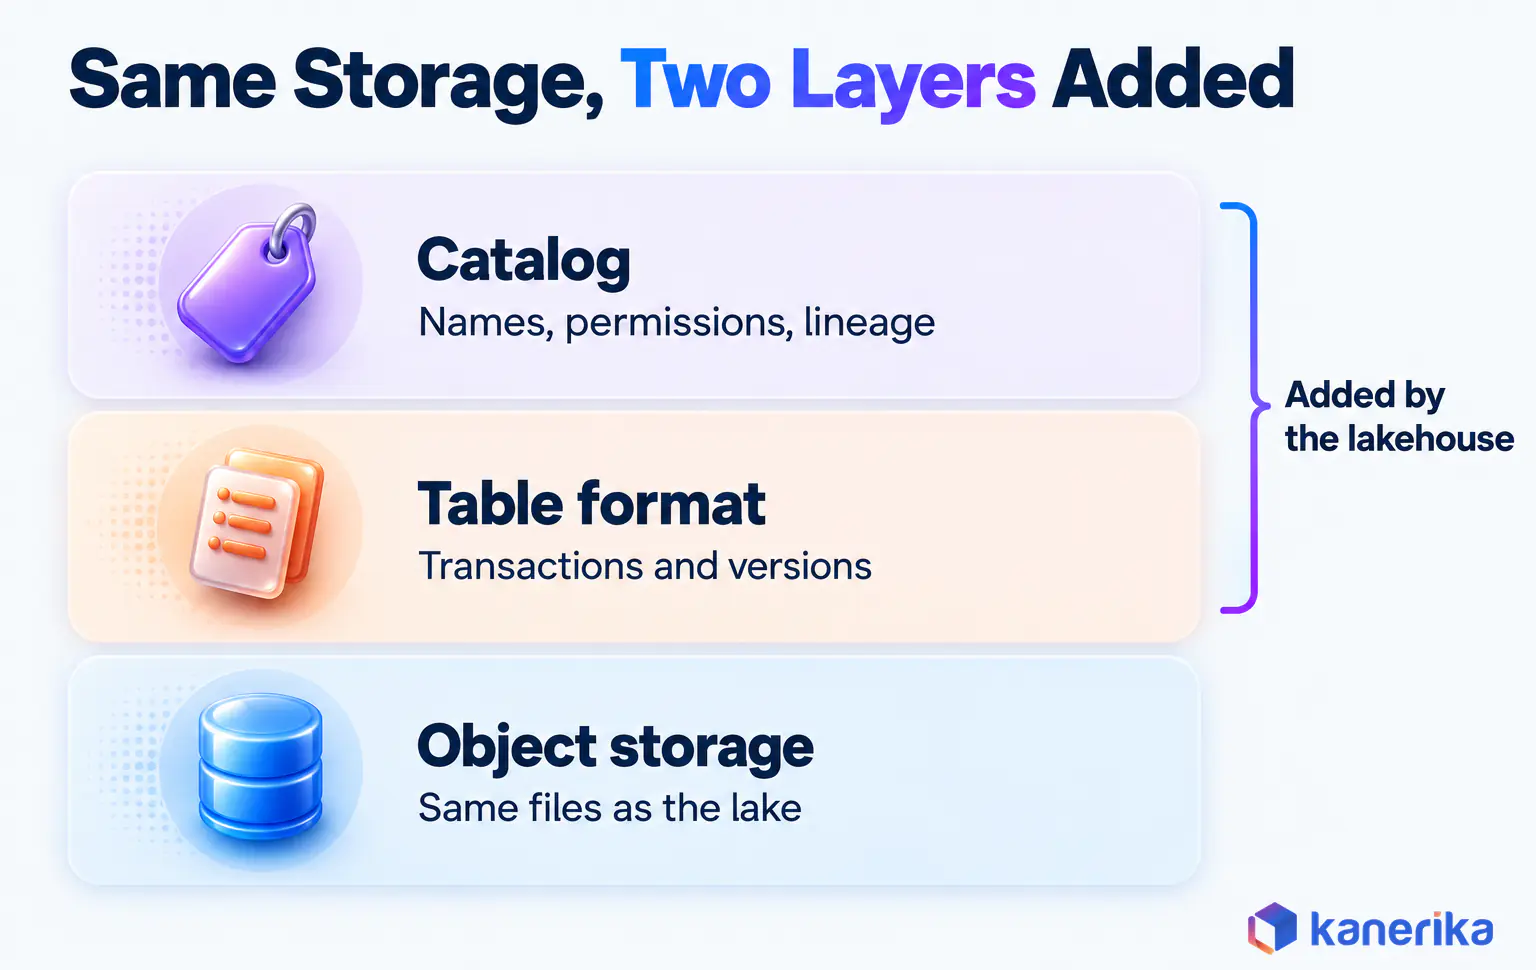
Data lake vs lakehouse: pick a lakehouse when many teams share changing data, and a plain lake for raw, rarely changed data. Both store files in the same cheap object storage, such as Amazon S3 or Azure Data Lake Storage. A lakehouse adds a table format and a catalog on top of those files.
That brings safe updates, deletes, version history and access control, which a plain lake lacks. Judge cost by the whole bill: data copies, pipeline upkeep and staff time count more than storage. You can also move gradually by converting one high-value workload in place, then the rest.
Key Takeaways
- A lakehouse is a data lake plus an open table format and a catalog, on the same object storage.
- Pick a plain lake for raw data that lands and rarely changes, such as logs, archives and exploration sets.
- Pick a lakehouse when many teams query, correct, delete or audit the same data.
- Delta Lake, Apache Iceberg and Apache Hudi add ACID transactions and time travel to files in the lake.
- Judge cost as total cost of ownership, counting data copies, pipelines, maintenance and skills alongside storage.
- Migrate one workload at a time by converting existing files in place, then retire the old copies.
One Data Lake, Three Teams, Three Different Numbers
Picture the Monday after quarter close at a mid-sized retailer. Finance pulls revenue from the sales folder in the company data lake and gets one figure. The data science team, working from a copy it exported to train a demand model, gets another.
The BI team reports a third number. Its dashboard reads a curated extract that a nightly job rebuilds, and that job was still rewriting files when the dashboard refreshed at 7 a.m. Nobody made a mistake on purpose. The lake simply has no way to say which version of the data is the true one at a given moment.
That gap is what the lakehouse was built to close. It keeps the same cheap files in the same object storage. Then it adds a table layer that records every change as a transaction, and a catalog that decides who can see what. So the data lake vs lakehouse question is less about storage and more about trust in shared tables that keep changing.
The rest of this guide shows where that trust gap opens and when it is worth paying to close it.
Data Lake vs Lakehouse at a Glance
The short version fits in one table, so start there. The first rows look alike, and the gaps open once data has to change, be governed or serve many users at once. Is your real question a lake against a warehouse? Then read our guide on data lake vs data warehouse instead, because that is a different decision.
| Dimension | Data lake | Lakehouse |
|---|---|---|
| Storage | Object storage such as Amazon S3, ADLS Gen2 or Google Cloud Storage | The same object storage |
| Data format | Raw files: CSV, JSON, Parquet, images, logs | Parquet files managed by an open table format (Delta Lake, Iceberg or Hudi) |
| Schema | Applied when data is read (schema-on-read) | Enforced on write for curated tables, with controlled schema changes |
| Transactions | None; each job writes files directly | ACID transactions recorded in a table log |
| Updates and deletes | Rewrite whole files or partitions by hand | MERGE, UPDATE and DELETE as single commits |
| BI and SQL | Possible, but slow and inconsistent on raw files | Built for many concurrent SQL and BI users |
| ML and AI access | Direct file access, often on copied data | Direct access to the same governed tables |
| Governance and catalog | Folder permissions; catalog optional | Central catalog with table, row and column controls plus lineage |
| Typical cost driver | Engineering time to keep data usable, plus extra copies | Compute for queries and table maintenance, plus platform skills |
| Best fit | Raw retention, archives, exploration, one team | Shared analytics, BI, AI and regulated data across teams |
Pick the lake column when data mostly lands and stays put. Pick the lakehouse column when the same data gets corrected, deleted, queried by many people and audited.
What a Data Lake Is and Where It Still Wins
A data lake is a central store that keeps data in its original form until someone needs it. You land files first and decide their structure later, which makes ingestion fast and storage cheap.
That design still wins in several places. Raw clickstream, IoT readings and application logs arrive in huge volumes and rarely change after they land. Compliance archives must be kept for years but are read only during an audit.
Data scientists exploring a new source want every field, not a cleaned subset. In each of these cases a plain lake does the job well, without the overhead of a table layer. Several documented data lake designs, such as Walmart’s and Robinhood’s, later added a table format.
How a Data Lake Stores and Reads Data
Modern lakes run on cloud object storage: Amazon S3, Google Cloud Storage or Azure Data Lake Storage Gen2. Microsoft describes ADLS Gen2 as built on Azure Blob Storage, with a hierarchical namespace that organizes objects for analytics.
First, data lands as files. For example, a sales feed might arrive as daily Parquet files under a folder such as /sales/2026/10/. Support tickets arrive as JSON, while product photos arrive as images. Nothing checks those files against a fixed structure on the way in.
Structure gets applied at read time instead, which is called schema-on-read. A Spark or Trino query states which columns it expects and how to parse them. That is flexible, since two teams can read the same file in two ways. It is also the root of the problem in the opening story, because two readings can produce two answers.
The Data Swamp Problem
A lake without rules tends to decay. Files pile up with no owner, no description and no record of where they came from. Duplicates also appear when teams copy data to work around slow or messy folders.
Three gaps cause most of the damage. There are no transactions, so a reader can see a half-written folder. There is no catalog, so nobody can find or trust a dataset. And there are no quality gates, so bad records land next to good ones.
Our guide to data lake vs data swamp covers the warning signs in detail. A lakehouse is one structured answer to all three gaps at once.
Kanerika Service
Data Modernization Services
Kanerika moves enterprises from aging lakes and warehouses to governed, AI-ready platforms, one workload at a time, with the old systems running until the new ones prove out.
Explore Data ModernizationWhat a Lakehouse Adds on Top of the Lake
A lakehouse is a data lake with a table layer and a catalog on top. The files stay where they are, in the same object storage, but software now manages them as tables with rules.
The idea was set out in a research paper by Michael Armbrust, Ali Ghodsi, Reynold Xin and Matei Zaharia. They describe a lakehouse built on open, direct-access formats such as Apache Parquet, with first-class support for machine learning and data science. The paper targets five problems of the older lake-plus-warehouse setup: stale data, weak reliability, high total cost of ownership, lock-in and limited use-case support.
In practice, a lakehouse has three layers. Object storage holds the files, while an open table format turns groups of files into tables with a transaction log. A catalog sits above both and controls names, permissions and lineage. That way, engines for SQL, BI, streaming and machine learning can all read the same tables.
Open Table Formats and the Transaction Log
An open table format is a set of rules for how a table’s files and metadata are written. The data still lives in Parquet files. Alongside them sits a log or metadata tree that lists which files belong to each version of the table.
In other words, every write becomes a commit in that log. When a job adds, changes or removes rows, it writes new files first. Then it records one entry that names the files in the next version. Readers only see committed versions, so they never see a half-finished write. Old versions stay listed too, which is what makes time travel possible.
Three formats lead the field, and all three are open source.
| Format | Project home | What it is known for |
|---|---|---|
| Delta Lake | Independent open-source project under the Linux Foundation since 2019 | ACID transactions and time travel; the table format behind Databricks and Fabric OneLake tables |
| Apache Iceberg | Apache Software Foundation | Open table format with time travel, read by engines such as Spark, Trino, Flink, Presto and Hive |
| Apache Hudi | Apache Software Foundation | Calls itself an open data lakehouse platform; built for incremental processing and upserts |
The Delta Lake project, Apache Iceberg and Apache Hudi each publish their own specs. For most teams the format matters less than the fact that it is open, because several engines can then read one table without exporting it.
The Catalog and Governance Layer
The catalog is the part of a lakehouse that people feel most. It gives every table a name, an owner and a set of permissions. So access is granted on a table such as sales.orders rather than on a folder path.
Each major platform ships its own catalog. Databricks uses Unity Catalog, and on AWS the Glue Data Catalog and Lake Formation handle table definitions and fine-grained access. Microsoft Fabric organizes data in OneLake, which every Fabric tenant includes and which stores tables in Delta Parquet or Iceberg format.
A good catalog also records data lineage, meaning which job produced which table from which sources. When finance asks why revenue moved, lineage shows the path instead of leaving the team to rebuild it by hand.
Case Study
Zero-Downtime Databricks Migration for Retail Analytics
A large US retail chain moved PostgreSQL and Cassandra data into governed Delta Lake tables under Unity Catalog with zero downtime, decommissioning 100% of its legacy infrastructure.
Read the Case Study →One Copy of Data for BI, Data Science and AI
The quiet win of a lakehouse is fewer copies. In a classic two-tier setup, data lands in the lake and gets copied into a warehouse for BI. Then it is copied again into extracts for data science. Each copy needs its own pipeline, its own refresh schedule and its own access rules.
A lakehouse lets the BI tool, the notebook and the AI pipeline read one governed table. When a record is corrected, every consumer sees the fix at the same moment. That is the cure for the three-numbers problem: one table, one version, one answer.
What Happens When a Record Changes
The clearest way to see the difference is to change one record and watch what each architecture does. Take two everyday events at the retailer. First, a sale from last Tuesday was keyed at the wrong amount. Second, a customer has asked for their personal data to be deleted under a privacy law.
The Same Two Changes in a Plain Data Lake
In a plain data lake, neither change is a simple command.
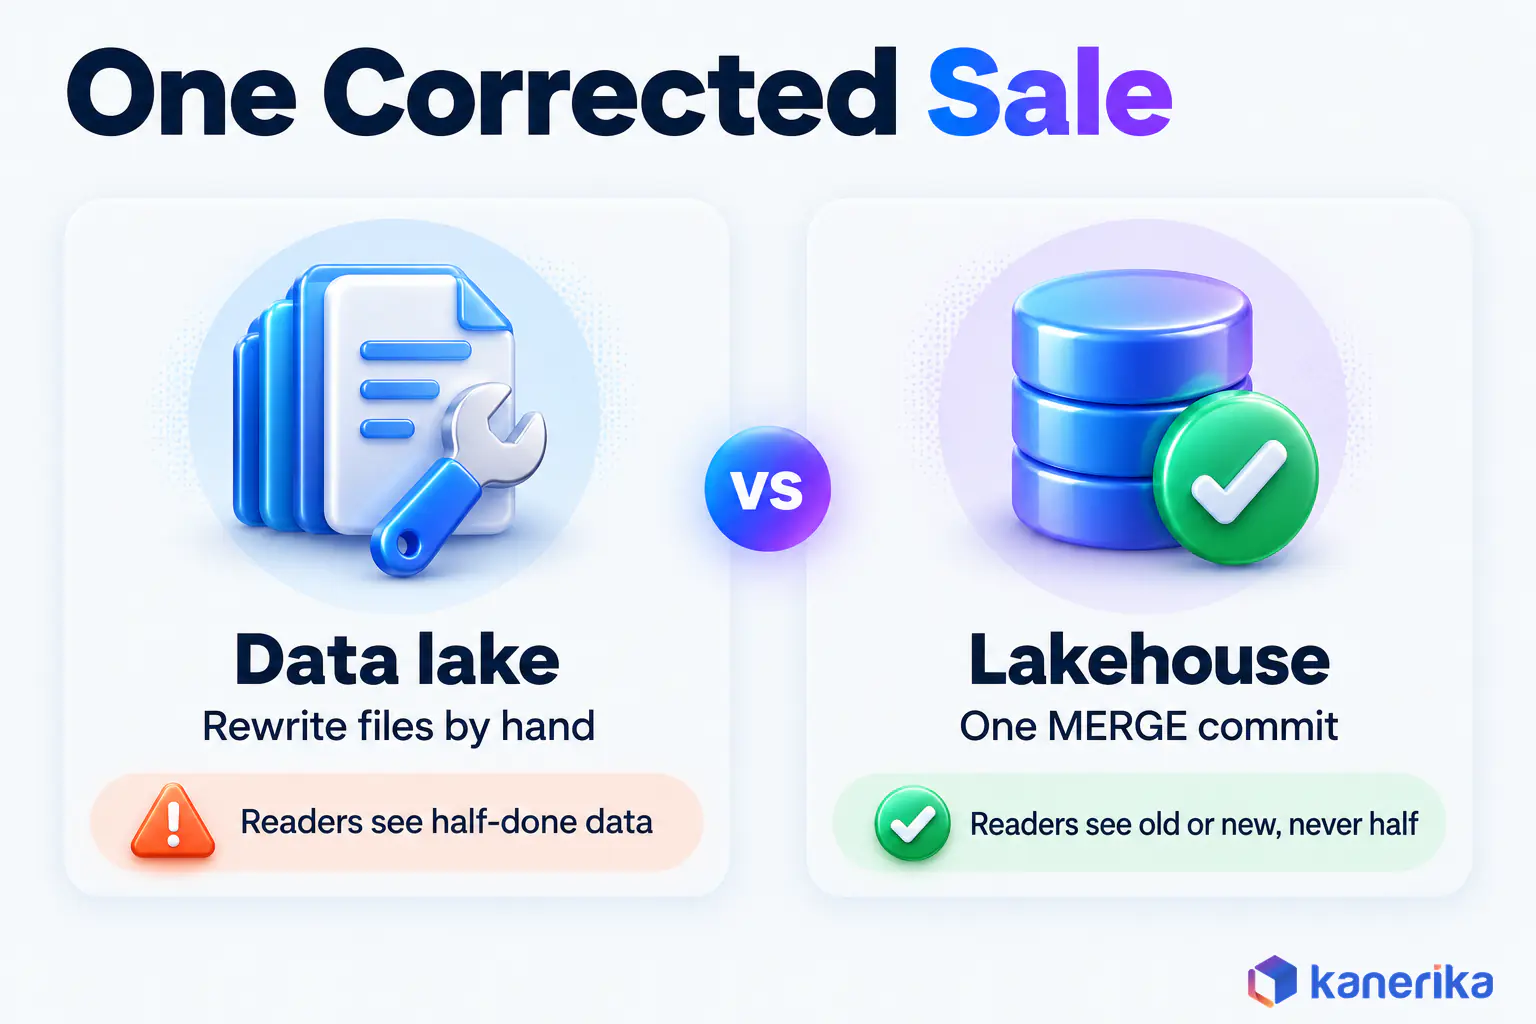
- An engineer finds every file that holds the wrong sale or the customer’s rows. With no index, that can mean scanning a whole partition or more.
- A job rewrites those files without the bad rows and with the fixed amount.
- While the job runs, readers can see a mix of old and new files, so a dashboard that refreshes mid-job shows half-corrected totals.
- If the job fails halfway, someone has to clean up the partial output by hand.
- Afterward there is no built-in record of the table’s earlier state, which makes an audit hard to answer.
So one wrong amount becomes a small engineering project, and the dashboard is wrong while it runs.
The Same Two Changes in a Lakehouse
In a lakehouse, both changes are single statements that commit as one transaction.
-- Correct last Tuesday's sale
MERGE INTO sales AS t
USING sales_corrections AS c
  ON t.order_id = c.order_id
WHEN MATCHED THEN UPDATE SET t.amount = c.amount;

-- Honor a deletion request
DELETE FROM customers WHERE customer_id = 1042;

-- Audit: read the table as it was before the change
SELECT * FROM sales VERSION AS OF 41;
Readers keep seeing the previous version until each commit lands, and then they switch to the new one in a single step. Similarly, if a job fails, nothing is committed. Time travel lets an auditor read version 41 and compare it with the current one.
The syntax above is Delta Lake SQL, and Iceberg supports the same operations with snapshot reads. Microsoft Fabric supports the pattern as well, as our guide to time travel in a Fabric lakehouse shows.
One caution applies to privacy deletes. Time travel keeps old files until a cleanup job removes them. So a deletion is complete only after the retention window passes and a VACUUM or snapshot-expiry job runs. Agree that policy with your compliance team before go-live.
Data Lake vs Lakehouse: Head-to-Head on Five Dimensions
Once you see how changes work, the rest of the comparison follows. The five dimensions below are where the two architectures behave differently in daily operation, and each one ends with a plain verdict.
Reliability and ACID Transactions
ACID stands for atomicity, consistency, isolation and durability. In plain terms, a change either happens fully or not at all, and readers never see it halfway. Delta Lake, Iceberg and Hudi all bring these guarantees to files in object storage.
A plain lake, however, has no such guarantee. Two jobs writing to the same folder can overwrite each other, and a crash leaves partial files behind. Teams work around that with locks, staging folders and naming tricks, and every workaround is code someone must maintain.
Verdict: if more than one job writes to the same data, the lakehouse wins clearly.
Query Performance, Concurrency and Freshness
Speed depends on more than the architecture label. The query engine, file sizes, partitioning and how often small files get compacted all matter, so treat any single speed-up figure with suspicion.
Even so, the table layer gives engines a head start. The log keeps file-level statistics, such as the lowest and highest value of each column in each file. Because of that, a query can skip files that cannot match. A query for last Tuesday’s sales, for example, skips every file whose highest order date is earlier than Tuesday.
Concurrency gets the same boost. Many readers can query one table while a writer commits new data, because each reader sees a consistent version.
Freshness improves too. Streaming jobs can append small batches all day, which keeps dashboards closer to real time than a nightly copy into a warehouse. A raw lake can be quick for one engineer scanning one well-organized dataset. Still, it struggles when dozens of BI users hit the same data at once.
Verdict: for shared SQL and BI, choose the lakehouse; for one-off scans of raw files, the lake is fine.
Governance, Security and Compliance
Data governance is where many lakes fail an audit. Permissions on folders are coarse, so a user can either read the whole sales folder or none of it.
A lakehouse catalog grants access per table, and platforms such as Unity Catalog and Lake Formation support row filters and column masks on top. A regional manager then sees only their region, while a support analyst sees a masked email column. Lineage, audit logs and data classification live in the same place, and identity comes from your provider, such as Microsoft Entra ID on Azure.
Privacy laws add one more test: can you find and delete one person’s data on request? In a lakehouse, that is a DELETE plus a retention policy. In a lake, it is a file-rewrite project every time.
Verdict: for regulated or personal data, the lakehouse is the safer default.
Cost: Compare Total Cost of Ownership, Not Storage Price
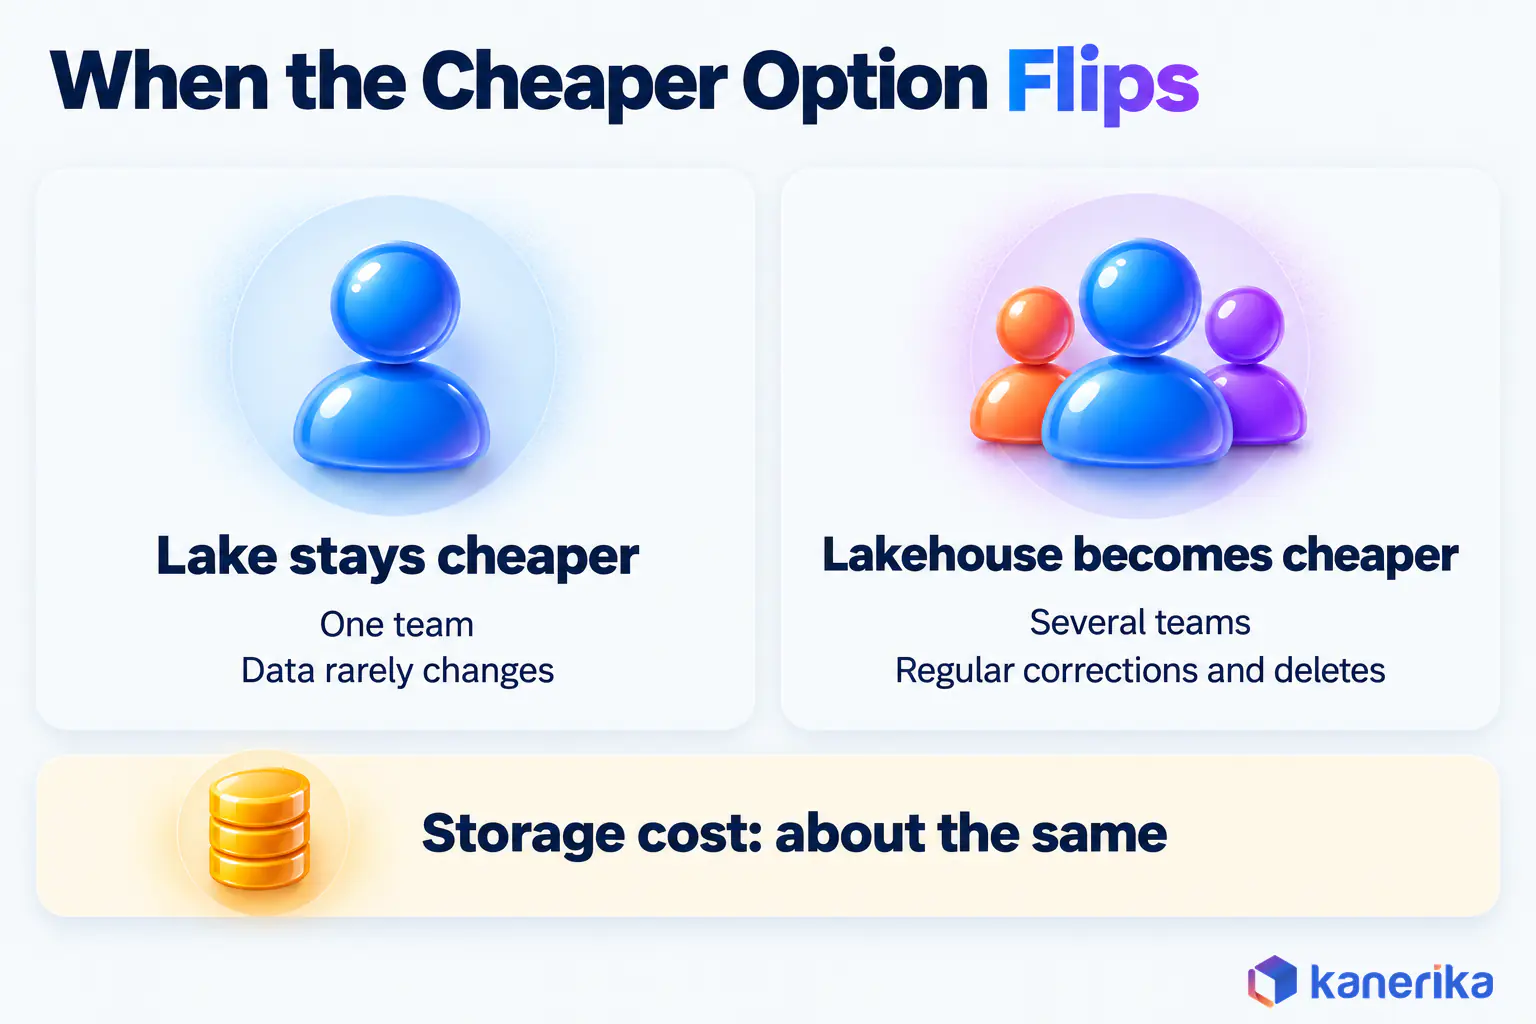
Storage is the line item people quote first, and it is the least useful one here. Both architectures keep data in the same object storage, so the per-terabyte bill is about the same.
The real gap sits in everything around the storage. A lake looks cheap until you count the pipelines that copy data into a warehouse. Then add the engineering hours spent fixing broken folders and the duplicate storage those copies create. A lakehouse brings its own costs, too: compute for compaction and cleanup jobs, a platform subscription and staff who know the table format and catalog.
| Cost line | Data lake | Lakehouse |
|---|---|---|
| Object storage | Low per terabyte | Same storage, plus old versions kept for time travel |
| Compute | Pay per query or job | Queries plus regular compaction and cleanup jobs |
| Data copies | Often a second copy in a warehouse, plus extracts | Usually one governed copy |
| Pipeline upkeep | Custom code for updates, deletes and recovery | Built-in MERGE, DELETE and rollback |
| Governance | Extra tools and manual reviews | Catalog included with most platforms |
| Staff and skills | General cloud and data engineering | Table-format, catalog and platform skills |
Who runs the platform matters as much as which one you pick. A lake usually depends on a few engineers who know the folders by heart. A lakehouse needs people who understand compaction, retention and catalog permissions, so budget for that training before the first workload goes live.
Verdict: a lake stays cheaper only while one team uses the data and nothing has to change. Once a second team or regular corrections arrive, the copies and custom fixes usually cost more than the table layer.
Openness and Vendor Portability
Lock-in was one of the five problems the lakehouse paper set out to fix, and open table formats are the answer. Because the data stays in Parquet with an open log, more than one engine can read it.
The formats are also learning to read each other. Databricks UniForm lets Iceberg clients read Delta Lake tables without rewriting the data files. Snowflake can also query Iceberg tables kept in your own cloud storage through an external volume. On AWS, Amazon S3 Tables provide managed Iceberg tables with automatic compaction.
A raw lake is open too, but only at the file level, since every engine must agree on how to parse the files.
Verdict: both are open, yet the lakehouse is open at the table level, which is the level that matters for shared work.
Where Databricks, Microsoft Fabric, Snowflake and AWS Fit
Every major data platform now sells a lakehouse in some form. They differ mostly in their default table format and catalog. So the table below maps each one and leaves the platform choice to our dedicated comparisons.
| Platform | Table format | Catalog and governance | Where the files live |
|---|---|---|---|
| Databricks | Delta Lake, with Iceberg reads through UniForm | Unity Catalog | Your cloud object storage (S3, ADLS or GCS) |
| Microsoft Fabric | Delta Parquet or Iceberg in OneLake | OneLake catalog and OneLake security (table, row and column roles) | OneLake, built on ADLS |
| Snowflake | Native tables, plus Apache Iceberg tables | Snowflake-managed or external Iceberg catalog | Snowflake storage, or external volumes for Iceberg |
| AWS | Apache Iceberg in S3 Tables, plus Delta Lake and Hudi on S3 | AWS Glue Data Catalog and Lake Formation | Amazon S3 |
Once you settle on a lakehouse, the next call is the platform. For AWS-centered teams, see Databricks vs AWS, and for Microsoft shops, Microsoft Fabric vs Databricks compares the two most common choices. Deeper vendor detail lives in our guides to Databricks lakehouse architecture and the Microsoft Fabric lakehouse.
Datasheet
Snowflake vs Databricks vs Microsoft Fabric Datasheet
Compare the three leading data platforms side by side on architecture, table formats, governance and fit, so the platform choice follows from your workloads.
Get the Datasheet →Data Lake or Lakehouse: Which Should You Choose?
The right answer depends on what happens to your data after it lands. Ask who reads it, how often it changes and what rules it must follow, and the choice usually makes itself.
| Scenario | Pick | Why |
|---|---|---|
| Raw logs, clickstream or IoT data kept for later | Data lake | Data is appended and rarely changed; cheap storage comes first |
| Compliance archive read only during audits | Data lake | Low access, long retention, no updates |
| A data science team exploring a new source | Data lake, or a lakehouse raw layer | Flexibility matters more than governance at this stage |
| Finance and sales dashboards on shared tables | Lakehouse | Many readers need one consistent version |
| Customer data under privacy deletion rules | Lakehouse | Row-level DELETE, audit history and access controls |
| Daily corrections, late records or change data capture | Lakehouse | MERGE handles upserts as single commits |
| Machine learning features shared by several models | Lakehouse | Versioned tables make training data reproducible |
| A small team with one use case and no BI demand | Data lake, for now | A table layer adds work before it adds value |
If your situation mixes several rows, the lakehouse usually wins, because the lake scenarios can live inside it as a raw layer. The reverse is not true, since a plain lake cannot offer transactions to the rows that need them.
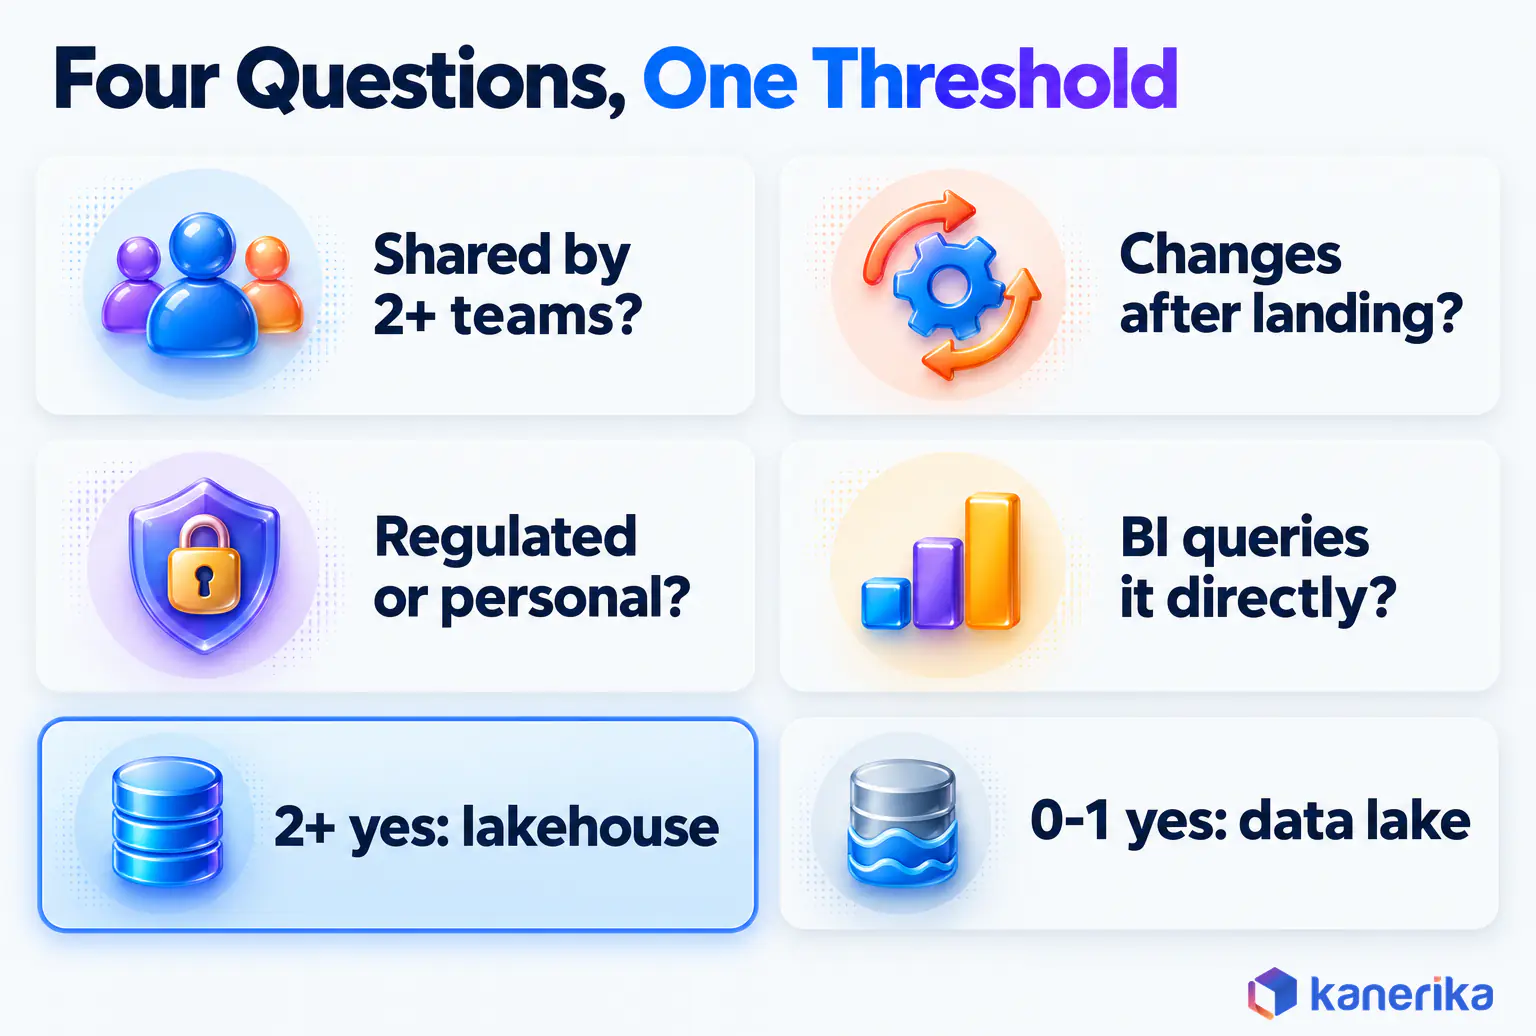
Four Questions That Settle It
When the table does not settle it, four questions will. Answer each one for the workload you plan to move first.
- Do two or more teams read the same data? If yes, lean toward a lakehouse.
- Does the data change after it lands? Updates, deletes or late records point to a lakehouse.
- Is any of it regulated or personal? If yes, you need table-level controls and audit history.
- Do BI users query it directly? If yes, a lakehouse serves them without a separate copy.
Two or more yes answers make a strong case for a lakehouse. Zero or one means a well-run lake is enough for now. Either way, test the answer with a pilot on one workload before you commit a budget.
Moving From a Data Lake to a Lakehouse Without a Big-Bang Migration
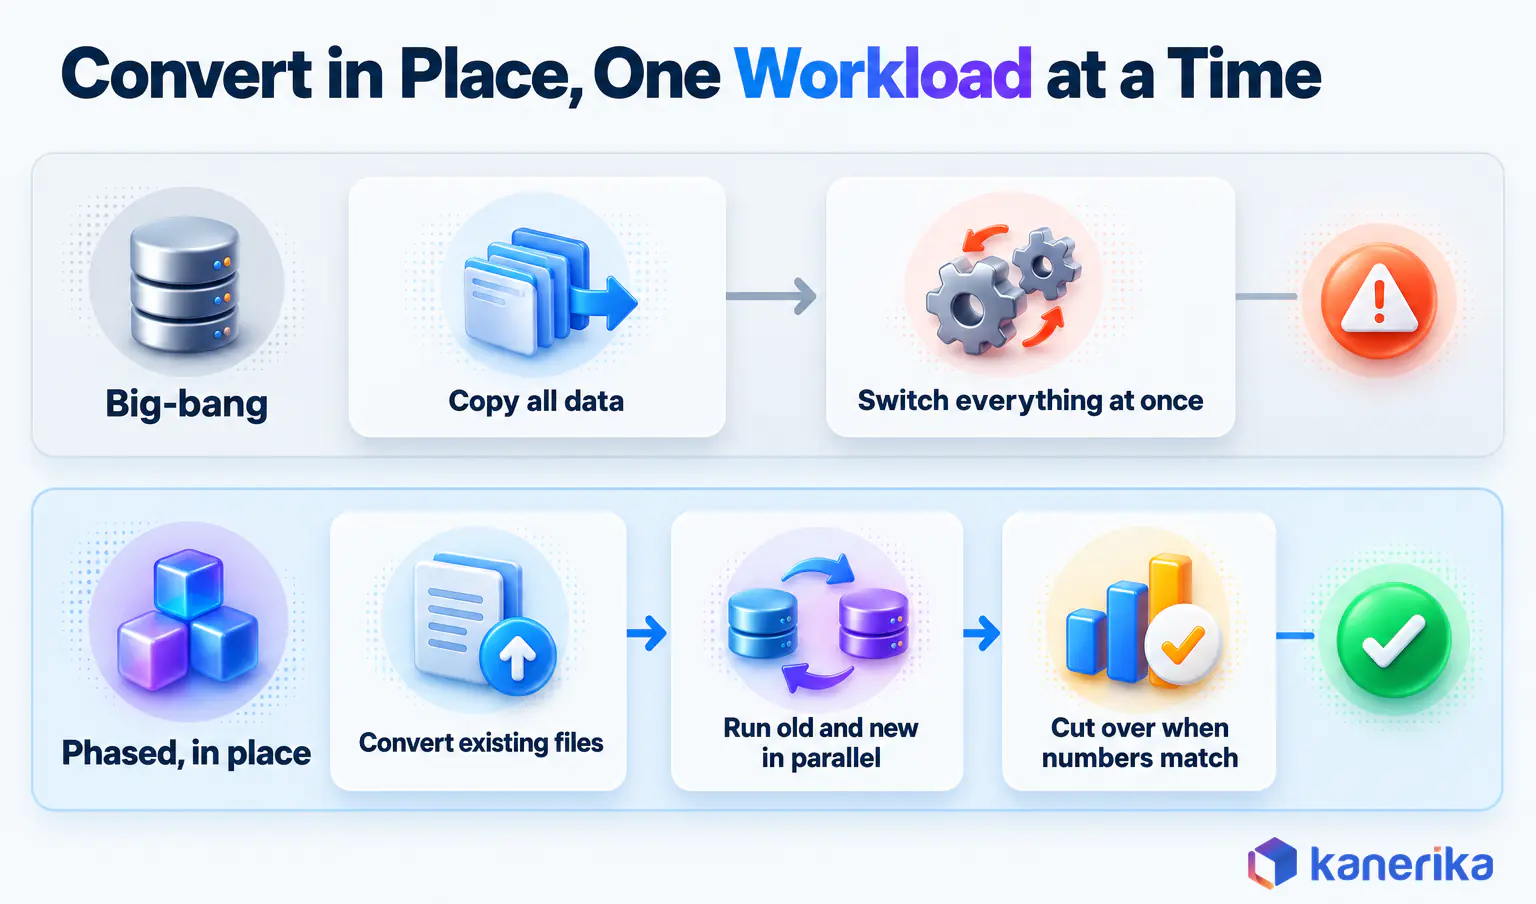
Moving to a lakehouse does not require moving your data. Both architectures use the same object storage. So you can add the table layer on top of files you already have, then switch workloads one at a time.
The path below keeps risk low, since the old pipelines keep running until the new tables prove themselves.
- Pick one high-value workload. Choose a dataset that several teams argue over, such as daily sales or customer records.
- Convert in place. Delta Lake’s CONVERT TO DELTA command and Iceberg’s migrate procedure turn existing Parquet data into tables without copying it.
- Organize in layers. Keep raw data in a bronze layer, cleaned and joined data in silver and business-ready tables in gold. This medallion architecture keeps the lake’s raw role inside the lakehouse.
- Register tables in the catalog. Set owners, permissions and retention before anyone builds a dashboard.
- Run old and new side by side. Compare outputs for a few cycles until the numbers match.
- Cut over and decommission. Point consumers at the new tables, then retire the old pipelines and copies.
-- Delta Lake: turn an existing Parquet folder into a table
-- (add PARTITIONED BY (...) if the folder is partitioned)
CONVERT TO DELTA parquet.`s3://retail-lake/sales/`;

-- Apache Iceberg on Spark: migrate an existing table in place
CALL catalog.system.migrate('retail.sales');
Start where the pain is loudest, because a visible win funds the next step. If your starting point is a warehouse rather than a lake, our guide to data warehouse to data lake migration covers that path.
Plan the people side as carefully as the tables. Name an owner for each gold table, agree who approves schema changes and decide how long old versions stay. Those three choices prevent most of the problems in the next section.
Common Mistakes on Both Sides
Neither architecture fails on its own; the way teams run it decides the outcome. The mistakes below come up again and again, on both sides of the choice.
On the data lake side: most mistakes come from missing ownership and discovery.
- Letting it turn into a swamp. Data lands with no owner, no description and no expiry date.
- Skipping the catalog. Without one of the data catalog tools in place, people cannot find data, so they copy it again.
- Forcing BI onto raw files. Dashboards on raw folders are slow and give inconsistent answers. The BI team’s 7 a.m. half-rewritten extract in the opening story is this mistake.
On the lakehouse side: most mistakes come from building or maintaining more than the workload needs.
- Over-building for day one. A full medallion design for every source, before one workload has proven its value, wastes months.
- Ignoring table maintenance. Without regular compaction, small files slow queries down. Without a VACUUM or snapshot-expiry policy, storage grows and deleted data lingers.
- Treating ACID as data quality. Transactions stop half-written data, not wrong data. You still need tests, freshness checks and data observability to catch bad values.
Overall, the common thread is ownership. Every table, in either architecture, needs a named owner, a clear purpose and a rule for how long it lives.
How Kanerika Builds Lakehouses That Hold Up in Production
Kanerika helps enterprises decide whether a lakehouse is worth it, then builds one workload at a time. Our Databricks and Microsoft Fabric practices stay platform-neutral at the decision stage, so the platform follows from your workloads, skills and existing cloud.
- Assess. Map sources, consumers and pain points, and score which workloads need transactions, governance or shared BI.
- Design. Choose the table format, catalog and layer design, and set retention and maintenance policies up front.
- Govern. Register every table with an owner, access rules and lineage before users arrive.
- Migrate one workload. Convert in place, run in parallel, prove the numbers match, then cut over.
A large US retail chain, the one in the case study card above, shows that approach in practice. Its data sat in PostgreSQL and Cassandra, and it needed a governed lakehouse without taking applications offline.
Kanerika moved the data into Delta Lake tables under Unity Catalog. Sources stayed live through timestamp-based change data capture and Delta MERGE, and the team cut over one application at a time.
That is the one-workload-at-a-time path from the migration section, applied to live production systems. The card lists the outcomes, and the full case study has the details.
If you are weighing a data lake vs lakehouse move, our data modernization services start with the same assessment.
Kanerika Service
Databricks Consulting and Implementation
Kanerika designs and builds Databricks lakehouses with Delta Lake tables, Unity Catalog governance and phased migrations that keep source systems live until cutover.
Explore Databricks ServicesFinal Verdict: Data Lake or Lakehouse?
Choose a lakehouse when several teams need reliable SQL, BI and AI on shared data that changes, is regulated or must be audited. Keep a plain data lake for raw retention, archives and early exploration, where cheap storage matters more than control. Many enterprises end up with both, since a lakehouse keeps the lake as its raw layer. So in the data lake vs lakehouse decision, the lake fits data that lands and rests, and the lakehouse fits data that many people change and trust.
Frequently Asked Questions
Is a lakehouse the same as a data lake?
No. A lakehouse is built on a data lake but adds two layers. An open table format such as Delta Lake, Apache Iceberg or Apache Hudi brings ACID transactions, updates, deletes and time travel to the files. A catalog then adds table names, permissions and lineage, so many teams can trust and share the same data.
Is a data lakehouse better than a data lake?
It is better for shared, changing data. When several teams run SQL, BI or AI on the same tables, or when records get corrected and deleted, a lakehouse gives consistent answers and audit history. For raw logs, archives and early exploration that one team owns, a plain data lake is simpler and does the job well.
What is the difference between Apache Iceberg and Delta Lake?
Both are open table formats that add ACID transactions and time travel to Parquet files. Delta Lake is a Linux Foundation project and the default format in Databricks. Apache Iceberg is an Apache project that engines such as Spark, Trino, Flink, Presto and Hive can read. Databricks UniForm also lets Iceberg clients read Delta tables.
Is Microsoft Fabric OneLake a data lake or a lakehouse?
OneLake is the single data lake that every Fabric tenant includes, built on Azure Data Lake Storage. It stores tables in Delta Parquet or Iceberg format, so Fabric lakehouse items, warehouses and Power BI read the same open tables. In practice, OneLake is the storage layer and the Fabric lakehouse is the table and catalog layer above it.
Can Snowflake work as a data lake or lakehouse?
Snowflake can act as part of a lakehouse. Besides its native tables, it supports Apache Iceberg tables whose data stays in cloud storage you manage, connected through an external volume. That lets Snowflake and other engines share the same open tables. It is not a raw file store, so most teams still keep a separate lake for raw files.
What is an example of a data lakehouse?
A retailer might keep raw point-of-sale files in Amazon S3, convert the sales data into Delta Lake or Iceberg tables and govern them in a catalog. Finance dashboards, a demand forecasting model and an AI assistant then read the same tables. Databricks, Microsoft Fabric and AWS with S3 Tables are common platforms for this pattern.
What is the difference between a data lake and a data swamp?
A data lake is organized storage where data has owners, descriptions and a known source. A data swamp is a lake that has decayed, with undocumented files, duplicate copies and no quality checks, so people cannot find or trust anything. A catalog, clear ownership and retention rules keep a lake from turning into a swamp.
Does a lakehouse replace a data warehouse?
For many workloads it can, because a lakehouse supports SQL, BI and ACID transactions on governed tables. Some teams still keep a warehouse for very high-concurrency reporting or existing tools, often reading the same open tables. The choice depends on workload mix, skills and current investments, so plan it per workload rather than as one switch.
When should an enterprise keep a data lake instead of moving to a lakehouse?
Keep a plain data lake when the data is appended and rarely changed, one team owns it and nobody runs BI on it directly. Raw logs, IoT readings, compliance archives and early exploration sets are good examples. If two or more teams start sharing the data, or it needs corrections and deletes, plan a lakehouse.
What is the medallion architecture in a lakehouse?
The medallion architecture organizes lakehouse tables into three layers. Bronze holds raw data as it arrived, silver holds cleaned and joined data, and gold holds business-ready tables for reports and models. Each layer is built from the one before, which keeps the raw history while giving BI and AI teams trusted, curated tables.
Is Databricks a data lake or a lakehouse?
Databricks is a lakehouse platform. It stores data in your own cloud object storage, such as Amazon S3, ADLS or Google Cloud Storage, and manages it as Delta Lake tables governed by Unity Catalog. Azure Databricks is the same platform on Azure, so it also works as a lakehouse on top of an Azure data lake.
What are the disadvantages of a data lake?
A plain data lake has no transactions, so readers can see half-written data and failed jobs leave partial files behind. Updates and deletes mean rewriting files by hand. Without a catalog, data becomes hard to find and trust, teams copy it again, and the lake can decay into a swamp with no owners or quality checks.
What are the disadvantages of a data lakehouse?
A lakehouse adds moving parts. Tables need regular compaction and cleanup jobs, old versions add some storage, and the team must learn a table format, a catalog and a platform. Building a full layered design before any workload proves its value can waste months, and transactions alone do not guarantee correct data, so quality checks still matter.
Can an existing data lake be converted into a lakehouse?
Yes, usually without copying the data. Delta Lake’s CONVERT TO DELTA command and Apache Iceberg’s migrate procedure turn existing Parquet data into tables in place. Teams then register those tables in a catalog, run the old and new pipelines side by side for a few cycles and switch consumers over one workload at a time.
Is a lakehouse more expensive than a data lake?
Storage costs about the same, because both use the same object storage. A lakehouse adds compute for compaction, a platform subscription and new skills. A plain lake often hides its cost in duplicate warehouse copies, custom pipelines for corrections and engineering time spent on broken folders. Compare total cost of ownership for your workloads rather than storage price.
Do data lakes support ACID transactions?
A plain data lake does not. Object storage writes files one at a time, so two jobs can overwrite each other and readers can see partial results. ACID transactions arrive only when you add an open table format such as Delta Lake, Apache Iceberg or Apache Hudi, which turns the lake into a lakehouse with a transaction log.
Can a data lake support SQL queries?
Yes. Engines such as Spark, Trino and Presto can run SQL directly on files in a data lake by applying a schema when the data is read. The catch is consistency and speed. Without a table layer, queries may read half-written folders and scan more files than needed, which is why shared BI usually moves to a lakehouse.
Is Delta Lake the same as a data lakehouse?
Not exactly. Delta Lake is an open table format, one building block of a lakehouse. It adds a transaction log, ACID guarantees and time travel to Parquet files. A full lakehouse also needs object storage underneath, a catalog for permissions and lineage, and query engines for SQL, BI and machine learning on top.