TL;DR
An AI pilot is a short trial run of an AI system inside a real workflow. A small group of users work with real company data for a set number of weeks. The pilot has one job. It has to tell you whether to scale the system, change it, or stop. Most pilots stall because nobody agreed that decision rule up front. Pick one workflow, measure the baseline first, and set the exit test on day one.
Key Takeaways
- What makes something a pilot is the decision attached to its end date. Size and technology are secondary.
- The famous AI failure numbers measure different things, and three of the four most-quoted ones do not say what people think they say.
- Score candidate use cases on business value, data availability, process maturity, adoption readiness and technical feasibility before anyone writes code.
- Agent pilots need a different metric set than model pilots, because task completion and intervention rate matter more than accuracy.
- Build the evaluation harness before the system, or you will have no way to read the result.
- A pilot should end in one of three verdicts, and each verdict needs different evidence to be credible.
The Pilot Is Not the Experiment. The Decision Is.
S&P Global Market Intelligence surveyed more than 1,000 organizations across North America and Europe in 2025 and found that 42% of them scrapped most of their AI initiatives that year, up from 17% the year before. The same research found the average organization abandoned 46% of its AI proofs of concept before they reached production.
Read those two numbers together and a pattern appears. Companies are not failing to build AI. They are failing to finish deciding about it. That gap between activity and outcome is the defining problem of enterprise AI right now.
A pilot that runs for four months, produces a positive-sounding readout and then quietly stops being mentioned has not failed technically. It failed because nothing in its design forced a verdict. This guide is about designing the verdict first and the system second.
What Is an AI Pilot?
An AI pilot is a controlled deployment of an AI system into a real business workflow, with a limited user group, real enterprise data and a fixed end date. It exists to test one thing, which is whether the system changes a business outcome. Whether the technology can be made to run is a question the earlier stages already answered.
That distinction is the whole job. A trained model that answers 200 test questions correctly has proved something about the model. A pilot proves something about the organization around it.
AI Pilot Meaning in Plain Terms
Strip away the jargon and an AI pilot is a supervised trial run. A small group of people use the system to do their actual job for a set number of weeks, on the company’s actual data, while somebody records what changed.
Two things make it a pilot rather than an experiment. It runs inside the real workflow instead of alongside it, and it has a decision attached to its end date.
AI Pilot Project or AI Pilot Program? The Difference Matters
An AI pilot project is one use case, one team and one outcome. An AI pilot program is a portfolio of them, run under shared standards, with a common intake process, a shared evaluation approach and a governance model that applies to all of them.
Most organizations should run two or three pilot projects well before they try to stand up a program. A program built on top of inconclusive projects inherits the same problem at a larger scale, and it becomes much harder to cancel. The program-level view, sequenced across quarters, is covered in Kanerika’s AI implementation roadmap.
The Four Questions a 2026 Pilot Has to Answer
Before a pilot is worth running, it should be aimed at four specific answers.
- Does it move the process metric? Cycle time, error rate, cost per transaction, or whichever number the workflow owner is already measured on.
- Will the people in the workflow use it? Adoption is measured by behaviour, not by survey responses.
- Can it clear governance? Data residency, access control, auditability and human oversight, tested during the pilot rather than discovered after it.
- Can the company afford to run it every day? Inference cost, support load and monitoring, at the volume production would actually see.
Where the Pilot Sits in the Sequence
Teams use prototype, proof of concept and pilot interchangeably, and that vagueness is expensive. Each stage answers a different question and each has a different sign-off. Kanerika covers the upstream stages in depth in its guides to the AI proof of concept and the difference between a proof of concept, a prototype and an MVP, so this table is the short version.
Table 1: The five stages and what each one is allowed to conclude
| Stage | Question it answers | Environment | Who signs it off | What it produces |
|---|---|---|---|---|
| Idea | Is this worth exploring? | A document | Business sponsor | A business case |
| Prototype | Can we build the interaction? | Sandbox, synthetic data | Engineering lead | A demonstrable interface |
| Proof of concept | Does the capability work on our data? | Isolated test set | Data science lead | Feasibility evidence |
| Pilot | Does it change the workflow outcome? | Live workflow, limited users | Workflow owner plus risk | A scale, iterate or stop verdict |
| Production | Can we operate it every day? | Full enterprise environment | Operations and security | Sustained business value |
The Missing Piece in Most Pilots
Look down the sign-off column. The pilot row is the only one where the person accountable is the business owner of the workflow rather than a technologist. When a pilot is run entirely by a data team with a friendly business observer, nobody in the room has the authority to say stop, and so nobody does.
Write the exit decision into the charter and name the person who makes it. That one sentence prevents more wasted quarters than any architectural choice in this article.
Case Study
36% Cost Savings With AI and ML Powered RPA in Insurance
An insurer needed fraud detection that held up on real claim volumes rather than on a sample. See what was measured and what the rollout changed.
Read the Case Study →What the AI Pilot Failure Statistics Actually Measured
Four numbers dominate every conversation about AI pilots. They get quoted interchangeably, as if they all say the same thing. They do not, and using the wrong one in a steering committee will cost you credibility the first time somebody checks.
MIT Project NANDA and the 95% Figure
MIT Media Lab’s Project NANDA published The GenAI Divide: State of AI in Business 2025, drawing on 52 executive interviews, a survey of 153 leaders and an analysis of roughly 300 publicly disclosed AI deployments. Its headline finding is that 95% of the organizations studied saw no measurable profit and loss impact from their generative AI investment.
That is a statement about measurable financial return. It says nothing about how many pilots crashed. A pilot can run perfectly, deliver the capability it promised, and still sit inside that 95% because the organization never connected it to a P&L line. The report’s own diagnosis points at learning and workflow integration as the binding constraint, with model quality well behind them.
S&P Global on Abandonment
The S&P Global Market Intelligence survey cited at the top of this article measures something different again. It counts initiatives the company walked away from, at 42% in 2025 against 17% in 2024, with 46% of proofs of concept abandoned before production. Those are investment decisions, and a rising abandonment rate is not automatically bad news. An organization that kills 46% of its proofs of concept on evidence is doing better than one that keeps all of them alive on hope.
The Two Gartner Predictions
Gartner predicted in July 2024 that at least 30% of generative AI projects would be abandoned after proof of concept by the end of 2025. The reasons Gartner named were poor data quality, inadequate risk controls, escalating costs and unclear business value. It was a prediction about generative AI specifically, and it was about the PoC gate, not about all AI work.
The newer and more relevant one for anyone planning an agent pilot came in June 2025, when Gartner predicted that over 40% of agentic AI projects will be canceled by the end of 2027, again citing escalating costs, unclear business value and inadequate risk controls. Gartner also flagged agent washing, estimating that only around 130 of the thousands of vendors marketing agentic products were building genuinely agentic systems.
What RAND Actually Found
The line “more than 80% of AI projects fail” is usually credited to RAND. RAND’s report The Root Causes of Failure for Artificial Intelligence Projects and How They Can Succeed, published in August 2024, does contain that sentence, but it is phrased as “by some estimates” and footnoted to other people’s work. It is background context that RAND borrowed from elsewhere.
What RAND itself contributed is more useful anyway. The authors interviewed practitioners with years of applied AI experience and identified the recurring organizational anti-patterns behind failure, including misunderstanding the problem, insufficient or unsuitable data, chasing the technology rather than the problem, missing infrastructure, and applying AI to problems that are simply too hard for it.
Table 2: The four statistics side by side
| Statistic | What it measured | What it does not mean | Source and date |
|---|---|---|---|
| 95% | Organizations with no measurable P&L impact from GenAI spend | That 95% of pilots broke or were cancelled | MIT Project NANDA, 2025 |
| 42% and 46% | Companies abandoning most AI initiatives, and the share of PoCs dropped | That the technology did not work | S&P Global Market Intelligence, 2025 |
| 30% and 40% | Forward predictions on GenAI abandonment after PoC, and agentic project cancellation | An observed count of failures | Gartner, July 2024 and June 2025 |
| Over 80% | A third-party estimate RAND quoted as context | A RAND finding | RAND, August 2024 |
The practical use of all this is narrow but real. When you set a pilot’s success bar, you are implicitly choosing which of these outcomes you are trying to avoid. Avoiding the 95% means designing for a P&L line from day one. Avoiding the 40% means budgeting for the cost and the controls before the agent is built.
Choosing the Right AI Pilot Project
Almost every guide says to start with a business problem rather than an AI capability. Very few give you an instrument for deciding between the eleven business problems your leadership team will suggest in the first workshop.
Score Every Candidate on Five Factors
Rate each candidate from 1 to 5 on all five, and refuse to average them. A 1 on any single factor is a disqualifier, because that factor will be the thing that kills the pilot regardless of how strong the other four are.
Table 3: The five-factor pilot scoring model
| Factor | The question | What a score of 1 looks like |
|---|---|---|
| Business value | Does solving this show up in a number someone owns? | Nobody can name the metric it improves |
| Data availability | Does the data exist, and can this team legally reach it? | Access needs a new legal agreement |
| Process maturity | Is the workflow stable enough to measure against? | Every region does it differently |
| Adoption readiness | Will the people doing the work change how they work? | The team believes the tool is there to replace them |
| Technical feasibility | Can a current model do this reliably enough? | The required accuracy has no tolerance for error |
Map the Survivors on Impact and Feasibility
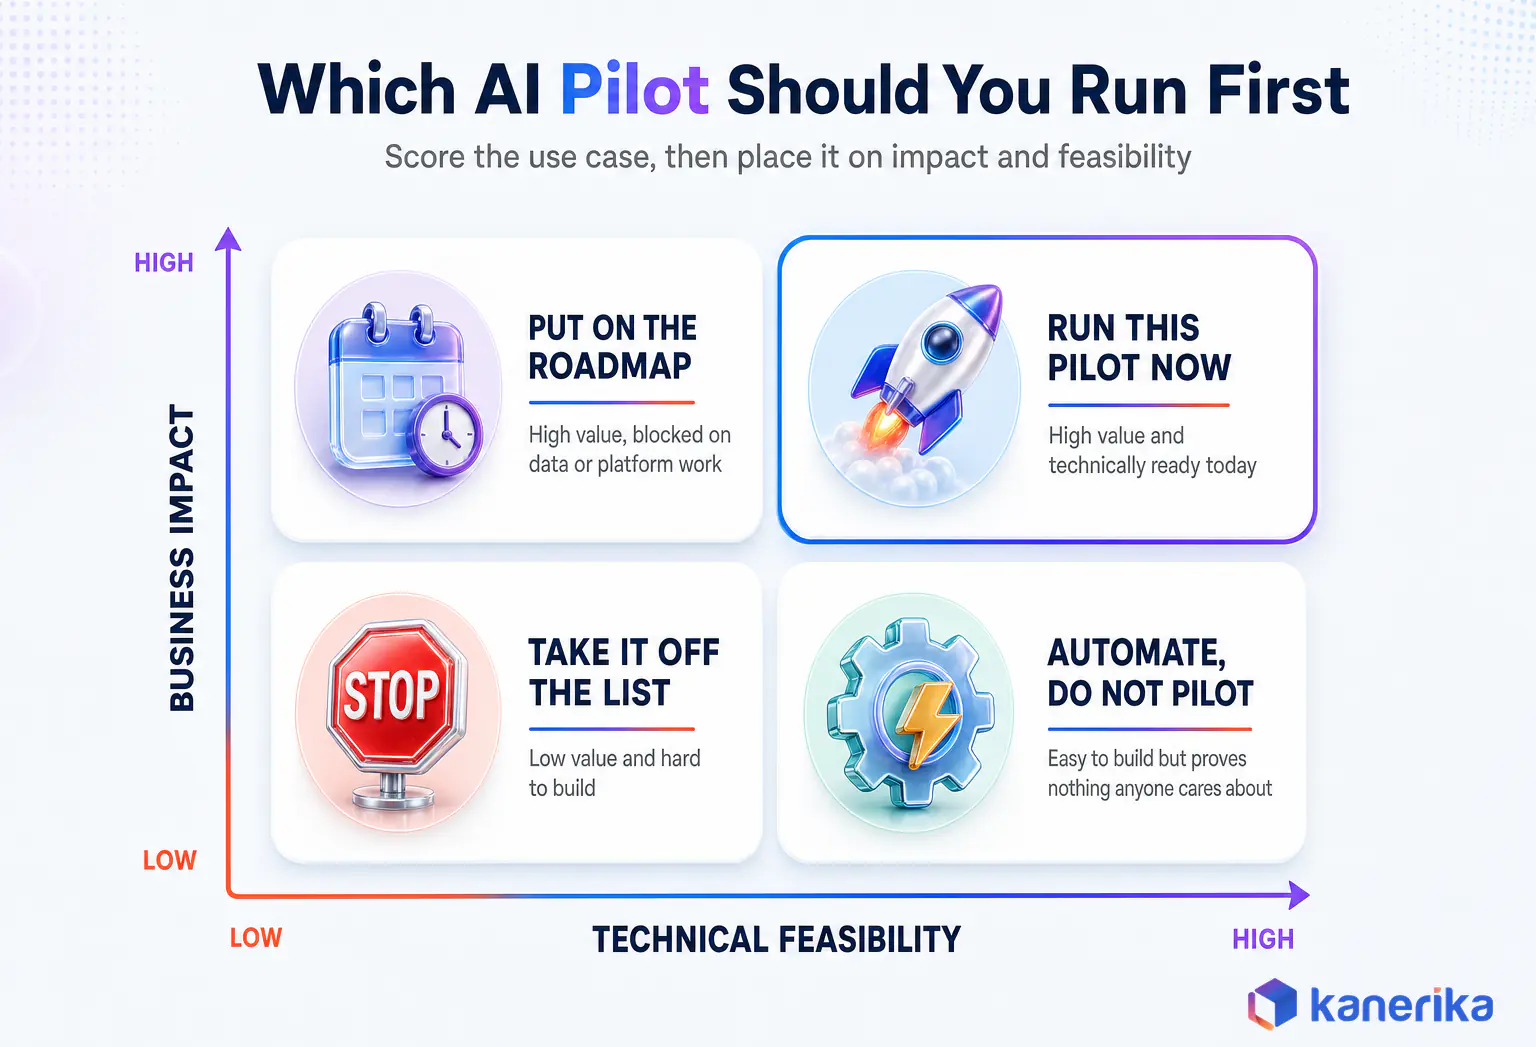
Plot whatever survives the scoring on two axes, business impact and technical feasibility. High impact with high feasibility is the pilot you run now. High impact with low feasibility goes on the roadmap behind a data or platform investment. Low impact with high feasibility is a good automation candidate but a poor pilot, because winning it proves nothing anyone cares about. Low impact with low feasibility comes off the list.
Document intelligence, customer service triage, analyst-facing data assistants and predictive maintenance keep landing in the top-right quadrant for enterprises because they have abundant historical data, a tolerant error profile and an owner who already reports a cycle-time number.
Keep the First One Small Enough to Finish
Begin with manageable pilot projects that require fewer resources, allowing for testing and validation before committing to larger investments. You can even buy another domain that isn’t related to your brand name to test whether a strategy works, and then integrate it into your main site once you confirm the results.
The same logic applies inside the enterprise. One team, one workflow, one data source and one measurable outcome will teach you more in eight weeks than a three-department programme will teach you in nine months.
Six Questions to Answer Before Approval
- Which decision or workflow step changes, and how will we see that it changed?
- Who owns the outcome after the pilot team goes away?
- Which single metric are we moving, and what is its value today?
- What data does this need, and who approves that access?
- What happens operationally when the AI is wrong?
- What ends this pilot, in a number, on a date?
Checklist
Enterprise AI Readiness Before You Approve a Pilot
Work through the data, platform, governance and skills questions a pilot will hit in week three, while it is still cheap to answer them.
Get the Checklist →Writing the Pilot Charter
A pilot charter is one page. It is the artifact that turns a good intention into something that can be audited later, and it is the single most reliable predictor of whether the pilot ends in a decision.
Table 4: The seven-field pilot charter
| Field | What goes in it | Who owns the answer |
|---|---|---|
| Problem | The workflow step and the cost of it today | Workflow owner |
| Users | Named people, not a department | Workflow owner |
| Data | Sources, sensitivity class, approval status | Data owner and privacy |
| Boundary | What is explicitly out of scope | Pilot lead |
| Duration | Start date and hard end date | Sponsor |
| Success metrics | Baseline value and target value for each | Workflow owner and analytics |
| Exit criteria | The thresholds that trigger scale, iterate or stop | Sponsor |
Two fields do most of the work. The boundary field stops the pilot from quietly absorbing adjacent problems, which is how an eight-week pilot becomes a six-month project. The exit criteria field is what makes the final meeting short.
Agentic AI Pilots Are Not Model Pilots
Pilot design changed in 2025 and 2026 because the thing being piloted changed. A predictive model produces a number that a human then acts on. An agent takes actions across systems on its own, which moves the risk from being wrong to doing something wrong. The type of agent you are piloting changes how much of that risk you are carrying.
Table 5: Traditional ML pilot compared with an agentic pilot
| Dimension | Traditional ML pilot | Agentic AI pilot |
|---|---|---|
| What it does | Predicts or classifies | Executes a multi-step workflow |
| Behaviour | Fixed once trained | Chooses a different path each run |
| Primary metric | Model accuracy | Task completion rate |
| System surface | One or two integrations | Many tools, APIs and write permissions |
| Evaluation | Offline, against a held-out set | Continuous, against live traces |
| Main risk | A wrong prediction | A wrong action that is hard to reverse |
The Metrics That Replace Accuracy
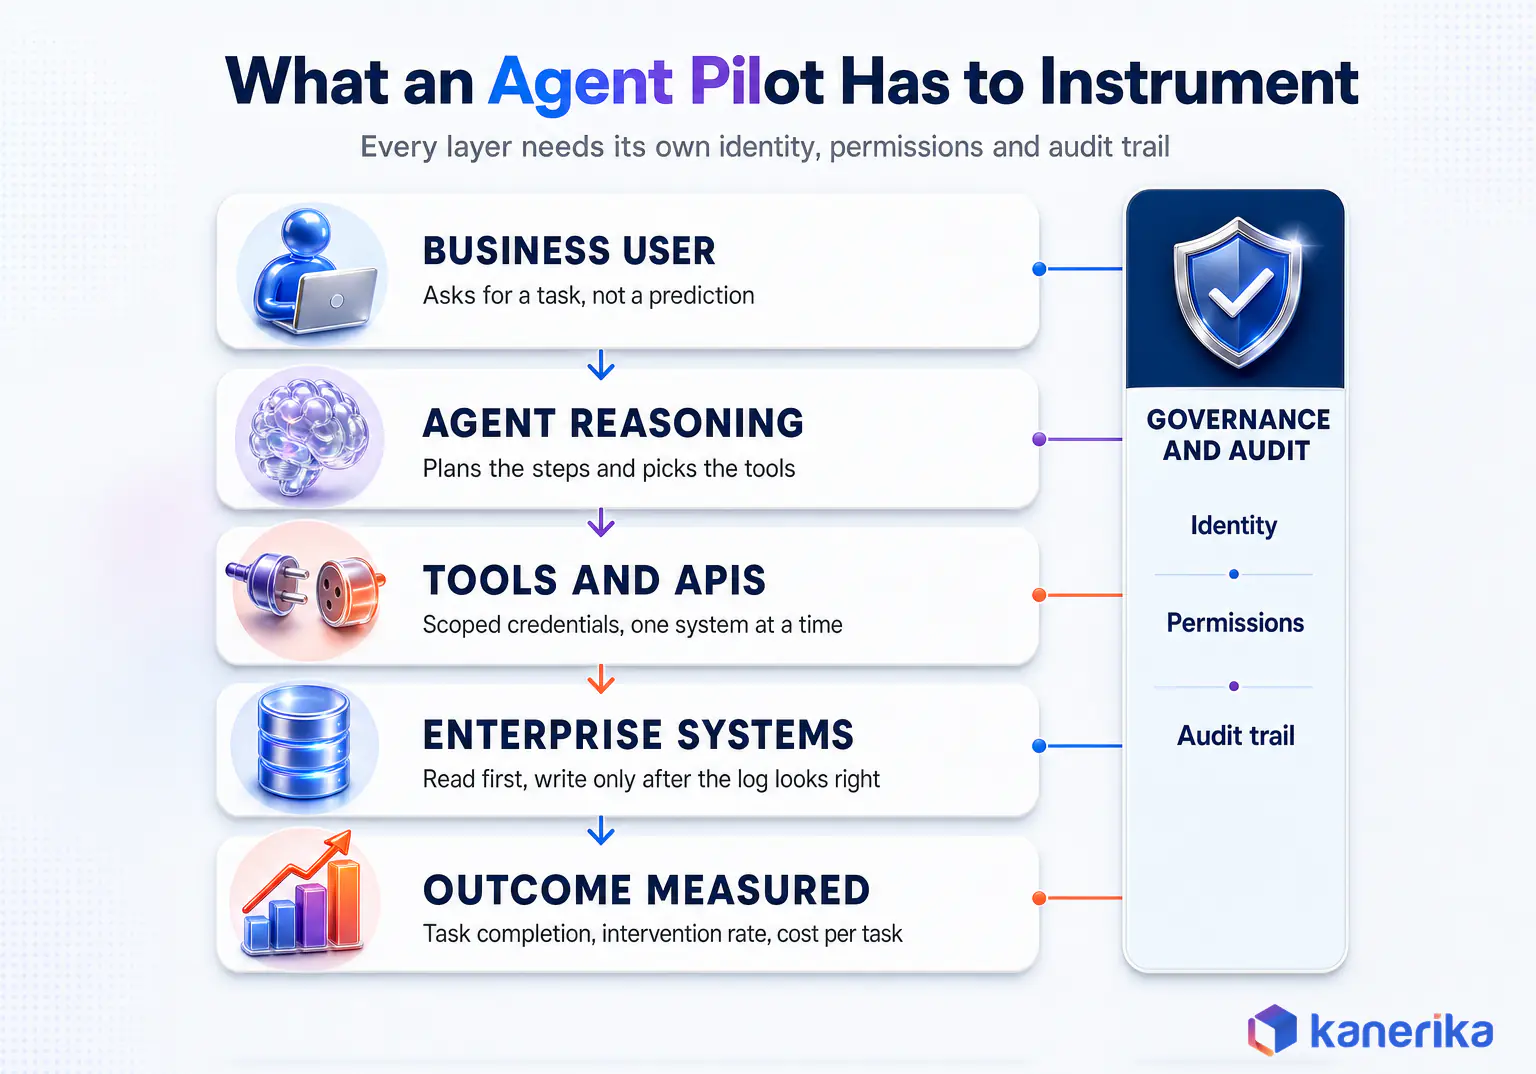
Accuracy is close to meaningless for an agent, because an agent can take a perfectly accurate first step and still fail the task. Instrument these instead.
- Task completion rate. The share of assigned tasks the agent finished end to end without help.
- Human intervention rate. How often a person had to step in, and at which step.
- Tool selection accuracy. Whether the agent reached for the right system at the right moment.
- Escalation quality. Whether the cases it handed to a human were the ones that genuinely needed one.
- Cost per completed task. Tokens, tool calls and retries, divided by tasks actually finished.
- Safety failures. Any action taken outside its permitted scope, counted rather than described.
Give the Agent Access in Stages
Start an agent pilot in read-only mode against production data, with every intended action logged but not executed. Compare that log against what the humans actually did. Only once the proposed-action log looks sane should the agent get write permission, and then to one system at a time.
Each stage needs its own identity, its own scoped credentials and its own audit trail, which is where AI governance tooling starts earning its place in a pilot. An agent that shares a service account with three other systems cannot be evaluated, because you cannot attribute what it did. Kanerika covers the controls in more depth in its guide to agentic AI governance.
Build the Evaluation Harness Before the System
The most common sequencing mistake in AI pilots is building the system, showing it to people, and then trying to work out how to score it. By then the only available evidence is opinion, and opinion is what produces a readout nobody can act on.
Why the Harness Comes First
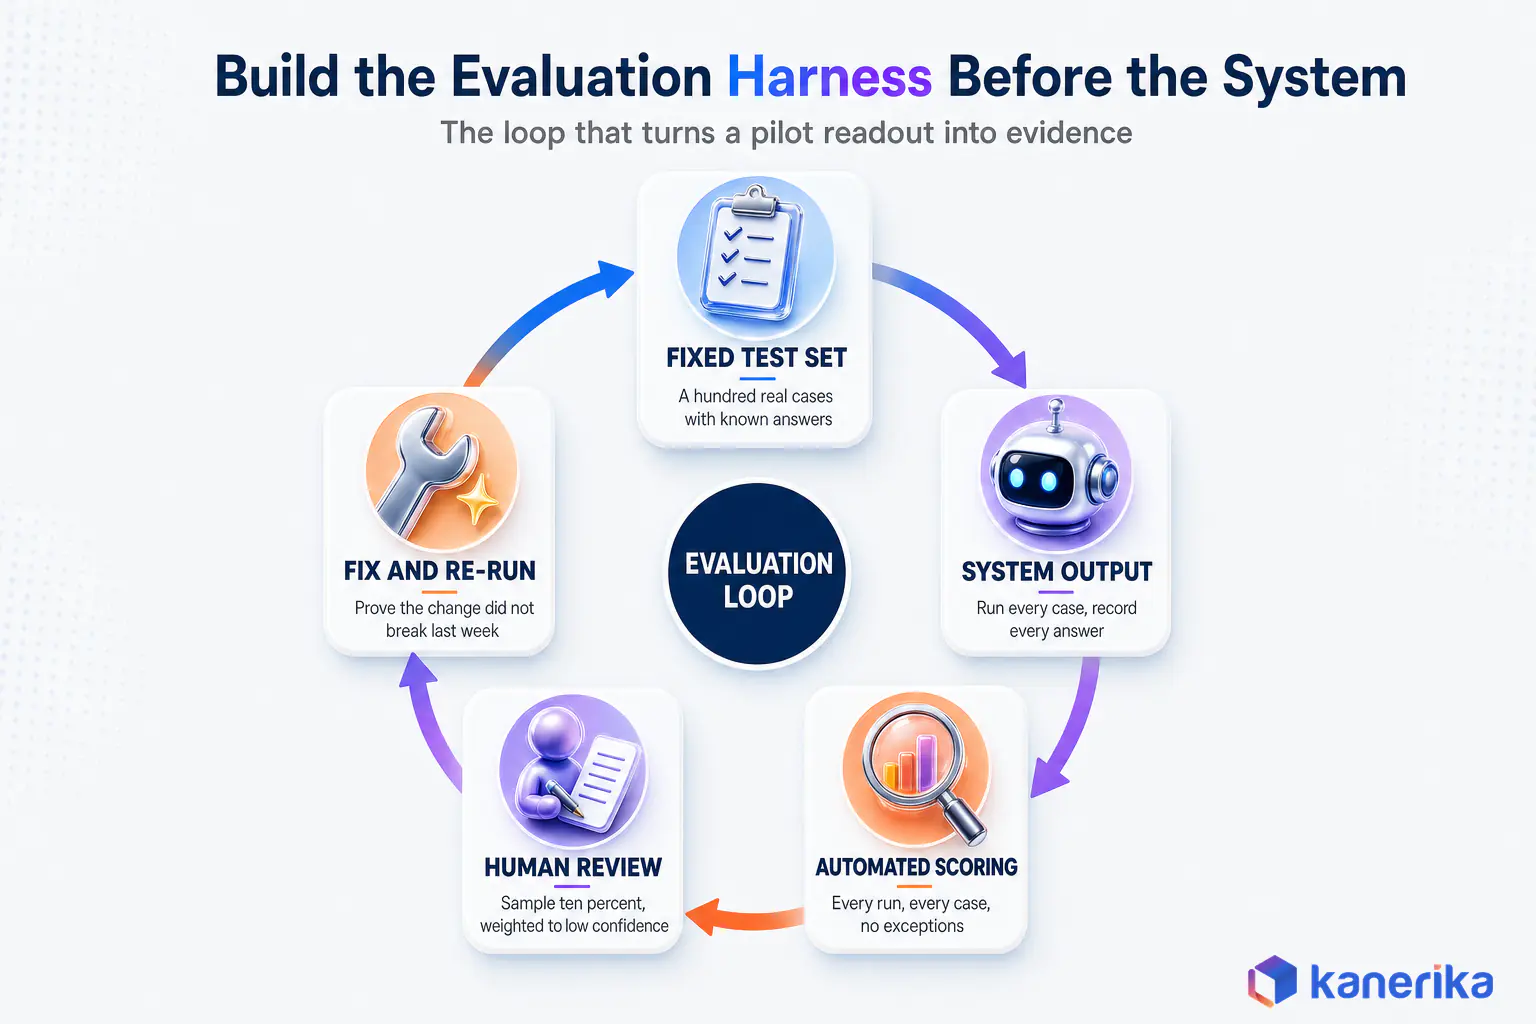
An evaluation harness is a fixed set of representative cases, an expected outcome for each, and an automated way to run the system against them and record the result. Building it first forces the team to define correctness while it is still cheap to argue about. It also gives you a regression test, so a prompt change in week six can be shown not to have broken week two.
The harness does not have to be large. A hundred well-chosen cases drawn from real historical work will surface more than a thousand synthetic ones.
What to Measure for an LLM Pilot
- Factual correctness against a known answer
- Hallucination rate, counted as claims not supported by the retrieved source
- Retrieval quality, measured separately from generation quality
- Consistency across repeated runs of the same input
- Refusal and safety behaviour on the edge cases your compliance team cares about
Separating retrieval from generation matters more than teams expect. Most answers that look like model failures turn out to be retrieval failures. The fix usually lives in the data layer. On retrieval-augmented systems this is where most of the improvement actually comes from.
Automated Scoring and Human Review
Automated scoring handles volume and regression. Human review handles judgement, and it is the only thing that catches an answer that is technically correct and practically useless. A workable ratio for a pilot is automated scoring on every run, with a sampled human review of perhaps 10% of cases weekly, weighted toward the cases the automated scorer was least confident about.
Record who reviewed what. When the steering committee asks how you know the system is good, the answer should be a count, not an impression.
Data and Governance Prerequisites, and the 2026 Regulatory Clock
Pilots fail on data far more often than on models. The failure is rarely dramatic. The data exists, but nobody owns it, or it takes five weeks to get approval, or the field the workflow depends on is populated in three different formats across two regions.
The Data Readiness Gate
Five things need to be true before a pilot starts. The data is accurate and complete enough for the decision being automated, because poor data quality is the most common reason a working model produces unusable output. Access is granted and scoped. Lineage is traceable, so an auditor can see where an answer came from. Sensitive fields are classified and handled. An API or connector exists, so the pilot is not running on a quarterly CSV export.
A fuller version of this gate, with seven dimensions and a scoring rubric, is set out in the AI readiness assessment framework.
What the EU AI Act Requires of a Pilot Right Now
Anyone running a pilot that touches EU users or EU data needs the current timeline rather than the one that was circulating in 2025, because it moved this year.
The AI Omnibus, which entered into force on 27 July 2026, deferred the high-risk obligations. Standalone Annex III high-risk systems now apply from 2 December 2027, and AI embedded in regulated products under Annex I from 2 August 2028. What did not move is Article 50.
The transparency duties for AI systems that interact with people or generate synthetic content applied from 2 August 2026, with a short grace period for the watermarking requirement on systems already on the market. The prohibitions and AI literacy obligations have applied since 2 February 2025, and the general-purpose AI model rules since 2 August 2025. The published implementation timeline tracks each date.
Table 6: What the current EU AI Act timeline means for a pilot
| Date | What applies | What a pilot team should do about it |
|---|---|---|
| 2 Feb 2025 | Prohibited practices and AI literacy | Screen the use case against the prohibited list before scoping |
| 2 Aug 2025 | General-purpose AI model obligations | Ask your model vendor for its documentation pack |
| 2 Aug 2026 | Article 50 transparency duties | Disclose AI interaction and mark synthetic output in the pilot itself |
| 2 Dec 2027 | Annex III standalone high-risk systems | Build the risk management and logging now if production lands after this |
| 2 Aug 2028 | Annex I embedded high-risk AI | Fold it into the existing product conformity process |
The deferral only moves the date. The obligations themselves are unchanged. A pilot that starts in 2026 and reaches production in 2027 will be inside the high-risk regime for most of its operating life, and retrofitting logging, human oversight and technical documentation into a live system costs several times what building them into a pilot costs.
Checklist
Agentic AI Readiness for a First Agent Pilot
The identity, permission, audit and escalation questions to settle before an agent gets write access to a production system.
Get the Checklist →How Long Does an AI Pilot Take, and What Does It Cost?
A pilot that has no end date is not a pilot. Eight to sixteen weeks is the range that keeps the work honest, long enough to see real usage patterns and short enough that the sponsor stays interested.
Table 7: A realistic pilot shape and the gate at the end of each phase
| Phase | Typical duration | What must be true to leave it |
|---|---|---|
| Discovery and charter | 1 to 2 weeks | Charter signed, baseline metric measured |
| Data preparation and access | 2 to 4 weeks | Data flowing, classified and approved |
| Harness and build | 3 to 6 weeks | Harness passing, system in front of real users |
| Live evaluation | 2 to 3 weeks | Enough usage volume for the metric to be meaningful |
| Decision | 1 week | Verdict recorded against the exit criteria |
The Seven Roles a Pilot Needs
Most of these are part-time, and one person often covers two. What matters is that none of them is missing, because each absence has a signature failure mode.
- Business owner. Owns the metric and makes the exit call.
- Domain expert. Judges whether an output is actually right.
- Data engineer. Gets the data in, reliably, more than once.
- AI engineer or data scientist. Builds and tunes the system.
- Evaluation lead. Owns the harness and the scoring.
- Security and governance lead. Clears access and signs off on controls.
- Product or delivery lead. Protects the boundary and the end date.
Listen on Spotify
AI Agent vs Traditional Workflow. The $10K Decision Most Businesses Get Wrong
The Costs Teams Underestimate
Model inference is usually the smallest line in a pilot budget and the one everybody plans for. Ongoing MLOps work is usually the largest and the one nobody costs. The expensive parts are data preparation, integration work against systems that were never designed for programmatic access, the security review, the time domain experts spend on evaluation, and the change management needed to get real usage rather than polite usage.
Budget for the evaluation effort explicitly. A pilot where nobody has time to score the output produces a readout built on anecdotes.
Reading the Result: Scale, Iterate or Stop
The pilot ends on the date in the charter. What happens in that meeting depends entirely on whether you measured business outcomes or AI activity.
Measure Outcomes, Not Activity
Prompt counts, user logins and “number of people who tried it” are activity metrics. They rise during any pilot, because a new tool is interesting, and they fall the moment the novelty does. Hours returned to the team, cycle time on the workflow, error rate, cost per transaction and downstream customer impact are outcome metrics. Only the second set survives contact with a CFO.
Table 8: The three verdicts and the evidence each one needs
| Verdict | Evidence required | Immediate next step |
|---|---|---|
| Scale | Target metric hit, adoption sustained past the novelty window, security cleared, unit cost known | Name a production owner and a support model before the team disbands |
| Iterate | Metric moved but short of target, with a specific and testable reason why | One more time-boxed round, with a new exit threshold, not an open extension |
| Stop | Metric unmoved, or the cost per unit of value is worse than the current process | Write down what was learned about the data and the workflow, and reuse it |
Free Assessment
AI Maturity Assessment
See where your organization sits before you decide whether one pilot or a portfolio is the right next move.
Take the AssessmentIf the Answer Is Scale
A scale verdict opens a second piece of work. Production needs a named owner, a support rota, monitoring with alerting, a cost ceiling, a rollback path and a retraining or re-evaluation cadence. Kanerika’s guide to moving an AI pilot to production covers that hand-off in full, and the AI maturity model sets out what the organization around it needs to look like by then.
Stopping well is underrated. A pilot that ends with a documented reason, a cleaned dataset and a mapped workflow has produced assets the next pilot will use. A pilot that ends by going quiet has produced nothing except scepticism.
Nine Mistakes That Kill AI Pilots
- Starting from the technology. “Where can we use an LLM” produces a list of places AI could go. What you need is a list of problems worth solving.
- No named workflow owner. When the accountable person is a technologist, the pilot optimizes for technical elegance and nobody defends the business metric.
- No exit criteria. Without a number and a date, every readout is arguable and the default outcome is drift.
- Measuring the model instead of the process. An F1 score is not a business result and cannot be defended in a budget review.
- Treating governance as a final review. Security and privacy questions discovered in week ten turn into a rebuild.
- Ignoring integration until the end. The demo runs on an export. Production runs on an API that does not exist yet.
- Scoping it to win an approval. A pilot built to impress a steering committee skips the unglamorous work that production depends on.
- Running too many at once. Five shallow pilots with no owner produce five inconclusive readouts and a reputation problem.
- Skipping change management. If the people in the workflow think the system is there to remove them, adoption data will tell you so and the pilot will read as a technical failure. The organizational versions of these blockers are covered separately in Kanerika’s guide to AI adoption challenges.
How Kanerika Runs an AI Pilot
Kanerika is an AI-first data and automation consulting firm, founded in 2015 and headquartered in Austin, Texas, with around 300 professionals across the US, India, Argentina and Singapore. It is a Microsoft Solutions Partner for Data and AI, a Databricks Registered Consulting Partner and a Snowflake Select Tier Partner, and it holds ISO 27001, ISO 27701:2019 and ISO 9001:2015 certifications along with SOC 2 Type II compliance and a CMMI Level 3 appraisal.
Most of the pilots Kanerika’s teams are asked to rescue arrive with the same shape. The model works, the demo went well, and six weeks later nobody can say whether it should be scaled. The delivery sequence below exists to prevent that specific outcome.
Kanerika Service
AI Strategy Consulting
Kanerika runs the use-case scoring with your business owners, measures the baseline from the existing system, and writes the charter before anything gets built.
Scope Your First PilotAssess Before Anything Is Built
The first two weeks go on the charter and the baseline. Kanerika’s AI strategy practice runs the use-case scoring with the business owners rather than for them, because a score the workflow owner did not help produce will not hold when the pilot gets difficult. The baseline metric is measured from the existing system, not estimated, so there is something real to compare against later.
Instrument the Workflow Before the Model Touches It
The evaluation harness is built from historical cases the domain experts have already adjudicated. On document-heavy pilots this is usually a few hundred real files with known correct extractions. The harness runs from the first build, so every subsequent change is measured rather than assumed.
Build on Governed Data
Access, lineage and classification are handled through Kanerika’s data governance practice and its kanSuite services, kanGovern, kanComply and kanGuard, delivered on Microsoft Purview. For pilots with heavy pipeline work, FLIP handles the data movement so the pilot team is not hand-building ingestion that will be thrown away.
Use Agents Where the Agent Pattern Fits
Kanerika builds and operates its own agents, which is where the metric set earlier in this article comes from. Karl handles analytics questions against governed data, Klara does document intelligence and compliance checking against a playbook, Alan summarizes and analyzes legal documents, Susan handles PII redaction, and Mike checks arithmetic and cross-section consistency inside documents. Piloting an existing agent against your workflow is usually faster than building one, and it makes the build-versus-buy question answerable with evidence.
A Pilot That Produced a Number
A client wanted to modernize vendor agreement processing, which at the time meant staff reading unstructured PDFs held in Oracle Content Management Cloud. Kanerika analyzed the data environment, prepared the infrastructure, and built a chat interface, built on large language models, that let users query agreements with detailed prompt criteria to find a vendor. The published outcome is 90% faster vendor selection with LLM agreement processing, with the case study recording faster access to contract information and more reliable vendor decisions.
That engagement has the shape this whole article argues for. One workflow, one document set, one user group, and an outcome stated as a percentage against a measured baseline rather than as a description of the technology.
Talk to Kanerika
Planning Your Next AI Pilot?
Bring the use case and the workflow. Kanerika’s team will help you score it, write the charter and set the exit test in a single working session.
Book a Working Session →Wrapping Up
An AI pilot is cheap compared with what follows it, and its value is almost entirely in the quality of the decision it produces. Scope one workflow, write the charter, build the harness before the system, instrument the right metrics for the kind of AI you are actually running, and put a date and a number on the exit. Do that and a stop verdict becomes a useful result instead of an embarrassment. Skip it and you will join the 42% who walked away without ever learning why.
Frequently Asked Questions
What is an AI pilot?
An AI pilot is a time-boxed deployment of an AI system into a real business workflow. A limited group of users works with real company data for a fixed number of weeks, measured against a baseline. The pilot exists to produce one decision. Scale the system, change it, or stop it.
What is the difference between an AI pilot and an AI proof of concept?
A proof of concept asks whether the capability works on your data. It runs in an isolated test environment and a technical lead signs it off. A pilot asks whether that working capability changes a business outcome. It runs inside the live workflow with real users, and the workflow owner signs it off.
Can an AI pilot fail?
Yes, and a clear failure is a useful result. Pilots fail when nobody wrote exit criteria, when the data was not ready, or when the workflow owner was never accountable. They also fail when the use case needs accuracy the technology cannot deliver. A documented failure still leaves usable assets behind.
How do you choose an AI pilot use case?
Score each candidate from one to five on business value, data availability, process maturity, adoption readiness and technical feasibility. Do not average the scores. A one on any single factor is a disqualifier, because that factor will be what ends the pilot. Then plot the survivors on business impact against technical feasibility.
What data do you need before starting an AI pilot?
The data has to be accurate enough for the decision being automated, and reachable through an API rather than a manual export. Access must be granted and scoped before the build starts. Lineage must be traceable so an auditor can see where an answer came from. Sensitive fields must be classified and handled.
How does the EU AI Act affect an AI pilot in 2026?
Article 50 transparency duties applied from 2 August 2026. A pilot that talks to people or generates synthetic content has to disclose that. The AI Omnibus moved high-risk obligations for standalone Annex III systems to 2 December 2027 and for embedded Annex I systems to 2 August 2028. Prohibited practices have applied since February 2025.
What is the difference between an AI pilot project and an AI pilot program?
A pilot project covers one use case, one team and one outcome. A pilot program covers a portfolio of projects sharing intake, evaluation and governance standards. Finish two or three projects cleanly before standing up a program. Whatever the individual projects got wrong, the program will inherit at a larger scale.
How do you move an AI pilot into production?
A scale verdict needs four things before the pilot team disbands. Name a production owner and a support model. Put monitoring and alerting in place with a cost ceiling. Agree a rollback path. Set a cadence for re-evaluation or retraining. Treat production as a separate piece of work with its own plan.
What industries benefit most from AI pilots?
Sectors with high data volume, repeatable processes and a measurable cycle time see the clearest results. Banking and insurance pilot fraud detection and document processing. Healthcare pilots claims automation and clinical decision support. Manufacturing pilots predictive maintenance and quality inspection. Retail and logistics pilot demand forecasting and route optimization work.
What is the success rate of AI pilots?
There is no single reliable number, because the widely quoted figures measure different things. S&P Global found 42% of companies scrapped most AI initiatives in 2025 and that the average organization abandoned 46% of its proofs of concept. MIT Project NANDA found 95% of organizations saw no measurable profit impact from generative AI spend.
Is the 95% AI pilot failure statistic accurate?
The figure comes from MIT Project NANDA, which studied enterprise generative AI investment in 2025. It found that 95% of the organizations it looked at had no measurable profit and loss impact to show for that spend. The study counted financial return across an organization. It did not count how many individual pilots reached production.
Why is an AI pilot important?
A pilot tests the assumptions that a business case rests on, using real data and real users, before the company commits production budget. It surfaces integration gaps, access problems and adoption resistance while they are still cheap to fix. It also produces evidence that a sponsor can defend in a budget review.
What steps are involved in an AI pilot?
Write a charter that names the problem, users, data, boundary, duration, metrics and exit criteria. Measure the baseline. Secure and classify the data. Build the evaluation harness. Build the system and put it in front of real users. Run it long enough to gather meaningful usage. Then record a verdict against the exit criteria.
How long does an AI pilot typically take?
Eight to sixteen weeks is the normal range. Discovery and the charter take one to two weeks. Data access takes two to four weeks. The build takes three to six. Live evaluation takes two to three weeks, and the decision one. Pilots needing new data access or a security review run longer.
How much does an AI pilot cost?
Cost depends far more on data and integration work than on the model itself. Inference is usually the smallest line in the budget. The larger costs are data preparation, building connectors to systems never designed for programmatic access, the security review, and expert time spent evaluating output. Budget the evaluation effort explicitly.
What are the common metrics to evaluate an AI pilot?
Use the process metric the workflow owner already reports, such as cycle time, error rate or cost per transaction, measured against a baseline. Add technical quality measures that suit the system. For a language model, track factual correctness, hallucination rate and retrieval quality. For an agent, track task completion rate and human intervention rate.
How are agentic AI pilots different from traditional AI pilots?
A predictive model produces an output a person then acts on. An agent takes actions across systems by itself, so the risk shifts from a wrong answer to a wrong action. Accuracy stops being the useful measure. Track task completion, human intervention rate, tool selection accuracy, cost per completed task and safety failures instead.