TL;DR
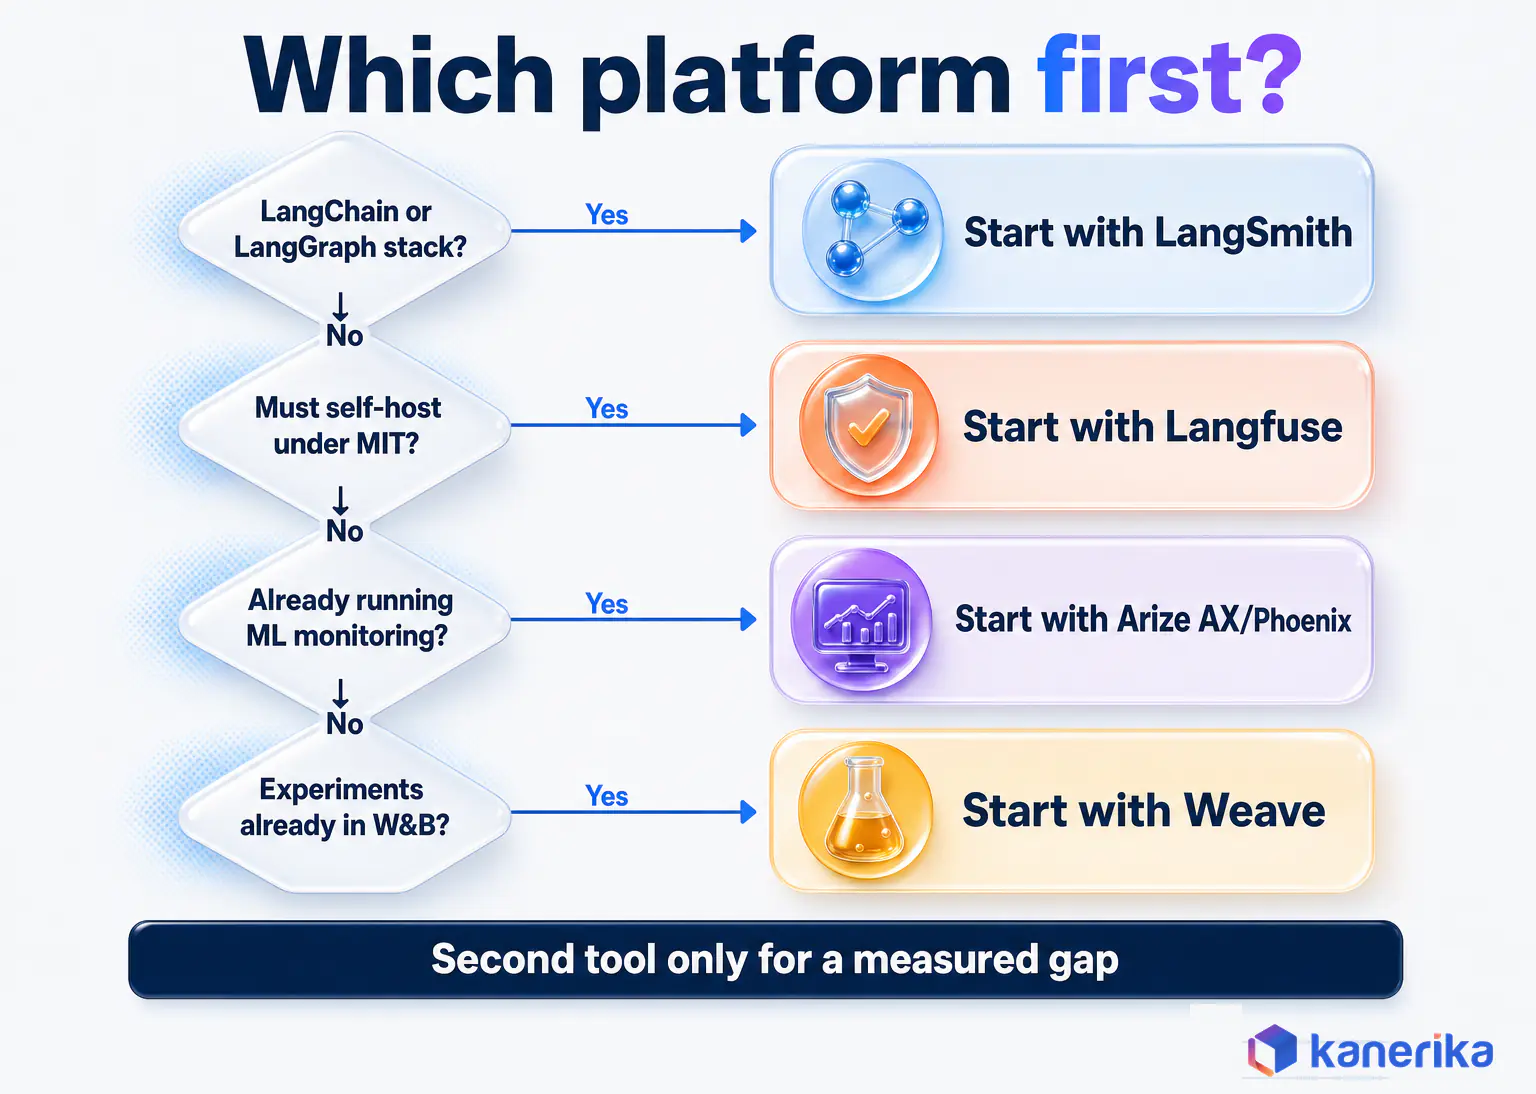
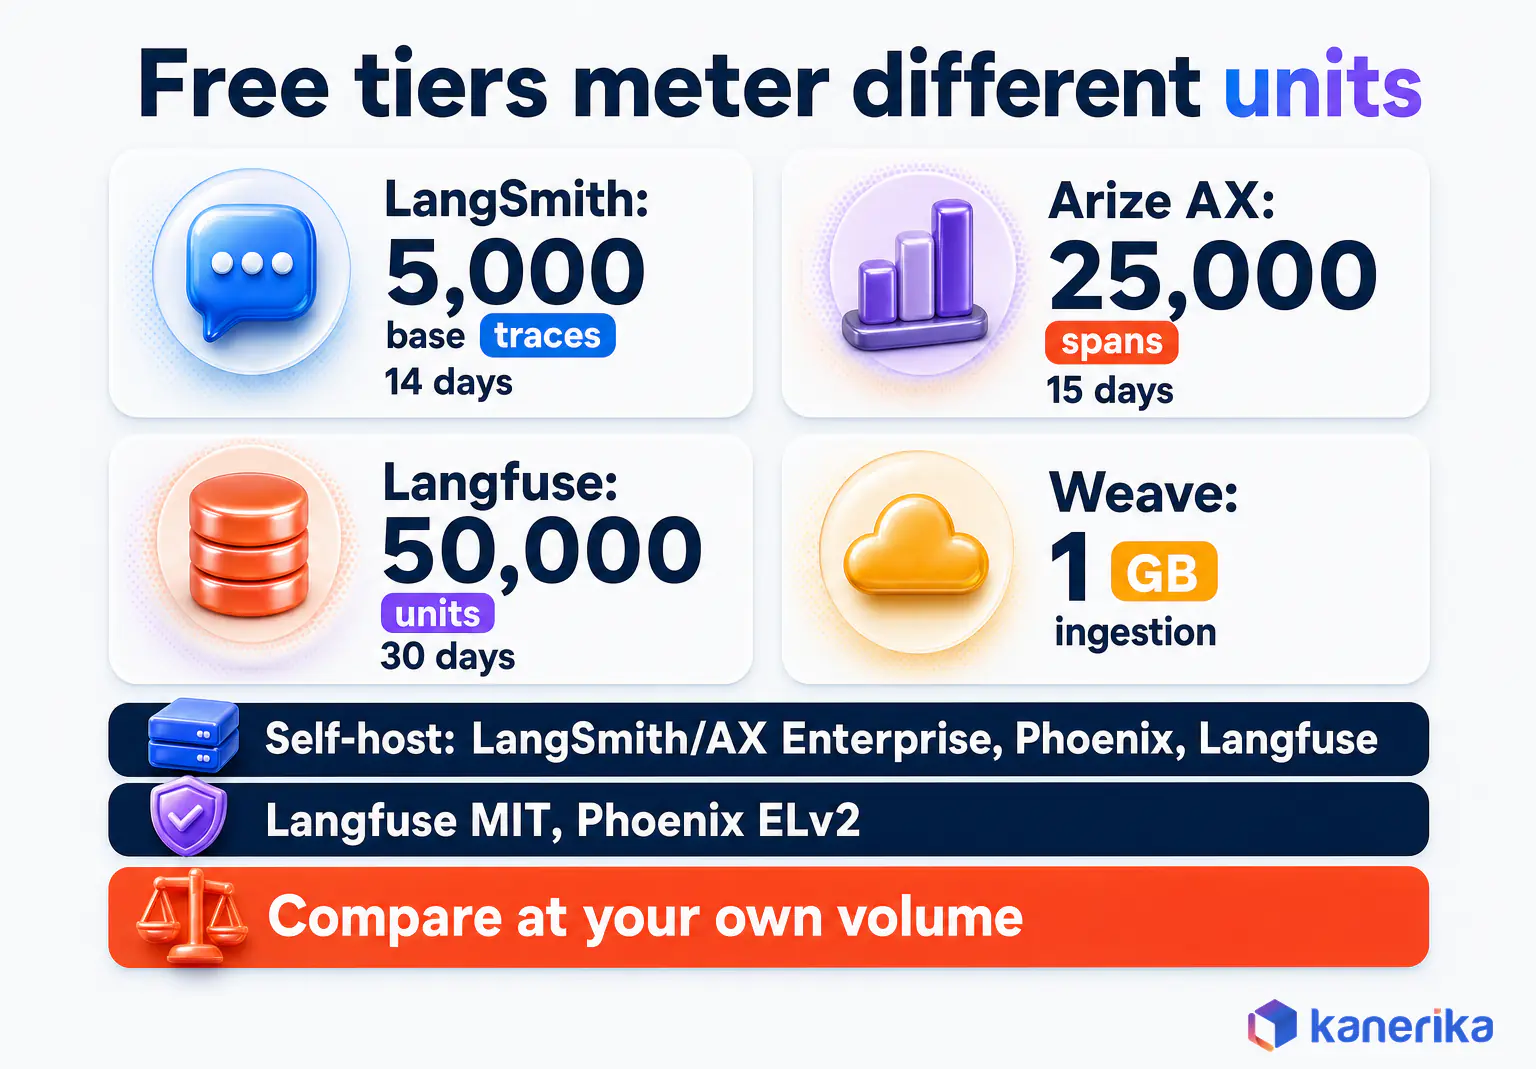
This is a buyer’s guide to LLMOps observability platforms, with the verdict first. Choose LangSmith if you build on LangChain or LangGraph, Langfuse if traces must stay in your cloud under MIT, Arize AX if you already monitor classic ML models, Phoenix for free self-hosted tracing and evals, and W&B Weave if your experiments live in Weights & Biases. All of them trace LLM calls and run evaluations, so the choice comes down to stack fit, cost at volume, self-hosting and lock-in. Instrument with OpenTelemetry first, because all of them accept OTel traces. Free tiers meter different units: LangSmith 5,000 base traces, Arize AX 25,000 spans, Langfuse 50,000 units and Weave 1 GB a month. Tier prices were checked on November 3, 2026, so confirm them on each vendor’s pricing page before you sign.
Key Takeaways
- Verdict: LangSmith for LangChain and LangGraph teams, Langfuse for MIT self-hosting, Arize AX for teams already running ML monitoring, Phoenix for free self-hosted tracing and evals, and W&B Weave for W&B experiment teams.
- Arize vs Langfuse: Arize AX wins when LLM and classic ML monitoring must share one view, while Langfuse wins on open licensing and published volume pricing.
- Langfuse vs Phoenix: both self-host their core features for free. Langfuse is MIT with a managed cloud on published tiers, while Phoenix uses the Elastic License 2.0 and has Arize AX as its upgrade path.
- LangSmith self-hosting needs the Enterprise plan, and Arize AX self-hosting does too, while Langfuse and Phoenix self-host for free.
- All of them accept OpenTelemetry traces, so instrument on OTel first. Prompts, datasets, evaluators and dashboards still have to be rebuilt on a switch.
- Vendors meter traces, spans, units and gigabytes differently, so price each one at your own volume. On Langfuse Core, 1 million units a month lists at $101.
A Clean HTTP 200 and a Wrong Answer
Picture a retrieval assistant that passes every test before it ships on a Monday. For three weeks after that, the logs show no errors, no timeouts and no infrastructure alerts. Every request still returns HTTP 200.
Then the complaints arrive. The answers are wrong, but they arrive with total confidence. A prompt update two weeks earlier changed how queries reached the retriever, and the assistant has answered from irrelevant context ever since.
Standard monitoring was never built to flag that failure, because nothing technical broke. Vectara’s hallucination leaderboard, updated October 22, 2026, puts summarization hallucination rates across 111 models between 1.8% and 24.2%. The median is 9.6%, so a typical model gets about one summary in ten wrong.
Each of those wrong answers still returns a clean status code. LLMOps observability is the practice that catches them, so the platform you choose decides how fast you see the next one. This guide compares LangSmith, Arize AX, Phoenix, Langfuse and W&B Weave on fit, cost at volume, self-hosting and lock-in, and it gives the verdict first.
Quick Verdict: Which LLMOps Observability Platform to Choose
Most teams can settle the choice with two facts: the framework they build on and where trace data may live. Find your situation in the table and stop at the first row that fits. The head-to-head sections below break a tie between two finalists.
| Your situation | Start with | Why it wins | Watch out for |
|---|---|---|---|
| Building on LangChain or LangGraph | LangSmith | Native tracing and evals, with agent runs shown as nested trees | Self-hosting needs Enterprise; pricing is per seat |
| Traces must stay in your cloud under an open license | Langfuse, self-hosted | MIT for all core features, with no usage limits when self-hosted | RBAC, audit logs and retention policies need the Enterprise license |
| Already monitoring classic ML models | Arize AX | LLM and ML monitoring in one hosted platform | Self-hosting is Enterprise only; span metering adds up for agents |
| Free self-hosted tracing and evals, with a paid upgrade path | Arize Phoenix | Free to self-host with no feature gates, built on OpenTelemetry | Elastic License 2.0 bars offering it to others as a managed service |
| Experiments already tracked in W&B | W&B Weave | Traces sit beside runs and training jobs | Metered by data volume, so long agent traces cost more |
| None of the above | Langfuse plus one hosted option | Low lock-in and published pricing | Run both on two weeks of real traffic before you sign |
The verdict rests on vendor pages checked on November 3, 2026.
Head-to-Head: Arize vs Langfuse, Langfuse vs Phoenix and Other Matchups
These are the pairings buyers compare most often. The table gives the short answer for each, and the sections after it explain who wins when.
| Matchup | Pick the first when | Pick the second when | Cost at volume | Self-hosting | Lock-in (our assessment) |
|---|---|---|---|---|---|
| Arize vs Langfuse | You monitor classic ML models and LLMs together | You want MIT code and published volume pricing | AX Pro: $50 for 50,000 spans, then custom Enterprise. Langfuse Core: $101 for 1 million units | AX on Enterprise only; Langfuse free | AX medium; Langfuse low |
| Langfuse vs Phoenix | You want MIT terms or a managed cloud with published tiers | You want free self-hosted evals with Arize AX as the upgrade | Both free when self-hosted; you pay for the infrastructure | Both free | Both low on OTel |
| LangSmith vs Langfuse | You build on LangChain or LangGraph | You mix frameworks or must self-host on a budget | LangSmith Plus: $39 per seat plus pay-as-you-go traces. Langfuse Core: $29 plus $8 per 100,000 units | LangSmith on Enterprise; Langfuse free | LangSmith medium; Langfuse low |
| LangSmith vs Arize | Your stack is LangChain-native | LLM apps and ML models share one monitoring program | LangSmith meters seats and traces; AX meters spans | LangSmith and AX on Enterprise; Phoenix free | Both medium; Phoenix low |
| Arize vs W&B Weave | Production model monitoring is the main job | Experiment tracking is the main job | AX meters spans; Weave Pro charges $0.10 per extra MB | AX on Enterprise; Weave offers Self-Managed | Both medium |
Arize vs Langfuse: Monitoring Breadth or Open Code
Choose Arize AX when one team watches classic ML models and LLM apps together, because AX puts both in the same platform. Choose Langfuse when licensing and cost control matter more. Its core is MIT, self-hosting is free without usage limits, and its cloud volume pricing is published.
For tracing LLM calls, cost and latency tracking, and LLM-as-judge evaluation, the gap is small, since both cover all three. Volume is where they split. At 1 million units a month, Langfuse Core lists at $101, while AX Pro includes 50,000 spans and larger volume moves to custom Enterprise pricing.
Langfuse vs Phoenix: Two Free Self-Hosted Options
This is the closest matchup, because both are free to self-host. Phoenix promises no license fees, usage limits or feature gates, covering tracing, evals, datasets, experiments and prompt management. Langfuse self-hosts all core features free under MIT, with unlimited usage.
Pick Langfuse if you want MIT terms, or a managed cloud with published tiers later. Note that project-level RBAC, audit logs, retention policies and server-side masking need its paid Enterprise license. Pick Phoenix if you already use OpenInference instrumentation or expect to move up to Arize AX.
Checklist
Generative AI Checklist
Check data readiness, security, governance and evaluation coverage before a generative AI system goes live.
Get the Checklist →LangSmith vs Langfuse: Ecosystem Fit or Framework Freedom
LangSmith wins for LangChain and LangGraph teams, since its datasets, evaluators and annotation queues fit the framework natively. Langfuse wins for mixed frameworks, strict data residency or a fixed budget. LangSmith charges $39 per seat on Plus, then bills extra traces pay-as-you-go through a usage calculator rather than a listed rate. Langfuse publishes its per-unit rates, and it self-hosts free, while LangSmith self-hosting needs Enterprise.
LangSmith vs Arize: Framework Depth or Model Coverage
Choose LangSmith when the app is LangChain-native and the team wants prompt versioning and evals in one product. Choose Arize when LLM apps share a monitoring program with classic ML models. LangSmith prices by seat and base trace, while AX prices by span, so model an agent run on the AX meter before comparing. For a self-hosted Arize option without an Enterprise contract, Phoenix is the route.
Arize vs W&B Weave: Production Monitoring or Experiment Tracking
Pick Arize when the job is watching production models, LLM or classic ML, for drift and quality. Pick Weave when the job is iterating on prompts and fine-tuned models next to W&B experiment runs. Weave meters gigabytes, so trace size drives its bill. Arize meters spans, so trace depth drives its bill.
LangSmith Competitors for Agent Observability: Arize Phoenix, Langfuse and W&B Weave
Teams weighing LangSmith against Arize Phoenix, Langfuse and W&B Weave for agents should test three things. First, check how each renders a nested agent run, which LangSmith shows as a tree. Second, price a real agent trace, because span meters and data meters both grow with every tool call. Third, confirm tool-call spans keep their arguments and results.
Phoenix and Langfuse are the free self-hosted options, so they suit agent teams with residency rules. The agent section below lists the failure modes worth testing in a trial.
LLMOps Observability in Brief: The Five Loops to Test a Platform Against
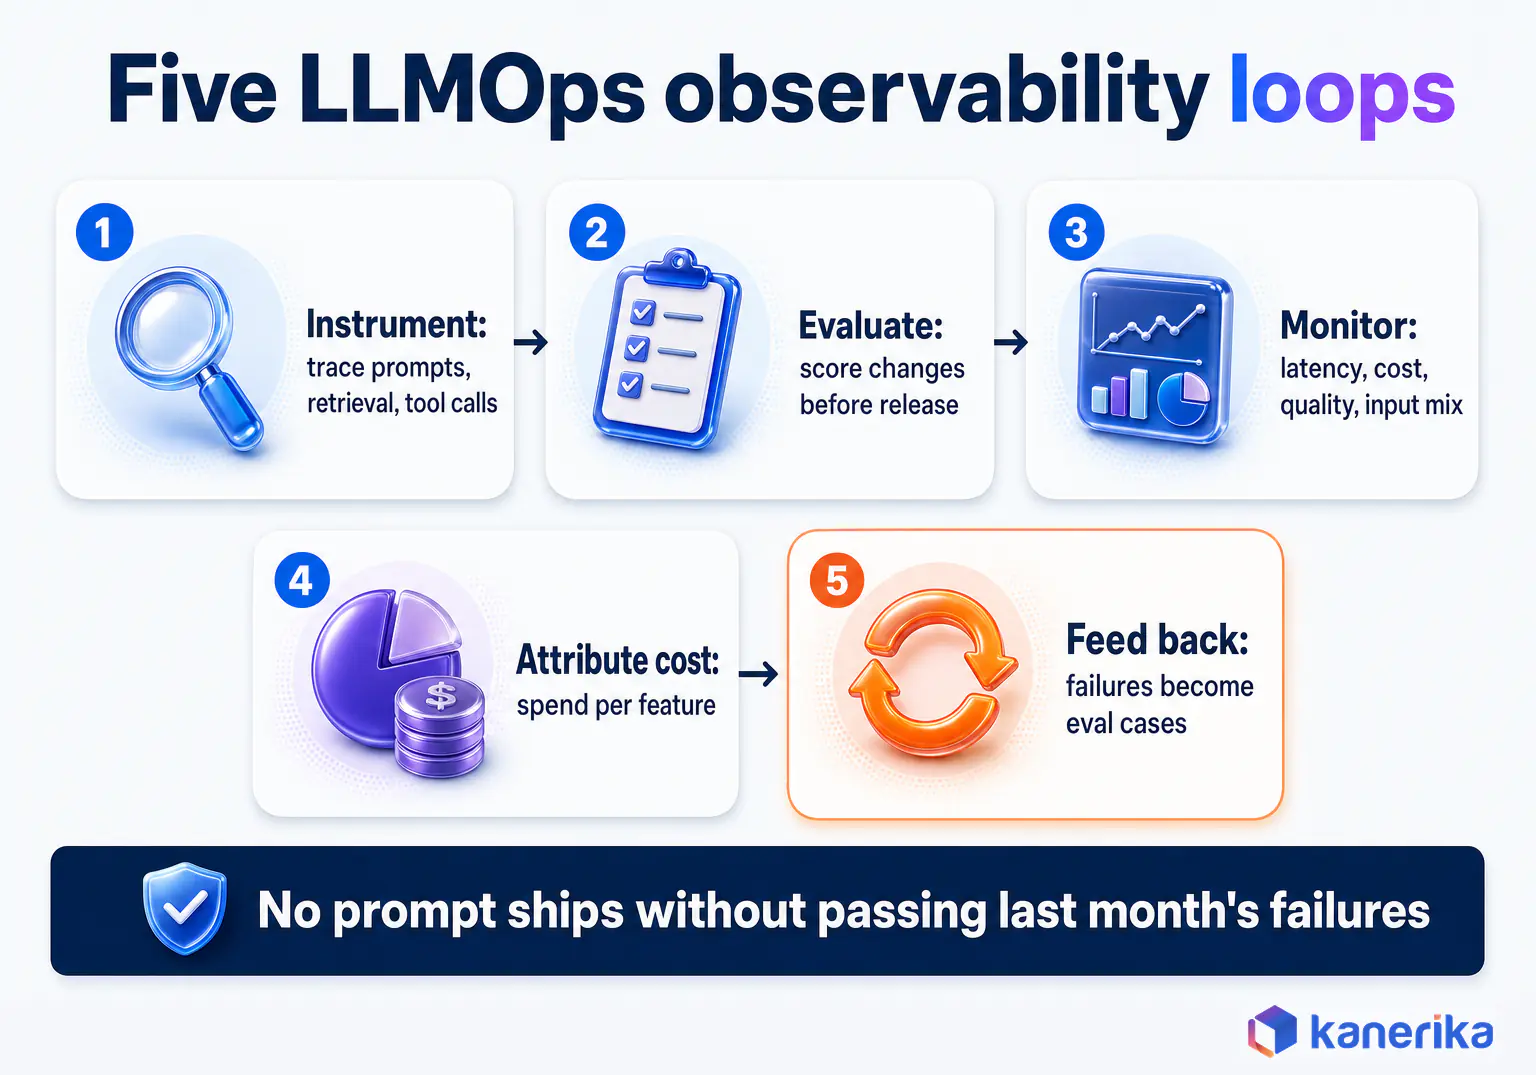
LLMOps observability is the operating loop that keeps a live LLM application measurable after release. It joins tracing, evaluation, cost tracking and drift detection into one weekly cycle. Every working program runs five loops: instrument, evaluate before release, monitor in production, attribute cost and feed failures back into eval sets.
Teams running enterprise LLM deployments usually get tracing working early. Evaluation and the feedback loop are where programs stall, so test those hardest in a trial. For what to trace and how to set it up, read our LLM observability explainer and instrumentation how-to.
The Metrics a Platform Must Track, in Brief
In a trial, check that the platform charts latency p50 and p95, time to first token, cost per task, faithfulness, retrieval relevance, refusal rate and input-mix drift. Then check that it marks each prompt or model change on those charts, so a drop points straight at its cause.
Cost attribution is easier when an LLM gateway tags each call with a team and a feature first.
The Evaluation Layer in Brief: RAGAS, G-Eval and LLM-as-Judge
RAGAS scores RAG pipelines, G-Eval grades open-ended answers against a rubric, and LLM-as-judge is the general pattern behind both. All three plug into the four platforms through SDKs or custom evaluators.
Most teams run heuristic checks on every trace, an LLM judge on a 10-20% sample and a weekly human slice to calibrate the judge. Budget for that judge too. At 100,000 traces a month and a 20% sample, a small judge model costs about $5.50 a month and a larger one about $110, at prices checked on November 2, 2026. A wider LLM evaluation framework decides which checks gate a release.
LangSmith, Arize, Langfuse and W&B Weave: Platform by Platform
The four platforms overlap on tracing, so the useful differences sit in hosting, licensing, OpenTelemetry support and how each one prices volume. Each profile covers lifecycle fit, hosting, license, OTel, tiers and the team it suits. Tier facts come from vendor pricing pages checked on November 3, 2026.
LangSmith: Deepest Fit for LangChain and LangGraph Teams
LangSmith is the observability and evaluation platform from the team behind LangChain. It covers the full loop with tracing, datasets, evaluators, prompt versioning and annotation queues for human review. Teams weighing LangChain vs LangGraph get the tightest integration with either, including agent runs shown as nested trees.
Hosting is more flexible than many older comparisons suggest. The Enterprise plan runs in the cloud, as a hybrid with a SaaS control plane and a self-hosted data plane, or fully self-hosted. Cloud data can sit in the US or the EU.
LangSmith also accepts OpenTelemetry traces from any OTel-compatible agent, including non-LangChain frameworks, as its OpenTelemetry guide explains. That lowers the lock-in risk earlier reviews warned about.
On LangSmith’s pricing page, the Developer plan is $0 for one seat with up to 5,000 base traces a month, then pay-as-you-go. Plus costs $39 per seat a month with up to 10,000 base traces. Base traces keep 14 days of history, while extended traces keep 180 days as a paid upgrade.
Instrumentation in Python is one decorator on each step you want traced:
from langsmith import traceable

@traceable
def retrieve_documents(query: str) -> list:
    # your retrieval logic
    return docs

@traceable
def generate_response(query: str, docs: list) -> str:
    # your LLM call
    return response
Best fit: teams already building on LangChain or LangGraph who want tracing and evaluation in one product. Teams on other frameworks can still send their traces through OpenTelemetry.
Arize AX and Phoenix: Strongest for Teams Already Running ML Monitoring
Arize ships two products that are easy to confuse. Phoenix is the self-hostable tracing and evaluation tool. Arize AX, by comparison, is the hosted enterprise platform that puts LLM monitoring next to classic ML model monitoring.
Phoenix is released under the Elastic License 2.0, a source-available license. It lets you run and modify Phoenix inside your company but bars offering it to others as a managed service. For most internal platform teams, that limit never comes up. Phoenix is also free to self-host with no feature limits, covering tracing, evals, datasets, experiments and prompt management.
Phoenix is built on OpenTelemetry, so a single register call sets up the tracer provider:
import phoenix as px
from phoenix.otel import register

# Register an OpenTelemetry tracer provider that exports spans to Phoenix
tracer_provider = register(project_name="rag-assistant", auto_instrument=True)
On Arize’s pricing page, AX Free includes 25,000 spans a month, 1 GB of storage and 15-day retention. AX Pro costs $50 a month for 50,000 spans, 10 GB and 30-day retention. Enterprise is custom and runs as SaaS or self-hosted.
The span meter matters especially for agents. One agent run can emit many spans, so a free tier of 25,000 spans covers fewer user requests than the number suggests.
Best fit: teams that already monitor classic ML models and want LLM traces, evals and drift in the same place. It also suits groups running MLOps on Databricks or a similar platform who want one monitoring view across model types.
Langfuse: The Open-Source Default for Data Sovereignty
Langfuse is the open-source option most teams try first when trace data must stay inside their own cloud. It covers tracing, prompt management, datasets, evaluations and annotation in one product. It is framework-neutral, so teams choosing between LlamaIndex, LangChain or Haystack can keep the same backend whichever they pick.
The license is the main draw. Per Langfuse’s open-source page, all product capabilities are MIT-licensed without usage limits. Enterprise modules such as SCIM, audit logging and data-retention policies need a commercial license when self-hosted.
The repository license names ClickHouse, Inc. as the copyright holder. Read it before you fork, as you would for any dependency.
The Python SDK can wrap the OpenAI client, so calls are traced without decorators:
from langfuse.openai import openai  # drop-in replacement for the openai client

# Every call through this client is traced automatically
response = openai.chat.completions.create(
    model="gpt-6.1-sol",
    messages=[{"role": "user", "content": query}]
)
On Langfuse’s pricing page, Hobby is free with 50,000 units a month, 30 days of data access and two users. Core costs $29 a month with 100,000 units, then $8 per 100,000 extra units, falling to $7, $6.50 and $6 at higher volume. Core also keeps 90 days of data.
Pro costs $199 a month and also adds SOC2 and ISO27001 reports plus a HIPAA-ready region. A Teams add-on costs $300 a month, while Enterprise is $2,499 a month.
Best fit: teams with data sovereignty rules, mixed frameworks or a firm cost ceiling who want the full product under an open license.
W&B Weave: Best for Teams Already Living in Weights & Biases
Weave is the LLM tracing and evaluation toolkit inside Weights & Biases. Its strength, above all, is continuity. Traces, evaluations and datasets sit next to the experiment runs and training jobs a research team already tracks in W&B.
A function decorated with weave.op is traced along with its inputs and outputs:
import weave
from openai import OpenAI

weave.init("rag-assistant-project")
client = OpenAI()

@weave.op()
def generate(query: str) -> str:
    response = client.chat.completions.create(
        model="gpt-6.1-sol",
        messages=[{"role": "user", "content": query}]
    )
    return response.choices[0].message.content
Weave also accepts OpenTelemetry trace data at its own OTLP endpoint, according to its OTel documentation. The same endpoint exists on multi-tenant cloud, Dedicated Cloud and Self-Managed deployments, so OTel-instrumented apps can send spans to any of them.
On Weave’s pricing page on CoreWeave, the Free plan is $0 with 1 GB a month of Weave ingestion. Pro starts at $60 a month with 1.5 GB. Extra ingestion costs $0.10 per MB on Pro and $0.20 per MB on Enterprise.
Metering by data volume changes the math. A team logging long agent traces with large retrieved documents fills 1 GB much faster than a team logging short chat turns. So measure your average trace size before you compare.
Best fit: research-heavy teams that iterate on prompts and fine-tuned models side by side and want one line of history from experiment to trace.
Feature-by-Feature LLMOps Platform Comparison
A side-by-side view helps once you know which loop matters most to your team. The table compares the four on hosting, license, OpenTelemetry, entry tiers and workflow, using vendor pages checked on November 3, 2026.
Hosting, License, OTel and Tiers Side by Side
The lock-in row is our editorial assessment. It reflects how much of a typical setup lives in native SDK objects, so it shows what would need rebuilding on a switch.
| LangSmith | Arize AX / Phoenix | Langfuse | W&B Weave | |
|---|---|---|---|---|
| Hosting options | Cloud (US or EU); hybrid or self-hosted on Enterprise | AX as SaaS, or self-hosted on Enterprise; Phoenix self-hosted | Cloud or self-hosted | Multi-tenant cloud, Dedicated Cloud or Self-Managed |
| License | Commercial | AX commercial; Phoenix Elastic License 2.0 | MIT for all product capabilities; enterprise modules commercial | Commercial service |
| OTel ingestion | Accepts OTel traces from any OTel-compatible agent | Phoenix is built on OTel | Accepts OTel traces | Accepts OTel trace data at its OTLP endpoint |
| Free-tier volume | 5,000 base traces a month, 1 seat | 25,000 spans a month, 1 GB | 50,000 units a month, 2 users | 1 GB a month of ingestion |
| Retention on entry tiers | 14 days base; 180 days extended (paid) | 15 days Free; 30 days Pro | 30 days Hobby; 90 days Core | Check the W&B pricing page |
| Entry paid price | Plus, $39 per seat a month | Pro, $50 a month | Core, $29 a month | Pro, from $60 a month |
| Prompt management | Versioned prompts in the platform | Prompt playground and versioning in AX | Versioned prompts, MIT-licensed | Prompts stored as versioned objects |
| Eval workflow | Datasets, evaluators, annotation queues | Evals and RAG metrics; Phoenix evals library | Datasets, LLM-as-judge evals, annotation | Evaluations linked to W&B runs |
| Compliance reports | Check the vendor trust center | Check the vendor trust center | Pro: SOC2 and ISO27001 reports, HIPAA-ready region | Check the vendor trust center |
| Lock-in risk (our assessment) | Medium: most value sits in LangChain-native features | Low for Phoenix on OTel; medium for AX workflows | Low: MIT code plus OTel ingestion | Medium: value tied to the W&B workspace |
What the Comparison Shows
Langfuse and Phoenix give the clearest exit paths, because you can run both yourself. LangSmith and Weave reward teams already inside their ecosystems, and leaving them means exporting data and rebuilding native features.
For retrieval-heavy apps, read this table next to your vector database choice. Retrieval quality shows up in every trace, whichever platform records it.
Kanerika Service
Build LLM Applications With Observability From Day One
Kanerika builds enterprise LLM applications with tracing, evaluation and quality monitoring planned into the first release.
Explore LLM DevelopmentPricing at Scale: What the Published Tiers Mean at Production Volume
Pricing pages look comparable until you notice the metering unit. LangSmith counts traces, Arize AX counts spans, Langfuse counts billable units, meaning any tracing data point such as a trace, observation or score, and Weave counts data ingested.
One user request can be one trace but ten or more spans, depending on how many retrieval and tool steps it runs. As a result, the same workload can sit inside one free tier and far outside another.
| Platform | Entry free | First paid | Metering unit | Retention | Beyond the included volume |
|---|---|---|---|---|---|
| LangSmith | Developer: $0, 1 seat, 5,000 base traces a month | Plus: $39 per seat a month, 10,000 base traces | Traces | 14 days base; 180 days extended | Pay-as-you-go beyond the included traces |
| Arize AX | Free: 25,000 spans, 1 GB | Pro: $50 a month, 50,000 spans, 10 GB | Spans and storage | 15 days Free; 30 days Pro | Enterprise, custom pricing |
| Langfuse | Hobby: 50,000 units, 2 users | Core: $29 a month, 100,000 units | Billable units | 30 days Hobby; 90 days Core; 3 years Pro | $8 per 100,000 units, graduated to $7, $6.50 and $6 |
| W&B Weave | Free: 1 GB a month of ingestion | Pro: from $60 a month, 1.5 GB a month | Data ingested | Check the pricing page | $0.10 per MB on Pro; $0.20 per MB on Enterprise |
What the Tiers Cost at Volume
Langfuse is the one vendor here whose graduated rates are fully published, so it is the only one we price at volume. On the Core plan, 1 million units a month costs $29 plus 900,000 units at $8 per 100,000, or $101 a month.
At 10 million units, the next 9 million bill at $7 per 100,000. That adds $630, for a total of $731 a month. Both figures are list prices on the Core plan, before discounts.
Weave, by comparison, scales on a different axis. On Pro, every extra 100 MB of ingestion costs $10, so trace size matters as much as trace count.
Per-volume metering pushes teams to sample harder. Sampling is fine for routine traffic, but keep full capture for errors, high-cost requests and flagged users. The traces you need most should never be sampled away.
Retention is the other hidden cost. If base traces disappear after 14 days, any failure you want for the eval set has to be copied into a dataset before then. Build that export into the weekly review, or pay for longer retention on the traces that feed evaluation.
Kanerika Service
Run Production LLMs With MLOps Discipline
Kanerika’s MLOps consulting brings CI/CD, drift detection and model monitoring to production AI programs.
Explore MLOps ConsultingRun the numbers at your own trace volume and average trace size before you shortlist. A two-week trial on real traffic gives a better estimate than any pricing calculator.
OpenTelemetry, Lock-In and What Switching Costs
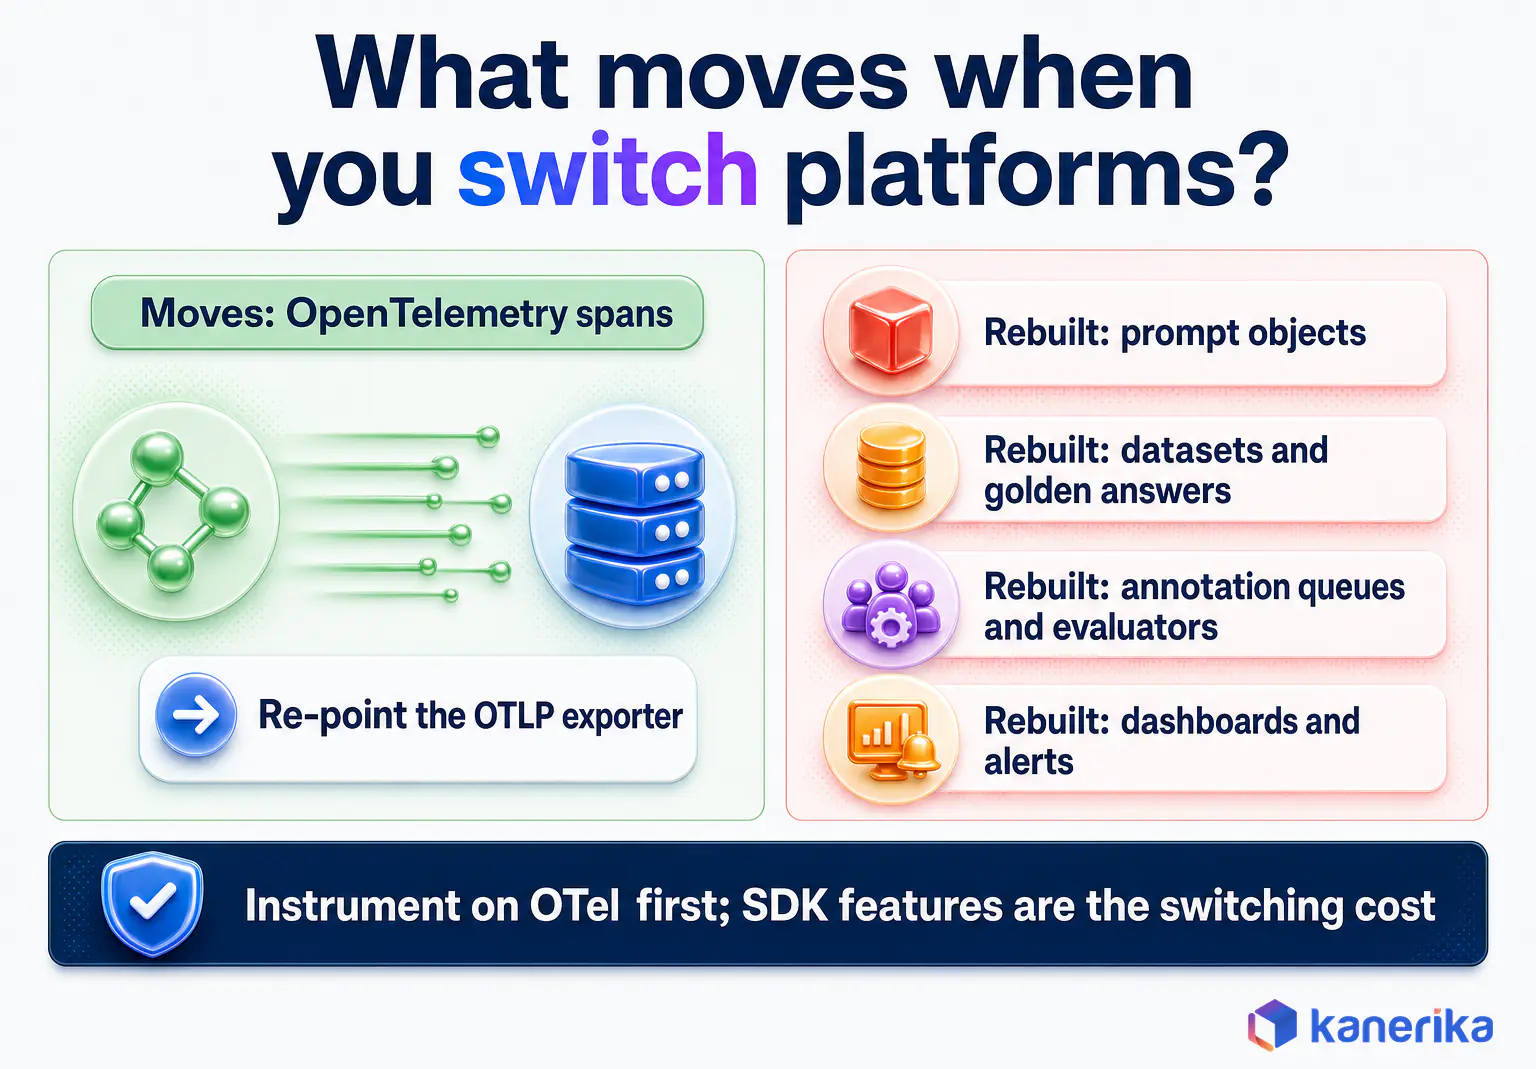
OpenTelemetry is the open standard for traces, metrics and logs, and it is the cheapest insurance against lock-in. If your app emits standard spans, the backend then becomes a configuration choice.
The GenAI semantic conventions define how to name LLM spans and their attributes, such as model, token counts and operation type. They now live in a dedicated repository, open-telemetry/semantic-conventions-genai. Pin the version you instrument against, because attribute names in this area still change.
All four platforms accept OTel traces in some form. A portable setup points one exporter at whichever backend you choose:
from opentelemetry import trace
from opentelemetry.sdk.trace import TracerProvider
from opentelemetry.exporter.otlp.proto.http.trace_exporter import OTLPSpanExporter
from opentelemetry.sdk.trace.export import BatchSpanProcessor

# Change the endpoint URL to switch backends; the instrumentation stays the same
provider = TracerProvider()
exporter = OTLPSpanExporter(endpoint="http://your-backend/v1/traces")
provider.add_span_processor(BatchSpanProcessor(exporter))
trace.set_tracer_provider(provider)
Spans, though, are only part of what a team builds. Prompt objects, datasets, annotation queues, evaluator definitions and dashboards live in each vendor’s native SDK or UI. None of them move when you change an exporter.
A platform switch usually means five pieces of work:
- Re-point the exporter: change the OTLP endpoint and credentials, the smallest job when instrumentation is pure OTel.
- Rebuild prompt management: move versioned prompts and their deployment labels into the new tool’s format.
- Migrate datasets: export eval sets and golden answers, then re-import them and re-link them to evaluators.
- Recreate evaluators: port judge prompts and thresholds, then re-check judge agreement on the new platform.
- Rebuild dashboards and alerts: recreate cost, latency and quality views and wire alerts back into on-call tools.
Agents also add one more check. Tool calls made through the Model Context Protocol show up as spans too, so confirm the new backend renders them with arguments and results intact.
The practical rule follows from the list. Instrument on OpenTelemetry first, then treat every vendor SDK feature you adopt as a switching cost you have chosen to accept.
Privacy, Compliance and Governance of Prompts in Traces
Every trace is a copy of what a user typed and what the model said back. That makes your observability backend a data store with the same privacy duties as your application database.
A claims assistant, for example, may log policy numbers, names and medical details inside prompts. If those traces flow to a SaaS backend unredacted, you have created a second copy of regulated data outside your main controls.
Redaction is easiest at the edge. A masking step in the app, or in an OpenTelemetry collector you run, replaces names and numbers with typed placeholders before export. Debugging still works, because engineers can see that a policy number was present without seeing the number itself.
Five Controls for Prompt Data in Traces
Five controls cover most of the exposure:
- Redact before export: strip or mask PII in the app or the collector, before spans leave your network.
- Set retention on purpose: match trace retention to your data policy instead of the plan default.
- Choose the data region: LangSmith cloud stores data in the US or the EU. Self-hosted Langfuse, Phoenix or LangSmith Enterprise keep traces in your own cloud instead.
- Limit who sees raw traces: restrict trace access to the people who debug, and log that access.
- Test for leaks: add prompt-injection and data-exfiltration cases from LLM red teaming to the eval set.
Teams running private LLMs or building toward sovereign AI often choose self-hosting for this reason alone. Keeping traces in-region is simpler than proving that a vendor’s controls match your own.
For a standards anchor, use NIST AI 600-1, the Generative AI Profile of the AI Risk Management Framework, published on July 26, 2024. Observability records give evidence for its measure and manage functions. They also slot into a wider AI governance framework and responsible AI program.
Checklist
AI Governance Checklist
The policies, controls and records an AI program needs before auditors ask for them.
Get the Checklist →Agent Observability Inside LLMOps
Agents turn one request into a tree of model calls, tool calls and sub-tasks. Observing them means reading that tree, because the final answer rarely shows where a run went wrong.
Consider a research agent that plans, searches twice, calls a pricing API and writes a summary. If the API returns an empty result and the agent carries on, the summary reads well and is still wrong. The trace is the only place that failure is visible.
Agent Failure Modes Worth an Alert
The table lists the agent failure modes worth an alert. Our guide to AI agent observability covers each one in more depth.
| Failure mode | What it looks like in production | Signal to alert on |
|---|---|---|
| Runaway loops | The agent revisits the same step and spends tokens on every pass | Step count per run above a set limit |
| Silent tool failures | An API call fails and the agent proceeds with empty context | Tool spans with an error status or empty output |
| Context overflow | Context grows past the model limit and earlier reasoning is cut off | Tokens per trace close to the context limit |
| Sub-agent hallucination | A sub-agent returns a fabricated result that the parent treats as fact | Judge scores on sub-agent outputs |
| Non-termination | The agent hits its step cap and returns a partial result without saying so | Completion status plus step count |
| Branch divergence | Parallel branches reach conflicting conclusions | Disagreement checks across branch outputs |
In multi-agent systems, each hand-off between agents is another place for context to drop. Good agent orchestration records those hand-offs as spans, so the tree stays readable when something fails.
Checklist
Agentic AI Readiness Checklist
Check whether your data, controls and monitoring are ready before AI agents run in production.
Get the Checklist →How to Choose the Right LLMOps Observability Platform
The verdict table at the top settles most choices from framework, hosting rules and existing tools. When two finalists remain, a trial on real traffic decides it.
Running a Fair Trial
Run the trial on real traffic and judge each candidate on the same five things. First, check how fast an engineer finds the cause of a known failure and how cleanly agent runs render. Then estimate what the volume would cost at full traffic. After that, check how retention and redaction fit your policy, and how much of the setup stays portable on OTel.
Maturity also changes the weighting. A team with one prototype needs fast tracing and a generous free tier more than enterprise access controls. A team with ten production apps needs cost attribution, retention policies and single sign-on before anything else.
Some teams end up with two tools. One workable split pairs a tracing and prompt platform with a second tool for a specialist job. For example, RAG evaluation can run in Phoenix while tracing stays in Langfuse.
Add that second tool only for a measured gap. Every extra platform means another SDK, another retention policy and another place for prompts to leak.
When None of These Fits
Some teams still need a different shape of tool. Helicone, Braintrust, Datadog LLM Observability and MLflow are other options, from gateway-style logging to LLM views inside an existing monitoring or ML platform. Our wider list of AI observability tools compares them in more detail.
A 30-60-90 Day LLMOps Observability Rollout
A rollout works best when each phase ends with one loop running for real. The plan below assumes one production LLM app and a small platform team, so widen the scope for a larger estate.
Days 1-30: Instrument and Baseline
- Pick the platform with the verdict table above, then set up OpenTelemetry instrumentation.
- Trace every production request, with token counts, latency and cost tags per feature.
- Record two to four weeks of baseline latency, cost and refusal rates before you set thresholds.
- Agree on retention, redaction and access rules with security before traces leave the app.
Days 31-60: Evaluate and Gate
- Build the first eval set from real production traces, including every failure users reported.
- Add heuristic checks on all traces, then an LLM judge on a sample.
- Gate prompt and model changes in CI/CD so that every change runs the eval set first.
- Calibrate the judge against a weekly slice of human-reviewed traces, so its scores stay trustworthy.
Days 61-90: Monitor and Close the Loop
- Set alerts on p95 latency, cost per task, faithfulness and input-mix drift once baselines exist.
- Route flagged traces into an annotation queue, then into the eval set.
- Review cost per task by feature with product owners at least once a month.
- Write down the switching plan, separating what is pure OTel from what is vendor-native.
Give each loop a named owner by day 90. Platform engineers usually own instrumentation and alerts, while product teams own eval sets and quality thresholds. Without that split, the feedback loop is the first thing to stop.
Teams on Microsoft platforms can fold the same gates into MLOps in Microsoft Fabric. Budget for people as well as licenses, and our guide to AI development cost shows where LLM project money tends to go.
How Kanerika Runs LLMOps Observability
Kanerika builds and runs production LLM applications for enterprises, and observability is part of the delivery plan from the first release. Our LLM development practice commits to monitoring output quality continuously after launch.
Our MLOps consulting team also brings CI/CD for models, drift detection and model monitoring to the same programs. The approach carries into our RAG development work and into deployments that use FLIP, Kanerika’s own platform.
We stay platform-neutral and pick the tool that fits each client’s framework, hosting rules and compliance needs. Engagements usually move through five stages:
- Assess the stack fit: framework, hosting model and compliance rules decide the shortlist before any tooling work.
- Instrument on OpenTelemetry: standard spans from the first production release, so the backend stays swappable.
- Build the first eval set from production traces: then gate every prompt change in CI/CD against it.
- Redact PII before traces leave the app: Susan, Kanerika’s AI PII redactor, masks personal data at the source before export.
- Wire cost and drift alerts into existing monitoring: so LLM signals reach the on-call tools teams already watch.
Case Study: 43% Faster Document Retrieval for an Investment Bank
An investment bank handled unstructured RFI documents and structured data through manual processes. Analysts searched repositories by hand, while routine data requests waited on specialists.
Access controls also sat outside the retrieval process. As a result, every new retrieval path reopened a compliance question.
Kanerika deployed KlarityIQ to process the unstructured documents and Karl to query structured enterprise databases, with chat interfaces across both. Secure role-based access control was applied at the retrieval layer itself. The engagement delivered these results:
- 43% faster information retrieval across documents and databases
- 100% role-based compliance achieved at the point of retrieval
- 35% improvement in workforce efficiency
The engagement put controls at the point where data is retrieved. That is also the point where a trace can show which document reached the prompt and whether the user was allowed to see it.
The lesson for observability is where to look first. Retrieval is where access rules apply and where wrong context enters a prompt, so it is the step most worth instrumenting and evaluating. The full story is in the investment bank case study.
Case Study
43% Faster Document Retrieval for an Investment Bank
KlarityIQ and Karl gave analysts faster retrieval across documents and databases, with role-based access enforced at the point of retrieval.
Read the Case Study →The Bottom Line on LangSmith, Arize, Phoenix, Langfuse and W&B Weave
LLMOps observability decides whether your team or your users find the next wrong answer. All four platforms trace and evaluate, but they part ways on hosting, license, metering and how tightly they bind you to an ecosystem.
Instrument on OpenTelemetry, start the eval set from real failures and recheck tier prices, last verified on November 3, 2026, before you commit. Then settle the choice by your stack. Choose LangSmith for LangChain teams, Langfuse for open self-hosting, Arize AX for ML monitoring shops, Phoenix for free self-hosted evals and Weave for W&B users.
Frequently Asked Questions
What is LLMOps observability and why does it matter in production?
LLMOps observability is the practice of tracing, evaluating and monitoring live LLM applications, then feeding failures back into tests. It matters because LLM failures rarely raise errors. A wrong answer still returns HTTP 200, so only traces, quality scores and cost tracking show when an assistant drifts, overspends or answers from the wrong context.
What is the difference between LangSmith and Langfuse?
LangSmith is a commercial platform from the LangChain team, with the deepest fit for LangChain and LangGraph apps. Langfuse is open source, with every product capability under MIT, and suits teams that self-host for data control. Both trace, evaluate and manage prompts. LangSmith Enterprise can also be self-hosted, and both accept OpenTelemetry traces.
Can LangSmith be self-hosted?
Yes, on the Enterprise plan. As of November 3, 2026, LangSmith Enterprise runs in the cloud, as a hybrid with a SaaS control plane and a self-hosted data plane, or fully self-hosted. Cloud data can be stored in the US or the EU. Teams that need traces inside their own network should plan for Enterprise pricing.
Should I instrument with OpenTelemetry or a vendor SDK?
Start with OpenTelemetry for spans, because all four platforms accept OTel traces and your instrumentation stays portable. Then add the vendor SDK only where it gives you something OTel lacks, such as prompt versioning, datasets or annotation queues. That mix keeps switching costs visible and limited to the features you chose to adopt on purpose.
Is Arize Phoenix the same as Arize AX?
No. Phoenix is the self-hostable tracing and evaluation tool from Arize, released under the Elastic License 2.0. Arize AX is the hosted platform that adds enterprise LLM and ML monitoring. As of November 3, 2026, AX Free includes 25,000 spans a month with 15-day retention, and AX Pro costs $50 a month for 50,000 spans.
Can multiple LLMOps tools be used together?
Yes. Some teams trace in one platform and run a specialist job in another, such as RAG evaluation in Phoenix beside tracing in Langfuse. OpenTelemetry makes this easier, because one instrumented app can export spans to more than one backend. Add a second tool only for a measured gap, since each one adds an SDK and a retention policy.
What LLM evaluation frameworks work with these platforms?
RAGAS, G-Eval and LLM-as-judge methods all work with LangSmith, Arize, Langfuse and W&B Weave through SDKs or custom evaluators. RAGAS suits RAG pipelines, G-Eval suits open-ended answers, and judges scale scoring across live traffic. Heuristic checks such as schema and regex tests run cheaply on every trace and catch obvious regressions first.
How do teams avoid vendor lock-in with an LLMOps platform?
Instrument with OpenTelemetry from the start, because all four platforms accept OTel traces and spans move with an exporter change. Keep eval sets and prompts exportable in plain formats. Treat native SDK features, such as prompt objects, datasets and annotation queues, as switching costs you accept on purpose, and write the exit plan down early.
How much does LLMOps observability cost at scale?
It depends on volume and on each vendor’s metering unit. As of November 3, 2026, LangSmith Plus costs $39 per seat a month, Arize AX Pro $50 a month, Langfuse Core $29 a month and W&B Weave Pro from $60 a month. On Langfuse Core, 1 million units a month costs $101 at list price, before discounts.
When should an enterprise bring in an implementation partner for LLMOps?
Bring in a partner when several LLM apps reach production without shared tracing, eval sets or cost alerts, or when compliance rules shape where traces can live. A partner such as Kanerika can assess stack fit, instrument on OpenTelemetry, build eval sets from real traces and redact PII. Internal teams then own the loops once they run.
What is the best open-source LLM observability tool in 2026?
Langfuse is the most permissive choice, since all its product capabilities are MIT-licensed without usage limits. Arize Phoenix is source-available under the Elastic License 2.0, which allows internal use but bars offering it as a managed service. Pick Langfuse for a fully open stack, or Phoenix when RAG evaluation and Arize compatibility matter more.
How does LLMOps observability connect to AI governance?
Traces, eval scores and release decisions form the evidence governance teams need. NIST AI 600-1, the Generative AI Profile published on July 26, 2024, gives suggested actions for measuring and managing generative AI risk. Observability records show what a model produced, how it was tested and who approved each change, which supports audits and incident reviews.