TL;DR
An AI pilot to production move fails most often when teams treat the demo as proof and build outside the daily workflow. They also leave cost and ownership for later, and RAND notes that, by some estimates, more than 80 percent of AI projects fail. The fix is a scored review of seven go/no-go criteria, from business baseline and evaluation to fallback, run cost and operating owner. If any criterion scores zero, hold the release and fix that gap first. Otherwise, embed the AI in the tools people already use and release it in four measured stages. After launch, track the cost of each accepted result against the manual baseline.
Key Takeaways
- The costliest mistakes are treating the demo as proof, building outside the daily workflow and budgeting for inference only.
- Ship a pilot only after it scores on seven go/no-go criteria: business baseline, evaluation set, integration, security review, fallback, run cost and operating owner.
- RAND notes that, by some estimates, more than 80 percent of AI projects fail, twice the rate of IT projects without AI.
- Most stalls come from the organization around the model, such as missing owners, unclear value and AI built outside the daily workflow.
- A scored review with a named owner for each criterion turns the release into a decision instead of a debate.
- Release in stages from shadow mode to full production, and back each step with an evaluation harness built from real cases.
- Track cost per accepted outcome, because inference is only one line in what AI costs to run.
The Agent Worked. Nobody Used It.
A support team once built an AI agent with Kanerika to answer service questions and draft replies for its associates. The demo went well, and the sponsors signed off on it.
Then the usage reports came in, and they were flat. The agent ran in its own window, so associates had to leave their service portal, open a new tool and paste in the case. On a busy shift, that one extra step was enough to skip it.
Nothing about the model changed, though. Usage rose once the team embedded the agent inside the portal, right next to the case each associate was already working on.
That story sums up the gap this guide covers. Moving an AI pilot to production is rarely blocked by the model alone. It stalls on integration, data, evaluation, cost and ownership, and each of those has a practical fix.
What Does AI Pilot to Production Actually Mean?
AI pilot to production means turning a model that worked in a controlled test into a system the business runs every day. The pilot asks whether the idea can work at all. Production then asks a harder question: can the business run it reliably, safely and at a cost it accepts?
Because of that, the two tests use different data, different users and different rules for failure. A pilot often runs on a clean sample with a few willing testers. Production, however, meets messy records, impatient users and edge cases nobody listed in the brief.
The stakes rise as companies move from chat assistants to agents that act on systems. We track that shift in our AI predictions for 2026.
An agent that updates a record or sends an email needs stronger gates than a tool that only drafts text. Still, the same gap applies to classic machine learning, such as the predictive AI models that forecast demand.
Pilot Success and Production Readiness Are Different Tests
A pilot can pass on a hand-cleaned sample and still fail at the same task in production. The model is unchanged, yet everything around it gets harder. Use the rows below to spot which column your project still lives in.
| Dimension | Pilot | Production |
|---|---|---|
| Data | Curated sample, often cleaned by hand | Live feeds with gaps, duplicates and drift |
| Users | A few motivated testers | Every user in the target team, skeptics included |
| Uptime | Best effort, restarted by the builder | Agreed availability with support hours |
| Owner | The project team or a vendor | A named business owner and an operating team |
| Evaluation | Demo cases and gut feel | A test set of real cases with agreed pass marks |
| Cost | Covered by an innovation budget | Charged to a business line and tracked per outcome |
| Failure handling | Someone notices and fixes it | Fallback to people, rollback and an incident process |
Why Most AI Pilots Stall Before Production
Because the failure rate is high, plan for it from day one. A 2024 RAND report notes that, by some estimates, more than 80 percent of AI projects fail. That is twice the rate of IT projects that do not involve AI.
RAND’s interviews also point at the conditions around the algorithm. Thirty of the 50 industry practitioners RAND interviewed named persistent data quality problems, which no amount of prompt tuning can fix.
Agentic projects face the same pressure. Gartner predicted in June 2025 that more than 40% of agentic AI projects will be canceled by the end of 2027. It pointed to rising costs, unclear business value and inadequate risk controls.
Generative AI pilots show a similar pattern. An MIT NANDA report, as reported by Fortune, found that only about 5% of AI pilot programs achieve rapid revenue acceleration. Most still stall with little measurable effect on profit and loss.
So where do enterprise teams go wrong? They treat a good demo as proof that the work is done. The demo tested the model, while production tests everything around it, from the workflow and data feeds to the controls, the budget and the owner.
Diagnose What Your Pilot Has Not Proven Yet
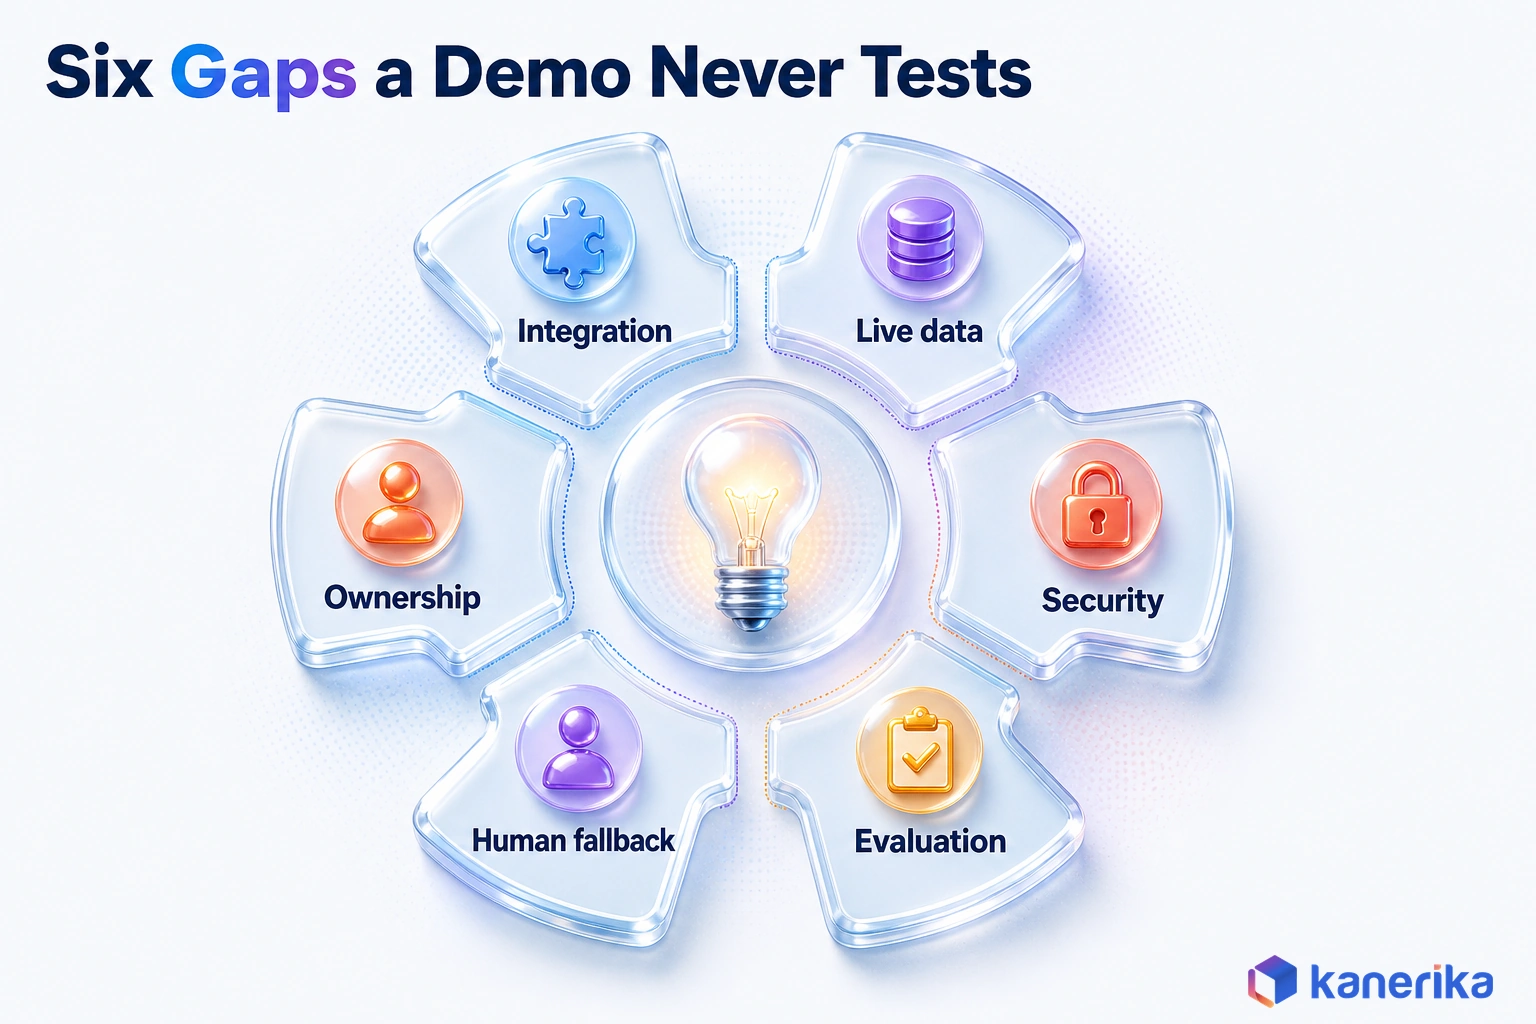
Before anyone debates a launch date, list what the pilot never tested. Most pilots prove only that a model can produce good output when the input is good. They rarely prove the six things that decide whether it survives once it meets real work.
Treat the six as open questions, each one closed by evidence instead of opinion. The table then gives the question to ask and the proof that answers it.
| Gap | Question to ask | Evidence that closes it |
|---|---|---|
| Integration | Does the AI run inside the system where the work already happens? | A live connection in the target workflow, tested by real users |
| Live data | Will production data look like the pilot data? | A profile of live inputs, with gaps, formats and volumes checked |
| Security | Who can reach the model, its data and its actions? | A signed access review and least-privilege permissions |
| Evaluation | How do we know the output is good enough on real cases? | Pass rates on a representative test set, agreed before launch |
| Human fallback | What happens when the AI is wrong or unavailable? | A tested handoff to people and a rollback path |
| Ownership | Who runs, funds and answers for it after launch? | A named business owner and an operating team with time set aside |
Look Beneath the Pilot at Legacy Systems
The integration and live data gaps often lead somewhere older than the AI itself. Many pilots sit on top of legacy systems with undocumented business rules, such as a discount rule buried in an ERP screen. The model cannot respect a rule nobody wrote down, so finding those rules is part of the job.
Architecture matters here too, because a pilot that read a weekly file export may need event feeds, APIs and elastic compute. When the rules live inside an aging ERP, an SAP modernization program may need to move first. In either case, a cloud-native architecture gives the AI clean interfaces to call.
Keep, Rebuild or Redesign Each Pilot Component
Not every part of a pilot should go to production as it is, so review each one separately. Some pieces carry over, some need a production-grade rebuild, and some reveal that the design itself was wrong.
| Component | Keep when | Rebuild when | Redesign when |
|---|---|---|---|
| Model or prompt | It passes the test set on live data | Accuracy holds but latency or cost does not | It fails on common real cases |
| Data pipeline | It already reads production sources | It depends on manual exports or copies | The data the use case needs does not exist |
| User interface | Users already work in it | It is a standalone demo screen | Users would need to change tools to use it |
| Integration | It calls stable APIs with error handling | It relies on scripts or screen scraping | The target system cannot accept AI output |
| Controls | Access and logging meet policy | Logging exists but is incomplete | The AI can take actions nobody approved |
A redesign verdict is not a failure. Finding it before launch costs far less than finding it after users have lost trust in the tool.
If the table shows more rebuild and redesign entries than keeps, pause and measure readiness before you commit to a date. A structured look at data, process and governance then makes that call far less subjective.
AI Assessment
Is Your AI Pilot Ready for Production?
Score your data, processes and governance with Kanerika’s AI maturity assessment and see which gaps to close before you set a launch date.
Start Your AI Assessment →Choose the Production Pattern Before the Tool
Teams often pick a platform first and work out the operating model later. That order invites rework, because the right pattern depends on who will build, run and improve the system for years.
Build, Buy or Partner
There are three ways to source and staff a production AI system. Each fits a different mix of skills, urgency and how much the capability sets you apart.
| Option | Fits when | Watch-outs | Typical owner |
|---|---|---|---|
| Build in-house | The AI is a core advantage and you have ML, data and platform engineers | Hiring time and the full cost of running it yourself | Internal product or platform team |
| Buy a product | The use case is common, such as document capture or service triage | Limited control, vendor lock-in and data residency terms | Business owner with IT oversight |
| Partner | You need production skills now and want to grow internal capability over time | Knowledge transfer must be planned, or the skills leave with the partner | Joint team, moving to an internal owner |
Building in-house also means deciding whether to hire a data engineer or a data scientist first, since production work leans heavily on pipelines.
Partnering often works best as a bridge. External engineers carry the system through its first releases while your people learn to run it. That model is close to staff augmentation, but focused on one delivery.
Forward deployed engineers take that idea further still. They sit with the business team, so the person fixing an integration hears the user’s complaint the same day. The video below explains why that matters when a pilot has to become a product.
Put the AI Inside the Workflow People Already Use
The opening story shows the most common adoption failure we see. A separate app, a new login or a copy-and-paste step turns every use into a small decision, and busy people decide against it.
Embedding means the AI appears where the work happens. For example, that could be a panel in the CRM, a suggested reply in the service desk or a field on an invoice screen. The user then accepts, edits or rejects the output without leaving the task. Suggested replies are a common entry point for AI agents for customer support, since associates check each draft before it goes out.
A simple test follows from this. If using the AI takes more than one click from where the user already is, expect adoption to lag however good the output looks. The same rule applies when you deploy an AI chatbot for business, so place it where customers and staff already work.
Set the Human-Autonomy Boundary: Assistive, Intelligent, Autonomous
The second design choice is how much the AI may do before a person steps in. Kanerika moves systems through three stages, so each step up has its own exit test.
| Stage | What the AI does | Who approves | Exit test before the next stage |
|---|---|---|---|
| Assistive | Drafts, summarizes or suggests | A person approves every output | Users accept most suggestions with light edits |
| Intelligent | Makes routine decisions and flags exceptions | People review exceptions and a sample of routine cases | Error rates on routine cases stay within the agreed limit |
| Autonomous | Completes the task end to end within set limits | Owners review logs and outcomes on a schedule | Rollback tested and actions limited to reversible or pre-approved ones |
Few systems need to reach the third stage. Plenty of value sits in the first two, and each move up should rest on evidence from the stage below. The assistive stage is AI augmentation in practice, since people stay in charge while the AI does the drafting.
Staying assistive a little longer is often the faster path overall, even though it feels slower. It needs fewer approvals, and it also builds the trust that the next stage depends on.
Kanerika Service
Agentic AI Services
Kanerika designs and runs AI agents with clear approval boundaries, least-privilege tool access and staged autonomy, from assistive to autonomous where the risk allows.
Explore Agentic AI ServicesA Go/No-Go Framework for Production Release
Every release decision should be a short meeting with evidence on the table. Instead of debating how well the demo went, the team reviews a scored framework.
Score each criterion 0, 1 or 2. Zero means no evidence, one means partial evidence with a plan, and two means proven. Each criterion also has a named gate owner who signs the score.
| Criterion | What a 2 looks like | Gate owner |
|---|---|---|
| Business baseline measured | Current cost, time or error rate recorded before the AI | Business owner |
| Representative evaluation set passed | Agreed pass marks met on real, recent cases | Product or ML lead |
| Integration live in the target workflow | Users reach the AI inside their existing tool | Engineering lead |
| Security and access review signed | Permissions, data handling and logging approved | Security lead |
| Fallback and rollback tested | Handoff to people and a rollback rehearsed | Operations lead |
| Run-cost estimate approved | Monthly run cost and cost per outcome signed off | Finance partner |
| Operating owner named | A person and team accountable after launch | Executive sponsor |
The rule is simple: any zero is a no-go, whatever the total. A high score with one zero still means the system can fail in a way nobody planned for. If your risk team already scores AI use cases, an AI risk assessment template gives every criterion the same fields.
Worked Example: Should Invoice Extraction Move to Production?
Here is an illustrative example, not a client result. A finance team has piloted AI that reads supplier invoices and then fills in the accounts payable system. The scores below are made up so that you can see how the rule works.
| Criterion | Score | Why |
|---|---|---|
| Business baseline measured | 2 | The team timed manual entry before the pilot |
| Representative evaluation set passed | 2 | Pass marks met on recent invoices from many suppliers |
| Integration live in the target workflow | 1 | Output lands in the AP system, but exceptions still go by email |
| Security and access review signed | 2 | Access and logging approved by the security lead |
| Fallback and rollback tested | 0 | Nobody has tested what happens if the service is down at month end |
| Run-cost estimate approved | 1 | The estimate covers inference but not human review time |
| Operating owner named | 2 | The AP manager owns it after launch |
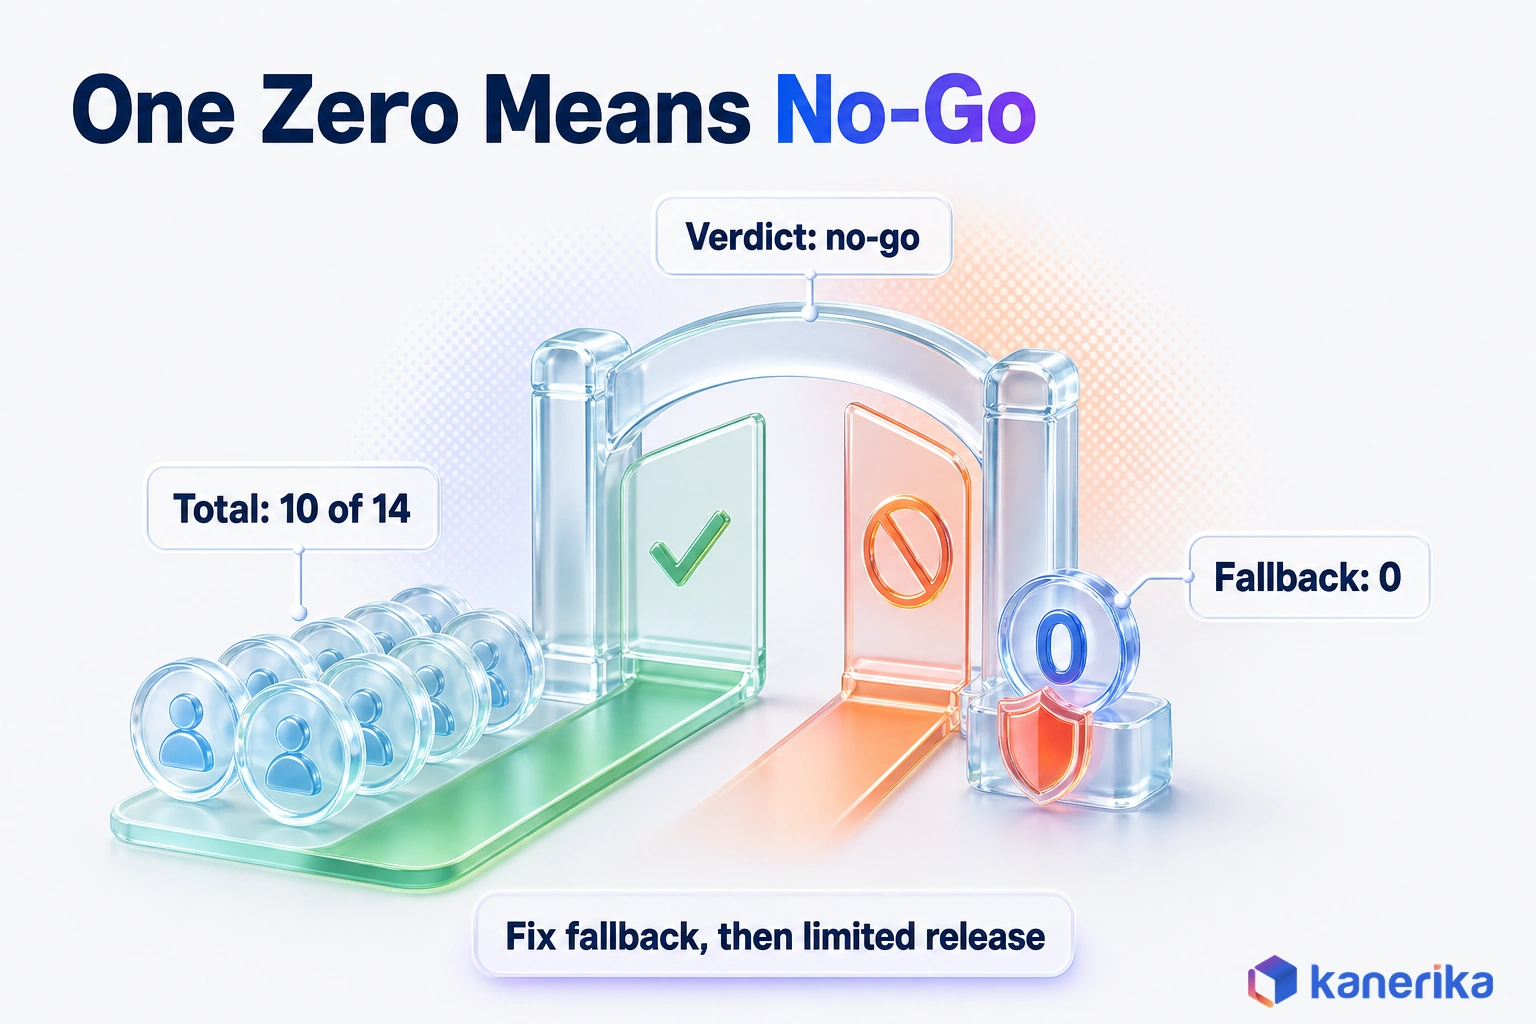
| Total | 10 of 14 | No-go: one criterion scores zero |
On paper, the total looks healthy at 10 out of 14. The verdict is still no-go, because fallback scored zero. Month-end close is the worst possible time to learn that invoices have stopped flowing.
The fix is narrow. The team rehearses a manual fallback, adds review time to the cost estimate and then rescores. With fallback at 1 or higher, the system moves to a limited release instead of waiting for a perfect score.
Release in Four Evidence-Based Stages
Even when a system passes the go/no-go review, it should not reach every user on day one. Staged release is the safest route, because it limits the damage from anything the review missed. Each stage also produces the evidence for the next one.
- Shadow mode. The AI runs on live inputs while people still do the work, and nobody acts on its output. Exit evidence: AI output matches or beats human decisions on agreed measures.
- Limited release. A small group of users works with the AI, and a person approves every output. Exit evidence: users accept the output and edit rates hold steady.
- Staged rollout. More teams or regions join in waves, with monitoring on each wave. Exit evidence: quality, latency and cost per outcome hold at higher volume.
- Full production. The system becomes business as usual under its operating owner. Exit evidence: support, monitoring and retraining run without the project team.
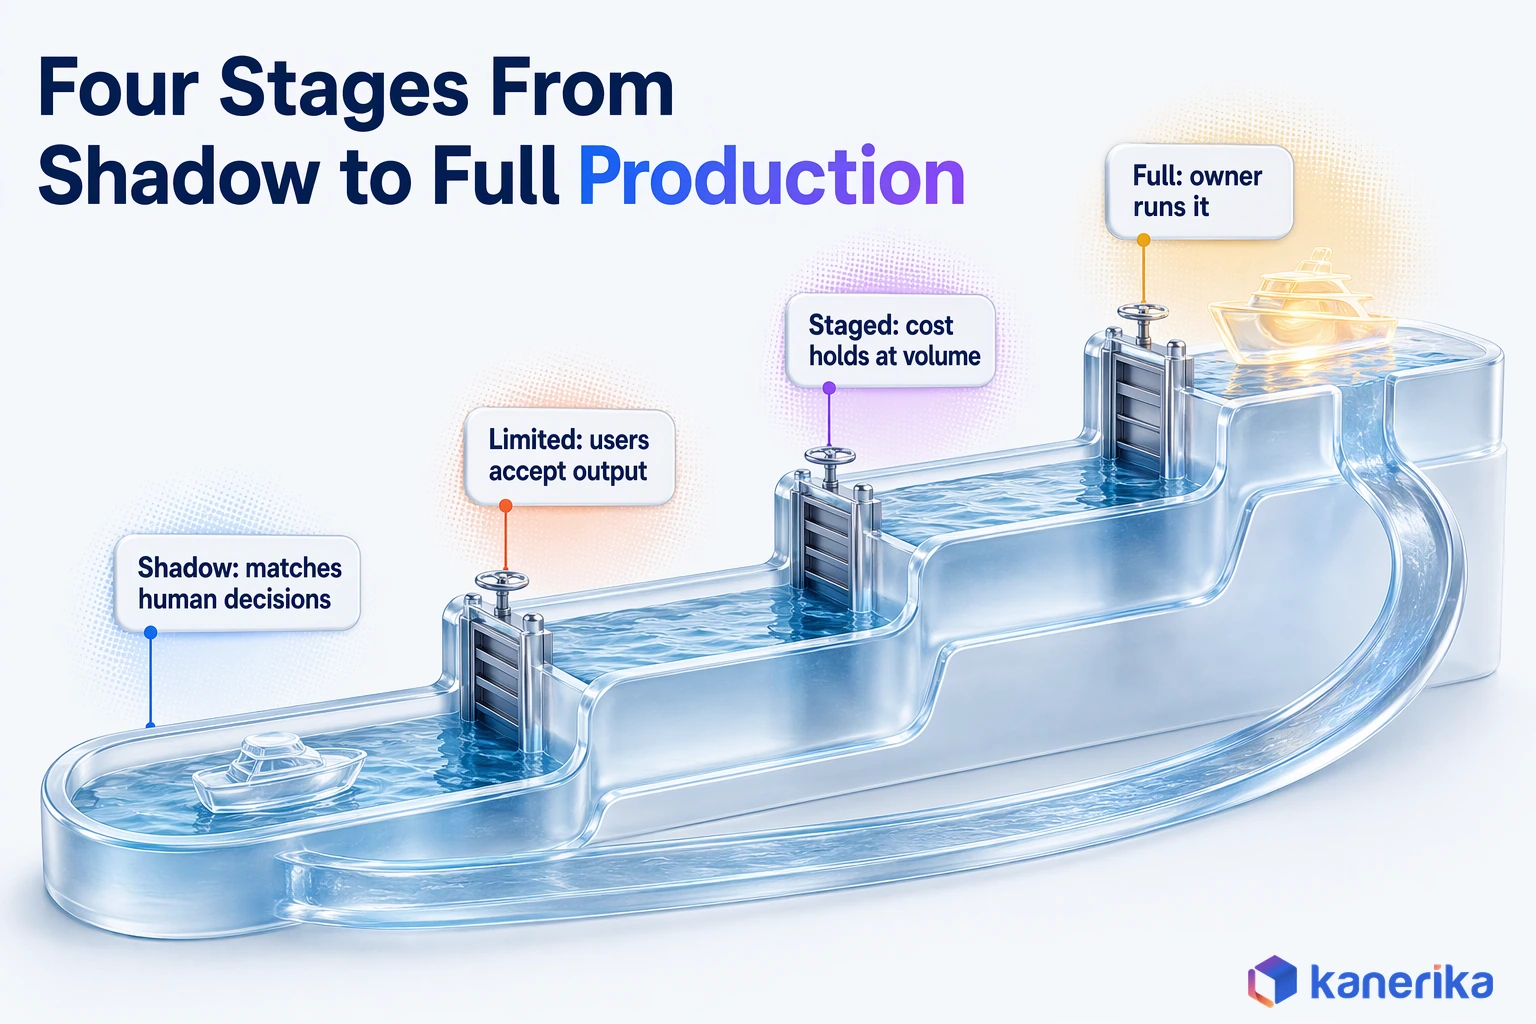
Every stage also has a clear way back. If a wave shows a problem, the team returns to the previous stage instead of patching a live system under pressure.
Build an Evaluation Harness for LLM and Agent Systems
Language models and agents change behavior when a prompt, model version or data source changes. An evaluation harness catches that shift before users do, much like regression tests in ordinary software.
A practical setup has four parts, and none of them needs exotic tooling.
- A golden set from real cases. Pull recent, representative cases from the pilot or from production logs, include the awkward ones, and record the correct answer for each.
- A regression suite. Run the full set on every prompt, model or retrieval change, and block the change if scores drop. Retrieval changes count too, because a RAG or agentic RAG pipeline can shift answers without any change to the model.
- Pass thresholds agreed before go-live. The business owner and the builders set the pass marks together, so nobody moves the line after seeing results.
- A human review sample. People grade a regular sample of live output, since that catches problems the golden set misses.
For agents, test the actions as well as the words, which our guide to agentic AI testing covers step by step. Check that the agent calls the right tool, passes valid inputs and stops when it should.
Operate It After Launch
Launch is when the operating work begins. Inputs drift as customers, products and documents change, so accuracy that held on launch day can slide within months.
- Monitoring tracks quality scores, latency, cost and usage on a dashboard the owner actually reads.
- Drift checks compare live inputs and outputs with the evaluation set and raise an alert when they diverge.
- Incident response defines who is paged, how users are told and when the system is switched off.
- Rollback restores the previous model, the previous prompt or the manual process within an agreed time, so users keep working.
- Agent permissions follow least privilege, and any irreversible action, such as a payment or a deletion, needs human approval.
Write all of this down before launch day, since an incident is the wrong moment to decide who can switch the system off. The same least-privilege thinking extends to AI supply chain security, which covers models, datasets, packages and agent tools.
For a lifecycle view of these controls across ML, LLMs and agents, see our playbook on AI model risk management.
What Does AI Cost to Run in Production?
Pilot budgets usually cover the model and the build team, but little else. Production then adds running costs that pilots never see, and some of them grow with every new user.
| Cost line | What drives it | How to keep it in check |
|---|---|---|
| Inference and compute | Request volume, prompt length and model size | Route simple requests to smaller models and cache repeat answers |
| Data pipelines | Number of sources, refresh frequency and volume | Reuse governed pipelines instead of one-off feeds |
| Integration | Systems touched and how often they change | Use stable APIs and own the connectors |
| Evaluation and monitoring | Test runs, dashboards and review time | Automate the regression suite and sample with care |
| Human review | Share of output a person checks | Lower review rates only as evidence allows |
| Support and retraining | Incidents, drift and new data | Schedule retraining instead of relying on emergency fixes |
| Security and compliance | Access reviews, audits and logging | Build controls once and reuse them across systems |
Inference is usually the first line teams try to trim, and LLM inference optimization can cut latency and cost without losing quality. It is still only one line of seven.
Track Cost per Successful Outcome
The number that matters most is cost per successful outcome. It divides the total run cost by the outcomes that were accepted without rework.
Cost per successful outcome = total run cost for the period ÷ outcomes accepted without rework in the same period
Consider a hypothetical month for a service-desk triage system to see why the denominator matters. It costs $15,000 to run and routes 12,000 tickets, but only 10,000 reach the right team without rework. The real cost is $1.50 per correctly routed ticket, against the $1.25 that a volume-based view would show.
That gap is why rework belongs in the business case. Setting the wider budget, however, is a separate exercise, which our guide to enterprise AI spending covers line by line. For the release itself, compare the figure with the baseline cost of the manual task, and the release decision gets much easier to make.
Talk to Kanerika
Model the Run Cost of Your AI Pilot
Kanerika helps you map every production cost line, set a cost per successful outcome and compare it with your manual baseline before release.
Talk to Our AI Team →How to Measure AI Success Once It Is Live
Success metrics should change as the system matures, so plan them by stage. Early on you prove quality, later you prove adoption and value, and at scale you prove that the gains hold.
| Stage | Quality | Adoption | Business value |
|---|---|---|---|
| Pilot | Pass rate on the evaluation set | Tester feedback | Estimated against the baseline |
| Limited release | Acceptance and edit rates | Share of eligible tasks that use the AI | Time saved per task, measured |
| Scale | Drift alerts and incident count | Active users over time | Cost per successful outcome against the baseline |
Take the invoice pilot from the worked example. First, in the pilot, the team reports one number, the pass rate on recent invoices from many suppliers. In limited release, the question then becomes how often AP clerks accept the extracted fields, and how many they edit first. At scale, the figure that matters is cost per accepted invoice against the timed manual baseline.
The edit rate is the early warning in that chain. When clerks start correcting more fields, quality has slipped before the cost figures move. That gives the owner time to act while the fix is still small.
Pick a few metrics for each stage and report them on a fixed schedule. A dashboard with forty measures tends to hide the one that is slipping.
Risks, Governance and Controls at Launch
Governance at launch comes down to a small set of controls with clear owners. You need to know what could go wrong, who watches for it and what happens when it does.
Two public frameworks help structure that work. The NIST AI Risk Management Framework 1.0 was released on January 26, 2023. NIST then added a Generative AI Profile on July 26, 2024.
ISO/IEC 42001:2023 is the AI management system standard. Your launch controls can map to both. Our side-by-side comparison of the two frameworks shows how they fit together.
| Risk | Control | Owner |
|---|---|---|
| Wrong or made-up output | Evaluation harness, human review sample and confidence thresholds | Product or ML lead |
| Sensitive data exposure | Data classification, masking and access limits on prompts and logs | Security lead |
| Unapproved agent actions | Least-privilege tool access and approval for irreversible steps | Engineering lead |
| Bias or unfair outcomes | Fairness tests on the evaluation set and review of flagged groups | Risk or compliance lead |
| Silent quality decline | Drift monitoring and scheduled re-evaluation | Operating owner |
| Vendor or model change | Version pinning and a regression run before every upgrade | Platform owner |
This table covers the launch itself. Each owner should also map to a control in your wider set of AI governance best practices. For the security rows, our map of LLM security tools sorts the options by gap.
For the full policy, roles and review cycle, see our guide to building an AI governance framework. Our overview of responsible AI practices then covers the principles, tools and standards behind it.
Which Processes Should Move to Production First?
The first production system sets the tone for every one that follows, so choose it with care. A quick, visible win buys patience for harder projects, while an early failure can freeze the whole program.
Good first candidates also tend to share five traits.
- High volume. The task happens hundreds of times a week, so small gains add up.
- Low ambiguity. Correct answers are clear enough to test against, so evaluation stays simple.
- A measurable baseline. You already know the time, cost or error rate before the AI arrives.
- Reversible errors. A mistake can be caught and corrected before it reaches a customer or the books.
- An existing workflow home. The AI can sit inside a tool people already use, so adoption is easier.
Invoice data capture and service ticket triage often fit all five. Credit decisions and clinical judgments usually do not, because errors are hard to reverse and the stakes are high. Those can still use AI, but they belong at the assistive stage until evidence builds.
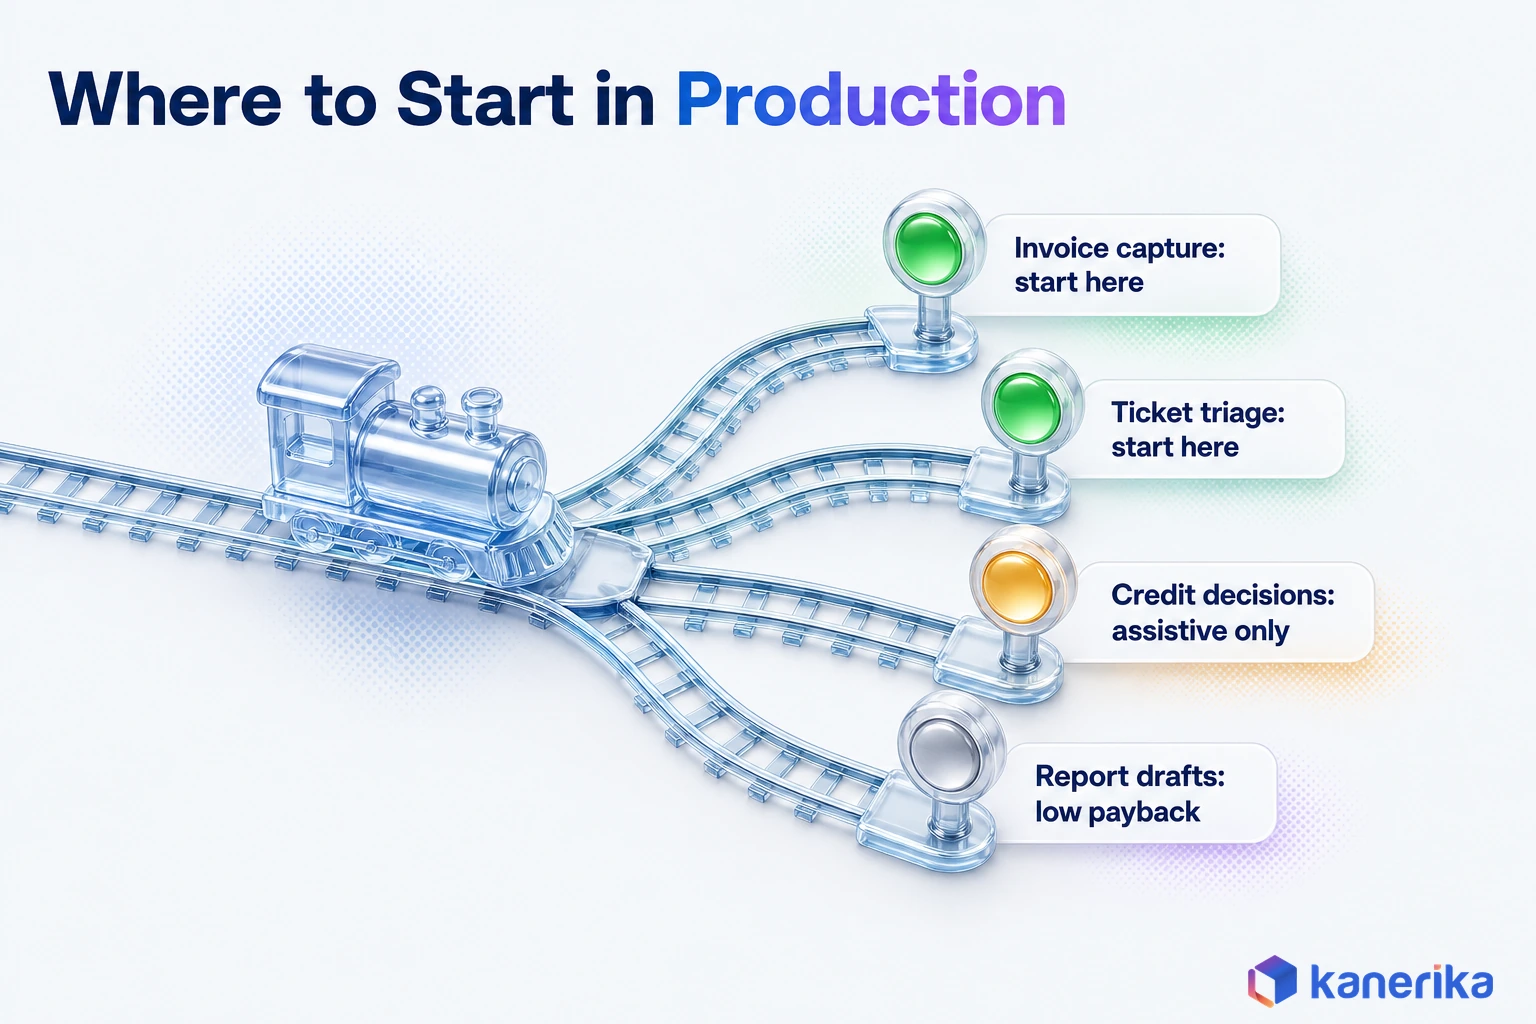
Low-volume tasks with easily reversed errors, such as drafting internal reports, are safe places to experiment. They rarely repay the full cost of a production release, though, so they make weak first candidates.
Ticket triage is also a common first step in contact center automation, because the volume is high and errors are easy to correct. For regulated decisions, our guide to generative AI in banking walks through use cases, risks and a roadmap to production.
Ownership, Sponsorship and Adoption
Every production AI system needs a person whose job includes it. Without an owner, the system drifts, nobody approves the next fix, and the budget disappears in the next planning cycle.
Three roles matter most. The executive sponsor ties the system to a business goal and protects its budget. Outcomes belong to the business owner, who also decides when the AI moves to a new stage. The operating team then keeps it running, from monitoring to retraining.
Adoption needs a plan of its own. People who used to do the task need to know what changes in their day and how to flag a bad answer. Short training inside the actual tool works better than a long slide deck.
Some processes will change, and that is healthy. When an approval step exists only because the old process was slow, removing it may deliver more than the AI does.
When several pilots compete for the same owners and budget, the decision moves up a level. That portfolio choice belongs in your wider digital transformation strategy, so each production release serves a shared goal.
Common Mistakes That Keep AI Pilots From Production
The same mistakes show up across industries and model types. Each one has a fix that costs far less before launch than after it.
- Treating the demo as proof. Fix it by scoring the go/no-go criteria before launch, using evidence from real cases.
- Building outside the workflow. Fix it by embedding the AI in a tool users open every day, such as the CRM or service desk.
- Testing on clean data only. Fix it by profiling live inputs before release and adding messy cases to the evaluation set.
- Skipping the baseline. Fix it by measuring the manual process before the pilot, so value has a reference point.
- Budgeting for inference only. Fix it by modeling every cost line, then tracking cost per successful outcome.
- Granting agents broad permissions. Fix it by starting with read access, adding actions one at a time and requiring approval for irreversible ones.
- Leaving ownership with the project team. Fix it by naming a business owner and an operating team before release.
- Jumping straight to autonomy. Fix it by moving from assistive to intelligent to autonomous only when evidence supports it.
Most pilots that stall make two or three of these at once. Fixing one usually exposes the next, so pair the scored review with a written readiness checklist that every release goes through.
Checklist
Enterprise AI Checklist for AI Readiness, Governance & Adoption
Work through readiness, governance and adoption steps before each AI release, from data and access checks to owners and monitoring.
Get the Checklist →How Kanerika Moves an AI Pilot to Production
Kanerika works with enterprises that have a promising pilot and need it running inside real operations. Our AI services and agentic AI teams follow the path this guide describes, in four steps.
- Pilot assessment. We score the pilot against the six gaps and the go/no-go criteria, so the work plan starts from evidence.
- Production design. We plan the integration into the existing workflow, the evaluation harness and the run-cost model before new code is written.
- Staged release. Systems start assistive, move to intelligent, and then become autonomous only where the risk allows it.
- Managed operation. We monitor quality, drift and cost after launch, and retrain models when the data changes.
Where speed matters, our forward deployed engineers work inside the client team. Integration problems then surface and get fixed close to the people who find them.
Proof From Client Work
A real estate developer backed by a large Middle-Eastern public investment fund wanted LLMs to process its vendor agreements. The contracts sat as unstructured PDFs in Oracle Content Management Cloud, so vendor search was slow and manual.
Kanerika began with readiness instead of the model. The team first analyzed the data environment, then assessed and upgraded the infrastructure for GCP readiness. Only after that did it build a chat interface with prompt criteria for vendor search.
The results followed that groundwork, with an 82% reduction in manual processing time and a 90% boost in vendor selection. Cloud integration efficiency also increased by 75%.
It is the pattern this guide argues for, with readiness first and scale second.
Case Study
90% Faster Vendor Selection with LLM Agreement Processing
Kanerika prepared a real estate developer’s data and GCP infrastructure, then built an LLM chat interface over vendor agreements, cutting manual processing time by 82%.
Read the Case Study →The Bottom Line
Enterprise teams go wrong when they judge a pilot by its demo and build it outside the daily workflow. They also leave evaluation, cost and ownership for later. Those gaps stall far more pilots than model quality does.
The way to ship is a disciplined path. Close the six gaps, score the seven go/no-go criteria, release in four stages, and then track cost per successful outcome.
If every criterion scores at least one, ship in stages. If any criterion scores zero, hold it in shadow mode and fix that gap first. That is how an AI pilot to production move ends with a system people actually use.
Frequently Asked Questions
How do you move AI from pilot to production?
Start by listing what the pilot never tested, such as integration, live data, security, evaluation, fallback and ownership. Score each gap with evidence and treat any zero as a no-go. Then release in stages, from shadow mode to limited release, staged rollout and full production. Each stage moves forward only when its exit evidence is in.
Why do most AI agent pilots fail to reach production?
Agent pilots usually stall for organizational reasons. Teams build them outside the tools people use, so adoption stays low. Costs rise at real volumes, and value was never measured. Gartner predicted in June 2025 that more than 40% of agentic AI projects will be canceled by the end of 2027. Rising costs and unclear value were the reasons.
What is the difference between an AI pilot and a proof of concept?
A proof of concept tests whether an idea is technically possible, often on sample data and without real users. A pilot runs the idea with real users on a limited scope to test value and fit. Treat the pilot as a rehearsal for production, with real data, real workflows and success measures agreed up front.
How much does it cost to run AI in production compared with a pilot?
Production usually costs more than the pilot because new cost lines appear. Beyond inference, budget for data pipelines, integration, evaluation, monitoring, human review, support, retraining and security work. Prices vary by model and volume, so track cost per successful outcome instead. Divide the total run cost by the outputs accepted without rework.
How do you evaluate an LLM or AI agent before go-live?
Build a golden set of real, representative cases with the correct answer for each. Agree pass thresholds with the business owner before testing starts. Run the set as a regression suite after every prompt, model or data change. For agents, also check tool calls and stopping behavior, and have people grade a regular sample of live output.
What share of AI projects fail before reaching production?
RAND reports that, by some estimates, more than 80 percent of AI projects fail. That is about twice the failure rate of IT projects without AI. In RAND’s interviews, 30 of 50 people named persistent data quality problems as a cause. Planning for data, evaluation and ownership early is the most reliable way to stay out of that group.
What's the best approach to scale AI agents across an enterprise?
Scale one proven agent before adding more. Run it through the go/no-go review, release it in waves, and watch quality, latency and cost per outcome at each wave. Then reuse the same evaluation harness, access controls and monitoring for the next agent. Shared foundations make every later agent faster and safer to launch than the first one.
How long does it take to move an AI agent from pilot to production?
Timing depends on the gaps the pilot left open, so there is no standard duration. A pilot already embedded in the target tool, using live data and with a named owner, moves quickly. One that needs new integrations, data cleanup or security reviews takes longer. Scoring the release gates early shows which work will drive the schedule.
What's the difference between assistive, intelligent, and autonomous AI agents?
An assistive agent drafts or suggests, and a person approves every output. An intelligent agent handles routine decisions and flags exceptions for people to review. An autonomous agent completes tasks end to end within set limits, while owners review its logs on a schedule. Each stage should be earned with evidence from the stage before it.
Should we build AI agents as standalone applications or integrate them into existing tools?
Integrate them into existing tools wherever you can. A separate app adds a login, a new window or a copy step, and busy users often skip it. An agent inside the CRM, service desk or ERP screen gets used because it sits next to the work. Build standalone only when no existing tool can host the output.
How do we identify the right processes to automate first?
Look for five traits in a candidate process. The task runs at high volume, correct answers are clear, and you already know its manual cost or error rate. Errors should be easy to catch and reverse, and the AI should fit inside a tool people already use. Invoice data capture and ticket triage often meet all five.
Does AI implementation require changing our existing processes?
Some change is usually needed, though often less than teams expect. The AI should fit into the current workflow first, so people keep their tools and habits. Over time, steps that existed only because the old process was slow can be removed. Plan short training inside the actual tool and explain what changes in each role.
What are the biggest AI implementation failures?
Common failures include an agent nobody uses because it sits outside the workflow, and a model that degrades as live data drifts. Others are runaway inference costs, agents with broader permissions than they need, and systems with no owner after launch. Each one is cheaper to prevent with a release gate than to repair in production.