TL;DR
Parameter-efficient fine-tuning (PEFT) trains a small set of new or selected weights on a frozen model, and LoRA is the right default for most teams. Pick QLoRA when GPU memory is the limit, since its 4-bit base let researchers fine-tune a 65-billion-parameter model on one 48GB GPU. Test DoRA, AdaLoRA, rsLoRA or PiSSA only after a benchmark on your own data shows plain LoRA leaving a gap. Pick full fine-tuning when a hard new domain needs more capacity than an adapter gives, and pick RAG when the model needs facts that change. PEFT cuts training memory and storage per task, but the model you serve is still the full base model. As of November 2026, PEFT works on open-weight models such as Qwen3.8-27B and gpt-oss-20b through peft 0.21.2, because hosted frontier models do not expose their weights.
Key Takeaways
- Parameter-efficient fine-tuning freezes the base model and trains a small fraction of its parameters, often under 1% to a few percent depending on the method.
- LoRA adds no inference latency once its weights are merged into the base model with
merge_and_unload(); unmerged adapters add some overhead. - QLoRA’s 4-bit NF4 base made a 65-billion-parameter fine-tune fit on one 48GB GPU, according to the 2023 paper.
- LoRA learns less than full fine-tuning on hard, out-of-domain tasks, but it also forgets less of what the base model already knew.
- Rank, alpha and target modules move results more than any other setting, so start at rank 8 or 16 and run a short sweep.
- One base model can serve many task adapters at once, which is why PEFT changes the cost of multi-tenant LLM deployments.
A 65-Billion-Parameter Model, One 48GB GPU
In 2023, researchers fine-tuned a 65-billion-parameter model on a single 48GB GPU and matched full 16-bit fine-tuning, according to the QLoRA paper. Full fine-tuning a model that size means gradients and optimizer states for all 65 billion weights, spread across a multi-GPU cluster.
Picture a bank that wants ten specialist behaviors from one model: a claims classifier, a contract extractor, a style-matched writer. Full fine-tuning then means ten full model copies to train, store and monitor. Parameter-efficient fine-tuning instead turns that into ten small adapter files on one shared base.
Cheap training, however, moves the hard questions elsewhere. Which parameters do you train, which rank do you pick, and do you merge the adapter or serve it separately? This guide answers each one, so you can plan before you train.
What Is Parameter-Efficient Fine-Tuning?
Parameter-efficient fine-tuning is a family of techniques that adapts a pretrained model by training only a small set of weights. The rest of the model stays frozen, so it keeps every weight it was released with.
Think of a generative AI model as a large, finished machine. Instead of rebuilding every part, you bolt on a small, adjustable component and tune only that. The trainable part is also small, often well under 1% of the total parameter count. That one design choice is why PEFT costs so much less to train than updating every weight.
Dataset size also causes most of the confusion here. Pretraining a foundation model needs internet-scale text, but fine-tuning works with far smaller sets. A few thousand to a few hundred thousand instruction-formatted examples is the usual range for a single task or domain.
For example, a team with 5,000 labeled support tickets is a typical case. That set is far too small to pretrain anything. Still, it is often enough to teach a strong base model the team’s categories and reply format. So comparing your data against pretraining scale is the wrong benchmark.
PEFT is also model-agnostic. Early papers tested it on encoder models like BERT, while today it runs almost entirely on decoder-only, open-weight LLMs. Kanerika’s guide to LLM architecture explains the transformer layers that adapters attach to.
How PEFT Works in Four Steps
Every PEFT method follows the same basic loop, whatever it calls its trainable part. The steps below also show where the savings come from.
- Freeze the base model. Every original weight is set to not require gradients, so the optimizer never touches it.
- Inject or select trainable parameters. The method adds a low-rank matrix pair, an adapter module or a soft prompt, or it unfreezes a small existing subset such as bias terms.
- Train only those parameters. Forward and backward passes still run through the whole frozen model, but gradients and optimizer states exist only for the small trainable set.
- Save, then merge or swap. The result is a small adapter file, usually megabytes rather than gigabytes. You either merge it into the base weights or keep it separate so several adapters can share one base.
Parameter-Efficient Fine-Tuning vs Full Fine-Tuning
The table below shows where PEFT and full fine-tuning really differ, so you can judge the trade. It also corrects two claims that circulate often: PEFT does not shrink the served model, and it is not uniformly better at generalizing.
| Criteria | Full Fine-Tuning | PEFT (LoRA Family) |
|---|---|---|
| Trainable parameters | 100% of model weights | Typically under 1% to a few percent |
| GPU memory during training | Weights, gradients and optimizer states for every parameter | Full weights for the forward pass; gradients and optimizer states only for the small trainable set |
| Training data needed | Benefits from larger, broader task data | Works with smaller task-specific sets, though more data still helps |
| Storage per task | A full model copy per task | A small adapter file per task, from a few megabytes to a few hundred |
| Served model size | One full model per task | Still the full base model; the adapter does not replace it |
| Inference latency | Baseline latency | No added latency once merged; some overhead if adapters stay unmerged |
| Multi-task serving | Swap full models | One base model hosts many adapters |
| Generalization and forgetting | Learns hard new domains more completely, with higher risk of forgetting | Learns less on hard new domains, but forgets less |
| Governance overhead | One large artifact per task | Many small adapters to version and tie to their base model |
Read the last two rows together. The trade is capacity for stability, and the governance cost moves from a few big files to many small ones.
Where SFT and Instruction Tuning Fit
Supervised fine-tuning, or SFT, is a training objective, not a rival to PEFT. It means training on labeled input-output pairs, usually instructions and responses, so the model follows them more reliably.
Still, the two answer different questions. SFT describes what data and objective you train on, while PEFT describes which parameters move during that training. Hugging Face’s TRL SFTTrainer accepts a peft_config argument, so a team can run standard SFT while updating only a LoRA adapter.
Preference training follows the same pattern. A LoRA adapter can be trained with direct preference optimization (DPO) or another feedback method, exactly as it is with SFT. Many teams run SFT first, then a short preference pass, each producing its own adapter.
Kanerika’s guide to LLM training places SFT next to pretraining and preference alignment in the wider pipeline. This article, by contrast, stays on the parameter-efficiency layer.
Kanerika Service
LLM Development Services
Kanerika designs, adapts and deploys language models for enterprise workloads, from the retrieval-or-adaptation decision to LoRA baselines, evaluation and serving.
Explore LLM DevelopmentWhy Full Fine-Tuning Stopped Being the Default: The Benefits of PEFT
Full fine-tuning updates every weight, so it must also store gradients and optimizer states for every weight. Adam-style optimizers keep roughly two extra numbers per parameter, which is why memory balloons well past the size of the model itself.
Then two shifts made PEFT the practical default. Open-weight models became good enough to adapt rather than only prompt. Organizations also wanted more specialist behaviors from each model, and a full training run per behavior stopped making sense.
Five Benefits of Training an Adapter
Here is what changes when you train an adapter instead of the whole network:
- Training memory drops. Gradients and optimizer states exist only for the small trainable set, so the job fits on fewer or smaller GPUs.
- Storage per task shrinks. Each task saves a small adapter file instead of a full model copy.
- Per-task deployment gets simpler. One base model can host many adapters, so a new behavior does not mean a new server.
- Forgetting goes down. The frozen base keeps its general skills, and research shows LoRA preserves more of them than full fine-tuning.
- Data needs fall. A narrow training signal moves only a few parameters, so a few thousand clean examples often suffice.
Memory Math for a 27B Model
A rough memory estimate makes the first benefit concrete. Assume a 27B-parameter model and standard mixed-precision training with Adam. Each parameter then needs about 16 bytes. That covers 2 for the bf16 weight, 2 for its gradient, 4 for an fp32 master copy and 8 for two Adam states.
Full fine-tuning that model needs roughly 432GB before activations, which means several 80GB GPUs. Held in 4-bit, the frozen weights take about 13.5GB, and only the small adapter carries gradients and optimizer states. That gap, before activations and buffers, is the whole reason QLoRA fits on one card.
Still, none of these benefits shrinks the model at inference. The served model is still the full base, plus a small adapter.
The Three Families of PEFT Methods
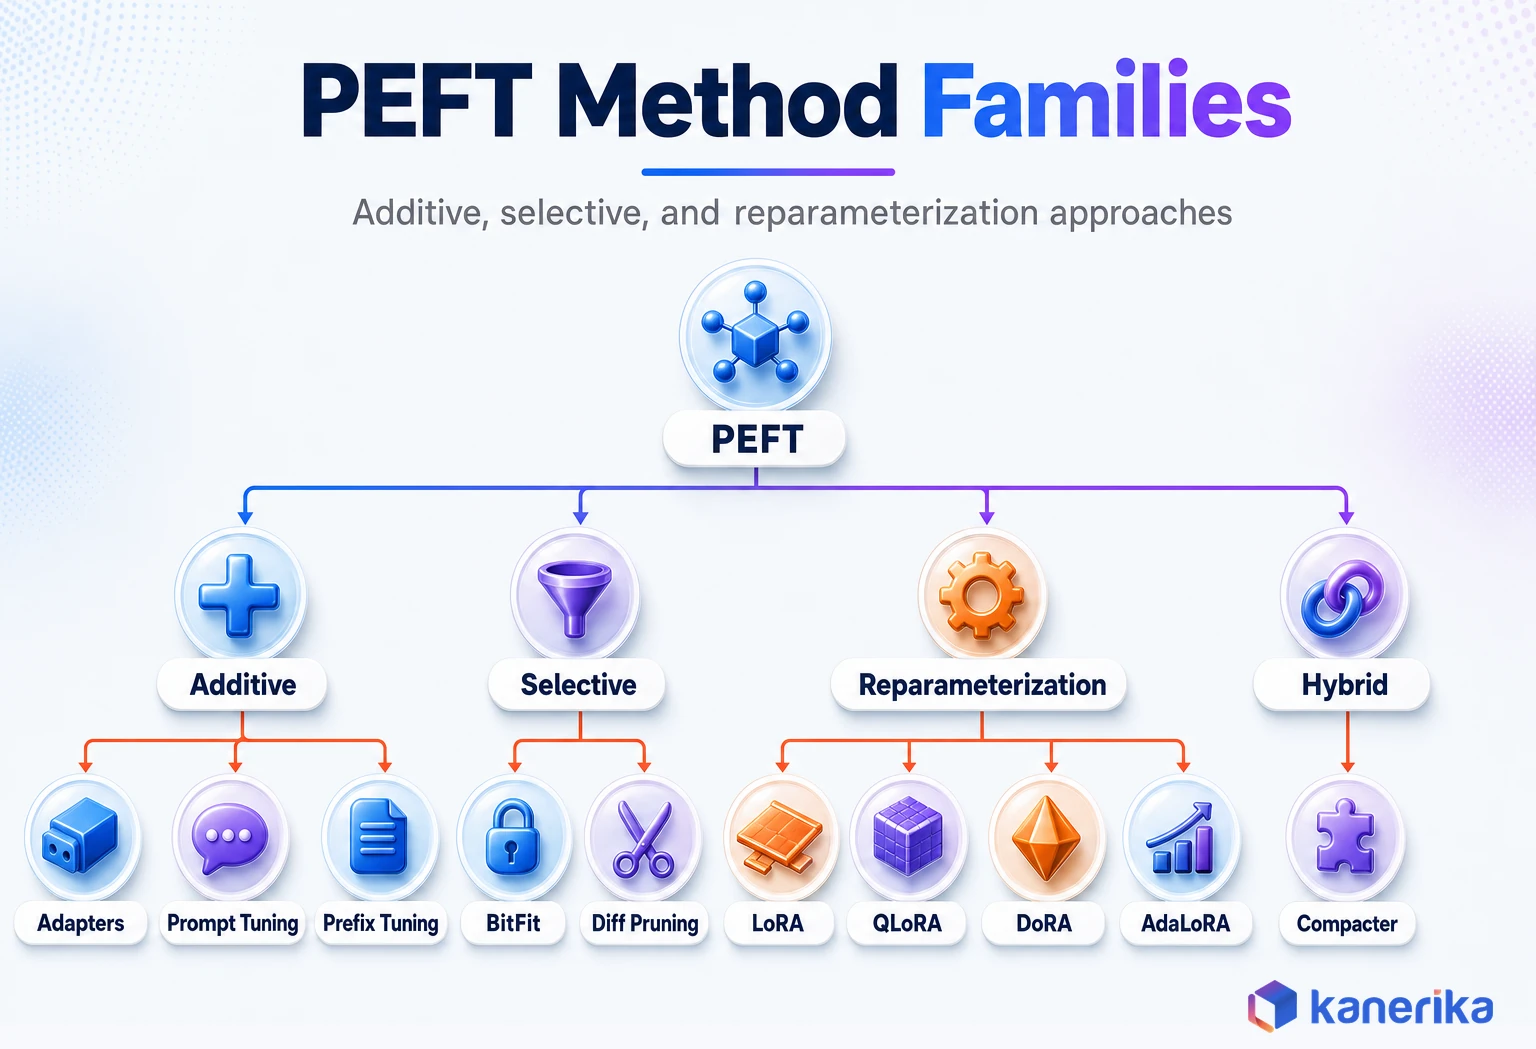
Most PEFT methods fall into three main families, and the family tells you what to expect before you read a benchmark. A 2023 critical review, Xu et al., uses five groups: additive, partial, reparameterized, hybrid and unified fine-tuning. Partial is what this guide calls selective, and those first three groups cover nearly every method teams deploy.
Consider a team choosing between a soft prompt and a LoRA adapter for the same task. The first adds new inputs and cannot merge into the weights, while the second can. That difference comes straight from the family each method sits in.
Additive Methods: Add New Parameters
Additive methods leave every original weight alone and insert new trainable parameters instead. Bottleneck adapters, prompt tuning and prefix tuning all sit here. They keep the deployment footprint small, but most of them cannot merge into the base weights the way LoRA does.
Selective Methods: Train a Subset of Existing Weights
Selective methods, by contrast, add nothing new. They unfreeze a thin slice of existing weights, such as bias terms in BitFit, and train only that slice. They are simple to implement, but a bias-only update has little room to learn a complex behavior.
Reparameterization Methods: Decompose the Update Itself
Reparameterization methods, the family LoRA belongs to, learn a compact factorization of the weight update. That factorization can then be added back into the original weights at deployment time.
QLoRA, DoRA, AdaLoRA, rsLoRA, PiSSA, LoRA+, VeRA and LoftQ all vary this one idea, so they share its strengths. The peft LoRA guide lists 11 initialization options alone, which shows how much work this family attracts. Hybrid recipes such as Compacter mix low-rank structure with parameter sharing, but they are rare in production.
| Family | What It Trains | Mergeable Into Base? | Typical Members |
|---|---|---|---|
| Additive | New modules or soft prompts beside the frozen model | Usually not | Bottleneck adapters, prompt tuning, prefix tuning |
| Selective | A small subset of existing weights | Already part of the base | BitFit, diff pruning |
| Reparameterization | A low-rank factorization of the weight update | Yes | LoRA, QLoRA, DoRA, AdaLoRA, rsLoRA, PiSSA, VeRA |
| Hybrid | Mechanisms from more than one family | Depends on the recipe | Compacter |
If merging matters for your serving plan, the table already narrows the choice to one family. That is why most production teams start with reparameterization.
How LoRA Fine-Tuning Works
LoRA, short for Low-Rank Adaptation, leaves a weight matrix frozen and learns a small correction beside it. The effective weight becomes W’ = W + BA, scaled by lora_alpha divided by the rank r.
A concrete example helps, because the savings are easier to see in numbers. Take a 4,096 by 4,096 attention projection, which holds about 16.8 million weights. At rank 8, matrix A is 8 by 4,096 and matrix B is 4,096 by 8, so LoRA trains 65,536 weights for that layer. That is about 0.4% of the original matrix, as the original LoRA paper describes in general form.
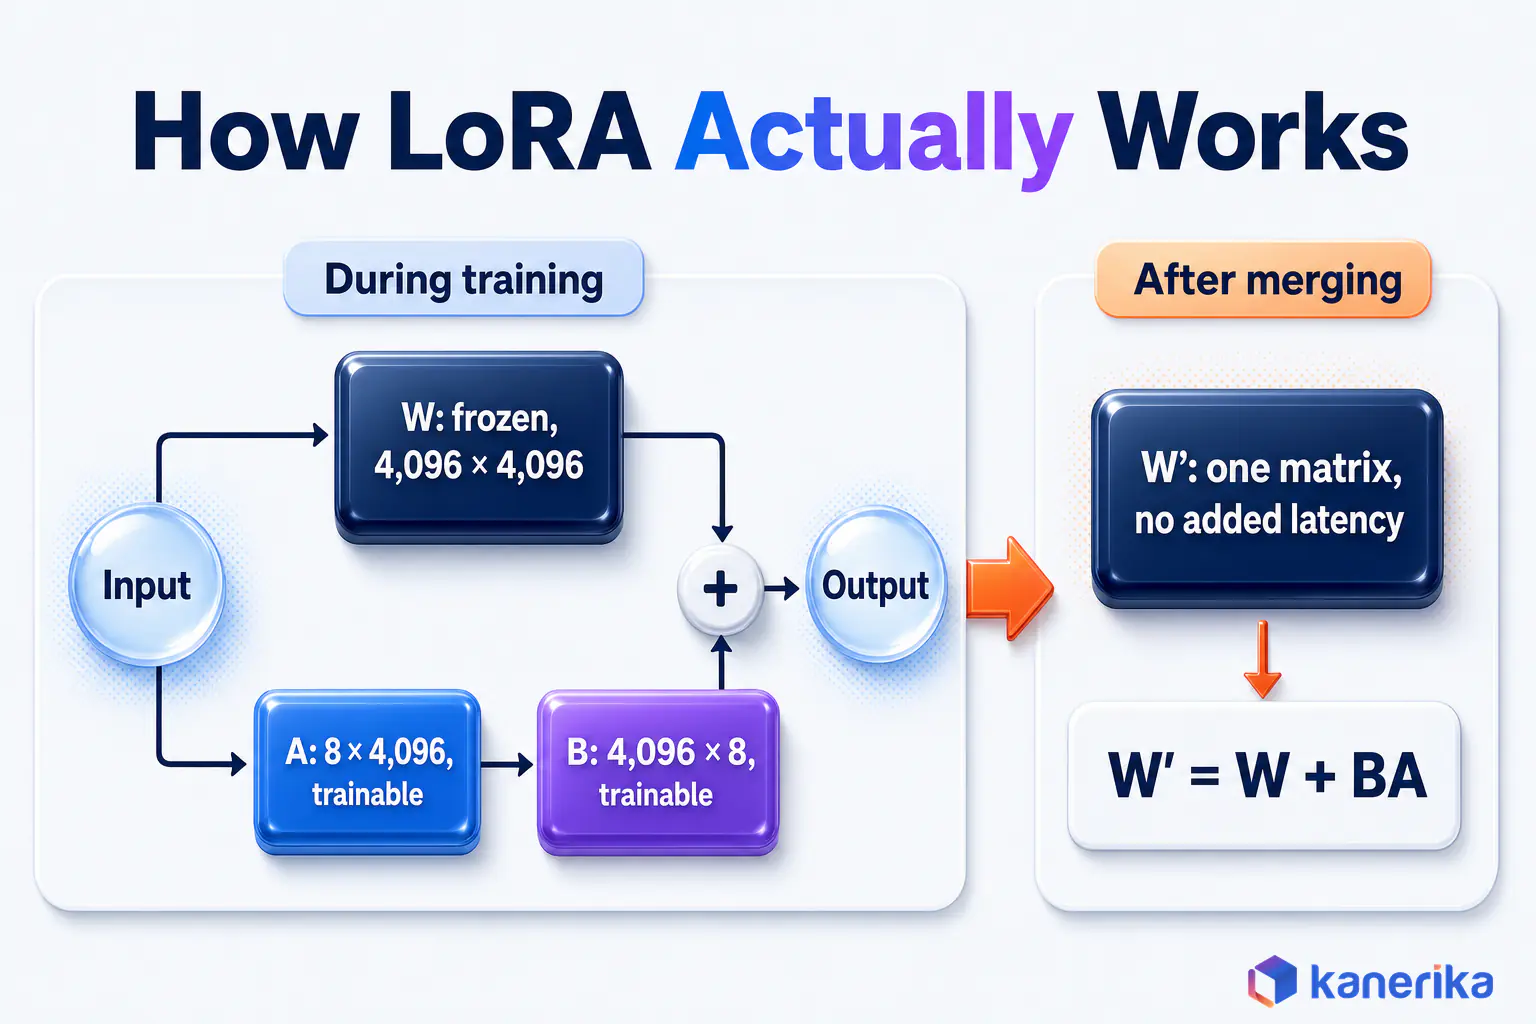
First, A projects the input down to rank r, and then B projects it back up. Only A and B train, while W never changes. The rsLoRA option, use_rslora=True, changes the scaling from lora_alpha/r to lora_alpha/sqrt(r). That keeps higher ranks from training too timidly.
Target Modules, Rank and Alpha
Adapters usually attach to the attention projections, meaning the query, key, value and output matrices. Many teams also add the feed-forward layers. No single set of target modules is correct for every task, so test a narrow and a broad set against each other.
Rank and alpha also need tuning. A higher rank gives more capacity, but past a point the extra parameters mostly raise training cost without a matching quality gain.
The rank is best read as a budget for how many independent directions the update may change. A formatting task, such as always answering in a fixed JSON schema, needs few directions, so rank 8 is often plenty. A task that teaches new reasoning patterns, such as a niche programming language, may need rank 32 or more.
Alpha then sets how loudly that update speaks relative to the frozen weights. Doubling alpha at a fixed rank doubles the scale of BA, so treat the two as a pair. Change one, and recheck the other on the same validation set.
Why Merging Matters
One more property also makes LoRA attractive for production. After training, BA can be added straight into W, so the served model has the base architecture and the base latency. Teams that switch behaviors per request keep adapters unmerged instead, trading a little latency for flexibility.
Mergeability, small files and simple tooling are why LoRA became the face of parameter-efficient fine-tuning. Nearly every variant in the next section keeps that merge property, so you rarely give it up by testing one.
LoRA Variants: QLoRA, DoRA, AdaLoRA, rsLoRA, PiSSA, LoRA+, VeRA and LoftQ
Each LoRA variant fixes one specific weakness rather than replacing the idea. Knowing which weakness it fixes tells you when to reach for it.
QLoRA: When GPU Memory Is the Limit
QLoRA loads the frozen base model in a 4-bit format called NF4. It then quantizes the quantization constants a second time and uses paged optimizers to avoid memory spikes. The trainable LoRA matrices, however, stay in higher precision.
NF4 is easier to grasp with an analogy. Pretrained weights cluster around zero in a bell-shaped curve, so NF4 places its 16 possible values where weights are dense. Fewer levels go to rare extreme values, which keeps the rounding error small where it matters most.
During training, each 4-bit block is converted back to bf16 just long enough for the math. Gradients flow through those temporary values into the LoRA matrices, while the stored base never changes.
The headline result is the one this guide opened with: a 65-billion-parameter model fine-tuned on one 48GB GPU, matching 16-bit fine-tuning. The paper’s Guanaco models reached 99.3% of ChatGPT’s score on the Vicuna benchmark, a figure tied to that benchmark only.
DoRA: Separating Magnitude from Direction
DoRA, or Weight-Decomposed Low-Rank Adaptation, splits each weight into a magnitude and a direction. It then applies LoRA only to the direction part. The paper reports steady gains over plain LoRA, with no added inference cost once merged.
The intuition is that full fine-tuning tends to change a weight’s direction and its size in different ways. Plain LoRA couples the two, while DoRA lets them move separately, which brings its learning pattern closer to full training.
In the peft library, DoRA is one flag, use_dora=True, on a normal LoRA config. DoRA adds more overhead than plain LoRA, so the peft LoRA guide recommends merging its weights for inference.
AdaLoRA: Spending the Rank Budget Where It Matters
AdaLoRA assigns rank adaptively across layers with an SVD-style parameterization. Layers that matter more get a larger effective rank, while the rest get pruned down. Its advantage is largest at small parameter budgets, where every unit of rank counts.
rsLoRA and PiSSA
rsLoRA changes just one number, so it is cheap to test. With use_rslora=True, peft scales the update by lora_alpha/sqrt(r) instead of lora_alpha/r. Standard scaling shrinks the update as rank grows, so rsLoRA makes high-rank runs worth trying.
PiSSA, by contrast, changes where training starts. Instead of random values, it initializes the adapter from the principal singular components of the original weights. You enable it with init_lora_weights="pissa", which runs an SVD that can take minutes, or a faster "pissa_niter_[n]" option.
The PiSSA paper reports faster convergence and better scores than LoRA. Treat that as a reason to test it on your data, not as a promised gain.
LoRA+, VeRA and LoftQ
LoRA+ keeps LoRA’s structure and gives matrices A and B different learning rates. Its paper reports gains of 1% to 2% and up to roughly twice the training speed at the same compute.
VeRA shares one pair of frozen random matrices across all layers and trains only small scaling vectors. That cuts trainable parameters far below LoRA while the paper reports similar quality.
LoftQ initializes the LoRA matrices to offset the error that quantization introduces. The paper shows it helps most at aggressive 2-bit and mixed 2-to-4-bit settings, because that is where quantization error is largest.
The table compares what each variant changes and when it earns a place in your plan.
| Variant | What It Changes | When to Use It |
|---|---|---|
| QLoRA | Holds the frozen base in 4-bit NF4 | GPU memory during training is the hard limit |
| DoRA | Splits weights into magnitude and direction | Plain LoRA leaves a measured quality gap |
| AdaLoRA | Allocates rank per layer | The parameter budget is tight |
| rsLoRA | Scales by lora_alpha/sqrt(r) | You want to test high ranks |
| PiSSA | Starts from principal singular components | Convergence is slow from random initialization |
| LoRA+ | Separate learning rates for A and B | You want faster training at the same compute |
| VeRA | Shared random matrices plus scaling vectors | You store many adapters on a tight storage budget |
| LoftQ | Quantization-aware initialization | You train on a 2-bit or mixed 2-to-4-bit base |
PEFT Methods Beyond LoRA: Adapters, Prompt Tuning and Prefix Tuning
Before LoRA became the default, additive methods were the main way to adapt a large model cheaply. They still win in a few situations, so they are worth understanding.
Imagine a platform that must keep each customer’s adaptation strictly isolated and never merged. An adapter or soft prompt that lives outside the weights suits that rule well, because nothing ever merges. The three methods below are the ones you will meet most often.
Bottleneck Adapters
Houlsby et al.’s adapter paper inserted small bottleneck modules inside each transformer layer. Each module is a down-projection, a nonlinearity and an up-projection, and only those modules train.
The paper came within 0.4% of full fine-tuning on the GLUE benchmark while training roughly 3.6% of parameters per task. That result proved, years before LoRA, that a frozen model plus a small module could nearly match full training.
Prompt Tuning
Prompt tuning, from Lester et al., prepends trainable “soft prompt” embeddings to the input. The whole model stays frozen, and the gap with full fine-tuning closes as model scale grows.
Still, do not confuse it with prompt engineering. Prompt tuning trains vectors that never appear as readable text, while prompt engineering edits the words you send.
Prefix Tuning and P-Tuning
Prefix tuning, from Li and Liang, trains continuous vectors at every transformer layer, not just the input. The paper trains around 0.1% of parameters and does best, relative to full fine-tuning, in low-data settings.
P-tuning learns prompt embeddings through a small prompt encoder. Its successor, P-Tuning v2, applies deep prompt tuning, with trainable prompts at every layer much like prefix tuning. Neither touches the base model’s weights, so neither can merge into them.
So when do these older methods still win over LoRA? Prompt tuning suits very large bases, where a small soft prompt closes most of the gap. Bottleneck adapters suit platforms that must keep each task’s module physically separate. For most other jobs, LoRA’s mergeability and tooling make it the safer first choice.
Talk to Kanerika
Not Sure Which PEFT Method Fits Your Workload?
Talk to Kanerika’s AI engineers about choosing between LoRA, QLoRA, adapters and retrieval for your data, hardware and serving plan.
Schedule a Demo →Selective PEFT and What IA3 Actually Does
Selective PEFT trains a few of the weights the model already has, without adding a new structure. The simplest example shows both its appeal and its limit.
BitFit unfreezes only the bias terms and then trains those. It is fast to set up, but its small capacity means it usually trails LoRA on harder tasks. Diff pruning is more flexible, learning a sparse mask so that only scattered individual weights change.
What Is IA3?
IA3 stands for Infused Adapter by Inhibiting and Amplifying Inner Activations. It comes from the paper behind the T-Few method and has its own peft IA3 reference.
IA3 often gets filed next to selective methods because it trains so few weights. It actually adds new ones, so Xu et al. class it as additive. It learns three small vectors per targeted layer. Those vectors rescale the key, value and feed-forward activations element by element, instead of adding a matrix product as LoRA does.
Because it learns vectors rather than matrices, IA3 usually trains fewer parameters than LoRA at similar coverage. Its authors framed it as a cheaper alternative to in-context learning. It does not need more memory or compute than LoRA, a claim that circulates often and is wrong.
Where does IA3 fit in practice? It suits few-shot adaptation, where a team has only dozens of labeled examples and wants the smallest possible adapter. It is also handy when thousands of per-user adapters must stay cheap to store. For larger datasets and harder tasks, LoRA usually has the capacity edge.
Which Open-Weight Models Can You Fine-Tune with PEFT in November 2026?
PEFT needs access to the model’s weights, so the first filter is simple: only open-weight models qualify. Hosted frontier models such as Claude Opus 5.5, GPT-6.1 Sol and Gemini 4 Argon do not expose their weights at all.
Dense or Mixture-of-Experts
Architecture is then the second filter. A dense model runs every parameter on every token, so LoRA targets its attention and feed-forward layers as usual. A mixture-of-experts (MoE) model routes each token through a few experts, which changes what you target.
Take gpt-oss-20b as an example. It holds 21B parameters, but only 3.6B are active per token. The peft LoRA guide explains that many MoE models store expert weights as parameter tensors, not linear layers. You target them with target_parameters and a per-layer rank_pattern. The same guide warns that LoRA on expert layers can slow inference substantially, so it recommends merging. It also notes that vLLM serves fused MoE expert layers since v0.11.2.
The table lists open-weight bases that fit a PEFT plan as of November 2026, with the facts that affect fine-tuning.
| Model | Architecture | License | Note for PEFT |
|---|---|---|---|
| Qwen3.8-27B | Dense | Apache 2.0 | 262,144-token native context, extendable to 1M; standard LoRA targets apply |
| Mistral Small 4 | MoE, 119B total, 6.5B active | Apache 2.0 | 256k context; target expert layers for full coverage |
| gpt-oss-20b | MoE, 21B total, 3.6B active | Apache 2.0 | Runs within 16GB of memory thanks to MXFP4 expert weights |
| gpt-oss-120b | MoE, 117B total, 5.1B active | Apache 2.0 | Runs on a single 80GB GPU such as an H100 |
| DeepSeek V4.1-Flash-1017 and V4-Pro-0813 | See the model cards | MIT | 1M-token context, per DeepSeek’s own pages |
| Mistral Large 4 | About 1T total, 52B active | Mistral Ecosystem Open-Weight License (modified MIT) | Model-as-a-service operators need a commercial license |
| Phi-4-mini-instruct | Dense, 3.8B | MIT | 128K context, released February 2025; a small, cheap base |
License and Model Size
License is the third filter. Apache 2.0 and MIT are simple. Custom licenses, such as those on Mistral Large 4, GLM-5.3 and Qwen3.8-Max, need a careful read before commercial use. Kanerika’s guide to open-source LLMs compares the wider field.
Small bases also deserve a look. A 3.8B base with a LoRA adapter can be enough for a narrow, high-volume task, as Kanerika’s guide to small language models explains. Teams weighing the DeepSeek line can start with the DeepSeek overview.
Matching the Base to Your Hardware
How do you choose between a dense and an MoE base for a PEFT plan? A dense model keeps targeting simple and memory use predictable, so it is the easier first project. An MoE model gives more total knowledge per unit of active compute, but you must decide whether the adapter touches the experts or only attention.
Serving hardware often settles the question. gpt-oss-120b runs on a single 80GB GPU, which makes it a practical large base for one-server adapter hosting. A dense 27B model in bf16 needs about 54GB for weights alone, so it also fits one 80GB card with room for adapters.
Kanerika Service
AI Model Engineering
Kanerika helps teams pick an open-weight base, check its license and adapt it with the PEFT method that fits the task and the serving hardware.
Explore AI Model ServicesPEFT Trade-Offs: Memory, Training Cost, Latency and Accuracy
Trainable parameter count is the number most PEFT comparisons lead with, and it is a poor stand-in for real cost. Training memory has five parts: frozen weights, trainable weights, their gradients and optimizer states, activations for the backward pass, and temporary buffers.
Cut trainable parameters from 1% to 0.1% and only two of those parts shrink. The frozen weights and the activations stay about the same, which is why QLoRA’s 4-bit base is a separate lever. One lever shrinks how many weights get gradients, while the other shrinks the frozen weights themselves.
Inference latency, by contrast, depends more on deployment than on method family. A merged adapter runs at base speed, while an unmerged adapter or a soft prompt adds runtime work. Storage tells a similar story: a PEFT adapter shrinks the file you add, not the model that runs.
Here is how that plays out on a real budget decision. A team that drops rank from 32 to 8 saves gradient memory, yet its GPU bill barely moves if the frozen base dominates memory. Switching the base to 4-bit would cut far more, at the cost of some quantization error to evaluate.
What Each Lever Saves
The table shows what each lever saves and what it leaves alone.
| Lever | What It Saves | What It Does Not Change |
|---|---|---|
| Lower LoRA rank | Gradient and optimizer memory, adapter file size | Frozen weight memory, activation memory |
| 4-bit base (QLoRA) | Memory held by the frozen weights | Number of trainable parameters |
| Merging the adapter | All adapter latency at inference | Served model size |
| Unmerged multi-adapter serving | Servers per task, since one base serves many | Small per-request adapter overhead remains |
| Soft prompts | Trainable parameters, to a very small count | Per-request compute, which rises slightly |
A sensible order for pulling these levers follows from the table. Fix memory first with a 4-bit base, then tune rank for quality. Decide merging last, once you know how many tasks will share the base. Reversing the order risks tuning rank on hardware you later abandon.
The Accuracy Trade
Accuracy also has its own trade. A 2024 study, “LoRA Learns Less and Forgets Less”, compared LoRA with full fine-tuning on programming and math tasks. LoRA trailed on those hard tasks at standard ranks, but it kept more of the base model’s original skills.
That one finding retires two overclaims at once. LoRA is not simply as good as full fine-tuning, and it is not simply better at generalizing. It trades some new learning for less forgetting, and your task decides which side matters.
What the PEFT Research Actually Tells Us
Read in order, the core PEFT papers tell one coherent story rather than a pile of acronyms. Each step solved the bottleneck that the previous one left, so the order matters.
Houlsby et al.’s 2019 adapters came within a fraction of a percent of full fine-tuning on GLUE. Prefix tuning and prompt tuning, both published around 2021, showed that training 0.1% to a few percent of parameters could hold up at scale.
Hu et al.’s 2021 LoRA paper then set the baseline. On GPT-3 175B, it reported 10,000 times fewer trainable parameters and three times less GPU memory than full fine-tuning with Adam. QLoRA followed in 2023 and quantized the frozen base itself, fitting a 65B fine-tune on one 48GB GPU.
What Followed LoRA
DoRA, AdaLoRA, rsLoRA, PiSSA, LoRA+, VeRA and LoftQ each target one weakness of that baseline. Xu et al.’s 2023 review groups them into families precisely because head-to-head comparisons rarely survive outside each paper’s setup.
The practical lesson is to trust your own benchmark over the newest acronym. Every reported gain rests on one model, one dataset and one hyperparameter search, so results rarely transfer unchanged.
What the Research Leaves Open
The research also leaves gaps that matter in enterprise work. Few papers measure how an adapter behaves after months of shifting user inputs. Fewer still test how many adapters one base can serve before quality or latency slips. Those answers come from your own evaluation sets and production monitoring, which is why the later sections of this guide focus on them.
One more pattern holds across the papers. Gains are largest when the base model already knows the domain reasonably well and the adapter only shapes behavior. When the task is far from the base model’s knowledge, every method in this family struggles more, and full fine-tuning regains ground.
How to Fine-Tune an LLM with the Hugging Face peft Library
Nearly every method in this guide ships as a ready configuration in Hugging Face’s open-source peft library. It works with Transformers and TRL, and the peft conceptual guide to LoRA explains the moving parts.
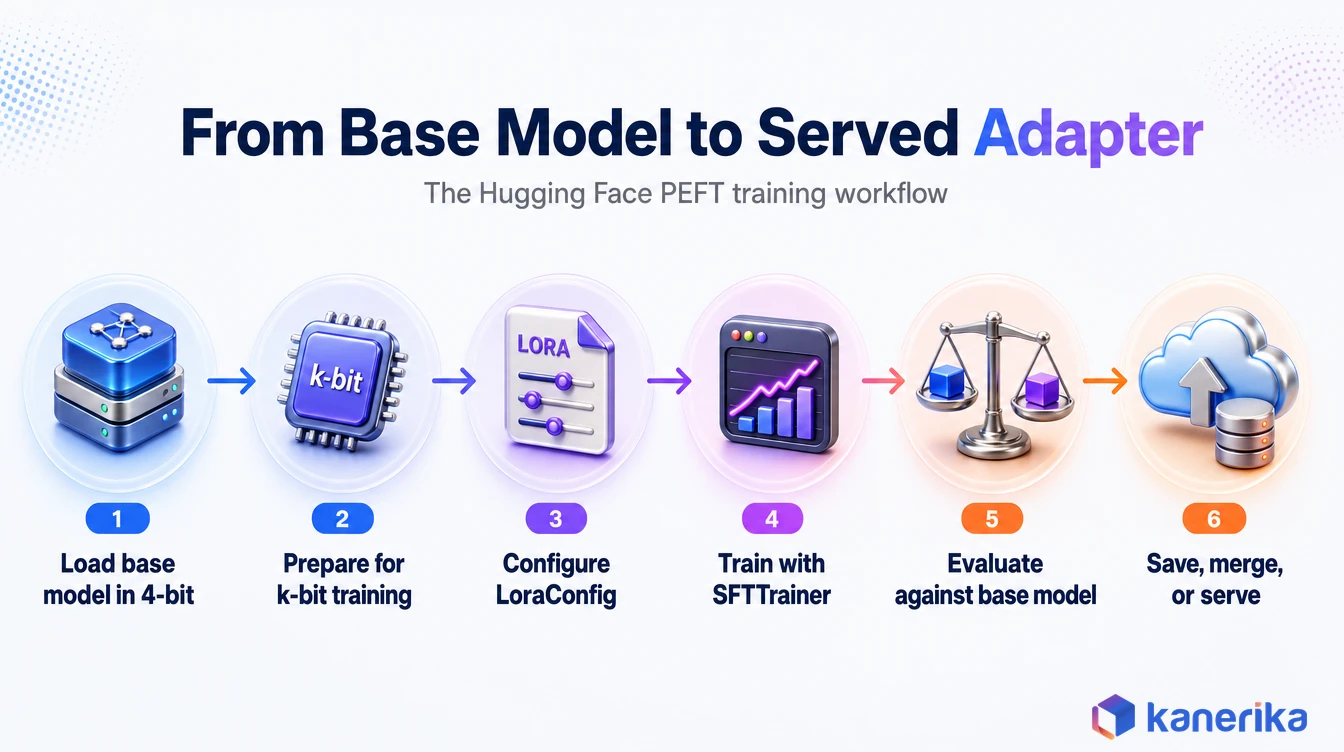
For most teams, this library is where parameter-efficient fine-tuning stops being theory and becomes a script. The six steps below take you from a base model to a saved adapter.
Pin the Versions First
Version pins matter more than usual here. As of November 2026 the release is peft 0.21.2, published October 1, 2026, and it requires Python 3.10 or newer. The Transformers PEFT integration supports the non-prompt-learning methods and needs peft 0.20 or newer. Loading an adapter onto a tensor-parallel base needs peft 0.21.1 or newer.
Six Steps from Base Model to Adapter
- Pick an open-weight base and clean the data. A dense base such as Qwen3.8-27B keeps targeting simple, while gpt-oss-20b is a good MoE starting point. Data quality and consistent formatting matter more than raw volume.
- Load the base in 4-bit for QLoRA. A
BitsAndBytesConfigset to NF4 with double quantization, plusprepare_model_for_kbit_training, loads the frozen base in reduced precision. - Configure LoraConfig. Set the rank
r,lora_alpha,target_modules(or"all-linear"),lora_dropout,biasandtask_type. Callprint_trainable_parameters()to see the exact trainable share. - Train with TRL’s SFTTrainer. Pass the LoRA config as
peft_configto SFTTrainer, and only the adapter’s weights update. - Evaluate against the untuned base. Compare outputs on the target task and on tasks the model should not lose.
- Save the adapter, then decide whether to merge. The adapter saves as a small file.
merge_and_unload()folds it into the base for single-task serving, or you keep it separate for multi-adapter serving.
Format the Training Data
Data formatting deserves more attention than it usually gets. Store each example as one JSON line holding a list of chat messages, with system, user and assistant turns. The trainer then applies the base model’s own chat template, so training and serving see the same token layout.
Keep a few hundred examples aside before you train anything. They become the task evaluation set in step 5, and they must never leak back into training.
A Minimal QLoRA Training Script
The script below runs steps 2 to 4 for a QLoRA job. Before running it, replace the model id and data path with your own.
# Python 3.10+ ; pip install "peft==0.21.2" transformers trl bitsandbytes datasets
import torch
from datasets import load_dataset
from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
from peft import LoraConfig, prepare_model_for_kbit_training
from trl import SFTConfig, SFTTrainer

BASE_MODEL = "path/to/qwen3.8-27b"   # a dense open-weight base you are licensed to use

bnb = BitsAndBytesConfig(
    load_in_4bit=True,
    bnb_4bit_quant_type="nf4",
    bnb_4bit_use_double_quant=True,
    bnb_4bit_compute_dtype=torch.bfloat16,
)
model = AutoModelForCausalLM.from_pretrained(
    BASE_MODEL, quantization_config=bnb, device_map="auto"
)
model = prepare_model_for_kbit_training(model)
tokenizer = AutoTokenizer.from_pretrained(BASE_MODEL)

lora = LoraConfig(
    r=16,                      # start at 8 or 16, then sweep
    lora_alpha=32,
    target_modules="all-linear",
    lora_dropout=0.05,
    bias="none",
    task_type="CAUSAL_LM",
)

data = load_dataset("json", data_files="train.jsonl", split="train")
trainer = SFTTrainer(
    model=model,
    args=SFTConfig(output_dir="adapter-v1", num_train_epochs=2),
    train_dataset=data,
    peft_config=lora,
    processing_class=tokenizer,
)
trainer.train()
trainer.save_model("adapter-v1")   # saves only the adapter weights
LoRA Settings That Matter Most
The settings below are where most of the tuning effort goes, so tune them first. The starting points are common practice, not library defaults.
| Parameter | Controls | Common Starting Point | Change It When |
|---|---|---|---|
| r (rank) | Capacity of the low-rank update | 8 or 16 | The task is far from the base model’s skills and low ranks underfit |
| lora_alpha | Scale of the BA update | Equal to or double the rank | Training is unstable, or the adapter’s effect is too weak or too strong |
| target_modules | Which matrices get an adapter | Attention projections, or “all-linear” | Attention-only targeting underperforms |
| lora_dropout | Regularization on the adapter path | 0.05 to 0.1 on small datasets | The adapter overfits |
| use_rslora | Scaling by lora_alpha/sqrt(r) | Off for low ranks | You test high ranks |
| task_type | Model head and loss shape | CAUSAL_LM for most LLM work | You train a classification or seq2seq head |
Pin peft, transformers and trl together in your environment file. That matters because adapter checkpoints depend on the exact architecture mapping the training run used.
Loading, Merging and Serving Multiple Adapters in Production
A trained adapter still needs a serving decision before it reaches users. The choice is between one merged model and one base with many swappable adapters.
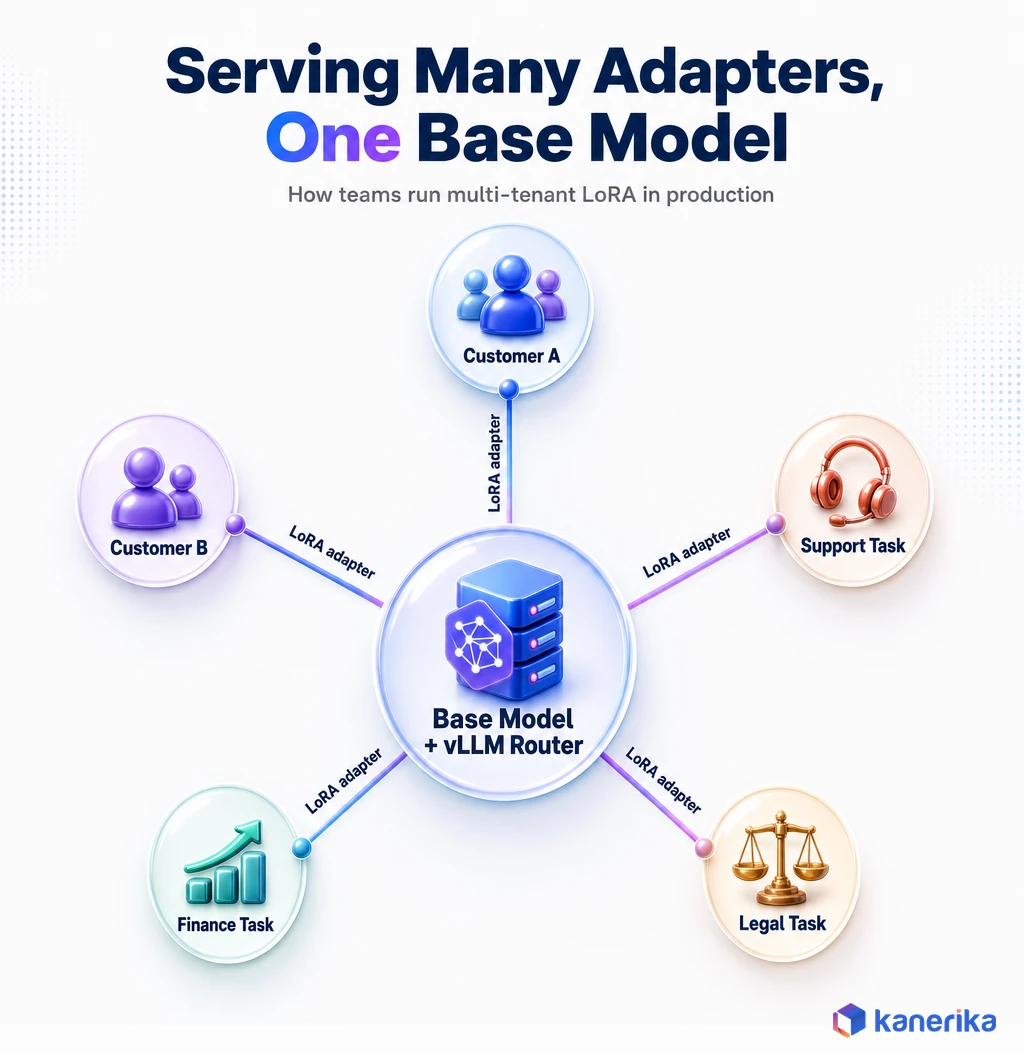
Hugging Face’s peft developer guide to LoRA documents two operations that are easy to confuse. The first, merge_and_unload(), returns a standalone model with the adapter folded in, so there is no adapter latency. The second pair, merge_adapter() and unmerge_adapter(), toggles the merge on the same object for side-by-side tests.
Merging and Blending Adapters
Adapters can also be blended. The add_weighted_adapter method can combine an SFT adapter and a DPO adapter with weights such as 0.7 and 0.3 under combination_type="linear". The result is then one adapter that carries both training signals.
One Base Model, Many Customers
Unmerged adapters are what make “one base model, many customers” practical. A server such as vLLM holds one base model and applies a different adapter per request, as its LoRA serving documentation describes.
The economics are easy to see with ten tenants. Ten fully fine-tuned models mean ten full copies to host, each sized for its own peak traffic. Ten adapters on one base mean one model in GPU memory plus ten small files, with traffic pooled across tenants.
The catch, however, is noisy neighbors. One tenant’s traffic spike now slows everyone on that base, so capacity planning and per-tenant rate limits become part of the design.
Moving Adapters into Production
Follow this sequence when you move adapters into production:
- Decide merge or serve. Merge with
merge_and_unload()when one task owns the deployment, and keep adapters unmerged when many tasks share a base. - Pick a serving engine. Compare SGLang and vLLM or vLLM and Ollama on multi-adapter support before committing.
- Route through a gateway. An LLM gateway maps each tenant or task to its adapter and logs every call.
- Version every adapter. Record the base model id, data version and LoRA config next to the adapter file.
- Keep a rollback path. Promote adapters behind an evaluation gate, and keep the previous version loadable.
Multi-adapter serving changes behavior, not size. Every request still runs the full base model, so plan GPU capacity around the base, not the adapters.
How to Evaluate a PEFT Adapter Before Production
An adapter is cheap to train, which tempts teams to ship it on a good demo. Evaluation is where parameter-efficient fine-tuning earns trust, because a small adapter can still break skills the base model had.
Consider a support adapter that answers billing questions well after training. If nobody checks, it may also have lost the base model’s ability to summarize long emails. A regression set built from those older skills catches that before customers do.
Five Checks Before Promotion
The NIST AI Risk Management Framework is a voluntary framework for trustworthy AI, with a Playbook of suggested actions. Its measure-and-manage approach also maps well onto adapter sign-off. Run these five checks before promotion:
- Task evaluation set. Hold out examples that never touch training, and score the adapter against the untuned base on them.
- Regression set from base skills. Keep 100 to 200 examples of tasks the base model already does well, and fail the adapter if those scores drop.
- Rank sweep. Train at rank 8, 16 and 32 on the same data, and keep the smallest rank that meets the quality bar.
- Adapter registry record. Store the base model id, data version, LoRA config and evaluation results with every adapter.
- Sign-off. A named owner approves promotion, and the previous adapter stays loadable for rollback.
Reading the Results
Reading the results takes judgment, not just a pass mark. Suppose the adapter gains 12 points on the task set but drops 4 points on summarization. A rank sweep or a smaller learning rate often recovers the regression without losing much of the gain.
If the regression persists at every setting, the task may belong in a separate adapter. Routing summarization requests to the untouched base is a valid design, and unmerged serving makes it cheap.
Kanerika’s LLM evaluation framework covers scoring methods in depth. For the registry itself, the comparison of MLflow, Hugging Face Hub and Azure ML shows where adapter records can live. After launch, LLMOps observability tooling watches for drift.
Choosing a Method: PEFT vs Full Fine-Tuning vs RAG vs Prompting
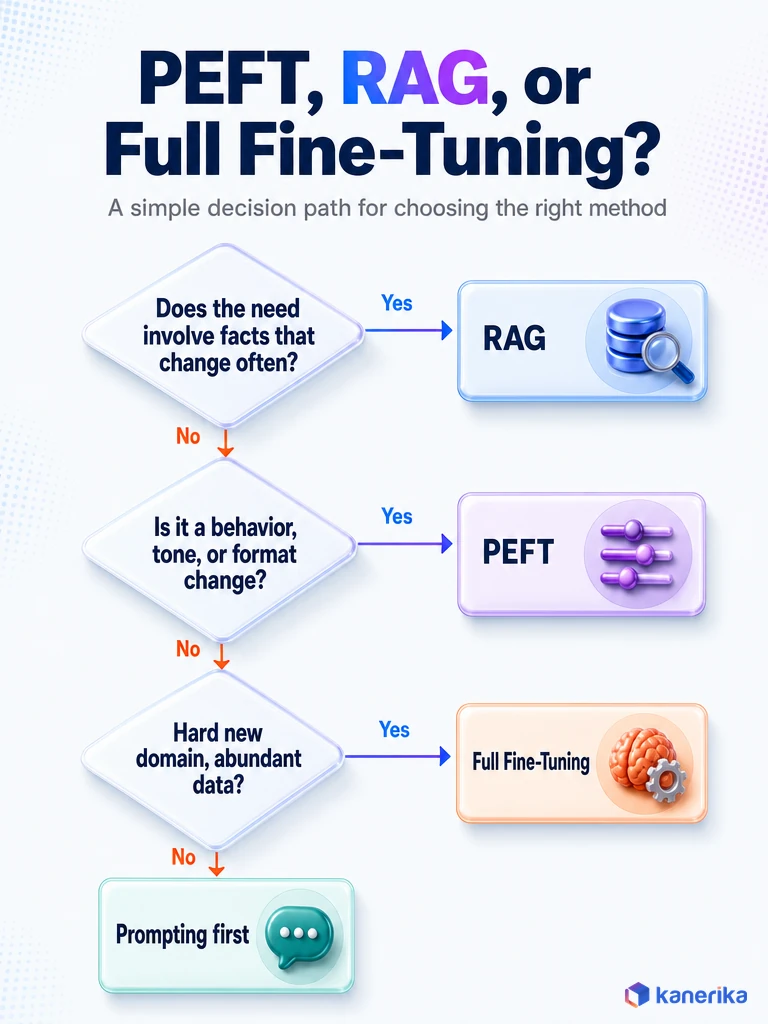
The right method depends on what you need the model to change. PEFT changes behavior, while retrieval changes what the model knows at answer time.
Four questions usually settle most cases, so start there. Does the model need a new behavior, tone or format, or does it need facts it never saw? Is the task close to what the base already does? How many behaviors must one deployment support? And how often does the underlying knowledge change?
Where RAG and Long Context Fit
Retrieval-augmented generation pulls current or private content in at query time without touching weights. A team that needs a consistent style and current citations usually needs both techniques together. Kanerika’s RAG vs fine-tuning decision guide covers that choice in full, and its round-up of RAG tools lists the retrieval stack.
Long context windows also do not change this logic. Claude Opus 5.5 has a 1M-token window and GPT-6.1 Sol has 1,050,000 tokens, so a prompt can carry many facts. They still do not change how the model behaves, which is the job an adapter does.
| Main Need | Prompting | RAG | PEFT | Full Fine-Tuning |
|---|---|---|---|---|
| Improve instructions or output format | Best first option | Not the right tool | Useful if prompting stays inconsistent | Usually unnecessary |
| Add fresh or private facts | Limited by the context window; 1M-token windows carry facts but not behavior | Best fit | Not the right tool alone | Not the right tool alone |
| Change behavior, style or a narrow skill | Partial, inconsistent at scale | Not the right tool | Strong fit, the usual starting point | Consider if PEFT capacity falls short |
| Learn a hard new domain with abundant data | Weak fit | Not the right tool alone | Can underperform at standard ranks | Best fit when data and budget allow |
| Support many variants from one deployment | Prompt templates | Per-tenant indexes | Strong fit, many adapters on one base | Expensive, one model copy per variant |
Read the table by row, not by column. Most real projects land on two cells, such as RAG for facts and an adapter for format.
A Worked Example: A Claims Assistant
For example, take an insurer building a claims assistant. Policy wording changes every quarter, so it goes into a retrieval index that updates without retraining. The insurer’s required response structure and tone stay fixed for years, so a LoRA adapter teaches them once.
Start with prompting either way. If a well-written prompt plus retrieval gets the output right most of the time, an adapter may not be worth the operational cost.
Teams already leaning toward retrieval can go further with advanced RAG patterns. Kanerika also publishes a white paper on choosing a generative AI approach, which walks tech leaders through prompting, RAG, PEFT and full fine-tuning for enterprise programs.
Common PEFT Mistakes and How to Avoid Them
Most PEFT failures come from treating an adapter as too small to deserve real rigor. The list below covers the mistakes that show up most often in practice.
- Starting with a low rank and never testing higher. A rank of 4 or 8 chosen without comparison can quietly underfit; a short sweep is cheap.
- Trusting auto-detected target modules. Defaults are a starting point, and tasks that lean on feed-forward layers often need them targeted explicitly.
- Changing rank without revisiting alpha. Alpha scales the adapter’s effect, so a rank change alone can shrink or amplify it in ways that look like a bug.
- Overfitting a small dataset. A small parameter count lowers but does not remove the risk, so use dropout, a validation set and early stopping.
- Skipping the untuned-base comparison. Without it, you cannot tell how much of a result came from the adapter.
- Expecting PEFT to fix bad data. An adapter learns whatever the examples teach, so duplicated, mislabeled or inconsistent data produces a confidently wrong model.
- Mismatching the tokenizer or chat template. An adapter trained with one chat template and served with another will produce broken or rambling output.
- Assuming PEFT shrinks the deployed model. The adapter is small, but every request still runs the full base model.
- Leaking evaluation data into training. Only a held-out set that never touched training can confirm a gain.
The Root Cause Behind Most Mistakes
Most of these mistakes share a root cause. Because PEFT runs are cheap, teams skip checks they would never skip on a full training run. The fix is a standing evaluation harness that every adapter passes through, so rigor costs nothing extra per run.
The same discipline that limits LLM hallucination protects a base model’s other skills from a careless adapter. Access controls from Kanerika’s LLM security guide apply to the training pipeline as much as to serving.
Where PEFT Pays Off in Enterprise Work
PEFT pays off where a narrow, stable behavior must be repeated at scale. The scenarios below are illustrative, meant to show where its trade-offs fit real constraints rather than to record a specific deployment.
The common thread is a behavior that changes slowly while the facts around it change fast. An adapter handles the first, and retrieval handles the second.
- Document extraction in finance or legal. A LoRA adapter trained on a few thousand labeled documents can teach a house output format the base model lacks.
- Clinical text under strict data rules. Training a small adapter on infrastructure the team controls keeps protected data inside its governance boundary.
- Multi-tenant SaaS. One base model with a LoRA adapter per customer avoids running a full model for each tenant.
- Private deployments. Teams running private LLMs gain twice: cheaper training and many task adapters without many full models.
- Speech and vision models. The same low-rank update adapts large speech and vision-language models to a narrower domain without retraining the full network.
Each scenario shares one test you can run before committing budget. Write down the behavior you want, then check whether a prompt plus retrieval already delivers it. If it does not, and the behavior will stay stable for months, an adapter is a good bet.
The opposite case also matters. If the target changes weekly, an adapter becomes a retraining treadmill, and retrieval or prompting will cost less to keep current.
How Kanerika Builds Custom LLM Solutions
Kanerika builds custom LLM systems by deciding first what belongs in retrieval and what belongs in parameter-efficient fine-tuning. That ordering keeps teams from training an adapter to memorize facts that will change next quarter.
The work spans LLM development services, AI model engineering, RAG development and MLOps consulting. Kanerika’s six-stage approach runs like this:
- Decide retrieval or adaptation per need. Facts that change go to retrieval, while stable tone, format or task skill goes to an adapter.
- Audit and format the data. Remove duplicates, fix labels and apply one chat template across the set.
- Build a LoRA or QLoRA baseline. Train on an open-weight model with a pinned rank sweep, starting at rank 8 or 16.
- Evaluate against two sets. Score a task set plus a base-skill regression set of 100 to 200 examples.
- Register, serve and monitor. Store the base model id, data version and LoRA config with every adapter, then watch it in production.
- Run a governance review. AI governance services cover approval, access and rollback before promotion.
Case Study: Brand Compliance at a Payment Technology Provider
Stage 1 is where most projects get decided, and a brand compliance project for a leading payment technology provider shows why. Kanerika built a conversational assistant over centralized brand guidelines, which raised the brand compliance rate by 35% and cut approval turnaround time by 60%. Manual effort per brand query also fell by 70%.
That project was retrieval, not PEFT, and that is the point. Brand policies change, so they sat in retrieval where an update needs no retraining. An adapter would only have standardized tone, which is the narrow job PEFT does well.
Case Study
60% Faster Brand Approvals with Conversational AI
A leading payment technology provider raised its brand compliance rate by 35%, cut approval turnaround time by 60% and reduced manual effort per brand query by 70%.
Read the Case Study →Practitioner Rules and Credentials
A few practitioner rules also carry across every engagement. Start at rank 8 or 16, not at the largest rank the GPU allows. Keep a 100 to 200 example regression set from tasks the base model already does well. Store the base model id, data version and LoRA config with every adapter, so any result can be reproduced.
Kanerika holds ISO 27001 and ISO 27701 certifications, SOC 2 Type II and GDPR compliance, and was certified in the Claude Partner Network in October 2026. FLIP, Kanerika’s workflow automation platform, then connects these model services to the business processes around them.
Start with LoRA, Then Earn the Complexity
For most teams, parameter-efficient fine-tuning should start with plain LoRA at rank 8 or 16 on an open-weight base. Move to QLoRA when memory blocks you, and test DoRA, rsLoRA or PiSSA only when your benchmark shows a gap.
Judge every experiment on quality, memory, cost, latency and forgetting together, not on parameter count. Choose full fine-tuning when a hard domain needs more capacity, choose RAG when facts change, and choose PEFT when behavior is the thing to fix.
Frequently Asked Questions
What is parameter-efficient fine-tuning in simple terms?
Parameter-efficient fine-tuning adapts a pretrained model to a new task by training only a small set of new or selected weights. The rest of the model stays frozen. Methods like LoRA add a small trainable component beside existing layers. This cuts training memory, storage and experiment time sharply compared with updating every weight in the model.
What is the difference between PEFT and LoRA?
PEFT is the general category, and LoRA is one method inside it. LoRA belongs to the reparameterization family and learns a low-rank update beside frozen weights. Other PEFT methods include adapters, prompt tuning, prefix tuning, BitFit and IA3. LoRA is the most widely used because it merges cleanly into the base model before deployment.
Can a LoRA adapter be merged back into the base model?
Yes. The peft library’s merge_and_unload() method folds the adapter into the base weights and returns a standalone model with no adapter latency. Merging suits a deployment that serves one task. Keep adapters unmerged when one base model must serve many tasks or tenants. Check the peft LoRA guide for merge caveats on specific variants.
Is QLoRA a PEFT method or a quantization method?
QLoRA is both a quantization technique and a PEFT method. It holds the frozen base model in 4-bit NF4 precision, which is the quantization part. It then trains LoRA adapters in higher precision on top, which is the PEFT part. The combination is what let researchers fine-tune a 65B model on one 48GB GPU.
Which open-weight models can be fine-tuned with PEFT in 2026?
As of November 2026, common bases include Qwen3.8-27B, Mistral Small 4, gpt-oss-20b and gpt-oss-120b under Apache 2.0. DeepSeek V4.1-Flash-1017 and Phi-4-mini-instruct use MIT licenses. Mistral Large 4 ships under a custom license, so read it before commercial use. Hosted frontier models such as Claude Opus 5.5 do not expose weights for PEFT.
Is PEFT as accurate as full fine-tuning?
Not always. A 2024 study found LoRA trailed full fine-tuning on hard programming and math tasks at standard ranks. The same study found LoRA forgot less of the base model’s existing skills. Whether PEFT reaches full fine-tuning quality depends on the task, the rank and how far the target behavior sits from the base model.
Does LoRA add inference latency?
No, once the adapter is merged into the base weights. The merged model has the same architecture as the original, so it runs at the same speed, as the LoRA paper states. Latency appears only when adapters stay unmerged so one server can switch between tasks per request. That overhead is usually small but worth measuring.
What is IA3 fine-tuning?
IA3 stands for Infused Adapter by Inhibiting and Amplifying Inner Activations. It learns small vectors that rescale the key, value and feed-forward activations inside each targeted layer. LoRA adds low-rank matrices instead. IA3 usually trains fewer parameters than LoRA and needs no more memory. It suits few-shot tasks where the smallest possible adapter matters.
Is instruction tuning the same as PEFT?
No. Instruction tuning, usually done through supervised fine-tuning, describes what data and objective you train on. PEFT describes which parameters change during that training. The two work together in practice. Hugging Face’s TRL SFTTrainer accepts a PEFT configuration directly, so teams often run instruction tuning through a LoRA adapter rather than updating every weight.
Can PEFT be combined with RLHF or DPO?
Yes. LoRA adapters can be trained through reinforcement learning from human feedback or direct preference optimization, the same way they are trained with supervised fine-tuning. Many teams run SFT first and a preference pass second. The peft library’s add_weighted_adapter method can then blend an SFT adapter and a DPO adapter into one combined adapter.
How much GPU memory does QLoRA need?
The QLoRA paper fine-tuned a 65-billion-parameter model on a single 48GB GPU by holding the frozen base in 4-bit NF4 precision. It matched full 16-bit fine-tuning on the paper’s tasks. Real memory needs scale with model size, sequence length and batch size. Smaller models fit on smaller cards, so measure your own setup before buying hardware.
What LoRA rank should I start with?
Start with rank 8 or 16 for most tasks, then run a short sweep that adds 32. Keep the smallest rank that meets your quality bar on a held-out set. Raise the rank when the task sits far from the base model’s skills and low ranks underfit. Revisit lora_alpha whenever you change the rank.
Should I use PEFT or RAG?
Use PEFT when the model must change its behavior, tone or output format. Use RAG when it needs current or private facts at answer time. Many production systems use both, with retrieval for changing facts and an adapter for stable behavior. Start with prompting plus retrieval, and add an adapter only if outputs stay inconsistent.