TL;DR
Data lineage traces every number from its source, through each transformation, to the reports that use it. It records datasets, columns, jobs and reports as a graph, so a team can trace a bad figure backward and test a change forward. Column-level lineage is the depth that matters, because a table-level graph cannot show which field broke a metric. Tools capture lineage in five ways, through connectors, SQL parsing, runtime events, declared metadata and manual entry, and each method misses something. For tools, single-platform estates start with native lineage, regulated multi-cloud estates buy an enterprise platform, and engineering-led teams use OpenLineage. Start with your critical reports, measure how much of their path you can see, and run lineage as a living control instead of a one-time diagram.
Key Takeaways
- Data lineage records where data starts, every transformation it passes through and every table, model and report that uses it.
- Column-level lineage shows which field fed a metric, which is the question most incidents and audits actually ask.
- Platform-native lineage in Microsoft Purview, Fabric, Databricks Unity Catalog and Snowflake is strong inside its own platform and thin outside it.
- No single capture method sees everything, so stored procedures, custom SQL and BI models are where graphs usually go dark.
- Choose a tool on source coverage, capture method, column depth, BI reach, governance fit and total running cost, not on connector counts.
- Measure lineage by the share of critical report paths you can trace end to end, then keep it current through change management.
The Two-Point Margin Drop Nobody Could Explain
At 8:40 on a Monday, the CFO posts a short question to the leadership channel. Why did gross margin on the executive dashboard fall two points overnight, when sales barely moved?
At first, finance suspects the warehouse. The data team then checks the nightly loads and finds nothing broken. Then the BI team traces a Friday change to the semantic model, which turns out to be harmless. By Thursday, three teams have spent most of a week on one number.
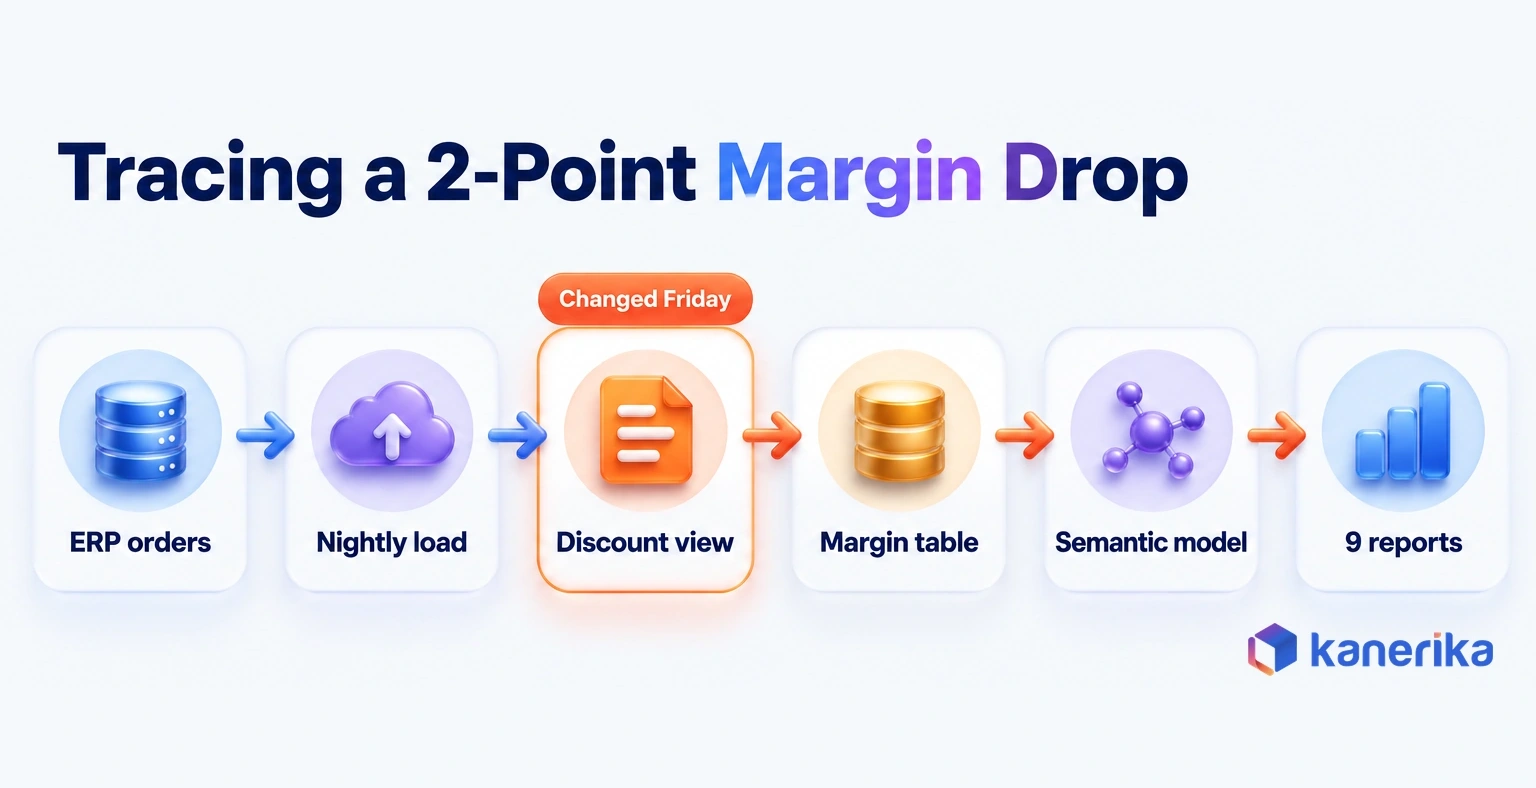
Eventually, the cause turns up in a single SQL view. A developer changed how discounts are netted out of revenue, and the edit flowed quietly into the margin table, the semantic model and nine reports. With data lineage in place, the same trace takes minutes, because you click the margin field, walk upstream and find the edited view.
The scene is a composite, yet any data team will recognize it. This guide explains what lineage records and which types matter. It then covers how tools capture it, how the main data lineage tools compare in 2026, and how to implement it in six stages.
Lineage feels optional until someone senior asks where a number came from and nobody can answer quickly.
What Is Data Lineage?
Data lineage is the record of where data originates, every transformation it passes through, and every table, model and report that consumes it. In other words, it is a map of the routes your data travels, with every junction labeled.
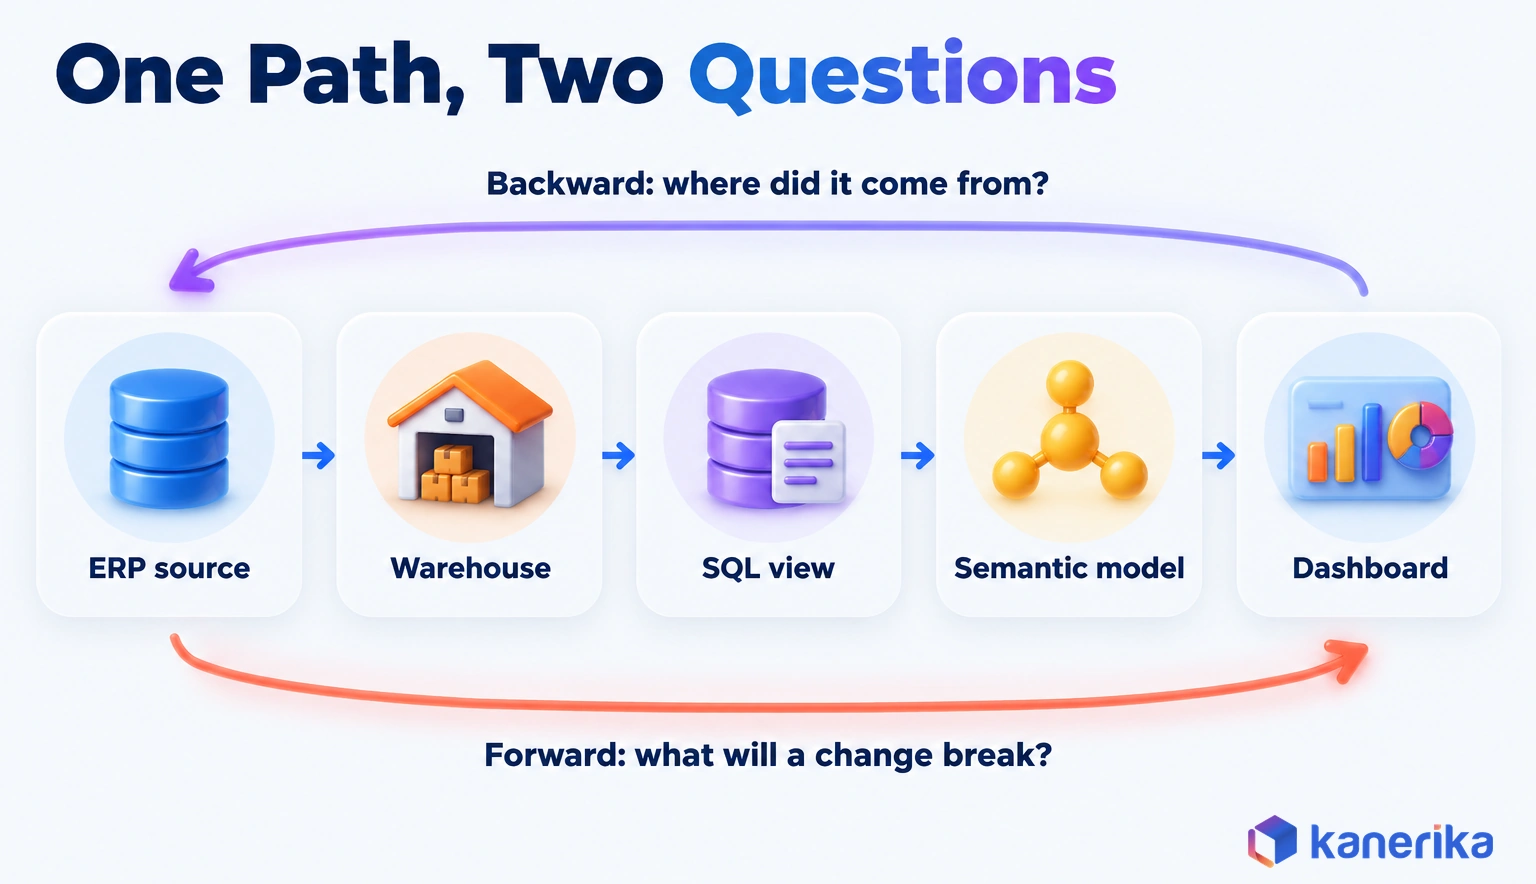
Take a revenue figure on a sales dashboard. It starts as order lines in an ERP system and gets extracted each night. Then it lands in a warehouse table, passes through a SQL view that removes returns, and rolls up into a monthly aggregate. A semantic model then turns that aggregate into a measure, and the dashboard tile displays it.
So lineage captures every one of those hops. Read it backward and you learn where the number came from. Read it forward and you learn which reports, models and downstream jobs will change if you edit any step. That is why impact analysis depends on it.
Kanerika Service
Data Governance Services From Kanerika
Kanerika builds governance programs with lineage, classification and ownership designed in, so every critical report can be traced back to its sources.
Explore Data Governance Services
What a Lineage Graph Records
Most tools store lineage as a graph, because a graph fits paths naturally. The nodes are the things data lives in or passes through, while the edges are the movements and transformations between them.
- Nodes: source tables, files, columns, jobs, notebooks, views, semantic models and reports.
- Edges: the read and write relationships between nodes, ideally down to which column produced which.
- Run metadata: when a job ran, whether it succeeded, and which inputs and outputs it touched on that run.
- Ownership and context: who owns each asset, its classification and the business term it maps to.
The OpenLineage project formalizes this as three objects. It tracks metadata about datasets, jobs and runs, so every lineage event says which job ran, on which run, reading and writing which datasets. That split between static structure and runtime evidence comes up again when you compare capture methods.
Data Lineage vs Data Provenance vs Data Mapping vs Data Observability
These four terms get used interchangeably, but each one answers a different question. Lineage is about the path, while provenance is about origin and custody. Mapping covers how fields correspond, and observability checks whether the data is healthy right now.
| Term | Question it answers | Main users | Example |
|---|
| Data lineage | Where did this data come from, and what does it feed? | Data engineers, BI teams, governance leads | Margin field traced from ERP order lines to nine reports |
| Data provenance | Who created this record, when, and has it been altered? | Auditors, scientists, compliance teams | A lab result tied to the instrument and operator that produced it |
| Data mapping | Which source field corresponds to which target field? | Integration and migration teams | CUST_NM in the legacy system maps to customer_name in the warehouse |
| Data observability | Is the data fresh, complete and behaving as expected? | Data reliability and platform teams | An alert fires when a nightly load arrives with 40% fewer rows |
Still, the terms overlap in practice. For instance, mapping documents are often the first lineage a migration team writes, and observability tools use lineage to show which reports an incident will hit. If you are weighing the monitoring side, Kanerika’s comparison of data observability vs data quality covers where those two disciplines split.
Datasheet
Elevate Data Governance, Compliance and Security of Your Organization
See how Kanerika sets up governance controls, automation and monitoring so lineage, classification and compliance evidence stay current across your estate.
View the Datasheet →
Data Lineage vs a Data Catalog and Data Governance
Two more neighbors cause confusion: the data catalog and the governance program around it. A catalog is the inventory, lineage maps the routes between the items in it, and governance sets the rules both must follow. Microsoft’s Unified Catalog overview describes an inventory of data assets, their metadata and their lineage, with glossary terms and quality rules on top.
Put simply, a catalog answers what data exists and who owns it. Lineage, by contrast, answers how that data moves and what depends on it. Kanerika’s guide to an enterprise data catalog covers the inventory side. Governance then decides who keeps both current, and our explainer on data governance vs data management shows where those roles divide.
Why Data Lineage Matters in 2026
Lineage pays off in five recurring situations, and each one gets more expensive when a data estate grows. Here is where teams feel it first.
Faster root cause. When a figure looks wrong, a backward trace narrows the search from the whole platform to a handful of upstream steps. For example, the margin incident above shrinks from a week to an afternoon once the path is visible.
Without a traced path, every incident turns into archaeology, because nobody knows where to start. Engineers read old SQL, analysts rebuild the figure in a spreadsheet, and someone adds a footnote to the dashboard saying the data is under review. That footnote costs more than the hours spent, since people stop trusting the report and start keeping their own versions. It is also a familiar symptom of bad data quality.
Safer change. Before anyone renames a column or rewrites a view, a forward trace lists every model and report that depends on it. Owners can then be warned before a release instead of after a complaint.
Proof at migration cut-over. Moving from an old warehouse to a lakehouse means proving that every report still draws on the right sources. Lineage on both sides shows which paths have moved and which still point at legacy tables. It also gives data migration testing a clear list of paths to verify.
Where the Stakes Rise: Regulation and AI
Regulatory evidence. The Basel Committee published BCBS 239, its Principles for effective risk data aggregation and risk reporting, in January 2013. Global systemically important banks, however, were only expected to comply from January 2016. Because supervisors expect a bank to show how risk figures are aggregated from source data, BCBS 239 is a lineage question. Privacy rules such as GDPR and CCPA raise a similar need. A team must know every place personal data flows before it can protect or delete it.
Trust in AI data. Training sets, feature tables and model versions all have upstream sources. If a source changes or is withdrawn, lineage tells you which models were trained on it and need review.
Analysts have started to put numbers on that risk. In a February 2025 release, Gartner predicted that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. The same release reported that 63% of organizations either lack the right data management practices for AI or are unsure whether they have them.
Lineage is one of those practices. A model’s output is only as explainable as the path behind its training data and features. So a team that cannot trace that path cannot defend the model.
Migrations test all five of these benefits at once. For that reason, the podcast episode below asks how Fortune 500 companies actually govern their data migrations.
Types of Data Lineage
Lineage comes in several flavors, and the type you need depends on who is asking the question. For example, a finance director and a data engineer can look at the same graph and need very different levels of detail.
The eight types below form three pairs plus two views. Each pair is one choice about what the graph shows or how it was built. The last two rows, by contrast, are views: which direction you trace, and whether the graph reaches models.
| Type | What it shows | Who relies on it |
|---|
| Business lineage | Flow between systems and business terms, with technical detail hidden | Data owners, finance, compliance |
| Technical lineage | Jobs, queries, tables and transformation logic | Data engineers, platform teams |
| Table-level lineage | Which tables and views feed which others | Platform teams planning changes |
| Column-level lineage | Which source column produced each target column | Engineers, auditors, BI developers |
| Design-time lineage | Paths inferred by parsing code and metadata before anything runs | Architects, migration teams |
| Runtime lineage | Paths observed from jobs that actually ran, with timestamps | Operations and incident teams |
| Backward and forward lineage | Upstream sources of an asset, or downstream consumers of it | Root-cause and impact analysis |
| AI and ML lineage | Training data, features, experiments and model versions | ML engineers, model risk teams |
Which Types Matter Most, and Why
Column-level lineage comes first, because incidents and audits ask about fields. A table-level graph tells you the margin table reads from the orders view, but not that only the discount field changed. With dozens of columns per table, the table-level answer still leaves a team reading SQL by hand.
Design-time and runtime lineage also complement each other. Parsing code shows every path that could run, including rarely used branches. Runtime events, by contrast, show what did run, on which date, against which inputs. Audits and incident reviews usually need the second kind, because they ask what happened on a specific day.
Finally, AI and ML lineage is the newest branch. It links a model version to the exact training snapshot and feature definitions. Because of that link, a model risk team can reproduce or retire it with confidence.
Talk to Kanerika
Find Where Your Lineage Goes Dark
Bring one critical report. Kanerika’s team will walk its path from source to dashboard with you and show where your current lineage stops.
Book a Lineage Review →
How Lineage Gets Captured: Five Methods and What Each Misses
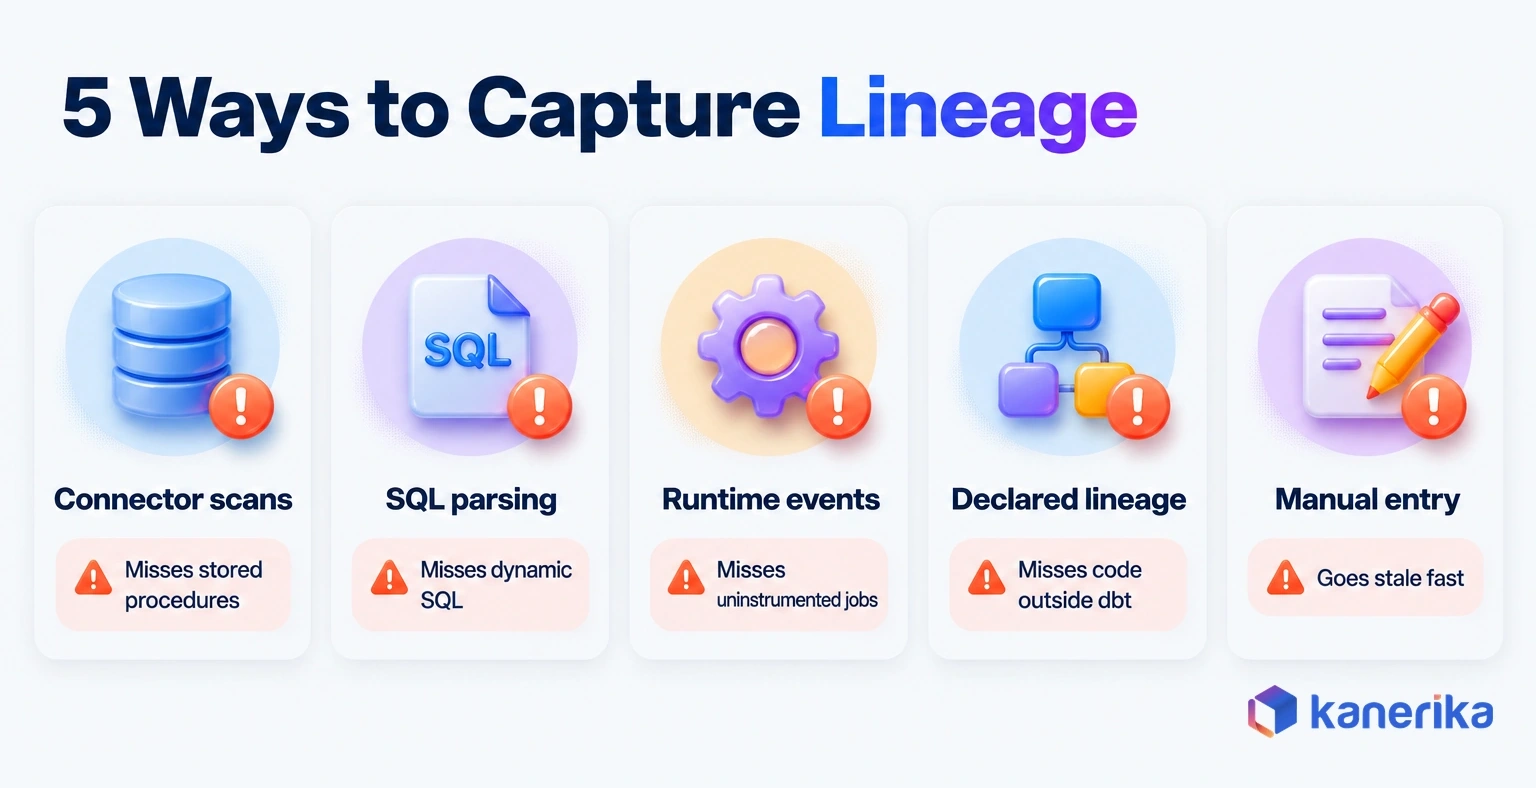
Every lineage graph is assembled from evidence, and the evidence comes from one of five places. So knowing which method a tool relies on tells you in advance where its graph will have holes.
| Method | How it works | What it sees | Blind spot | Effort |
|---|
| Connector or static scanning | Reads metadata from databases, ETL tools and BI platforms | Structure across many systems | Logic hidden in scripts and stored procedures | Low to medium |
| SQL and query-log parsing | Parses SQL text and query history to infer reads and writes | Column-level paths inside the warehouse | Dynamic SQL and code outside SQL | Medium |
| Runtime events | Jobs emit lineage events as they run, for example through OpenLineage | What actually ran, with timestamps | Jobs that are not instrumented | Medium to high |
| Declared lineage | Reads dependencies a framework already records, such as dbt manifests | Model-to-model dependencies | Anything outside the framework | Low |
| Manual entry | People draw or upload lineage for systems no tool can read | Legacy and third-party systems | Goes stale as soon as code changes | High to maintain |
Most real deployments combine three or four of these, because each method covers another’s blind spot. For example, a platform’s own engine captures its internal paths while a scanner reaches the BI layer. Manual entries then fill in a mainframe feed that nothing else can read.
Manual lineage still has a place, as long as it is scoped. Microsoft Purview’s lineage guide describes custom lineage pushed through Atlas hooks and the REST API, plus manual lineage with column-level mapping. That suits a handful of stable legacy feeds, but it is a poor fit for logic that changes every sprint.
Querying Lineage as Data
Runtime capture is also queryable once it lands. On Databricks, for example, Unity Catalog writes lineage into system tables. An engineer can then ask which upstream tables feed a reporting table with plain SQL.
-- Which upstream tables feed the gross margin table?
SELECT DISTINCT source_table_full_name
FROM system.access.table_lineage
WHERE target_table_full_name = 'finance.gold.gross_margin_daily';
A query like this turns lineage from a picture into something you can test, alert on and audit. The same habit applies on any platform that exposes lineage as data rather than only as a diagram.
Worked Example: Tracing a Gross-Margin Figure From ERP to Dashboard
A concrete trace shows what good lineage looks like in practice. Here is the path behind the margin figure from the opening scene, followed backward and then forward.
- ERP source. Order lines and discount records live in the ERP system, with list price, discount percentage and cost per line.
- Nightly load. An ingestion job copies both tables into the warehouse raw layer without changing values, following the load-first ELT pattern.
- Discount logic. A SQL view calculates net revenue per line by applying the discount field. This is the step that changed on Friday.
- Cost join. A second view joins net revenue to standard cost by product and date.
- Aggregate table. A scheduled job rolls lines up into daily gross margin by region and product family.
- Semantic model. The BI layer defines the gross margin percentage measure on top of the aggregate.
- Dashboard. The executive dashboard shows the measure, along with eight other reports built on the same model.
- Trace and fix. The backward trace from the dashboard field stops at the discount view. The forward trace from the discount field then lists all nine reports, so every owner hears about the correction at once.
Two details make this trace work. First, it runs at column level, so the graph points at the discount field rather than at a whole table. Second, it reaches the semantic model and the reports, which is where many graphs stop.
Next, try the same exercise on one of your own critical numbers. Wherever you cannot follow the path, you have found a gap in coverage, and that gap is worth more than any tool demo.
Data Lineage Tools in 2026
Lineage tools fall into three camps: built into a data platform, bought as an enterprise lineage or catalog platform, or run yourself from open source. Platform-native lineage comes with the platform and works well inside its walls. Once data leaves those walls, however, it cannot see much.
Where your data lives, and who runs it, decides which camp fits. An estate built mostly on one platform can get far with native lineage. By contrast, an estate spread across clouds, legacy databases and several BI tools needs something that stitches the pieces together. Finally, engineering teams that already instrument their pipelines can run the open-source camp themselves. Lineage is also only one part of a wider catalog. So if you are comparing whole governance suites, Kanerika’s review of data governance tools covers that broader choice.
| Tool | Category | Main capture method | Column-level | Best fit |
|---|
| Databricks Unity Catalog | Platform-native | Runtime capture of queries, notebooks, jobs and pipelines | Yes | Databricks-centered lakehouses |
| Microsoft Purview | Platform-native catalog | Connectors, Atlas hooks, REST API, manual entry | Yes for supported sources and manual mapping | Microsoft-heavy estates |
| Microsoft Fabric lineage view | Platform-native | Workspace item relationships | No, item level | Fabric workspace impact checks |
| Snowflake lineage | Platform-native | Captured inside Snowflake | Yes, Enterprise Edition or higher | Snowflake-centered warehouses |
| IBM watsonx.data intelligence (formerly Manta) | Enterprise lineage | Scanners and parsers across 50+ technologies | Yes, with history | Complex multi-vendor estates |
| Informatica, Collibra, Alation, Atlan | Enterprise catalog | Connectors and parsing, varies by source | Depends on connector | Governance-led programs |
| OpenLineage with Marquez | Open source | Runtime events from instrumented jobs | Depends on integration | Engineering-led teams |
| OpenMetadata, DataHub, Apache Atlas, Spline | Open source | Connectors, parsing or job agents | Depends on connector | Teams that can run their own platform |
Platform-Native Lineage: Microsoft Purview and Fabric, Databricks Unity Catalog, Snowflake
Native lineage is the cheapest place to start, because it is already part of the platform you pay for. Its limits are worth knowing before you rely on it for an audit. For a broader feature view, see Kanerika’s comparison of Unity Catalog vs Purview vs Collibra.
Databricks Unity Catalog captures table and column-level lineage across notebooks, jobs, pipelines and queries, and it also records user-defined functions. Its lineage system tables, system.access.table_lineage and system.access.column_lineage, keep a rolling one-year window, so longer audit trails need their own export. Kanerika’s guide to Databricks data lineage goes deeper on that platform.
Microsoft Purview collects lineage as data moves through Data Factory, Data Share and Power BI. For sources it cannot scan, Purview accepts custom lineage through Atlas hooks or its REST API, and people can add manual lineage with column mapping.
Watch on YouTube
Revolutionizing Data Governance for a Bank with Microsoft Purview
Kanerika shows how a bank used Microsoft Purview to classify sensitive data and automate lineage across its source systems, a working view of Purview lineage at enterprise scale.
Microsoft Fabric gives every workspace a lineage view. According to Microsoft’s Fabric documentation, it shows relationships between items in the workspace plus external sources one step upstream. Users with the Viewer role do not see data sources. So if business users hold that role, the people who most need the view see only part of it. Because the view works at item level, column detail comes from Purview or another tool.
Snowflake lineage requires Enterprise Edition or higher. It covers object and column lineage, each retained for one year, but it is not available for objects in shared databases or in INFORMATION_SCHEMA. Therefore, if key feeds arrive through shared databases, plan manual entries for those hops. Since Databricks and Snowflake both stop at one year, a team that may face questions about older numbers should schedule a lineage export early.
Enterprise Platforms: Catalog Suites and a Dedicated Lineage Tool
Enterprise platforms earn their cost when lineage has to cross many vendors. They pull metadata from databases, ETL tools, scripts and BI platforms into one graph that a governance team can manage.
Informatica, Collibra, Alation and Atlan sit mainly among data catalog tools and governance suites. For these, lineage is one module alongside glossaries, data quality and access workflows. Their column-level depth varies by connector, so the real test is your own estate. Run each one against your stored procedures and BI models rather than trusting a feature list.
IBM, on the other hand, took a more lineage-specific route. As of October 2026, the former Manta product page redirects to IBM watsonx.data intelligence Data Lineage. That product provides column-level historical lineage across more than 50 technology integrations. For systems it cannot read out of the box, IBM points teams to its OpenManta framework.
Open-Source Lineage: OpenLineage and Marquez, OpenMetadata, DataHub, Apache Atlas, Spline
Open-source options suit teams that would rather run software than buy it. They cost engineering time instead of license fees, and they reward teams that already instrument their data pipelines.
OpenLineage is an open standard and a Linux Foundation project. It defines a standard API for lineage events, so a job reports its datasets, job and run in one consistent format. Marquez is the reference implementation, a metadata server and UI that works with OpenLineage integrations for Airflow, Spark, Flink, dbt and Dagster.
Besides Marquez, OpenMetadata and DataHub are open-source metadata management tools with lineage graphs, search and ownership built in. Apache Atlas provides the metadata model behind several governance tools, which is why Purview accepts Atlas hooks. Spline, meanwhile, tracks lineage for Apache Spark jobs. Whichever you choose, budget for hosting, upgrades and connector maintenance, because nobody else will do them for you.
Whatever the tool, lineage only pays off inside a governance program with named owners and classification rules. A short checklist helps you confirm those basics before a tool goes in.
Checklist
Data Governance Checklist
Confirm owners, classification rules, policies and lineage coverage before you shortlist a lineage tool, so it has a program to plug into.
Get the Checklist →
How to Choose a Data Lineage Tool: Six Criteria
The best tool is the one that can see your critical paths end to end, not the one with the longest connector list. Six criteria separate a good fit from an expensive diagram.
| Criterion | Question to ask | Red flag |
|---|
| Source coverage | Can it read every system on your top ten report paths? | Coverage proven only on a vendor demo dataset |
| Capture method | Does it parse code, observe runs, or both? | Static scans only, with no run evidence |
| Column-level depth | Does it resolve columns through views and stored procedures? | Column lineage that stops at the first view |
| BI and semantic reach | Does the graph reach measures and report visuals? | Lineage that ends at the warehouse table |
| Governance integration | Does it link to your catalog, glossary and owners? | A separate graph nobody maintains |
| Total cost drivers | What do licenses, connectors, parsing and admin time add up to? | Extra fees for each connector you actually need |
First, run every shortlisted tool against the same three report paths from your own estate. Pick one simple path, one with stored procedures, and one that crosses a cloud boundary. The results usually settle the decision faster than any feature comparison.
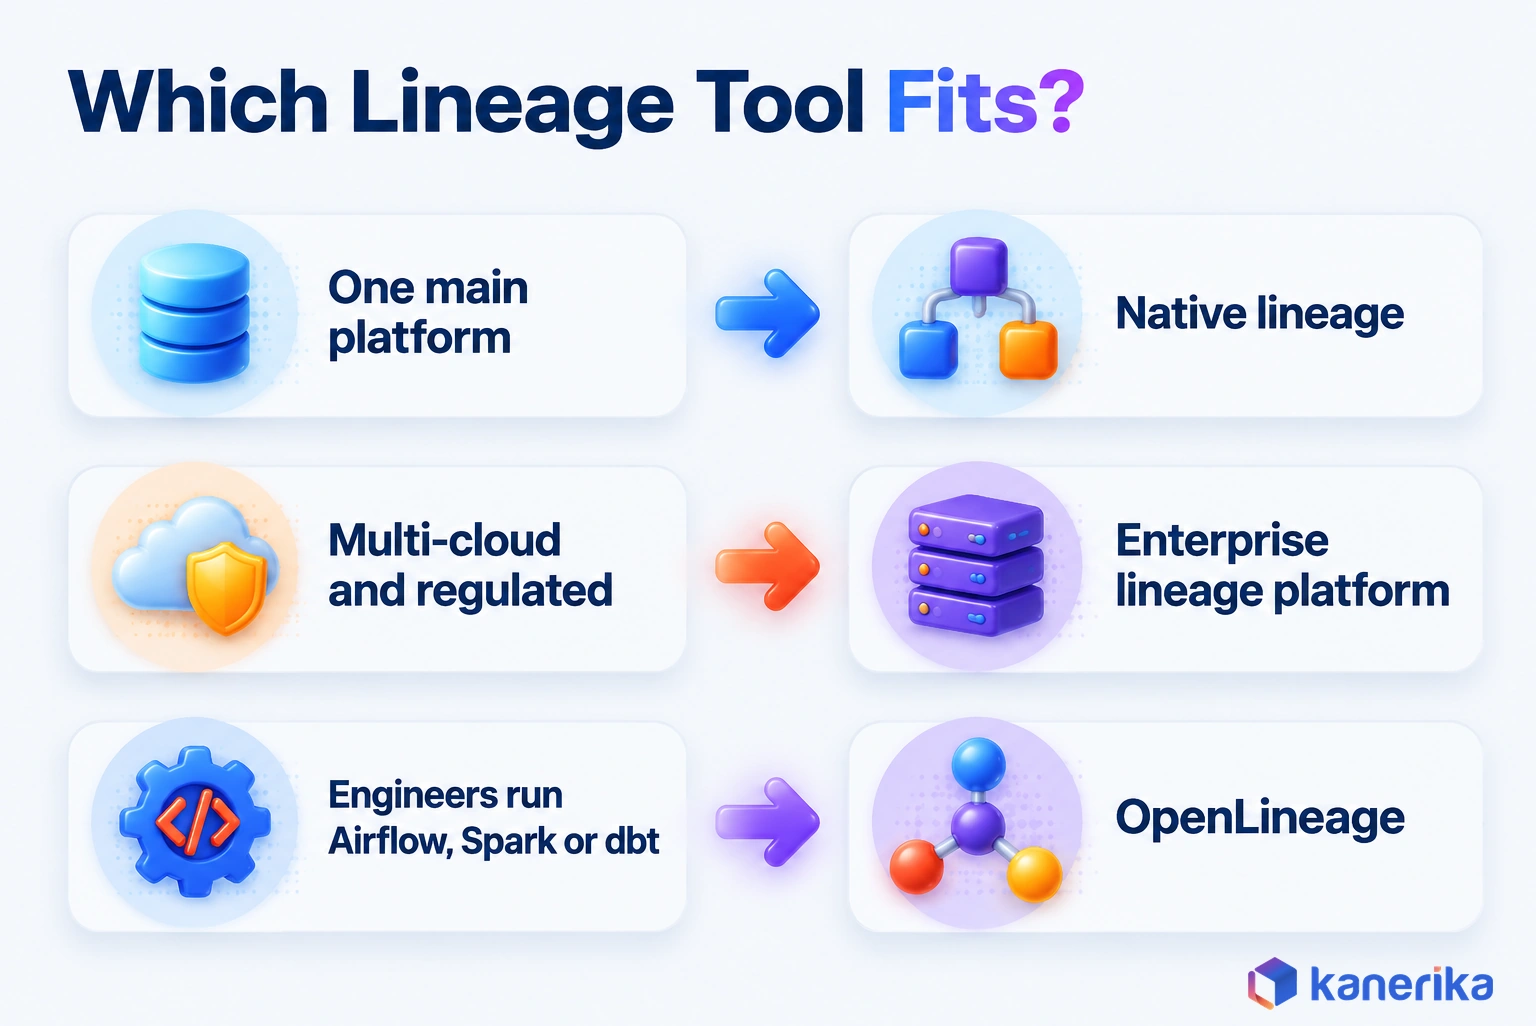
The decision path then has three branches. When most of your data and reports sit on one platform, start with native lineage and add manual entries for the few outside feeds. For estates that span several clouds under strict regulation, an enterprise lineage or catalog platform is worth its cost. Finally, if engineers own the pipelines and already run Airflow, Spark or dbt, OpenLineage gives runtime evidence without a license.
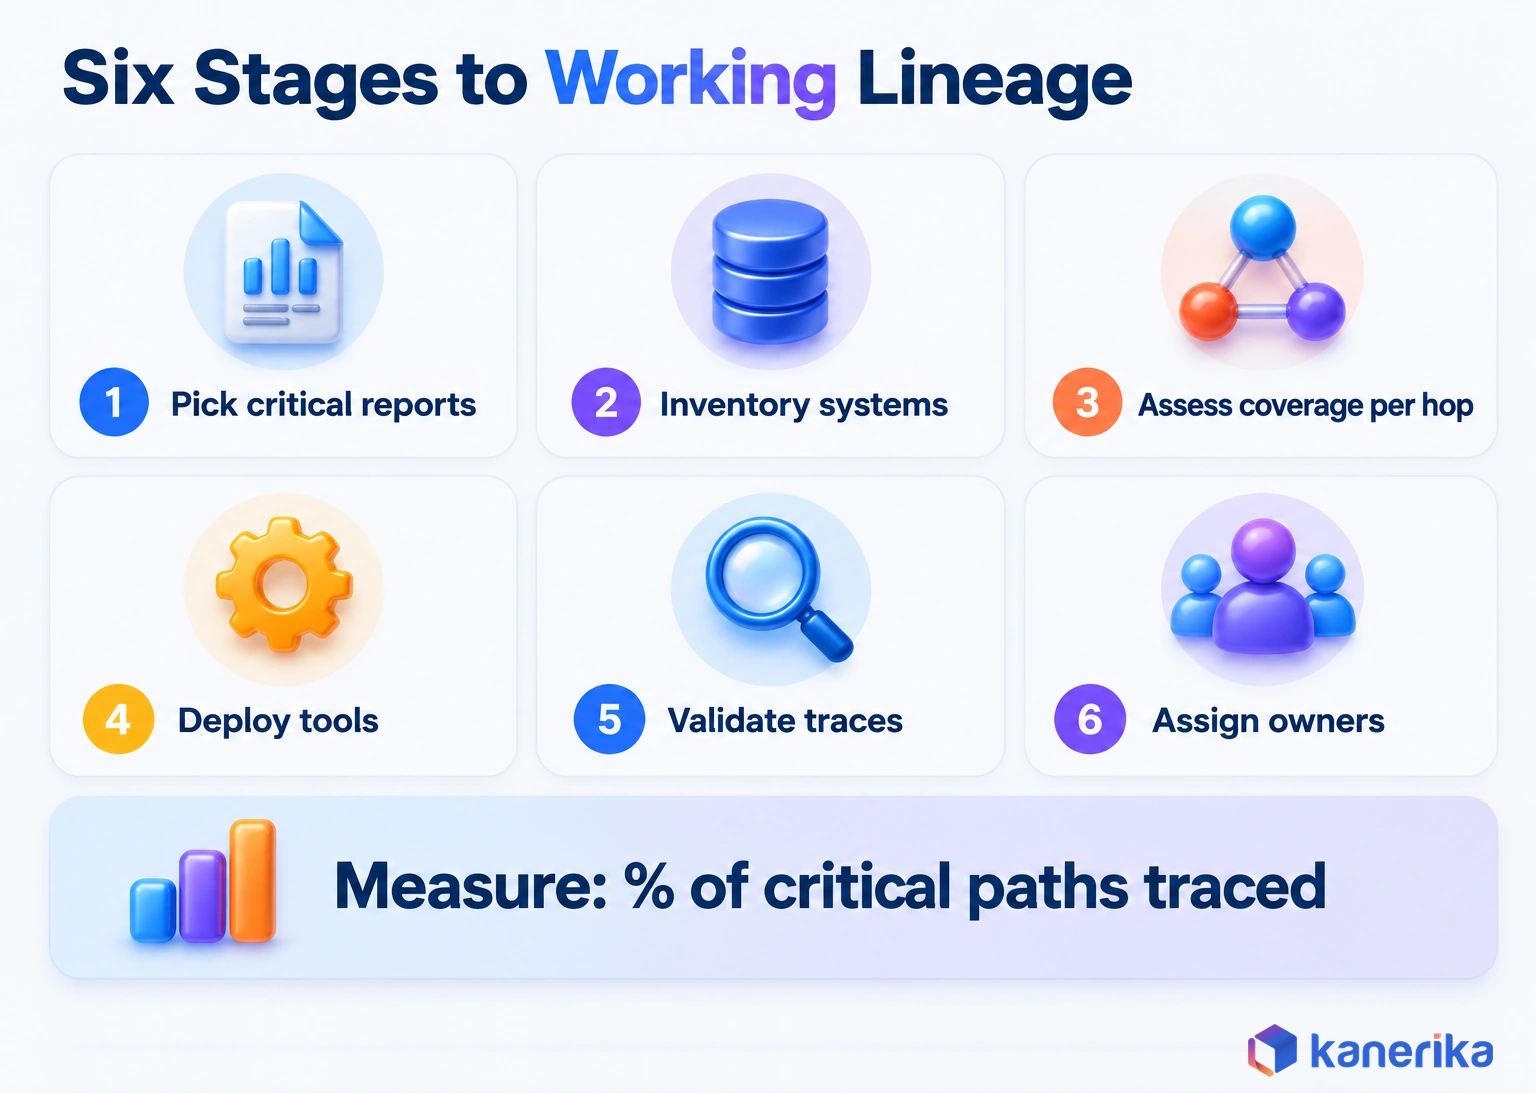
How to Implement Data Lineage in Six Stages
Lineage programs fail when they try to map everything at once. A staged plan that starts from the reports people care about gets value in weeks and builds from there.
- Pick critical data elements and reports. Choose the ten to twenty reports and fields that leadership, regulators or customers rely on most, such as revenue, margin and risk exposure.
- Inventory the systems. List every source, pipeline, warehouse layer and BI tool on those paths, including spreadsheets and manual uploads.
- Assess capture coverage per hop. For each hop, note which method could capture it and where nothing can. Stored procedures and custom scripts usually top that list.
- Deploy tools and integrations. Turn on native lineage first, then add scanners, OpenLineage instrumentation or manual entries for the gaps.
- Validate the graph. Compare sample traces against the actual SQL and job code. Track coverage as the percentage of critical paths you can trace end to end.
- Operate it. Name an owner per domain, the same principle behind a data mesh. Then add a lineage check to change management so no release ships without an impact review.
Validation is the stage teams skip, even though it is the one that makes lineage trustworthy. During a migration, pair it with data reconciliation tools so you can confirm the values match as well as the paths.
In short, coverage is a better progress metric than node counts. A graph with 40,000 nodes and no path through the margin report is less useful than a small graph that traces every critical number.
What Enterprises Get Wrong About Data Lineage
The same eight mistakes show up across industries, but none of them is about picking the wrong vendor. They are mostly about believing a graph covers more than it does.
- Relying on manual documentation alone. Hand-drawn diagrams go stale with the next sprint, and nobody notices until an audit.
- Treating “a connector exists” as “covered”. A connector that reads table names but not transformation logic leaves the important part dark.
- Stopping at table level. Table-level graphs cannot answer which field broke a metric, which is the question most incidents ask.
- Skipping stored procedures and custom SQL. Business rules often live in procedures that scanners cannot parse, so the graph jumps over them.
- Ending the graph before BI. If lineage stops at the warehouse, nobody can see which reports a change will break.
- Treating static metadata as run evidence. A parsed path shows what could happen, while an audit asks what did happen on a given date.
- Leaving lineage without an owner. A graph with no accountable owner or data steward per domain decays quietly until people stop trusting it.
- Assuming lineage equals compliance. Lineage is evidence for a control, not the control itself. Regulators still expect policies, owners and tested processes around it.
Most of these trace back to the same root cause. Lineage gets bought as a tool, yet it needs to run inside a data governance program with owners, reviews and a coverage target.
Fixing the list does not require a new platform, though. It usually starts with an honest coverage check on the paths that matter, followed by a plan for each hop that is still dark.
How Kanerika Implements Data Lineage
Kanerika treats lineage as part of governance delivery, so every engagement starts from the reports that matter rather than from a tool. The work follows the same six stages, grouped into five delivery steps. Discovery covers critical data elements and the systems behind them, which are stages one and two. A gap assessment then measures capture coverage per hop, followed by tool fit and build, validation, and handover to owners.
One engagement shows how that plays out in a regulated setting. A global bank with about 9,000 branches and 22,000 ATMs held data across SAP, Dynamics 365, CRM, Oracle, Netezza and file systems. In this banking engagement, Kanerika used Microsoft Purview to automate lineage from those sources through the Lakehouse layers. It also added data classification policies for PII, PCI and PHI data.
The results were measurable. The bank recorded zero data breaches and full adherence to compliance regulations, and data classification accuracy improved by 72%.
Outside banking, the approach works the same way. Discovery sets the coverage target, and the gap assessment shows which hops need scanners, OpenLineage events or manual entries. Validation then checks sample traces against real SQL before anything is called done.
Kanerika’s data governance services cover that full cycle, from ownership models to automated lineage. For Microsoft estates, the Microsoft Purview practice sets up scanning, classification and custom lineage for sources Purview cannot reach on its own. When monitoring is part of the brief, the team also helps compare data observability tools that read the same lineage graph.
Case Study
Zero Breaches, 100% Compliance for a Bank with Purview
A global bank with data across SAP, Dynamics 365, Oracle, Netezza and file systems got automated lineage through its Lakehouse layers, 72% better classification accuracy and zero data breaches.
Read the Case Study →
Wrapping Up
Data lineage turns a question that once took a week into one that takes minutes. The types that matter most are column-level and runtime lineage, because they answer which field changed and when.
On tools, single-platform estates should start with native lineage, and regulated multi-cloud estates need an enterprise platform. Engineering-led teams can build on OpenLineage instead. Whichever tool you pick, implement it by starting with critical reports, measuring coverage and keeping the graph current. To put data lineage to work, pick one critical number this week, trace it, and write down the first hop where the path goes dark.
Frequently Asked Questions
What is data lineage?
Data lineage is the record of where data comes from, every transformation it passes through, and every table, model and report that uses it. Teams read it backward to find the source of a wrong number. They read it forward to see what a change will affect. Most tools store it as a graph of datasets, columns, jobs and reports.
What is an example of data lineage?
A gross margin figure on a dashboard is a good example. It starts as order lines in an ERP system, loads into a warehouse, passes through a SQL view that applies discounts, and rolls up into an aggregate table. A semantic model turns that into a measure. Lineage records each of those hops, down to the discount column.
What is the difference between data lineage and a data model?
A data model describes how data is structured, with its entities, attributes and relationships. Data lineage describes how data moves and changes between systems over time. A model tells you what a customer table contains. Lineage tells you where each customer field came from and which reports depend on it, so the two work together.
What is the difference between data lineage and data observability?
Data observability monitors whether data is healthy, checking freshness, volume, schema and distribution. Data lineage maps where data comes from and where it goes. The two connect closely. When an observability alert fires, lineage shows which upstream job caused it and which downstream reports it will affect, so teams can fix and warn faster.
Who needs data lineage, and what are the benefits?
Data engineers, BI developers, governance leads, auditors and ML teams all rely on data lineage. It speeds up root cause analysis and makes schema changes safer. It also gives proof during migrations and evidence for regulators. For AI teams, it links models to the training data and features behind them, which makes reviews possible.
How does data lineage help validate data integrity and accuracy?
Lineage shows every step a value passed through, so teams can check each transformation against its expected logic. When a number looks wrong, a backward trace narrows the search to a few upstream steps. During migrations, lineage on both platforms confirms that reports draw on the right sources, while reconciliation checks confirm the values match.
Does Microsoft Purview provide end-to-end lineage, including Microsoft Fabric?
Purview captures lineage as data moves through Data Factory, Data Share and Power BI. It accepts custom lineage through Atlas hooks and its REST API, plus manual lineage with column mapping. Fabric has its own workspace lineage view at item level, showing sources one step upstream. End-to-end coverage depends on which of your sources Purview can scan.
Can Snowflake track column-level data lineage?
Yes. Snowflake lineage covers both object and column lineage, and each is retained for one year. The feature requires Enterprise Edition or higher. It is not available for objects in shared databases or in INFORMATION_SCHEMA. Paths that leave Snowflake, such as BI reports or upstream ETL tools, need another tool to complete the picture.
Are open-source data lineage tools suitable for enterprises?
They can be, if an engineering team is ready to run them. OpenLineage gives a standard format for lineage events, and Marquez stores and displays them. OpenMetadata, DataHub, Apache Atlas and Spline cover other needs. The trade is license savings for hosting, upgrades and connector maintenance, which in-house teams must own themselves.
How can data lineage help with regulatory compliance?
Regulators often ask how a reported figure was produced. Data lineage shows the sources, transformations and owners behind it. Banks follow BCBS 239, the Basel Committee principles for risk data aggregation published in January 2013. Privacy rules also require knowing where personal data flows. Lineage provides evidence, and controls and policies still have to surround it.
What is the future of data lineage?
Lineage is moving from static diagrams to runtime evidence that teams can query. Open standards such as OpenLineage let many tools share lineage events. Column-level coverage is becoming the expected depth. AI and ML lineage is also growing, linking model versions to training data and features so teams can explain and audit model behavior.
What are the main types of data lineage?
The main types come in pairs. Business lineage shows flows between systems, and technical lineage shows jobs and code. Table-level lineage links tables, while column-level lineage links individual fields. Design-time lineage is parsed from code, and runtime lineage is observed from jobs that ran. Teams also trace backward to sources and forward to consumers.
What is column-level data lineage?
Column-level data lineage shows which source column produced each target column, including the logic in between. It answers which field fed a broken metric, which a table-level graph cannot do. It matters most for audits, incident reviews and schema changes. Databricks Unity Catalog, Snowflake Enterprise Edition and IBM watsonx.data intelligence all capture lineage at column level.
What is data lineage in ETL?
In ETL, data lineage tracks how each extract, transform and load step moves and changes data. It records which source tables a job reads, what logic it applies, and which targets it writes. Good ETL lineage reaches inside transformations, so a team can see how a field was calculated as well as where it landed.
What are the best data lineage tools in 2026?
The right tool depends on the estate. Databricks Unity Catalog, Microsoft Purview, Microsoft Fabric and Snowflake give native lineage inside their own platforms. IBM watsonx.data intelligence, Informatica, Collibra, Alation and Atlan cover multi-vendor estates. OpenLineage with Marquez, OpenMetadata, DataHub, Apache Atlas and Spline suit engineering teams that run open-source software.
How do you create data lineage in an enterprise?
Start with the ten to twenty reports that matter most. List every system on their paths, then check which hops a tool can capture. Turn on native lineage first and fill gaps with scanners, OpenLineage events or manual entries. Validate traces against the real SQL, then assign owners and add lineage checks to change management.
How do you represent data lineage?
Data lineage is usually shown as a directed graph. Boxes stand for datasets, columns, jobs and reports, and arrows show how data moves between them. Good views let you expand a table into its columns and filter by time. Lineage can also be stored as rows in system tables, so teams can query it with SQL.
What is the difference between data lineage and data mapping?
Data mapping defines which source field corresponds to which target field, usually for one integration or migration. Data lineage records the full path data takes across many systems over time, including every transformation and every consumer. A mapping document is often the first lineage a migration team writes. Lineage then extends it across the whole estate.
What is the difference between data lineage and data provenance?
Data provenance focuses on origin and custody. It records who created a record, when, with which instrument or process, and whether it was altered. Data lineage focuses on the path and transformations between systems. Provenance matters most in science, healthcare and audit trails. Lineage supports root cause analysis, impact analysis and governance.




