TL;DR
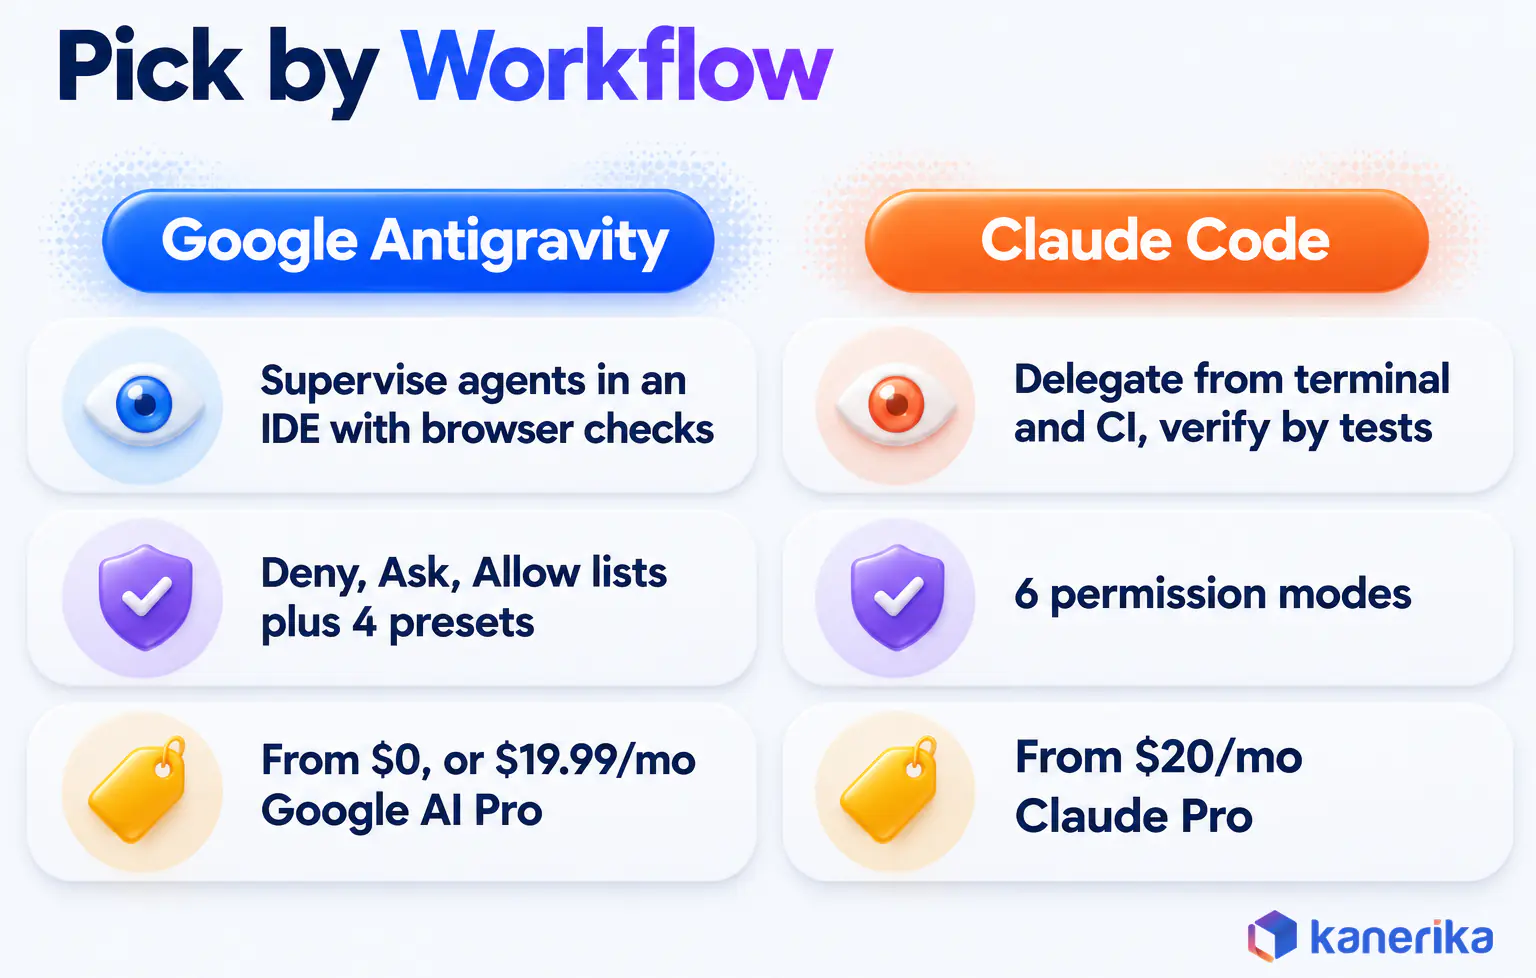
Google Antigravity vs Claude Code is a workflow choice: pick Antigravity to supervise agents in an IDE, and Claude Code to delegate from the terminal. Antigravity is a generally available agent platform with an App, IDE, CLI, extensions and an SDK, plus a built-in browser for checking UI work. Claude Code is Anthropic’s agent for the terminal, IDEs, desktop and web, and it comes with every plan from $20 Claude Pro upward. Antigravity can also run Claude Sonnet 5.5 and Opus 5.5 on paid plans, but inside its own agent harness, so results can differ. Antigravity starts free with weekly limits, while team seats cost $25 a month on Claude Team ($20 billed annually) or from $30 on Gemini Enterprise. Choose Antigravity for Google Cloud shops and frontend work, choose Claude Code for large repos and CI, and settle close calls with a two-week pilot.
Key Takeaways
- Antigravity is generally available as an App, IDE, CLI, extensions and SDK, so teams can supervise agents through plans, walkthroughs and browser checks.
- Claude Code runs in the terminal, VS Code, JetBrains, a desktop app, the web, Slack and Chrome, but it needs at least a Claude Pro plan.
- Claude Sonnet 5.5 and Opus 5.5 also run inside Antigravity on Pro (non-trial), Ultra and Enterprise plans, though Antigravity’s agent harness shapes the results.
- Antigravity uses Deny, Ask and Allow lists with four presets, while Claude Code has six permission modes from default to bypassPermissions.
- List prices start at $0 or $19.99 a month for Antigravity and $20 for Claude Pro, while Claude Team seats cost $20 to $25 a month and Gemini Enterprise seats start at $30.
- Pick by workflow and governance first, then confirm with a two-week pilot that measures cost per accepted pull request.
A Team Lead, Two Trial Seats and a 40-Engineer Decision
Picture an engineering lead with a Google AI Pro trial on one laptop and a Claude Pro seat on the other. By Friday, she owes her CTO one pick for 40 engineers.
Her first surprise comes on day one. On the trial, she cannot test Claude Sonnet 5.5 or Opus 5.5 inside Antigravity. That is because Google limits them to paid, non-trial Pro plans and above.
Her second surprise is how differently the two tools ask for permission. In its default mode, Claude Code reads files freely but asks before it edits anything. Antigravity’s default Auto preset, by contrast, runs commands in a sandbox with no network and checks anything outside it automatically.
So her decision turns on workflow, permissions and the bill for 40 seats, more than on which model sounds smarter. Every price, model and version below comes from vendor pages checked on November 3, 2026.
Google Antigravity vs Claude Code at a Glance
Both tools are coding agents that read a repository, change files and run commands for you. They belong to the wider family of AI coding agents, but they start from opposite ends of a developer’s day.
Antigravity builds the work around an app and an editor, so you watch agents plan, act and report back. Claude Code, on the other hand, starts in the terminal and then reaches outward into IDEs, a desktop app, the web and chat tools.
Side-by-Side Comparison
Table 1: Google Antigravity and Claude Code side by side, checked November 3, 2026 against vendor pricing and documentation pages.
| Area | Google Antigravity | Claude Code |
|---|---|---|
| Product surfaces | App, IDE, CLI, Extensions and SDK | Terminal CLI, VS Code, JetBrains, desktop app, web, Slack and Chrome |
| Primary workflow | Supervise agents in an app or IDE, then review plans, walkthroughs and browser checks | Delegate tasks from the terminal or IDE, then review diffs and verify with your own tests |
| Models | Gemini 4 Argon and Gemini 3.8 Flash, as well as Claude Sonnet 5.5 and Opus 5.5, by plan | Opus 5.5, Sonnet 5.5, Haiku 5.5 and Fable 5.1, by plan |
| Permission model | Deny, Ask and Allow lists, plus four presets from Request Review to Turbo | Six permission modes, from default to bypassPermissions |
| Entry price | Individual plan at $0 with weekly limits; Google AI Pro at $19.99 a month | Claude Pro at $20 a month, or $17 a month when billed annually |
| Team and enterprise route | Google Cloud: Gemini Enterprise from $30 per seat a month, or pay-as-you-go with a $0 seat fee | Claude Team from $25 per seat monthly; Claude Enterprise at $20 per seat billed annually, plus usage |
| Best fit | Google Cloud shops and UI work, especially when reviewers check agents visually | Mixed stacks, large repos and CI pipelines, especially when teams live in the terminal |
If you run a regulated codebase, read the permission and team rows first. Those two rows decide what an agent may touch, and they also decide who signs the contract.
What Google Antigravity Is in November 2026
Google Antigravity is an agent-first development platform, which means the agent does the work while you supervise it. The Antigravity pricing page labels the product Generally Available and lists five surfaces: the App, Extensions, CLI, IDE and SDK.
The App and the IDE are where most people meet it. You describe a task, the agent drafts an implementation plan, and then you approve or redirect that plan before code changes. When the agent finishes, it hands back a walkthrough with screenshots and browser recordings, so you can judge the result without rerunning everything.
Around that loop, the platform also carries the building blocks teams expect from a modern agent:
- Subagents and teamwork, so one task can split across several agents at once.
- Skills and rules, because the agent needs to learn how your team writes and reviews code.
- Hooks that run your own checks at set points while the agent works.
- MCP servers as well as a plugins Marketplace for outside tools and services.
- A built-in browser, so the agent can open and test the app it just built.
- Artifacts that record the work: implementation plans, walkthroughs, screenshots and browser recordings.
The Antigravity changelog shows how fast these pieces move. Version 2.28.0 shipped on October 27, 2026, and v2.28.2 followed two days later, so check the release notes before you lock a pilot plan.
How Antigravity Differs From Gemini Code Assist
Gemini Code Assist is Google’s coding assistant inside the IDEs developers already use. Antigravity, by contrast, is the agent-first platform, where the agent plans and carries out multi-step work while you review it. If you are comparing assistants of the first kind, start with our overview of AI code assistants.
Google also has a terminal agent of its own. Our Gemini CLI vs Claude Code comparison covers that matchup, so this guide stays on the Antigravity platform.
What Claude Code Is and Where It Runs
Claude Code is Anthropic’s coding agent, and it began life in the terminal. It reads your codebase, edits files and runs commands, while the Claude Code overview docs list four groups of places where it runs:
- The terminal, where you hand the agent tasks in plain language.
- IDEs: VS Code, as well as JetBrains through a plugin that needs the CLI installed.
- A desktop app and a web version, for when you work away from the editor.
- Team tools: Slack and a Chrome extension.
Claude Code comes with Claude Pro and every higher plan, but the Free plan does not include it. Like Antigravity, it also supports subagents, hooks, skills and MCP servers, plus a plan mode that maps out changes before any edit happens.
The deeper difference is where the work starts. Claude Code expects you to delegate a task and judge the diff, while Antigravity expects you to watch agents in a visual workspace. For Claude Code against two other agent styles, see OpenClaw vs Claude Code vs Claude Cowork.
Kanerika Service
Plan Your AI Coding Agent Rollout
Kanerika scopes which repos an agent may touch, sets permission policy and runs a measured pilot on Antigravity, Claude Code or both.
Explore Agentic AI ServicesAgent-First IDE vs Terminal-First Agent: How the Work Loop Differs
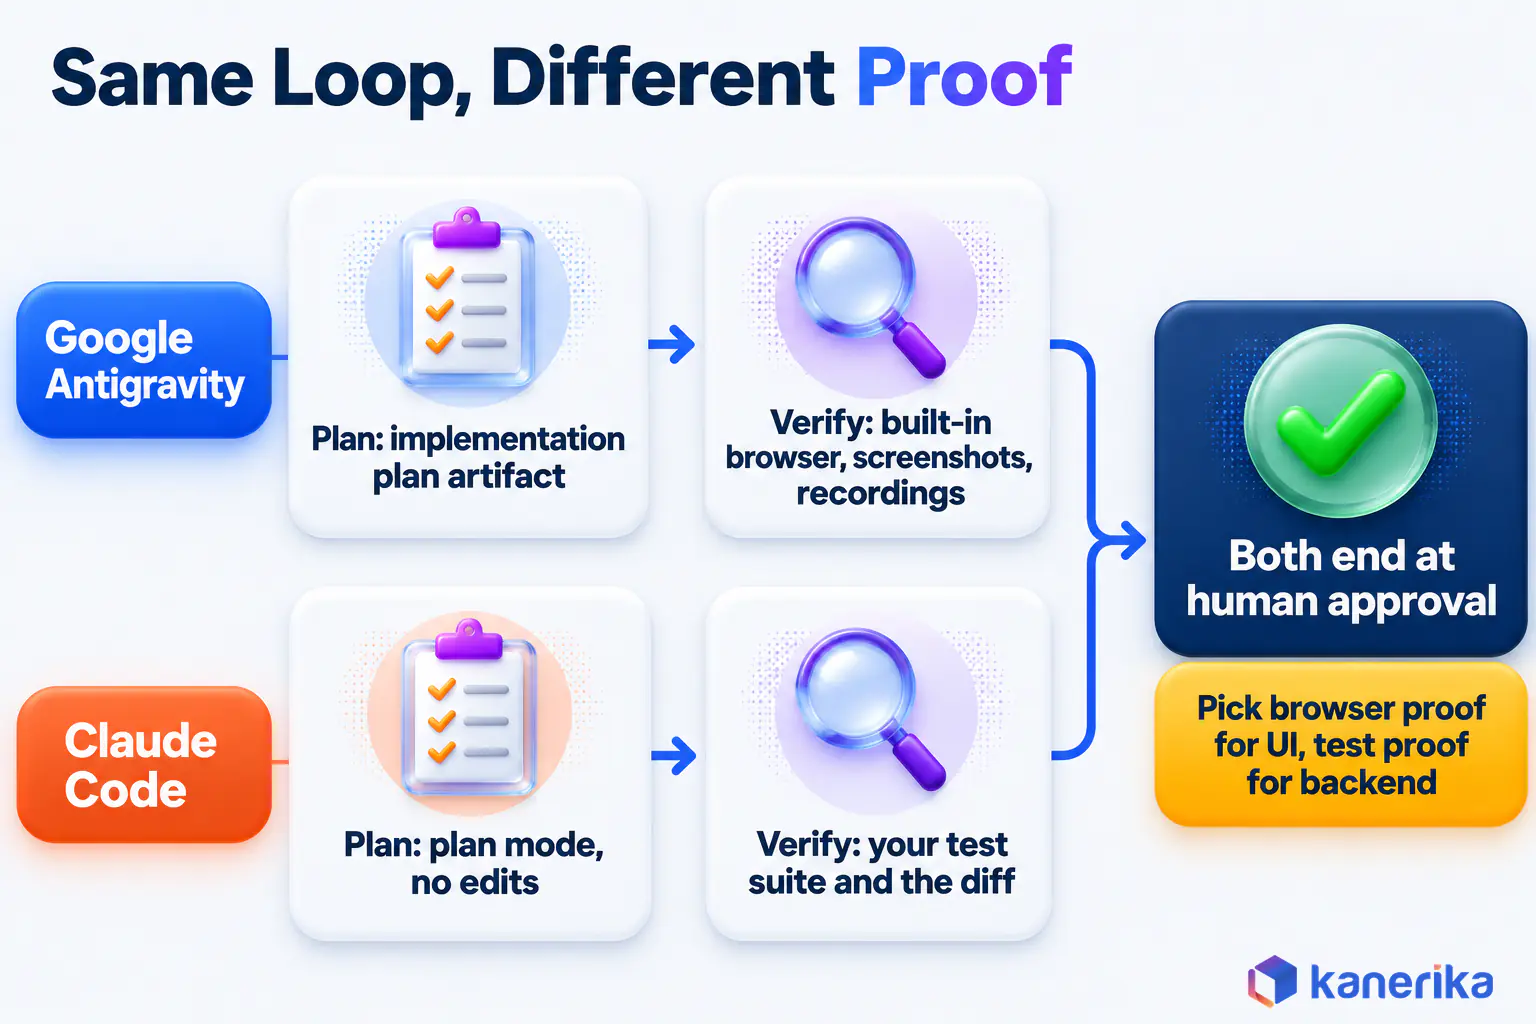
Every coding agent runs the same basic loop: plan the change, edit files, run something, check the result and wait for approval. What differs is where each step happens, and also what evidence you get back at the end.
Take a small task, such as adding a date filter to a dashboard page. In Antigravity, the agent drafts a plan, edits the code, opens the page in its built-in browser and then returns screenshots. In Claude Code, the agent proposes a plan, edits the files, runs your test suite and then shows you the diff.
Both loops end when a human approves the change. The four subsections below cover the places where the two loops split, starting with what you review.
Planning and Review Artifacts
Antigravity produces artifacts as it works: an implementation plan before coding and a walkthrough after it. You review the plan before the agent touches code, and then the walkthrough bundles screenshots and browser recordings as proof of what changed.
Claude Code takes a text-first route instead. Its plan mode lets the agent read and propose without editing, so the diff becomes the main review artifact. That suits reviewers who already think in pull requests and line comments.
Neither style wins in the abstract. A design-heavy team gets more from recordings, while a platform team gets more from a clean diff it can paste into review.
Browser Verification vs Test-Driven Verification
Antigravity’s built-in browser lets the agent open the app it built and capture what it saw. That matters most for UI work, since a passing unit test can still hide a broken layout or a dead button.
Claude Code verifies through whatever your repo already runs: unit tests, linters, type checks and build scripts. So the stronger your test suite, the more you can trust its results. That is why teams pair it with generative AI in software testing practices.
Parallel Agents and Long-Running Work
Both tools can split work across several agents at once. Antigravity uses subagents and teamwork, and it also supports scheduled runs through /schedule plus headless operation for jobs that run without a screen.
Claude Code supports subagents, agent teams and background agents, so a long task can keep running while you do something else. Still, running many agents at once quickly becomes an AI agent orchestration problem, because someone has to review every result.
Extensibility: MCP, Hooks, Skills and Plugins
Both tools connect to outside systems through the Model Context Protocol, an open standard for wiring agents to tools and data. Each also lets you shape agent behavior with skills, hooks and written rules, which is the practical side of agentic context engineering.
Table 2: Extension points in each tool, as listed in vendor docs and changelogs on November 3, 2026.
| Extension point | Google Antigravity | Claude Code |
|---|---|---|
| MCP servers | Supported | Supported |
| Hooks | Supported | Supported, and version 2.1.317 also adds onFailure “block” for Agent SDK hooks |
| Skills | Supported, as well as rules | Supported |
| Parallel agents | Subagents and teamwork | Subagents, agent teams and background agents |
| Plugins | Marketplace, with partner plugins from Canva, Figma, Linear, Notion, Stripe, Supabase and Vercel since v2.28.2 | Plugins and plugin marketplaces through /plugin, bundling skills, subagents, hooks and MCP servers |
The plugin row is where risk enters. Each plugin or MCP server is code you did not write, so treat it like a new dependency, as the security section below explains.
Which Models Each Tool Runs in November 2026
A coding agent is two things: the model that writes code and the agent harness around it that plans, calls tools and checks results. Antigravity and Claude Code differ on both, and your plan level also decides which models you get.
The Antigravity models page lists access by plan. Table 3 shows that matrix as of November 3, 2026.
Table 3: Models available in Google Antigravity by plan, from the Antigravity docs.
| Model | Plans that include it |
|---|---|
| Gemini 4 Argon | Pro, Ultra and Enterprise, but not Free or Plus |
| Gemini 3.8 Flash | All plans |
| Gemini 3.7 Flash, Gemini 3.6 Flash and Gemini 3.1 Pro | Enterprise only |
| Claude Sonnet 5.5 and Claude Opus 5.5 (thinking) | Pro (non-trial), Ultra and Enterprise |
| Claude Sonnet 4.6, Claude Opus 4.6 and GPT-OSS-120b | Free, Plus and Pro (GPT-OSS-120b also Ultra) until removal on November 18, 2026 |
Antigravity also exposes thinking levels of Low, Medium and High, while Nano Banana 2 powers its image generation. For background on Google’s model family, see our guide to Google Gemini AI.
Claude Code runs Anthropic’s own models: Opus 5.5, Sonnet 5.5, Haiku 5.5 and Fable 5.1. Fable 5.1 is the plan-sensitive one. On Max it can use up to half your weekly limit, but on Pro you pay for it with usage credits.
Here is the point that trips up many comparisons. When Claude Opus 5.5 runs inside Antigravity, Google’s agent harness decides the prompts, tools and checks around the model. So the same model can behave differently in each tool, and only a test on your repo shows by how much.
Our explainer on agentic harness engineering covers why the wrapper around a model matters this much. For a buyer, then, the lesson is plain: compare tools rather than model names.
What Changes on November 18 and December 1, 2026
Two dates matter for any pilot planned in November 2026. On November 18, 2026, Antigravity removes Claude Sonnet 4.6, Claude Opus 4.6 and GPT-OSS-120b from its model list.
On December 1, 2026, the Gemini 4 Argon API price doubles. Input moves from $2 to $4 per million tokens, while output moves from $10 to $20 per million tokens.
So budget any API-billed agent runs at the new rate from the first day of your pilot. Model prices are still only one line in an engineering budget. Team structure and delivery speed decide most of the rest, which is where product engineering discipline counts.
Case Study
40% Lower Dev Costs with Product Engineering
Kanerika assembled a 35-member team within 90 days for a global logistics spend management platform during a PE-backed merger, cutting development costs by 40% and time to market by 25%.
Read the Case Study →What Changed in the Latest Releases
Both products ship updates often, so any comparison is only as good as its check date. These are the latest changes each changelog listed on November 3, 2026.
Google Antigravity v2.28.0 to v2.28.2
- On October 27, 2026, v2.28.0 added the built-in browser, a PDF viewer and attachments of any file type.
- The v2.28.1 release then added a third-party tools notice on Marketplace plugins.
- On October 29, 2026, v2.28.2 added partner plugins from Canva, Figma, Linear, Notion, Stripe, Supabase and Vercel.
- That same release also added plugin account sign-in, although it is not yet available for business or enterprise accounts.
Claude Code 2.1.317
- Version 2.1.318 now tops the Claude Code changelog, which shows no release dates, but the governance changes below arrived in 2.1.317.
- Agent SDK hooks gained an onFailure “block” option.
- A cost report API arrived on the Claude apps gateway.
- Extra OpenTelemetry (OTel) attributes give monitoring tools more detail than before.
The two lists point in different directions. Claude Code’s additions lean toward governance, since cost reports and more telemetry help platform teams see what agents spend. Antigravity’s additions lean toward reach instead, with more file types and more partner tools inside the app.
Benchmarks: What the Numbers Show and What They Hide
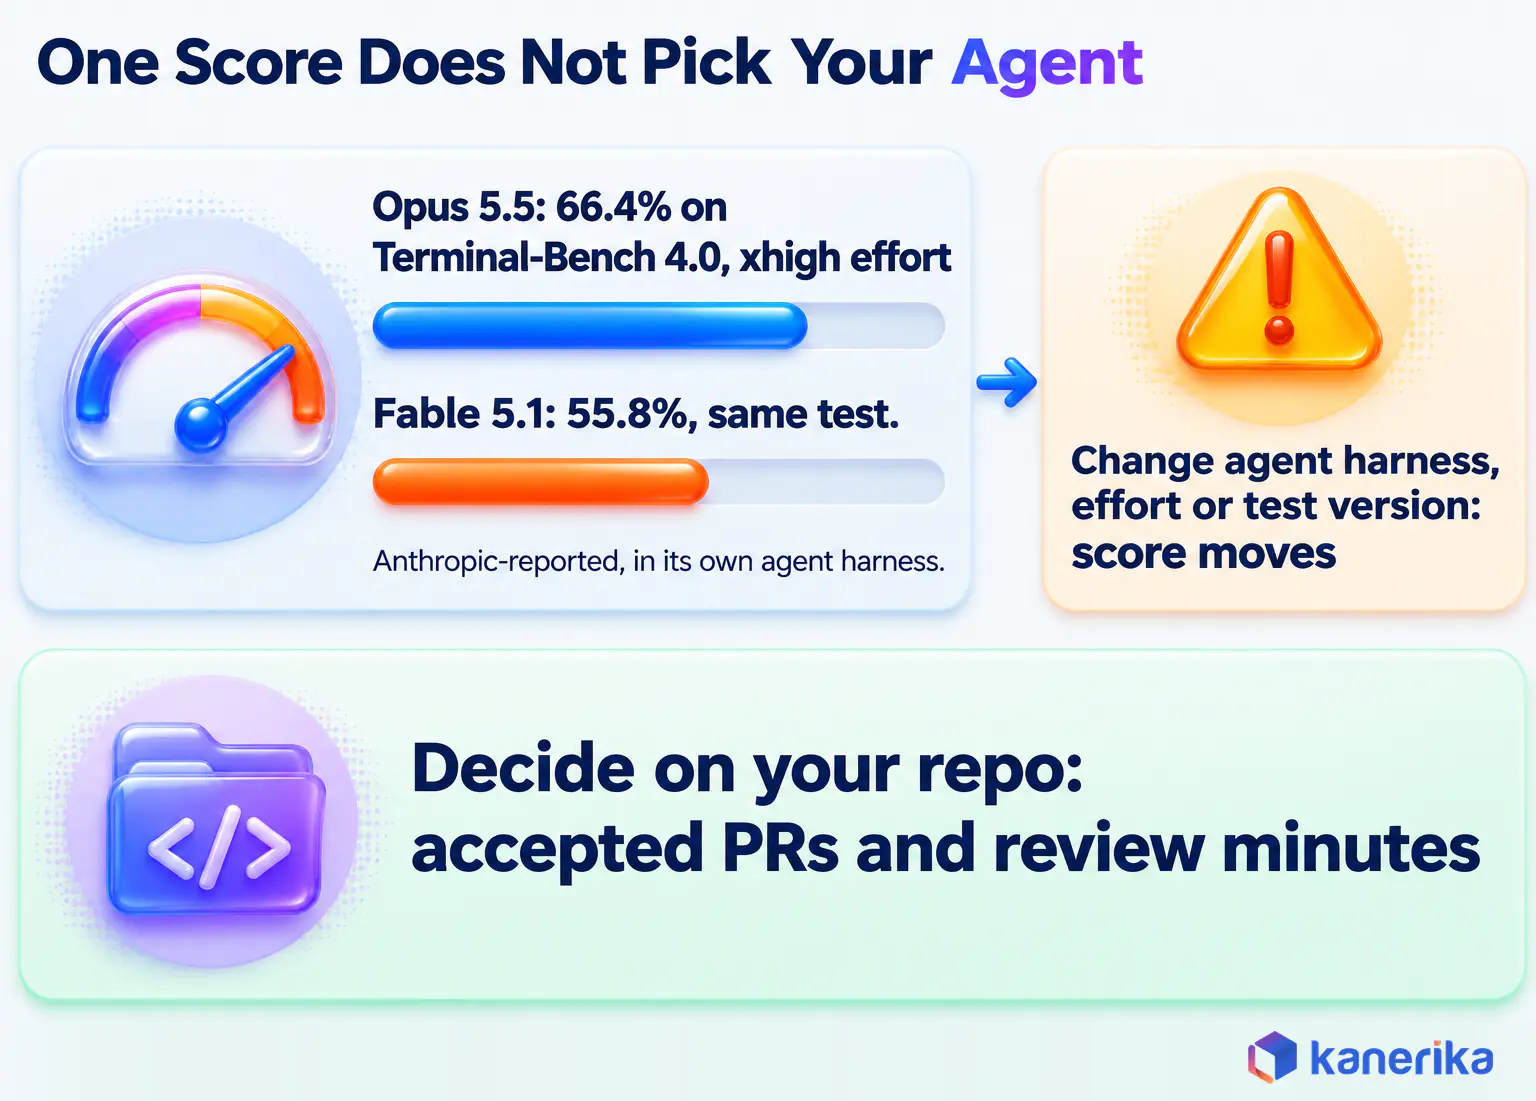
A benchmark tests a model inside one agent harness on a fixed set of tasks. Your team will run a different agent setup on a messier codebase, so a benchmark is a starting signal and never a verdict.
Search results for this comparison quote SWE-bench scores that disagree by many points. The gaps come from different benchmark versions, agent setups and effort settings, as well as vendor-run tests with their own rules.
One figure is worth knowing. Anthropic reports that Opus 5.5 scored 66.4% on Terminal-Bench 4.0 at xhigh effort, against 55.8% for Fable 5.1, on its Claude Opus page. Opus 5.5 matches or beats Fable 5.1 on most listed benchmarks, but those are Anthropic’s own numbers.
Google-side scores need the same care. So before you trust any number, ask which agent setup ran it, at what effort level, and on which version of the test.
The DORA 2025 report adds a wider warning. It found that AI acts as an amplifier of an organization’s existing strengths and weaknesses.
Put plainly, a team with weak tests and slow review will get faster at shipping problems, whichever agent it picks. That is why the pilot later in this guide measures accepted pull requests and review minutes, since those numbers reflect your own code. For test design, see our guide to AI agent evaluation.
Security, Permissions and Enterprise Governance
A coding agent can read secrets, run shell commands and push code, so its permission model matters more than any feature list. Both tools let you decide what the agent may do without asking, and both also let you lock that down hard.
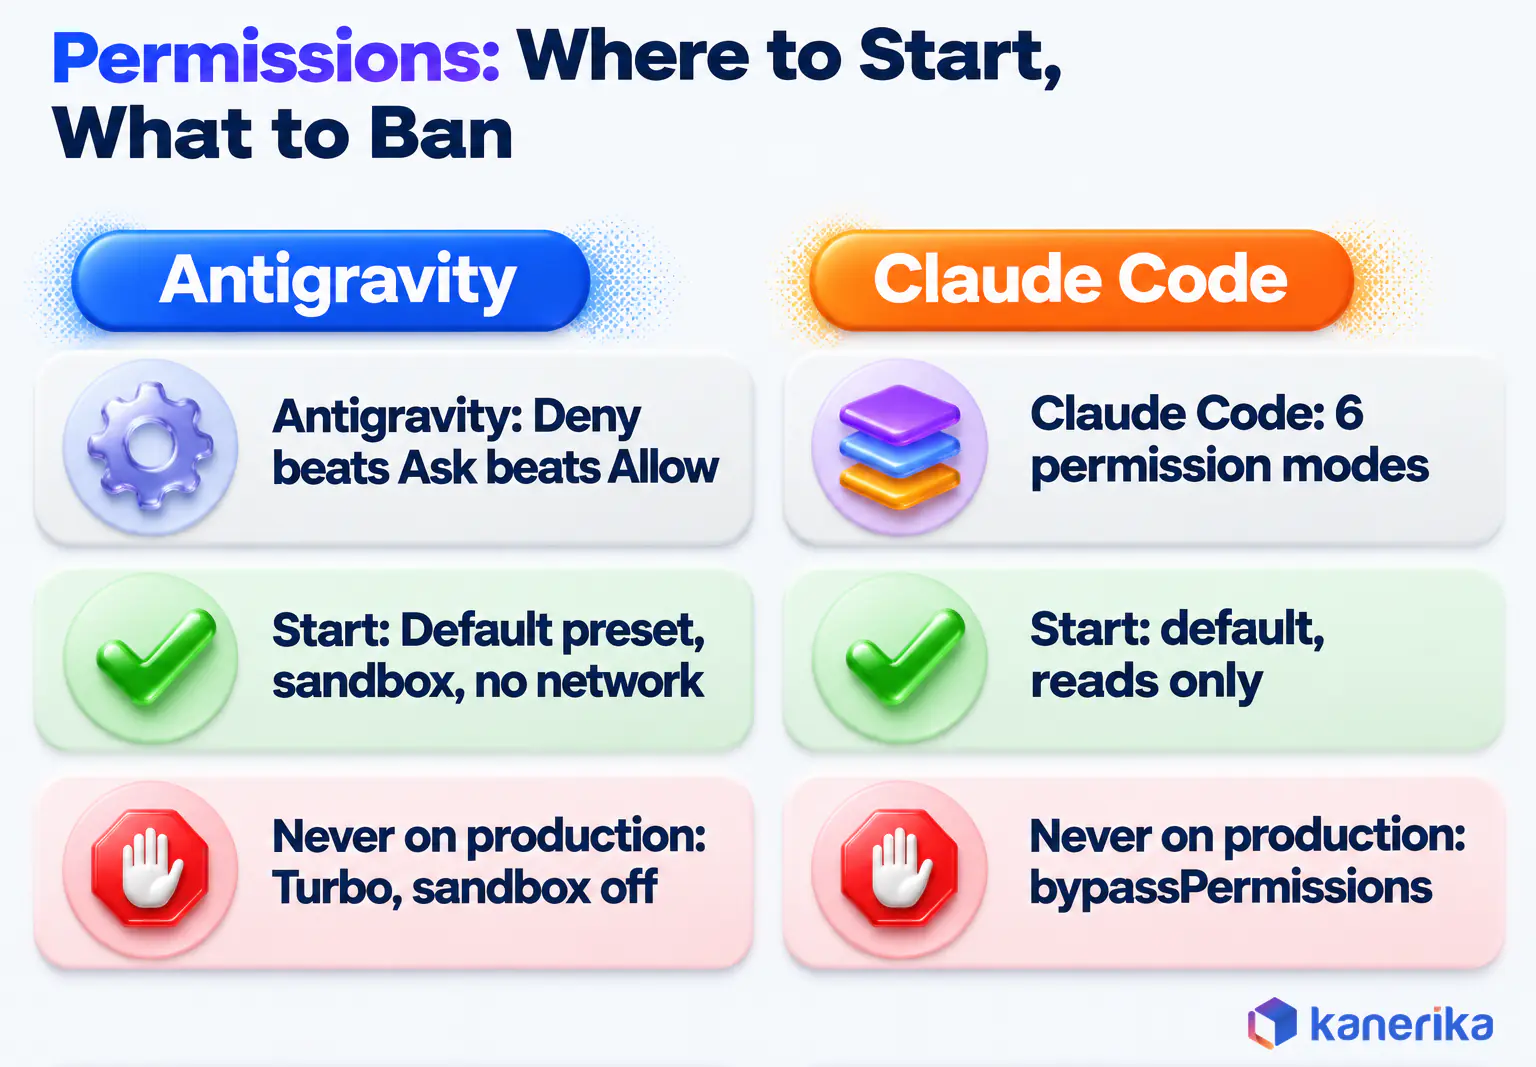
Antigravity’s permissions docs describe three lists: Deny, Ask and Allow. When rules conflict, Deny wins over Ask, and Ask wins over Allow. Four presets then sit on top of those lists.
Claude Code takes a different shape, because its six permission modes each set what runs without a prompt. Table 4 puts both side by side.
Permission Models Compared
Table 4: Permission settings compared, from the Antigravity and Claude Code docs on November 3, 2026.
| Tool | Setting | What runs without asking |
|---|---|---|
| Antigravity | Deny, Ask and Allow lists | Rules per action, where Deny beats Ask and Ask beats Allow |
| Antigravity | Request Review preset | No terminal commands: the sandbox is off, every command asks and file access is workspace only |
| Antigravity | Default preset | Terminal sandbox, workspace and temp folders only, with no network |
| Antigravity | Auto preset | The default where available: sandboxed commands with no network, and commands outside the sandbox checked automatically |
| Antigravity | Turbo preset | Sandbox off, so access is unrestricted |
| Claude Code | default | Reads only |
| Claude Code | acceptEdits | Reads, file edits and common filesystem commands |
| Claude Code | plan | Reads, plus classifier-approved commands when auto mode is available |
| Claude Code | auto | Everything, with background safety checks |
| Claude Code | dontAsk | Reads and pre-approved tools, while anything that would prompt is denied |
| Claude Code | bypassPermissions | Everything, so it is meant for isolated containers and VMs only |
The decision rule is simple. Antigravity now ships on Auto, so switch it to Default and keep Claude Code on default, then widen access one repo at a time. Never allow Turbo or bypassPermissions on a production repository.
Prompt Injection and Plugin Risk
Prompt injection is the threat both tools share. A README, an issue comment or a config file can carry instructions that the agent reads as commands. Untrusted MCP servers and plugins widen that surface, and Antigravity has shown a third-party tools notice on Marketplace plugins since v2.28.1.
Here is how that plays out. An agent asked to fix a failing test reads a README line telling it to upload environment files. With the sandbox on and the network off, that request fails harmlessly, but under Turbo or bypassPermissions nothing stops it.
Our guide to agentic AI security covers these attacks in depth. The short version is to deny secrets folders, keep the sandbox on and approve each new MCP server as you would a new vendor.
Enterprise Readiness Checklist
Before any agent touches a production repository, run these eight checks with security and procurement. Each one maps to what the vendors publish, and when a vendor page is silent, the check says what to request.
- Identity and seats: confirm how seats are provisioned on Gemini Enterprise or Claude Team and Enterprise, as well as who can add users.
- Data terms: Antigravity business use runs under the Google Cloud Terms of Service. For SOC 2 or HIPAA needs, request each vendor’s current attestation and contract terms.
- Permission policy: write down which preset or mode each repo tier may use, so Turbo and bypassPermissions stay banned on production.
- Sandbox and network: keep Antigravity’s Default preset for sensitive repos, and also hold Claude Code to default or plan mode there.
- Audit and cost telemetry: route Claude Code’s OTel data and cost report API into your monitoring, then review Antigravity’s admin controls.
- Spend caps: set Antigravity spend caps in Google Cloud, while you track Claude usage against plan limits and API credits.
- Model availability: confirm the models you tested exist on the plan you will buy, since Claude models in Antigravity need a paid Pro plan or higher.
- Rollback: agree how to revert an agent’s change, who owns the fix and how fast it must happen.
Telemetry is the check teams skip most often, even though it is the one that shows what agents actually did. Our guide to AI agent observability explains what to log, while an AI governance framework turns these checks into written policy per repo tier.
Checklist
Download the AI Governance Checklist
A practical list of controls to put in place before AI agents work on production code and data.
Get the Checklist →Pricing: Subscriptions, API Tokens and Team Cost
Pricing for coding agents has two layers: the seat or subscription you pay each month, and the usage that agents burn on top. Antigravity and Claude Code price both layers differently, so compare them at your real team size.
Subscription and Seat Prices
Table 5 lists subscription prices from the Claude pricing page as well as the Antigravity pricing page, checked November 3, 2026.
Table 5: Subscription and seat prices at list rates.
| Plan | List price | What you get |
|---|---|---|
| Antigravity Individual | $0 a month | Basic weekly rate limits, but unlimited Tab completions and Command requests |
| Google AI Pro | $19.99 a month or $199.99 a year | Gemini 4 Argon in Antigravity, plus Claude Sonnet 5.5 and Opus 5.5 once the trial ends |
| Gemini Enterprise Standard or Plus | From $30 per seat a month | Business route through Google Cloud, with admin controls and spend caps |
| Google Cloud pay-as-you-go | $0 seat fee | Pay for usage under Google Cloud terms |
| Claude Free | $0 | Claude Code not included |
| Claude Pro | $20 a month, or $17 a month billed annually ($200 up front) | Claude Code included |
| Claude Max | $100 a month | 5x Pro usage and $100 a month in API credits, while Fable 5.1 can use up to half the weekly limit |
| Claude Ultra | $200 a month | 10x Pro weekly usage, no 5-hour limit for verified accounts and $200 a month in API credits |
| Claude Team Standard | $25 per seat monthly, or $20 billed annually | Standard team seat |
| Claude Team Premium | $125 per seat monthly, or $100 billed annually | 5x more usage than Standard |
| Claude Enterprise | $20 per seat a month, billed annually, 20-seat minimum | Usage cost scales with model and task |
API Token Prices
API prices matter when agents run in CI or through an SDK, because every token is billed. Table 6 uses Anthropic’s API pricing docs as well as Google’s published Gemini rates.
Table 6: API token prices per million input and output tokens.
| Model | Input / output price | Notes |
|---|---|---|
| Claude Opus 5.5 | $4 / $20 | 1M-token context, 128K max output |
| Claude Sonnet 5.5 | $2 / $10 | 1M-token context, 128K max output |
| Claude Haiku 5.5 | $0.10 / $0.50 for prompts up to 100K tokens | Higher output rate when prompts exceed 100K tokens |
| Claude Fable 5.1 | $10 / $50 | 1M-token context, 128K max output |
| Gemini 4 Argon | $2 / $10 through November 30, 2026; $4 / $20 from December 1, 2026 | Up to 1M combined context |
| Gemini 3.8 Flash | $0.75 / $3.75 through December 31, 2026; then $1.50 / $7.50 | Rate doubles after December 31, 2026 |
Worked Scenarios at List Price
These examples use list prices only, so treat them as arithmetic rather than quotes. Usage overages, API-billed runs and the reviewer time each pull request needs all come on top.
- One developer: Claude Pro costs $20 a month while Google AI Pro costs $19.99, a gap of one cent. The Antigravity Individual plan costs $0, but it carries basic weekly limits and no Gemini 4 Argon.
- Ten-person team: 10 Claude Team Standard seats cost 10 x $25 = $250 a month, or $200 billed annually. Ten Gemini Enterprise seats start at 10 x $30 = $300 a month.
- Fifty-person org: Claude Enterprise costs 50 x $20 = $1,000 a month billed annually, plus usage. Gemini Enterprise starts at 50 x $30 = $1,500 a month.
- Mixed Claude seats: 10 Team Premium seats and 40 Standard seats cost $1,250 + $1,000 = $2,250 a month at monthly rates.
- One agent run on the API: take 200,000 input tokens and 20,000 output tokens. On Sonnet 5.5 that costs $0.40 + $0.20 = $0.60, while Opus 5.5 costs $1.20.
- The same run on Gemini 4 Argon: it costs $0.60 through November 30, then $1.20 from December 1, 2026.
Cost control is a governance job as much as a finance one. Spend caps, API credit limits and usage telemetry belong in the same policy as permissions, so finance and security work from one picture.
Kanerika Service
Get an AI Governance Assessment
Kanerika reviews permission policy, data terms, spend caps and telemetry before coding agents reach production repositories.
Explore AI Governance ServicesSeat price also rarely decides the choice. A tool that saves ten review minutes per pull request beats a cheaper seat with more rework. That is why the pilot below tracks cost per accepted pull request.
Google Antigravity vs Claude Code: Which to Choose by Workload
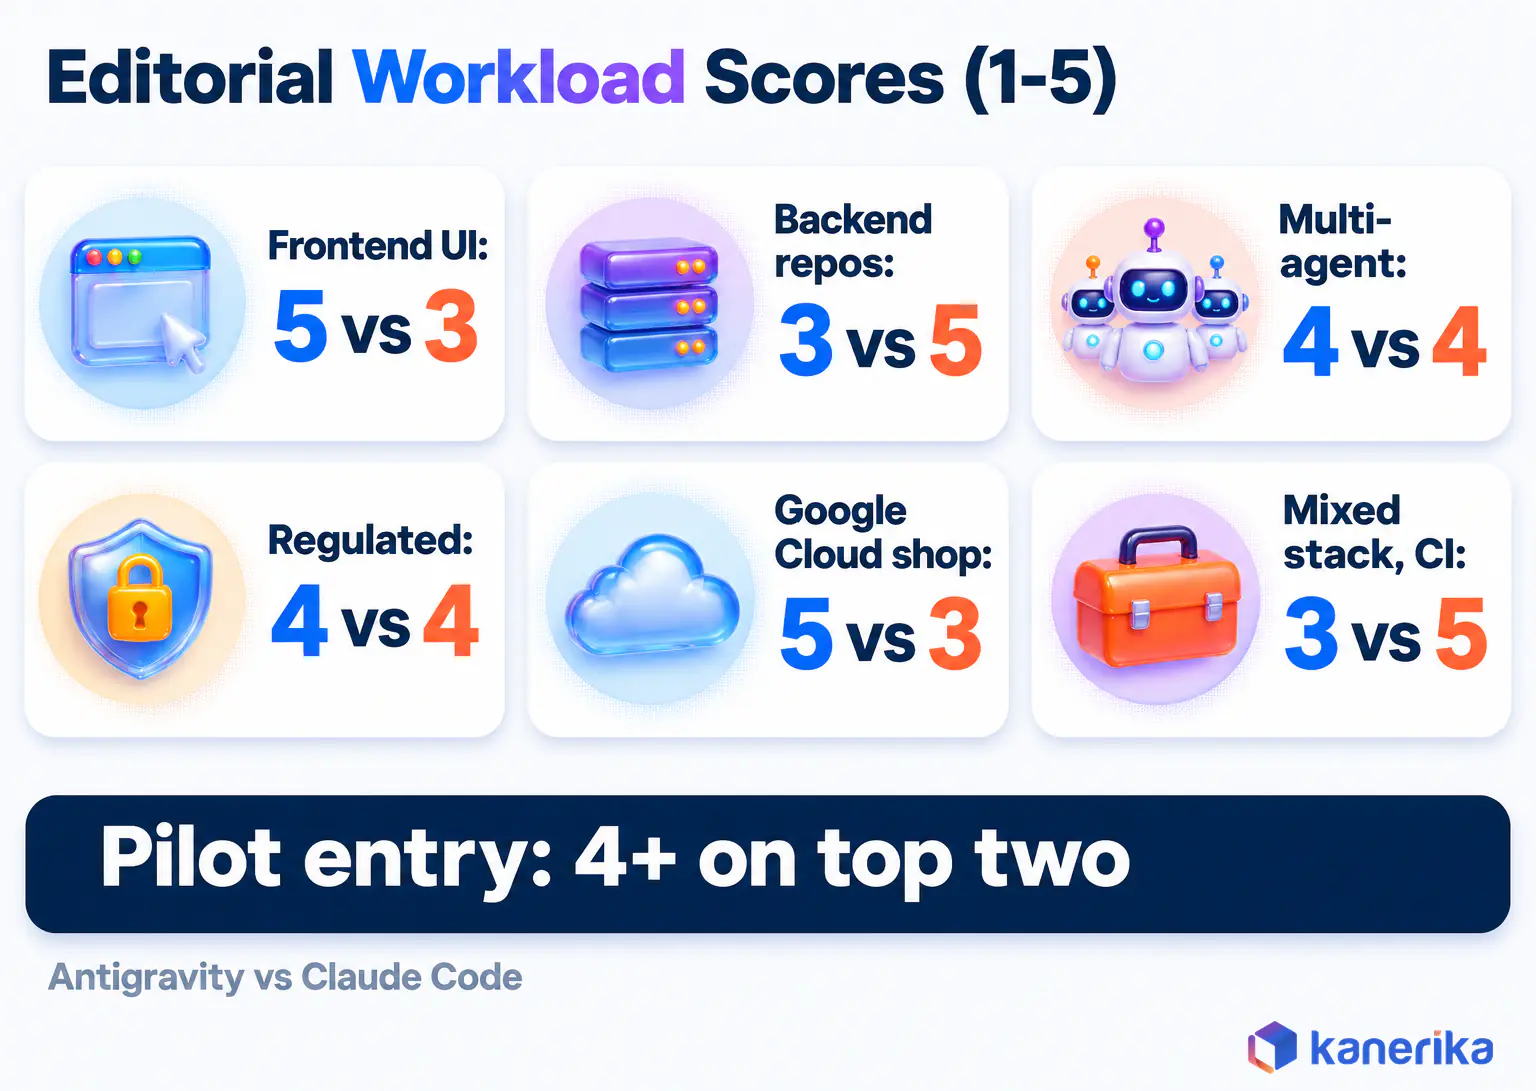
The right pick depends on the work your engineers do most, so start from workloads instead of feature lists. Below, each workload gets a score from 1 to 5 per tool, which is our editorial judgment rather than a benchmark.
Treat the scores as a starting point for your own shortlist meeting. Then adjust them for your codebase, your test coverage and how your reviewers like to work.
Frontend and UI Work
Antigravity has the edge here, so we score it 5 against 3 for Claude Code. Its built-in browser and walkthrough recordings let a reviewer see the page the agent built, which catches layout bugs that tests miss.
Large Backend Repos and Refactors
Claude Code fits better, at 5 against 3, because it runs inside your existing terminal and CI habits. Opus 5.5 also brings a 1M-token context window with 128K output for wide changes.
Multi-Agent Work
This one is even, at 4 each. Antigravity shows parallel agents in a visual workspace, while Claude Code runs subagents, agent teams and background agents from the terminal.
Regulated Enterprise
We also score this 4 each, since both tools have granular permissions. Your data terms, vendor attestations and telemetry needs decide it, so let procurement and security break the tie.
Google Cloud Shop or Mixed Stack
If your company already buys Google Cloud, Antigravity’s Gemini Enterprise route and spend caps fit existing billing, so it scores 5 against 3. A mixed stack with pipelines across clouds reverses that score, because Claude Code drops into any terminal.
Turn those scores into a shortlist rule. A tool should score 4 or more on your top two workloads before it enters your pilot.
Strengths and Trade-Offs
Table 7: Strengths and trade-offs at a glance.
| Tool | Strengths | Trade-offs |
|---|---|---|
| Google Antigravity | Visual supervision, a built-in browser and plan artifacts, as well as Gemini and Claude models in one app with Google Cloud billing | Claude models need a paid Pro plan, the model list changes on November 18, and the Argon API price doubles on December 1 |
| Claude Code | Terminal-first delegation, six permission modes and OTel data, as well as a cost report API and wide surface coverage | Not included on Claude Free, and it runs Anthropic models only, with Fable 5.1 limited by plan |
Still comparing more options? See GPT Codex vs Claude Code, Copilot, Cursor and Windsurf compared and Grok Build vs Hermes vs Claude Code. If you start from prototypes rather than production code, also read our take on vibe coding.
How to Run a Fair Two-Week Pilot
A pilot is the most reliable way to settle a close call. It is only fair, though, when both tools face the same model, tasks and rules. Two weeks is long enough to see real pull requests, yet short enough to hold the team’s attention.
- First, pick one model for both tools: Claude Sonnet 5.5 or Opus 5.5, since both run in Claude Code and in paid Antigravity plans.
- Run the same 10 to 20 backlog tasks in both tools, so UI fixes, backend changes and at least one refactor all appear.
- Fix the permission setting at Default in Antigravity (not its Auto default) and default in Claude Code, then leave it unchanged for two weeks.
- Record four metrics per task: accepted pull request rate, review minutes per pull request, escaped defects and cost per accepted pull request.
- Use the same reviewers for both tools, because reviewer habits can skew the scores.
- Finally, run the exit gate below before anyone buys seats.
Cost per accepted pull request ties the metrics together. To get it, divide seat cost plus usage for the pilot by the number of pull requests that merged.
Baseline your review and defect numbers before day one, or you will have nothing to compare against. Our list of software development KPIs covers how to set those baselines.
The Pilot Exit Gate: Four Governance Questions
A tool that wins on metrics still has to pass four questions before it reaches production. Write the answers down, because an auditor will ask for them later.
- What code does this agent touch, and where does that code go? Classify repos with regulated data, personal data or proprietary IP first, then scope permissions from that.
- What can the agent do without human approval? Define the line between autonomous action and review, and then enforce it in your CI/CD pipeline.
- How will you detect and fix AI-written defects in production? Agree the detection and repair steps before the first agent pull request merges.
- What is the rollback plan? Test how fast the team can revert an agent’s breaking change, and also name who owns the incident.
Passing the gate starts the harder part. Production needs owners, monitoring and support long after the pilot team moves on.
How Kanerika Helps Engineering Teams Adopt AI Coding Agents
Kanerika helps engineering teams move coding agents from a trial seat to governed daily use, whichever tool wins the pilot. The work runs in five stages, and each stage ends with something the team can check.
- Workflow and risk assessment: map the repos, data and pipelines the agent will touch, then rate each one by risk.
- Agent harness and permission policy: set a preset or mode per repo tier, as well as deny lists for secrets and the sandbox on by default.
- Two-week paired pilot: run both tools on the same tasks, then report cost per accepted pull request.
- Rollout with telemetry: wire Claude Code’s OTel data and cost report API, or Antigravity’s spend caps, into review gates and dashboards.
- Ongoing support: embedded engineers through Forward Deployed Engineering keep agents, policies and integrations working once the pilot ends.
The order matters, because each stage feeds the next one. The risk map from stage 1 sets the permission tiers in stage 2, and those tiers then fix the rules for the stage 3 pilot.
Stage 4 turns pilot metrics into standing dashboards. That way, the cost per accepted pull request you measured in two weeks keeps being tracked after rollout.
Stage 5 decides whether the rollout lasts. Our explainer on forward deployed engineers shows how that role differs from a standard software engineer, and why it suits agent rollouts.
Datasheet
Forward Deployed Engineers Datasheet
How Kanerika’s embedded engineers work inside your team to take AI pilots into production and keep them running.
View the Datasheet →This work sits inside our agentic AI services and AI governance services. It also connects to the code itself through custom software development, and Kanerika is part of the Claude Partner Network.
Proof From a Product Engineering Engagement
The closest proof is a product engineering engagement rather than an AI coding agent rollout. A global logistics spend management and freight audit platform needed to scale during a PE-backed merger. Kanerika then assembled a 35-member team within the first 90 days.
The product engineering engagement cut development costs by 40% and brought products to market 25% faster. That discipline of clear ownership, measured delivery and governed change is exactly what a coding agent rollout needs.
What a Rollout Leaves Behind
A finished rollout leaves four working artifacts: a permission policy per repo tier, a pilot scorecard, a telemetry dashboard and a rollback runbook. Those artifacts stay useful even if you switch tools later, because they describe your rules instead of a vendor’s.
They also make the next decision faster. When a new agent or model ships, the team reruns the same pilot and scorecard instead of starting the debate from scratch.
Give each artifact a named owner: platform engineering for the permission policy, team leads for the scorecard and security for the rollback runbook. Without owners, policies drift as soon as the pilot team disbands.
Review the scorecard every quarter, too. Both vendors change models and prices often, as the November 18 and December 1, 2026 changes on the Google side show.
Choosing a partner for this work is a decision of its own. The podcast below covers what to look for in a product engineering partner.
Bottom Line: Google Antigravity vs Claude Code
Pick Google Antigravity if your team supervises agents visually, builds a lot of UI or already buys through Google Cloud. Pick Claude Code if your team delegates from the terminal, works in large repos and wants six permission modes with OTel telemetry.
Teams that want Claude models in a visual workspace can also run them in Antigravity on a paid plan. Expect Antigravity’s agent harness to change the results, though, so test before you commit.
When the call is close, a two-week pilot on your own repo settles Google Antigravity vs Claude Code better than any benchmark.
Frequently Asked Questions
Is Google Antigravity as good as Claude Code?
Both are strong coding agents, but they suit different workflows. Antigravity fits teams that supervise agents in an app or IDE and check UI work in a built-in browser. Claude Code fits teams that delegate tasks from the terminal and verify results through their own tests. Run a short pilot on your repository to see which one your team prefers.
Is there a Google equivalent to Claude Code?
Google Antigravity is the closest equivalent. It is an agent-first platform with an App, IDE, CLI, extensions and an SDK, and its agents plan, edit code, run commands and verify results. Google also has Gemini CLI, a terminal agent closer to Claude Code’s style of working, which our Gemini CLI vs Claude Code comparison covers in detail.
Is Google Antigravity better for running multiple AI coding agents?
Antigravity makes parallel agents easy to watch, with subagents, teamwork, scheduled runs and headless operation in a visual workspace. Claude Code also runs subagents, agent teams and background agents, but from the terminal. Neither wins outright here. Pick the tool whose review flow your team will keep up with, because every agent result still needs a human check.
Which AI coding tool is safer for enterprise source code?
Neither is safe by default for every repository, but both can be locked down. Antigravity uses Deny, Ask and Allow lists with a sandboxed Default preset. Claude Code has six permission modes, from read-only default to bypassPermissions. Real safety comes from your policy, so keep sandboxes on, deny secrets folders and ban Turbo and bypassPermissions on production.
Is Claude Code compliant with HIPAA and SOC 2?
Compliance depends on your plan, contract and use case, so do not rely on a blog answer. Ask Anthropic for its current attestation reports and contract terms for the plan you will buy, and ask Google the same for Antigravity. Then confirm how code, prompts and logs are stored, and who on the vendor side can access them.
What does SWE-bench measure, and should you trust benchmark claims?
SWE-bench measures how well a model and its agent harness fix real software issues taken from public code repositories. Scores vary by benchmark version, agent setup, effort setting and who ran the test, which is why published numbers disagree. Treat vendor scores as a starting signal, then measure accepted pull requests and review time on your own code.
Is Claude Code the best coding agent, or is there anything better?
No single agent is best for every team. Claude Code is strong for terminal-first work and large repos, while Antigravity suits visual supervision and UI checks. Codex, Copilot, Cursor and Windsurf each fit other workflows as well. Shortlist two tools that score well on your top workloads, then let a two-week pilot on your repository decide.
Which is easier for beginners?
Antigravity is often easier for beginners because its App and IDE show plans, walkthroughs and browser screenshots, so you can see what the agent did. Claude Code assumes some comfort with the terminal, though its VS Code and desktop surfaces lower that bar. Either way, beginners should start in a cautious permission setting and review every change.
Can Google Antigravity run Claude models like Opus 5.5 and Sonnet 5.5?
Yes. Antigravity lists Claude Sonnet 5.5 and Claude Opus 5.5 as thinking models on the Pro plan outside the trial, and on Ultra and Enterprise. They are not on the free plan. The models run inside Google’s agent harness, so results can differ from the same model in Claude Code. Older Claude 4.6 models leave Antigravity on November 18, 2026.
Is Google Antigravity free to use?
Antigravity has an Individual plan at $0 a month with basic weekly rate limits and unlimited Tab completions and Command requests. The free plan includes Gemini 3.8 Flash but not Gemini 4 Argon or the Claude 5.5 models. Google AI Pro at $19.99 a month adds those models for individuals, while businesses buy seats or usage through Google Cloud instead.
How much does Claude Code cost compared with Google Antigravity?
Claude Code starts with Claude Pro at $20 a month, or $17 a month billed annually, and the Free plan does not include it. Antigravity starts at $0, and Google AI Pro costs $19.99 a month. For teams, Claude Team Standard costs $25 per seat monthly, while Gemini Enterprise starts at $30 per seat a month through Google Cloud.
What is Google Antigravity and how is it different from Gemini Code Assist?
Google Antigravity is an agent-first development platform where agents plan, write, run and verify code while you supervise through plans and walkthroughs. Gemini Code Assist is Google’s coding assistant inside existing IDEs. Choose Code Assist for help inside your current editor, and choose Antigravity when you want agents to carry out multi-step tasks under your review.
Is Gemini CLI similar to Claude Code?
Gemini CLI is closer to Claude Code than Antigravity is, because both are terminal agents that read a repository, edit files and run commands. Their access rules, models and pricing differ, so that matchup needs its own look. Our Gemini CLI vs Claude Code guide covers it, while this guide compares Claude Code with the wider Antigravity platform.
Is Google Antigravity just VS Code, and do I have to change editors?
Antigravity is more than an editor. It includes an IDE, but it also has a standalone App, a CLI, extensions and an SDK, plus agent features like implementation plans, walkthroughs and a built-in browser. Teams attached to their current setup can look at the Extensions and CLI surfaces first, then decide whether switching to the full IDE is worth it.
Can Claude Code work with VS Code and JetBrains IDEs?
Yes. Claude Code runs in VS Code and in JetBrains IDEs, where the JetBrains plugin needs the Claude Code CLI installed. It also runs in the terminal, a desktop app, the web, Slack and a Chrome extension. Teams can keep their current editor and still use plan mode, subagents, hooks, skills and MCP servers in their daily work.
Which is better for large codebases and complex refactoring?
Claude Code usually fits large backend repos better. It works inside existing terminal and CI habits, and Opus 5.5 brings a 1M-token context window with 128K output. Antigravity can run Opus 5.5 too on paid plans, but inside Google’s agent harness. Test both on one real refactor and compare accepted pull requests and review minutes per change.