TL;DR
Vision language models are AI models that read an image, such as a photo, scan or chart, together with a text prompt and answer in text or JSON. As of November 2026, the main API options are Google’s Gemini 4 Argon, OpenAI’s GPT-6 and GPT-6.1 models and Anthropic’s Claude 5.5 models. Qwen3.8-27B, Gemma 4, Qwen3-VL and InternVL3.5 are open-weight options released under the Apache 2.0 license. Image resolution sets the token count, so it drives both cost and how well a model reads small print. For high-volume pages, Claude Haiku 5.5 and Gemini 3.8 Flash have the lowest listed prices, while Qwen3.8-27B or Gemma 4 suit self-hosting. Test three candidates on a few hundred of your own labeled images before you commit.
Key Takeaways
- A vision language model joins a vision encoder, a small projector and a language model, so it can answer questions about images in text or JSON.
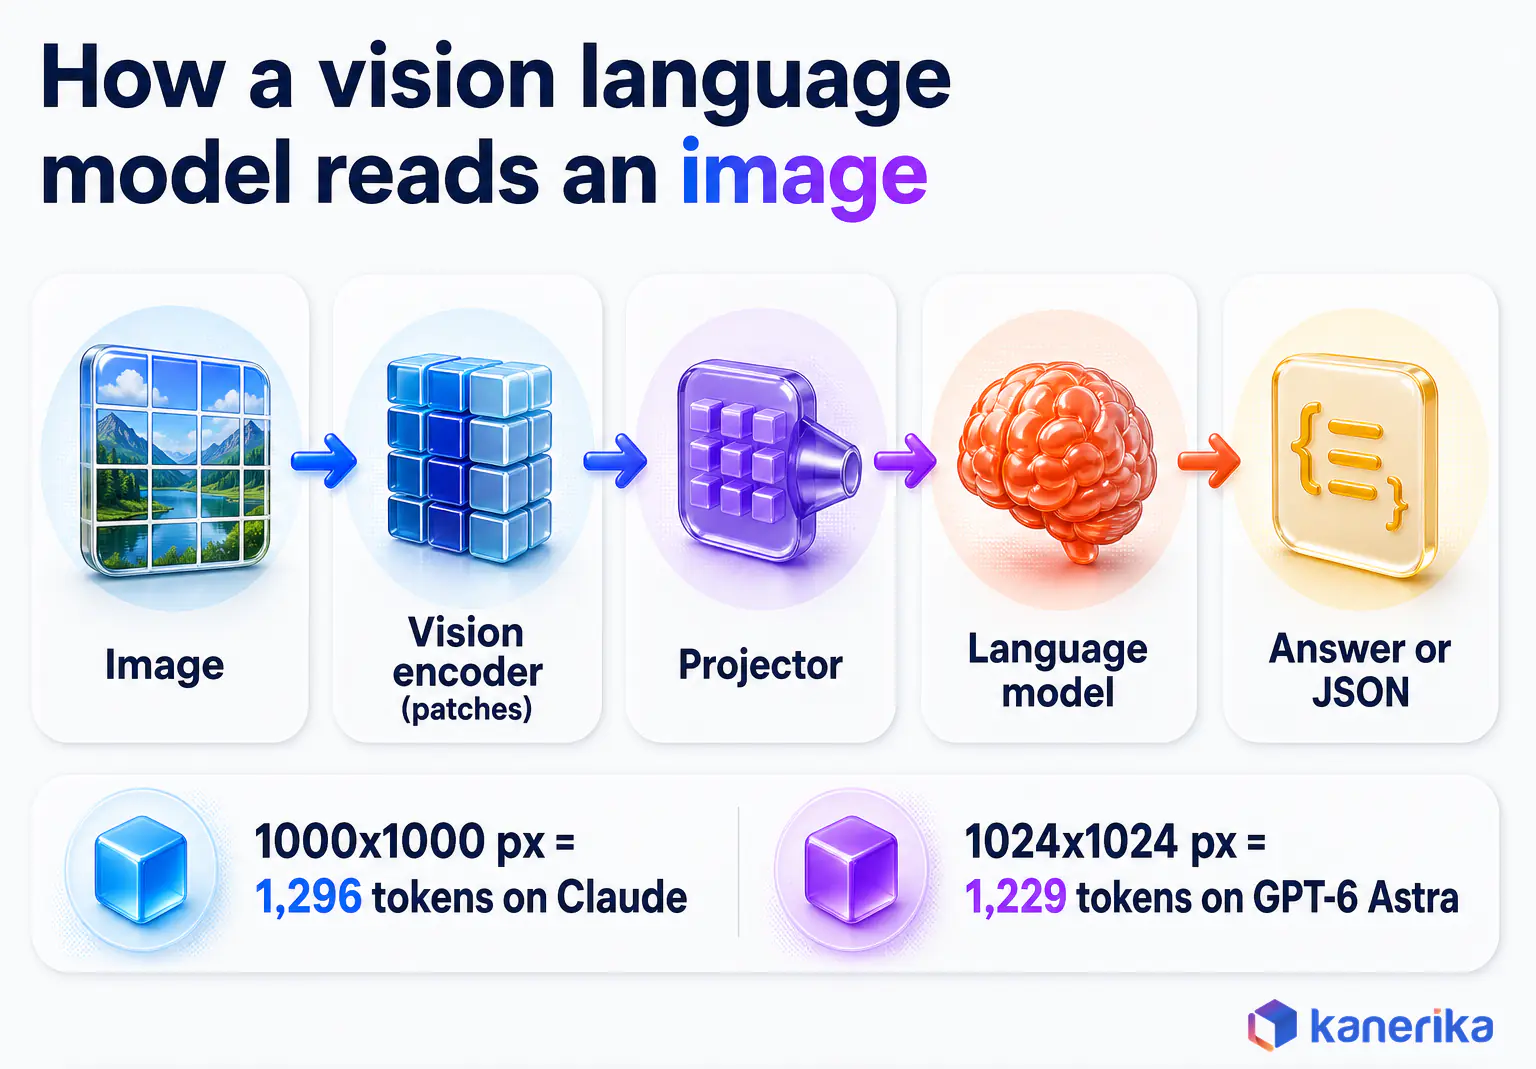
- Image resolution sets the bill: a 1000×1000 px image costs 1,296 tokens on Claude, and a 1024×1024 px image costs 1,229 tokens on GPT-6 Astra at high detail.
- As of November 2026, API choices include Gemini 4 Argon, GPT-6.1 Sol, GPT-6 Astra and the Claude 5.5 family.
- Qwen3.8-27B, Gemma 4, Qwen3-VL and InternVL3.5 ship open weights under Apache 2.0, while Qwen3.8-Max uses a custom license.
- VLMs still misread numbers, small text and damaged scans, so any figure that moves money needs a rule check and a human reviewer.
- Choose a model through a pilot on 300 to 500 of your own labeled items, scored on cost per accepted document.
Can a Vision Language Model Read Your Invoices?
Picture an accounts payable team on the first Monday of the month. By then, the inbox holds supplier PDFs, phone photos of paper invoices and scans with receipts stapled behind them. An OCR tool turns every page into text, but it cannot tell which of six numbers is the amount due.
That gap between reading characters and understanding a page is the job vision language models were built for. They read layout, tables, stamps and handwriting together, then return the fields you asked for. They also make mistakes OCR never makes, so the review design matters as much as the model. For fixed cameras on a production line, see machine vision AI.
What Are Vision Language Models?
Vision language models (VLMs) are AI models that take an image and a text prompt as input and return text or structured output. The image can be a photo, scan, screenshot, chart or PDF page. So you might ask a VLM to list invoice line items or explain a dashboard.
A VLM reads and reasons about images, but it does not create them, because image generation is a different model class. VLMs are one branch of multimodal AI, which covers systems that work across text, images, audio or video. Multimodal models also accept plain text, so one model can serve chat and image tasks.
VLMs vs LLMs vs Computer Vision vs OCR
Teams often ask whether a VLM replaces the tools they already run, such as OCR. Classic AI image recognition models are trained for one narrow task, while a VLM follows new instructions written in plain language.
| Tool | Input | Output | Strength | Weak spot |
|---|---|---|---|---|
| LLM | Text | Text | Reasoning over text | Cannot see images or layout |
| Computer vision model | Images or video | Labels, boxes or masks | Fast on one trained task | Needs retraining for each new task |
| OCR | Scans and images | Raw text with positions | Cheap and exact on clean print | Loses layout, tables and handwriting |
| VLM | Images plus a prompt | Text or JSON | Follows new instructions | Can misread digits or invent content |
How Vision Language Models Work: Encoder, Projector, Language Model
Inside a VLM, three parts pass the image along like runners in a relay. A vision encoder turns pixels into vectors, then a projector converts them for the language model, which writes the answer. Each part shapes the cost, speed and accuracy you see in production.
1. Vision Encoder
The encoder splits an image into small square patches and turns each patch into a vector. Most designs use a vision transformer (ViT), which treats patches the way a text model treats words. As a result, a busy invoice page can become thousands of patch vectors.
Much of this design traces back to CLIP, which OpenAI trained on 400 million image-text pairs and published in 2021. Because of CLIP, encoders learned to place an image and its caption close together in one vector space. Earlier designs such as ViLBERT and DeepMind’s Flamingo now matter mostly as history.
2. Projector
The encoder’s vectors do not match the language model’s format, so a small neural network called a projector maps them into its token space. Think of it as a translator. Each patch vector goes in, and one or a few vectors come out that the language model reads like words. Some models use cross-attention layers instead, which let the language model look at image features directly.
3. Language Model
The language model reads the visual tokens next to your prompt, then writes the answer one token at a time. To the model, a picture is a run of extra input tokens, so a larger image raises the bill but keeps small print readable. A 1920×1080 screenshot, for example, is downsized to 1456×819 on Claude’s standard tier, about 1,560 tokens, so tiny footer text can blur.
How VLMs Are Trained
Training usually happens in three stages, and each one teaches a different skill.
- Contrastive pretraining on image-caption pairs, so the encoder learns which text matches which image.
- Instruction tuning on image, question and answer examples, so the model learns to follow prompts about pictures.
- Optional fine-tuning on your own domain, for example with low-rank adapters (LoRA), a form of parameter-efficient fine-tuning.
Few enterprise teams touch the first two stages, so they start from a trained model and decide later whether the third is worth it.
Vision Language Models in Late 2026: API and Open-Weight Options
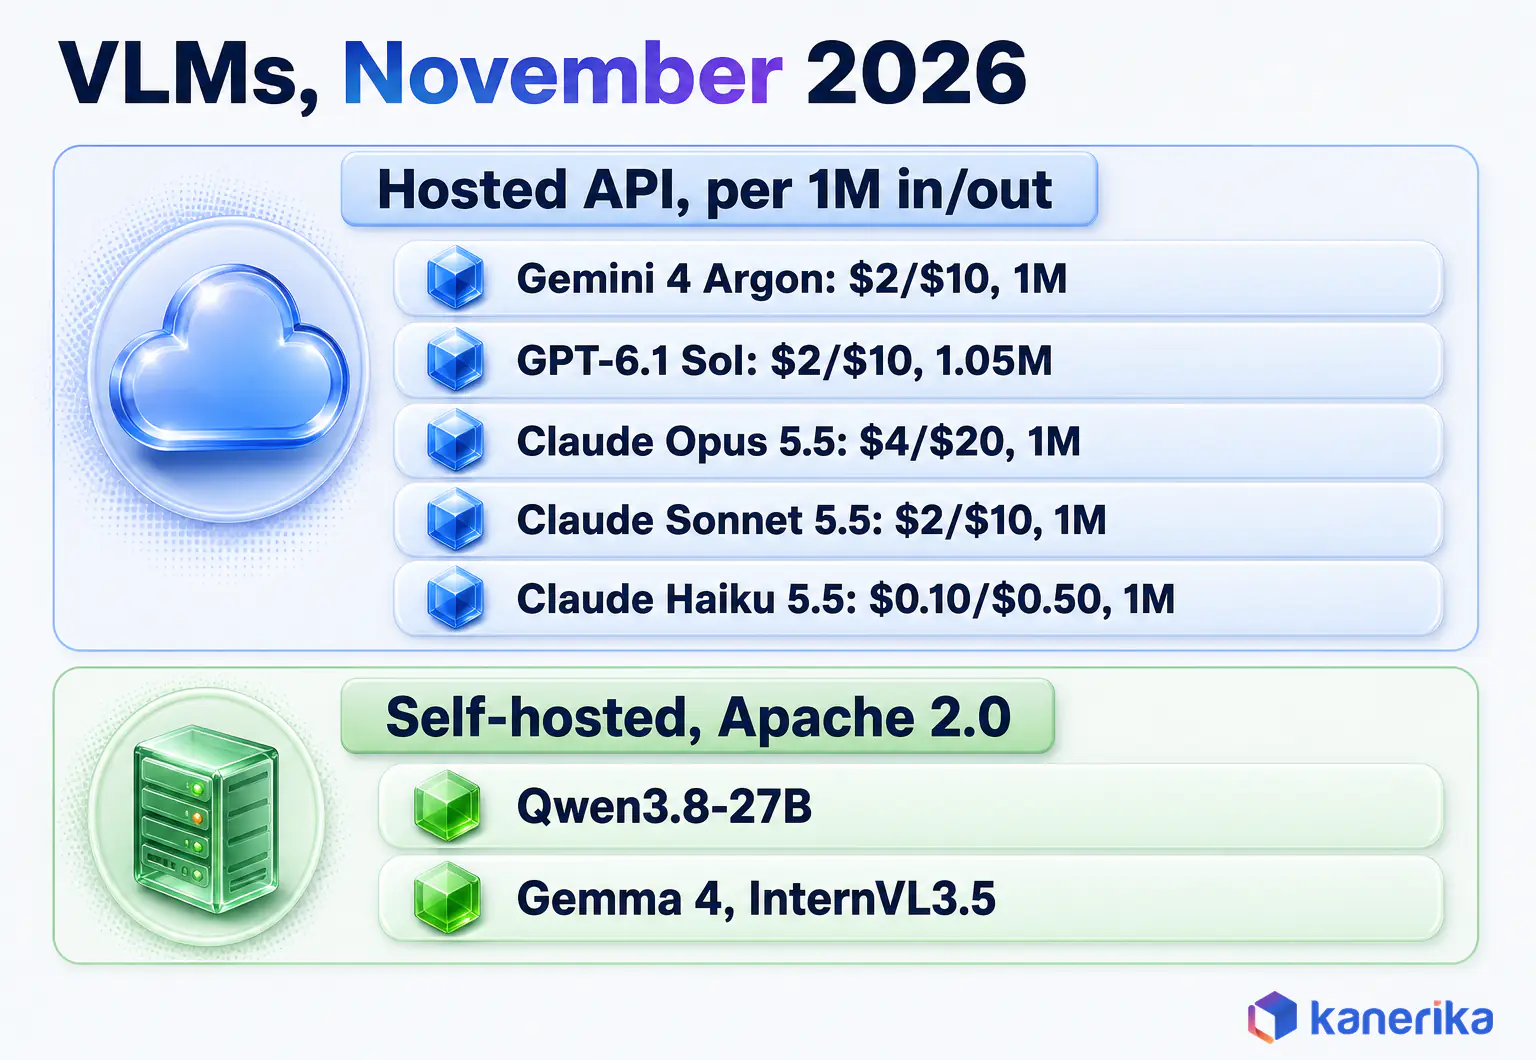
As of November 3, 2026, the main image-input APIs are Gemini 4 Argon, GPT-6.1 Sol and the Claude 5.5 models. The list changes every few months, so treat the table as a snapshot. Because each vendor reports its own benchmarks, no single model wins without a shared test. Price, license and context still narrow the field, and the picks by job below rest on those facts alone. Text-only rankings sit in separate roundups of the top LLMs and open-source LLMs.
Vision language models with image input, as of November 3, 2026 (prices per 1M tokens, input / output)
| Model | API ID or repo | Price or license | Context | Notes |
|---|---|---|---|---|
| Gemini 4 Argon | gemini-4-argon | $2 / $10 through November 30, 2026; $4 / $20 from December 1, 2026 | Up to 1M | Model card published October 13, 2026 |
| Gemini 3.8 Flash | Gemini API | $0.75 / $3.75 through December 31, 2026; then $1.50 / $7.50 | See docs | Lower-cost Google option |
| GPT-6.1 Sol | gpt-6.1-sol | $2 / $10 | 1,050,000 | Published September 29, 2026 |
| GPT-6 Astra | gpt-6-astra | $10 / $50 | 1.05M | Used in OpenAI’s vision guide |
| Claude Opus 5.5 | claude-opus-5-5 | $4 / $20 | 1M | Announced September 22, 2026 |
| Claude Sonnet 5.5 | claude-sonnet-5-5 | $2 / $10 | 1M | Announced September 28, 2026 |
| Claude Haiku 5.5 | claude-haiku-5-5 | $0.10 / $0.50 up to a 100K prompt | 1M | Announced October 7, 2026 |
| Qwen3.8-27B | Qwen/Qwen3.8-27B | Apache 2.0 | 262,144, up to 1M | Dense, image input |
| Qwen3.8-Max | Qwen/Qwen3.8-2.4T-A95B | Custom license | 1M (hosted) | 2.4T total, 95B active |
| Gemma 4 | Google on Hugging Face | Apache 2.0 | See cards | E2B to 31B |
| Qwen3-VL | Qwen on Hugging Face | Apache 2.0 | See cards | 2B to 235B-A22B |
| InternVL3.5 | InternVL on Hugging Face | Apache 2.0 | See cards | 1B to 241B-A28B |
API Models
For image work, three specs decide the bill: price per 1M tokens, context window and the prompt size where a higher rate starts. Gemini 4 Argon (model card published October 13, 2026) lists $2 / $10 per 1M tokens through November 30, 2026, then $4 / $20. Gemini 3.8 Flash is the lower-cost Google choice for high-volume image work, and Google has announced Gemini 4 Carbon without a listed price.
OpenAI’s GPT-6.1 Sol has a 1,050,000-token context, but prompts over 272K tokens cost 2x input and 1.5x output. Assuming about 1,300 tokens per page, as on Claude, that threshold sits near 210 pages, so split larger batches into separate requests. Batch and Flex run 50% lower, so a backlog that can wait costs half as much.
Anthropic’s Claude 5.5 models share a 1M-token context and a 128K output limit, and the Claude vision docs use claude-opus-5-5 in examples. At 1,296 tokens per 1000×1000 px page, a 100K prompt holds about 77 pages, and Haiku 5.5 output costs $2.50 per 1M above it. Keep each request below that page count, because Haiku 5.5 keeps its $0.50 output rate only for prompts up to 100K tokens.
Open-Weight VLMs
Open weights let you run the model on your own GPUs, so images never leave your network. For commercial use, though, the license matters more than any benchmark chart.
- Qwen3.8-27B is a dense Apache 2.0 model tagged image-text-to-text, with a 262,144-token native context.
- Gemma 4 comes in five sizes, and the 31B and 26B-A4B checkpoints are tagged image-text-to-text.
- Qwen3-VL has September and October 2025 checkpoints, as well as January 2026 Embedding and Reranker models for image search.
- Qwen3.8-Max publishes its weights too, but read its custom license before commercial use.
Names such as 26B-A4B list total and active parameters. These are mixture-of-experts models, which run part of the network per token but keep all weights in memory.
Top Picks by Job, as of November 2026
The right model depends on the job, so the picks below sort the same models by what you need them to do. Each row rests only on listed prices, licenses and context limits shown above, not on vendor benchmarks.
| Job | Top picks | Why they fit | Watch for |
|---|---|---|---|
| High-volume pages on a budget | Claude Haiku 5.5, Gemini 3.8 Flash | Lowest listed API prices: $0.10 / $0.50 up to a 100K prompt, and $0.75 / $3.75 | Haiku output costs $2.50 above 100K; Flash rises to $1.50 / $7.50 after December 31, 2026 |
| Long, mixed documents on a hosted API | GPT-6.1 Sol, Claude Sonnet 5.5, Gemini 4 Argon | $2 / $10 each, with 1M context (1.05M on Sol) | Argon moves to $4 / $20 on December 1, 2026; Sol prompts over 272K cost more |
| Self-hosting with a permissive license | Qwen3.8-27B, Gemma 4 | Apache 2.0 open weights; Qwen3.8-27B has a 262,144-token native context | You own the GPUs, capacity and updates |
| Largest open weights | Qwen3.8-Max | 2.4T total and 95B active parameters, 1M context when hosted | Custom license, so read the terms before commercial use |
Within each row, the pilot later in this guide settles which model wins on your own pages. For most document teams, the first two rows hold the starting shortlist.
What Image Inputs Cost: Tokens, Tiles and Cost per Document
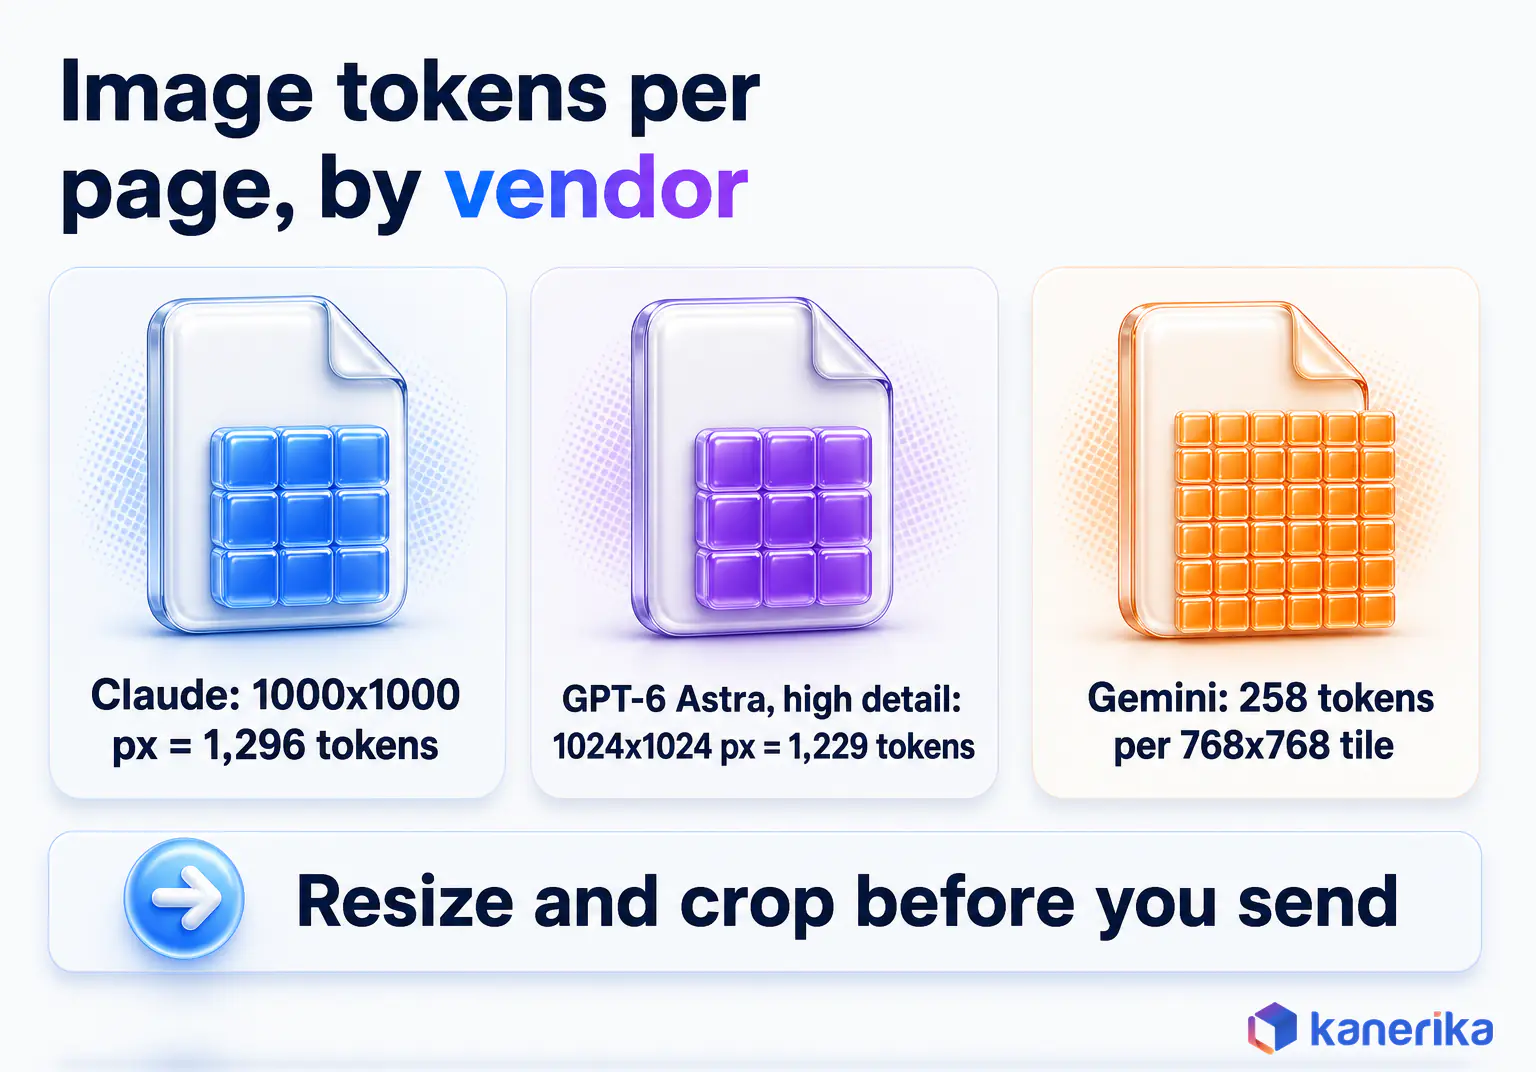
Every image becomes input tokens, and a 1000×1000 px page costs 1,296 of them on Claude. Since each vendor counts them differently, the same page can cost very different amounts.
The rules below come from the Claude vision docs, the OpenAI images and vision guide and the Gemini image understanding docs. OpenAI’s guide adds an image-token calculator for testing your own sizes.
| Vendor | How images are counted | Example from the docs | Limits per request |
|---|---|---|---|
| Claude | By pixel size; large images are downsized | 1000×1000 px = 1,296 tokens; 1920×1080 becomes 1456×819 = 1,560 tokens (2,691 on the high-resolution tier) | 600 images, 128 MB, 8000×8000 px max |
| OpenAI GPT-6 | Patches; detail set to low, high or original | gpt-6-astra, high detail: 1024×1024 = 1,024 patches, billed as 1,229 tokens | 1,500 images, 512 MB, 30,000 patches per image |
| Gemini | 768×768 tiles for larger images | 258 tokens if both sides are 384 px or less; otherwise 258 per tile | 3,600 image files; media_resolution caps tokens |
A Worked Cost Example
Say you send 10,000 single-page invoices a month to Claude Sonnet 5.5 at 1000×1000 px. Then the images alone are 10,000 times 1,296, or 12,960,000 input tokens, which costs about $25.92 at $2 per 1M. Per 1,000 documents, that is about $2.59 of image input on Claude Sonnet 5.5, or about $0.13 on Claude Haiku 5.5 at $0.10 per 1M.
By comparison, the same pages on GPT-6 Astra at high detail come to 12,290,000 tokens, or about $122.90 at $10 per 1M. Prompt text, output and retries then come on top of both numbers.
However, token price is only the start. A cheap model that fails one page in five costs more per finished invoice than a pricier model that gets it right. So track cost per accepted document, meaning all model spend, retries and correction time divided by documents that pass validation.
Resize and crop before you send, because vendors downsize very large images anyway. For small print, crop the region that holds the figure instead of sending the whole page at a higher resolution.
Kanerika Service
Plan a Vision AI Pilot on Your Own Documents
Kanerika scopes your document types, tests candidate models on your files and designs the review flow.
Explore Generative AI ServicesEnterprise Use Cases for Vision Language Models
Strong VLM projects start where people already read images all day, such as invoice desks and inspection lines. Each use case needs a review level set by what happens when the model gets an answer wrong.
| Use case | Typical input | Review level |
|---|---|---|
| Invoice and claims extraction | PDFs, scans, phone photos | Rule checks on every field; human review of exceptions and payments |
| Visual inspection | Line camera photos | Human sign-off on rejects until error rates are proven |
| Retail shelf and catalog work | Shelf and product photos | Sampled review, since errors are cheap |
| Healthcare documents and triage | Referrals, forms, medical images | Clinician review on every output |
| Screen and UI agents | App screenshots | Restricted actions and approval for anything irreversible |
Document Understanding: Invoices, Claims and Forms
Invoices, claims and onboarding forms are the most common starting point, because a VLM can read a two-page table and return JSON. This work sits inside intelligent document processing, where the model is one step between capture and posting.
Document intelligence goes further and lets people ask questions across many documents at once. In insurance, the same reading step feeds AI agents for claims processing that check coverage and route each claim to an adjuster.
Visual Inspection in Manufacturing
On a production line, a camera captures each part, then a model checks for scratches, missing pieces or wrong labels. Classic computer vision still wins on high-speed checks for one defect. A VLM helps when defects vary or when the same pass must read a label, as many AI in manufacturing programs require.
Picture a bracket photo where the model flags a scratch near a mounting hole and reads the part number in the same pass. A false reject scraps a good part, and a missed defect reaches a customer. So people sign off on rejects until the error rates are proven.
Retail: Shelf Images, Catalog Tagging and Visual Search
Retailers use VLMs to compare shelf photos with planograms, write product attributes from catalog images and power search by photo. A shelf photo might come back as “3 facings of SKU A, 0 of SKU B”, and that gap becomes a restocking task for the store team.
If the count is off by one, a worker spots it on the next aisle walk, so sampled review is enough. The same photos feed wider computer vision in retail work on the store floor.
Healthcare: Documents and Image Triage
In healthcare, VLMs read referral letters and intake forms, and they sort images into queues for a clinician. A referral letter might come back as JSON with the requested specialty, and one misread field can send the patient to the wrong queue.
VLMs should not make diagnostic calls on their own, so every output that touches patient care needs clinician review. That rule matches the safeguards described in generative AI for healthcare.
Screens and Visual Agents
A newer use case points the model at a screen instead of a document. The model reads a screenshot, picks a button and then hands that action to automation code. So these multimodal AI agents that act on what they see need tight limits on what they may click.
For search over image-heavy manuals and slide decks, multimodal RAG pairs a VLM with retrieval, one of many multimodal AI applications built on the same reading step.
VLM vs OCR: When to Use Which
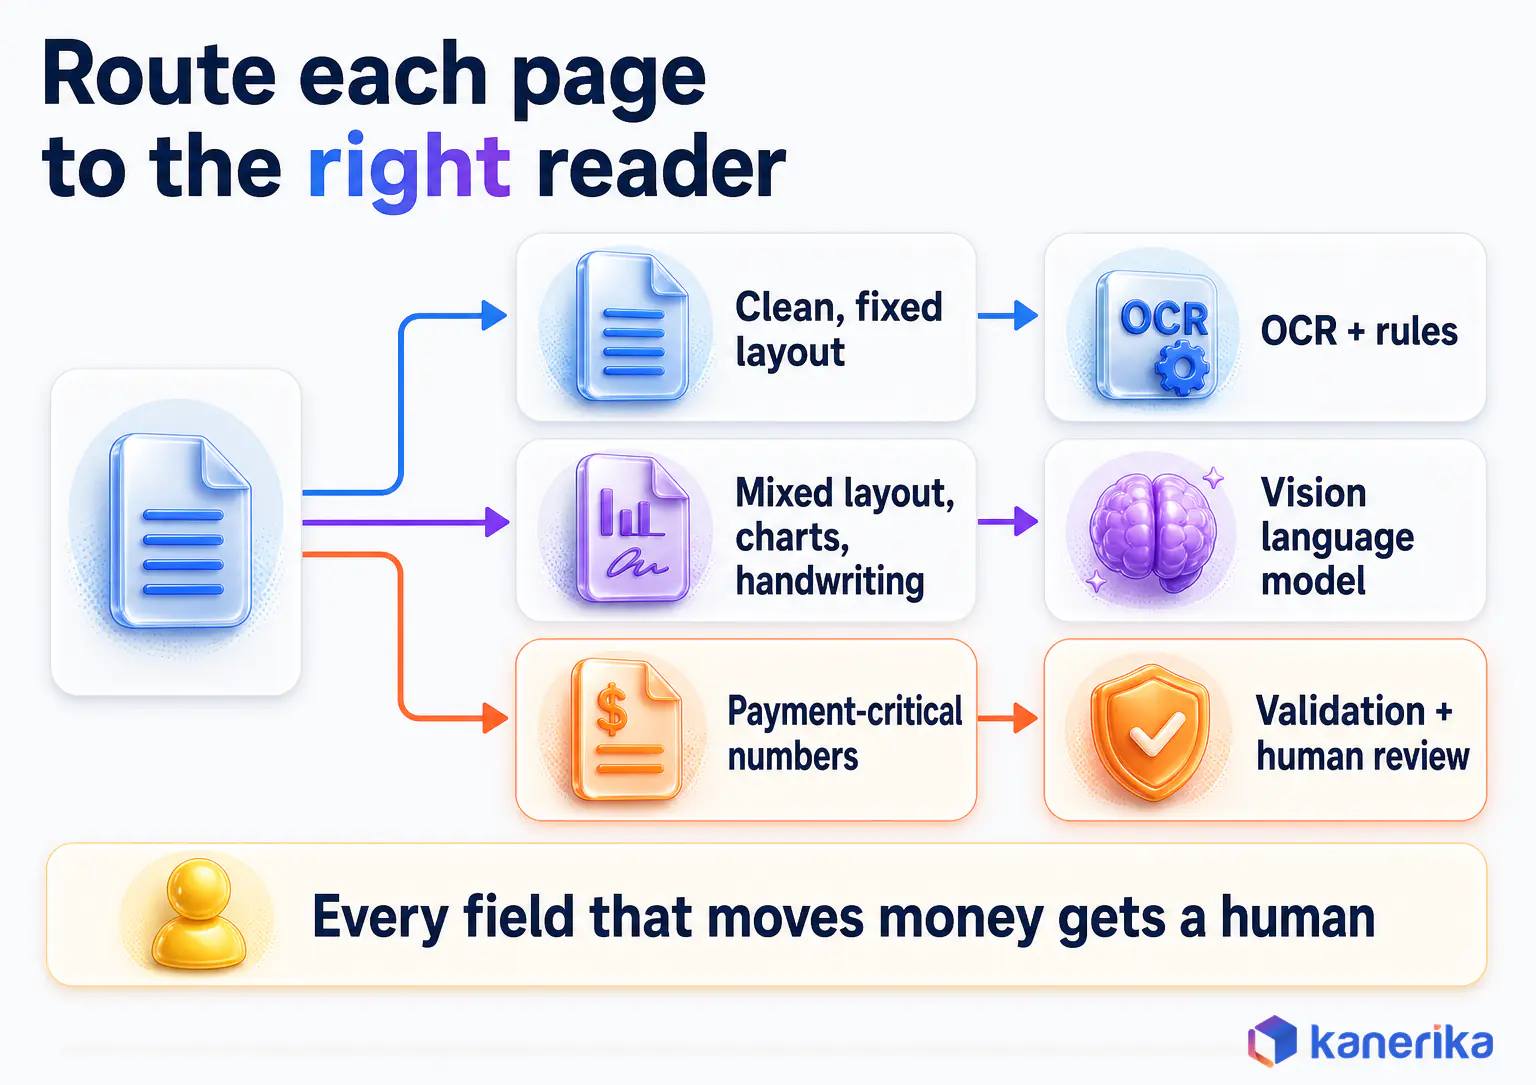
OCR and VLMs solve different halves of the document problem. OCR is cheap and exact on clean print, while a VLM understands layout and handwriting but can misread a digit. So for most document work, the answer is a hybrid that routes each page to the right reader.
A simple routing rule works for most teams.
- Clean, fixed-layout pages, such as a standard form from one supplier, go to OCR plus template rules.
- Mixed layouts, charts, stamps and handwritten notes go to a VLM instead.
- Any figure that triggers a payment goes through validation rules and a human reviewer, whichever reader produced it.
Routing cuts cost, too. When most pages are clean, sending only the messy ones to a VLM keeps the token bill small.
OCR output can travel with the image as extra context. On dense pages, that text gives the VLM a second source to check its reading against.
Where Vision Language Models Fail
VLMs fail most on numbers, small text, counts, exact positions and damaged scans, and they fail confidently. That makes their errors harder to spot than garbled OCR text. Knowing the common failure types tells you where to put checks.
- Numbers and small text, where a 7 read as a 1 changes an invoice total.
- Counting items in a crowded photo or rows in a long table.
- Exact positions, such as pixel coordinates or precise bounding boxes.
- Damaged or low-resolution scans, where folds, stamps and faint faxes push the model toward guessing.
- Content that is not there, such as a PO number filled in for a blank field.
An ACL 2026 Findings paper on perceptual hallucination built the DocHallu benchmark from 2,671 pairs of original and damaged document images. Hallucination appeared in every model tested, and it was higher for numbers than for text. On its key information extraction task, which removes the answer region from receipts and ID cards, the hallucination rate reached 61.0% for numerical answers.
Three habits reduce the damage. To begin with, crop and upscale the region that holds the figure you need. Then tell the model to answer “not visible” instead of guessing, a basic guard against LLM hallucination. Finally, check that line items add up to the total.
Security, Privacy and Visual Prompt Injection
Images can carry instructions as well as data. The OWASP entry on prompt injection (LLM01) names instructions hidden in an image next to harmless text as a multimodal injection risk. For example, a scanned letter with hidden text could tell a model to ignore its rules.
- Treat any text the model reads from an image as untrusted data, kept apart from system instructions.
- Restrict what a screen agent may do, and require approval for payments, deletions and messages.
- Mask personal data in scans before they reach a hosted API, and check where the vendor stores images. Claude, for example, refuses to name people in images, but a scan can still expose names and account numbers.
- Read open-weight licenses before commercial use, since Qwen3.8-Max ships under a custom license.
The LLM security guide goes deeper on prompt injection, while written AI governance policies decide who may send which images to which model. When you need outside help, AI governance services can set up the reviews behind them.
How to Evaluate a Vision Language Model on Your Own Data
Benchmarks tell you which models are worth testing, but only your own images tell you which one to choose. A short, structured pilot settles the question with evidence instead of opinion.
What Public Benchmarks Tell You
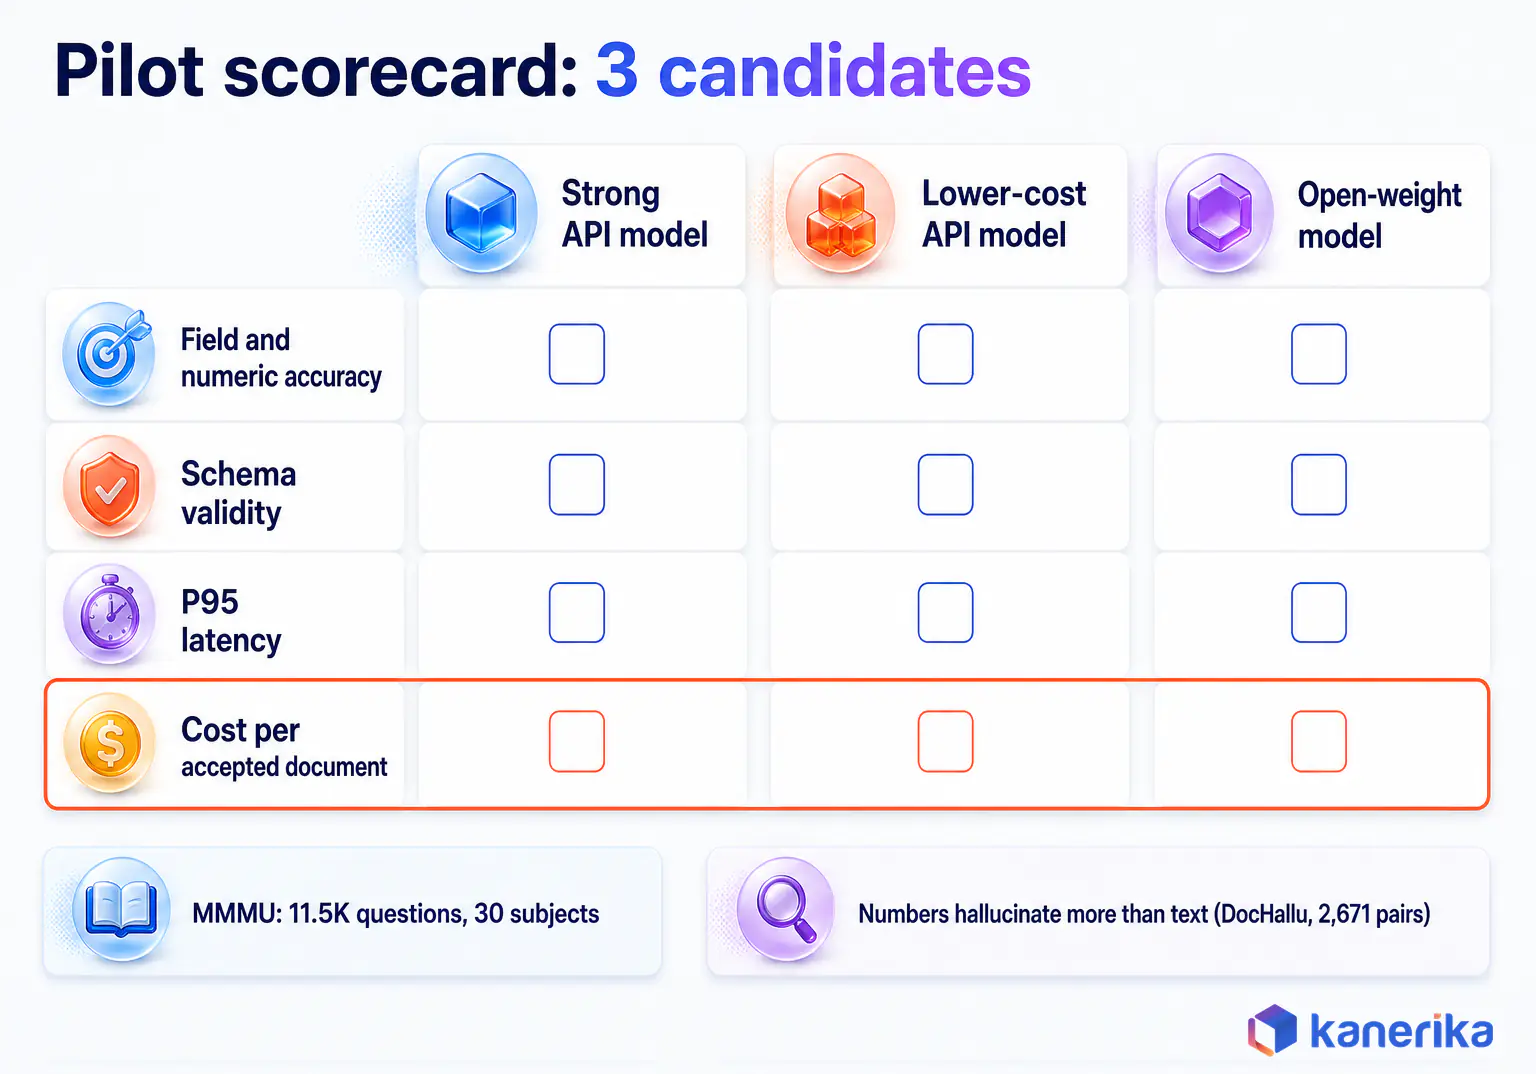
The best-known VLM benchmark is MMMU, with 11.5K college-level multimodal questions across 6 disciplines, 30 subjects and 183 subfields. MMMU-Pro is a harder follow-up. A high score shows broad visual reasoning, but it says little about a faded invoice from your largest supplier.
A Three-Step Pilot
- Define the work: document types, monthly volumes and an acceptance target for each field, such as invoice total.
- Then test one strong API model, one lower-cost API model and one open-weight model on the same 300 to 500 labeled items, with the same prompts and resolution.
- Finally, decide on field-level accuracy, valid schema output, P95 latency and cost per accepted document.
The 300 to 500 range is practitioner guidance, large enough to show error patterns and small enough to label by hand. Keep prompts and scoring under version control so the test can rerun when a new model ships. An LLM evaluation framework gives that work a repeatable structure.
Deploying VLMs: API, Self-Hosted or Fine-Tuned
After the pilot, a VLM runs in one of three ways: through a hosted API, as self-hosted open weights or as a fine-tuned model. A hosted API gives you current vendor models with no GPUs to manage, but you accept vendor price changes and retirements. Running open weights as private LLMs keeps images in your network, while you own capacity and updates.
For self-hosting, vLLM serves multimodal requests, including image_url inputs through an OpenAI-compatible API. As a result, code written for a hosted API can often point at your own server. Which engine to run depends on the workload, a trade-off the vLLM vs Ollama comparison walks through.
Fine-tune last, because better prompts, cropping and OCR hints often close most of the gap. When those gains stop, a small adapter can help, and weighing RAG vs fine-tuning shows when retrieval is the better fix.
Checklist
Generative AI Checklist
Check data, security, governance and evaluation before a model reads production documents.
Get the Checklist →Vision Language Model Selection Checklist
Run through this list before you sign a contract or commit GPU budget.
- Input types, such as photos, scans, screenshots or charts.
- Accuracy target per field, with money-moving fields marked.
- Data residency: whether images may leave your network or region.
- License, such as Apache 2.0, custom or commercial API terms.
- Image volume and token budget, priced with each vendor’s image rule.
- Latency: the P95 response time your workflow accepts.
- Resolution handling: how the model downsizes, tiles or patches images before reading them.
- Structured output: JSON schema support, so results load straight into your systems.
- Review workflow: who checks exceptions, and how fast.
- Retirement and price-change plan. The gpt-4o-2024-05-13 snapshot retired on October 23, 2026, other GPT-4o and GPT-4.1 snapshots retire on January 14, 2027, and Argon prices rise on December 1, 2026.
How Kanerika Builds Vision Language Model Pipelines for Documents
Kanerika treats model reading as one controlled step inside a document pipeline. FLIP AI invoice processing automates invoice capture, extraction and reconciliation. KlarityIQ, Kanerika’s document intelligence agent, answers questions over documents, spreadsheets and videos with role-based access.
Datasheet
KlarityIQ: Your Document Intelligence Agent
See what KlarityIQ reads, how it answers questions and how role-based access works.
View the Datasheet →Through Kanerika’s generative AI services, each project moves through five stages, and the model is chosen only after the first two.
- Document and image audit: formats, scan quality and volumes.
- Routing design: OCR for clean pages and model reading for mixed layouts.
- Extraction to a fixed schema, with validation rules on every field.
- A human review queue for exceptions and payment-critical values.
- Lifecycle tracking, with dashboards and monitoring of model versions.
Applied to a VLM pilot, stages 1 and 2 fix the scope: which document types go to the model and what accuracy each field needs. Model choice comes next, with three candidates tested on the same 300 to 500 labeled documents as in the pilot above. Stages 3 to 5 then turn the winning model into a production step.
Case Study: Invoice Processing With FLIP
In one engagement, a global corporate travel management company handled 4,000 to 5,000 invoices per region across three regions. The invoices arrived as PDF and Excel files, together with vouchers, receipts and bank confirmations. Kanerika then automated extraction and reconciliation with OCR and LLM models on FLIP.
The invoice processing case study reports a 75% reduction in manual effort and about 90% data extraction accuracy. Invoice processing ran 55% faster, and exceptions were resolved 30 to 40% faster. Read together, the figures show the value came from less manual handling and faster exception work, with accuracy at about 90%, not 100%.
That project paired OCR with LLM models, not a vision language model. Under the routing rule in the VLM vs OCR section, a VLM would take the scanned, stamped or handwritten pages that OCR misreads. The same five stages apply when a vision language model joins the pipeline, because the review queue keeps model errors away from payments.
Validation rules and the review queue are where accuracy numbers come from. Every corrected field becomes labeled data for the next model test, so the pipeline gets easier to evaluate over time.
Case Study
75% Less Manual Effort in Invoice Processing With FLIP
A travel management company automated mixed-format invoice extraction and reconciliation at about 90% accuracy.
Read the Case Study →Bottom Line: Which Vision Language Models to Pick in 2026
The best vision language models for 2026 come down to one pick per job. For high-volume pages, choose Claude Haiku 5.5 at $0.10 / $0.50 per 1M tokens up to a 100K prompt, with a 1M context. For long, mixed documents on a hosted API, choose GPT-6.1 Sol at $2 / $10 with a 1,050,000-token context.
When images must stay in your network, choose Qwen3.8-27B, an Apache 2.0 open-weight model with a 262,144-token native context. Qwen3.8-Max has the largest open weights, at 2.4T total parameters, but read its custom license first. Run that pick through a pilot on your own pages, and the lowest cost per accepted document confirms your top pick for 2026.
Frequently Asked Questions
What is a vision language model (VLM)?
A vision language model is an AI model that takes an image and a text prompt as input and returns text or structured output. The image can be a photo, a scan, a screenshot or a chart. VLMs read and reason about images. They do not generate images, because that is the job of a different model class.
What is the difference between a VLM and an LLM?
A large language model works only with text. A vision language model adds a vision encoder and a projector, so it can also read images. The language model inside a VLM still writes the answer. Most current flagship models, including the GPT-6 and Claude 5.5 families, accept both text and images through one API.
What are the best vision language models in 2026?
Pick by job, not benchmark. For high-volume pages, Claude Haiku 5.5 and Gemini 3.8 Flash have the lowest listed prices. GPT-6.1 Sol, Claude Sonnet 5.5 and Gemini 4 Argon cost $2 / $10 per 1M tokens, though Argon doubles on December 1, 2026. For self-hosting, Qwen3.8-27B and Gemma 4 use Apache 2.0. A pilot on your images picks the winner.
Are there open-source vision language models for commercial use?
Yes. Qwen3.8-27B, Gemma 4, Qwen3-VL and InternVL3.5 publish open weights under Apache 2.0, which generally permits commercial use. Qwen3.8-Max uses a custom license, so read its terms before you deploy it. Always check the license on the exact model card you download, since terms can differ between checkpoints and families.
How much does it cost to run a vision language model?
Cost depends on image tokens and the price per token. A 1000×1000 px image is 1,296 tokens on Claude, so 10,000 such pages on Claude Sonnet 5.5 cost about $25.92 in image input. Output tokens, retries and review time come on top. Measure cost per accepted document to see the real figure.
Do vision language models hallucinate, and how do you control it?
Yes. An ACL 2026 Findings paper found hallucination in every model it tested on damaged document images, and it was higher for numbers than for text. To control it, crop and upscale the region you need. Ask for “not visible” instead of a guess, check totals against line items and route money-moving fields to human review.
How do vision language models work?
A vision encoder splits the image into patches and turns each patch into a vector. A projector maps those vectors into the language model’s token space. The language model then reads the visual tokens next to your prompt and writes the answer. Higher image resolution creates more tokens, which raises cost and improves small-text reading.
What are the main applications of vision language models?
The most common use is document understanding, such as invoices, claims and forms. Other uses include visual inspection in manufacturing, shelf and catalog work in retail, and healthcare paperwork with clinician review. Newer agents read screenshots to operate software. Each use case needs a review level that matches the cost of a wrong answer.
What role do VLMs play in generative AI?
VLMs are the part of generative AI that understands images. They generate text, summaries or structured data from what they see. That lets generative AI systems answer questions about charts, extract fields from scans and describe photos. Image creation is handled by other model types, such as diffusion models, and sits outside what VLMs do.
Is ChatGPT a vision language model?
ChatGPT is an app built on OpenAI’s GPT models. The GPT-6 family accepts image input, and OpenAI’s vision guide uses gpt-6-astra in its examples. So when you upload a photo or screenshot to ChatGPT, it works as a vision language model. With text alone, it behaves like a standard large language model.
Is CLIP considered a vision language model?
CLIP is a contrastive image-text model that OpenAI published in 2021. It was trained on 400 million image-text pairs to match images with captions. It does not write free-form answers, so it is usually called a vision-language encoder rather than a full VLM. Many modern VLMs build on the idea that CLIP introduced.
What is visual language theory?
Visual language theory is a concept from communication and design. It studies how images, shapes, color and layout carry meaning, much like words in a sentence. It is separate from vision language models, which are AI systems. The overlap is loose, since both deal with how people and machines read meaning from visual material.
How are VLMs trained for multimodal understanding?
Training usually runs in three stages. Contrastive pretraining on image-caption pairs teaches the encoder which text matches which image. Instruction tuning on image, question and answer examples teaches the model to follow prompts about pictures. Teams can then fine-tune on their own data, often with low-rank adapters that train a small set of extra weights.
Can vision language models replace OCR?
Not fully, and most document teams use both. OCR is cheap and exact on clean printed text. A VLM handles mixed layouts, charts and handwriting, but it can misread digits. A common rule sends clean pages to OCR, messy pages to a VLM, and any payment-critical figure to validation and human review.