TL;DR
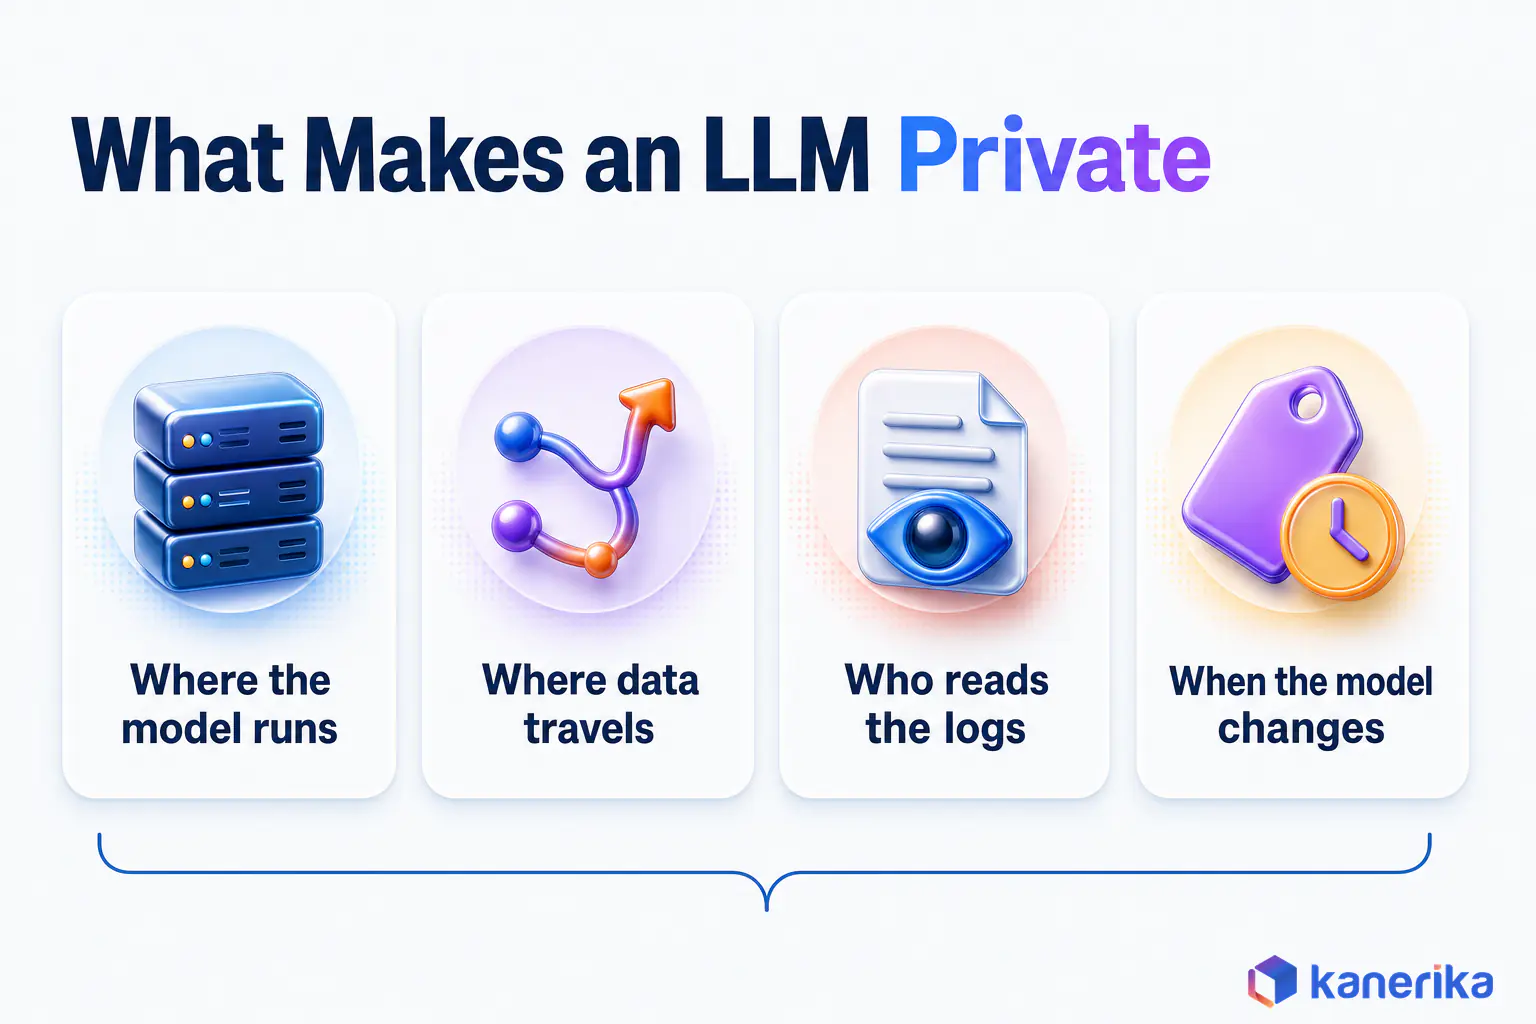
Private LLMs are AI language models that run under your control instead of a vendor’s default settings. You decide where the model runs, where your data goes, who can read the logs and when the model changes. That can be a model you host yourself or a managed service reached over a private network.
Adopt one when sensitive data, audit rules or steady heavy use make a public chatbot a poor fit. Skip it when your data is public, your usage is light or no team can run it. Before you adopt, check your data, pick a setup for each workload, read the model licence, price the full cost and plan governance.
Key Takeaways
- A private LLM rests on four controls: where the weights run, where data travels, who reads the logs and when the version changes.
- Self-hosted open-weight models and managed APIs over private networking can both be private, although effort and cost differ.
- The strongest reasons to go private are confidential data, residency and audit duties, version stability and steady high volume, especially in regulated sectors.
- Self-hosting trades per-token fees for fixed capacity and staff, so it pays only when usage is steady and large.
- Privacy is not security: access control at retrieval, prompt-injection defences, logging and evaluation remain your job.
- Adopt when data, obligations and volume justify owning the controls; otherwise start with the lightest private option, a managed model over private networking.
The Pilot That Stalled at Security Review
Picture a contracts team at a mid-sized insurer that finds a shortcut. Analysts paste supplier agreements into a public chatbot and ask it for renewal dates, liability caps and termination clauses. The summaries are good, and within a month the team wants the whole procurement group to work the same way.
The request then reaches the security office, which asks four plain questions. Where are the prompts stored, and for how long? Who at the vendor can read the conversation logs? Could this text end up in someone else’s model? Which model version wrote last Tuesday’s summary, and will the same question get the same answer next quarter?
Nobody on the team can answer, so the pilot stops and the contracts go back to manual review.
Private LLMs exist so that an organization can answer each of those questions with a simple “we decide”. This guide explains what a private LLM is, which deployment options qualify, what one costs and what to check before you adopt.
What Is a Private LLM?
A private LLM is a large language model deployment in which your organization, not a vendor’s default settings, controls the full path of every request. The model may come from Meta, OpenAI, Mistral or Google, and it may run in your data center or in a cloud account. Privacy comes from your control over where the model runs, where prompts and outputs go, who reads the logs and when the model changes.
Compare that with what happens when you type a question into a consumer chatbot. The provider picks the data center, writes the retention policy, decides whether conversations help train future models and can swap the underlying model overnight. For a recipe question none of that matters, but for a draft merger agreement all of it does.
The definition matters because vendors often sell “private” as a feature. It works better as a property of the deployment, because a property can be tested. If you are still picking a model family, our guide to choosing an enterprise LLM covers vendor selection. This article, by contrast, stays on the privacy boundary.
The Four Control Points That Make an LLM Private
A practical test is to ask who controls four points in the request path. When your organization controls all four, the deployment is private in a meaningful sense. When a vendor controls any of them by default, you have a dependency that a contract has to manage.
- Weights location: where the model files sit and run, such as your servers, your cloud tenancy or a provider’s shared fleet.
- Data path: which networks, regions and services a prompt crosses before it reaches the model and returns, including any document store it touches.
- Log access: who can read prompts, completions and traces, how long they are kept, and whether anyone outside your organization can see them.
- Version control: whether you decide when the model changes, or the provider updates it on its own schedule.
None of the four is about model quality or size. A small open-weight model run carelessly can fail all four tests. Meanwhile, a large managed model behind a private endpoint can pass most of them.
Private LLM vs Public LLM vs Enterprise-Managed LLM
Most buyers end up comparing three arrangements rather than two. The middle one, an enterprise API with contractual data terms, is where many organizations start. It removes the hardware work and also closes several gaps left by a consumer tool.
| Factor | Public chatbot | Enterprise-managed API (Azure, Bedrock) | Self-hosted private LLM |
|---|
| Data path | Public internet to the provider’s shared service | Your cloud tenancy, with optional private networking | Your network end to end |
| Use of your data for training | Set by consumer terms and account settings | Not used to train foundation models under the published Azure and Bedrock terms | Your decision alone |
| Residency | Provider’s choice | Stored in your geography; processing location depends on deployment type | Wherever you host it |
| Version pinning | Provider updates the model whenever it chooses | You choose among versions the provider offers, on its lifecycle | Full control |
| Operations burden | None | Low to moderate | High: GPUs, serving, patching, monitoring |
| Cost shape | Per seat or free | Per token | Fixed capacity plus staff, so idle time still costs |
The enterprise-managed column deserves a closer look, because its privacy comes from contract terms rather than from hardware you own. Microsoft’s Azure data privacy documentation says prompts and completions sent to models sold by Azure in Foundry are not available to other customers or OpenAI. They are also not used to train foundation models without permission. Amazon says model providers have no access to Bedrock logs or to customer prompts and completions, per the Bedrock data protection guide. So those terms close the training and log-access gaps, but they still do not give you the weights.
Private Does Not Mean Secure or Compliant
Moving a model inside your network removes one class of risk, the vendor seeing your data, and leaves every other class in place. An internal assistant can still show a junior employee a board paper if retrieval ignores document permissions. A hidden instruction in an uploaded file can still redirect the model, and logs full of customer records can still sit unencrypted for years.
Regulators and auditors look at the whole system rather than the hosting choice. A private deployment gives you the levers for access control, logging, prompt-injection defences and records retention, yet someone still has to pull them. That is why Kanerika’s LLM development work treats governance as part of the build rather than a later review. The governance section further down lists the controls to have in place before production.
Kanerika Service
Private LLM Development
Kanerika designs and builds private LLM systems, from the deployment choice and model serving to retrieval with access control, evaluation and monitoring.
Explore LLM Development
Why Enterprises Adopt Private LLMs
Enterprises go private when a specific constraint blocks a public tool, and that constraint usually falls into one of four groups. Naming it early also points to the right deployment option, since each option solves a different problem.
Sensitive Data and Intellectual Property
The most common driver is the data itself, especially when it is regulated or secret. Contracts, source code, product designs, patient notes and customer records are exactly where an LLM saves the most time. They are also exactly what legal teams least want leaving the building.
Consider, for example, an engineering group that wants an assistant to explain a legacy codebase. The value is obvious, but the code is the company’s core asset. A self-hosted model, or a managed model with no training use, lets the team use the assistant without debating every file it reads.
Residency, Contracts and Audit
Regulation turns data location and traceability into hard requirements. The EU AI Act sets the clearest dated obligations for teams that build and document LLM systems. For that reason it is worth knowing the dates, and the European Commission’s AI Act Service Desk timeline lists the milestones.
- Entry into force: 1 August 2024.
- Prohibitions and AI literacy duties: applied from 2 February 2025.
- General-purpose AI model obligations: applied from 2 August 2025.
- Most remaining rules, including Article 50 transparency duties: applied from 2 August 2026.
- High-risk rules for Annex III and Annex I systems: 2 December 2027 and 2 August 2028, as amended by the Digital Omnibus on AI.
Healthcare also adds its own layer. HHS guidance on cloud computing treats a cloud provider that handles electronic protected health information as a business associate. That relationship calls for a business associate agreement. A private deployment does not remove that duty, even though it narrows who touches the data. Still, it does make the chain of custody shorter and easier to document for an auditor.
Control Over Model Behavior and Versions
A model that changes without notice causes trouble in any regulated review. Suppose a credit memo or claims decision was drafted with model help. An auditor may then ask you to reproduce that output months later, which is only possible when you know which version ran.
Private hosting lets you pin a version, test a newer one against your own evaluation set and then switch on your own schedule. Managed APIs allow similar discipline, although you work within the provider’s version lifecycle rather than yours.
Predictable Cost at Steady, High Volume
Per-token pricing is efficient when usage is light or unpredictable, because you pay nothing when nobody asks a question. At steady, high volume the picture can flip. For example, a document pipeline that runs every night at the same load can keep a fixed block of GPUs busy. Busy fixed capacity can then cost less per answer than metered calls. The cost section below shows how to test that for your own workload.
How a Private LLM Works
A private LLM works like any LLM application with one difference: every hop stays on infrastructure you control or have contracted for. Following a single question through the system shows where the control points sit and where data could escape. For the model internals behind that path, see our explainer on LLM architecture.
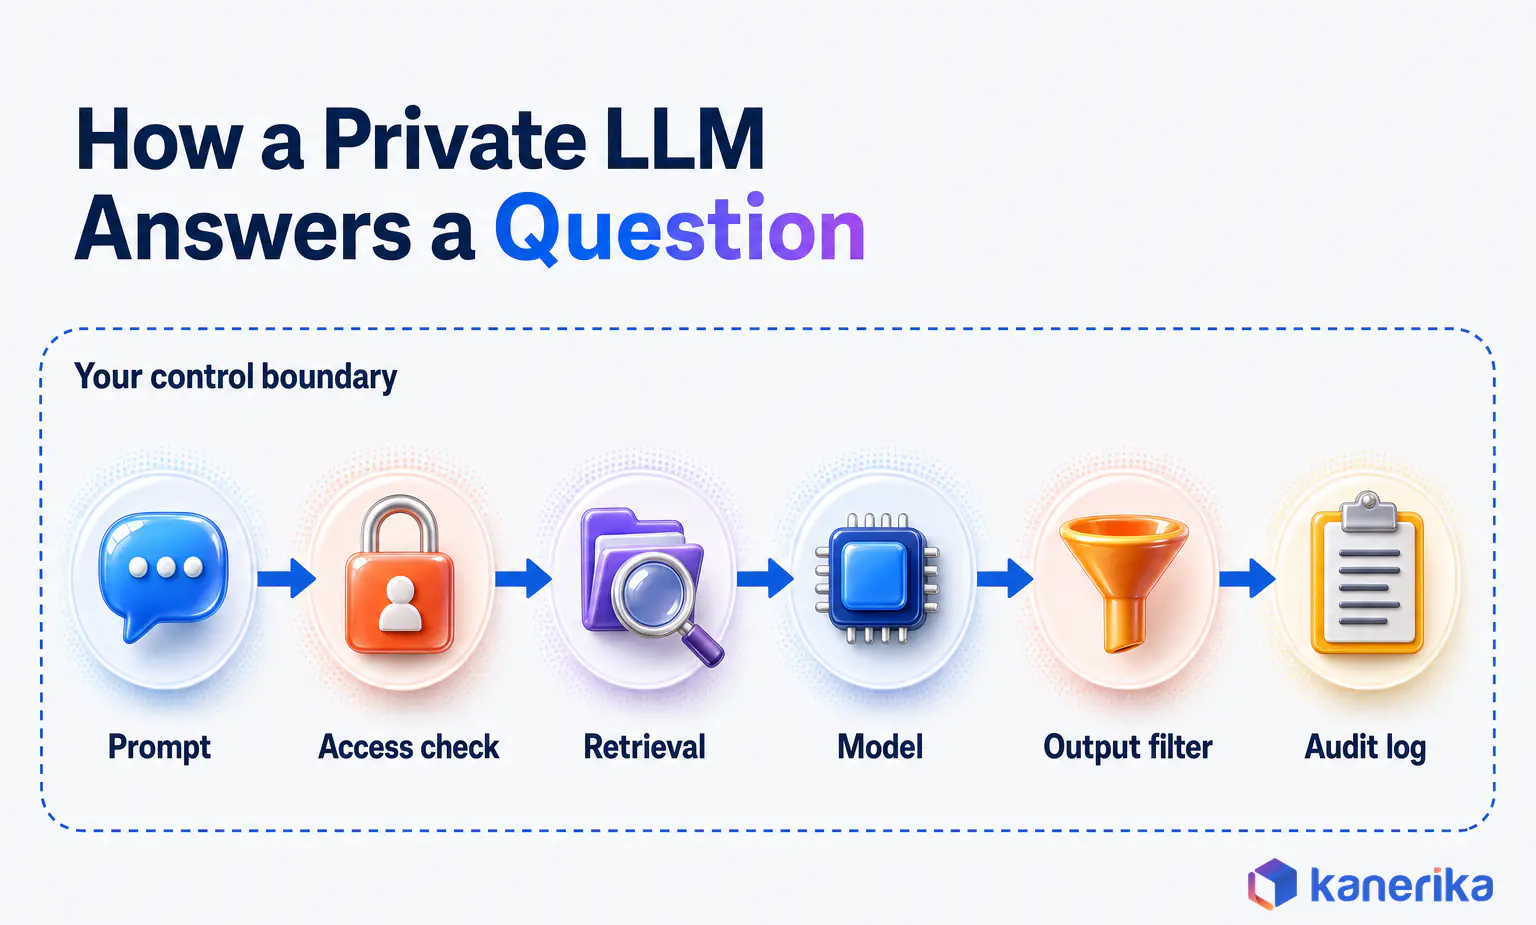
Take a finance employee who asks for the payment terms in the latest agreement with Supplier X. The question passes through an identity check, a retrieval step that searches approved documents, the model itself, an output filter and a logging layer. Each step either respects that employee’s permissions or quietly ignores them, so the design decides which.
What Happens to Your Data During Inference
Inference is the moment when the model reads a prompt and writes an answer. In a private setup the sequence usually runs in five steps, and each one carries its own leak risk.
- Prompt intake: the question arrives through an authenticated app, so the leak risk is an open endpoint or a browser plugin that copies text elsewhere.
- Retrieval: the system searches internal documents or tables for context, so the risk is returning documents the user is not allowed to open.
- Inference: the model processes prompt and context in memory on your GPUs or contracted endpoint, so the risk is shared hosts without isolation or debug dumps.
- Output filtering: rules check the answer for personal data, secrets or policy breaches, so the risk is having no filter at all.
- Logging: prompts, sources and answers are recorded for audit and evaluation, so the risk is logs kept longer than policy allows or read by too many people.
The retrieval and logging steps cause most real incidents, because they handle the most data with the least scrutiny. A model that never stores anything can still leak through an index that ignores permissions.
Where RAG and Fine-Tuning Fit
Most private deployments need the model to know company facts it never saw during training. There are two ways to add that knowledge, but they solve different problems. Our comparison of RAG vs fine-tuning covers the full trade-off, and the short version for a privacy design follows.
| Approach | What it changes | Privacy effect | Use when |
|---|
| Retrieval-augmented generation (RAG) | What the model can look up at question time | Knowledge stays in your stores, where per-user access rules can still apply | Facts change often, or when access differs by role |
| Fine-tuning | How the model writes and behaves | Training data is absorbed into the weights, so per-user access control is no longer possible | When you need a consistent format, tone or domain vocabulary |
For most enterprise knowledge, retrieval-augmented generation is the safer default, because a document removed from the index stops appearing in answers the same day. Fine-tuning still earns its place for style and task skills. It is a form of model training, and our explainer on how LLM training works walks through the process. Kanerika’s RAG development practice starts from the access model, not the model choice.
Datasheet
KlarityIQ: Your Document Intelligence Agent
Product specs for KlarityIQ, Kanerika’s agent for finding and extracting answers from enterprise documents, the retrieval layer a private LLM project depends on.
View the Datasheet →
Private LLM Deployment Options
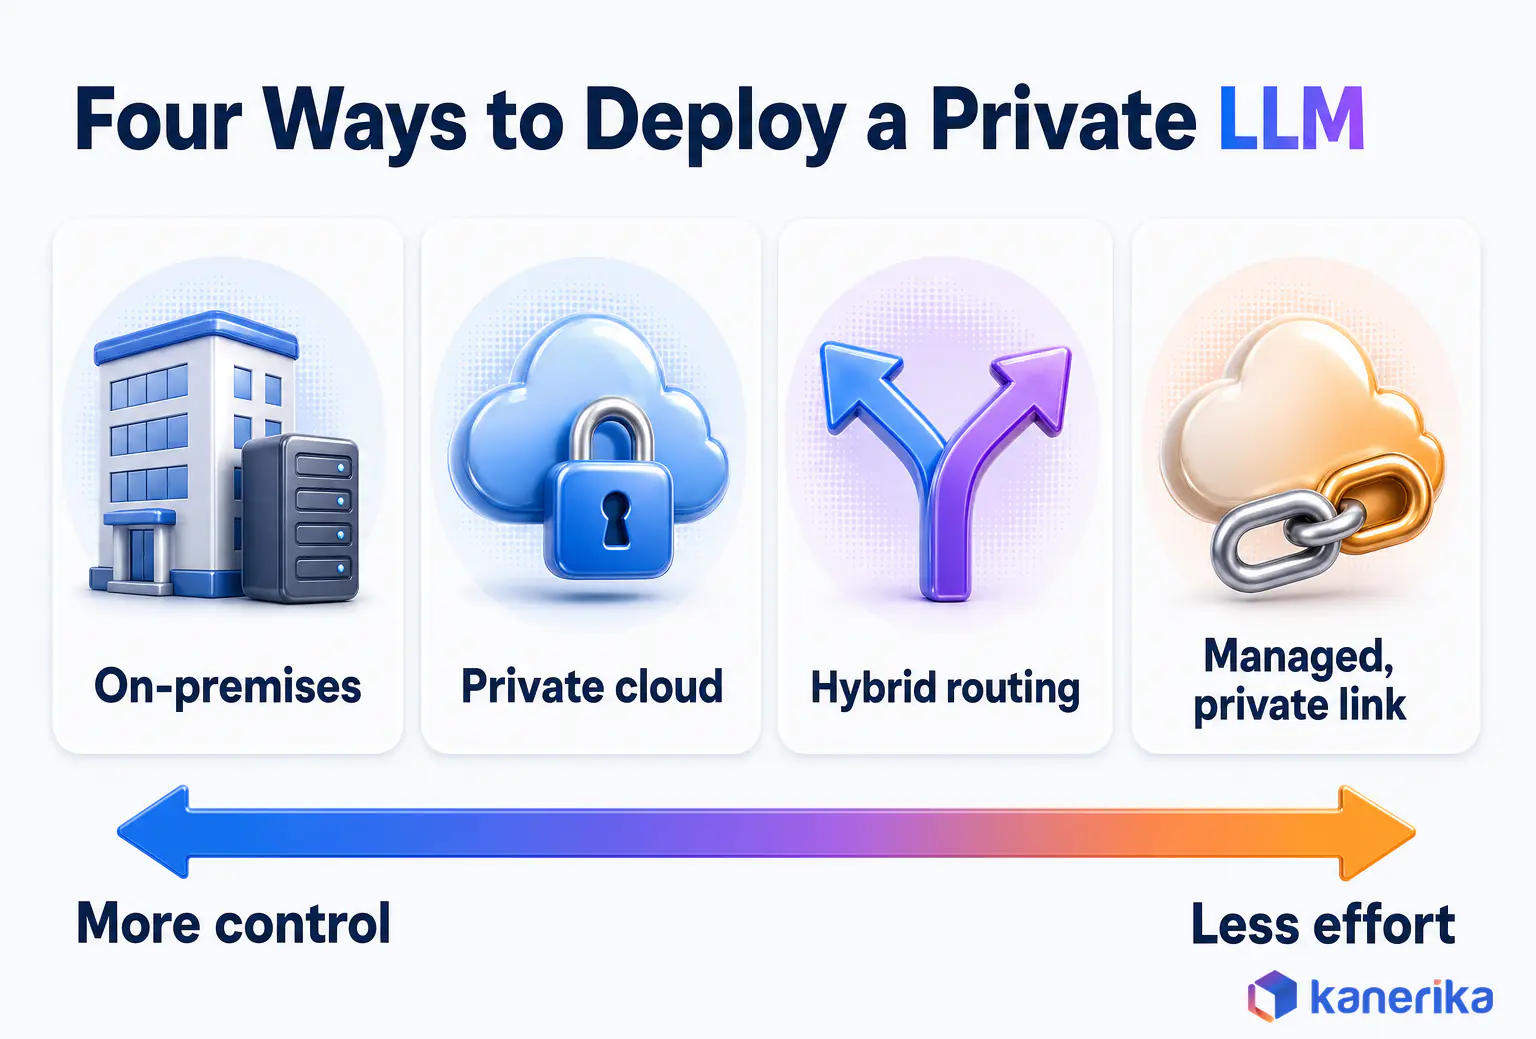
There are four common ways to run a private LLM, and they differ in who controls each of the four control points. The right answer is often more than one option, chosen workload by workload. Teams already make ML model deployment decisions one model at a time in the same way.
The table compares the four on the questions security and finance teams ask first. Read it as a starting point for each workload rather than a company-wide verdict.
| Option | Where it runs | Who can see prompts | Residency | Ops effort | Best for |
|---|
| On-premises | Your data center | Your staff only | Fixed by your site | Highest | Workloads such as air-gapped or classified systems |
| Self-hosted in private cloud | GPU instances in your VPC or VNet | Your staff, on the cloud’s infrastructure layer | Region you choose | High | Teams with cloud skills that also want full model control |
| Managed model over private networking | Provider endpoint reached through a private link | Not shared with model makers or other customers under Azure and Bedrock terms | Stored in your geography; processing location depends on deployment type | Low | A fast start with strong contract terms |
| Hybrid routing | A mix of the above | Depends on the route | Set per route | Moderate to high | Mixed workloads with different sensitivity |
Watch on YouTube
What Does It Take to Deploy an Enterprise LLM?
Kanerika’s team talks through what it takes to move an enterprise LLM from pilot to production, a useful companion to the deployment options compared above.
On-Premises
On-premises deployment puts the model on servers in your own data center. It is the only option that works for air-gapped networks, such as defense programs or plant control systems that never touch the internet. You buy or lease GPUs, run the serving software and own every patch. The control is complete, and so is the load on your infrastructure team.
Self-Hosted in Your Private Cloud
Self-hosting in a private cloud runs the same open-weight model on GPU instances inside your own virtual network. You keep control of weights, logs and versions, while the cloud provider handles the hardware. This is the usual route for teams that want the model under their own keys but do not want to run a data center.
Capacity planning still matters here, because GPU instances bill whether or not anyone is asking questions.
Managed Models Over Private Networking
The data terms quoted earlier apply here; what this option adds is the network path. Managed services let you call a provider’s model without the traffic crossing the public internet. On AWS, Amazon Bedrock can be reached from your VPC through AWS PrivateLink. Microsoft keeps data at rest in your chosen geography for Global and DataZone deployments. Global deployments may still process prompts in any region where the model runs, so choose a regional deployment when processing location matters.
What you give up, though, is the weights and the release schedule. If your main worry is a vendor training on your data, this option often answers it at a fraction of the effort. It fits less well when a regulator or client contract says no third party may process the data at all.
Hybrid Routing by Data Sensitivity
Hybrid routing sends each request to a different model depending on what it contains. A classifier, or a simple rule based on the data source, tags the prompt before it leaves the application.
A hospital group shows how this plays out. Questions that include patient records go to a self-hosted model inside the hospital network. Questions about policies, rotas or letter drafting, by contrast, go to a managed API over private networking. Clinical data never leaves, while the general workload needs no GPUs of its own. The routing rule itself becomes a control that auditors will want to inspect, so version it like code.
Choosing a Model and Serving Stack
Once the deployment option is clear, choosing a model becomes a question of fit rather than leaderboard position. Five checks settle most decisions: the licence, the hardware the model needs, its context length, its language coverage and its score on your own data.
That last check matters most. A public benchmark shows how a model handles someone else’s questions. A test set of a few hundred real questions from your own users shows how it handles yours.
Open-Weight Models and Their Licences
Licence terms decide whether you can use a model at all, so read them before you test quality. The table lists five widely used open-weight models with the licence shown on each Hugging Face model card. For rankings and benchmark results, see our list of open-source LLMs worth evaluating.
| Model | Licence | What to check |
|---|
| Llama 3.3 70B Instruct | Llama 3.3 Community License, gated access | Products above 700 million monthly active users need a separate licence from Meta |
| gpt-oss-120b | Apache 2.0, released by OpenAI in August 2025 | Standard Apache terms, including notice files |
| Qwen3-32B | Apache 2.0 | Standard Apache terms, including notice files |
| Gemma 3 27B | Gemma terms of use, gated access | Accept Google’s terms before download and review their use restrictions |
| Mistral Small 3.2 24B | Apache 2.0 | Standard Apache terms, including notice files |
Record the licence version you accepted for each model, because terms can change between releases. Legal review is quicker when the record already exists.
Serving Tools and Hardware Sizing
The serving layer turns model files into an API that your applications can call. Two common choices are vLLM for multi-user serving and Ollama for local testing and single-user setups. Our breakdown of vLLM vs Ollama explains when each fits. Both let a team run models behind its own endpoint instead of a vendor’s.
Hardware sizing starts with simple arithmetic. At 16-bit precision each parameter takes about two bytes, so a 70-billion-parameter model needs roughly 140 GB of GPU memory for the weights alone. Quantizing to 4 bits cuts that to about 35 GB, with some accuracy loss you should measure. Long prompts and many concurrent users then add cache memory on top.
- Confidential computing: NVIDIA data center GPUs offer confidential computing that protects data and models while in use, which helps when the host itself is not fully trusted.
- Smaller models: small language models run on a single GPU or on edge computing hardware, so they suit field equipment and offline sites.
- Right-sizing: many internal tasks, such as classification or extraction, do not need the largest model, and our comparison of SLMs and LLMs shows where the smaller option wins.
Talk to Kanerika
Sizing a Private LLM for Your Workloads?
In a short working session, Kanerika’s AI team maps each workload to a model, a deployment option and a hardware estimate before you commit to GPUs.
Book a Working Session →
What a Private LLM Costs
Private LLMs swap a variable bill for a mostly fixed one. As a result, their cost depends less on the model than on how steadily you use them. The total cost of ownership has six parts, and only some of them appear on the cloud invoice.
| Component | What drives it | One-time or recurring |
|---|
| GPU compute | Model size, concurrent users, hours in service | Recurring in the cloud; purchase plus refresh on premises |
| Storage and networking | Model files, vector indexes, logs, private links | Recurring |
| Engineering build | Serving, retrieval, access control, integration | One-time, then maintenance |
| Operations staff | Patching, monitoring, on-call cover, upgrades | Recurring |
| Evaluation and governance | Test sets, red-teaming, audits, documentation | Recurring |
| Licences and support | Model licence terms, enterprise support contracts | Varies by model and vendor |
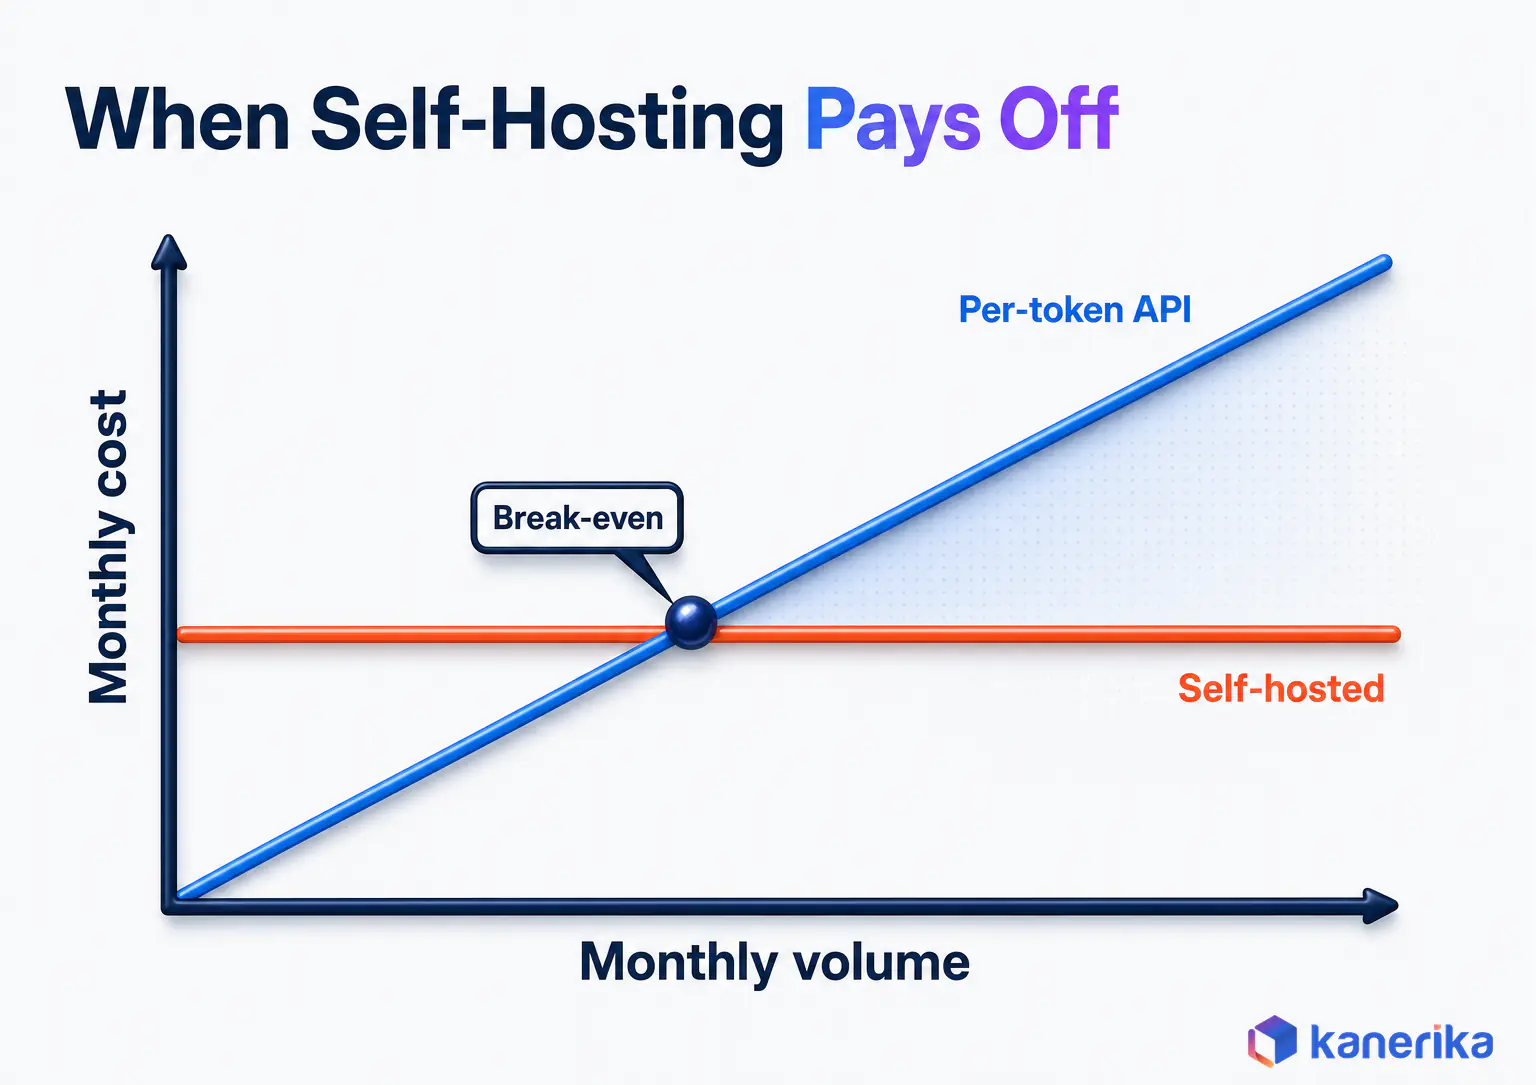
The break-even question compares that fixed cost with what the same workload would cost on a metered API. To illustrate, assume one million requests a month, each with 2,000 input tokens and 500 output tokens.
Anthropic lists Claude Opus 5.5 at $4 per million input tokens and $20 per million output tokens, as of October 2026, on its pricing page. That workload would cost $8,000 for input and $10,000 for output, or $18,000 a month.
Self-hosting pays off only if your fixed monthly cost for GPUs, staff and governance falls below that figure at the quality you need. Compare like with like, since a smaller self-hosted model may meet the bar for extraction while complex reasoning may still need a frontier model. The result also holds only while volume stays steady, because idle GPUs still bill. Run the calculation per workload rather than per company.
When Private Hosting Is Not Worth It
Self-hosting is the wrong call more often than its advocates admit. Skip it, or start with a managed option, in these situations.
- The data is public or low in sensitivity, such as marketing copy or published product documentation.
- Volume is low or arrives in bursts, so GPUs would sit idle for most of the month.
- No team can own GPU operations, patching and on-call support, so incidents would go unanswered.
- The task needs better reasoning than available open-weight models show on your evaluation set.
- A managed service with private networking and no training use already satisfies your legal and client terms, so extra control adds cost without adding protection.
Privacy-Enhancing Techniques
Privacy-enhancing techniques protect data in ways that network isolation alone cannot, especially while data is in use. Some are ready for production today, and others remain specialist tools for most LLM workloads. The right choice depends on the threat you face, so start there.
A bank fine-tuning a model on customer complaints worries about individuals being identifiable in the training data. A hospital renting cloud GPUs worries more about the cloud host seeing patient records in memory. The bank’s worry points to differential privacy, and the hospital’s to confidential computing. The table summarizes where each technique helps and what it costs you.
| Technique | What it protects | Maturity for LLM work | Cost | Use when |
|---|
| Confidential computing | Data and model while in use in memory | Available on data center GPUs | Moderate | When the host or cloud operator sits outside your trust boundary |
| Differential privacy | Individuals in training or analytics data | Mature for statistics, but harder for model training | Some accuracy loss | When fine-tuning on personal records |
| Federated learning | Raw data that cannot leave each site | Used in research and some regulated settings | High coordination effort | When several hospitals or banks train without pooling data |
| Homomorphic encryption | Data during computation | Too slow for LLM inference at scale | Very high | Narrow calculations on encrypted values |
| Secure multi-party computation (SMPC) | Inputs from parties that do not trust each other | Specialist use | High | When organizations run a joint analysis |
For differential privacy, NIST’s SP 800-226 guidelines, finalized in March 2025, explain how to evaluate privacy guarantees. They are also a sound yardstick for any claim a vendor makes. Most enterprises get further with confidential computing, strict retrieval permissions and short log retention than with the more experimental methods.
Risks, Governance and Common Mistakes
Private LLMs inherit every risk of a public model except vendor access, so governance is what turns isolation into something an auditor will accept. Two references set the baseline. The OWASP Top 10 for LLM Applications, 2025 edition, ranks prompt injection first as LLM01:2025. NIST’s Generative AI Profile, NIST AI 600-1, published on 26 July 2024, lists generative AI risks and suggested actions. It is also a companion to the NIST AI Risk Management Framework.
Our guide to LLM security risks and controls covers the threat categories in detail. This section stays on the controls and mistakes that matter most when the model runs privately.
On-Demand Webinar
The Real Cost of LLM Security Risks
An on-demand Kanerika webinar on the security risks that LLM deployments face and practical strategies to reduce them.
Watch the Webinar →
Governance Controls Before Production
Treat the list below as the minimum before real users and real data touch the system. It also covers the ethics questions, such as bias and explainability, that often sit in a separate policy document nobody reads.
- Access control enforced at retrieval, so answers only draw on documents the user could already open.
- Logging of prompts, sources and outputs, together with a set retention period and named readers.
- An evaluation set built from your own data, re-run before every model or prompt change.
- Human review whenever a decision has legal, financial or safety impact.
- Bias testing on the groups your use case affects, with results recorded.
- Explainability through cited sources, so a reviewer can trace each answer.
- Monitoring for drift, cost and failure rates once the system is live, using LLMOps observability.
- A named owner for the system and an incident process for when it misbehaves.
Our broader guide to AI governance explains how these controls fit into a company-wide program. That way the LLM does not become an exception to rules that cover every other system.
Common Mistakes
The same errors appear across private LLM projects, and each one has a simple fix.
- Treating isolation as security: add retrieval permissions, output filters and prompt-injection tests before the first release.
- Indexing everything: index only approved sources, and also carry document permissions into the vector database.
- Keeping logs forever: set retention to match your records policy, then limit who can read logs.
- Buying GPUs before measuring demand: pilot on a managed endpoint first, then size hardware from real traffic.
- Skipping evaluation: build a test set from real questions before launch and gate changes on it, using an LLM evaluation framework.
- Ignoring the licence: record the terms for every model and review them whenever you upgrade.
Checklist
AI Governance Checklist
A practical list of the policies, controls and owners an AI system needs before production, a companion to the controls and fixes above.
Get the Checklist →
Private LLM Use Cases by Industry
The strongest use cases for private LLMs share one trait: the data is sensitive, and the task repeats often enough to justify the build. Many start as generative AI pilots on public tools and move private once they touch real records. The table maps common workloads, such as note summaries and contract review, to the deployment option that usually fits.
| Industry | Workload | Data class | Usual option |
|---|
| Healthcare | Summarizing clinical notes, drafting discharge letters | Protected health information | Self-hosted or hybrid routing |
| Financial services | Credit memo drafts, reconciliation support, policy questions | Customer financial records, trading data | Private cloud, or managed over private networking |
| Legal | Contract review, clause extraction, due diligence | Privileged client documents | Self-hosted, or managed with no training use |
| Public sector | Case file search, correspondence drafting | Citizen records, sometimes classified | On-premises for classified data, private cloud otherwise |
| Manufacturing R&D | Searching design files, test reports and patents | Trade secrets and product designs | Self-hosted in private cloud |
Financial services shows how quickly sensitive data piles up in ordinary prompts. An operations analyst who reconciles settlement files against statements from a payment provider handles account numbers, merchant names and amounts in every question. A public chatbot is therefore a non-starter for that work. A private model with retrieval over approved files can match exceptions and draft notes for review while the records stay under the bank’s control.
Legal and R&D teams face the same issue, although with different documents. In each case the question is whether people can find what they need without widening who can see it. Our article on data accessibility explores that balance.
Should You Adopt a Private LLM? A Decision Framework
Whether to adopt a private LLM comes down to whether your data, your obligations and your volume justify owning the control points. Three questions, asked in order, settle most cases.
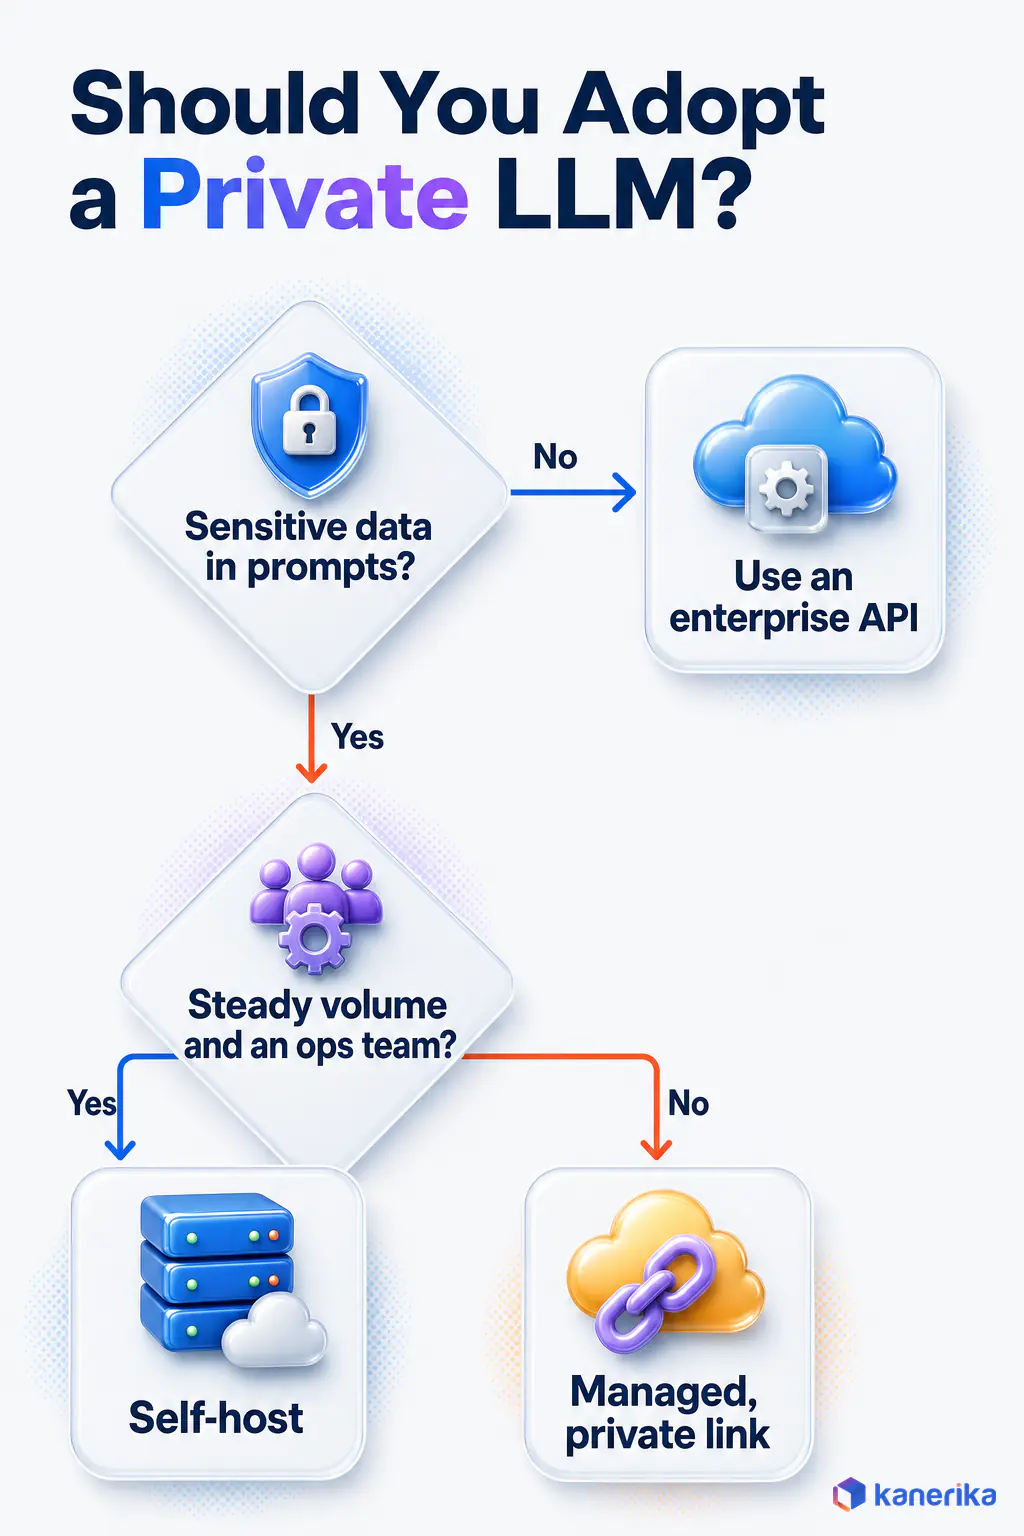
To begin with, look at the data. If prompts will carry nothing confidential, an enterprise API is enough and the other questions fall away. If they will, ask whether volume is steady and a team can run GPUs. A yes points to self-hosting, while a no points to a managed model over private networking. Classified or air-gapped work goes straight to on-premises.
Six Common Situations and the Right Call
The table expands those answers for the situations we see most often, and each row says adopt or not.
| Situation | Recommendation | Why |
|---|
| Regulated or confidential data in prompts, steady high volume, an ops team in place | Adopt a self-hosted private LLM | You need all four control points and can keep GPUs busy |
| Confidential data, low or uneven volume | Adopt a private LLM through a managed model over private networking | Contract terms cover training and log access without idle hardware |
| Classified or air-gapped environment | Adopt an on-premises private LLM | No external endpoint is permitted |
| Mixed sensitivity across many teams | Adopt a private LLM with hybrid routing | Sensitive prompts stay inside, while the rest uses cheaper managed capacity |
| Public data, occasional use | Do not adopt a private LLM yet; use an enterprise API | The controls would cost more than the risk they remove |
| No owner for operations or governance | Do not adopt yet; assign ownership first | An unmanaged private model is riskier than a managed public one |
If the answer is to adopt, the next decision is which model family to standardize on. Our guide to choosing an enterprise LLM then picks up from there.
Questions to Answer Before You Adopt
Answer these eight questions with a plain yes or no before you commit budget. Several “no” answers usually mean the lightest private option, a managed model over private networking, is the better first step.
- Have you classified the data each use case will send to the model?
- Do any contracts, regulators or clients forbid third-party processing of that data?
- Have you chosen a deployment option for each workload rather than one for the whole company?
- Have you checked the licence of every candidate model for your scale and use?
- Can you estimate monthly volume well enough to compare fixed and metered cost?
- Is there a team that will own serving, patching and on-call support?
- Will retrieval enforce the same permissions as the source systems?
- Do you have an evaluation set and a named owner for model changes?
Checklist
Generative AI Checklist
Work through the readiness questions for a generative AI rollout, from data and use cases to governance, before you commit budget to a private LLM.
Get the Checklist →
What to Watch Over the Next 12 Months
Two dated deadlines and one licensing pattern affect when you adopt and what you must document.
- EU AI Act deadlines: the majority of rules have applied since 2 August 2026, and Annex III high-risk rules follow on 2 December 2027, so preparation work falls inside the next year.
- 2 December 2026: new prohibitions on non-consensual sexual deepfakes and child sexual abuse material apply. Providers of synthetic-content systems placed on the market before 2 August 2026 must also meet Article 50(2) by then.
- Open-weight licences: Apache 2.0 releases such as gpt-oss-120b and Qwen3-32B sit beside custom licences such as Llama’s and Gemma’s, which keeps licence review part of every upgrade.
How Kanerika Helps Enterprises Adopt Private LLMs
Kanerika builds private LLM systems around the data first and only then the model, as part of its generative AI services. A typical engagement moves through five steps, each tied to one of the checks in this guide.
- Data-sensitivity assessment: classify the data each use case touches and the rules that apply to it before anything is built.
- Deployment choice per workload: match each workload to on-premises, private cloud, managed or hybrid routing, so no single option is forced on every team.
- Model and serving build: select and license the model, then stand up serving with pinned versions.
- Retrieval with access control: connect approved sources and enforce source-system permissions whenever a query runs.
- Evaluation and monitoring: build test sets and LLMOps monitoring so every change is measured before release.
Step four is where most of the privacy value sits, because it decides what each user’s answer can draw on.
Case Study: Role-Based Retrieval for an Investment Bank
An investment bank put that step into practice. Its analysts needed answers from long RFI documents and from structured databases, and each answer had to respect the analyst’s role. Kanerika deployed KlarityIQ for the unstructured documents and Karl for the structured databases, both behind a chat interface. Role-based access control was enforced inside the retrieval layer, so a response could only draw on sources the user was cleared to see.
The investment bank case study reports three results:
- 43% faster information retrieval
- 100% role-based compliance achieved
- 35% higher workforce efficiency
Case Study
43% Faster Document Retrieval for an Investment Bank
KlarityIQ for documents and Karl for databases, behind a chat interface with role-based access control enforced at retrieval, gave an investment bank 43% faster information retrieval and 35% higher workforce efficiency.
Read the Case Study →
The lesson also carries over to any private LLM program. The permission check belongs inside retrieval, wherever the model runs, whether on premises, in a private cloud or behind a managed endpoint.
A first project usually starts with one workload that has a clear owner and a measurable cost. Contract review and service desk policy questions are typical examples. The team runs it on the deployment option the assessment pointed to and measures answer quality and cost against the current process. Only then do the same controls extend to the next workload.
Starting narrow keeps the security review short, because reviewers assess one data class and one route instead of a whole platform. It also gives finance a real cost figure for the break-even test described earlier.
What Each Engagement Leaves Behind
Every engagement leaves records the client keeps using after go-live. They include a data classification per use case, a written deployment decision per workload, an evaluation set from real questions and dashboards for quality and cost. An auditor asks for these first, and they turn the next model upgrade into a routine change.
KlarityIQ, the document agent behind the bank’s results, is the subject of the podcast episode below. It explains how the agent turns enterprise documents into data people can search and use. To map your own workloads to the right deployment option, book a working session with Kanerika’s AI team.
Wrapping Up
Private LLMs give an organization control over four things a public chatbot decides for you. Those are where the model runs, where data travels, who reads the logs and when the model changes. That control is worth paying for when prompts carry regulated or confidential data or when auditors need reproducible outputs. It also pays when steady volume makes fixed capacity cheaper than metered calls.
It is not worth it, though, for public data, light usage or a team with no one to run it. So before adopting, classify your data, choose a deployment option per workload and check each model licence. Then price the full cost of ownership and put governance in place. If those checks come back clear, a private LLM is the right next step. If they do not, start with the lightest private option, a managed model over private networking, and revisit self-hosting when volume and staffing catch up.
Frequently Asked Questions
What is a private LLM?
A private LLM is a large language model deployment where your organization controls where the model runs, where prompts and outputs travel, who can read the logs and when the model version changes. It can be an open-weight model you host yourself or a managed model reached over private networking under strict data terms.
How does a private LLM work?
A user’s question passes through an authenticated app, a retrieval step that searches approved company documents, the model running on your GPUs or a contracted private endpoint, an output filter and an audit log. Every hop stays on infrastructure you control or have contracted for, so you decide what data the model sees and who reviews it.
What is the biggest risk of using an LLM with company data?
The biggest practical risk is exposing data to people who should not see it, either through a vendor or through your own system. Retrieval that ignores document permissions and prompt injection hidden in files are common causes. OWASP ranks prompt injection as the top risk in its 2025 Top 10 for LLM applications, ahead of every other category.
Does Azure OpenAI or Amazon Bedrock count as a private LLM?
They can, depending on your requirements. Microsoft states that prompts sent to models sold by Azure in Foundry are not available to other customers or to OpenAI. AWS states that Bedrock model providers cannot access prompts or logs, and Bedrock supports AWS PrivateLink. What you do not get is the model weights or full control of release timing.
What infrastructure do you need to run a private LLM?
You need GPUs with enough memory for the model, serving software such as vLLM, a document store or vector index for retrieval, identity and access control, plus logging and monitoring. As a rough guide, a 70-billion-parameter model needs about 140 GB of GPU memory at 16-bit precision, and quantization or a smaller model reduces that requirement.
How long does it take to deploy a private LLM?
Timelines depend on the option you choose and the state of your data. A managed model over private networking can reach a pilot quickly, because there is no hardware to buy. Self-hosting adds GPU procurement, serving setup and security review. Data classification, permission mapping and evaluation usually take longer than standing up the model itself.
Do you need an in-house ML team to run a private LLM?
Not necessarily for a managed deployment, where the provider runs the model and your team focuses on retrieval, access control and evaluation. Self-hosting needs people who can operate GPUs, serving software, patching and on-call support. Many organizations start with a managed option, build those skills gradually, and bring hosting in-house once volume justifies it.
Can a private LLM help with HIPAA or GDPR compliance?
It can make compliance easier to demonstrate, because data stays in a known location and logs are under your control. It does not make a system compliant on its own. HHS guidance treats cloud providers handling protected health information as business associates, and GDPR duties such as data minimization and access rights still apply to everything the model touches.
How do you keep a private LLM up to date with new information?
Use retrieval-augmented generation rather than retraining. New documents go into an indexed store, and the model pulls the relevant passages at question time, so answers reflect changes the same day. Removing a document removes it from answers too. Fine-tuning is better reserved for teaching style or task skills, not for keeping facts current over time.
When is a private LLM not worth it?
Skip self-hosting when the data is public or low in sensitivity, when usage is light or comes in bursts, or when nobody can own GPU operations and monitoring. It is also unnecessary if a managed model with private networking and no training use already meets your legal and client terms at a lower total cost.
What is the difference between a public and private LLM?
A public LLM runs on a provider’s shared service under that provider’s retention, training and update policies. A private LLM runs where you choose, keeps prompts and logs inside your boundary or under contract, and changes version only when you decide. The underlying models can be identical, because the difference lies in who controls the deployment.
Is a local LLM private?
A model running on your own laptop or server is private in one sense, because prompts never leave the machine. It is the same idea as an on-premises LLM at a smaller scale. It is not automatically safe, though, since you still need access control, patching, logging and protection against harmful instructions hidden inside documents it reads.
Is there a private LLM?
Private describes a deployment rather than a product, so any model you can run under your own control can become one. Open-weight options include Llama 3.3 70B, gpt-oss-120b, Qwen3-32B, Gemma 3 27B and Mistral Small 3.2 24B. Managed services such as Azure in Foundry or Amazon Bedrock can also serve as private deployments under their published data terms.
How to use an LLM privately?
Start by deciding which data the model may see. Then pick a deployment, either an open-weight model self-hosted in your network or a managed model reached through private networking with no training use. Add retrieval that respects existing permissions, set a log retention period, and test the system against your own questions before anyone relies on it.
What is LLM privacy?
LLM privacy is the practice of controlling what personal or confidential data reaches a language model, where that data travels, how long it is stored and who can read it. It covers prompts, retrieved documents, outputs and logs, and it also covers whether any of that data could later be used to train a model.
How much does a private LLM cost?
Cost depends on GPU capacity, storage, engineering, operations staff, evaluation and licences rather than on a per-token fee. A useful test is to price your monthly workload on a metered API and compare it with your fixed self-hosting cost. Self-hosting usually wins only at steady, high volume, and a managed private endpoint often wins below that level.
What is the difference between LLM and AI?
AI is the broad field of systems that perform tasks associated with human intelligence, such as prediction, perception and planning. An LLM is one kind of AI, a model trained on very large amounts of text to understand and generate language. So every LLM is a form of AI, but most AI systems in production are not language models.
Is ChatGPT a private LLM?
The consumer ChatGPT app is not a private LLM, because OpenAI runs the service, sets the retention policy and chooses the model version. Models sold by Azure in Foundry come closer, since Microsoft states that prompts are not shared with OpenAI or used for training without permission. Full control over the weights requires an open-weight model such as gpt-oss-120b.














