TL;DR
The top LLMs in November 2026 are Claude Opus 5.5, GPT-6.1 Sol, Gemini 4 Argon, Claude Fable 5.1 and GPT-6 Astra among closed models. Opus 5.5 matches or beats Fable 5.1 on most benchmarks Anthropic lists, yet its token prices are 60% lower. For mid-price work, GPT-6.1 Sol and Claude Sonnet 5.5 both cost $2 input and $10 output per million tokens. If you need downloadable weights, Qwen3.8-27B (Apache 2.0) and DeepSeek V4 (MIT) carry standard licenses, while Mistral Large 4 and GLM-5.3 use custom ones. Gemini 4 Carbon is announced only and Kimi K3.1 Pro weights had not shipped by November 2, so check each status before you plan. Then test two or three candidates on your own data before you commit.
Key Takeaways
- The November 2026 leaders are Claude Opus 5.5, GPT-6.1 Sol and Gemini 4 Argon, with Claude Fable 5.1 and GPT-6 Astra as the premium tier.
- Input prices across the ranked tiers run from $0.10 per million tokens on GPT-6 Luna and Claude Haiku 5.5 to $10 on GPT-6 Astra and Fable 5.1.
- GPT-6.1 Sol and Claude Sonnet 5.5 share a $2 input and $10 output price, so quality on your own tasks decides between them.
- Long prompts cost more, since OpenAI raises rates above 272K tokens and xAI from 200K, and Gemini 4 Argon doubles on December 1, 2026.
- As of November 2, 2026, Mistral Large 4, GLM-5.3 and the Qwen3.8-Max base model have public weights under custom licenses, so check terms first.
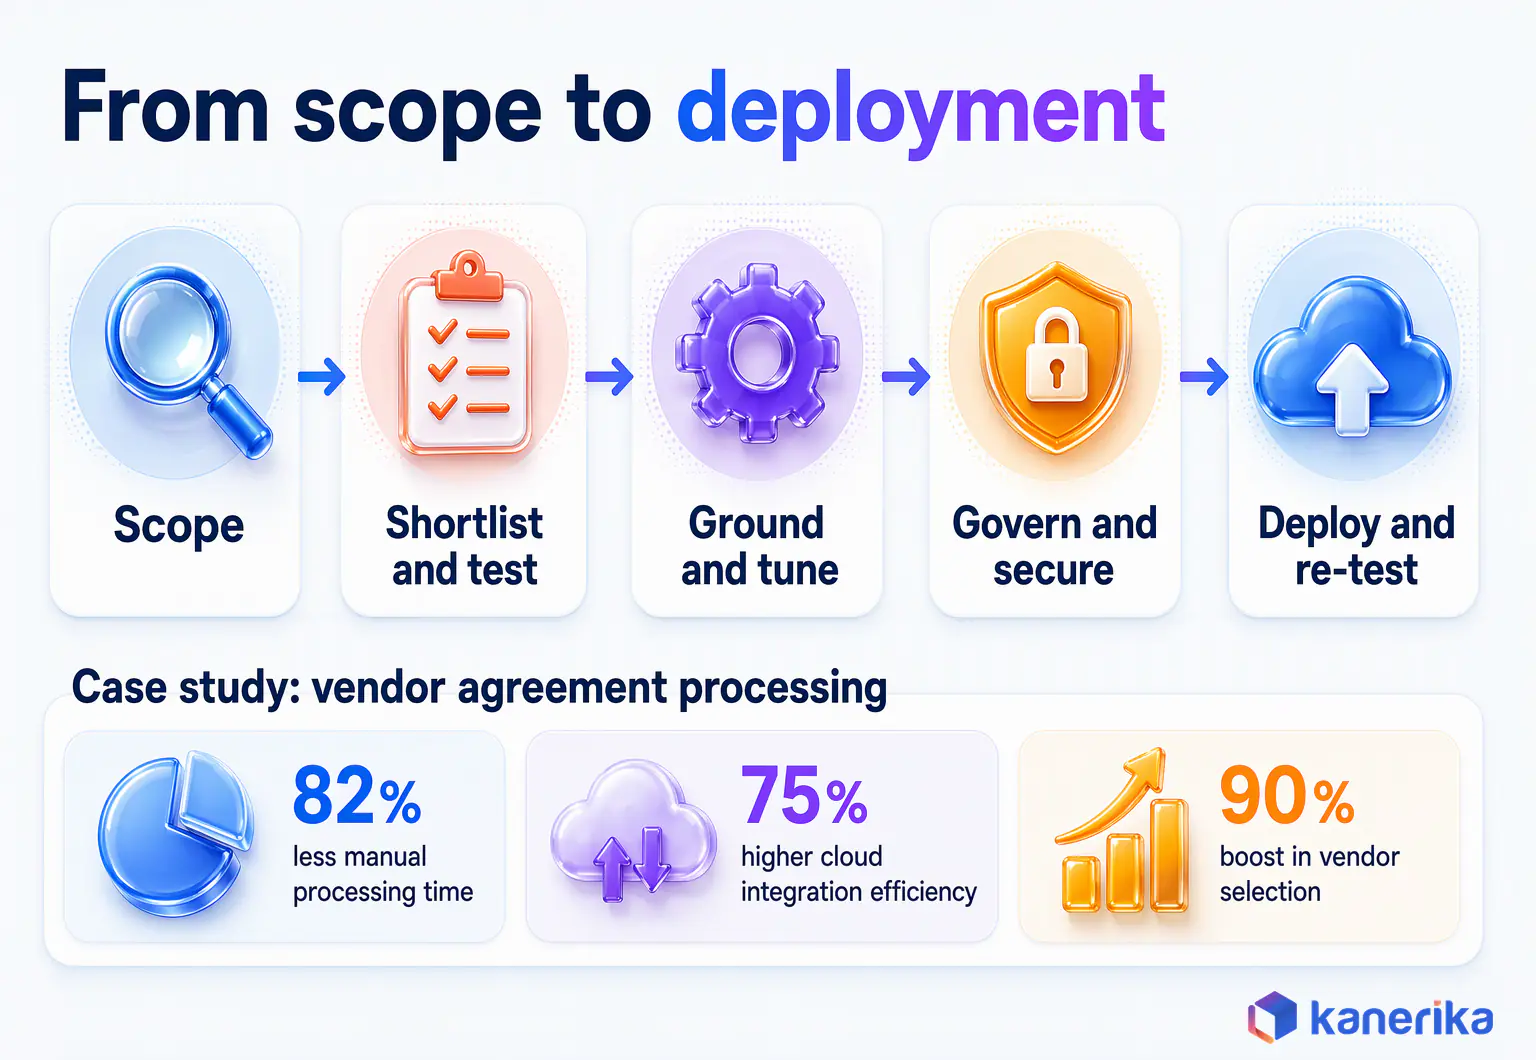
- Kanerika shortlists, tests and governs models on client data, and one LLM vendor agreement project reached a 90% boost in vendor selection.
Why Your Spring 2026 Model Pick Is Already Out of Date
Picture a team that chose its model in spring 2026 and built a support assistant around it. The assistant works, and nobody has revisited the model choice since.
Yet since September, Anthropic, OpenAI and Google have each shipped a new flagship tier. Google has also set a price rise for Gemini 4 Argon on December 1, and the team’s cost model still assumes the old sheet.
So the pick that looked safe in April now has cheaper and stronger rivals, and its budget may already be wrong. Any team planning an enterprise LLM rollout faces the same problem, because model lists change faster than procurement cycles. A fixed re-test schedule is the only reliable defense against that drift.
This guide gives you a dated ranking of the top LLMs, verified prices and the availability status of each model. It also includes a scorecard and a two-week test plan you can reuse when the next release lands.
Top LLMs at a Glance: The November 2026 Ranking
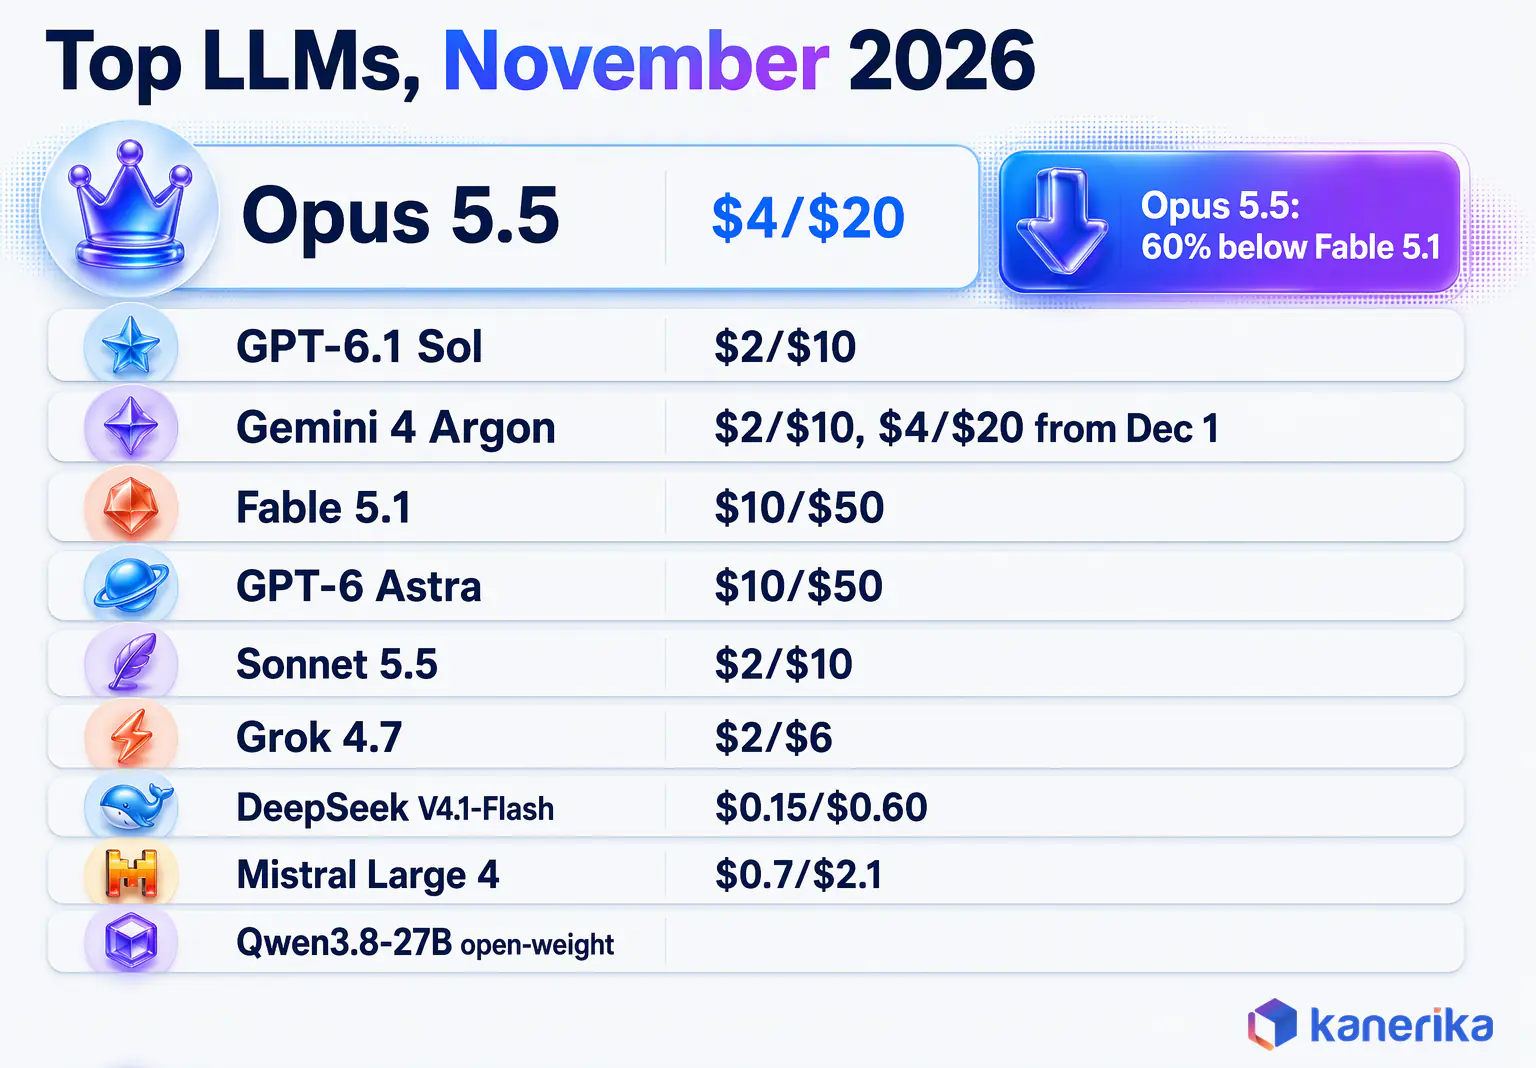
This ranking of the top LLMs covers the ten models a builder or buyer should look at first in November 2026. Each row shows status, list price and context window, so you can rule a model in or out quickly.
Status matters as much as price here, because a preview or announced model cannot carry a production workload yet. For a head-to-head of the three consumer chat assistants and their plans, read our ChatGPT vs Gemini vs Claude comparison.
Read the ranking from rank 1 down. The order is an editorial call based on vendor positioning, the benchmarks vendors publish and list price.
Prices are standard API rates per million tokens, read from each vendor’s pricing page on November 2, 2026. Each figure also links back to its vendor source in the entries further down.
The Ranking Table
Ranks 4 and 5 are premium tiers, worth testing only after ranks 1 and 2 miss your bar. Ranks 8 to 10 trade some convenience for much lower prices or the option to self-host.
The “best first use” column is an editorial starting point, so treat it as a hypothesis for your tests. In the end, your own results on real tasks decide the final pick among the top LLMs.
| Rank | Model | Provider | Status | Input / output per 1M | Context | First to test for |
|---|---|---|---|---|---|---|
| 1 | Claude Opus 5.5 | Anthropic | Live | $4 / $20 | 1M | Coding agents and hard reasoning |
| 2 | GPT-6.1 Sol | OpenAI | Live | $2 / $10 | 1.05M | General production work |
| 3 | Gemini 4 Argon | Live (Google does not label it GA or preview) | $2 / $10 until Nov 30, then $4 / $20 from Dec 1 | Up to 1M | Teams already on the Gemini API | |
| 4 | Claude Fable 5.1 | Anthropic | Live | $10 / $50 | 1M | Tasks that fail on Opus 5.5 |
| 5 | GPT-6 Astra | OpenAI | Live | $10 / $50 | 1.05M | Tasks that fail on Sol |
| 6 | Claude Sonnet 5.5 | Anthropic | Live | $2 / $10 | 1M | Assistants at volume, such as support |
| 7 | Grok 4.7 | xAI | Live | $2 / $6 under 200K tokens | 500K | Work where output volume drives cost |
| 8 | DeepSeek V4-Pro / V4.1-Flash | DeepSeek | Live (V4-Pro GA) | V4-Pro $0.66 / $1.98, Flash $0.15 / $0.60 (off-peak) | 1M on Flash | High volume on a tight budget |
| 9 | Mistral Large 4 | Mistral AI | Public preview API; weights public (custom license) | $0.7 / $2.1 | 1M (model card) | Cheap trials while it stays in preview |
| 10 | Qwen3.8 family | Alibaba | Open weights on 27B (Apache 2.0) and the Max base (custom license) | Self-hosted cost on 27B; Max $2 / $6 on QwenCloud | 262K native on 27B, up to 1M; Max 1M | Data that must stay on your servers |
How We Ranked These Models
A large language model is a neural network trained on huge volumes of text so that it can read and generate language. Teams reach it through a vendor API, or they run it on their own hardware when the license allows. For the internals, see our guide to how LLMs are built.
We judged each model on five criteria, using only what vendors publish on their own pages. After that, we grouped the models into tiers, so a team can start testing with the right two or three.
- Vendor-published capability evidence, such as model cards and benchmark tables.
- Price per million input and output tokens, including cache and long-prompt rules.
- Context window and maximum output limits.
- Availability status, from live and preview to announced or not yet shipped.
- Deployment control, meaning downloadable weights and their license, or API access only.
This ranking is an editorial reading of vendor pages as of November 2, 2026. Kanerika did not run its own benchmark for it, so treat each rank as a starting point for your tests.
Why Benchmarks Alone Cannot Pick Your Model
Vendor benchmarks run under fixed prompts, settings and effort levels, so they may differ from your workload. For example, the Claude Sonnet 5.5 page lists a Terminal-Bench 4.0 score with no effort level. Because of that, you cannot set it against the Opus 5.5 figure, which comes from a different setup.
Independent trackers such as Artificial Analysis help you cross-check vendor claims across providers. On November 2, 2026, its home page described Intelligence Index v5.0 as built from 9 evaluations measured independently by Artificial Analysis.
Read such a leaderboard in three passes. First, note the index version, since scores from different versions do not compare. Next, check output tokens per second and cost per task, which the site reports beside the index.
Last, open the provider view, which compares API hosts on speed, latency, price and endpoint accuracy, because one model can behave differently by host. Even so, the only score that predicts your results comes from your own data. So build a test set early with an LLM evaluation framework.
Checklist
Enterprise AI Readiness Checklist
Settle the data, security and governance questions before you test an LLM.
Get the Checklist →The Top LLMs in November 2026, Ranked From 1 to 10
Each entry below covers what the model is for, what it costs and where it fits among the top LLMs.
1. Claude Opus 5.5 (Anthropic)
Anthropic announced Claude Opus 5.5 on September 22, 2026, and its model overview recommends Opus 5.5 for most work.
On its Opus 5.5 page, Anthropic reports 66.4% on Terminal-Bench 4.0 compared to 55.8% for Fable 5.1. Opus 5.5 matches or beats Fable 5.1 on most listed benchmarks, while its input and output prices are both 60% lower.
Prompt caching also cuts repeat costs, since cache reads bill at $0.20 per million tokens and cache writes at $5. Kanerika is Certified in the Claude Partner Network and builds on the Claude family alongside other providers.
- Pick it for: coding agents and multi-step reasoning, especially across long documents.
- You pay: $4 input and $20 output per 1M tokens on Anthropic’s pricing page.
- Window: 1M tokens in, up to 128K out.
2. GPT-6.1 Sol (OpenAI)
OpenAI published GPT-6.1 Sol on September 29, 2026, and it runs under the API id gpt-6.1-sol. It sits in the middle of OpenAI’s GPT model family, so it fits most production work at a moderate price.
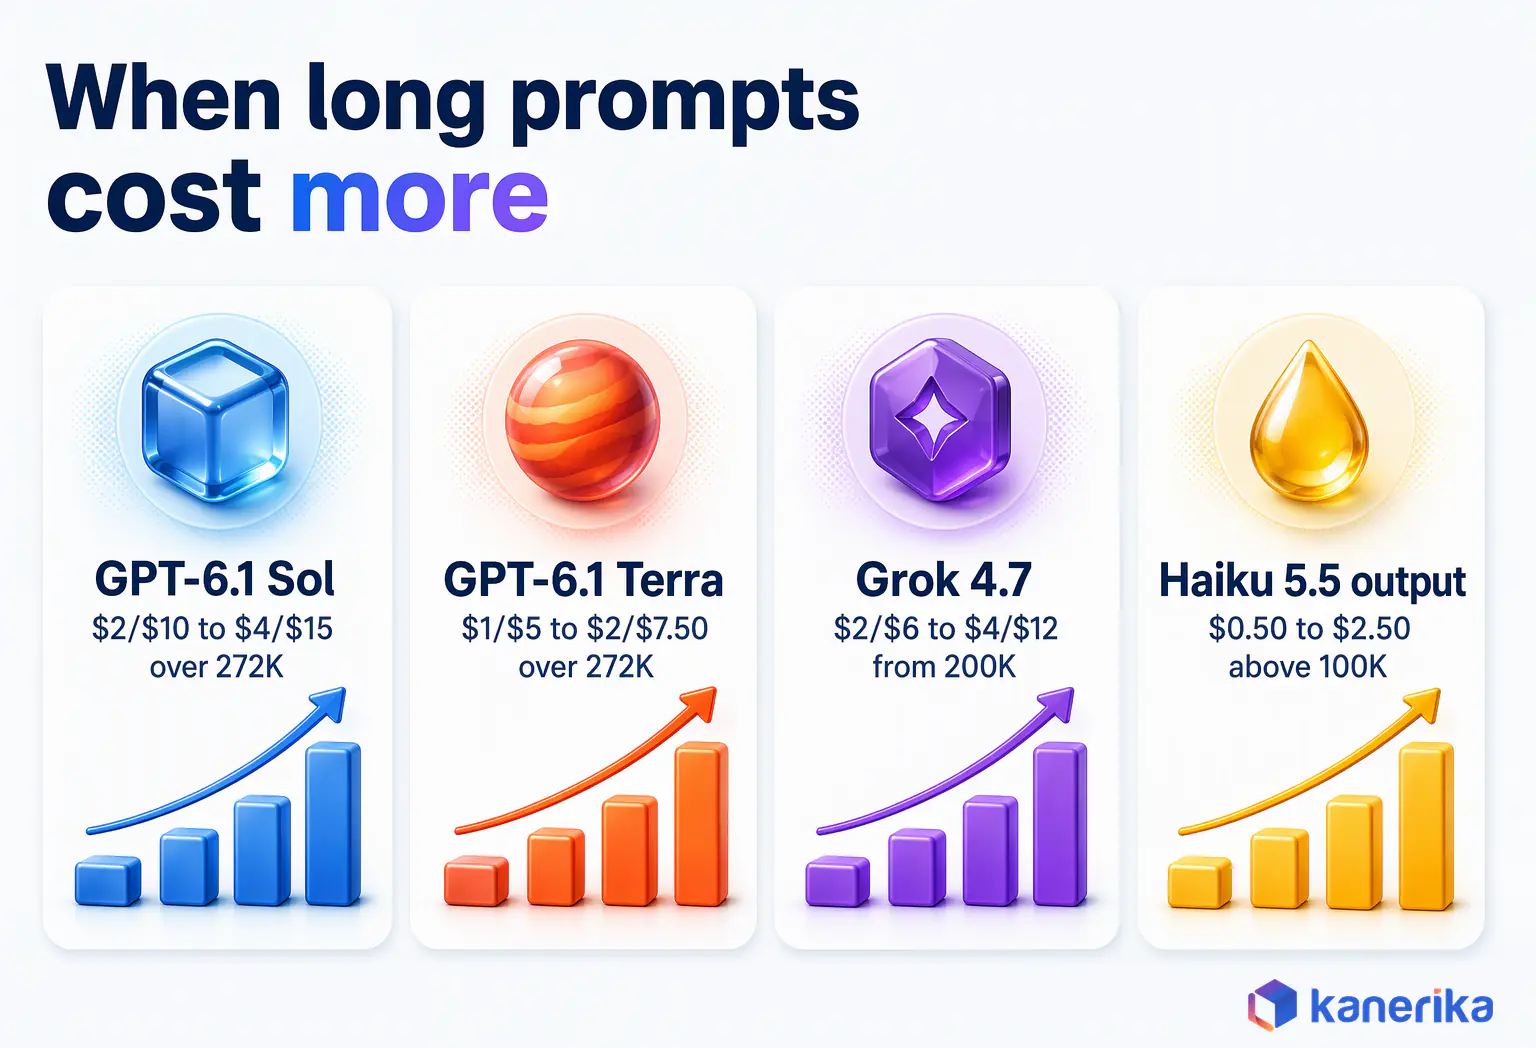
Sol lists a 1,050,000-token context window as well as 128,000 output tokens on OpenAI’s model page. Once a prompt passes 272K tokens, it costs 2x on input and 1.5x on output. As a result, a 300K-token prompt bills at $4 input and $15 output per million.
Batch and Flex processing run 50% lower when a job can wait. Teams on the OpenAI API can switch between Sol and its siblings easily.
The standard rate on OpenAI’s pricing page is $2 input, $0.10 cached input and $10 output per 1M tokens. At that price, Sol is the default to try for general assistants, coding help and batch document jobs.
3. Gemini 4 Argon (Google)
Google published the Gemini 4 Argon model card on October 13, 2026, and the model runs under the id gemini-4-argon. It is live in the Gemini API, although Google’s pages do not label it GA or preview.
Argon handles up to 1M tokens of combined context, so it suits long reports and large document sets. Plan for the price change now, because Argon costs $2 input and $10 output through November 30, 2026. From December 1, the rate on the Gemini API pricing page rises to $4 and $20.
Model both rates in your budget. Our Google Gemini guide covers the wider model family.
- Through November 30, 2026: $2 input and $10 output per 1M tokens.
- From December 1, 2026: $4 input and $20 output, on the same window of up to 1M combined tokens.
- Who should test it: teams on the Gemini API, provided that the budget covers the December rate.
4. Claude Fable 5.1 (Anthropic)
Anthropic’s model overview lists Claude Fable 5.1 as its top tier, priced at $10 input and $50 output per million tokens. It also shares the 1M context window and 128K output limit of Opus 5.5.
Because Opus 5.5 matches or beats it on most listed benchmarks at 60% lower prices, Fable 5.1 is a model to test selectively. Try it only on tasks that still fail on Opus 5.5.
The math is simple. At $10 and $50 per 1M tokens, every Fable 5.1 call costs 2.5 times the Opus 5.5 rate on the same 1M window. Reserve it for the small share of tasks that Opus 5.5 still fails.
5. GPT-6 Astra (OpenAI)
GPT-6 Astra is OpenAI’s premium tier, and it runs under the id gpt-6-astra. It costs $10 input, $1.00 cached input and $50 output per million tokens, five times the Sol rate.
Astra lists a 1.05M context window with 128K output, so its limits match Sol. Moving up to it keeps you on the same API, ids and SDKs.
When should you test it? Only after Sol has missed the bar on a high-stakes task, since a fivefold price step needs a measured gain to justify it.
6. Claude Sonnet 5.5 (Anthropic)
Anthropic announced Claude Sonnet 5.5 on September 28, 2026, as the mid-price model in the 5.5 family. It costs $2 input and $10 output per million tokens, the same list price as GPT-6.1 Sol.
Sonnet 5.5 also shares the 1M context window and 128K output limit of Opus 5.5. Cache reads cost $0.10 and cache writes $2.50, which helps assistants that reuse long system prompts.
- Rate: $2 input and $10 output per 1M tokens, level with Sol.
- Start here if: you run customer-facing assistants or everyday coding work at volume.
7. Grok 4.7 (xAI)
xAI’s Grok 4.7 runs under the id grok-4.7, and it comes with a 500,000-token context window. According to the xAI models page, it costs $2 input and $6 output per million tokens for prompts under 200K tokens.
Watch that threshold closely, because crossing it reprices every token in the request.
For a larger window, Grok 4.3 lists 1M tokens at $1.25 input and $2.50 output under 200K. For a closer look at xAI against two rivals, see Grok vs ChatGPT vs DeepSeek.
- Prompts under 200K tokens: $2 input and $6 output per 1M, with cached input at $0.50.
- Prompts at 200K and over: $4 and $12 on every token in the request.
- Why test it: its $6 output rate sits below the $10 mid-price norm, which helps output-heavy work.
8. DeepSeek V4-Pro and V4.1-Flash (DeepSeek)
DeepSeek V4-Pro reached general availability on August 13, 2026, and it runs under the id deepseek-v4-pro. During off-peak hours, it costs $0.66 input and $1.98 output per million tokens.
V4.1-Flash followed with a news post dated October 17, 2026, under the id deepseek-flash. It brings 1M tokens of context at $0.15 input on a cache miss and $0.60 output off-peak, as shown on the DeepSeek pricing page.
Flash rates double at peak, which runs from 1am to 4am and from 6am to 10am UTC, Monday to Friday. The pricing page does not state parameters, but the V4-Pro-0813 and V4.1-Flash-1017 weights are on Hugging Face under the MIT license. See our DeepSeek overview for background.
The practical move is to schedule batch jobs outside those peak windows. Do that, and V4.1-Flash carries the lowest listed API rates among the ten ranked models, with a 1M-token window.
9. Mistral Large 4 (Mistral AI)
Mistral AI released Mistral Large 4 on October 6, 2026. As of November 2, 2026, its hosted API was still a public preview. The Mistral Large 4 announcement describes 1T parameters, with 52B of them active.
At $0.7 input and $2.1 output per 1M tokens, it prices close to DeepSeek V4-Pro. The weights are public too, in the ungated Mistral-Large-4-1T-A52B repo created September 30, 2026, with an NVFP4 build added October 15, 2026. Its model card lists a 1M context window and the Mistral Ecosystem Open-Weight License, a modified MIT license.
That makes Large 4 a low-cost way to trial a very large model. Keep the hosted API out of production until it leaves preview, and check the license before commercial use. Running it as a hosted model service needs a separate commercial license from Mistral, the model card says.
10. Qwen3.8 Family (Alibaba)
Alibaba’s Qwen3.8-27B is the smallest open-weight pick in this ranking. Its Hugging Face model card lists a dense model under the Apache 2.0 license, with 262,144 tokens of native context that extends to 1M.
Qwen3.8-Max arrived on August 3, 2026, with 2.4T parameters, 95B active and a 1M context window. The base weights went up on Hugging Face as Qwen3.8-2.4T-A95B, in a repo created August 8, 2026, under a custom “qwen3.8-max” license.
Its model card calls Qwen3.8-Max the official version built on that model, and QwenCloud lists it at $2 input and $6 output per 1M tokens.
- Qwen3.8-27B costs only your own hosting, so it suits teams that can run the GPUs.
- Qwen3.8-Max is a 1M-context model at $2 and $6 hosted, and its base weights carry a custom license to check before commercial use.
Also Worth Testing: GLM-5.3
GLM-5.3 has 753B parameters and shares its base with GLM-5.2, with gains from extra post-training. Its weights are on Hugging Face as zai-org/GLM-5.3, in a repo created August 25, 2026. It ships under a custom “glm-5.3” license rather than MIT or Apache, so check the license before commercial use.
Budget Tier for High-Volume Work
High-volume jobs such as tagging, routing and extraction rarely need a flagship model. For that reason, four budget options stand out on price.
- GPT-6 Luna at $0.10 input and $0.50 output, with a 1.05M window.
- Claude Haiku 5.5 at $0.10 and $0.50 up to 100K prompt tokens, with output rising to $2.50 above that.
- GPT-6.1 Terra at $1 and $5, with the same window as Sol.
- Gemini 3.8 Flash at $0.75 and $3.75 through December 31, 2026, then $1.50 and $7.50.
For even lighter workloads, small language models can run on modest hardware, and our SLMs vs LLMs guide explains when each one fits.
Announced or Pending: Check Before You Plan
Several models in the news are not ready for production planning yet. So check each status on the vendor page before you put a model in a roadmap.
Two items were still open when we checked on November 2, 2026.
- Gemini 4 Carbon, which Google announced in October 2026 without a price, model id or availability date.
- Kimi K3.1 Pro, with a 1M context window and weights due by November 4, 2026, though they had not shipped on November 2.
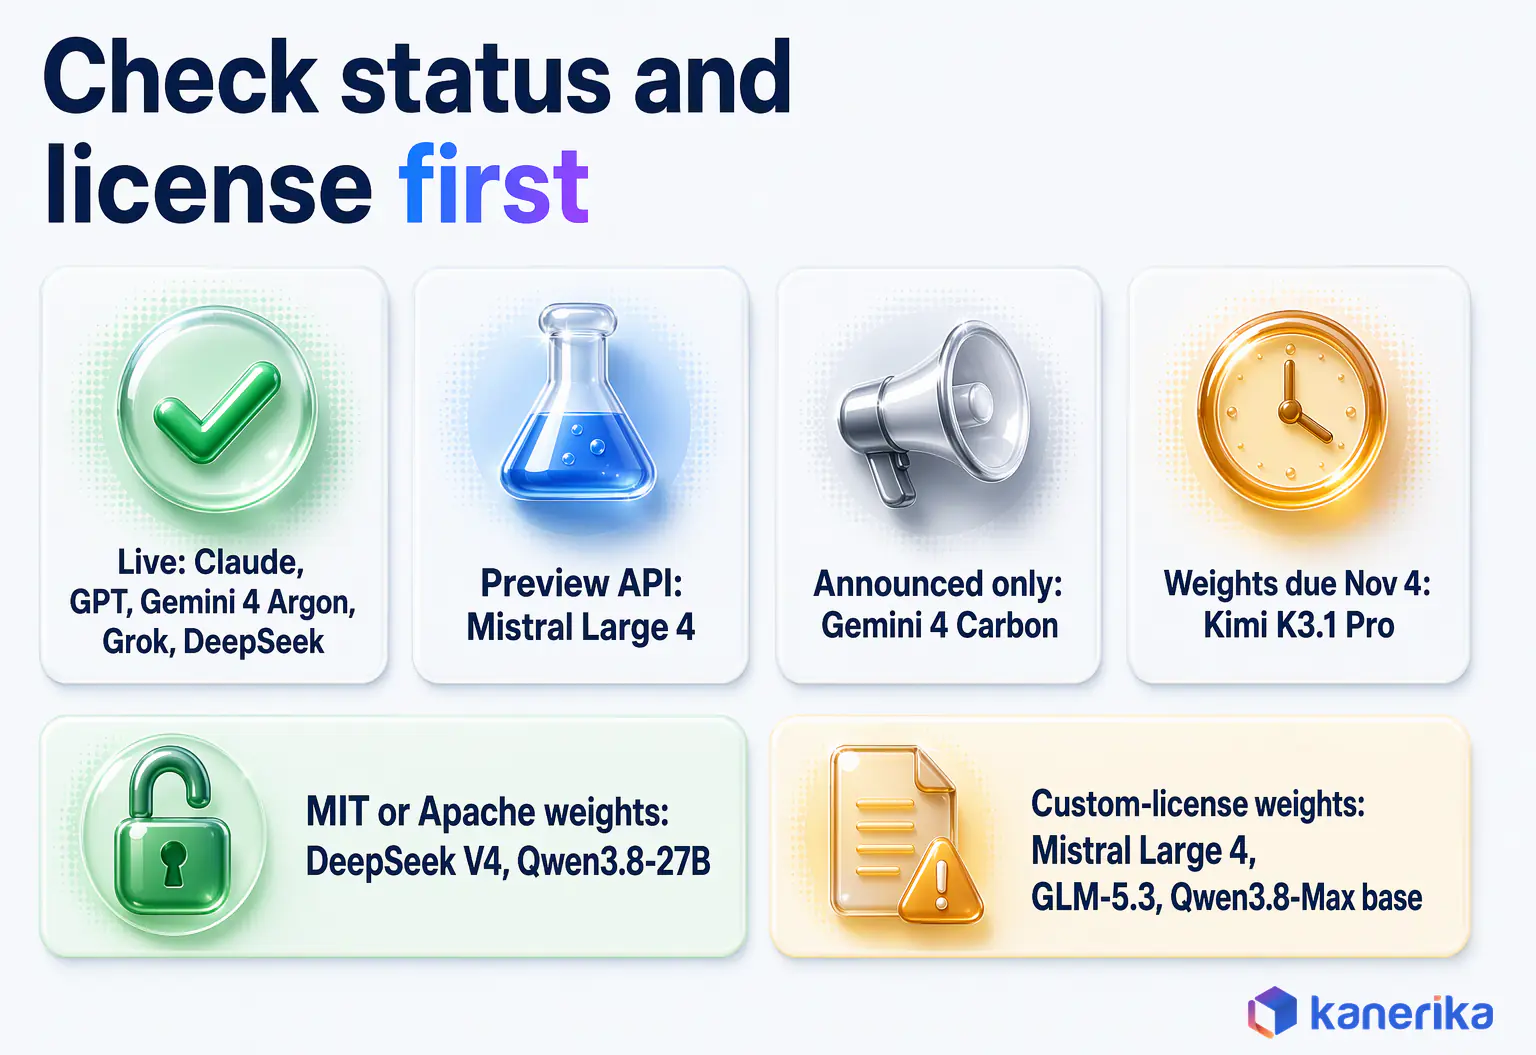
Two earlier gaps have closed, since the Qwen3.8-Max base model and Mistral Large 4 now have public weights under custom licenses. Meta’s newest listed model is Muse Spark 1.1 from July 9, 2026, with no current Llama release confirmed.
Open-Weight vs Closed LLMs: What You Can Actually Download
Open weights mean you can download a model’s trained parameters and then run it on your own hardware. Open source goes further, because it also covers training code, data or a license that permits broad reuse. API-only models stay on the vendor’s servers, so you reach them through a paid endpoint.
The difference matters for data residency and cost control, as well as vendor risk. Here is where the November 2026 models stand on that scale.
- Downloadable under a standard license, which covers Qwen3.8-27B under Apache 2.0 and DeepSeek V4-Pro and V4.1-Flash under MIT.
- Downloadable under a custom license, which covers Mistral Large 4, GLM-5.3 and the Qwen3.8-Max base model, so check each license before commercial use.
- Weights due but not shipped, which covers Kimi K3.1 Pro as of November 2, 2026.
- Closed and API-only, which covers Claude, GPT, Gemini and Grok.
Self-hosting gives you control over where data lives and when the model changes. In return, you take on GPU capacity, scaling, security patching and model updates. For that reason, many teams run private LLMs for sensitive workloads and keep a managed API for everything else.
Consider a bank that must keep customer records inside one country. A closed API works only if the vendor processes data in that region, whereas Qwen3.8-27B can run on the bank’s own servers. In exchange, the bank must staff GPU operations for as long as the model stays in use.
For the full open model field, read our guide to open-source LLMs. Regulated sectors that need national or regional control should also review sovereign AI requirements before choosing.
LLM API Pricing Compared: What the Top LLMs Cost at Scale
API pricing is the per-token rate you pay each time a model reads your prompt and writes a response. So compare cached, long-prompt and peak rates as well as list prices.
The table below uses only figures from vendor pricing pages. When a vendor page did not state a figure, the cell says so.
| Model | Input | Cached input | Output | Long-prompt or dated rule |
|---|---|---|---|---|
| Claude Opus 5.5 | $4 | $0.20 (cache read) | $20 | Not stated |
| Claude Fable 5.1 | $10 | Not stated | $50 | Not stated |
| Claude Sonnet 5.5 | $2 | $0.10 (cache read) | $10 | Not stated |
| Claude Haiku 5.5 | $0.10 | $0.01 (cache read) | $0.50 | Output $2.50 once prompts pass 100K tokens |
| GPT-6.1 Sol | $2 | $0.10 | $10 | Once a prompt passes 272K, 2x input and 1.5x output |
| GPT-6.1 Terra | $1 | $0.05 | $5 | Over 272K tokens, 2x input and 1.5x output |
| GPT-6 Astra | $10 | $1.00 | $50 | Not stated |
| GPT-6 Luna | $0.10 | $0.01 | $0.50 | Not stated |
| Gemini 4 Argon | $2 | Not stated | $10 | Then $4 / $20 from Dec 1, 2026 |
| Gemini 3.8 Flash | $0.75 | Not stated | $3.75 | Then $1.50 / $7.50 after Dec 31, 2026 |
| Grok 4.7 | $2 | $0.50 | $6 | Once a prompt reaches 200K, $4 / $12 for the whole request |
| DeepSeek V4-Pro | $0.66 (off-peak) | Not stated | $1.98 (off-peak) | Off-peak rate shown |
| DeepSeek V4.1-Flash | $0.15 (off-peak, cache miss) | Not stated | $0.60 (off-peak) | Double during weekday peak hours |
| Mistral Large 4 | $0.7 | Not stated | $2.1 | Not stated |
Dated and Conditional Price Changes
Four dated or conditional rules change these numbers.
- Gemini 4 Argon doubles to $4 input and $20 output on December 1, 2026.
- Gemini 3.8 Flash doubles to $1.50 and $7.50 after December 31, 2026.
- DeepSeek V4.1-Flash bills double during weekday peak hours in UTC.
- Claude Haiku 5.5 output rises from $0.50 to $2.50 above 100K prompt tokens.
Across the ranked tiers, input prices run from $0.10 to $10 per million tokens, a 100x spread. That range is why a routing layer such as an LLM gateway can pay off once volume grows.
Cost per Completed Task
Token price alone hides retries and human review. A better unit is the cost of one task that passes your quality check, and it takes four steps to work out.
- First, multiply input tokens per task by the input price.
- Add output tokens per task times the output price.
- Divide that sum by the success rate on your test set.
- Finally, add the cost of human review for outputs that need it.
Here is an illustrative example with assumed numbers. A task with 2,000 input and 500 output tokens on GPT-6.1 Sol costs $0.004 plus $0.005, or $0.009 per attempt. At an assumed 90% success rate, that comes to about $0.01 per completed task before review.
Best LLM by Use Case
Which of the top LLMs fits depends on the job, so start each use case with a short list of first tests.
Coding and Agents
Claude Opus 5.5, GPT-6.1 Sol and Claude Sonnet 5.5 are the first three to test for coding agents. Opus 5.5 carries Anthropic’s recommendation for most work, while Sol and Sonnet 5.5 cost half as much per input token.
Run every candidate through the same repository tasks and the same tool harness, because agent results shift with the tooling around the model. Our GPT Codex vs Claude Code comparison covers the coding tools built on top of these models.
Enterprise RAG and Search
Retrieval-augmented generation grounds answers in your own documents, so retrieval quality often matters as much as the model. Start with a mid-price model such as Sol or Sonnet 5.5, then tune the pipeline with advanced RAG patterns. If answers still miss domain terms, our RAG vs fine-tuning guide explains when training helps.
Extraction and High-Volume Work
For classification, tagging and field extraction, test GPT-6 Luna, Claude Haiku 5.5 and DeepSeek V4.1-Flash first. All three cost $0.60 or less per million output tokens at their lowest listed rates, so retries stay cheap.
Kanerika Service
LLM Development and Evaluation
Kanerika shortlists, tests and builds LLM applications on your own tasks and data.
Explore LLM DevelopmentLong Documents
Contracts, filings and large codebases call for a 1M-class window. GPT-6.1 Sol, the Claude 5.5 family, Gemini 4 Argon and DeepSeek V4.1-Flash all list about one million tokens. Even so, a large window does not guarantee accurate recall, so test effective accuracy on your longest real documents.
Multimodal Work
Many teams need models that read scanned forms, charts or screenshots, in addition to plain text. Here is what the vendor pages we opened on November 2, 2026 say about inputs.
- Anthropic’s overview says all current Claude models take text and image input and return text.
- OpenAI’s model page says its latest models take text and image input and return text.
- Mistral describes Large 4 as natively multimodal, with a step up in image understanding.
- The Qwen3.8-27B model card calls it a native vision-language model that understands images and videos.
The Anthropic and OpenAI pages make no audio input claim, and we did not confirm Gemini 4 Argon’s input types. So check audio and video needs on the vendor’s own model page before you test.
If you need to generate images, video or speech, the language model ranking above is the wrong list. Artificial Analysis keeps separate boards for those, and ranks text-to-image and video models by Elo from blind human preference votes.
Private Deployment
When data cannot leave your environment, start with a model that has public weights. Qwen3.8-27B under Apache 2.0 and DeepSeek V4-Pro and V4.1-Flash under MIT carry standard licenses.
GLM-5.3, Mistral Large 4 and the Qwen3.8-Max base model are public too, but under custom licenses, so check the license before commercial use. Plan GPU capacity and patching before the pilot starts, and use our open-source LLM guide to compare serving options.
How to Choose and Test an LLM for Your Business
Choosing an LLM works best as a short, fixed experiment with a scorecard agreed before testing starts. That way, a strong demo cannot outweigh weak results on the tasks you actually run.
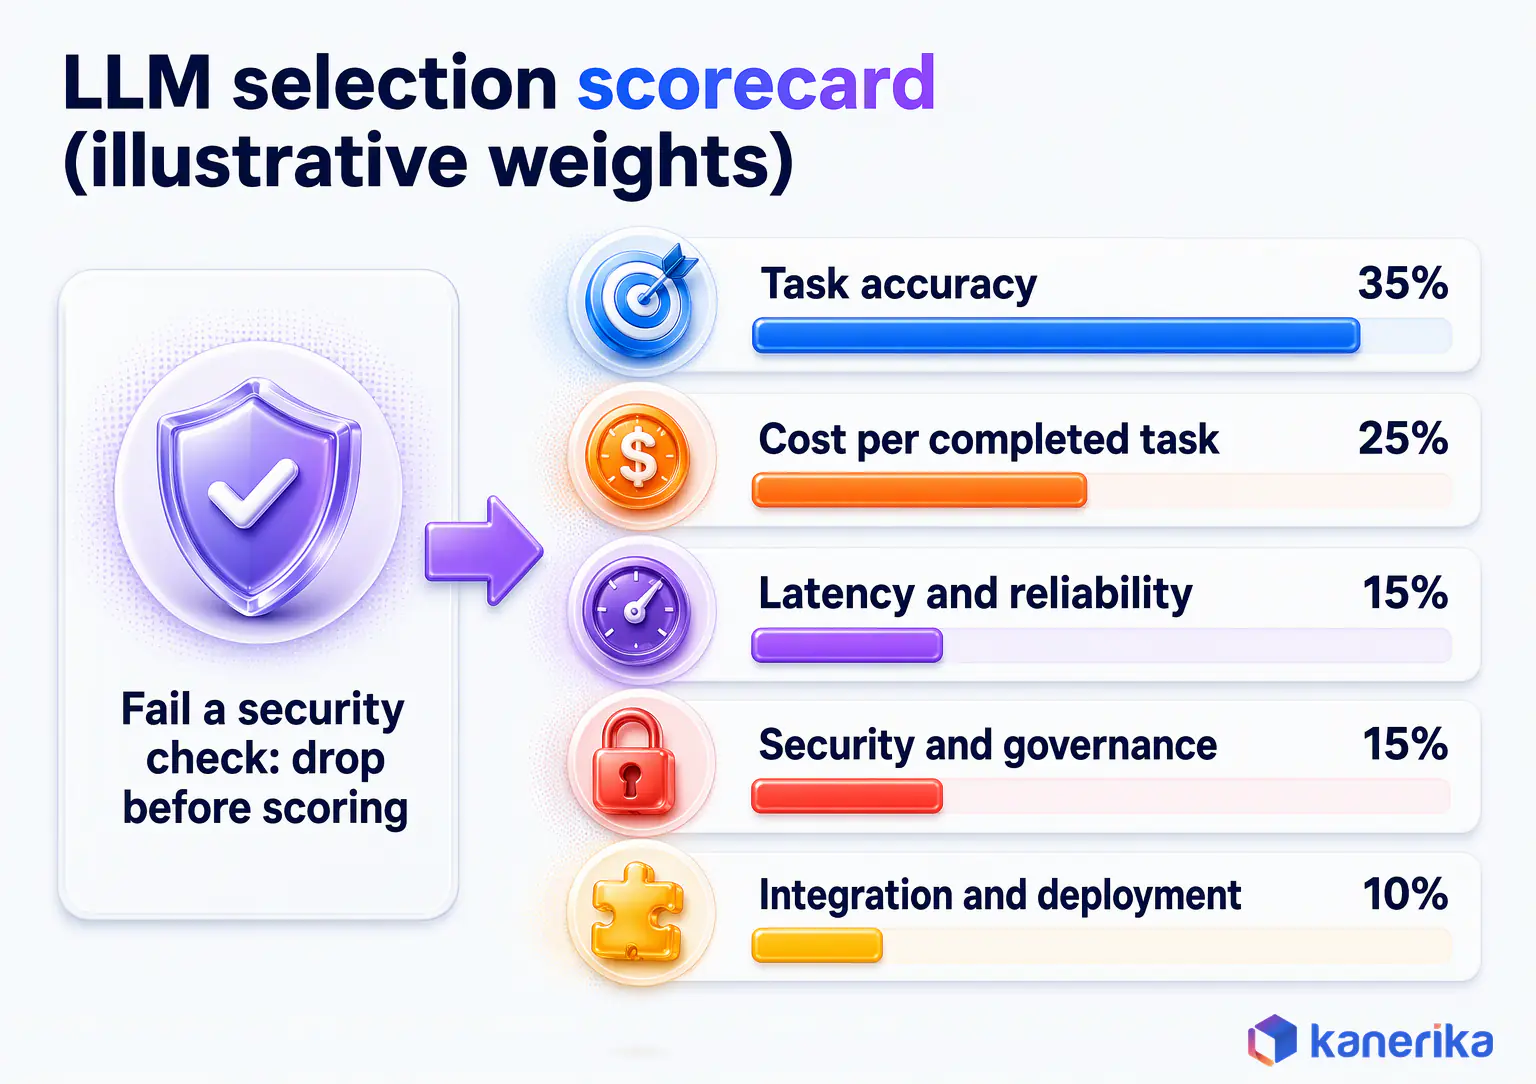
The weights below are illustrative, so adjust them to your own priorities. Also drop any model that fails a mandatory security check before you score it at all.
| Criterion | Illustrative weight | What to measure |
|---|---|---|
| Task accuracy | 35% | Correct answers on your own test set, such as valid extractions |
| Cost per completed task | 25% | Token cost divided by success rate, as well as review time |
| Latency and reliability | 15% | p95 latency as well as error rate |
| Security and governance | 15% | Data terms, together with access controls and audit logs |
| Integration and deployment | 10% | SDKs, regions and hosting options |
A Two-Week Test Plan
A two-week plan keeps the test small enough to finish and large enough to trust. The sizes and thresholds below are a suggested starting point, so change them to fit your risk level.
- In days 1 to 3, build a test set of about 200 real tasks, including 30 hard edge cases, and record a baseline.
- Over days 4 to 7, run the same tests across three or four models with fixed settings.
- During days 8 to 10, measure cost per completed task, p95 latency, failure rate and security results.
- By days 11 to 14, re-run the top two on 50 held-back tasks, then pick a primary model and a fallback.
Agree the pass criterion before day 1. A workable rule is that at least 95% of outputs pass schema validation and at least 90% are correct. The model must also stay within your p95 latency target.
Of the models that pass, pick the lowest cost per completed task as primary. Make the runner-up the fallback, ideally from a different vendor, and write down why each one won.
Route Work Across More Than One Model
One model rarely wins every task, so many teams route requests by difficulty instead. Send simple work to a budget tier first. Escalate to a stronger model only on clear triggers, such as a failed format check.
A gateway in front of the models handles this routing and gives you one place for logging, rate limits and fallbacks.
Here is a worked routing rule. It is a suggested approach built from the list prices above, so treat it as a template for your own tests.
| Request class | First model | Escalate to | Escalate when |
|---|---|---|---|
| Classification, tagging and field extraction | GPT-6 Luna or Claude Haiku 5.5 ($0.10 / $0.50) | GPT-6.1 Sol | Output fails the schema after one retry, or a Haiku prompt passes 100K tokens |
| Drafting, RAG answers and support replies | GPT-6.1 Sol or Claude Sonnet 5.5 ($2 / $10) | Claude Opus 5.5 | Output fails the schema after one retry, or a reviewer flags the answer |
| Multi-step agents and hard reasoning | Claude Opus 5.5 ($4 / $20) | Claude Fable 5.1 or GPT-6 Astra | The task class still fails your test set on Opus 5.5 |
The decision rule is the same on every route. Start at the cheapest tier that passed your test set for that class, and move up one tier only on a logged trigger.
Review the escalation rate each week. As a rough guide, a route that escalates more than one request in five probably belongs a tier higher. The same rule can live in a small config file.
# Suggested routing rule (illustrative)
routes:
  extract_or_classify:
    model: gpt-6-luna            # or claude-haiku-5-5 under 100K
    escalate_to: gpt-6.1-sol
  draft_or_rag_answer:
    model: gpt-6.1-sol           # or claude-sonnet-5-5
    escalate_to: claude-opus-5-5
  agent_or_hard_reasoning:
    model: claude-opus-5-5
    escalate_to: claude-fable-5-1
checks:
  schema: strict_json            # required fields, types, enums
  retries_same_model: 1          # append the validation error
  on_second_failure: escalate
  on_fallback_failure: human_review_queue
Add a Schema Validation and Fallback Check
Validate every output against a schema before it reaches a user or another system. A simple fallback check runs in four steps.
- Parse the response as JSON and check required fields, types and allowed values.
- On a failure, retry once on the same model with the validation error added to the prompt.
- If the retry fails, send the request to the route’s escalation model and log both failures.
- If that call also fails or the provider times out, return a safe error and queue the item for human review.
Monitor After Launch
Vendors retire models on fixed dates, so pin model versions in production and track deprecation notices. OpenAI retired gpt-4-turbo, o1, o3-mini and gpt-4o-2024-05-13 on October 23, 2026. It retires gpt-5, o3 and o3-pro on December 11, 2026, then the GPT-4o and GPT-4.1 snapshots on January 14, 2027.
Re-run your test set at least once a quarter and whenever a provider ships a new version. Also track drift, cost and error rates in production, because a silent model update can change answers overnight. Keep a changelog of each version switch and the test results behind it, so that an audit can trace why a model changed.
LLM Security, Privacy and Data Residency Checks
Security review decides whether a model can touch real data, so run it in parallel with quality testing. Use these five checks as a minimum, then extend them with your own LLM security standards.
- Retention and training terms, including whether the provider trains on API data and how long it keeps prompts.
- Processing region, so that prompts and outputs stay in the jurisdictions your rules allow.
- Prompt injection defenses for RAG pipelines and tool calls, tested with hostile inputs.
- Least-privilege access for agents, as well as human approval before high-impact actions.
- Audit logs for every model call, kept at least as long as compliance reviews require.
For instance, a support agent that can issue refunds should wait for a human click before any money moves. Likewise, a RAG assistant should only retrieve documents the signed-in user is already allowed to open.
On-Demand Webinar
Strategies to Reduce LLM Security Risks
A Kanerika session on prompt injection, data leakage and access controls for LLM applications in production.
Watch the Webinar →Red-team testing before launch finds injection paths that normal tests miss. Beyond single projects, policy for access, monitoring and approvals belongs in an AI governance program that covers every model you run.
How Kanerika Helps Enterprises Pick and Run the Right LLM
Kanerika builds with whichever model fits the job and keeps that choice testable as vendors change. Our LLM development services follow the IMPACT methodology, which takes each project from scoping to live deployment with defined checkpoints.
In practice, the work runs in five stages, and each one ends with a decision the business owner signs off. As a result, model choice stays a business decision backed by test evidence, and the client can see why one model beat another.
- Scope the use case and the acceptance threshold with the business owner before any build starts.
- Shortlist two to four models from the tiers above, then test them on the client’s own documents and tasks.
- Ground the chosen model with retrieval over client data through RAG development, and fine-tune only when retrieval falls short.
- Govern and secure it with kanGovern and kanGuard policies on Microsoft Purview, plus Susan for PII redaction before prompts leave the network.
- Deploy, monitor and re-test as vendors ship new versions, while FLIP keeps the underlying data pipelines clean and AI-ready.
Three habits keep this stable once a model is live. Pin model versions, keep the evaluation set under version control and route by task, so a model change touches one route at a time. Our generative AI teams apply the same rules across chat, search and document workflows.
Talk to Kanerika
Choosing an LLM for Production?
Talk to Kanerika about shortlisting, testing and governing the right model for your workload and data.
Schedule a Demo →A typical shortlist mixes one premium model, one mid-price model and one budget or open-weight model. That way, the test shows exactly what each step up in price buys for the client’s own tasks.
When the budget model passes, the client saves on every call. When it fails, the premium tier has proven it is worth the price.
Case Study: LLM-Powered Vendor Agreement Processing
The client was a real estate developer backed by a vast Middle-Eastern public investment fund. Its teams reviewed vendor agreements by hand, which made the process slow and document-heavy.
The agreements sat as unstructured PDFs in Oracle Content Management, and each one had to be read and checked before teams could compare vendors. Its data environment also needed work before it was ready for Google Cloud Platform (GCP).
According to the case study page, accurate information extraction and question answering were the hard technical problem. That is the first failure a model test set should probe. A wrong clause or a missed field can skew every vendor decision built on it.
Kanerika first assessed the data environment and moved the workloads to GCP. Next, the team built a chat interface with detailed prompt criteria, so staff could query agreements and select vendors in plain language. Reviewers could then ask questions of the agreements directly.
That design put agreement review and vendor choice into one conversational workflow. As published, the project brought an 82% reduction in manual processing time and a 75% increase in cloud integration efficiency.
It also delivered a 90% boost in vendor selection. These figures come from the published case study page, so read the full vendor agreement processing case study for the details.
The same pattern carries over to other document-heavy processes such as contracts, claims or invoices. Test the shortlisted models on the client’s own files first, then ground the winner in that data and measure the time saved.
That way, the business case rests on results from its own work. Kanerika reports cost per completed task alongside accuracy, so finance and engineering see the same numbers.
Frequently Asked Questions
What are the top LLMs in November 2026?
The leading closed models are Claude Opus 5.5, GPT-6.1 Sol, Gemini 4 Argon, Claude Fable 5.1 and GPT-6 Astra. Strong open-weight options include Qwen3.8-27B and GLM-5.3, while DeepSeek offers low off-peak API prices. Opus 5.5 matches or beats Fable 5.1 on most benchmarks Anthropic lists. The best pick still depends on your workload and budget.
Which LLM is best for coding?
Claude Opus 5.5 is a strong first test for coding agents. Anthropic reports 66.4% on Terminal-Bench 4.0, ahead of Fable 5.1 at 55.8%. GPT-6.1 Sol and Claude Sonnet 5.5 cost less per token and suit everyday code work. Run each one on your own repository before you commit, since public scores use fixed settings.
Are open-weight LLMs good enough for business use?
Yes, for many workloads. Qwen3.8-27B ships under Apache 2.0 on Hugging Face, and GLM-5.3 weights are also public. These models let you keep data inside your own environment. You take on hosting, scaling and patching in return, so budget for GPU capacity and an engineering team before you switch from a managed API.
How much do the top LLMs cost per million tokens?
Prices range widely. Claude Opus 5.5 costs $4 input and $20 output per million tokens. GPT-6.1 Sol and Claude Sonnet 5.5 cost $2 and $10. GPT-6 Luna and Claude Haiku 5.5 start at $0.10 and $0.50. Premium tiers such as GPT-6 Astra and Fable 5.1 reach $10 and $50. OpenAI Batch pricing for Sol and Terra is 50% lower.
Which LLM has the largest context window?
GPT-6.1 Sol and GPT-6.1 Terra list 1,050,000 tokens. The Claude 5.5 family, Gemini 4 Argon and DeepSeek V4.1-Flash list about one million. Grok 4.7 lists 500,000. A larger window raises cost, because OpenAI and xAI bill long prompts at higher rates. Test answer quality on your real documents before relying on the full window.
What is the cheapest capable LLM API?
GPT-6 Luna and Claude Haiku 5.5 are the cheapest at $0.10 input and $0.50 output per million tokens. DeepSeek V4.1-Flash costs $0.15 and $0.60 off-peak, and double at peak. Measure cost per completed task, because a cheap model that needs retries or human review can cost more overall.
Can LLMs be fine-tuned for my industry?
Yes. Fine-tuning trains a base model on domain data such as contracts or clinical notes, which sharpens answers on specialist questions. Open-weight models give you the most control over this step. Many teams start with retrieval over their own documents first, then fine-tune only when retrieval alone cannot reach the accuracy they need.
How do I keep data private when using an LLM?
Start with the provider’s data retention and training terms. Confirm where prompts are processed and stored, and check rules such as GDPR. For strict requirements, a self-hosted open-weight model keeps data inside your environment. Many teams also mask personal data before prompts leave the network and log every model call for audit.
How should we test an LLM before production?
Build a test set from real documents, tickets and tasks. Run the same set across three or four shortlisted models with fixed settings. Score accuracy, valid output format, p95 latency and cost per completed task. Add security checks for prompt injection and data leakage. Repeat the test whenever a provider ships a new version.
How often should we review our LLM choice?
Review it every quarter at minimum. Providers change models and prices often. Gemini 4 Argon moves from $2 to $4 input per million tokens on December 1, 2026, and OpenAI retires several older models in December. Re-run your test set on current models so you avoid overpaying or missing a better fit.