TL;DR
In RAG vs fine-tuning, choose RAG when facts change or need citations, and choose fine-tuning when the facts are right but the format is wrong. RAG retrieves approved documents at query time, so the model’s weights never change. Fine-tuning trains the weights on examples, which makes it strong at behavior and weak at adding facts. Many enterprise systems use both, with RAG for knowledge and a small fine-tune for format. Check the provider’s lifecycle before you train, because OpenAI is winding down its fine-tuning platform and training jobs end January 6, 2027. Score a prompt baseline, RAG and any fine-tune on one shared evaluation set, then ship the cheapest option that passes.
Key Takeaways
- RAG fixes a knowledge gap: the model lacks current, private or citable facts, so you retrieve them at query time.
- Fine-tuning fixes a behavior gap: the model knows enough but answers in the wrong format, tone or label set.
- Research shows retrieval beats unsupervised fine-tuning for both existing and new knowledge, so do not train to add facts.
- A tuned hosted model lives only as long as its base model and platform, so keep training data portable across providers.
- Fine-tuning still runs on Microsoft Foundry, Google Vertex AI and open-weight models, while OpenAI’s platform takes new jobs only until January 6, 2027.
- Decide with one shared evaluation set that scores a prompt baseline, RAG and fine-tuning on faithfulness, format, p95 latency and cost.
One Support Assistant, Two Different Failures
Picture an internal IT support assistant in its second week of production. An employee asks how to request VPN access, and the assistant quotes last quarter’s policy, which has since changed. A minute later it drafts a ticket summary in free-form prose and ignores the three-field format the service desk requires.
Both answers look like “the AI got it wrong,” yet they are different problems. The first is a knowledge gap, because the model never saw the new policy. The second is a behavior gap, because the model never learned the house format.
That split is the RAG vs fine-tuning decision in miniature. Retrieval fixes the first problem but does little for the second. Fine-tuning fixes the second and handles the first poorly, so the real work is telling the two apart.
The same assistant returns throughout this guide as a worked case. It sits on top of the wider topic of retrieval-augmented generation, which this post does not repeat in full.
RAG vs Fine-Tuning: The Short Answer
Put simply, RAG changes what the model can see, while fine-tuning changes how the model behaves. Retrieval-augmented generation looks up relevant documents for each question and places them in the prompt. Fine-tuning runs extra training on examples, so the lesson is stored in the model’s weights.
That one difference drives every row in the table below. RAG keeps knowledge outside the model, where you can update it, restrict it by user and cite it. Fine-tuning bakes behavior into the model, where it costs nothing extra per query but must be retrained when the target moves.
Read each row as a trade-off rather than a score. A row that favors RAG for a policy assistant can still favor fine-tuning for a ticket classifier. For the simpler question of RAG compared with a standalone LLM, see our separate guide.
| Factor | RAG | Fine-tuning |
|---|---|---|
| What changes | The prompt: retrieved passages are added at query time | The model weights: trained on labeled examples |
| Best for | Policies, contracts, product facts and anything that changes | Fixed formats, label sets, tone and narrow repeatable tasks |
| Data needed | Approved documents, chunked and indexed | Input and ideal output pairs; OpenAI’s minimum is 10 examples |
| Freshness | Updates as soon as the index is refreshed | Frozen at training time until you retrain |
| Citations | Answers can point to the source passage | No built-in link from an answer to a source |
| Main risk | Retrieval misses and permission leaks in the index | Stale facts, training data resurfacing and base-model retirement |
When the Answer Is Both
Some systems fail in both ways at once, like the support assistant above. The usual order is to build retrieval first, because wrong facts do more damage than a messy format. Then measure whether a better prompt fixes the format before you pay for training.
A small fine-tune on top of RAG is a real option, yet it doubles the upkeep. You end up with an index to refresh and a model to retrain, each with its own tests. The hybrid section later in this guide covers the three common ways to combine them.
What RAG Changes, and Where It Breaks
RAG gives a general model a reference library it can consult before it answers. The idea comes from the 2020 paper by Lewis et al. on retrieval-augmented generation. It paired a language model with a vector index of Wikipedia. Enterprise RAG swaps Wikipedia for your own policies, contracts, tickets and product documents.
The model itself does not change. Because knowledge lives in the index, you can add a document in the morning and the assistant can cite it by the afternoon. You can also delete a document and know it is gone, which is far harder to promise once a fact sits inside trained weights.
This guide stays at the decision level rather than the build level. To compare frameworks and libraries for the build itself, see our roundup of RAG tools.
How a RAG Request Works
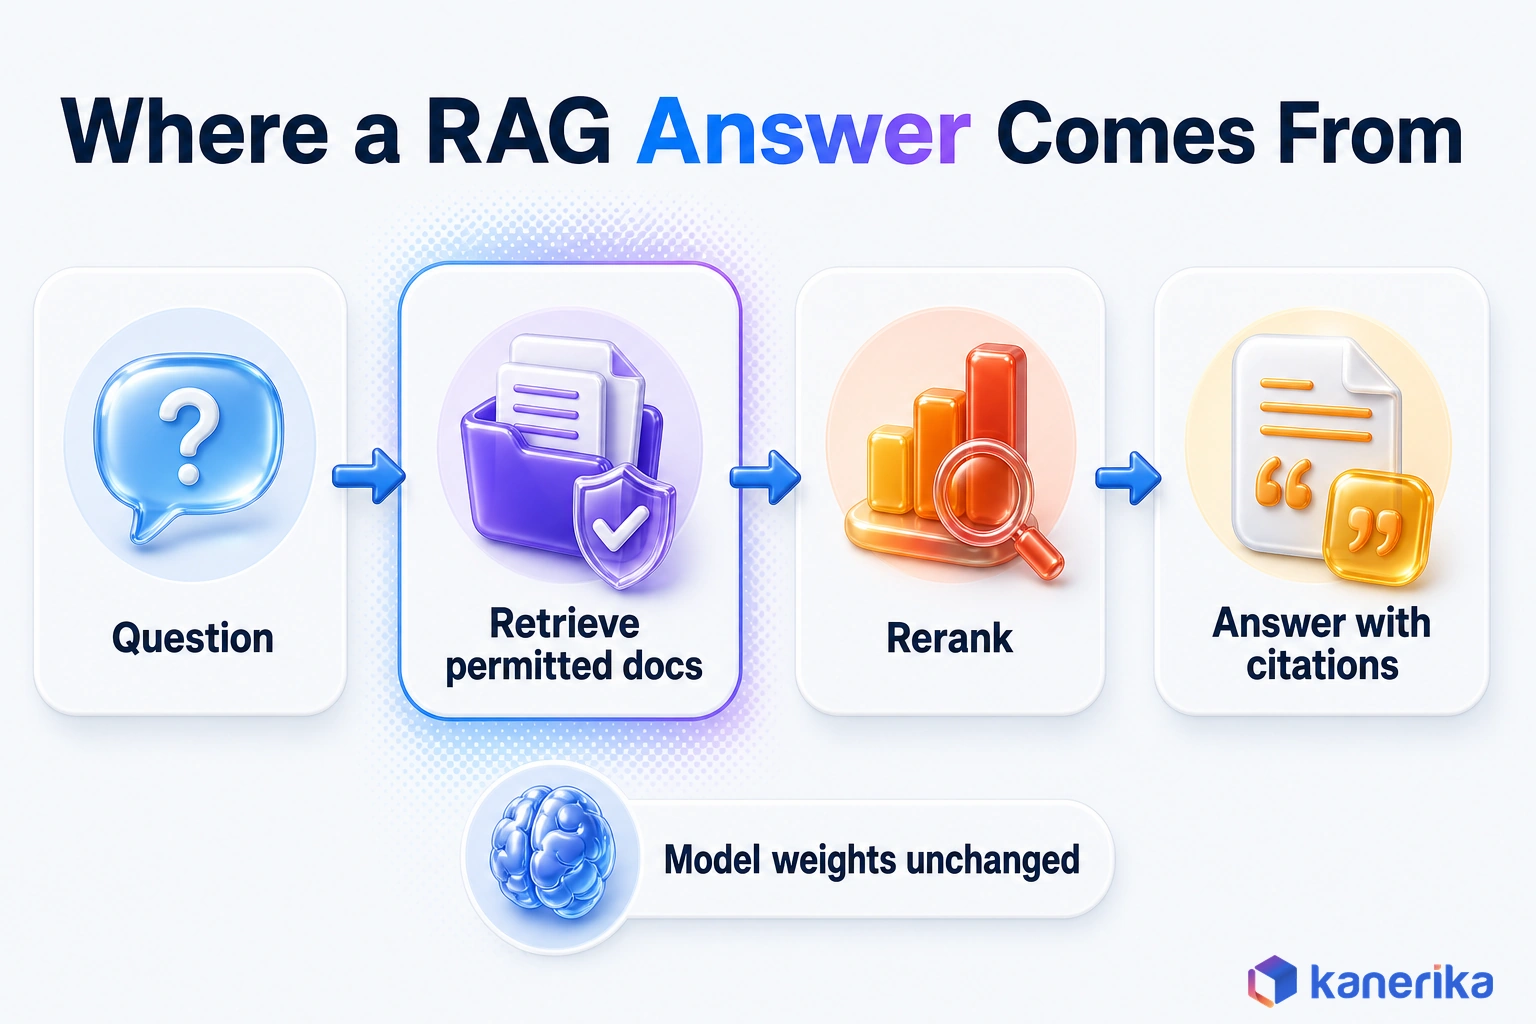
Every RAG answer follows the same short path, and each step sits outside the model’s weights. The model is only one component of the wider LLM architecture around it.
- Query: the user’s question is turned into a search, usually an embedding plus keywords.
- Retrieve: the system fetches candidate passages from the index, filtered to what this user may see.
- Rerank: a reranker orders the candidates by relevance and keeps the best few.
- Assemble: the top passages go into the prompt beside the question and the instructions.
- Answer: the model writes a reply that cites the passages it used.
Each hop is also a place where quality is won or lost. A strong model cannot rescue a passage that was never retrieved, so most RAG tuning happens in search rather than in generation.
Where RAG Breaks
RAG fails in predictable ways, and each one looks like a model problem from the outside. The fixes, though, live in search and data engineering, as the list shows.
- Retrieval misses: the right passage exists but never reaches the prompt. Fix it with hybrid search, a reranker or the methods in our guide to advanced RAG.
- Stale index: documents changed, but nobody re-indexed them. Fix it with change-triggered indexing and a named owner.
- Split answers: a rule and its exception land in different chunks, and only one is retrieved. Fix it by testing chunk size and overlap on real questions.
- Permission leaks: the index ignores who is asking, so one user sees another team’s files. Fix it by filtering on access rights at retrieval time.
- Added latency: retrieval and reranking add hops before the first word. Fix it with fewer passages, a lighter reranker or a cache.
For that reason, none of these failures is fixed by fine-tuning the generator. For chunking, Microsoft’s Azure AI Search chunking guidance suggests starting at 512 tokens with a 25% overlap, which is 128 tokens. Our guide to the RAG pipeline walks through debugging each stage.
What Fine-Tuning Changes, and What It Cannot Do
Fine-tuning teaches a model a habit rather than a reference. You show it many examples of an input and the exact output you want, and training adjusts the weights until that pattern becomes the default.
As a result, it is especially good at behavior. A tuned model can return a fixed JSON schema every time or follow a strict label set for ticket routing. It can also write in a regulated house style. Because the lesson lives in the weights, prompts get shorter, so per-query cost and latency usually fall.
What fine-tuning does not do well is keep facts current. If the VPN policy changes again next quarter, a tuned model keeps quoting the old one until someone builds new examples and retrains it.
Full Fine-Tuning, LoRA/QLoRA and Preference Tuning
Fine-tuning is a family of methods, and the cheaper ones changed the economics. LoRA, published in 2021, trains small adapter matrices instead of every weight. Its authors report 10,000 times fewer trainable parameters and three times less GPU memory than fine-tuning GPT-3 175B with Adam.
QLoRA went further in 2023 by quantizing the base model. Its authors fine-tuned a 65B model on a single 48GB GPU with full 16-bit task performance. Preference tuning such as DPO then steers style by ranking a preferred answer over a rejected one. Our guide to parameter-efficient fine-tuning methods covers each one in depth.
Why Fine-Tuning Is a Poor Way to Add Facts
Teams often reach for fine-tuning to “teach the model our data.” The evidence points the other way. In a 2023 comparison, Ovadia et al. found that RAG consistently outperformed unsupervised fine-tuning, both for knowledge the model had seen and for new knowledge.
The same study notes that language models struggle to learn new facts this way. A tuned model may also blend a trained fact with an older one, and it cannot show where an answer came from. Microsoft’s Foundry fine-tuning overview makes the same point, saying fine-tuning “doesn’t replace retrieval for current information.”
If the goal is “know our documents,” retrieval is the stronger default. For background on how LLM training works, from pre-training to tuning, see our separate guide.
Kanerika Service
LLM Development and Fine-Tuning
Kanerika builds and tunes LLM systems for behavior gaps such as fixed formats, label sets and house style, with training data kept portable across providers.
Explore LLM DevelopmentThe Model-Lifecycle Risk of Fine-Tuning a Hosted Model
A fine-tuned hosted model is tied to its base model and to the platform that serves it. When the provider retires either one, the tuned version goes with it, and you rebuild on whatever comes next.
This risk is now concrete. As of November 3, 2026, OpenAI’s supervised fine-tuning guide says the platform is “winding down” and no longer open to new users. Eligible existing customers can create training jobs until January 6, 2027, unless the base model shuts down earlier.
The shutdown dates are also staged. Fine-tunes of gpt-4.1-nano shut down on October 23, 2026, and gpt-4.1 and gpt-4.1-mini fine-tunes shut down on January 14, 2027. The OpenAI deprecations page shows how access narrowed. A May 7, 2026 notice closed training to organizations that had never fine-tuned, and a July 2, 2026 cut followed for those with no fine-tuned inference in the prior 60 days.
The lesson applies to every vendor, not only one. Before you train, write down the base model’s retirement date and who will redo the work when it arrives.
Where You Can Still Fine-Tune in Late 2026
Fine-tuning has not gone away; it has moved. The table lists the main routes, each checked against the vendor’s own page on November 3, 2026.
| Platform | Status checked November 3, 2026 | Source |
|---|---|---|
| OpenAI | Closed to new users; eligible customers create jobs until January 6, 2027 | OpenAI SFT guide |
| Microsoft Foundry | SFT, DPO and reinforcement fine-tuning, plus distillation; models include gpt-4.1, gpt-4o, o4-mini, gpt-oss-20b and Qwen3.8-27B | Foundry overview |
| Google Vertex AI | SFT on Gemini 3.5 Flash-Lite, 3.5 Flash, 3.1 Flash-Lite and the 2.5 Pro, Flash and Flash-Lite models; Gemini 4 Argon is not listed | Vertex AI tuning docs |
| Open-weight models | gpt-oss-20b, Mistral Small 4 and Qwen3.8-27B under Apache 2.0, tuned with LoRA on your own hardware | Model licenses; see open-source LLMs |
The verdict is simple. The portability of your training data matters more than the tuned weights, because clean examples move to a new base model and weights do not.
Strengths and Limits at a Glance
Each method is strong at a different job, and each strength comes with a condition. The table pairs every row with a concrete example or figure, so you can test it against your own case.
Kanerika Service
RAG Development Services
Kanerika designs permission-aware RAG systems with source citations, tuned chunking and reranking, and an evaluation set that proves each change.
Explore RAG Development| Dimension | RAG | Fine-tuning |
|---|---|---|
| Main strength | Current facts with citations, such as a policy changed this morning | Consistent output, such as the same three-field ticket every time |
| Data to start | Existing documents; Azure suggests 512-token chunks with 128-token overlap | Labeled pairs; OpenAI accepts a minimum of 10 examples |
| Access control | Filters passages by each user’s permissions at query time | None per user; everyone who calls the model gets the same weights |
| Per-query cost | Higher; 8,000 input tokens a query in our cost example | Lower; short prompts once the format is learned |
| Change cost | Re-index the changed document | Rebuild examples and retrain |
| Main limit | Only as good as retrieval | Weak at adding facts, per Ovadia et al. (2023) |
| Lifecycle | Swap the model and keep the index | Ends with the base model, as with gpt-4.1-nano on October 23, 2026 |
In practice each strength holds only while someone does the upkeep. RAG avoids retraining only while someone owns the index, and fine-tuning keeps prompts short only while the task stays stable.
Diagnose the Gap Before You Choose
The fastest way to settle RAG vs fine-tuning is to look at how the current system fails. Collect a few dozen real wrong answers, then sort each one by what went wrong rather than by how bad it looks.
Wrong or outdated facts point to a knowledge gap, while correct facts in the wrong shape point to a behavior gap. Many teams find both, and some find the task itself was never stated clearly.
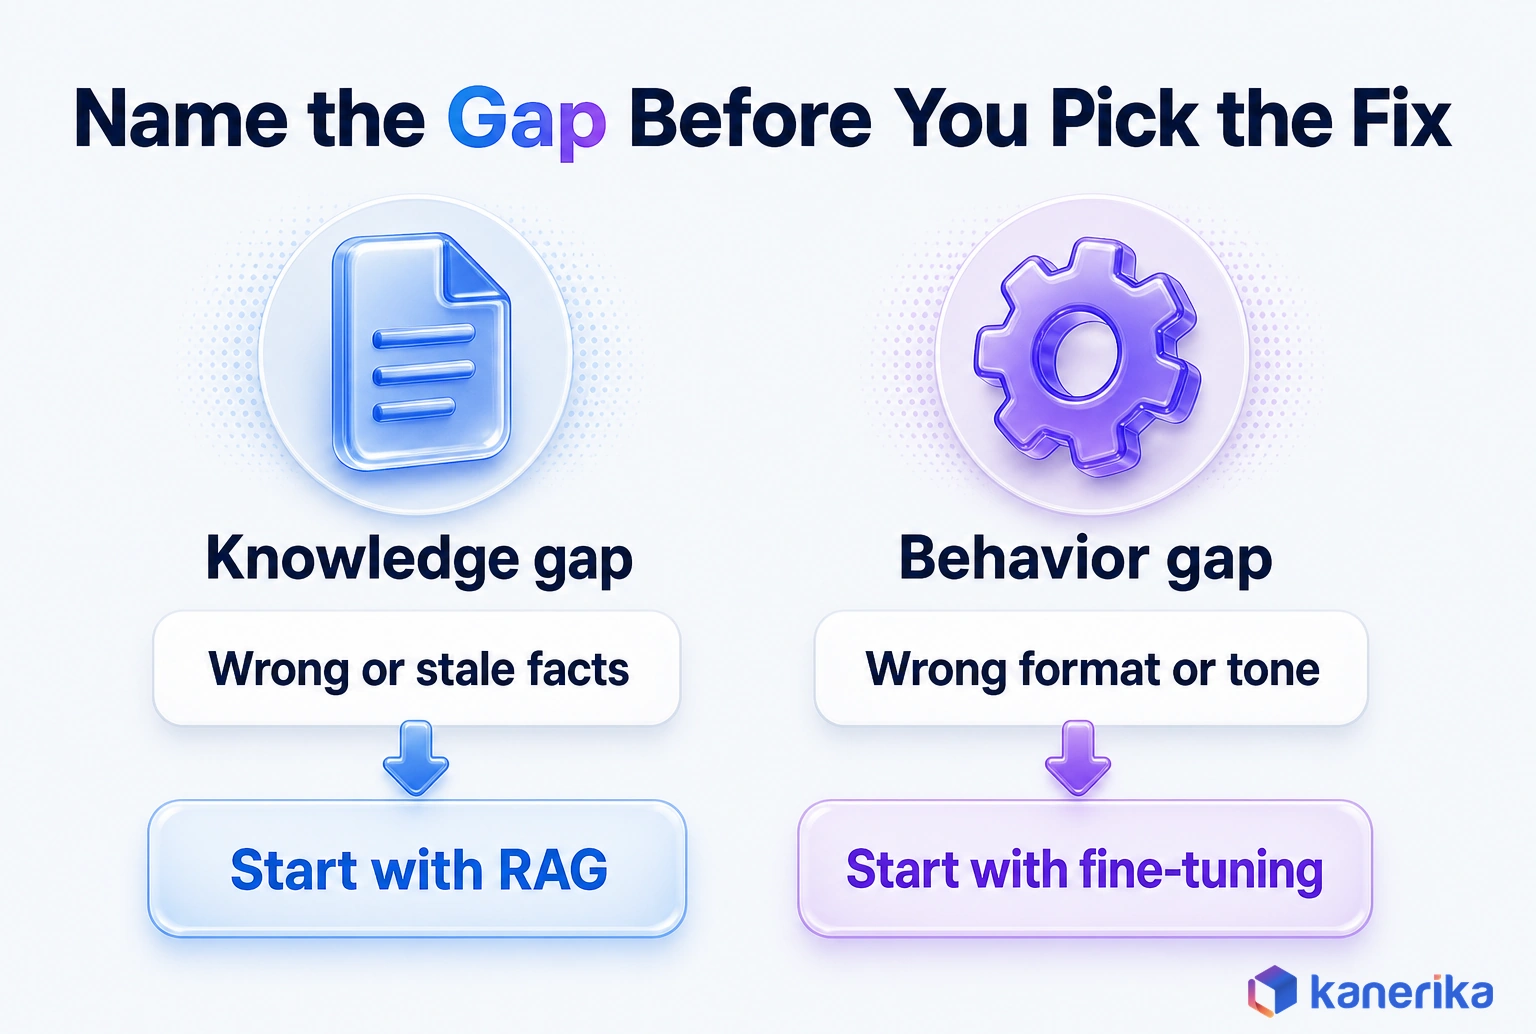
| Knowledge gap (start with RAG) | Behavior gap (start with fine-tuning) |
|---|---|
| Wrong, outdated or invented facts about your business | Right facts in the wrong format, tone or label set |
| Cannot say where an answer came from | Long instructions ignored on high-volume tasks |
| Answers differ by team because access rules differ | Output breaks a JSON schema the next system needs |
| Facts change weekly or monthly | The task is stable and repeats thousands of times |
When the failures fit neither column, the problem is the specification. A clearer prompt with worked examples usually fixes vague answers before either method is needed.
This step is cheap, yet it prevents the most expensive mistake in this decision: training a model to fix a search problem.
Try Prompting and Long Context First
Before you build either system, write the best prompt you can, with clear instructions and a few worked examples. If that clears your evaluation bar, you are done. If not, it becomes the baseline that RAG or fine-tuning must beat, and our prompt engineering best practices show how to write it.
Long context windows tempt teams to skip retrieval and paste whole manuals into the prompt. As of November 3, 2026, Claude Opus 5.5, Sonnet 5.5 and Haiku 5.5 each take 1M tokens. GPT-6.1 Sol takes 1,050,000, and Gemini 4 Argon takes up to 1M.
A bigger window is not a better reader, though. In the 2023 Lost in the Middle study, Liu et al. found accuracy was highest when the relevant text sat at the start or end. Accuracy dropped when it sat in the middle.
Long prompts also cost more on every call, as the worked example in the next section shows. Selecting the right few passages, the core of context engineering, usually beats sending everything. When the model needs live tools rather than documents, our comparison of MCP vs RAG covers that choice.
Talk to Kanerika
Not Sure Which Gap You Have?
Bring a sample of real failed answers. Kanerika’s engineers will help sort them into knowledge and behavior gaps and name the first fix to test.
Talk to an Engineer →RAG vs Fine-Tuning on Cost, Latency, Freshness and Security
Once the gap is clear, the operating profile decides how far to go. The four lenses below show where the money, the delay and the risk sit, so you can test them against your own volumes.
Cost: Upfront vs Per Query
RAG spends money on the indexing pipeline, the vector database and its hosting. It then pays again on every call, because each prompt carries retrieved passages. Fine-tuning moves spend to the front, into labeling, training runs, evaluation and, on some platforms, custom-model hosting.
The per-query side is easy to estimate with list prices. The example below is illustrative, with list prices checked November 2, 2026. It assumes 100,000 queries a month, each with 8,000 input tokens (question plus retrieved chunks) and 500 output tokens.
That volume comes to 800M input tokens and 50M output tokens a month. Each monthly cost is input tokens times the input price, plus output tokens times the output price.
| Model (list price per 1M input / output tokens) | Monthly cost |
|---|---|
| Claude Sonnet 5.5 or GPT-6.1 Sol ($2 / $10) | $2,100 |
| Claude Haiku 5.5 ($0.10 / $0.50, prompts up to 100k tokens) | $105 |
| Gemini 4 Argon ($2 / $10 through November 30, 2026; $4 / $20 from December 1, 2026) | $2,100, then $4,200 |
Now compare a long-context design that pastes a 300,000-token manual into every GPT-6.1 Sol call. That prompt crosses the 272K threshold, where input bills at 2x and output at 1.5x. Each query then costs about $1.21, or about $121,000 a month at the same volume.
The verdict is that model tier and retrieved-context size move the RAG bill more than the retrieval stack does. Fine-tuning cost sits in labeling, training runs and retraining, which each vendor prices per platform, so check its own page before you budget.
Latency
RAG adds steps before generation: a search, often a rerank and a longer prompt to read. How much that matters depends on the channel. A voice caller hears every retrieval hop as dead air, while an overnight batch job never notices.
A tuned model answers from a short prompt with no lookup, so it is usually faster per request. When latency is tight and knowledge is stable, that gap can decide the case. A tuned small language model can cut the delay further on narrow tasks.
Before you switch methods, try trimming the RAG path. Fewer retrieved passages, a lighter reranker or a cache for frequent questions often closes most of the gap.
Freshness and Maintenance
The two methods run on different clocks. A RAG system reflects a new document as soon as it is re-indexed, which can take minutes or hours. A fine-tuned model reflects only what it saw at training time.
That sets the maintenance rhythm. RAG work is triggered by content change, such as a new policy or a revised price list. Fine-tuning work is triggered by task change or measured drift, and each round means new examples, a new run and a new evaluation.
Both still need an owner, because an index nobody refreshes goes stale as surely as a model nobody retrains. Name the team that runs re-indexing or retraining before launch, not after the first wrong answer.
Datasheet
KlarityIQ: Your Document Intelligence Agent
See how KlarityIQ, Kanerika’s document intelligence agent, turns enterprise documents into structured, usable data that retrieval systems can search.
View the Datasheet →Security, Privacy and Auditability
Security often settles enterprise cases outright. With RAG, sensitive documents stay in a governed store, retrieval filters by each user’s permissions and every answer can cite its source for audit. With fine-tuning, training data enters the weights and can resurface for users who never had access to the source.
Each path also has its own attack surface. The OWASP Top 10 for LLM Applications lists LLM04:2025 Data and Model Poisoning, which covers fine-tuning data. It also lists LLM08:2025 Vector and Embedding Weaknesses, which applies directly to RAG indexes.
For a governance frame, NIST AI 600-1, the Generative AI Profile of the AI Risk Management Framework, was published on July 26, 2024. Our guide to securing LLM applications covers the controls, and our AI governance guide covers ownership and policy.
Teams that cannot send data to a hosted model at all should weigh private LLMs as the base for either approach.
Which Approach Reduces Hallucinations?
Hallucination is the failure most leaders raise in any RAG vs fine-tuning debate, so it deserves a direct answer. RAG reduces factual hallucinations more reliably than fine-tuning, because the model answers from supplied passages and can cite them. It does not remove them.
A RAG system still hallucinates when retrieval returns the wrong passage, nothing useful or two passages that disagree. The model may also blend retrieved text with its own memory. Requiring citations, and checking that each claim is supported by a cited passage, catches much of this.
Fine-tuning shapes format, not truth. It does not reliably add facts, as the Ovadia study showed, so on its own it is a weak hallucination fix.
It helps in one narrow way, by training the model to say “I don’t know” or to stay inside retrieved text. That is the idea behind RAFT, covered in the hybrid section below. For causes and controls beyond these two methods, see our guide to LLM hallucination.
A Six-Question Decision Framework
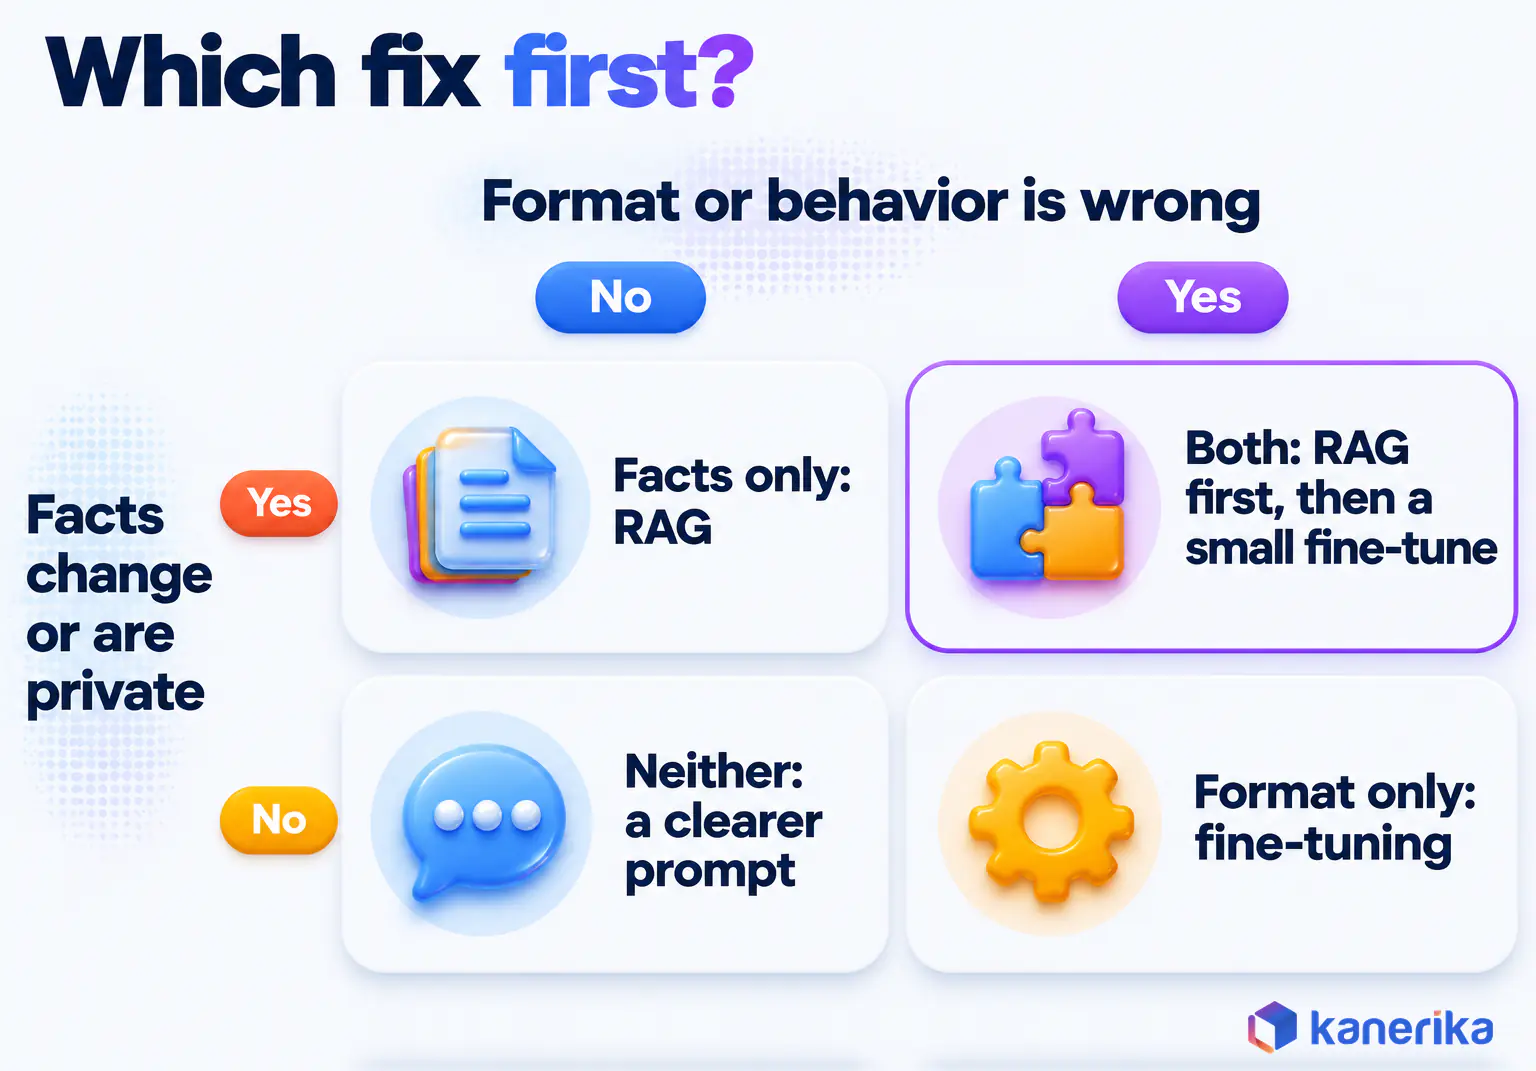
When the diagnosis is mixed, six questions turn the RAG vs fine-tuning choice into a plan. Answer them for one use case at a time, because a single company often needs RAG for one assistant and fine-tuning for another.
- Do answers depend on facts that change or are private? If yes, start with RAG.
- Must answers cite their sources? If auditors or users need to check, RAG is required.
- Is the failure about format, tone or behavior? If facts are right but the shape is wrong, fine-tuning fits.
- How much labeled data exists? OpenAI’s guide requires at least 10 examples, yet quality matters more than volume, so start with a small, clean set.
- What are the latency and per-query cost budgets? Tight budgets at high volume lean toward a tuned model.
- Who owns retraining or re-indexing? If nobody can retrain on a schedule, avoid a design that depends on it.
Two “RAG” answers and no behavior problem means you build retrieval and stop. A behavior failure on stable knowledge means you tune. Mixed answers lead to the worked example below.
Worked Example: An IT Support Assistant
Return to the assistant from the opening, the one that quoted an old VPN policy and ignored the ticket format. Run it through the six questions.
IT policies change every quarter and some are restricted to certain teams, so question one says RAG. Auditors want to know which policy an answer used, so question two says RAG with citations. The ticket format failure is behavior, so question three flags a possible fine-tune.
The service desk keeps a large archive of past tickets in the right format, which answers question four. Latency matters but is not extreme for an internal tool, and the knowledge team already owns the policy library.
The plan therefore follows directly. Build RAG first, with permission-aware retrieval and citations, and then measure format compliance on the shared evaluation set. Add a small fine-tune for ticket format only if the evaluations show a gap that a better prompt cannot close.
Recommended Starting Point by Enterprise Use Case
Common enterprise use cases tend to land in the same place, which gives a sensible default before any testing. Treat the table as a starting point, and let your evaluation set confirm it. For retrieval systems in production, see these RAG applications.
| Use case | Start with | Why | Risk note |
|---|---|---|---|
| Policy and knowledge Q&A | RAG | Facts change and answers need sources | Enforce document permissions in retrieval |
| Customer support | RAG, then optional fine-tune | Product facts change; reply style can be tuned | Route low-confidence answers to a person |
| Contract and document extraction | Fine-tuning | Fixed fields and formats repeat at volume | Validate outputs against a schema |
| Classification and routing | Fine-tuning | A stable label set suits trained behavior | Retrain when labels change |
| Regulated reporting | RAG with citations | Every statement must trace to a source | Keep sensitive data out of training sets |
| Code assistant on internal APIs | RAG | Internal APIs change with each release | Index only current, approved docs |
The case study near the end of this guide is the support row in practice. Grounding in current knowledge came first, and evaluations decide whether a second step is needed.
Common Mistakes When Choosing RAG vs Fine-Tuning
These mistakes come from treating the choice as a technology preference instead of a fix for a specific failure. Each one has a simple fix.
Checklist
Generative AI Checklist
Work through the data, security, evaluation and ownership checks to settle before a generative AI system goes into production.
Get the Checklist →- Fine-tuning to add facts. Retrieval beats unsupervised fine-tuning for knowledge, so put facts in an index.
- Skipping the baseline. Without a prompt-only score, nobody can tell whether a new system is better or only different.
- Ignoring permissions in the index. A RAG system that ignores who is asking becomes a data leak with a chat window, so filter at retrieval.
- Training on a platform with a near end date. Check the base model and platform retirement dates, and keep the data portable.
- Treating long context as free. A 300,000-token prompt costs about $1.21 a query in our example, so retrieve a few passages instead.
- Leaving re-indexing without an owner. A stale index fails exactly like an outdated model, so name the team before launch.
- Building a hybrid by default. Two systems mean two maintenance loops, so add the second only when evaluations demand it.
Most of these share one root cause. Each team picked a method before it measured the failure, so the diagnosis and evaluation steps in this guide are the cheapest insurance available.
That fix also compounds over time. Gap labels and the evaluation set carry over to the next use case, so the second decision starts from evidence, not a new debate.
Combining RAG and Fine-Tuning
Hybrids exist because the two methods fix different gaps, so a system with both gaps can use both. The catch is that every combination adds a component to build, monitor and evaluate.
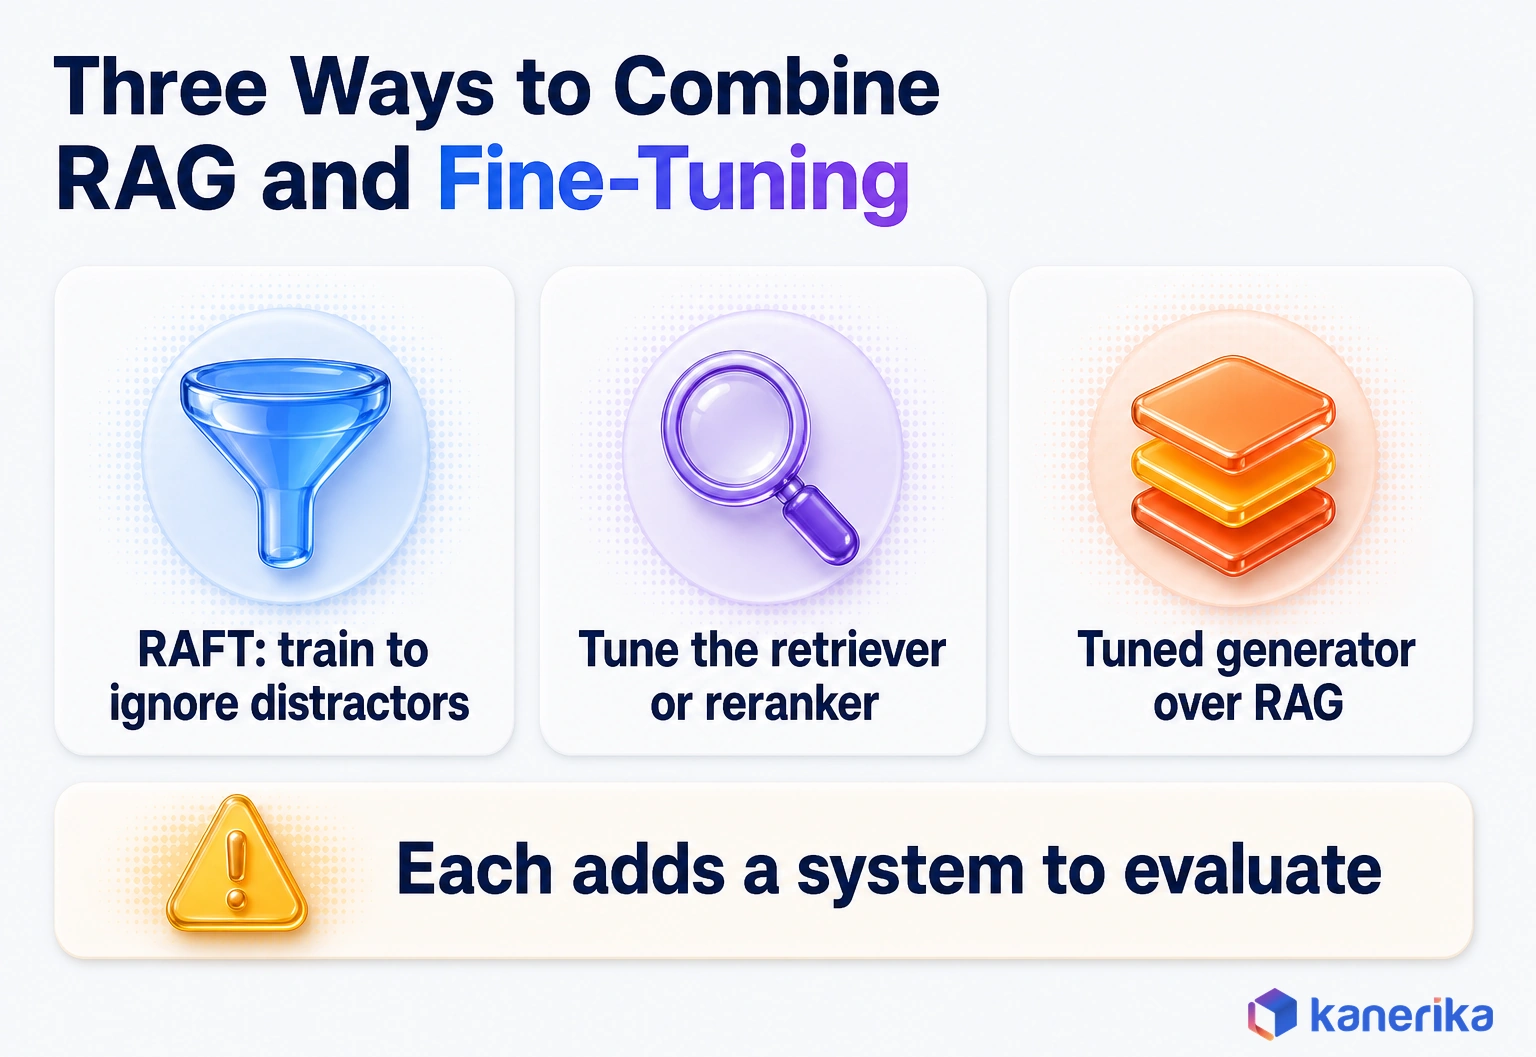
Use a hybrid when evaluations show that a single method leaves a measurable gap, not because it sounds more complete. The three patterns below cover most enterprise cases.
Retrieval-Augmented Fine-Tuning (RAFT)
RAFT, a 2024 method from Zhang et al., fine-tunes a model to work better with retrieval. Training mixes relevant documents with “distractor” documents, and the model learns to ignore the distractors and cite the relevant passage.
Picture a contracts assistant that retrieves the right clause along with three similar clauses from other agreements. A RAFT-style model is trained to answer from the clause that matches and to set the others aside.
RAFT fits when retrieval returns the right passage but the model still gets distracted by the noise beside it.
Tuning the Retriever or Reranker
Sometimes the best fine-tune never touches the generator. Training the embedding model or the reranker on your own question and passage pairs teaches search what “relevant” means in your domain.
In an IT help desk, for example, “VPN token” and “MFA reset” can look alike to a general embedding model. To your team they are different requests. Labeled question and passage pairs from past tickets teach the retriever that difference.
This attacks retrieval misses directly, which is where many RAG systems lose accuracy. It also leaves the generator free to change, so a model swap does not undo the work.
A Fine-Tuned Generator Over RAG
The most common enterprise hybrid keeps RAG for knowledge and tunes the generator for behavior, such as a ticket format or a regulated tone. It works well, but it doubles the maintenance surface.
You now have an index to refresh and a model to retrain, with two sets of evaluations that must both pass, so budget for both owners before you build. Systems that let an agent decide when and where to retrieve go one step further, as our guide to agentic RAG explains.
How to Evaluate Before You Commit
An evaluation set is what turns this decision from opinion into evidence. The same questions, scored the same way, let a prompt baseline, a RAG build and a fine-tune compete on equal terms.
- Build one evaluation set from real questions. Pull them from logs or tickets, with the correct answer and an acceptable source for each.
- Score a prompt-only baseline. This is the bar every other option must clear.
- Score a RAG build. Measure retrieval and answer quality separately, so you know which one failed.
- Score a fine-tune, if the diagnosis points to behavior. Use a held-out slice the model never trained on.
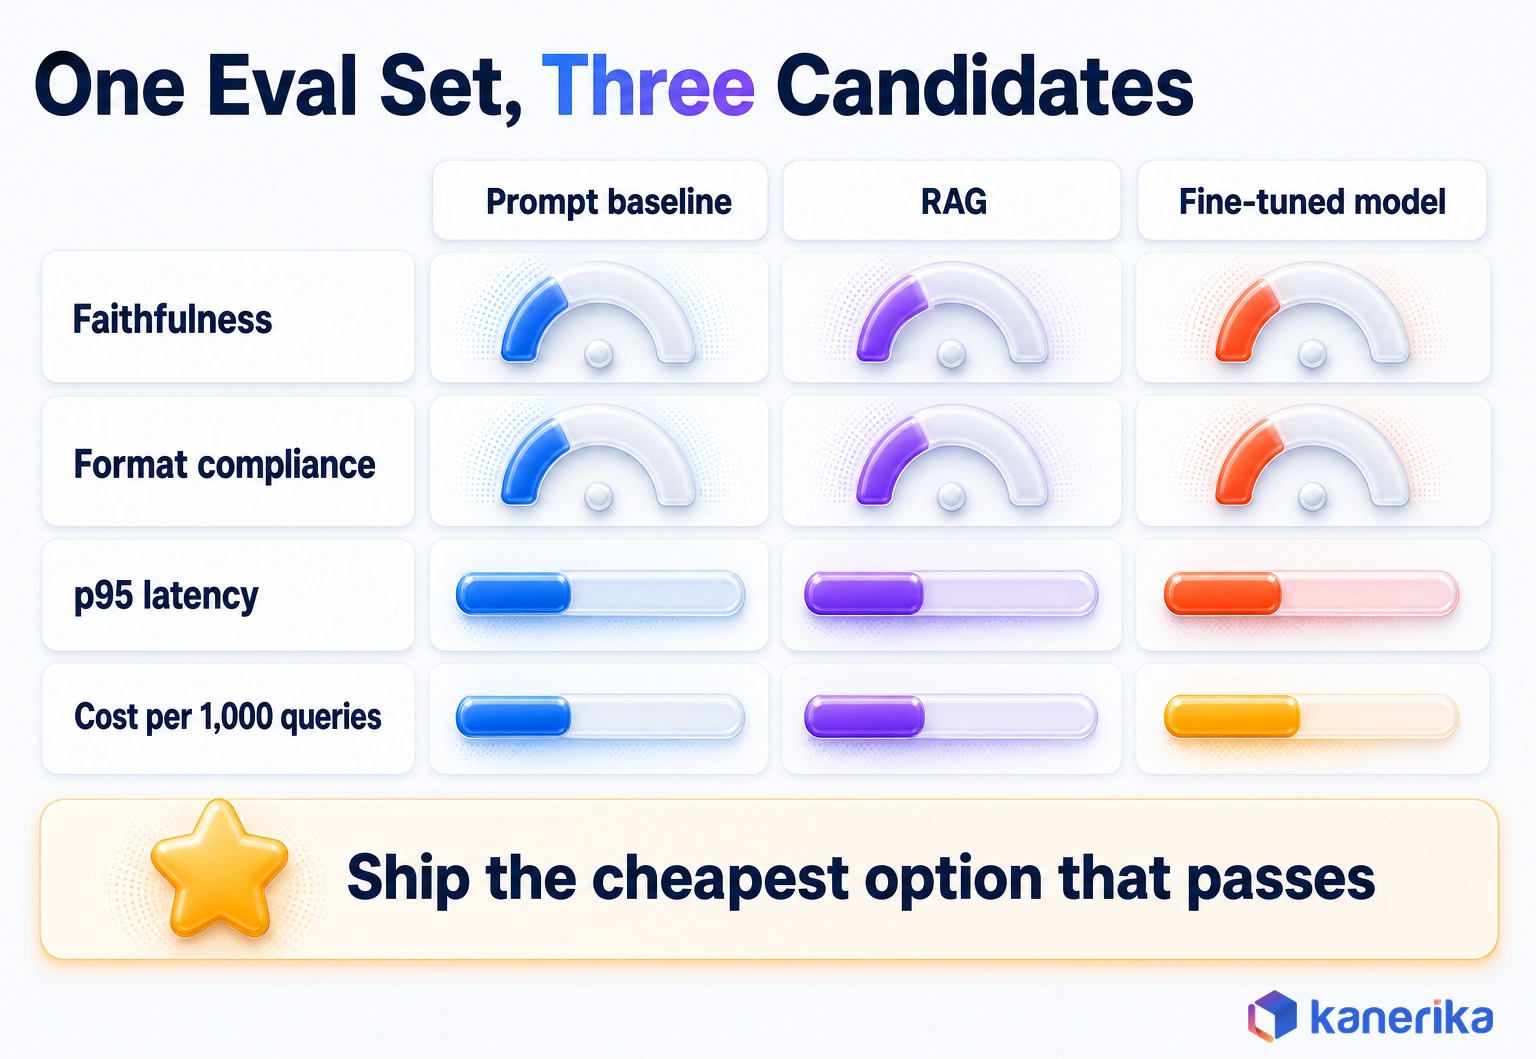
- Compare on four numbers, then decide. Faithfulness, format compliance, p95 latency and cost per 1,000 queries settle it, and the cheapest option that passes wins.
Talk to Kanerika
Want a Shared Evaluation Set for Your Use Case?
In a short working session, Kanerika will help you build one evaluation set from your own questions and score a prompt baseline against RAG.
Schedule a Demo →The Four Numbers That Decide It
Each number answers a different question, and two of them belong mainly to one method. The table shows what each metric tells you.
| Metric | What it tells you | Most relevant to |
|---|---|---|
| Faithfulness | Whether each claim is supported by the supplied context | RAG |
| Context recall | Whether retrieval found the passages needed to answer | RAG |
| Format compliance | Whether output matches the required schema or style | Fine-tuning |
| p95 latency | How slow the slowest common requests are | Both |
| Cost per 1,000 queries | What the design costs at volume, such as $21 on Claude Sonnet 5.5 in our example | Both |
Keep the set alive after launch, and re-run it whenever you re-index, retrain or change the base model. Between runs, LLM observability shows how the system behaves on live traffic. For metric design in more depth, see our LLM evaluation framework.
That way a silent regression shows up in a report rather than in a user complaint.
How Kanerika Builds RAG and Fine-Tuned LLM Systems
Kanerika treats RAG vs fine-tuning as a measurement problem, not a preference. The method is gap diagnosis first, then one shared evaluation set that every option must pass, from the prompt baseline to any fine-tune.
Most designs begin with retrieval, because enterprise questions usually depend on changing, private documents. Where behavior still needs tuning, the base model is chosen with its lifecycle in mind and the retraining owner is named up front. Kanerika’s generative AI services cover the wider program around these builds.
Six Stages From Failure Sample to Production
The work runs in six stages, and each one has a known way to fail.
- Failure sample: pull real user questions and failed answers, then label each as a knowledge or behavior gap. Skipping it leads teams to train a model for a search problem.
- Prompt baseline: measure the best prompt-only version first. Without it, no later gain can be proven.
- Retrieval build: build permission-aware RAG with source citations, with chunking and reranking tuned against the sample. The common failure is an index that ignores who is asking.
- Shared evaluation set: score prompt, RAG and any fine-tune on faithfulness, format compliance, p95 latency and cost per 1,000 queries. Separate test sets per option hide the real deltas.
- Targeted fine-tune: tune only for behavior gaps that remain, with training data kept portable across providers given the OpenAI wind-down.
- Monitor and route: send low-confidence answers to a person, re-index on content change and retrain only on measured drift.
Two practices carry across every project. Keep the training set in a provider-neutral JSONL file, so a model shutdown does not strand it. Re-run the shared evaluation set after every index or model change, so drift shows up as a number.
It also helps to store each evaluation result with the index version and model version it ran against. Then a regression can be traced to the change that caused it, instead of being argued about.
Kanerika’s RAG development services cover the retrieval build, and its LLM development services cover fine-tuning and custom model work. Kanerika also runs FLIP, its AI agent and workflow automation platform. KlarityIQ, its document intelligence agent, helps teams that need documents turned into usable data first.
Case Study: An AI Member Support Agent
A global expert-network firm with over one million subject-matter experts shows the pattern in practice. Its Member Success team answered repetitive tickets by searching knowledge bases and past Zendesk tickets by hand.
This was a knowledge gap, so retrieval came first. Kanerika built an AI agent integrated with those knowledge bases and Zendesk, working across chat and voice. Answers are grounded in the firm’s own knowledge, and low-confidence cases are routed to live executives.
The results: 65% of member queries resolved through self-service, 42% fewer tickets, 31% lower cost per ticket and 25% higher member satisfaction. Read the full AI member support agent case study for the build details.
Case Study
65% Self-Service Resolution with an AI Member Support Agent
A global expert-network firm grounded an AI agent in its knowledge bases and Zendesk, resolving 65% of member queries through self-service with 42% fewer tickets.
Read the Case Study →Conclusion: Choosing Between RAG and Fine-Tuning
RAG and fine-tuning fix different failures. RAG closes knowledge gaps, meaning facts that change, stay private or need a citation. Fine-tuning closes behavior gaps such as format, tone and narrow repeatable tasks.
Start by sorting real failures into those two types, and write the best prompt you can as a baseline. Build RAG when facts are the problem, and add a fine-tune only when evaluations show a behavior gap, after checking the platform’s lifespan.
For the IT support assistant from the opening, that means RAG for the VPN policy, plus a ticket-format fine-tune only if the numbers demand it. So how do you choose between RAG vs fine-tuning for an enterprise LLM? Diagnose the gap, score every option on one evaluation set and ship the cheapest one that passes.
Frequently Asked Questions
Is RAG the same as fine-tuning?
No. RAG retrieves relevant documents at query time and adds them to the prompt, so the model’s weights never change. Fine-tuning runs extra training on examples, so the lesson is stored inside the weights. RAG changes what the model can see, and fine-tuning changes how it behaves. Many enterprise systems use one, and some use both together.
Is RAG cheaper than fine-tuning?
It depends on volume and how often knowledge changes. RAG costs less upfront but adds retrieval and longer prompts to every query. In our example, 100,000 queries a month cost $105 on Claude Haiku 5.5 and $2,100 on Claude Sonnet 5.5. Fine-tuning costs more upfront for labeled data and training, then runs cheaper per call.
Can an LLM still hallucinate with RAG?
Yes. RAG lowers factual hallucinations but does not remove them. The model can still err when retrieval returns the wrong passage, nothing useful, or two passages that disagree. It may also mix retrieved text with its own memory. Requiring citations and checking that each claim is supported by a cited passage catches many of these errors.
Does RAG need more compute than fine-tuning?
At query time, usually yes. Every RAG request runs a search, often a rerank, and a longer prompt through the model. Fine-tuning moves compute to the front, with training runs and evaluation before launch and a shorter prompt on each later request. Total compute depends on query volume and how often you retrain or re-index.
Why might a business choose fine-tuning instead of RAG?
A business picks fine-tuning when its knowledge is stable but the model’s behavior is wrong. Common cases include strict output schemas, fixed classification labels, a required tone, or very high query volumes where short prompts save money and time. It also needs enough good input and output examples and a team that can retrain the model.
Which models can you still fine-tune in late 2026?
As of November 3, 2026, Microsoft Foundry offers tuning on models including gpt-4.1, gpt-4o, o4-mini and gpt-oss-20b. Google Vertex AI supports supervised tuning on Gemini 3.5 Flash, 3.5 Flash-Lite, 3.1 Flash-Lite and the 2.5 models. Open-weight models under Apache 2.0, such as Mistral Small 4 and Qwen3.8-27B, can be tuned on your own hardware.
Is fine-tuning better than RAG?
Neither is better in general. Fine-tuning is better for behavior problems, such as format, tone and narrow repeatable tasks. RAG is better for knowledge problems, such as changing facts, private documents and answers that must cite sources. Fine-tuning cannot replace RAG for current facts. Diagnose which gap you have and test both on one shared evaluation set.
What is the difference between RAG, fine-tuning and prompt engineering?
Prompt engineering changes the instructions and examples you send, with no new infrastructure. RAG adds a retrieval system that inserts relevant documents into each prompt. Fine-tuning trains the model’s weights on examples. Start with prompting because it is cheapest and sets a baseline. Add RAG for knowledge gaps, and fine-tuning for behavior gaps that prompting cannot close.
Can RAG and fine-tuning be used together?
Yes. Common hybrids include RAFT, which trains a model to ignore distractor documents and cite the relevant passage. Teams also tune the retriever or reranker, or run a fine-tuned generator over a RAG index. Each hybrid adds a system to maintain and evaluate, so add the second method only when evaluations show a measurable gap.
Is RAG better than fine-tuning for reducing hallucinations?
For factual hallucinations, yes. RAG grounds answers in supplied passages and can cite them, and fine-tuning does not reliably add facts. Fine-tuning helps in a narrower way, such as training a model to admit uncertainty or stay within retrieved text. The strongest setups combine good retrieval, required citations and an evaluation step that checks every claim.
When should I use RAG instead of fine-tuning?
Use RAG when answers depend on documents that change often, such as policies, prices or product details. Use it when content is private and access differs by user, or when answers must cite a source for audit. RAG also fits when you lack labeled training data, or when you want to switch models without retraining.
How much training data is needed to fine-tune an LLM?
OpenAI’s fine-tuning guide requires a training file with at least 10 examples. That number is only the floor. Quality matters more than volume, so start with a small set of clean, consistent input and output pairs that match real traffic. Score the result on a held-out slice, and add data only when the evaluation shows a gap.
What is the difference between LoRA and full fine-tuning?
Full fine-tuning updates every weight in the model. LoRA freezes the original weights and trains small adapter matrices beside them. Its 2021 paper reports 10,000 times fewer trainable parameters and three times less GPU memory than fully fine-tuning GPT-3 175B. QLoRA adds quantization, and its authors tuned a 65B model on one 48GB GPU.
What is RAG and why is it used?
RAG, or retrieval-augmented generation, connects a language model to an external knowledge source. For each question it retrieves relevant passages and adds them to the prompt, so the model answers from current, approved information. Enterprises use it to ground answers in their own documents, keep knowledge fresh without retraining, enforce access rules and cite sources.
Will long-context models replace RAG?
Not for most enterprise use. Flagship models offered windows of about 1M tokens as of November 3, 2026, yet every long call costs more and runs slower. The Lost in the Middle study found accuracy drops when relevant text sits in the middle of a prompt. RAG also enforces permissions and citations, which a pasted document set does not.
What are the main challenges of RAG?
Most RAG problems sit in search and data, and few sit in the model. Retrieval can miss the right passage, the index can go stale, and chunking can split a rule from its exception. Indexes that ignore user permissions can leak documents. Retrieval and reranking also add latency. Each issue needs a data engineering fix.
What is the biggest advantage of fine-tuning?
Fine-tuning gives consistent behavior. A tuned model can return the same schema, tone or label set every time without a long instruction block in the prompt. Shorter prompts lower per-query cost and latency, which matters at high volume. It suits narrow, repeatable tasks such as ticket routing, document extraction and replies in a regulated house style.
Does fine-tuning improve accuracy?
It improves accuracy on behavior, such as following a format or applying a fixed label set. It is much weaker at adding facts. Ovadia et al. found RAG consistently outperformed unsupervised fine-tuning for both existing and new knowledge. Microsoft’s Foundry documentation says fine-tuning does not replace retrieval for current information, so measure it against a baseline.
When should you not use fine-tuning?
Avoid fine-tuning when the real problem is missing or changing facts, when answers must cite sources, or when you lack good labeled examples. Avoid it too when nobody owns retraining, or when the base model or platform is close to retirement. In those cases a better prompt or a RAG system usually solves the problem at lower risk.
Is fine-tuning still worth it in late 2026?
Yes, for behavior gaps, though the vendor picture has shifted. OpenAI is winding down its fine-tuning platform, and eligible customers can create training jobs only until January 6, 2027. Microsoft Foundry and Google Vertex AI still offer tuning, and open-weight models such as gpt-oss-20b can be tuned with LoRA on your own hardware.
Is RAG considered training?
No. RAG does not train or change the language model at all. It searches an external index of documents at query time and places the best passages in the prompt. Building the index involves embedding documents, which is a data preparation step. Some hybrid designs also tune the retriever or reranker, yet core RAG involves no training.