TL;DR
Multimodal AI agents are AI systems that perceive images, audio, video and screens, then act on what they find through tools. Each one has four parts: perception, reasoning, memory and action. Model choice starts with modality support at the API level, because models differ in what they accept and return. Live voice also runs through separate session APIs, such as the OpenAI Realtime API and the Gemini Live API. On the AgentVista benchmark of hard visual tasks, the best model tested still reached only 27.3% overall accuracy. So scope each agent to one narrow task, gate every irreversible action, and test on your own recorded inputs before launch.
Key Takeaways
- A multimodal agent pairs a model that reads images, audio, video or screens with a loop that plans, calls tools and then checks results.
- Native speech-to-speech suits live conversation, while cascaded pipelines suit regulated work and hybrid designs suit document- and video-heavy work.
- GPT-6.1 Sol accepts text and images but not audio or video, so modality support decides the shortlist before price does.
- Claude Opus 5.5 matches or beats Fable 5.1 on most listed benchmarks while costing 40% of its per-token price.
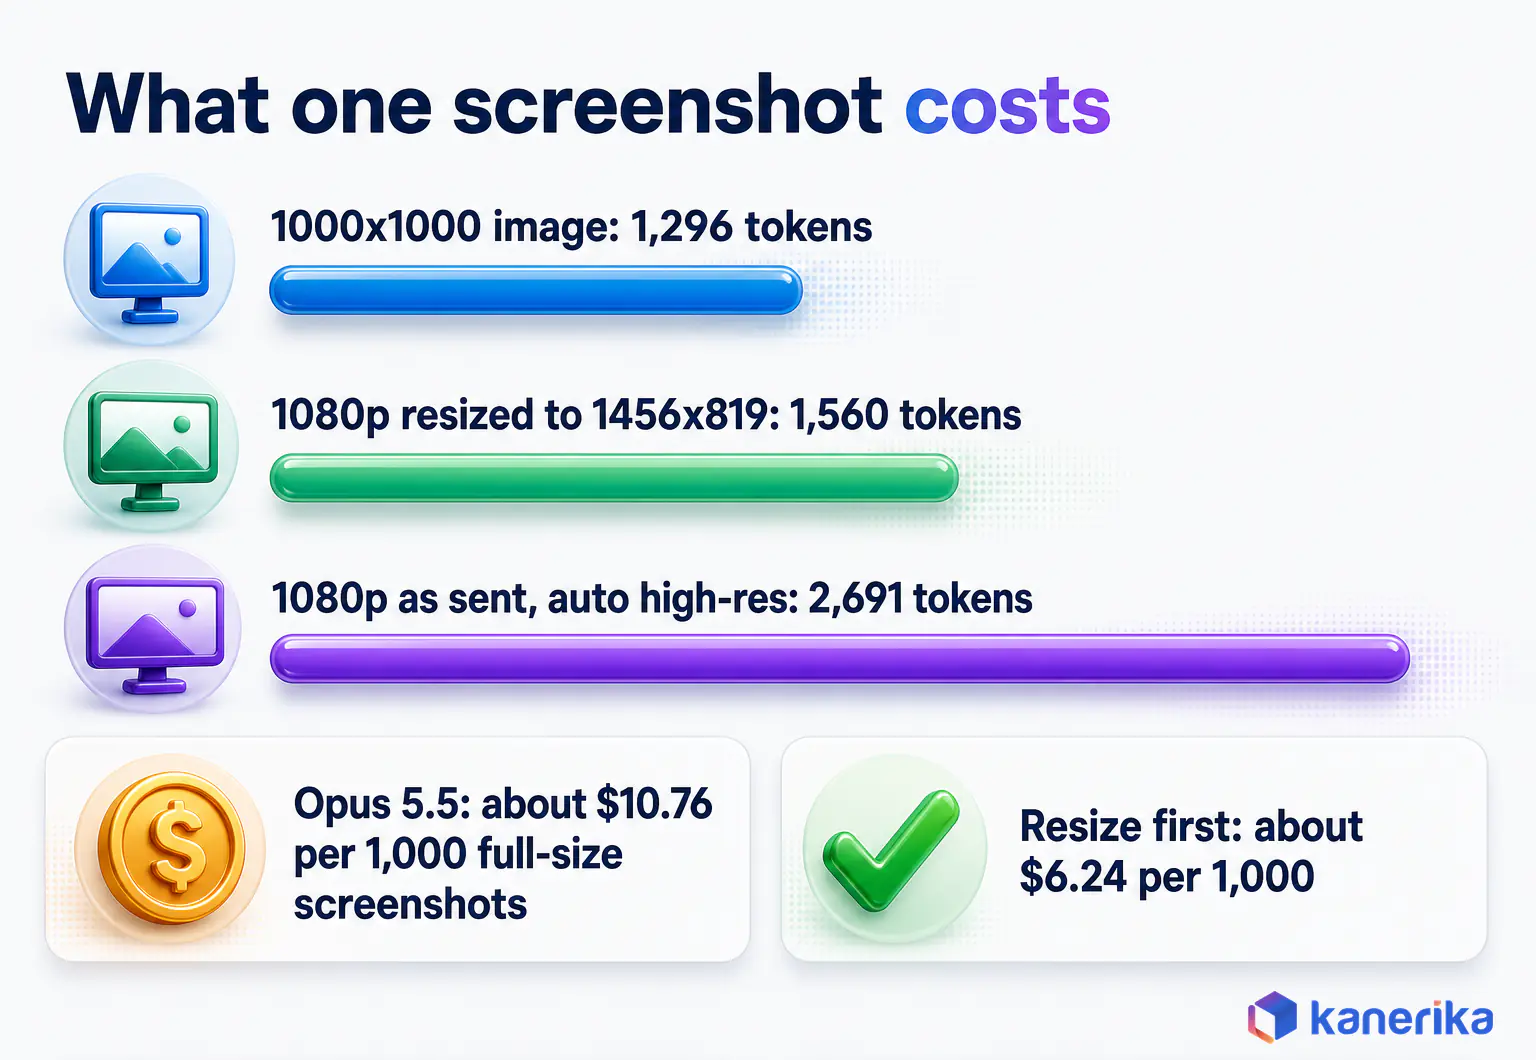
- On Claude Opus 5.5, a 1080p screenshot costs 2,691 tokens, per Anthropic’s vision docs as of November 3, 2026. Resized first, it costs 1,560, so screenshot-heavy agents need resolution limits.
- The best model on AgentVista reached 27.3% accuracy, so your own recorded tasks should decide go-live.
A Screenshot, a Voice Note and a Broken Pipeline
Early on a Monday, an operations engineer drops a screenshot of a failing dashboard into the support channel. Her voice note says the revenue tile reads zero, but the nightly load reported success.
An agent reads the tile and its timestamp, transcribes the note and then pulls the job logs. It finds an empty upstream file, so it asks her to approve a rerun before it touches the job.
That is a multimodal AI agent at work. The model reads pixels and sound, while the agent decides what to look up, which tool to call and when to ask a person.
What Are Multimodal AI Agents?
A multimodal AI agent is a software system that takes in several kinds of input, such as text, images, audio, video or a live screen. It reasons about a goal and then acts through tools. It plans steps, calls APIs or controls interfaces, and checks each result until the task is done or a person must decide.
The idea joins multimodal AI, models that handle several data types, with agentic AI, systems that pursue goals with some autonomy. Text-first LLM-powered autonomous agents already plan and call tools. Multimodal AI agents add perception, so they also bring a higher cost per turn and new errors, such as a blurry photo.
Model, Agent or Multi-Agent System?
Three terms get mixed up in vendor material, so it helps to separate them. A model answers a prompt, while an agent runs a loop around a model. A multi-agent system then splits work across agents that hand tasks to each other.
| Multimodal model | Multimodal agent | Multi-agent system | |
|---|---|---|---|
| What it is | A model that accepts more than one input type | A model plus planning, memory and tools in a loop | Several agents with defined roles that coordinate |
| What it does | Describes or extracts from an input | Completes a task across steps and tools | Splits a large workflow and hands work between agents |
| Example | Reads an invoice image and returns its fields | Matches the invoice to a purchase order and flags a mismatch | Intake, finance and review agents pass an invoice along |
Start in the middle column. Multi-agent systems add coordination overhead, so they pay off only once a single agent is reliable on its part of the job.
When a Workflow Actually Needs One
Use a multimodal agent when work already arrives as images, audio, video or screens and someone already acts on it by hand. Claims photos, recorded calls and dashboard screenshots all qualify.
Decision rule: when the input is structured text, use a text-only agent instead. If the steps never change, a fixed OCR-and-rules pipeline is also cheaper and more predictable.
How Multimodal AI Agents Work: Perception, Reasoning, Memory and Action
Every multimodal agent runs the same four-stage loop. Perception turns raw input into something the model can use, and then reasoning picks the next step. Memory tracks what happened, while action changes something in the world.
A single model call can describe a screenshot. An agent describes it, decides the error code needs a log lookup, and runs it before choosing again. Our guide to AI agent architecture also covers the general pattern.
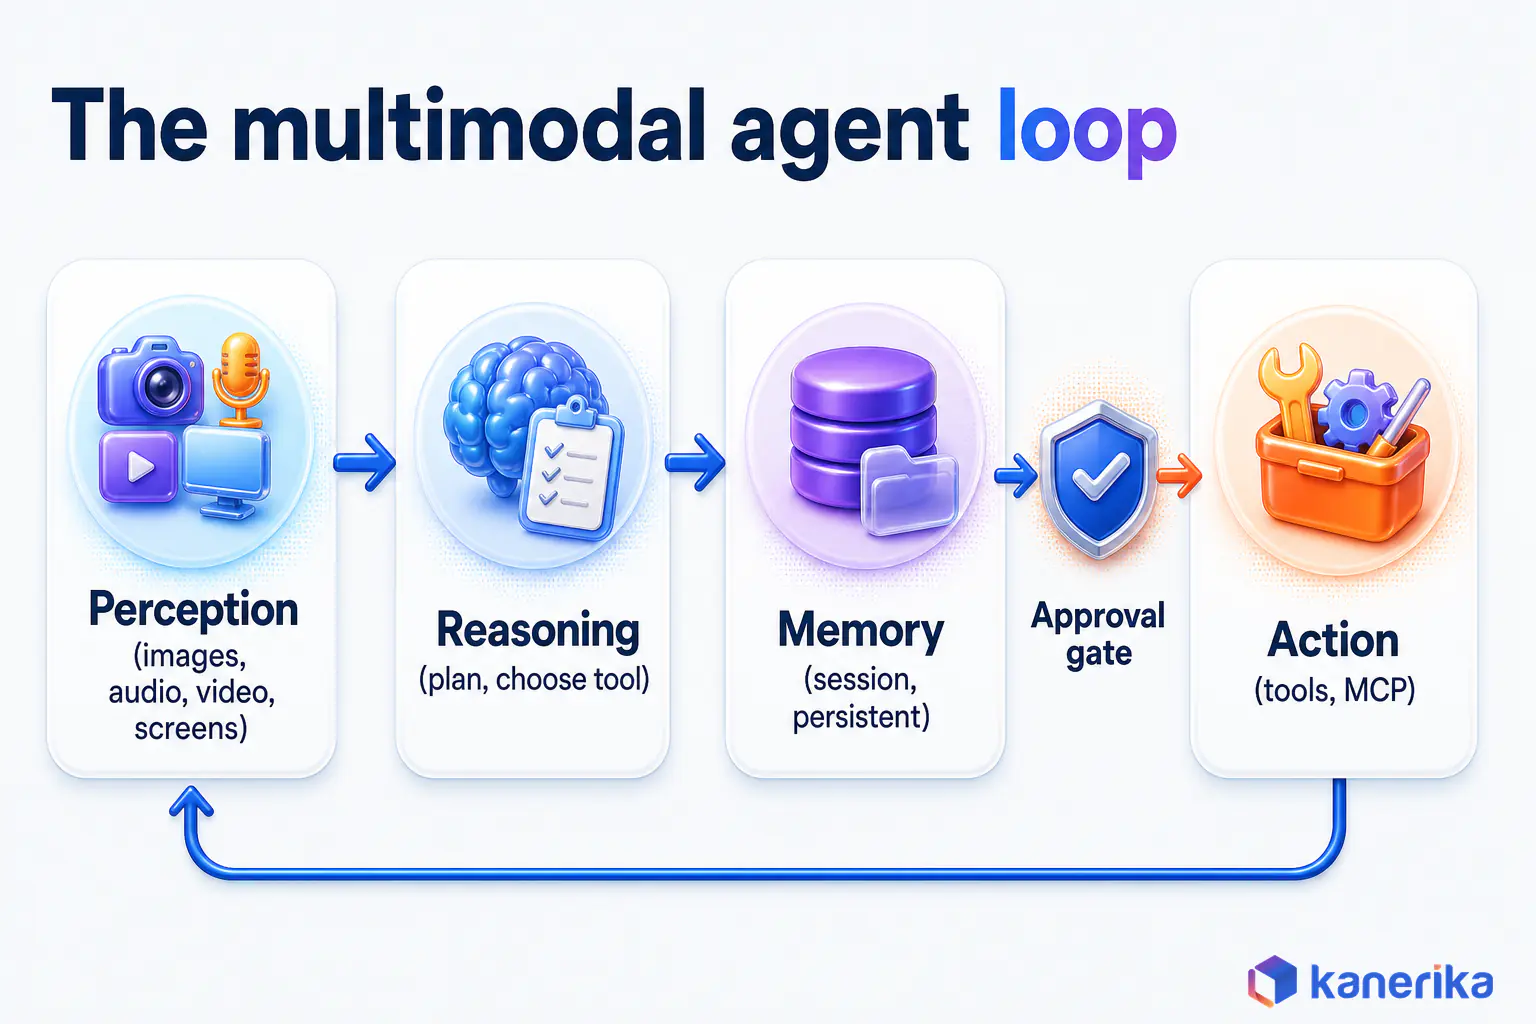
Perception
Images and screenshots pass through the model’s vision encoder. Documents may go through OCR first when layout and tables matter. Audio is transcribed by speech-to-text, unless a speech-native model handles it directly.
Video is the expensive case, so agents sample frames at a fixed rate. They also keep timestamps, because speech and visuals must be lined up later. How vision-language models encode images is covered in a separate guide.
Reasoning and Planning
The reasoning step reads the input, the goal and the history, then chooses one small, checkable action. For example, it checks an error code before fetching logs. When a screenshot is cropped, rotated or unreadable, the agent should ask the user instead of guessing.
Memory
Session state holds the current conversation, the images already seen and the tool results so far. Persistent memory keeps facts across sessions, such as a customer’s device model. Because media files are heavy, most agents store a text summary and keep the original in object storage. They reopen it when a later step needs the detail.
Action
The agent calls functions you define, queries systems through the Model Context Protocol, or clicks and types on a screen. The MCP specification is at version 2026-07-28. Our comparison of MCP and A2A also explains how agent-to-tool and agent-to-agent protocols differ.
Reading a log is low risk, but restarting a job or refunding an order is not. Decision rule: put an approval gate before anything irreversible, so the agent prepares the action and a person confirms it.
Native, Cascaded and Hybrid Architectures
The same loop can be wired three ways, and the choice shapes latency, cost and auditability. The difference shows most clearly in voice, because timing matters there.
A native design runs speech or live video through one model session. The OpenAI Realtime API works directly with audio and can call tools mid-conversation. The Gemini Live API also lets users interrupt the model while it speaks.
A cascaded design chains speech-to-text, a language model and text-to-speech. Each hop adds delay and drops tone of voice, but each one leaves a transcript you can log and test. Voice agents on Claude use this pattern, since they rely on a separate speech layer.
A hybrid design keeps a reasoning agent at the center and calls specialist parsers only when needed. An OCR engine reads the contract, for example, while a video model tags the clip. As a result, heavy perception stays off the expensive model for most turns.
| Architecture | Latency | Auditability | Cost | Best fit |
|---|---|---|---|---|
| Native | Lowest, one session | Harder, transcripts must be requested | Set by the session model | Live voice and video conversation |
| Cascaded | Higher, three hops | Strong, every stage leaves text | Each stage priced and swapped separately | Regulated workflows that need transcripts |
| Hybrid | Varies, fast when parsers are skipped | Good, parser output is structured | Lower when most turns skip heavy perception | Document- and video-heavy work |
Early, Late and Hybrid Fusion
Early fusion merges modalities before reasoning. It suits inputs tightly aligned in time, such as lip movement and speech in one clip. Late fusion processes each modality separately and combines the results at the end, which makes it easier to audit when inputs arrive at different times. Many production agents use both: early fusion inside a video clip, late fusion across the clip, the email and the form that came with it.
Decision rule: run native for live conversation, cascaded for regulated workflows that need transcripts, and hybrid for document- and video-heavy work.
Which Models Power Multimodal AI Agents in 2026
For an agent, the useful question is what each model accepts and returns at the API level. It also matters what each call costs, so the table lists price per million tokens. Our guide to multimodal models covers the model class itself, while this table draws on vendor documentation from early November 2026.
Inputs, Prices and Context by Model
Modality support is uneven. OpenAI’s GPT-6.1 Sol model page lists text in and out with image input only. So a Sol agent that must hear a caller needs a speech layer or a separate voice API.
| Model | Inputs | Notes | Price per 1M tokens (in / out) | Context |
|---|---|---|---|---|
| GPT-6.1 Sol | Text, images | Published September 29, 2026; cached input $0.10 | $2 / $10 | 1,050,000; 128,000 max output |
| GPT-6.1 Terra | See model page | Lower-cost OpenAI tier | $1 / $5 | 1,050,000; 128,000 max output |
| Claude Opus 5.5 | Text, images | Announced September 22, 2026 | $4 / $20 | 1M; 128K max output |
| Claude Fable 5.1 | Text, images | Higher-priced tier above Opus 5.5 | $10 / $50 | 1M; 128K max output |
| Claude Sonnet 5.5 | Text, images | Released September 28, 2026 | $2 / $10 | 1M; 128K max output |
| Claude Haiku 5.5 | Text, images | Released October 7, 2026 | $0.10 / $0.50 up to a 100k prompt | 1M; 128K max output |
| Gemini 4 Argon | See model card | Model card published October 13, 2026 | $2 / $10 through November 30, 2026; $4 / $20 from December 1, 2026 | Up to 1M combined |
| Gemini 3.8 Flash | See model page | Lower-cost Gemini tier | $0.75 / $3.75 through December 31, 2026; then $1.50 / $7.50 | See model page |
| Qwen3.8-Max | Text, vision input | Released August 3, 2026; open weights, custom license | Depends on hosting | 1M |
Where the vendor page does not list input types, check it before you shortlist. Modality decides whether a model can do the job at all.
Price Gaps and Open Weights
Opus 5.5 costs 40% of Fable 5.1 per token ($4 / $10 input, $20 / $50 output). Anthropic’s Opus 5.5 announcement shows it matching or beating Fable 5.1 on most listed benchmarks. The models overview also recommends starting with Opus 5.5 for most workloads. So Opus 5.5 is the default, and Fable 5.1 is a tier to test when Opus falls short.
Qwen3.8-Max is the open-weights option, a mixture-of-experts architecture with 2.4T total and 95B active parameters. Its weights are on Hugging Face under a custom license, so read that license before commercial use.
Announcements and Retirements
Google has announced Gemini 4 Carbon, but no price or availability is published yet. OpenAI retired gpt-4o-2024-05-13 on October 23, 2026. GPT-4o and GPT-4.1 snapshots then retire on January 14, 2027, so agents pinned to them need a migration plan.
Live voice runs through separate session APIs, which the next section covers. For the assistants built on these model families, see ChatGPT, Gemini and Claude compared.
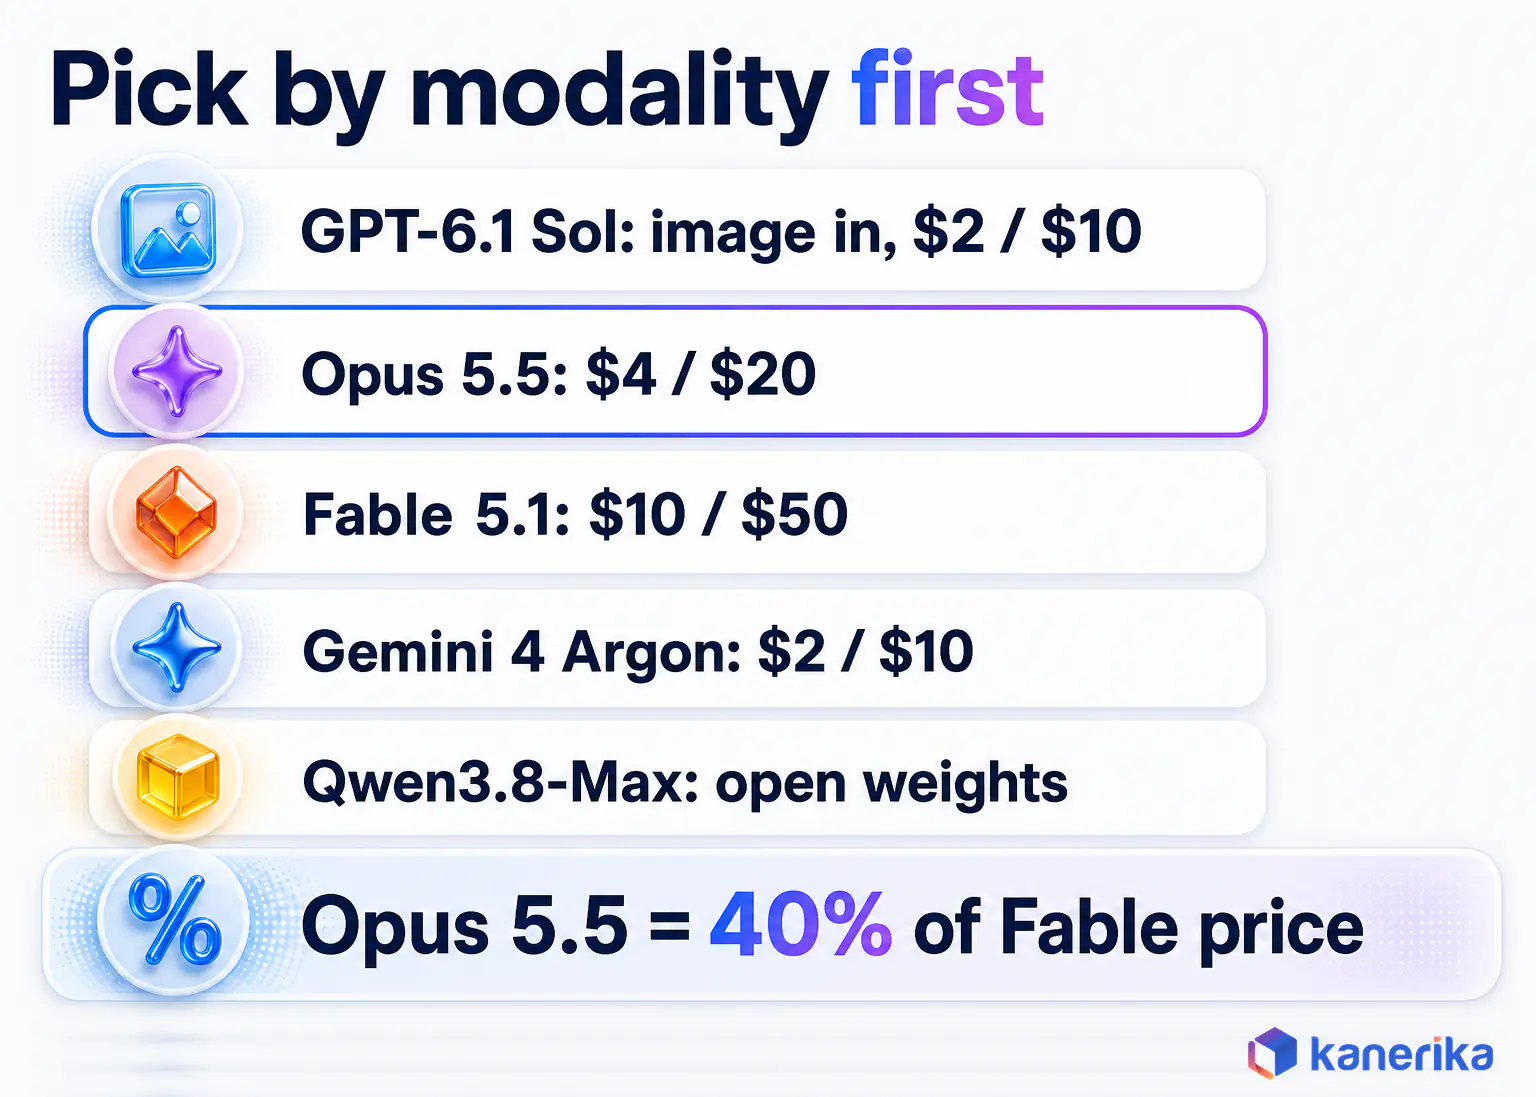
Decision rule: pick by modality first, then by price and context. Route routine perception, such as clean forms, to cheaper tiers like Claude Haiku 5.5 or Gemini 3.8 Flash.
Computer-Use and Voice Agents
Computer-use agents operate software through its screen, while voice agents hold a spoken conversation and call tools. Both reach systems that text agents cannot.
Computer-Use Agents
The agent takes a screenshot and decides where to click or what to type. It then acts and takes another screenshot to check the result. Anthropic’s computer_toolset_20260801 client toolset gives Claude screenshot, mouse and keyboard control of a desktop.
Because the agent acts on a real desktop, Anthropic’s documentation recommends running it in a dedicated virtual machine or container with minimal privileges. Its classifiers also scan each screenshot for injected instructions. The same page warns that latency may be too slow for real-time work with a person. Computer use therefore fits background tasks such as data gathering or software testing.
OpenAI’s computer use guide runs the same loop, with your code executing each action and returning a screenshot. It also adds confirmation and human approval for consequential actions.
Our review of computer-use products compares packaged options. Terminal agents such as Gemini CLI and Claude Code instead act on a machine through commands, which is faster to log.
Voice Agents
The OpenAI Realtime API runs speech-to-speech agents that work directly with audio, keep conversation state and call tools. It connects over WebRTC, WebSockets or SIP, so an agent can also answer a phone line.
In the Agents SDK you build a RealtimeAgent the same way as a text agent, with tools, handoffs and guardrails. The session layer handles the audio. OpenAI’s guide uses gpt-realtime-2.1 as its example model.
The Gemini Live API streams audio, images and text over WebSockets. It supports barge-in, so users can interrupt mid-sentence. It also offers function calling and Google Search as tools, returns audio transcriptions and lists 70 supported languages.
Our guide to AI voice agents covers call-center design. Decision rule: use computer use when no API exists and the task can run in the background. Use voice when the user’s hands or eyes are busy.
Enterprise Use Cases for Multimodal AI Agents
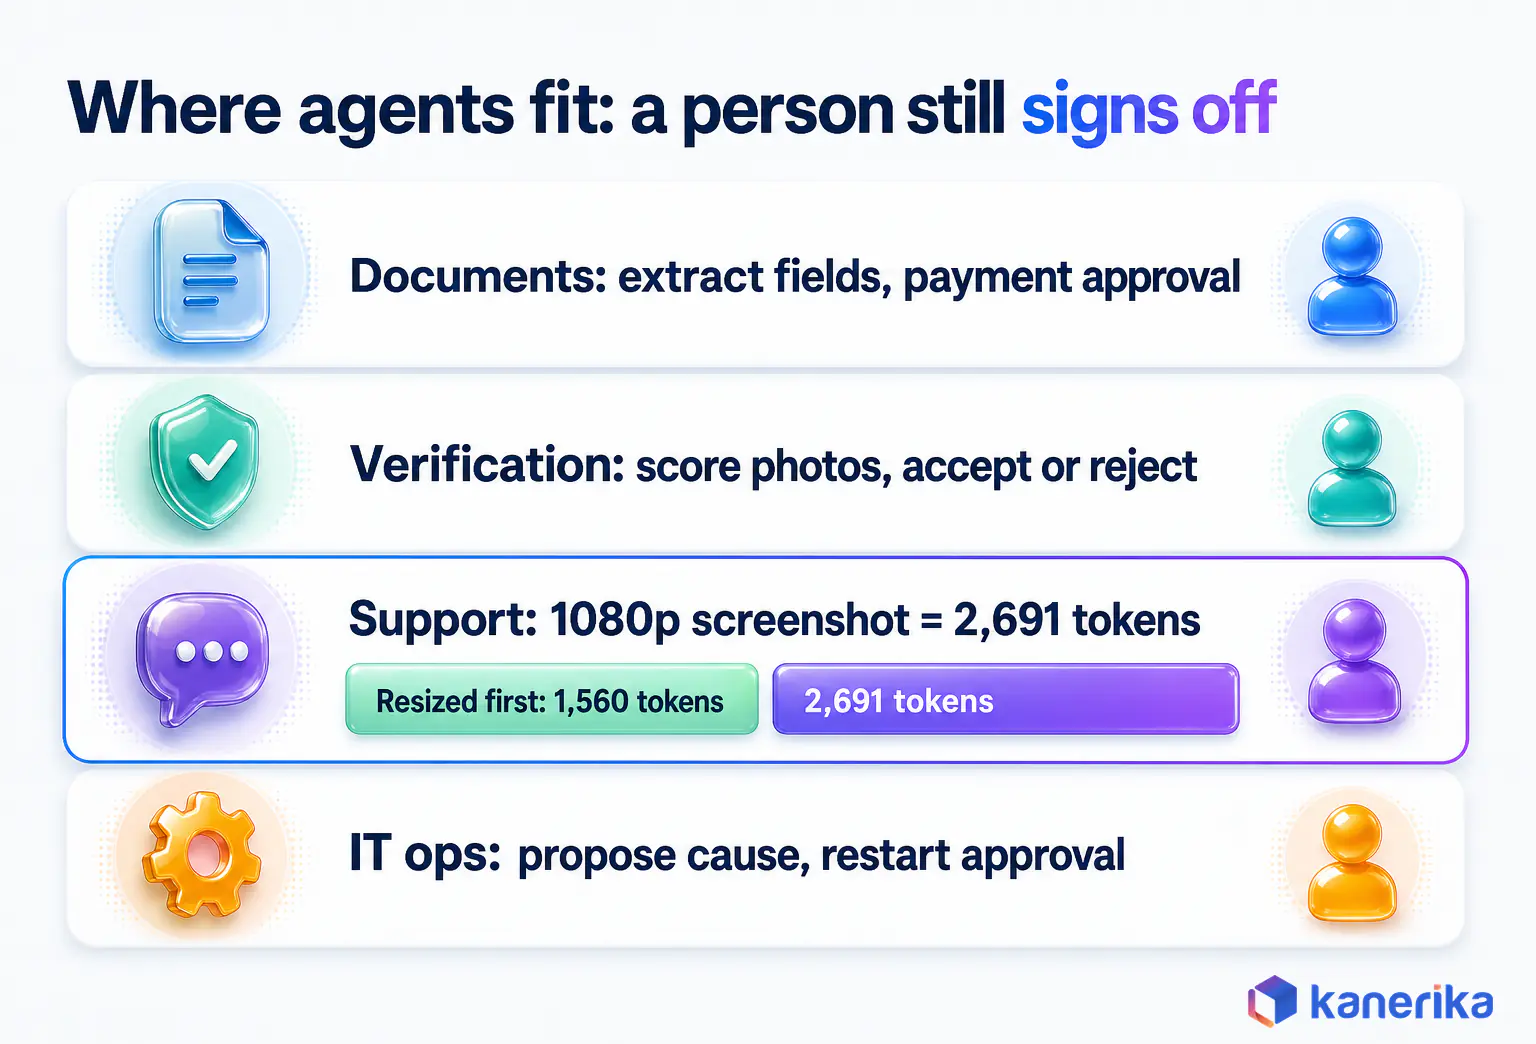
The strongest use cases share one trait. A person already reviews images, recordings or screens and then decides from them. The agent takes over the reading and preparation, so mixed inputs move faster, handoffs drop and checks run the same way every time.
Document Intake and Review
Invoices, contracts and forms arrive as scans with stamps, signatures and tables. The agent extracts fields and checks them against records before it flags mismatches. See document intelligence for extraction and multimodal RAG for questions across many files.
Visual Inspection and Verification
Product photos, damage images and counterfeit checks are slow, tiring work for people. The agent compares each image against references and scores the match. It then routes doubtful cases to an inspector, while AI video analysis covers the same idea for video.
Customer Support and Service Desks
Support tickets rarely arrive as clean text. A customer sends a screenshot of the error, a photo of the device and a voice note explaining what happened. An agent can classify the issue from all three and draft a reply that a person checks and sends. Our guide to AI agents for customer support explains routing and escalation.
Support centers deploy multimodal AI agents to manage queries across various channels, including chat, email, voice, and video, enabling seamless interaction. They can understand screenshots, transcribe voice notes, and read messages to resolve issues more quickly and accurately. These can be among the most effective AI tools for startups.
IT and Data Operations
The agent matches a broken chart’s time window to log entries and proposes a cause, as in the opening scenario. Restarts, reruns and configuration changes still stay behind an approval gate.
Field Service With Live Video
A technician streams live video and describes the fault by voice. The agent identifies the part and talks through the manual while the technician keeps both hands on the equipment. Barge-in matters here, because the technician will interrupt.
| Use case | Agent input | Agent action | Human sign-off |
|---|---|---|---|
| Document intake | Scans and PDFs with tables and stamps | Extracts fields and flags mismatches | Payment or contract approval |
| Visual verification | Product, damage or label photos | Scores against references | Final accept or reject |
| Support desk | Screenshots, voice notes, chat | Classifies and drafts the reply | Refunds and account changes |
| IT and data operations | Dashboard screenshots and logs | Proposes a likely cause | Restarts and reruns |
| Field service | Live video and voice | Identifies parts, guides steps | Safety-critical steps |
Decision rule: start where the human sign-off already exists. The agent prepares the decision, and then a person commits it.
Datasheet
KlarityIQ: Your Document Intelligence Agent
See how Kanerika’s document intelligence agent handles intake and review of complex business documents.
View the Datasheet →How to Build a Multimodal AI Agent, Step by Step
A first agent should be small enough to test by hand. Six steps take one workflow from idea to a limited rollout, and each step has a check before the next:
- Pick one narrow task and its inputs. List which images, recordings or screens arrive, and who acts on them in the current process.
- Choose the architecture and model. Apply the native, cascaded or hybrid rule, then pick a model that accepts your inputs.
- Build perception with explicit limits. Cap image resolution, frame rate and audio length in code, so costs stay predictable.
- Connect tools with least privilege. Use MCP or function calls, but keep read tools apart from write tools.
- Add approval gates, logging and tracing. Irreversible actions wait for a person, while every step is recorded.
- Test on recorded real inputs, then roll out small. Replay real screenshots, scans and calls before any user sees the agent.
Step 6 is the one teams skip, because synthetic inputs look clean. Accuracy on real inputs that are blurry, cropped and rotated is still the number that matters.
Frameworks and Building Blocks
The OpenAI Agents SDK, the Gemini Live API and Claude’s computer use toolset cover voice, streaming vision and screen control. For orchestration, LangGraph models an agent as a stateful graph. Our overview of AI agent frameworks also compares the wider field.
Build or Buy
Buy when the task is common and a product already handles your inputs, such as meeting transcription. Build when the workflow, the tools or the data control are specific to your business.
In practice, build the parts that hold your business rules, and buy the rest.
Kanerika Service
Agentic AI Services
Kanerika designs, builds and governs AI agents for enterprise workflows, from the input audit to approval gates and rollout.
Explore Agentic AI ServicesHow to Evaluate a Multimodal AI Agent
Vendor benchmarks are a humbling starting point. On the AgentVista benchmark (arXiv, February 2026), the best model tested, Gemini-3-Pro with tools, reached 27.3% overall accuracy. Hard tasks can also need more than 25 tool-calling turns.
Earlier academic work found the same gap. When OSWorld appeared on arXiv in April 2024, humans completed over 72.36% of its 369 real computer tasks. The best model then reached only 12.24%, struggling mostly with GUI grounding and operational knowledge.
A general benchmark cannot tell you whether an agent will handle your invoices. So test on your own tasks, with a metric for each stage of the loop. Our guide to AI agent evaluation covers test design, while the scorecard below adds what visual and spoken inputs need.
| Metric | What it tells you |
|---|---|
| End-to-end task success | Share of recorded tasks completed without a human rescue |
| Visual grounding accuracy | Whether the agent read the right field, button or region |
| Tool-call accuracy | Right tool, right arguments |
| P95 latency | How slow the slowest normal turns are |
| Interruption recovery (voice) | Whether it stops, listens and resumes after the user cuts in |
| Cost per accepted task | Total spend, retries and review included, per accepted task |
| Unauthorized-action rate | How often it tried an action outside its permissions |
Set your own bar per metric before testing, for example zero unauthorized actions across a full replay set. After launch, agent observability traces each perception step, tool call and approval, so drift shows up early.
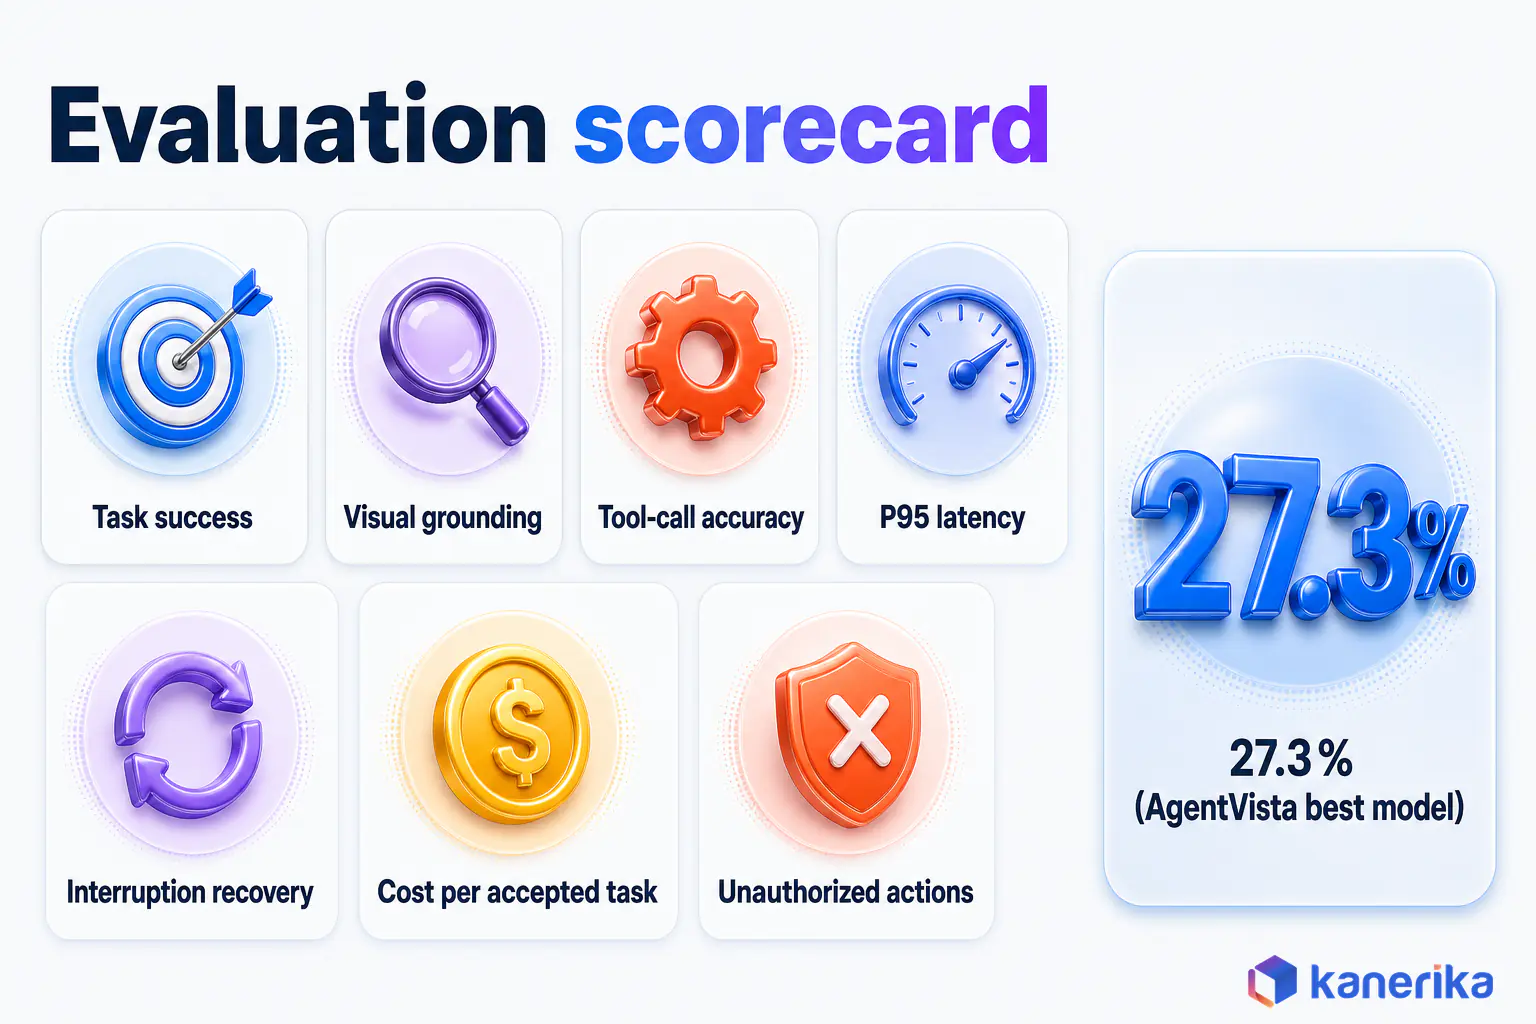
Decision rule: benchmarks shortlist models, but your own recorded tasks decide go-live.
Failure Modes and Security Risks
Multimodal agents inherit the failures of text agents and then add perception failures. Each one below deserves its own test:
- Misread images. Claude’s vision documentation warns about low-quality, rotated or very small images, and Claude also will not identify people.
- Timestamp mismatch. A spoken comment gets linked to the wrong moment in a video when timestamps drift.
- Missed frames. Sampling skips the moment that mattered, such as a brief error dialog.
- Lost constraints. An early instruction stops shaping later steps once a task runs long.
- Guessing instead of asking. When an input is unclear, the agent produces a confident hallucination about what it shows.
- Skipped verification. The agent acts but never checks the screenshot that shows the action failed.
Each failure maps to a control, such as resolution checks, an ask-the-user path, aligned timestamps and a post-action screenshot. AI guardrails then package these controls as policy.
Multimodal Prompt Injection
Hidden text in a screenshot, white-on-white text in a document, a spoken command or a QR code can redirect the agent. So treat every non-text input as untrusted data, never as instructions.
The risk is documented well beyond vendor docs. The OWASP LLM01:2025 Prompt Injection entry lists multimodal injection as its own attack scenario. In it, a malicious prompt hidden in an image beside benign text alters the model’s behavior. Researchers showed the media version in a 2023 arXiv paper, blending an adversarial perturbation into an image or audio clip. That perturbation steered LLaVa and PandaGPT to output attacker-chosen text.
Anthropic’s screenshot classifiers and sandbox advice, plus OpenAI’s confirmation steps, set the baseline. Our guide to agentic AI security also covers the wider threat model.
Privacy and Data Retention
Images and recordings often hold personal data the task never needed, such as faces, badge names or account numbers. Redact it before the model sees it, then limit retention of raw files and log access.
Decision rule: no failure mode on this list ships without a test case in your replay set and a named control.
Checklist
Agentic AI Checklist
Work through the scope, data, security and governance checks to clear before an AI agent goes live.
Get the Checklist →Latency and Cost of Multimodal AI Agents
Images become tokens, so the bill tracks what the agent looks at. Claude’s vision documentation lists a 1000×1000 image at 1,296 tokens. One request can carry up to 600 images, or 100 on models with a 200k-token context.
Claude Opus 5.5, announced September 22, 2026, reads screenshots at high resolution automatically, so a 1920×1080 capture costs 2,691 tokens. The docs list that figure as of November 3, 2026. At $4 per million input tokens that is about $0.011 a screenshot, or $10.76 per thousand. Resize it to 1456×819 before sending and it drops to 1,560 tokens, about $6.24 per thousand. That is the cheapest lever when the task does not need fine detail. A 1000×1000 image comes to about $5.18 per thousand.
OpenAI prices the same problem differently: on GPT-6.1 Sol and Terra, prompts over 272K tokens cost 2x on input and 1.5x on output. Batch and Flex still run 50% lower, so they suit overnight document jobs.
Latency Budget and Cost Levers
Latency adds up across capture, perception, reasoning, tool calls and the response. So track P50 and P95 for each stage, because the bottleneck is often a slow internal API or screen capture.
Four levers cut cost on most tasks:
- Downsample screenshots when the task does not need fine detail.
- Cache stable context, since GPT-6.1 Sol charges $0.10 per million cached input tokens against $2 standard.
- Route easy turns to cheaper models, such as Claude Sonnet 5.5 at $2 / $10 or Gemini 3.8 Flash at $0.75 / $3.75 until December 31, 2026.
- Sample video frames at a fixed rate instead of streaming every frame.
Decision rule: measure cost per accepted task, including retries and human review. A cheaper model that needs more retries can still cost more per finished task.
How Kanerika Builds Multimodal AI Agents
Kanerika’s agentic AI services team builds multimodal agents in five stages, and each one ends with a checkpoint before the next begins:
- Workflow and input audit. We map which inputs arrive as images, PDFs, audio or screens, and who signs off in the current process.
- Perception layer. We then choose OCR, image recognition or speech per input, with resolution and frame limits set in code.
- Agent layer on FLIP. The agent runs on FLIP with tool access scoped per action, so read and write permissions stay separate.
- Governance. Approval gates, PII redaction and audit logs go in before the first pilot user.
- Pilot, then scale. We test on recorded real inputs, then widen to more users and input types.
FLIP is Kanerika’s workflow automation platform, so it hosts the agent logic and integrations. Karl, the data insights agent, answers questions over business data once perception has produced structured results.
KlarityIQ, the document intelligence agent, fits the document intake stage, while Klara, the compliance agent, checks contracts against your governance playbook. Susan, the PII redaction agent, removes personal data from inputs before they reach a model.
Case Study: Product Authentication
One project shows the pattern on visual input. A global luxury goods retailer needed to authenticate products during returns and resale. Kanerika trained FLIP for computer-vision product authentication and then used Karl to automate real-time verification, with blockchain provenance tracking.
The AI vision case study reports 95% counterfeit detection accuracy, 68% faster product verification and 100% product traceability.
Teams that start with one input type and one approval step usually reach a pilot faster than teams that wire every modality at once. So pick the input your people spend the most time reading, and build the first agent around it.
AI Assessment
Check Your AI Readiness Before You Build an Agent
Score your data, infrastructure and governance readiness before you commit budget to a multimodal agent.
Start Your AI Assessment →Frequently Asked Questions
What is a multimodal AI agent?
A multimodal AI agent is a software system that takes in several kinds of input, such as text, images, audio, video or a live screen. It reasons about a goal, plans steps and acts through tools or interfaces. It checks each result and repeats until the task is done or a person needs to decide.
How are multimodal AI agents different from traditional AI models?
A traditional AI model usually handles one input type and returns one answer per request. A multimodal AI agent accepts several input types and runs a loop around its model. It plans, calls tools, remembers earlier steps and checks results. That lets it finish a multi-step task, such as matching an invoice photo to a purchase order.
What is a computer-use agent?
A computer-use agent operates software through its screen. It takes a screenshot, decides where to click or what to type, performs the action and checks a new screenshot. Anthropic recommends running it in a dedicated virtual machine or container, and OpenAI adds human approval for sensitive actions. It suits background tasks where no API exists.
How do voice AI agents work?
A voice agent listens, reasons and speaks inside a live session. Native designs such as the OpenAI Realtime API work directly with audio and call tools during the call. Cascaded designs chain speech-to-text, a language model and text-to-speech, which adds delay and keeps a transcript. Phone calls connect through SIP, and users can interrupt mid-sentence.
What frameworks are used to build multimodal AI agents?
Teams often combine vendor SDKs with an orchestration layer. The OpenAI Agents SDK offers RealtimeAgent for voice sessions with tools, handoffs and guardrails. The Gemini Live API handles streaming voice and vision. Claude’s computer use toolset covers screen control. MCP, at specification version 2026-07-28, connects agents to tools, and LangGraph models stateful multi-step flows.
Which industries use multimodal AI agents the most?
Use is strongest where people already review visual or spoken input. Retail uses them for product verification and returns. Financial services and insurance use them for document intake and claims photos. Manufacturing and utilities use them for inspection and field service. IT and support teams use them to read screenshots, logs and customer voice notes.
What are the main benefits of multimodal AI agents?
The main benefit is handling mixed inputs in one place. A single agent can read a screenshot, a scanned form and a voice note, so fewer handoffs happen between teams. Checks run the same way every time, and people spend their time on the final decision instead of on reading, sorting and data entry.
How much does it cost to run a multimodal AI agent?
Cost depends on tokens per task. On Claude, a 1920×1080 screenshot is 1,560 tokens on the standard tier and 2,691 on high resolution. At Opus 5.5’s $4 per million input tokens, that is about $10.76 per thousand high-resolution screenshots. Track cost per accepted task, including retries and human review, to see the real figure.
What are the biggest security risks of multimodal AI agents?
The biggest risk is multimodal prompt injection, where hidden text in a screenshot, document, audio file or QR code tries to redirect the agent. Others include broad tool permissions and personal data in images. Anthropic scans computer-use screenshots with classifiers and recommends a sandbox. Treat every non-text input as untrusted and gate irreversible actions.
Are multimodal AI agents safe to use in sensitive applications?
They can be, with the right controls. Run computer-use agents in an isolated virtual machine, give each tool the narrowest permission, and redact personal data before the model sees it. Keep audit logs and retention limits for raw images and recordings. Above all, require a human approval for any action that cannot be undone.
How do you evaluate a multimodal AI agent before production?
Test on recorded real inputs from your own workflow. Measure task success, visual grounding accuracy, tool-call accuracy, P95 latency, interruption recovery for voice, cost per accepted task and the unauthorized-action rate. Benchmarks help you shortlist models. On AgentVista, the best model tested reached 27.3% overall accuracy, so your own tasks should decide go-live.
Why do multimodal AI agents fail?
Common causes include misread images that are blurry, rotated or very small, speech and video that drift out of sync, and skipped frames. Agents also lose track of constraints over long tasks, guess when an input is unclear, and skip checking whether an action worked. Hard benchmarks show the gap, with 27.3% accuracy for the best AgentVista model.
How are multimodal AI agents different from multimodal LLMs?
A multimodal LLM is the model itself. It reads text and images, and sometimes audio, then returns a response. A multimodal agent wraps that model with planning, memory, tool access and approval gates. The model can describe a screenshot, while the agent can decide what to do about it and then carry out that step safely.
Is ChatGPT a multimodal AI agent?
ChatGPT is a multimodal assistant built on OpenAI models that accept text and images. It behaves more like an agent when it uses tools to complete steps for you. For business workflows, teams usually build agents on the OpenAI API instead, adding their own tools, permissions, logging and approval steps around the model they choose.
What are the core components of a multimodal AI agent?
A multimodal agent has four core parts. Perception turns images, audio, video and screens into input the model can use. Reasoning plans the next step. Memory holds session state and persistent facts. Action calls tools, queries systems through MCP or controls a screen, with an approval gate before anything irreversible reaches a live system.
What are some examples of multimodal AI agents?
Common examples include a document agent that reads scanned invoices and matches them to records, and a support agent that reads customer screenshots and voice notes. Others include an IT agent that reads dashboard screenshots alongside logs, a verification agent that checks product photos for counterfeits, and a field agent that guides technicians over live video.
What is the difference between a multimodal agent and a multi-agent system?
A multimodal agent is one agent that handles several input types, such as images and audio, inside one loop. A multi-agent system splits a workflow across several agents with defined roles that hand work to each other. The two can combine, though most teams should make one multimodal agent reliable before adding coordination between agents.
When does a business actually need a multimodal agent?
A business needs one when work already arrives as images, audio, video or screens and a person currently reads that input and acts on it. Claims photos, recorded calls and dashboard screenshots are typical. If the input is already structured text, a text-only agent or a fixed OCR pipeline is usually cheaper and easier to test.
Which AI models are best for building multimodal agents in 2026?
Start with modality support. GPT-6.1 Sol accepts text and images at $2 and $10 per million tokens. Claude Opus 5.5 matches or beats Fable 5.1 on most listed benchmarks at $4 and $20. Gemini 4 Argon costs $2 and $10 through November 30, 2026. Qwen3.8-Max offers open weights with vision input and a 1M context.
Can multimodal AI agents process live audio and video?
Yes, through real-time session APIs. The OpenAI Realtime API runs speech-to-speech agents that keep conversation state and call tools over WebRTC, WebSockets or SIP. The Gemini Live API processes continuous streams of audio, images and text, lets users interrupt and supports function calling. Standard text-and-image endpoints are a poor fit for live conversation.