TL;DR
Databricks AI Functions run LLM tasks from SQL, so use a task-specific function for standard jobs and ai_query for a named model or schema. As of November 3, 2026, Databricks lists 21 task-specific functions plus ai_query. Only ai_extract and ai_classify are GA among the 21, while 9 still carry a Beta label. The functions need Databricks Runtime 15.4 LTS or above and do not run on Classic SQL warehouses. Every call bills twice, once for query compute and once for model inference in DBUs. Published prices start at $0.21 per 1,000 short texts classified, so a pilot costs little.
Key Takeaways
- AI Functions run LLM tasks from SQL, notebooks, Lakeflow pipelines and Workflows, so there is no endpoint to deploy for hosted models.
- Start with one of the 21 task-specific functions, then switch to ai_query when a job needs a custom prompt, a named model or a fixed schema.
- Check maturity before production because only ai_extract and ai_classify are GA, while 9 functions carry a Beta label as of November 2026.
- The hosted model list changes often, so pin the endpoint name in one place and watch the deprecation dates.
- Budget for two cost lines, query compute and model inference, and then confirm the estimate in system.billing.usage after a pilot.
- Treat every text column as untrusted input, so mask PII with ai_mask and restrict EXECUTE grants before prompts reach a model.
Two Million Tickets and One SELECT Statement
Picture a support lead on a Monday morning with two million unrouted tickets in a Delta table. The old plan was a Python service that called a model API, parsed each reply and then wrote labels back. That service also needs keys, retries, a deployment and an owner.
With Databricks AI Functions, the same job becomes a query. One call to ai_classify inside a SELECT sorts every ticket, while Unity Catalog decides who may run it. The sections below cover which function to pick, which models sit behind them, what the bill looks like and how to keep the output honest.
What Are Databricks AI Functions?
AI Functions are built-in SQL functions that send column values to an AI model and return the answer as a new column. They handle jobs such as translation, classification, sentiment scoring, field extraction and document parsing. You can call them from Databricks SQL, notebooks, Lakeflow Declarative Pipelines and Workflows, as the Databricks AI Functions documentation describes.
A function like UPPER() runs pure computation on the warehouse. An AI Function looks the same in a query, but it routes each request to a foundation model. It then parses the reply into a typed value, so the routing explains both the power and the cost. If you are new to the platform itself, start with what Databricks is and how the lakehouse fits.
How Databricks AI Functions Work
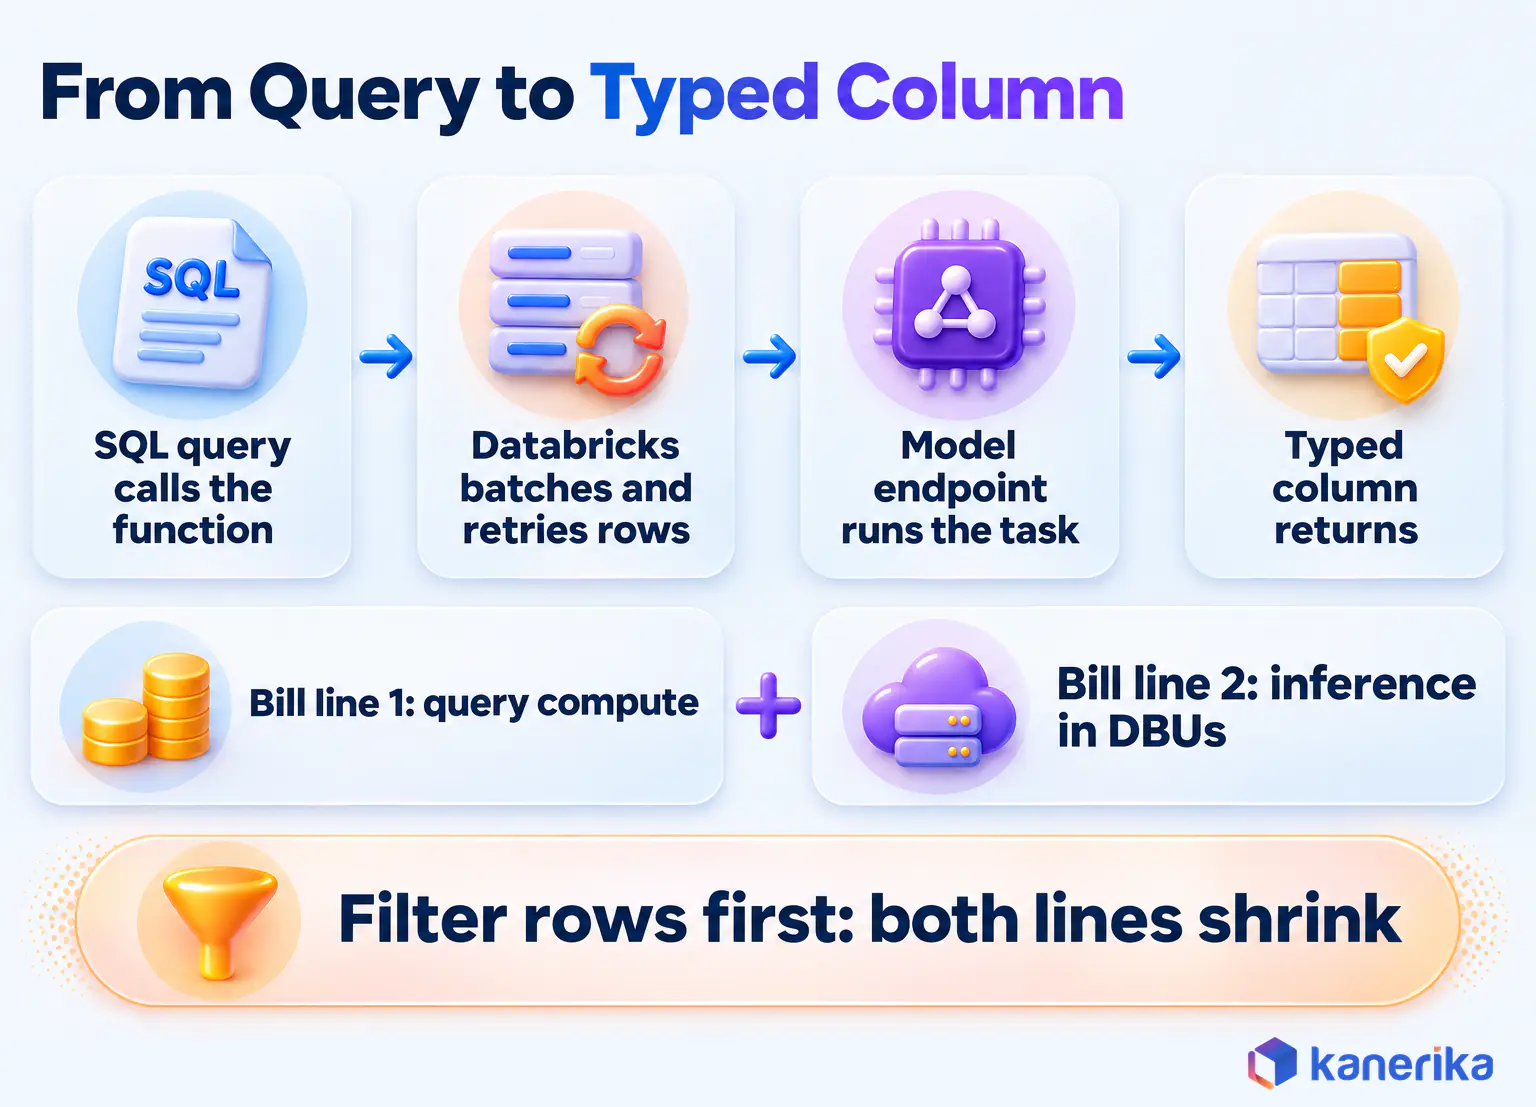
An AI Function call follows a short path from your query to a model and back. First, the query passes the column value plus a task definition to a model serving endpoint. With ai_query, your own prompt takes the place of that task definition. The response then comes back as a typed column in the same result set.
Databricks handles batching, retries and parallelization behind that path. As a result, a query over ten rows and one over ten million rows use identical syntax. Only the runtime and the bill change, so the habit that matters most is filtering rows before the function runs.
SELECT
  ticket_id,
  ai_analyze_sentiment(customer_message) AS sentiment,
  ai_classify(customer_message, ARRAY('billing', 'technical', 'shipping', 'other')) AS category
FROM support_tickets
WHERE created_date >= '2026-11-01';
Unity Catalog sits under this whole flow because it decides which users and service principals may run which functions on which tables. Permissions, lineage and audit logs also apply just as they do for an ordinary query. A raw API call bolted onto a pipeline cannot match that, because it sits outside the catalog.
Two cost lines follow from this design. You pay for the compute that runs the query, and most task-specific functions also add model inference, metered in DBUs. The cost section later in this guide shows where both lines appear.
Core Capabilities of Databricks AI Functions
Five capabilities explain why AI Functions fit inside data work rather than beside it. Each one removes a step that a separate AI service would need, so an analyst can add model output to a table without leaving SQL.
1. Native SQL Integration
AI Functions drop into a SELECT statement just as any built-in function does. So an analyst writing routine SQL can add a sentiment score or a translated column without switching languages or waiting for plumbing.
2. Hosted Models Ready to Call
Databricks hosts foundation models for AI Functions, such as system.ai.gpt-oss-20b, system.ai.claude-sonnet-5-5 and system.ai.gpt-6-1-sol. These endpoints appear on its supported-models list as of November 2026, so there is no provisioning step. For the wider platform view, see our guide to generative AI on the Databricks platform.
3. Structured Data Extraction and Classification
The ai_extract function pulls the fields you define out of text or parsed documents. Version 2.1 also adds citations and confidence scores. The ai_classify function sorts text into labels you supply. Version 2.0 brought up to 500 labels, multi-label output and label descriptions, and version 2.1 adds confidence scores and rationales.
4. Translation, Sentiment and Summarization
Three of the most common enrichment jobs in customer data have their own functions: ai_translate, ai_analyze_sentiment and ai_summarize. Each takes the input column and, at most, one extra argument. A review table can therefore gain a summary and a sentiment label in one pass.
5. Enterprise Governance Through Unity Catalog
Every AI Function call inherits the Unity Catalog permission model. By default, all users hold EXECUTE on the system.ai schema, so every function is open to everyone. Admins who need tighter control can revoke that default and then grant access function by function, once the account team enables per-function control.
Task-Specific Functions vs ai_query
Databricks splits AI Functions into one general-purpose function and a set of task-specific ones. The task-specific functions carry prompts that Databricks writes and maintains. By contrast, ai_query hands you the prompt, the model and the output format, along with the work of testing them.
For example, a support team sorting tickets gets good results from ai_classify on day one. A fraud team scoring transactions against its own rubric, however, needs ai_query and a named endpoint.
Table 1: Common AI Functions and Example Calls
| Function | Purpose | Example call |
|---|---|---|
| ai_query | Custom prompt against a named serving endpoint | ai_query(‘system.ai.gpt-oss-20b’, prompt) |
| ai_classify | Sorts text into labels you define | ai_classify(text, ARRAY(‘billing’, ‘technical’)) |
| ai_extract | Pulls named fields from text or parsed documents | ai_extract(parsed, ‘[“vendor”, “amount”]’, MAP(‘version’, ‘2.1’)) |
| ai_translate | Translates text into a target language | ai_translate(text, ‘es’) |
| ai_summarize | Condenses text to a target word count | ai_summarize(text, 40) |
| ai_analyze_sentiment | Labels sentiment as positive, negative, mixed or neutral | ai_analyze_sentiment(text) |
| ai_mask | Masks entity types such as names and emails | ai_mask(text, ARRAY(‘person’, ’email’)) |
| ai_parse_document | Extracts text, tables and layout from files | ai_parse_document(content, MAP(‘version’, ‘2.0’)) |
| ai_fix_grammar | Corrects grammar in input text | ai_fix_grammar(text) |
Table 1 leaves out ai_forecast on purpose because it is a table-valued function. You pass it a table or query of time series rows, and it then returns a table of projected values. Its arguments are on its reference page, since they differ from the one-column pattern above.
ai_query for Custom Prompts and External Models
The ai_query function is the one to use when no task-specific function fits or when a prompt needs custom wording. It also covers models outside Databricks. Hosted models, provisioned throughput endpoints, custom models and external models all share one call signature.
SELECT ai_query(
  'fraud-model-v3',
  named_struct('transaction_amount', amount, 'merchant_category', category, 'account_age_days', account_age),
  returnType => 'FLOAT'
) AS fraud_score
FROM transactions;
The function reached general availability on June 15, 2026. It also accepts images through the files argument, though only as JPEG or PNG. Its failOnError argument needs Databricks Runtime 15.3 or above and defaults to true.
Kanerika Service
Databricks Consulting and Implementation
Kanerika designs, builds and governs Databricks pipelines, including AI Functions jobs scoped through Unity Catalog and costed against real data volume before they scale.
Explore Databricks ServicesTask-Specific Functions for Common Jobs
Databricks recommends a task-specific function whenever one matches the goal. These functions skip the trial and error of writing an instruction, and Databricks also tunes them over time. In practice, ai_classify, ai_extract and ai_parse_document cover most everyday enrichment work.
Mixing both kinds inside one pipeline is common. For instance, a document job might call ai_parse_document to get the text and then call ai_query to score it against a business rubric.
ai_gen for Prompt-In, Text-Out
The ai_gen function takes a single prompt and returns a STRING, while Databricks chooses the model behind it. It suits quick generation work, such as drafting a short answer for each question in a table.
SELECT question,
  ai_gen('You are a teacher. Answer the student''s question in 50 words: ' || question) AS answer
FROM questions
LIMIT 10;
Switch to ai_query when you need to pick the model, set temperature or force a schema. Some jobs also need a model that plans several steps, calls tools and checks its own output. A single SQL function is the wrong shape for that, so use Databricks Agent Bricks for multi-step agents instead.
Table 2: Which Function to Start With
| Job | Start with | Why |
|---|---|---|
| A standard task such as labeling, masking or summarizing | The matching task-specific function | Databricks maintains the prompt, so you write one line |
| A custom rubric, a named model or a fixed JSON schema | ai_query | You control the endpoint, parameters and responseFormat |
| A quick free-text answer with no model choice | ai_gen | It is the shortest call, since Databricks picks the model |
Complete List of Databricks AI Functions (November 2026)
Check the full function list before you design a pipeline, because the right built-in function saves you from writing and testing a prompt. The AI Functions documentation lists 21 task-specific functions plus ai_query. The two tables below reflect that list as of November 3, 2026.
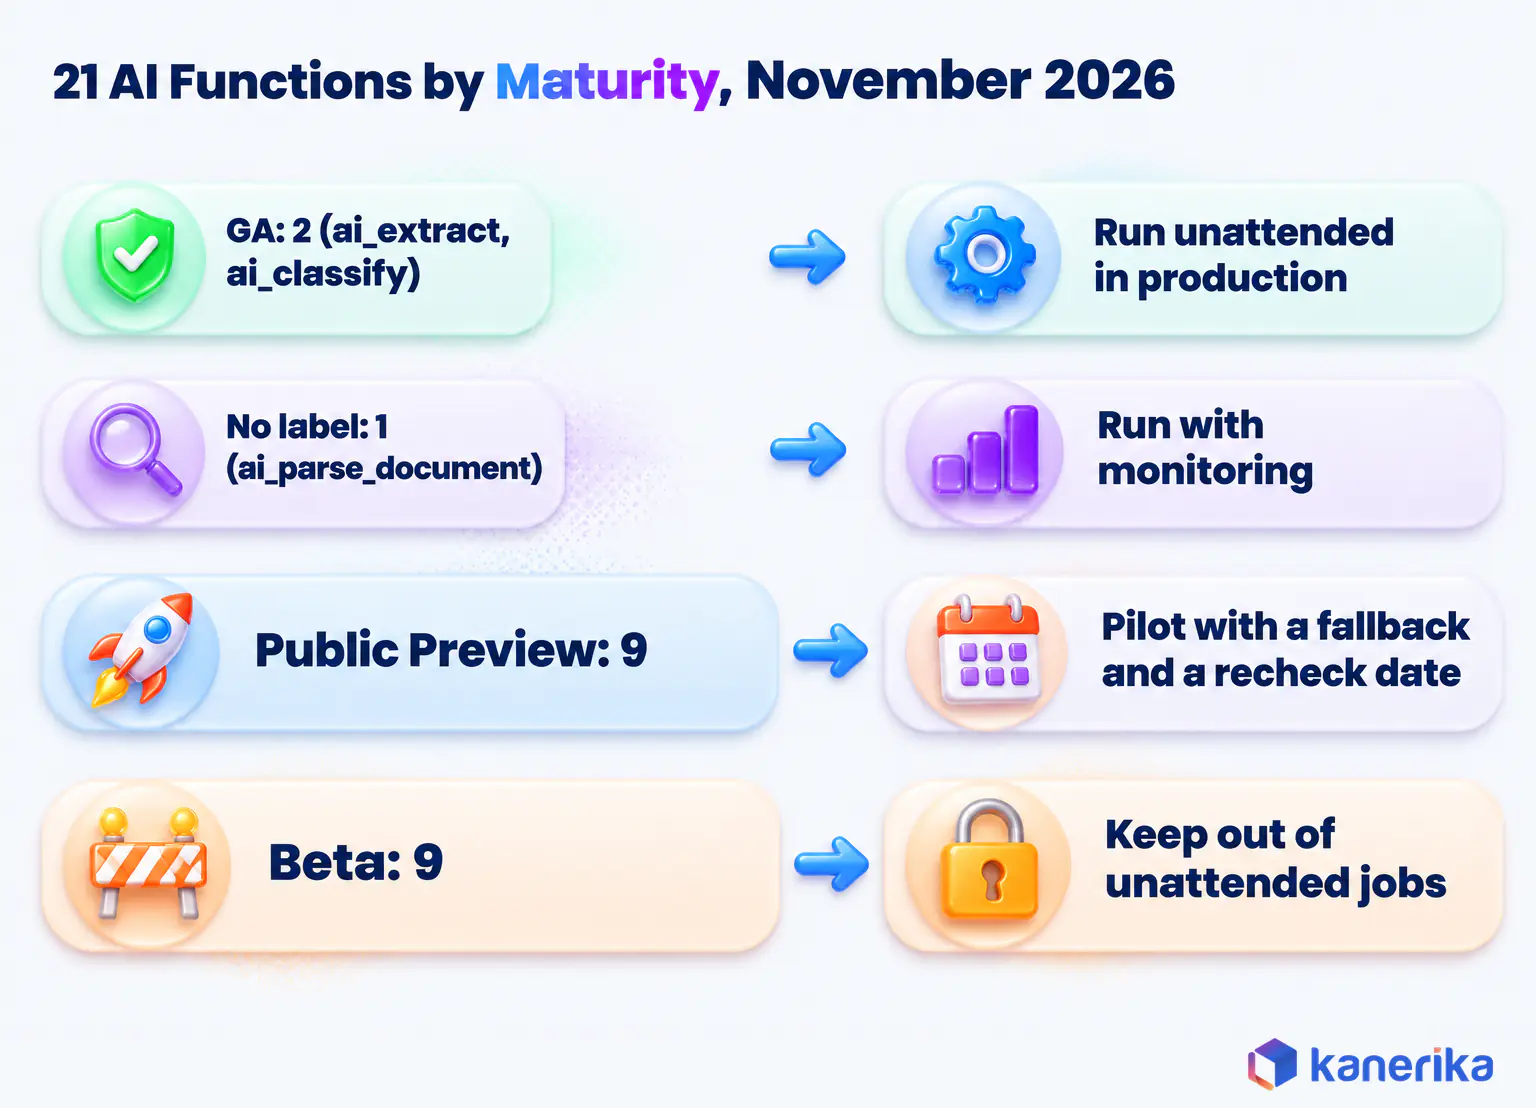
Nine of the 21 carry a Beta label on the docs index. So pilot those first, and keep them out of unattended production jobs until the label changes.
Checklist
Databricks Readiness Checklist
Check runtime versions, warehouse types, governance and data readiness before your first AI Functions pipeline goes into production.
Get the Checklist →All 21 Task-Specific Functions by Task Group
The first group handles documents, audio and text transformation, which is where most pipelines start.
Table 3: Document, Audio and Text Functions
| Function | What it does | Maturity label |
|---|---|---|
| ai_parse_document | Parses text, tables, figure descriptions and layout from files | None |
| ai_extract | Pulls the fields you define from documents or text | GA (June 11, 2026) |
| ai_classify | Sorts text into labels you provide | GA (June 11, 2026) |
| ai_prep_search | Turns parsed documents into search-ready chunks for RAG | Beta |
| ai_search | Returns ranked documents and a grounded answer to a question | Beta |
| ai_enrich | Generates new columns for each row from a schema you define | Beta |
| ai_transcribe | Transcribes audio with timestamps and optional speaker labels | Beta |
| ai_fix_grammar | Corrects grammar | Public Preview |
| ai_translate | Translates text into a target language | Public Preview |
| ai_summarize | Summarizes text | Public Preview |
| ai_mask | Masks entity types such as names and email addresses | Public Preview |
Analysis, Prediction and Search Functions
The second group analyzes text, predicts values and searches indexes, so it carries more Beta labels.
Table 4: Analysis, Prediction and Search Functions
| Function | What it does | Maturity label |
|---|---|---|
| ai_decide | Scores questions against text or data as probabilities, choices or scores | Beta |
| ai_analyze_sentiment | Labels the sentiment of text | Public Preview |
| ai_similarity | Scores the semantic similarity of two strings | Public Preview |
| ai_gen | Answers a prompt with a model Databricks picks | Public Preview |
| ai_predict_class | Trains a classifier and fills rows where the target is NULL | Beta |
| ai_predict_value | Trains a regression model and predicts missing numeric values | Beta |
| ai_forecast | Projects a time series forward to a horizon | Public Preview (version 2 in Beta) |
| ai_detect_anomalies | Flags anomalous values with expected values and bounds | Beta |
| ai_top_drivers | Ranks the dimension values behind a metric change between two groups | Beta |
| vector_search | Queries a search index of embeddings from SQL | Public Preview |
The search pair, ai_prep_search and ai_search, covers chunking and retrieval inside SQL. Teams that need more than that can compare the RAG tools that sit around a retrieval pipeline. Large semantic search jobs also belong on an embedding index, as our guide to Databricks Vector Search indexes explains.
Check Maturity Labels Before Production
The docs index tells only half the story, so read each function’s own reference page too. As of November 3, 2026, ai_extract and ai_classify are generally available. The Databricks June 2026 release notes date that GA to June 11, 2026. Meanwhile, ai_parse_document shows no label, and nine others still show a Public Preview banner.
Preview status matters most for jobs that run unattended, because behavior and regional coverage can still change. A contract pipeline built on ai_parse_document and ai_extract stands on the most settled ground. By comparison, a nightly translation job on ai_translate should carry a fallback and a date to recheck the label.
Version numbers also matter. Databricks recommends ai_extract version 2.0 or above and ai_classify version 2.1. Output from ai_classify 2.0 and 2.1 is not compatible, so pin the version in the options map before you switch.
ai_similarity for Semantic Matching and Deduplication
The ai_similarity function compares two strings and returns a FLOAT that shows how close they are in meaning. A score of 1, for example, means the strings are identical. Since the score is relative, use it to rank rows rather than as a fixed threshold.
Deduplication is the typical job, especially in CRM data. For example, a CRM table might hold one company under four spellings, so ranking each row against a reference name surfaces likely matches.
SELECT company_name
FROM customers
ORDER BY ai_similarity(company_name, 'Databricks') DESC
LIMIT 10;
Each comparison is a model call, so pairwise scoring across millions of rows gets expensive fast. That is also the point where an embedding index starts to pay for itself.
Which Models Work With AI Functions in November 2026
Task-specific functions pick their own model, so this question matters mainly for ai_query. When you name an endpoint, you choose the accuracy, the input types and the DBU rate in one decision. Because the hosted list changes often, treat the table below as a snapshot dated November 3, 2026.
Start a text labeling job on a small open-weight endpoint, and then move up only when a labeled sample says the answers fall short. Reach for a multimodal endpoint only when the input is an image, a video or an audio file.
Table 5: Databricks-Hosted Endpoints for ai_query (as of November 3, 2026)
| Model service name | Inputs listed | Good first use |
|---|---|---|
| system.ai.gpt-oss-20b | Text | High-volume labeling at the lowest DBU rate in Table 10 |
| system.ai.gpt-oss-120b | Text | Open-weight text jobs that need more accuracy than the 20B model |
| system.ai.qwen35-122b-a10b | Text | Open-weight text jobs at a higher output DBU rate, in Public Preview |
| system.ai.glm-5-3 | Text | Open-weight text alternative to test against your labeled sample |
| system.ai.gemma-3-12b, system.ai.kimi-k3 | Text, image | Open-weight options when some rows carry images |
| system.ai.claude-haiku-5-5 | Text, image | Fast proprietary model for routing, tagging and image checks |
| system.ai.claude-sonnet-5-5 | Text | Harder reasoning over long contracts or policy text |
| system.ai.claude-opus-5-5 | Text, image | The hardest reasoning jobs, including scanned pages |
| system.ai.gpt-6-luna, system.ai.gpt-6-1-sol | Text, image | Image description and classification through the files argument |
| system.ai.databricks-gemini-4-argon, system.ai.gemini-3-8-flash | Text, image, video, audio | Mixed media inputs in one pipeline |
| system.ai.grok-4-7 | Not listed | A further proprietary option to benchmark on your own rows |
The inputs column repeats what the Databricks supported-models page lists for each endpoint. Region availability still varies by cloud, and the Gemini models run on a global endpoint that needs cross-geography routing turned on. So confirm that your region serves the endpoint before you build on it.
Open-Weight vs Proprietary Endpoints
Open-weight endpoints such as the GPT-OSS pair and Qwen 3.5 122B carry published DBU rates, so they suit predictable, high-volume batch work. Proprietary endpoints from Anthropic, OpenAI and Google bring newer models into the same SQL call. For example, Claude Opus 5.5, released on September 22, 2026, matches or beats Fable 5.1 on most listed benchmarks.
Claude Sonnet 5.5 followed on September 28, then GPT-6.1 Sol on September 29 and Claude Haiku 5.5 on October 7, 2026. Google also published the Gemini 4 Argon model card on October 13, 2026. For the open-weight side, our guide to open-source LLMs and how they compare covers the families in depth.
Deprecations to Watch
Hosted endpoints retire on published dates, and a pipeline that names a retired endpoint stops working. As of November 3, 2026, Databricks lists DeepSeek V4 Flash (0731) for retirement on November 5, 2026. DeepSeek V4.1 Flash follows on November 19, 2026.
So keep the endpoint name in one place, such as a SQL UDF or a job parameter, and a swap becomes a one-line change. Then rerun your labeled sample on the new endpoint before the old one retires.
Why Data Teams Are Adopting AI Functions
The appeal comes down to fewer moving parts between a table and a model, so three gains show up first.
1. Faster Development With Less Custom Code
A team that wrote a Python service to call a model and write replies back can replace it with a SQL statement. Think back to the two million tickets: the keys, retries and deployment move to Databricks, and the team keeps one SELECT. The maintenance surface then shrinks from an application to a query.
2. Analytics and AI in One Platform
Engineers, analysts and data scientists work on the same tables under one governance model. That consistency pays off as AI jobs multiply, because each one can be tracked the way machine learning model management tracks experiments.
3. Security at the Function Level
Since AI Functions inherit Unity Catalog permissions, security teams get one control point for data and model access. So nobody has to manage API keys across a separate AI stack.
AI Functions Use Case Patterns in Production Pipelines
Most production jobs fall into a handful of repeatable patterns. Each one pairs an input column with a function and then lands a new column that a report, a queue or an app can read.
Use them as a starting map rather than a promise of results. Every pattern still needs a labeled sample from your own data before it runs unattended.
1. Support Teams Routing Inbound Email
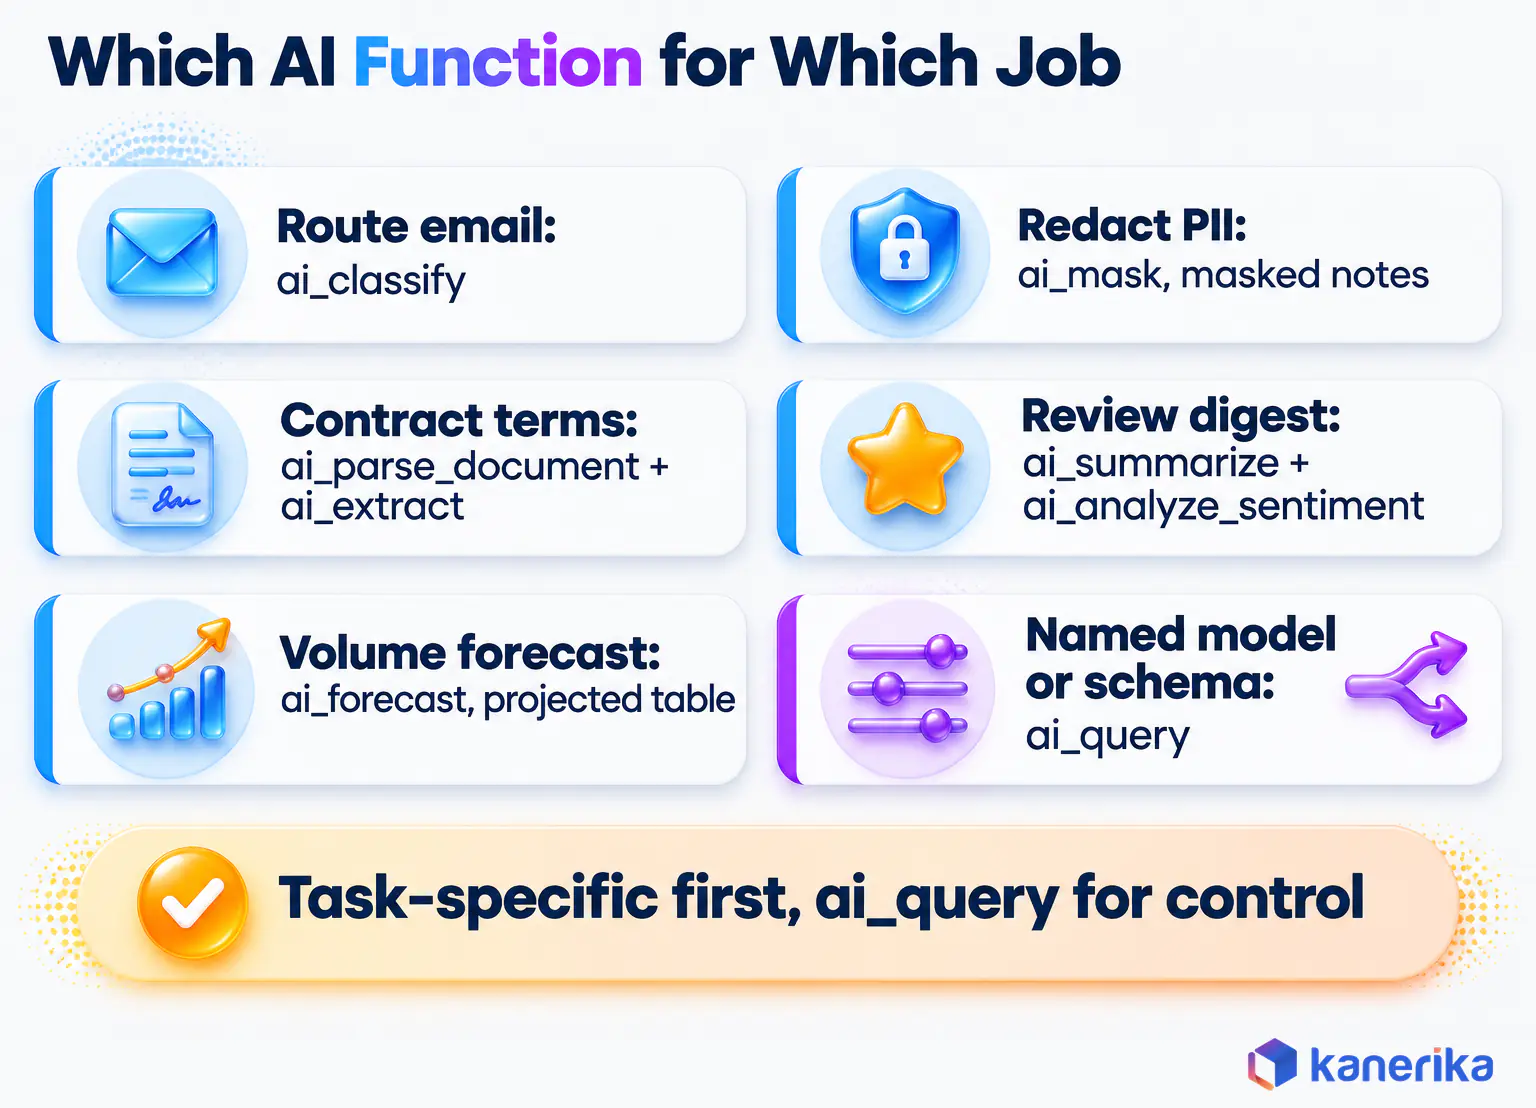
Support teams route inbound email by passing the message body to ai_classify with labels such as delivery status, damage claim and billing. The output is a label column, so a routing rule can read it and pick the queue. Label descriptions, available since version 2.0, also help when two categories sound alike.
2. Data Teams Redacting PII Before Sharing
A data team preparing service notes for a shared table runs ai_mask over the notes column. Names, emails and other listed entity types come back as [MASKED], while the rest of the text stays intact. The masked column then goes to the shared schema, but the raw column stays restricted.
3. Product Teams Summarizing Reviews at Scale
A product team reading thousands of reviews a week calls ai_summarize and ai_analyze_sentiment in one pass. The output is a short summary column as well as a sentiment label. So merchandisers query a table instead of reading a folder of raw text.
4. Procurement Pipelines Extracting Contract Terms
A procurement pipeline reads supplier PDFs from a Unity Catalog Volume and passes them to ai_parse_document. Next, ai_extract pulls pricing tiers, delivery terms and penalty clauses into columns. Analysts can then compare vendors in a table instead of reading each file by hand.
5. A Claims Pipeline Processing Intake Forms
A claims pipeline handles scanned intake forms the same way. First, ai_parse_document turns each image or PDF into text and layout. Then ai_extract returns fields such as claim number and incident date, while low-confidence fields go to a review queue. For the wider discipline, see our guide to intelligent document processing.
6. Planning Teams Forecasting Volume
A planning team passes a table of daily claim or order counts to ai_forecast. The function then returns projected values to a horizon you set, so the team gets a baseline without a separate model to host.
7. Documentation Teams Localizing Content
A documentation team runs ai_translate over a source table of articles to produce each target language. Because ai_translate carries a Public Preview label as of November 2026, the job also needs a fallback and a scheduled recheck.
AI Functions SQL Examples: Five Production Patterns
Calling one function in a notebook is easy. The harder part is packaging those calls so they keep working on a schedule, with typed output, controlled access and file inputs.
These five patterns cover the jobs that come up most once AI Functions move into a pipeline. Each uses syntax from the Databricks reference pages, with model names updated to the November 2026 endpoint list.
1. Enforce Structured Output With responseFormat
Free-text answers are hard to load into typed columns. So the responseFormat argument of ai_query makes the model return JSON that matches a schema you supply. You can write it as a DDL STRUCT string or as a json_schema object with strict set to true.
It needs Databricks Runtime 15.4 LTS or above and works with chat models only. The example below pulls a title, authors and keywords out of research paper abstracts.
SELECT ai_query(
  'system.ai.gpt-oss-20b',
  'Extract research paper details from the following abstract: ' || abstract,
  responseFormat => 'STRUCT<research_paper_extraction:STRUCT<title:STRING, authors:ARRAY<STRING>, abstract:STRING, keywords:ARRAY<STRING>>>'
)
FROM research_papers;
Every row returns the same fields in the same order, so a downstream job can parse the result into columns without guessing.
2. Wrap ai_query in a Reusable SQL UDF
Prompts copied into dozens of queries drift apart over time. Wrapping the call in a SQL user-defined function keeps one tested prompt and one endpoint name in one place. Unity Catalog then controls who may run it through GRANT EXECUTE.
CREATE FUNCTION correct_grammar(text STRING)
  RETURNS STRING
  RETURN ai_query(
    'system.ai.gpt-oss-120b',
    CONCAT('Correct this to standard English:\n', text));

GRANT EXECUTE ON correct_grammar TO ds;

SELECT * EXCEPT (text), correct_grammar(text) AS text
FROM articles;
Analysts call correct_grammar like any built-in function and never see the prompt behind it. When the prompt or endpoint changes, one edit updates every query, so a deprecation swap stays painless.
3. Send Images From a Unity Catalog Volume
The ai_query function also accepts files. Pass the binary content column from READ_FILES through the files argument, and a multimodal model then describes or classifies each image. The reference lists JPEG and PNG as the supported image types.
SELECT *, ai_query(
  'system.ai.gpt-6-luna',
  'What is this image about?',
  files => content
) AS output
FROM READ_FILES('/Volumes/main/multimodal/unstructured/image.jpeg');
Point the path at a folder in the Volume when you want to describe a whole batch of scanned forms in one query.
Kanerika Service
LLM Development Services
Kanerika designs prompts, picks endpoints and builds evaluation sets for LLM workloads, so ai_query jobs return typed, tested output on a schedule.
Explore LLM Development4. Redact PII With ai_mask Before Sharing Data
Support transcripts often carry names, emails and phone numbers that should never reach a shared table. The ai_mask function replaces each entity type you name with [MASKED] but leaves the rest of the text intact.
SELECT ai_mask(
  'John Doe lives in New York. His email is [email protected].',
  array('person', 'email')
);
-- Returns: "[MASKED] lives in New York. His email is [MASKED]."
A NULL input returns NULL, so count NULLs before you trust a masked column. Regulated data usually needs a policy layer as well, and our roundup of data masking tools compares the options.
5. Ingest Documents With ai_parse_document and ai_extract
Contracts, invoices and claims arrive as files. The ai_parse_document function turns each file into structured text and layout. Then ai_extract pulls the fields you define, since it accepts a STRING or the VARIANT that parsing returns but cannot read files directly.
Supported formats are PDF, JPG/JPEG, PNG, TIFF/TIF, DOC/DOCX and PPT/PPTX. Parsing needs Databricks Runtime 17.3 or above, which is a higher floor than the 15.4 LTS the other functions need. Also read the files with the binaryFile format so the function receives raw bytes.
WITH parsed_docs AS (
  SELECT
    path,
    ai_parse_document(content, MAP('version', '2.0')) AS parsed_content
  FROM READ_FILES('/Volumes/finance/invoices/', format => 'binaryFile')
)
SELECT
  path,
  ai_extract(
    parsed_content,
    '["invoice_id", "vendor_name", "total_amount"]',
    MAP('version', '2.1', 'instructions', 'These are vendor invoices.')
  ) AS invoice_data
FROM parsed_docs;
Whichever pattern you use, land the output in a Delta table with the endpoint name and run date as columns. A new model can then be compared with last month’s run on the same rows, so a change is judged on stored results.
AI Functions vs Model Serving vs Custom Code
AI Functions are one of three ways to put a model to work on Databricks data. The other two are a Model Serving endpoint called from an app and custom inference code you build yourself. The right choice depends on whether the job is batch enrichment, a live request or deep customization.
Table 6: AI Functions vs Model Serving vs Custom Code
| Factor | AI Functions | Model Serving endpoint | Custom code |
|---|---|---|---|
| Typical job | Batch enrichment of table columns | Real-time requests from an application | Unusual models, pre- or post-processing |
| Interface | SQL and PySpark functions | REST API | Your own service or notebook |
| Infrastructure | Managed by Databricks | Managed endpoint you configure | Self-managed scaling and retries |
| Governance | Inherited from Unity Catalog | Endpoint permissions | Built and maintained separately |
| Time to first result | One query | Endpoint setup plus client code | A full build |
The tradeoff runs both ways. A team that needs low-latency responses inside an app still reaches for an endpoint, while deep customization still calls for custom code. For batch classification and extraction, however, AI Functions cover the job with far less to maintain.
Many teams keep a few endpoints for latency-sensitive work and route scheduled enrichment through AI Functions. Our Databricks Unity AI Gateway guide covers governance for that gateway layer.
Databricks AI Functions vs Snowflake Cortex AI Functions
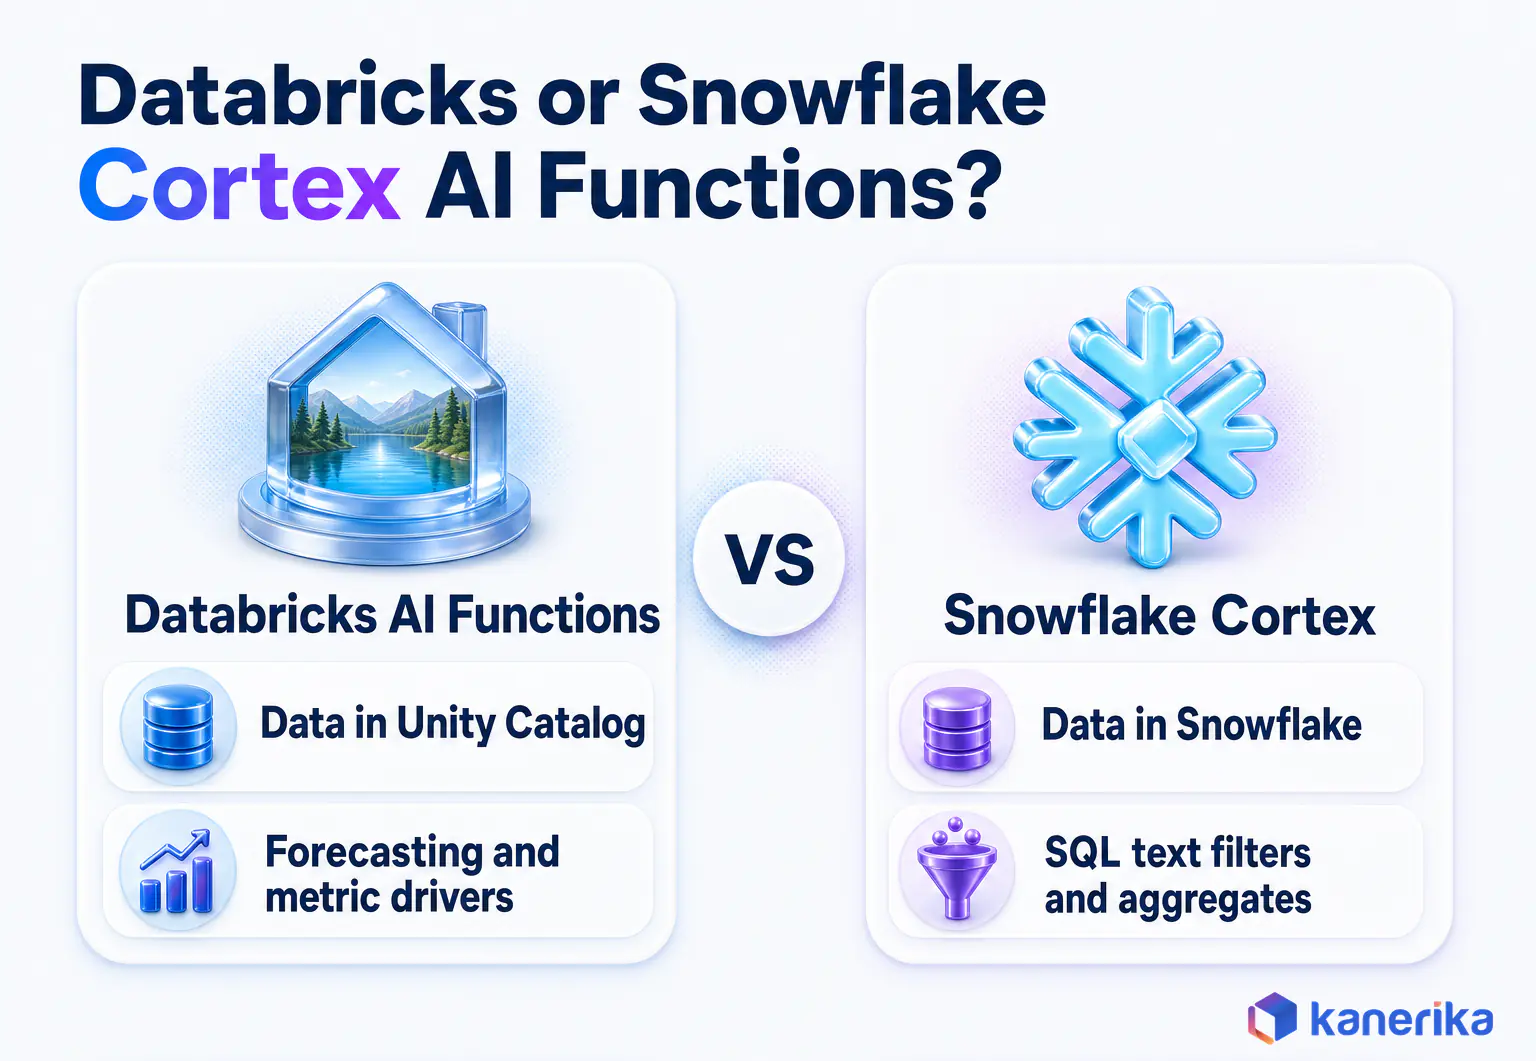
Both platforms let an analyst call a language model from SQL, so the choice usually follows where the data already lives. The two function sets overlap on classification, extraction, translation, sentiment and summarization.
The differences sit in access control, billing units and a few functions that only one side offers. Snowflake documents its set in the Snowflake Cortex AI Functions guide, with models from OpenAI, Anthropic, Meta, Mistral AI, DeepSeek and xAI.
Table 7: Databricks vs Snowflake Cortex AI Functions
| Dimension | Databricks | Snowflake Cortex |
|---|---|---|
| Function family | 21 task-specific functions plus ai_query | AI_COMPLETE, AI_CLASSIFY, AI_FILTER, AI_AGG, AI_EMBED, AI_EXTRACT, AI_SENTIMENT, AI_TRANSLATE, AI_PARSE_DOCUMENT and others |
| General-purpose call | ai_query | AI_COMPLETE |
| Distinctive functions | ai_forecast, ai_top_drivers, ai_predict_class, vector_search | AI_FILTER, AI_AGG, AI_SUMMARIZE_AGG |
| Access control | Unity Catalog EXECUTE grants, down to a single function | USE AI FUNCTIONS account privilege plus the CORTEX_USER or AI_FUNCTIONS_USER database role |
| Billing unit | DBUs | Credits per million tokens; AI_PARSE_DOCUMENT billed per page |
| Cost views | system.billing.usage | METERING_DAILY_HISTORY and CORTEX_AI_FUNCTIONS_USAGE_HISTORY |
| Compute note | No Classic SQL warehouses; Databricks Runtime 15.4 LTS or above | Warehouse cost still applies |
Billing is where teams feel the gap first. Snowflake charges text-generating functions for input and output tokens on top of normal warehouse cost. Databricks, by contrast, records inference under its own billing products, as the cost section below shows.
Which Platform’s AI Functions Fit When
Pick Databricks when your tables and permissions already live in Unity Catalog. It also fits jobs that mix LLM enrichment with forecasting, metric-driver analysis and vector search in one SQL function family.
Pick Snowflake Cortex when the data already sits in Snowflake, because AI_FILTER and AI_AGG let analysts filter and aggregate text in plain SQL.
Moving data across platforms only to reach one function rarely pays for itself. Teams weighing the wider question can start with our Databricks vs Snowflake comparison. Teams already on Snowflake can also review Snowflake Cortex in production before they scale.
Best Practices for Production AI Functions
A query that works on 100 rows can still fail, overspend or leak data at 10 million. Five habits close most of that gap, and each one is cheap to adopt before the first scheduled run.
1. Write Structured, Specific Prompts
A vague ai_query prompt produces inconsistent output across rows. A structured prompt with an explicit format behaves the same way every time, which matters once a job runs unattended.
2. Submit the Full Dataset in One Query
Splitting a dataset into small manual batches slows the job down. Databricks parallelizes and retries on its own when you submit the full dataset in a single query.
3. Set failOnError to False on Large Batch Jobs
One malformed row can stop a whole batch while failOnError stays at its default of true. Setting it to false returns an error message for that row instead, so the rest of an overnight run still finishes.
4. Filter the Table Before You Call the Function
Cost scales with token volume and compute time together. So running a function over a whole table when only a subset needs it multiplies spend without improving the output.
5. Treat Text Columns as Untrusted Input
Prompt injection is the top entry in the OWASP LLM01:2025 Prompt Injection guidance. Its indirect form arrives through external content such as files. So a support email or an uploaded PDF can carry instructions that a model reads as part of your prompt.
Three controls reduce the risk. First, mask PII with ai_mask before text reaches a prompt. Second, keep model output in its own column rather than feeding it into another prompt unchecked. Finally, restrict EXECUTE so only approved principals can call each function.
Our data governance services team scopes Unity Catalog grants and masking rules for AI workloads.
Limitations to Consider
AI Functions remove a lot of plumbing, but they do not remove the core limits of language models. Four limits shape how far a team should trust an unattended job.
1. Token Cost and Latency Grow With Input Size
A function called on every row of a large table behaves very differently than one called on a small subset. Cost and latency both scale with volume, and a bigger warehouse does not change that. So filter first, and then test on a sample before the full run.
2. Model Accuracy Still Needs Human Review
Hallucination risk exists on every platform. So output headed for a compliance decision or a customer-facing screen still needs a review step before it ships. A labeled sample, as the evaluation section below describes, also shows how often the model is wrong.
3. Task-Specific Functions Trade Flexibility for Simplicity
A task-specific function carries a prompt Databricks maintains, but you cannot tune it for an unusual edge case. Once a fixed function stops fitting the job, ai_query is the answer. So start with the fixed function for speed, but also keep an ai_query fallback ready for the odd cases.
4. Rollout Status Still Varies by Function (as of November 2026)
Only ai_query, ai_classify and ai_extract are generally available as of November 2026, so most of the set still sits in Beta or Public Preview. The maturity tables earlier in this guide show which label each function carries.
Labels and region coverage both move between releases, so recheck the reference page of every function a job depends on before your launch date.
How Much Do Databricks AI Functions Cost?
Most AI Functions jobs carry two cost lines, so a budget that counts only one of them comes in low. You pay for the compute that runs the query, whether that is a SQL warehouse, a cluster or a pipeline. Most task-specific functions also bill model inference on top, because they run on Databricks-managed serverless GPUs.
The sections below show what gets billed and what a real volume might cost.
White Paper
Databricks for the Intelligent Enterprise
Kanerika’s white paper on building governed data and AI workloads on Databricks, from lakehouse foundations to production AI.
Read the White Paper →What Gets Billed
First, the AI Functions documentation sorts functions into billing groups. The table shows which ones add inference charges as well as where each one appears in the billing system table.
Table 8: How AI Functions Are Billed
| Function group | Inference billed separately? | Recorded under |
|---|---|---|
| ai_classify, ai_extract, ai_parse_document, ai_search | Yes | AI_FUNCTIONS |
| ai_similarity, ai_analyze_sentiment, ai_summarize, ai_translate, ai_fix_grammar, ai_mask | Yes | MODEL_SERVING, offering type BATCH_INFERENCE |
| ai_query | Yes, for the endpoint you name | Usage of that serving endpoint |
| ai_forecast, ai_detect_anomalies, ai_predict_class, ai_predict_value, ai_top_drivers | No | Query compute only |
Query compute still applies to every row of this table. The forecasting and prediction functions simply add no separate inference line on top of it.
Published Prices per 1,000 Pages or Documents
Databricks publishes per-job prices for its document functions, so a first budget is much easier than token math. The figures below come from the Databricks AI Functions pricing page for US East, checked on November 3, 2026. Note the unit on each row, because parsing is priced per page while extraction and classification are priced per input.
Table 9: Published AI Functions Prices per 1,000 Units (US East)
| Function and document type | Price per 1,000 units |
|---|---|
| ai_parse_document, simple text (per 1,000 pages) | $0.70 to $1.05 |
| ai_parse_document, sparse tables (per 1,000 pages) | $1.40 to $1.75 |
| ai_parse_document, complex tables (per 1,000 pages) | $4.20 to $4.55 |
| ai_parse_document, dense forms (per 1,000 pages) | $5.95 to $6.30 |
| ai_extract, short text or one-page invoices (per 1,000 inputs) | $2.10 to $4.20 |
| ai_extract, precision mode for complex reasoning (per 1,000 inputs) | $28.00 to $50.75 |
| ai_classify, short text (per 1,000 documents) | $0.21 to $0.42 |
| ai_classify, rental contracts (per 1,000 documents) | $2.80 to $4.20 |
In particular, the spread inside ai_parse_document is the number to notice. Dense forms cost roughly six to nine times as much as simple text, so a pilot should sample the real document mix. Precision mode on ai_extract also costs more than ten times the standard rate, so reserve it for fields where an error is expensive.
Track Spend in system.billing.usage
The billing system table records both inference groups, so a query per product shows where the money goes. Start with the AI_FUNCTIONS product, and then add the documented product_features filter to isolate one function such as AI_PARSE_DOCUMENT.
-- AI_FUNCTIONS product usage for one workspace
SELECT *
FROM system.billing.usage u
WHERE u.workspace_id = <workspace_id>
  AND u.billing_origin_product = 'AI_FUNCTIONS';
-- To narrow it to one function, add:
--   AND u.product_features.ai_functions.ai_function = 'AI_PARSE_DOCUMENT'

-- Batch inference usage from task-specific functions, joined to jobs
SELECT *
FROM system.billing.usage u
  JOIN system.workflow.jobs x
    ON u.workspace_id = x.workspace_id
    AND u.usage_metadata.job_id = x.job_id
WHERE u.usage_metadata.workspace_id = <workspace_id>
  AND u.billing_origin_product = 'MODEL_SERVING'
  AND u.product_features.model_serving.offering_type = 'BATCH_INFERENCE';
The docs also give versions of the second query that join to clusters and Lakeflow pipelines instead of jobs. Our guide to Databricks system tables explains the usage schema if you are new to it.
See Total Cost by User
Finance teams also tend to ask who spent the money. So the documented query below joins usage to list prices and totals both inference products by month and principal. It covers the current month and the previous 12.
SELECT
  DATE_TRUNC('MONTH', u.usage_date)::DATE AS usage_month,
  COALESCE(u.identity_metadata.run_as, u.identity_metadata.run_by, 'UNATTRIBUTED') AS principal,
  ROUND(SUM(u.usage_quantity * p.pricing.effective_list.default), 2) AS list_cost_usd
FROM system.billing.usage u
JOIN system.billing.list_prices p
  ON u.cloud = p.cloud
  AND u.sku_name = p.sku_name
  AND u.usage_unit = p.usage_unit
  AND u.usage_end_time >= p.price_start_time
  AND (p.price_end_time IS NULL OR u.usage_end_time < p.price_end_time)
WHERE p.currency_code = 'USD'
  AND u.usage_date >= ADD_MONTHS(DATE_TRUNC('MONTH', CURRENT_DATE()), -12)
  AND (
    (u.billing_origin_product = 'MODEL_SERVING'
     AND u.product_features.model_serving.offering_type = 'BATCH_INFERENCE')
    OR u.billing_origin_product = 'AI_FUNCTIONS'
  )
GROUP BY 1, 2
ORDER BY 1 DESC, 3 DESC;
It reports list prices, so a negotiated discount makes the real figure lower. Rows marked UNATTRIBUTED point to usage with no run_as or run_by identity, which is worth chasing down.
A Worked Example From Published DBU Rates
Take 1,000,000 support tickets labeled through ai_query, where you name the endpoint. Each ticket sends about 400 input tokens and returns about 60 output tokens, so the total is 400 million input and 60 million output tokens.
Databricks prices model serving as DBUs consumed times the SKU price per DBU, according to its foundation model serving pricing page. This estimate uses that page’s example SKU price of $0.07 per DBU on AWS US East.
Table 10: Estimated Inference Cost for 1 Million Tickets (at $0.07 per DBU)
| Model (DBU per 1M input / output tokens) | Input DBU | Output DBU | Total DBU | About USD |
|---|---|---|---|---|
| GPT-OSS-20B (1.000 / 4.286) | 400.0 | 257.2 | 657.2 | $46 |
| GPT-OSS-120B (2.143 / 8.571) | 857.2 | 514.3 | 1,371.5 | $96 |
| Qwen 3.5 122B (3.143 / 31.429) | 1,257.2 | 1,885.7 | 3,142.9 | $220 |
Model choice moves the bill about 5x at the same volume, from roughly $46 to roughly $220. Output tokens drive most of that gap, because Qwen 3.5 122B charges 31.429 DBU per million output tokens. So test the smallest model that meets your accuracy bar first, and move up only when a labeled sample says you must.
Even so, treat these figures as an estimate for ai_query only. Task-specific functions such as ai_classify pick their own model and bill under their own products. Your SKU price, tier and cloud also change the rate, while SQL warehouse compute is billed on top.
The real number is whatever system.billing.usage shows after a pilot run. For wider levers such as warehouse sizing, see our guide to Databricks cost optimization.
Kanerika Service
Data Engineering Services
Kanerika builds the Lakeflow and Workflows layer around AI Functions, with cost tracking in system.billing.usage and pipelines sized for production volume.
Explore Data EngineeringMonitor Progress in the Query Profile
Long batch jobs need a progress view as well as a cost view. On Databricks Runtime 16.1 ML or above, run the query in the SQL editor, open the Running link and then choose AI Query in the query profile.
The panel shows completed and failed inferences as well as total request time, so row-by-row failures show up early.
Some workloads outgrow SQL functions altogether. When the job is a custom model of your own, the Databricks AI Runtime for fine-tuning and GPU training is the next step.
Getting Started With Databricks AI Functions
A first production job takes six steps, and the early ones take minutes. Skipping them, however, is how a pilot ends up failing on a warehouse type or a missing grant.
1. Confirm Compute and Runtime Requirements
AI Functions do not run on Classic SQL warehouses. Notebook and job use needs Databricks Runtime 15.4 LTS or above, with 18.2 or above recommended, while ai_parse_document needs 17.3 or above.
2. Confirm Region and Model Availability
Availability follows Model Serving regions rather than every workspace worldwide. Azure teams get the same requirements, as the Azure Databricks AI Functions page on Microsoft Learn shows. That page lists 20 task-specific functions as of November 3, 2026, though, because ai_transcribe does not appear on it yet.
3. Grant Execute Permissions Through Unity Catalog
By default, every user holds EXECUTE on every AI Function through the system.ai schema. Teams that need tighter control can revoke that default and then grant access per function. Your Databricks account team turns per-function control on. It also needs Databricks Runtime 17.3 LTS or above and a metastore or Unity Catalog admin to run the grants.
Two cautions apply before you run the sample below. The revoke stops every AI Function call at once, so re-grant the approved functions in the same change window. It also does not govern ai_query, whose model access sits under foundation model Unity Catalog permissions.
-- Remove the default open access
REVOKE EXECUTE ON SCHEMA system.ai FROM `account users`;

-- Re-grant only the approved functions
GRANT EXECUTE ON FUNCTION system.ai.ai_summarize TO `data-analysts`;
GRANT EXECUTE ON FUNCTION system.ai.ai_classify TO `data-analysts`;
4. Write and Test the Query
Choose a task-specific function, or ai_query for a custom prompt, and run it against a sample table first. Then compare the output with known-correct answers before you point the query at the full dataset.
5. Monitor Output and Move to Production
Errors caught at the sample stage cost minutes, but errors caught after a full run cost a rerun and a wasted bill.
6. Run at Scale Through Lakeflow, Workflows or Structured Streaming
Lakeflow Declarative Pipelines call AI Functions inside a transformation step, so each run adds a derived column. Our guide to Databricks Lakeflow pipelines covers that setup. Similarly, Databricks Workflows scheduling runs the same query on a timetable with task-level retries.
Finally, streaming is the third route. A Structured Streaming query can call ai_query on each micro-batch, so new tickets or documents get labels as they land rather than overnight. Set failOnError to false there too, so that one bad record does not stall the stream.
Troubleshooting Databricks AI Functions
A failing AI Functions query usually points to the compute type, the runtime version, permissions or the data itself. The table maps each symptom to its likely cause and the documented fix.
Table 11: AI Functions Troubleshooting Guide
| Symptom | Likely cause | Fix |
|---|---|---|
| Function not available on the SQL warehouse | A Classic SQL warehouse | Switch to a Pro or serverless SQL warehouse |
| Runtime error in a notebook or job | Runtime below 15.4 LTS, or below 17.3 for ai_parse_document | Upgrade to 15.4 LTS or above, with 18.2 or above recommended |
| responseFormat rejected | Runtime below 15.4 LTS, or a model that is not a chat model | Upgrade the runtime and then call a chat model endpoint |
| One bad row fails the whole job | failOnError defaults to true | Set failOnError => false and read errorMessage for each row |
| Endpoint not found | A retired or misspelled endpoint name | Check the supported-models page and its deprecation dates |
| Function missing in the workspace | Region not supported, or the preview is not turned on | Check regional availability as well as the Manage previews page |
| Permission denied on a function or UDF | No EXECUTE grant for the user or group | GRANT EXECUTE on the function to that principal |
| NULL outputs | NULL input, as with ai_mask, or a row that failed at the endpoint | Filter NULL inputs first, then inspect errorMessage |
| Slow or uneven runs | Data split into manual batches | Submit the full dataset in one query on Databricks-hosted endpoints |
Where to Look When the Table Does Not Help
Confirm the warehouse type first, because it is the quickest check. Our guide to Databricks SQL warehouse types explains the options and when each one fits.
Errors that persist after these fixes often sit outside AI Functions, such as in the cluster, job or workspace setup. The Databricks troubleshooting guide walks through those wider platform issues step by step.
How to Evaluate AI Functions Output Quality in Production
A query can finish without a single error and still return wrong labels, so output quality needs a check of its own. Three habits cover it, because each one catches a failure the others miss.
Build a Labeled Sample Before the First Full Run
A labeled sample turns “the output looks fine” into a number you can track. So pull a few hundred rows that reflect the real mix of your data, and have a domain expert label them by hand.
- Sample 200 to 500 rows across every category and source system.
- Label them by hand, with a second reviewer on unclear cases.
- Run ai_classify or ai_extract over the sample with each candidate model and prompt.
- Compare agreement rates, and then keep the cheapest option that clears your bar.
That agreement rate becomes the baseline every later prompt or model change has to beat, especially after an endpoint swap.
Track Error Rate and Null Outputs per Run
When failOnError is false, ai_query returns a struct holding the response and an errorMessage for each row. If the run stored that struct in a column named result, count the rows where result.errorMessage is not NULL.
SELECT
  COUNT(*) AS total_rows,
  COUNT_IF(result.errorMessage IS NOT NULL) AS failed_rows,
  COUNT_IF(result.response IS NULL) AS null_responses
FROM ticket_labels_run;
Store these counts with the run date, and then alert when they drift, since a jump usually means the input data or the endpoint changed.
Score Open-Ended Outputs With MLflow Judges
Labels work well for classification, while summaries and generated text need a different check. MLflow scorers handle this with LLM judges for qualities such as correctness, as well as your own code-based checks.
Judges are models too, so spot-check a handful of their scores by hand each month. Our overview of LLM evaluation frameworks compares the wider tooling for teams that need more than built-in judges.
Case Study: Faster Document Processing on Databricks for a Sales Intelligence Platform
A document pipeline is where AI Functions earn their keep, so a real document project is the useful comparison. This Kanerika sales intelligence case study covers a platform whose data engine relied on web scraping and document ingestion. It ran on MongoDB, Postgres and legacy JavaScript processing.
To be clear about scope, though, the project was not an AI Functions deployment. Instead, Kanerika rebuilt the JavaScript document workflows in Python on Databricks and unified disconnected sources. It is the kind of pipeline AI Functions are built to slot into.
Case Study
80% Faster Document Processing on Databricks
Kanerika rebuilt a sales intelligence platform’s JavaScript document workflows in Python on Databricks and unified its data sources, for 80% faster processing and 95% better metadata accuracy.
Read the Case Study →Challenges
- Outdated document workflows created maintenance bottlenecks that delayed service delivery.
- Disconnected data sources limited visibility and slowed access to reliable insights.
- Unstructured PDF and metadata processes added manual effort, so turnaround times stretched.
Solution
- Refactored document workflows from JavaScript to Python in Databricks for easier maintenance and faster processing.
- Integrated the disconnected data sources into Databricks so teams had one view across systems.
- Rebuilt PDF, metadata and classification workflows in Databricks to cut manual effort.
Outcomes
- 80% faster document processing
- 95% improvement in metadata accuracy
- 45% faster time-to-insight
Where AI Functions Fit in a Pipeline Like This
In a pipeline of this shape, ai_parse_document and ai_extract would replace hand-written parsing for PDFs. The ai_classify function would also tag each document by type, while the per-1,000 prices give a cost estimate before any code exists.
The output would land in Delta with the endpoint name and run date as columns. That keeps every model change measurable against the last run, just as the evaluation section describes.
How Kanerika Helps Enterprises Deploy AI Functions on Databricks
Kanerika is a Databricks consulting partner, and an AI Functions rollout with us runs in four stages. Each stage ends with something you can check, so the pilot never outruns the controls.
The first stage is readiness, when we check runtime versions, warehouse types, region and endpoint availability against the Databricks Readiness Checklist. Governance comes second, so we revoke the default system.ai grant, re-grant per function and mask PII before any prompt.
Next comes the cost model. We build a per-job price table plus a DBU estimate against your real volume, and then check it against system.billing.usage after the pilot. Production is the last stage, with Lakeflow or Workflows scheduling, failOnError set to false and a labeled sample that every model change must beat.
Our Databricks consulting services team runs these stages together with specialists from data engineering and LLM development. Prompt design, evaluation and pipeline build then sit with one team instead of three.
Talk to Kanerika
Plan Your First AI Functions Pipeline
Book a working session with Kanerika to scope one AI Functions job, check readiness and governance, and estimate its cost against your real data volume.
Book a Meeting →Wrapping Up
As of November 2026, AI Functions cover 21 task-specific jobs plus ai_query, and the core ones are generally available. So the hard part is no longer the SQL. Instead, it is picking the right function, pinning an endpoint that will not retire under you and counting both cost lines.
Start with a task-specific function, test it on a labeled sample and then read the bill in system.billing.usage after the pilot. With 21 functions to choose from, SQL you can paste and costs you can predict, Databricks AI Functions are ready for a scheduled job once that pilot clears your accuracy bar.
Frequently Asked Questions
What are Databricks AI Functions?
Databricks AI Functions are built-in SQL functions that send column values to an AI model and return the answer as a new column. They cover jobs such as classification, extraction, translation, summarization and document parsing. As of November 2026 there are 21 task-specific functions plus ai_query, all governed through Unity Catalog permissions.
How do Databricks AI Functions work?
A query calls the function on a column, and Databricks sends each value with a task definition or your prompt to a model serving endpoint. The reply comes back as a typed column in the same result. Databricks handles batching, retries and parallelization, so ten rows and ten million rows use the same syntax.
What is the difference between ai_query and ai_gen?
ai_gen takes one prompt and returns text from a model Databricks chooses, which makes it the quickest way to generate content in SQL. ai_query lets you name the serving endpoint, set parameters, send files and enforce structured output with responseFormat. Use ai_gen for simple prompts and ai_query whenever control or a schema matters.
How do Databricks AI Functions compare to Snowflake Cortex AI Functions?
Both run language models from SQL and cover classification, extraction, translation and summarization. Databricks controls access through Unity Catalog EXECUTE grants, bills in DBUs and adds forecasting, metric drivers and vector search. Snowflake uses an account privilege plus a database role, bills credits per million tokens and offers AI_FILTER and AI_AGG for text analysis.
Do Databricks AI Functions work on Classic SQL warehouses?
No. The Databricks documentation states that AI Functions are not available on Classic SQL warehouses, so use a Pro or serverless SQL warehouse instead. Notebooks and jobs need Databricks Runtime 15.4 LTS or above, with 18.2 or above recommended. Region and endpoint availability also vary, so confirm both before planning a rollout.
Can Databricks AI Functions return structured JSON output?
Yes. The responseFormat argument of ai_query makes a chat model return output that matches a schema, written as a DDL STRUCT string or a JSON schema with strict mode. It needs Databricks Runtime 15.4 LTS or above. Task-specific functions such as ai_extract also return structured results for the fields you define in the call.
How do you extract data from PDFs with Databricks AI Functions?
Read the files with READ_FILES using the binaryFile format, then pass the content to ai_parse_document on Databricks Runtime 17.3 or above. It returns structured text and layout. Call ai_extract on that parsed output with the fields you need, such as invoice number and total. The same flow handles images, Word and PowerPoint files.
Are Databricks AI Functions available in Azure Databricks?
Yes. Microsoft documents AI Functions for Azure Databricks on Microsoft Learn with the same requirements, so Azure teams can call them from SQL, notebooks and jobs. Availability still depends on the Azure region of your workspace and the endpoints served there. Check the regional list before you design a production pipeline around one function.
Which Databricks AI Functions are generally available?
As of November 3, 2026, ai_extract and ai_classify are generally available, with GA on June 11, 2026. ai_query followed on June 15, 2026. Nine functions still carry a Beta label, including ai_search, ai_enrich, ai_transcribe and ai_decide, and several others show Public Preview. Keep Beta functions out of unattended production jobs.
Can Databricks AI Functions read images and audio?
Yes, within limits. ai_query accepts JPEG or PNG images through its files argument when you name a multimodal endpoint. ai_parse_document reads PDF, image, Word and PowerPoint files. ai_transcribe turns audio into text with timestamps, but it carries a Beta label as of November 2026, so pilot it before relying on it.
What can you do with Databricks AI Functions?
You can classify support tickets, extract fields from contracts and invoices, parse PDFs, mask personal data, translate text, summarize reviews and score sentiment. Other functions forecast time series, flag anomalies, rank the drivers behind a metric change and search document indexes. Each job runs inside a SQL query, so the output lands in a table.
Can you use Databricks AI Functions in SQL?
Yes. Databricks AI Functions are designed for SQL first, so an analyst adds them to a SELECT statement like any built-in function. They also run from notebooks, Lakeflow Declarative Pipelines and Workflows. Notebook and job use needs Databricks Runtime 15.4 LTS or above, and the functions do not run on Classic SQL warehouses.
What is the difference between Databricks AI Functions and ai_query?
Task-specific AI Functions carry prompts that Databricks writes and maintains for common jobs such as labeling or masking. ai_query is the general-purpose function in the same family. It lets you name the endpoint, write your own prompt, send image files and force a JSON schema. Start task-specific and switch to ai_query when you need control.
What are the best use cases for Databricks AI Functions?
The strongest fits are high-volume batch jobs on text and documents. Typical examples are routing support email, redacting PII before data sharing, summarizing product reviews, extracting contract terms and processing intake forms. Forecasting and translation jobs also fit well. Each case should start with a labeled sample of a few hundred rows before it runs unattended.
Which AI models do Databricks AI Functions support?
Task-specific functions pick their own model. With ai_query you name an endpoint, and the Databricks list as of November 3, 2026 includes GPT-OSS 20B and 120B, Qwen 3.5 122B, Claude Haiku, Sonnet and Opus 5.5, GPT-6.1 Sol and Gemini 4 Argon. Pin the endpoint name in one place, since hosted models retire on set dates.
Why should businesses use Databricks AI Functions?
They remove the separate inference service that used to sit between a table and a model. Teams skip API keys, deployments and custom retry code, and Unity Catalog governs model access the same way it governs tables. That shortens the path from a pilot query to a scheduled job and leaves far less code to maintain.
How much do Databricks AI Functions cost?
You pay for query compute plus model inference in DBUs. Databricks publishes US East prices, such as $0.21 to $0.42 per 1,000 short texts for ai_classify. Parsing runs from $0.70 per 1,000 pages of simple text to $6.30 for dense forms. For ai_query, one million short tickets run about $46 to $220.
How do you track Databricks AI Functions spend?
Query the system.billing.usage table. Functions such as ai_classify and ai_extract appear under the AI_FUNCTIONS product, while ai_summarize and similar functions appear under MODEL_SERVING as batch inference. Join usage to system.billing.list_prices for a monthly cost per user, and check the query profile for failed inferences during a run. It is the fastest way to spot waste.