TL;DR
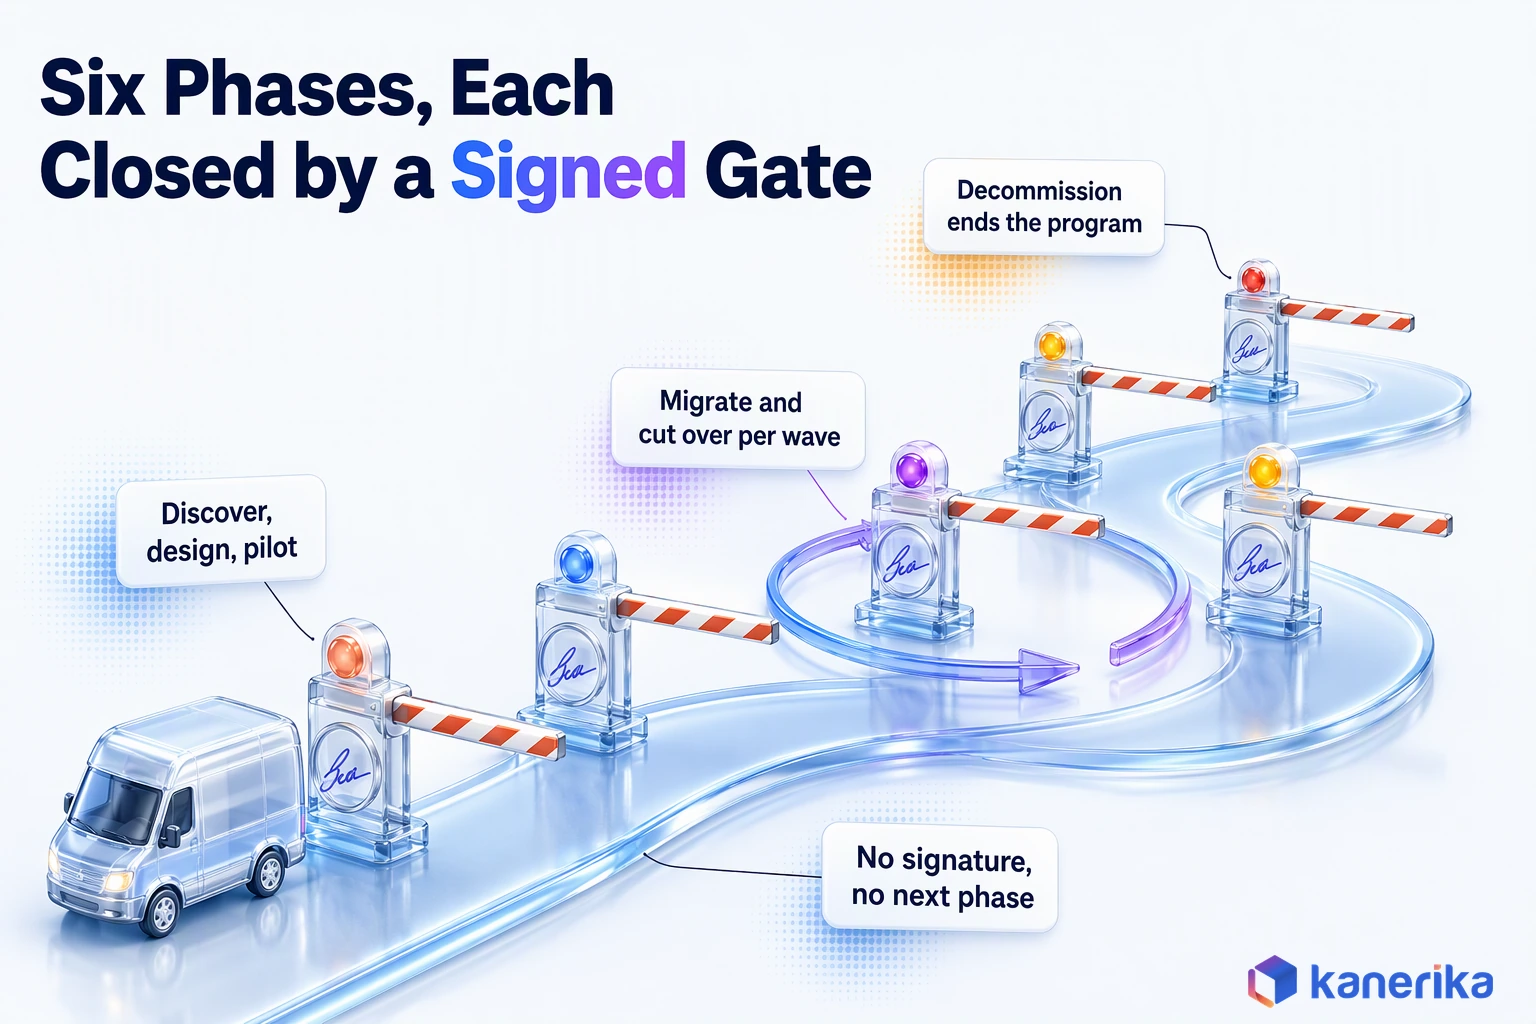
A data migration strategy is a signed plan, run in six gated phases, that fixes outcomes, scope, approach, governance, cutover and success measures up front. The six phases run from discovery and target design through a pilot and wave migration, then on to cutover and decommissioning. Each phase ends at an exit gate, and work moves on only once a named owner signs it. Settle rollback, reconciliation rules and report owners before the first wave starts. Use phased waves for large estates and one cutover for small, simple ones. Judge success by reconciliation pass rate, report parity and retired legacy licenses.
Key Takeaways
- A data migration strategy is a short, signed document that answers why you are moving, what moves, how it moves and how you will judge the result.
- Keep the strategy, the migration plan and the cutover runbook separate, because each has a different owner and a different time horizon.
- Run the work in six phases (discover, design, pilot, migrate, cut over, decommission) and close each one at an exit gate with a named signatory.
- Size the cutover window with arithmetic: replication must apply changes faster than the source creates them, or the sync never converges.
- Validate in layers, from row counts to business-rule reconciliation and report parity, and rehearse the rollback at least once.
- Count the migration as finished only when the legacy system is off, its licenses are retired and the success measures have a first reading.
The Migration Was Done. Then Finance Tried to Close the Month.
Picture a retailer that has just moved its finance data to a cloud warehouse. Every task on the project board is complete, and the old database server is booked for shutdown.
Three days into month-end close, the controller’s team finds that intercompany balances no longer match. The cause is a stored procedure on the old database that quietly netted out internal transfers, a rule nobody had written down.
Every row arrived, so no data was lost in the move. What went missing was a business rule, the person who knew it and a test that would have caught it. A data migration strategy finds that gap before cutover day, while it is still cheap to fix.
What a Data Migration Strategy Is (and What It Is Not)
A data migration strategy is the agreed answer to four questions. Why are you moving data, what moves, how does it move and how will you know it worked? It is written before tools are chosen, and it is signed by the people who own the business outcome.
Even so, the strategy is easy to confuse with the documents that follow it. It sets direction and decision rights for the whole program, so it changes rarely. The migration plan turns that direction into waves, dates and staffing, while the cutover runbook is the hour-by-hour script for the switch itself.
Keeping the three apart saves arguments later. When a wave slips, the plan changes and the strategy stays put. When someone asks to add a new source halfway through, the strategy is the document that says who decides.
Strategy vs Migration Plan vs Cutover Runbook
Each document answers a different question for a different reader. The table below shows how they divide the work, so each owner knows which document is theirs.
| Document | Question it answers | Owner | Time horizon |
|---|---|---|---|
| Data migration strategy | Why are we moving, what moves and how do we judge success? | Executive sponsor with the steering committee | The whole program, from assessment to retirement |
| Migration plan | Which waves run when, with which people and tools? | Migration lead | Per wave, revised as each wave closes |
| Cutover runbook | What happens, step by step, on switch day and how do we roll back? | Cutover manager | The cutover window and hypercare |
When a line could sit in more than one, a quick test helps sort it. Ask whether the line would change when a wave slips by two weeks. If it would, it belongs in the plan or the runbook, and the strategy stays short enough for executives to read and sign.
Types of Migration the Strategy Must Cover
A single program often mixes several kinds of movement, and each one puts something different at risk. A storage move risks file integrity, while a BI platform move risks the meaning of numbers that leaders read every week.
| Type | What moves | What the strategy must protect |
|---|---|---|
| Storage | Files and objects between storage systems | Integrity, permissions and retention rules |
| Database | Tables, schemas and stored logic between engines or versions | Business rules buried in procedures, keys and constraints |
| Application | Data behind an application that is replaced or upgraded | Workflows and the users who depend on them |
| Cloud | Workloads from on-premises to cloud, or between clouds | Residency, security controls and running cost (see this guide to multi-cloud data migration) |
| ETL and BI platform | Pipelines, semantic models and reports | Calculations, refresh schedules and report parity |
Name every type in scope at the start, before any design work begins. A strategy written only for the database move tends to forget the pipelines and reports on top of it. Those layers are also where users notice problems first.
Why a Data Migration Strategy Matters More in 2026
Three pressures make the planning harder to skip in 2026. Legacy ETL and BI tools are being retired, AI projects need governed data, and rules on privacy and data residency keep tightening.
Retirement is the first pressure. Teams moving off older ETL and reporting platforms are moving more than tables. They carry years of logic held in mappings, scripts and report formulas. That logic is also exactly where the finance problem in the opening came from.
AI is the second. Gartner predicted in February 2025 that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. That makes a migration the natural moment to decide which data will be trusted, labeled and governed in the target. Fixing it afterward means touching every consumer twice.
Regulation is the third pressure, since personal data has to be classified before it moves and some of it must stay in a specific region. Take EU customer records that the business has decided to keep in an EU region. The wave that carries them needs a residency sign-off before design starts, with a named owner and a written record of the call.
For a wider view of where tools and approaches are heading, this roundup of data migration trends covers the main shifts. The episode below covers those trends in more depth.
The Seven Parts of a Data Migration Strategy Document
A good strategy document fits on one page, with appendices behind it. That limit forces each part to give a clear answer, so a sponsor can sign it quickly.
Think of the page as a canvas with seven boxes. Each box answers one question and also carries one signatory. If a box has no signatory, nobody will defend it when the schedule gets tight.
Take scope, for example. A useful scope box lists what moves and also what will be retired without moving. Retiring unused tables and reports before migration shrinks the work and removes data nobody would test properly anyway.
| Part | Question it answers | Signed off by |
|---|---|---|
| 1. Outcomes and success criteria | What business result justifies the move? | Executive sponsor |
| 2. Scope and retire list | What moves, what stays and what is switched off? | Business data owners |
| 3. Target state | Which platform, architecture and data model do we land on? | Enterprise or data architect |
| 4. Approach and wave plan | How does data move, and in what order? | Migration lead |
| 5. Governance and decision rights | Who decides on scope, personal data, residency and go or no-go? | Steering committee |
| 6. Risk, continuity and rollback | What can fail, how long can the business wait and how do we go back? | Business continuity owner with IT operations |
| 7. Success measures | Which numbers prove the migration worked, and when are they read? | Executive sponsor and finance |
How the Signed Canvas Settles Later Arguments
Once the seven boxes are signed, the canvas becomes the reference for every later argument. Here is an illustrative case from the middle of a program. In wave three, the sales operations lead asks to add a legacy CRM extract to the current wave because a new dashboard needs it.
Under the canvas, the request goes to the business data owners who signed the scope box, not to the engineer who received the ticket. They check it against the retire list and the wave plan. Their call is to schedule the extract for the next wave, so the current wave’s reconciliation stays closed.
The decision and its reason go into the scope appendix, and the argument ends there. The same route works for every box, so a request to skip a rehearsal goes to whoever signed continuity.
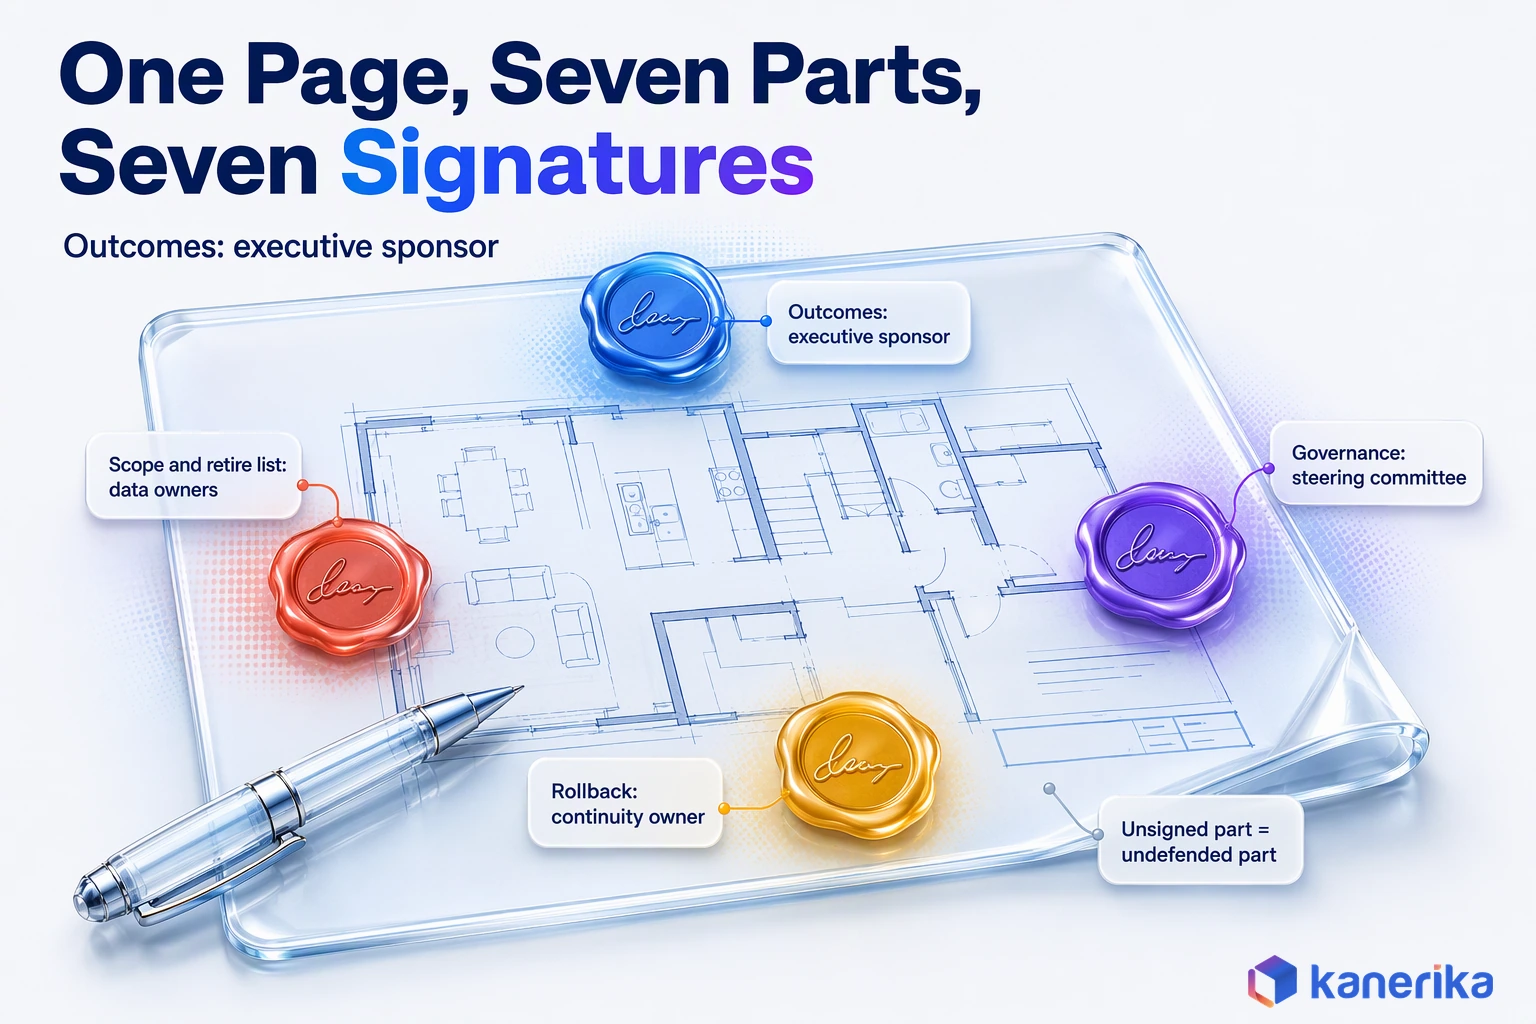
That route only works while the canvas stays one page. The inventory, dependency map, mapping specifications and rollback runbook hang off it as appendices, so each one can change without reopening the signed page.
Choosing Your Migration Approach
The approach is how data travels from source to target over time. It drives downtime, cost and how much risk sits on a single weekend. That makes it a strategy decision, too important to leave to a tool vendor.
Four approaches cover almost every program, and they differ mainly in where the risk sits. A big bang concentrates it on one weekend. Waves spread it out but keep two platforms running for longer.
A parallel run doubles operating effort for each close it covers. CDC buys near-zero downtime at the cost of replication tooling and the convergence arithmetic worked through later. Each approach still has a situation where it is the obvious pick.
- Big bang. Move everything in one cutover window. Pick it when the estate is small, dependencies are simple and the business can accept a planned outage.
- Phased waves. Move groups of related workloads one at a time. Pick it when the estate is large or dependencies cross many teams.
- Parallel run. Run old and new systems side by side and compare outputs. Pick it when results feed regulated reports or the financial close.
- Trickle or change data capture (CDC). Load once, then sync changes continuously until the switch. Pick it when downtime must stay close to zero.
The 7 Rs at the Workload Level
At the workload level, AWS lists seven migration strategies, often called the 7 Rs, and each choice belongs in a box on the canvas. Retire feeds the scope and retire list (part 2) directly, while retain keeps a workload where it is for now.
Rehost and relocate move a workload unchanged, to new infrastructure or to another cloud platform. Repurchase swaps it for a product such as SaaS, and replatform adds small optimizations. Refactor or re-architect rebuilds it around cloud-native services.
For large migrations, AWS notes that rehost, replatform, relocate and retire are the common choices. Moving a workload as is now and modernizing it later is itself a strategy decision, so record it in the approach box (part 4) with its owner.
Choosing between approaches for a specific platform takes gates and weighted scoring. That work sits in our data migration decision framework, so the strategy simply records the choice, the reason for it and who approved it.
Kanerika Service
Data Migration Consulting Services
Kanerika plans and runs ETL, BI and RPA migrations in gated waves, with reconciliation, cutover and legacy retirement built into the program.
Explore Migration ServicesThe Step-by-Step Framework: Six Phases With Exit Gates
A step-by-step framework turns the strategy into work that can be checked. Each phase below ends at an exit gate, a short list of conditions that a named owner must confirm before the next phase starts.
Gates matter because migrations rarely fail in one dramatic moment. They fail by drift: a mapping nobody reviewed, a pilot skipped to save a week, a rollback plan that was never tried. A gate stops that drift at a known point, before it reaches cutover.
The six phases are discover, design, pilot, migrate, cut over and decommission. Large estates repeat the migrate and cutover phases for each wave, so those gates run many times over the life of the program.
Phase 1: Discover and Profile the Source Estate
Discovery builds an honest picture of the source estate, including the parts nobody wrote down. Microsoft’s Cloud Adoption Framework advises teams to discover all dependencies first, and the reason is practical.
For instance, a table that looks unused may feed a monthly regulatory extract. Likewise, a report may depend on a spreadsheet that someone uploads by hand every Monday. Profiling is where the finance problem from the opening would have surfaced. Running old procedures against real data exposes rules that live only in code, such as the netting step.
- Inventory databases, pipelines, reports and file feeds, with an owner for each
- Profile data for nulls, duplicates, odd codes and fields reused for other purposes
- Map upstream and downstream dependencies, including manual workarounds
- Flag personal and regulated data for classification
Deliverable: a source inventory with owners, a dependency map and a data profile report. Exit gate: every in-scope object has a named owner and a keep, move or retire decision.
Phase 2: Design the Target, Mappings and Wave Plan
Design decides where each piece of data lands and in what order it moves. The core artifact is the mapping specification, which records the source field, the target field, the transformation rule and the person who approved that rule.
Here is one illustrative row, written for the netting rule from the opening. The field names are examples, but the shape is what a reviewer should expect on every line.
| Source field | Target field | Transformation rule | Tolerance | Approved by |
|---|---|---|---|---|
| legacy_gl.ic_amount | fin.fact_ledger.intercompany_net | Net transfers between group entities before posting, as the old stored procedure did | Matches the legacy close to the cent | Group financial controller |
Waves then come from the dependency map. Workloads that share tables or feed each other move together, and each wave should be small enough to test fully before the next one starts.
Effort depends mostly on how much logic must be converted, how clean the data is and how many reports need parity checks. Raw data volume usually matters less than people expect.
A workable first estimate counts those three items for each wave and gives each one a rough time per item. The pilot in Phase 3 then replaces those rough times with measured ones. To estimate migration cost, effort and timeline in more detail, use the worked tables in the decision framework.
Migration ROI Calculator
Estimate Your Migration ROI
Use Kanerika’s migration ROI calculator to compare the effort, cost and timeline of your planned migration before you sign the wave plan.
Calculate Migration ROI →- Write mapping specs with business rules in plain language
- Group workloads into waves by dependency
- Set tolerances for each reconciliation check
- Agree the target security model and naming standards
Deliverable: approved mapping specs, a target design and a dated wave plan. Exit gate: business owners have signed the rules for the first wave and the wave plan has dates.
Phase 3: Build and Run a Representative Pilot
A pilot proves the approach on real workloads before the program commits to it. Pick a slice that includes hard cases, such as a complex stored procedure, a very large table and a report that finance relies on.
Automation earns its place here, especially on large estates. Conversion accelerators, scripted loads and automated reconciliation make each later wave repeatable, and the pilot shows how well they handle your code. This look at the role of automation in migration also covers what to automate at each stage.
Tool categories include replication and CDC services, ETL conversion accelerators and validation frameworks. The strategy only needs to name the category chosen for each workload type.
- Build pipelines and conversions for the pilot set
- Run full reconciliation on pilot data
- Time each step to calibrate wave estimates
- Log defects and fix the conversion rules at the source
Deliverable: a pilot report with timings, defects and reconciliation results. Exit gate: the pilot reconciles within agreed tolerances and the measured timings fit the wave plan.
Phase 4: Migrate in Waves With Reconciliation
Wave execution is where the program spends most of its time, so its loop must be tight. Every wave follows the same loop of load, reconcile, triage exceptions, fix and sign off.
Exceptions also need a queue with owners. When a row fails a business rule, someone must decide whether the source data, the mapping or the tolerance is wrong. Without a queue, whoever happens to be on call makes those decisions silently.
Teams sometimes call this repeatable loop a migration factory. The name fits, because the gain comes from running the same steps the same way, wave after wave, and improving the loop between waves.
Checklist
Data Migration Checklist
Kanerika’s data migration checklist covers inventory, validation rules, cutover rehearsal and sign-off, so every wave follows the same tested loop.
Get the Checklist →- Load the wave and capture run logs
- Reconcile counts, checksums and business rules
- Clear the exception queue with named owners
- Collect business sign-off for the wave
Deliverable: a reconciliation report and an exception log per wave. Exit gate: every exception is closed or accepted in writing, and the business owner has signed the wave.
Phase 5: Cut Over, Roll Back if Needed, Hypercare
Cutover is the moment when users and systems switch to the target. The go or no-go call should rest on criteria agreed in advance, so the decision on the night is a simple check against them.
Choose online or offline cutover separately for each workload, since targets differ. Azure Database Migration Service, for example, supports online migrations with minimal downtime. Azure SQL Managed Instance targets can run online or offline, while Azure SQL Database targets are offline only. Offline is simpler but needs a longer outage.
Hypercare then follows the switch. For an agreed period, the migration team stays on call, watches loads and report usage, and fixes issues quickly before handing over to normal support.
- Final reconciliation within tolerance
- Rollback rehearsed, with its owner on shift
- Business testers have signed parity for critical reports
- Support rota and user communications ready
Deliverable: a signed go or no-go record and a hypercare log. Exit gate: critical defects are closed and loads run cleanly for the agreed hypercare period.
Sizing the Cutover Window: A Worked Example
The cutover window is the outage the business must accept, so size it with arithmetic before you promise a date. The figures below are illustrative inputs, chosen so that the method is easy to follow.
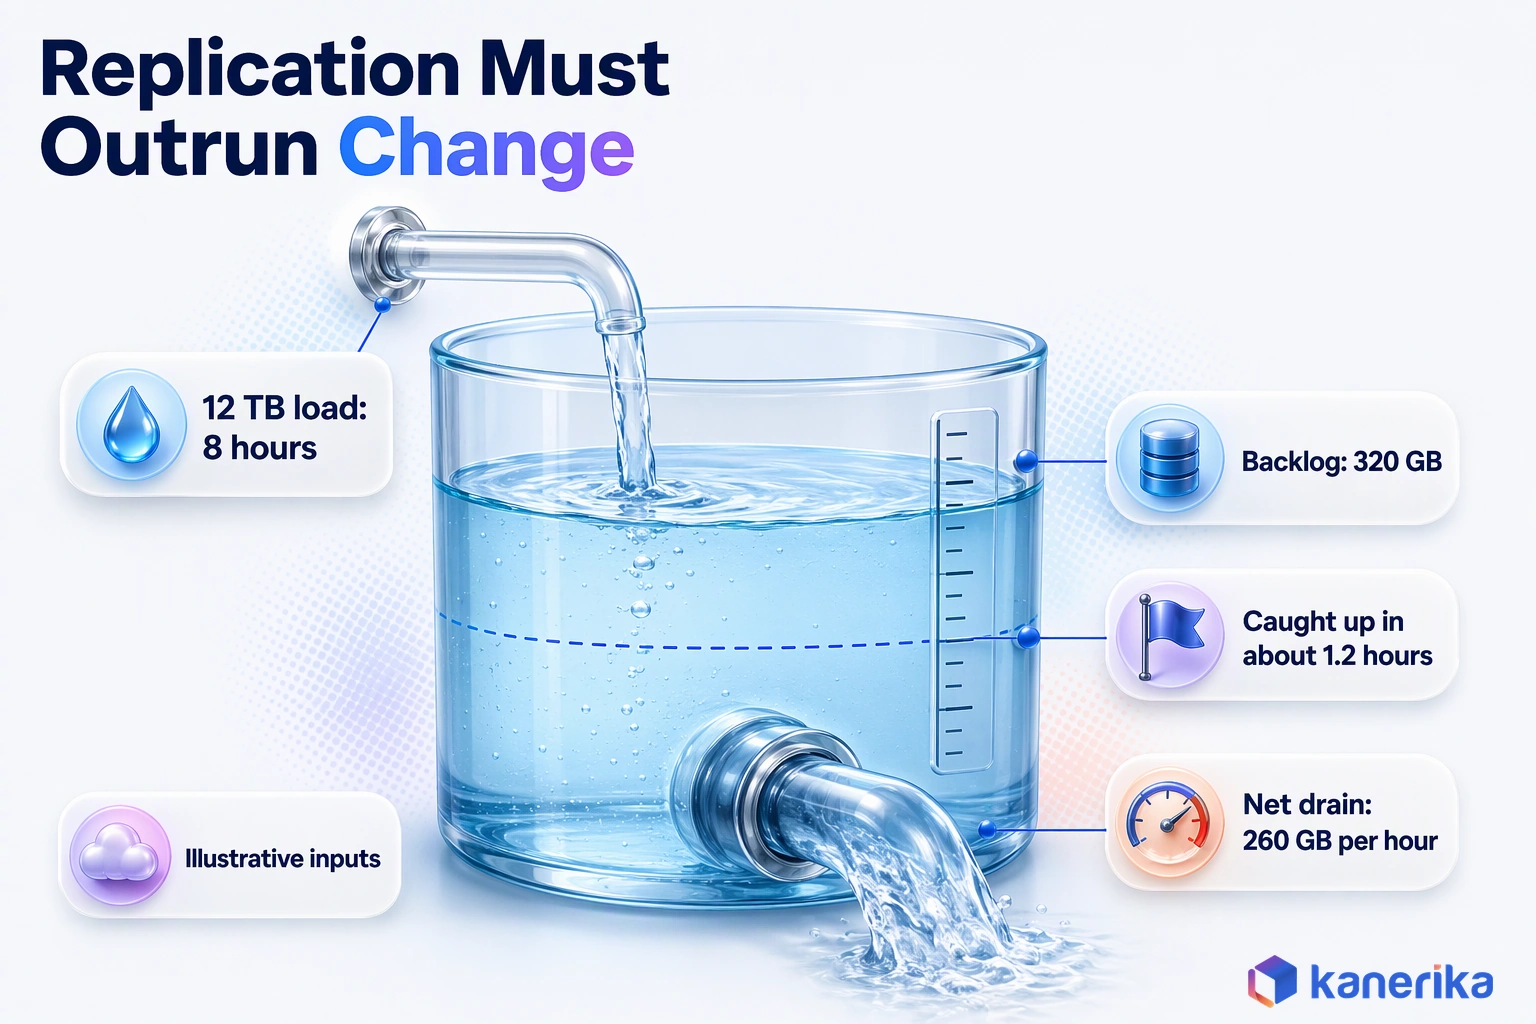
Assume a 12 TB database that loads at 1.5 TB per hour. The initial load takes 8 hours, and the source stays live the whole time. While it runs, the source changes at 40 GB per hour, so 320 GB of changes pile up.
Once the load ends, replication applies changes at 300 GB per hour. New changes keep arriving at 40 GB per hour, so the backlog shrinks at a net 260 GB per hour. At that rate, the 320 GB backlog clears in about 1.2 hours.
| Input | Value | Result |
|---|---|---|
| Initial load | 12 TB at 1.5 TB per hour | 8 hours, with the source still live |
| Source change rate | 40 GB per hour | 320 GB backlog when the load ends |
| Replication apply rate | 300 GB per hour | Net drain of 260 GB per hour |
| Backlog catch-up | 320 GB at 260 GB per hour | About 1.2 hours |
| Outage | Final delta freeze plus validation | Set by your checks, since the load ran online |
After catch-up, the outage covers only the final freeze, the last small delta and the validation checks. The rule to remember is simple. Replication must apply changes faster than the source creates them, or the sync never converges and no cutover date is safe.
Phase 6: Decommission and Realize Value
Decommissioning is the phase that gets cut when budgets run short, and it holds much of the business case. Until the old system is switched off, you pay for two platforms and users can drift back to the familiar one.
Set retire conditions in the strategy itself, before the first wave. Typical conditions are a clean parallel period, report parity signed by owners and an archive that meets retention rules.
- Archive data needed for legal retention in a readable format
- Remove user access, then shut down jobs and integrations
- End or reduce legacy licenses and support contracts
- Point the data catalog and lineage at the target
Deliverable: a decommission certificate and an archive index. Exit gate: the legacy system is off, its licenses are retired and the success measures have their first reading.
Governance and Decision Rights
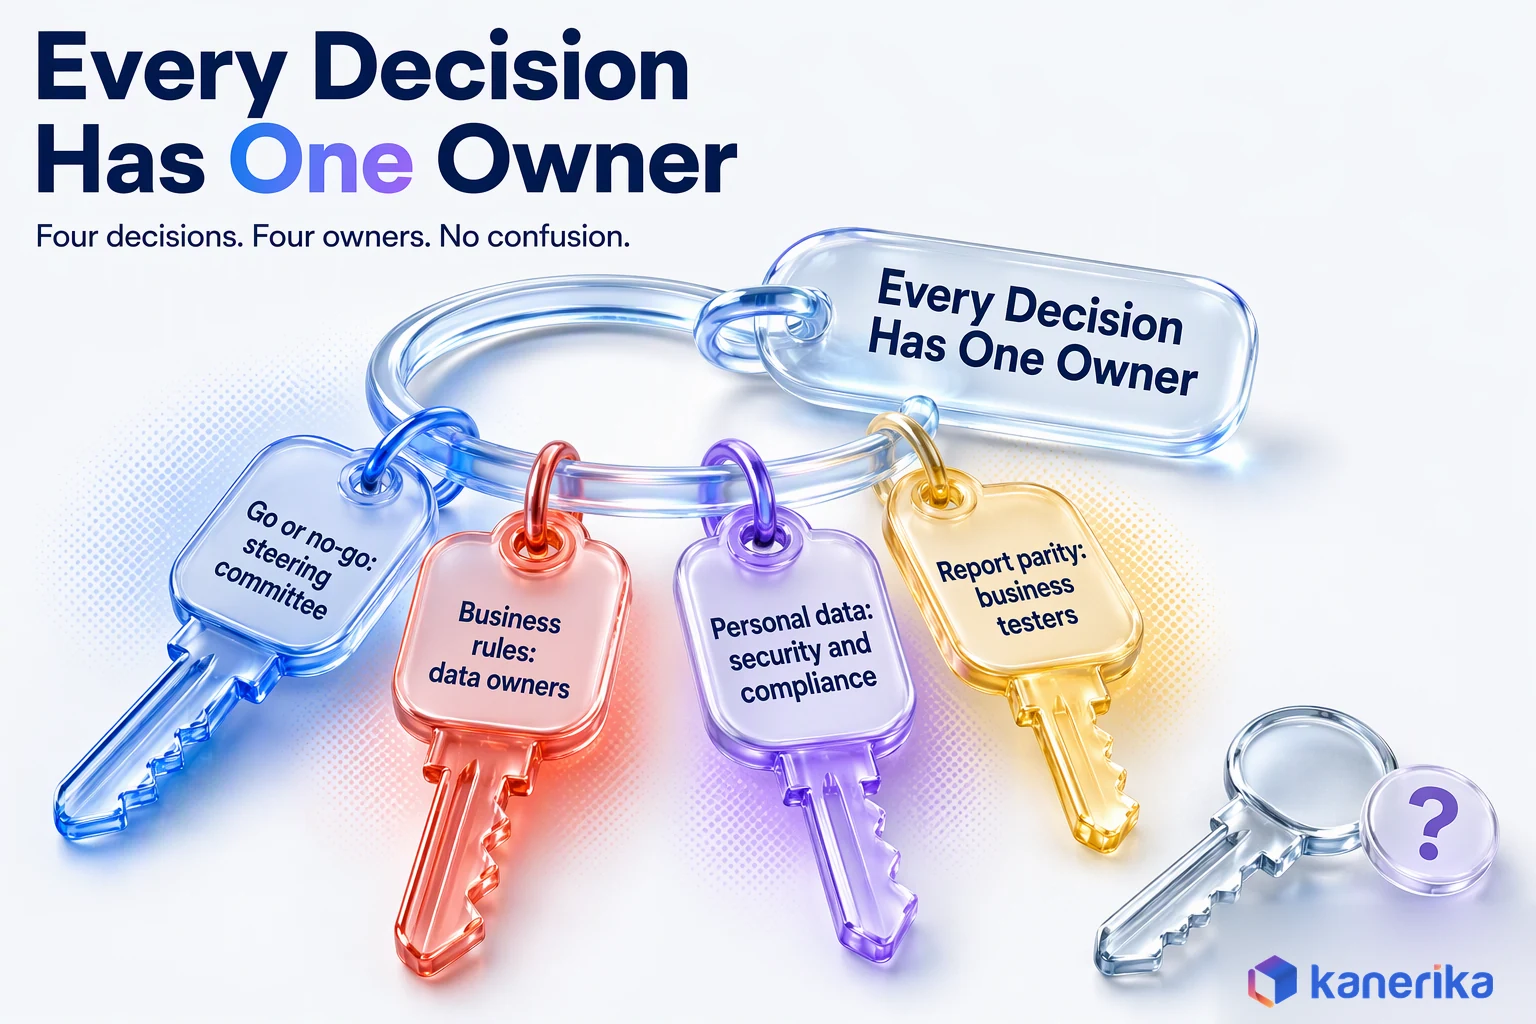
Governance in a migration means knowing who decides what before the decision becomes urgent. A short table of decision rights settles most disputes before they start.
Consider, for example, a column that holds customer birth dates. Someone has to decide whether it counts as personal data, whether it may leave its current region and who can see it in the target. If that decision has no owner, the engineer working the ticket makes it by default.
| Role | Decisions they own |
|---|---|
| Steering committee | Scope changes, budget, priority between waves and the final go or no-go |
| Business data owners | Business rules, reconciliation tolerances and retire decisions for their data |
| Migration lead | Wave plan, tooling and technical readiness for cutover |
| Security and compliance | Classification of personal data, data residency and the access model in the target |
| Business testers | Report parity sign-off and acceptance of each wave |
Lineage and access controls should arrive in the target together with the data. Otherwise, rebuilding them after go-live leaves a window where nobody can say where a number came from or who is allowed to see it.
Write the decision rights into the strategy, then review them at each wave gate. Kanerika’s data governance services cover this carry-over of lineage, classification and access controls into the new platform.
Data Quality, Validation and Rollback
Validation answers a single question: does the target give the same answers as the source, within tolerances the business has agreed? It works in layers, and each layer catches errors that the one before it misses.
Row counts come first, because they are cheap and catch gross failures such as a dropped partition. Checksums or column hashes then catch values that changed in transit.
A practical recipe runs in two steps. First, compute a per-day fingerprint on both sides and compare them. Then hash individual rows only for the days that differ, so the expensive check runs on a small slice. The example below uses SQL Server syntax.
-- Step 1: per-day fingerprint, run on source and target
SELECT order_date,
       COUNT(*)                    AS row_count,
       SUM(order_total)            AS total_amount,
       COUNT(DISTINCT customer_id) AS customers
FROM sales.orders
GROUP BY order_date;

-- Step 2: only for days that differ, hash each row and diff
SELECT order_id,
       HASHBYTES('SHA2_256',
         CONCAT_WS('|', order_id, customer_id,
                   CAST(order_total AS DECIMAL(18,2)), status)) AS row_hash
FROM sales.orders
WHERE order_date = '2026-03-31';
Cast every column to the same type and format on both sides before hashing. When source and target run different engines, use each engine’s own hash function on that same normalized string.
Business-rule reconciliation then tests things like account balances and order totals. Report parity is the last layer, where owners compare the reports they actually use. The opening example failed at the third layer, since counts and checksums matched while the netting rule was missing.
A rollback plan counts only if it has been tested. Set these criteria before cutover:
- The rollback has been rehearsed at least once on production-like data.
- It is time-boxed, with a point of no return written into the runbook.
- A named owner can trigger it without waiting for a meeting.
- Data written to the target after the switch has a plan, either replay or manual re-entry.
For the full test plan, including test types and sampling, see this guide on how to ensure data quality during data migration.
People, Communication and Adoption
A migration succeeds only when people trust the new numbers and stop using the old ones. That is why adoption is a workstream with its own owner, plan and measures.
Start with report owners. Each important report needs a person who will compare the old and new versions before signing off on parity. Finance teams, for instance, often want two closes in parallel before they let go of the old system.
Training works best when it is short and tied to real tasks. For example, show analysts where their usual tables now live, which names changed and where to raise a data issue.
Communication also needs a steady rhythm. Teams that first hear about cutover a week before it happens tend to resist it. Teams that saw the wave plan months earlier simply plan around it, and some ask to go first.
- Name an owner for every critical report
- Run parallel sign-off with business users
- Publish a communication calendar for each wave
- Give users one place to report data issues
Fear of the unknown is the usual source of resistance, and a visible plan with named owners answers most of it before it hardens.
Measuring Success: Data Migration KPIs
KPIs turn the outcomes box of the strategy into numbers that someone reads after go-live. The targets below are examples to adapt to your program rather than industry benchmarks.
Pick a small set, then read them at fixed points. A program that tracks dozens of measures tends to track none of them well.
| KPI | Example target | When measured |
|---|---|---|
| Reconciliation pass rate | 100% of critical checks, agreed tolerance for the rest | Every wave and at cutover |
| Critical defects at cutover | Zero open | Go or no-go meeting |
| Downtime vs plan | Within the planned window | Cutover night |
| Report parity | All critical reports signed by their owners | Before retirement |
| Legacy licenses retired | All in-scope licenses ended | Decommission phase |
| Time to insight | Faster refresh or report delivery than the baseline | After hypercare ends |
Report the first four during the program and the last two after it. The last two are the ones the sponsor will be asked about a year later, so record their baseline before migration starts.
Common Data Migration Strategy Mistakes
The same handful of mistakes shows up across industries. Each one traces back to a gap in the strategy itself, so a better tool alone does little.
- Treating migration as an IT task. Without business owners, nobody signs the rules. The decision rights table in the governance section exists to stop this.
- Skipping discovery. Undocumented dependencies surface as cutover failures. Phase 1’s exit gate exists to stop this.
- Moving everything. Data that should have been retired doubles test effort. The retire list in the scope box prevents it.
- Validating with counts only. Matching row counts say nothing about balances and totals. The layered checks in each Phase 4 wave catch what counts miss.
- An untested rollback. An unrehearsed plan tends to fail under pressure. Phase 5’s gate asks for a rehearsal for this reason.
- Leaving the old system running. Users drift back and costs double. Phase 6’s retire conditions close the business case.
Industry context changes which mistake hurts most. In fleet and logistics, counts-only validation is the costly one, because row counts can match while GPS events arrive out of order. This look at data migration in transportation covers that case.
In plants, skipped discovery hurts most, since shop-floor feeds into ERP are easy to miss. This guide to data migration in manufacturing walks through those systems.
How Kanerika Delivers a Data Migration Strategy
Kanerika runs migrations as staged programs with the same gates described above. The work starts with an assessment of the source estate, its owners and its logic, which then produces the inventory and the first wave plan.
A pilot follows, using FLIP migration accelerators to convert pipelines, reports or workflows and to time the conversion on the client’s own code. FLIP’s product page reports 70% less manual effort and 45% lower total cost on ETL migrations. It also reports 80% faster data refresh on BI migrations.
Waves then run with automated reconciliation and business sign-off, followed by a rehearsed cutover and retirement of the legacy platform. Kanerika’s data migration consulting services also cover ETL, BI and RPA moves across this full sequence.
Case Study: 80% Faster Insights After an Azure to Microsoft Fabric Migration
Challenge: A global leader in packaging solutions ran scattered workflows across Azure Data Factory and Synapse. An intermediate Parquet conversion step added latency and caused failures, and the company had no unified governance model for its data.
Solution: Kanerika migrated the Azure assets to Microsoft Fabric with its proprietary migration utility. The team also set up direct integration from SAP C4C to Fabric. In addition, a unified governance framework set standards for naming, version control and documentation.
How it maps to the canvas: each problem on the case page sits in one box of the strategy. The page ties failures and delays to the intermediate Parquet step. Removing it was a target-state decision (part 3), and the direct SAP C4C link to Fabric took out that redundant processing layer.
The missing governance model had left setups inconsistent and limited scaling, which makes it a governance box problem (part 5). Kanerika filled that box with a framework of standards for naming conventions, version control and documentation. The case page also reports that code integrity held through the move.
Results: The company saw 80% faster business insights and reporting, a 30% reduction in cloud and data costs and a 50% improvement in its data pipeline. Operations continued without interruption during the move.
Case Study
80% Faster Insights with Azure to Microsoft Fabric
Kanerika moved a global packaging leader from Azure Data Factory and Synapse to Microsoft Fabric, with 30% lower cloud and data costs.
Read the Case Study →The Bottom Line
A data migration strategy is the signed plan that settles outcomes, scope, approach, governance, cutover and success measures before any data moves. Build it as a step-by-step framework of six gated phases, from discovery to decommissioning, with a named owner for every gate.
Use phased waves for large or tangled estates, while keeping a single cutover for small, simple ones. Whatever the size, settle owners and rollback before the first load. Sign the strategy first, then let the six gates carry your data the rest of the way.
Frequently Asked Questions
What is a data migration strategy?
A data migration strategy is the signed plan that sets why data is moving, what moves, how it moves and how success will be judged. It covers outcomes, scope, target state, approach, governance, rollback and success measures. Business owners and an executive sponsor sign it before any tool is chosen or any data is loaded.
What are the four types of data migration?
The four commonly cited types are storage, database, application and cloud migration. Storage migration moves files between storage systems. Database migration moves tables and logic between engines or versions. Application migration moves the data behind a replaced system, and cloud migration moves workloads into or between clouds. Many programs also include ETL and BI platform moves.
What are the main data migration strategies?
The main strategies are big bang, phased waves, parallel run and trickle migration using change data capture. Big bang moves everything at once. Phased waves move related workloads in groups. Parallel run keeps both systems live while outputs are compared, and trickle migration syncs changes continuously until the final switch, which keeps the outage short.
What is the 7 step migration model?
The 7 step model is a common way to describe migration as planning plus six phases. Planning sets the strategy, then teams discover the source, design the target and waves, run a pilot, migrate in waves, cut over with hypercare and decommission the old system. Each phase ends at a signed exit gate before work moves on.
Is ETL the same as data migration?
ETL is a method for extracting, transforming and loading data, and it runs repeatedly to feed analytics. Data migration is a one-time program that moves data and logic to a new platform and then retires the old one. Migrations often use ETL tools to move data, and they also include governance, validation and cutover work.
Which tool is used for data migration?
Teams usually combine several tool categories. Replication and change data capture services move data with little downtime. Cloud database migration services handle engine moves, and conversion accelerators rewrite ETL jobs, reports or scripts. Validation frameworks compare source and target. The right mix depends on the source and target platforms, so test it during the pilot.
What are the basics of data migration?
The basics are knowing what you have, deciding what moves, moving it safely and proving it arrived correctly. That means an inventory with owners, a mapping specification, a tested approach and layered validation from row counts to report parity. A rehearsed rollback and a plan to switch off the old system complete the basic set.
How is AI changing data migration?
AI tools now help profile source data, suggest field mappings and convert code such as SQL, ETL jobs and report logic. That shortens the discovery and conversion phases. Every AI-converted item still needs testing and review by an engineer who knows the business rules, so reconciliation and sign-off stay in the plan for each wave.
How long does a data migration take?
Duration depends on how much logic must be converted, how clean the data is, how many reports need parity checks and how many waves the estate needs. A small database move can finish in weeks. A large ETL and BI estate usually runs in several waves over many months. Time a pilot to get a reliable estimate.
Why do data migrations fail?
Data migrations usually fail through gaps in planning. Common causes are skipped discovery, business rules nobody documented, validation that stops at row counts and rollback plans that were never rehearsed. Programs also stall when business owners are not involved or the old system is never switched off. A signed strategy with exit gates addresses each of these.
What are the 7 Rs of migration?
AWS lists seven migration strategies, retire, retain, rehost, relocate, repurchase, replatform and refactor or re-architect. Each one is a choice for a single workload, from switching it off to rebuilding it for the cloud. Some older guides list six Rs instead. Pick an R for each workload during the design phase.
What is a migration factory?
A migration factory is a repeatable way of running migration waves, where every wave follows the same loop of load, reconcile, triage exceptions, fix and sign off. The same team, scripts and checks run each time. Speed comes from repetition and from improving the loop between waves, which suits large estates with many similar workloads.
Why does governance matter in a data migration strategy?
Governance decides who owns each choice before it becomes urgent, such as scope changes, personal data classification, data residency and the go or no-go call. Without named owners, engineers make those calls by default. Good governance also carries lineage and access controls into the target, so people can trace numbers and control access from day one.
How do you plan a data migration that scales?
Plan in waves built from the dependency map, and keep each wave small enough to test fully. Prove the approach with a representative pilot first, then reuse the same scripts, checks and sign-off steps for every wave. Time the pilot to calibrate estimates, and size each cutover window with real load and change rates.
How do you keep data secure during migration?
Classify personal and regulated data during discovery, before anything moves. Encrypt data in transit and at rest, limit access to migration accounts and log every load. Decide data residency for each data set and record who approved it. Rebuild access controls in the target before users arrive, and remove access to the old system at decommission.
How do you make migrated data ready for AI?
Treat the migration as the point where data becomes trusted. Profile and clean it during discovery, retire what nobody uses and document business rules in the mapping specs. Carry lineage, classification and access controls into the target. AI teams can then find, understand and safely use the data without a second cleanup project later on.
What is an example of a data migration strategy?
A retailer moving finance data to a cloud warehouse might set faster month-end close as the outcome and retire unused reports first. It would move data in three waves by dependency, run two closes in parallel and rehearse rollback once. The sponsor would judge success by reconciliation pass rate, report parity and retired licenses.
What is the best approach for data migration?
The best approach depends on estate size, dependencies and how much downtime the business can accept. Phased waves suit large or tangled estates. A single big bang cutover suits small, simple ones. Parallel runs suit regulated or financial reporting, and change data capture suits systems that need near-zero downtime during the final switch to the target.