TL;DR
For data migration in manufacturing, go big bang at a single plant and phase by plant across several. Before the first load, settle eight steps: scope and owners, interfaces, master data, archive rules, approach, business checks, rehearsal and rollback. Scope the work by data family: master data, open transactions, plant-floor time series and quality records. Clean and de-duplicate master data across plants before you map a single field. If the bulk load cannot fit the outage window, preload history and sync changes until cutover. Prove success with business checks such as inventory value by plant, and name the rollback trigger before go-live weekend.
Key Takeaways
- Scope a plant migration by data family, not by system, because master data, open transactions, time series and quality records each need their own plan.
- Load in dependency order, from materials to BOMs to routings to open orders, because the new system rejects records that arrive too early.
- Pick big bang only when one plant fits its outage window; phase by plant when calendars differ or data is too large.
- Keep historian and SCADA data on a separate copy pipeline, and never pull large loads from PLCs while the line runs.
- Prove lot traceability with the same genealogy queries before and after the move, and keep audit trails readable.
- Rehearse the cutover on production-sized data, then agree the rollback trigger and staff hypercare on every shift.
A Cutover Weekend With Orders Still on the Floor
Picture a plant that runs three shifts, five days a week. The ERP cutover is booked for a Friday night, but hundreds of production orders are still open on the floor. Some are half built, some wait on a supplier lot and a few sit in quality hold.
By Monday morning, every one of those orders must exist in the new system with the right quantity, routing step and lot links. Moving the file is the easy part. The hard part is everything the plant keeps doing while the data moves.
That is why data migration in manufacturing is planned around production, not around the database. This guide covers the eight things to settle before the first production load. It also shows how to pick an approach, protect traceability and run a cutover without stopping the line.
What Data Migration in Manufacturing Covers
Data migration in manufacturing means moving the records a plant runs on from one system to another without breaking production. Those records include materials, recipes, orders, machine readings and quality evidence. Each one also behaves differently once it moves.
A useful way to scope the work is by data family rather than by system. An ERP holds several families at once, and a single family, such as quality records, often spans three systems. Scoping by family shows which records need cleaning, which need a live sync and which can stay in an archive.
The Four Data Families
For example, think of a mid-sized food plant moving from an old ERP to a new one. Its item master, open purchase orders, oven temperature history and lot release records all need a plan. They do not need the same plan, though, and treating them alike is how timelines slip.
| Data family | Example objects | Why it is hard | Typical treatment |
|---|---|---|---|
| Master data | Materials, BOMs, routings, work centers, suppliers | The same item is held several ways across plants | Cleanse, de-duplicate, then migrate |
| Open transactions | Production orders, inventory balances, open POs | Values change every shift until cutover | Migrate at cutover with a final delta load |
| Plant-floor time series | Historian tags, SCADA events, IoT readings | High volume; tag names and timestamps vary | Bulk history, then an incremental feed |
| Quality and traceability | Lots, serials, inspections, deviations | Links between records must survive intact | Migrate with genealogy checks, or archive read-only |
The table makes one point plain: a single “migrate everything” plan does not fit a plant. Master data needs cleaning first, before anything else loads. Open transactions need careful timing, and time series need a different pipeline altogether.
Where the Systems Sit
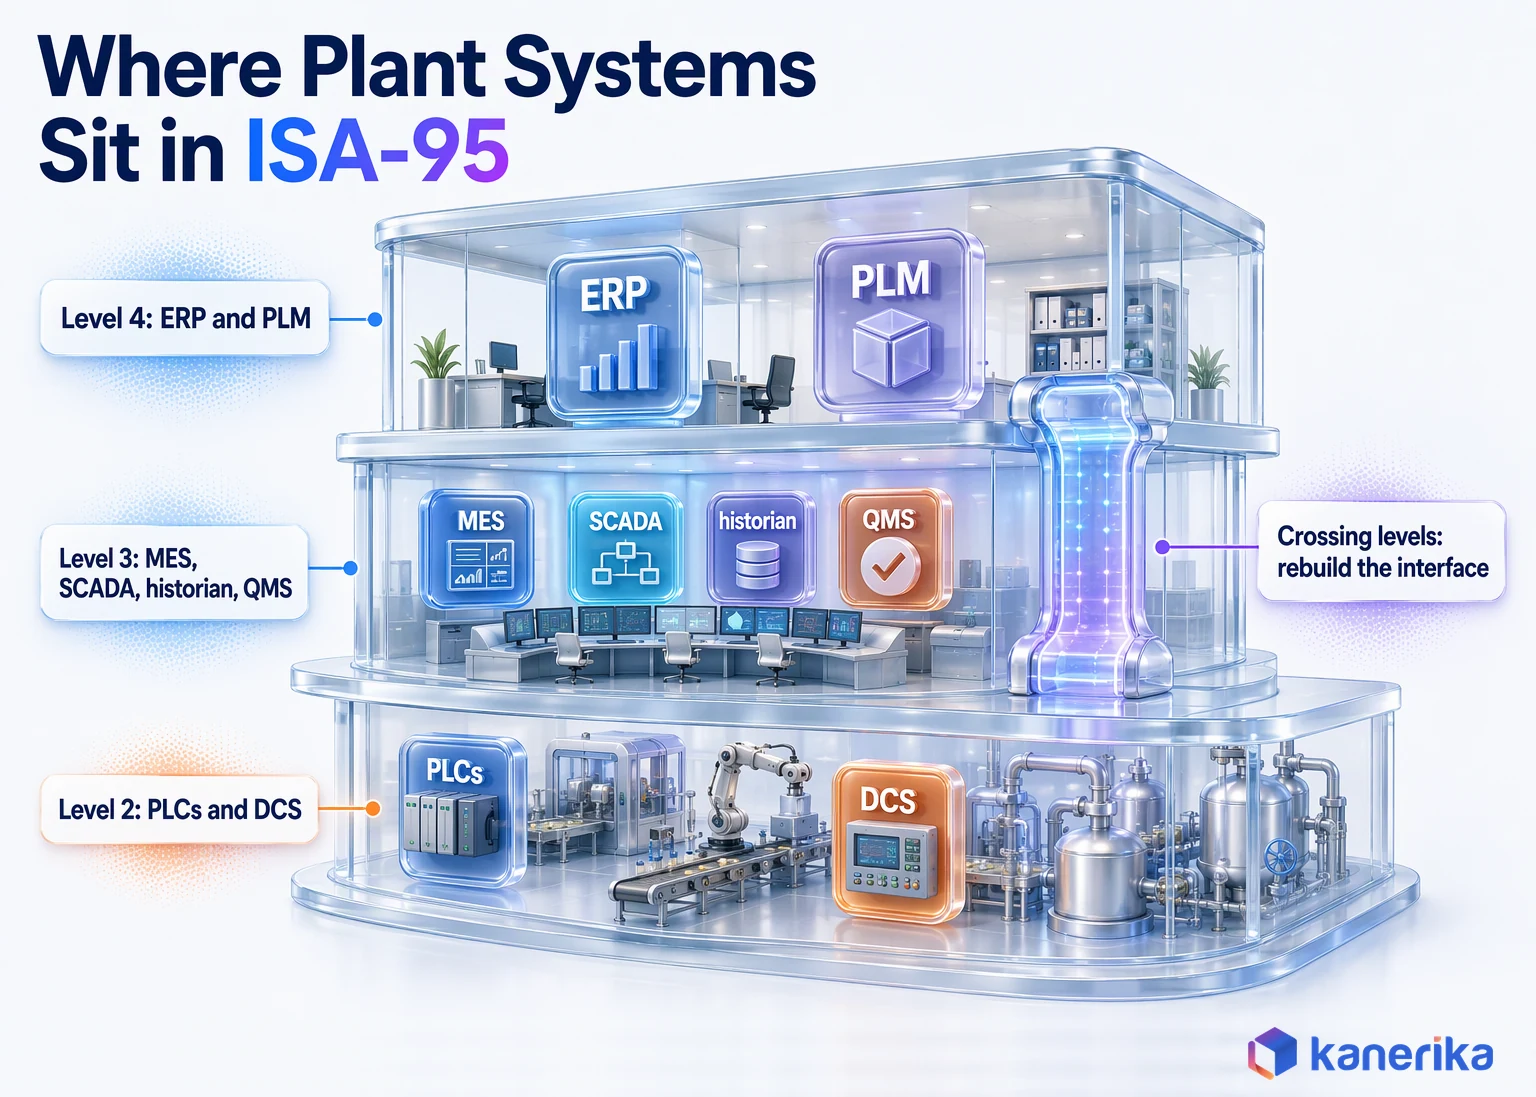
Manufacturing systems also sit at different levels of the plant. The ISA-95 standard, also published as IEC 62264, describes how enterprise and control systems integrate. Its key boundary runs between level 3, manufacturing operations, and level 4, business systems.
In practice, the ERP and PLM sit at level 4, where plans, costs and product definitions live. The MES, historian and QMS sit at level 3, where the plant records what it actually made. PLCs and distributed control systems sit at level 2, below both, and control the equipment itself. ISA groups SCADA with the MES at level 3.
This map matters because a migration that crosses the level 3 and level 4 boundary also changes the interfaces between them. A new ERP that sends orders to an old MES needs that interface rebuilt and tested before cutover, or the floor stops receiving work.
Why Dependencies Decide the Load Order
Manufacturing records also depend on each other in a strict chain. A bill of materials points to materials, a routing points to work centers, and an open production order points to both. Load an order before its BOM exists and the target rejects it, or accepts it with a blank component list.
So the load order follows the chain. Suppliers and materials come first, then BOMs and work centers, then routings, then open orders and inventory.
Teams that migrate one object in isolation tend to find the break late, in testing, when an order cannot be released. A dependency map built in week one is cheap, though. Finding the same gap during a rehearsal costs a full cycle.
Why Manufacturers Are Migrating Now
A plant migration usually starts with a deadline or a business change rather than a wish for cleaner data. So knowing your driver tells you how much time you have. It also tells you what the new system must do on day one.
For many manufacturers, the biggest deadline is SAP, especially for plants still on ECC. In a 2020 announcement, SAP said mainstream maintenance for core SAP Business Suite 7 applications runs until the end of 2027. Optional extended maintenance follows until the end of 2030, and SAP S/4HANA maintenance runs to 2040.
SAP also sells a paid transition option for SAP ERP, private edition. It requires systems to move to private edition on SAP HANA before the end of 2030. In an October 2026 update, SAP said subscriptions may run until the end of 2035, with further prerequisites. Treat it as an exception rather than a plan, and confirm any terms with SAP directly.
Mergers, Consolidations and Analytics Programs
Other drivers carry no fixed date but are just as real. For instance, an acquisition brings a second ERP and a second item master. A consolidation closes one plant and moves its products to another. Similarly, an analytics program on Microsoft Fabric or Databricks needs plant data in one place.
Finally, legacy reporting is a common driver too. Old report servers rarely survive an ERP change, so the BI layer moves too. The patterns there are covered in our guides to BI migration and Qlik to Power BI migration.
| Driver | What it forces | Deadline or trigger |
|---|---|---|
| SAP Business Suite 7 (ECC) maintenance end | ERP move to S/4HANA or another platform | End of 2027; optional extended maintenance to end of 2030 |
| Merger or acquisition | One item master, one supplier and customer list | Deal close and the integration plan |
| Plant consolidation | Transfer of products, routings and open orders | Closure date of the source plant |
| Analytics and AI programs | Plant data in a shared platform | Program start; no hard date |
| Legacy BI retirement | Report rebuild on a new tool | End of support for the old report server |
A team facing the SAP date has a fixed end point and should therefore plan backward from it. A team driven by analytics has more freedom, so it can phase the work by business value instead.
Automotive plants face the same SAP date with serial traceability on top, as our guide to data migration in automotive shows. Many plants also mix SAP with non-SAP systems, which turns a single move into an integration problem.
Case Study
60% Faster Data Integration for a Manufacturer with SAP
Kanerika consolidated SAP and non-SAP sources for an edible oil manufacturer running numerous plants, cutting data integration time by 60% and lifting productivity by 30%.
Read the Case Study →Before You Start: 8 Planning Steps With Exit Criteria
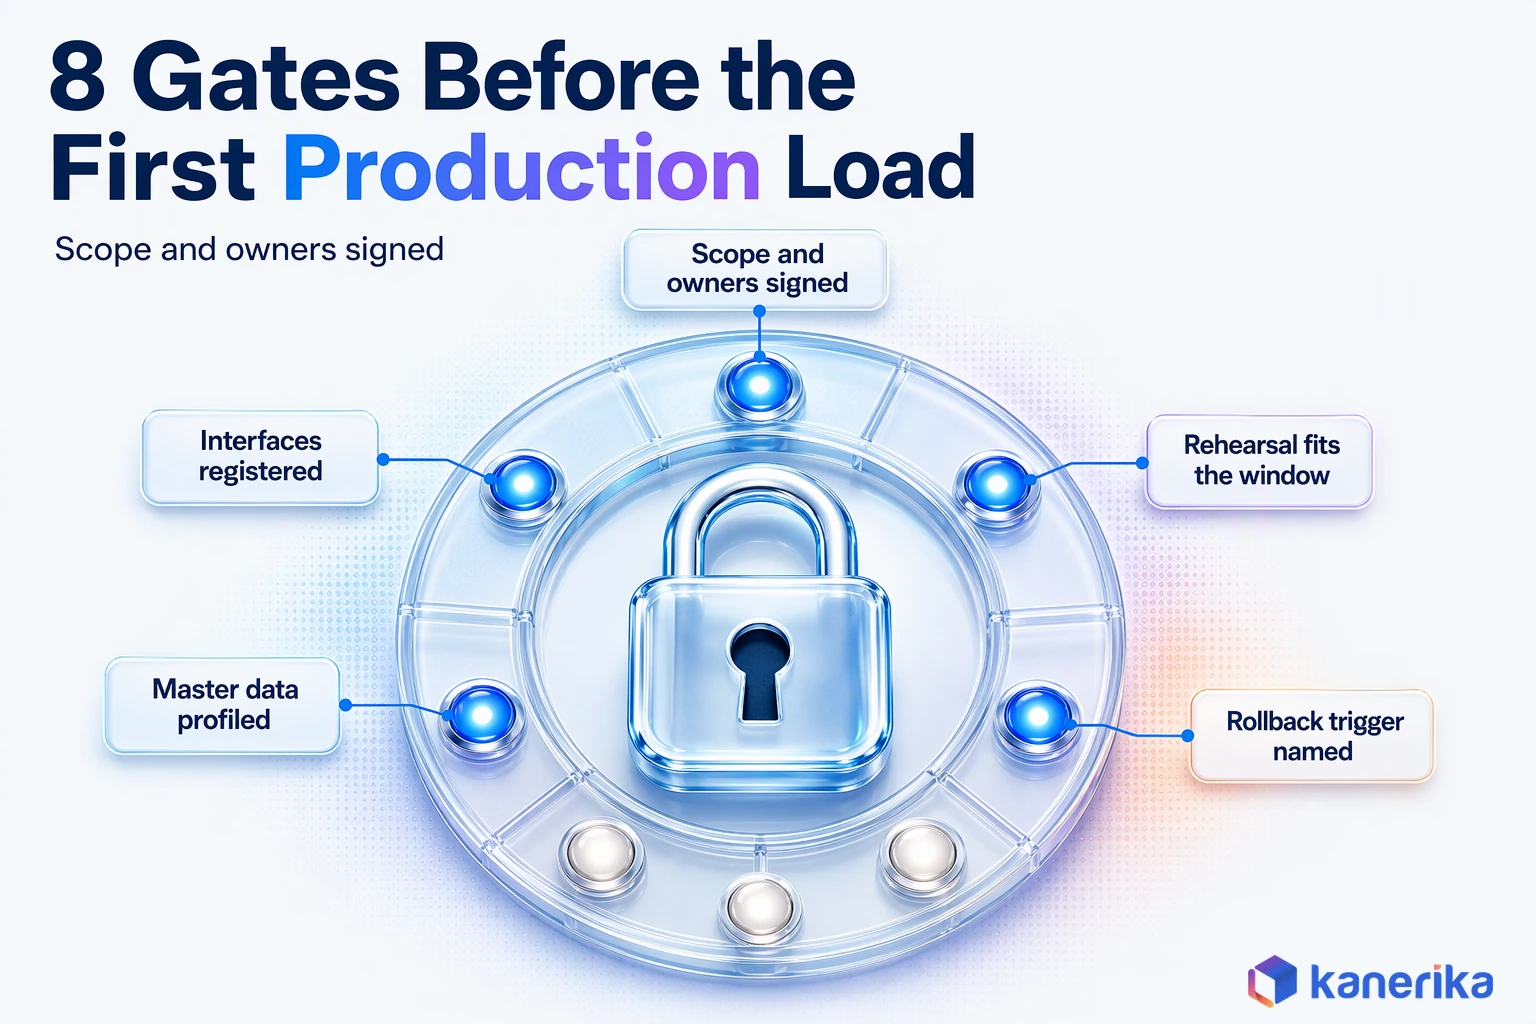
The work that decides a plant migration happens before anyone loads a record. These eight steps set the scope, the data rules and the safety net for data migration in manufacturing. Each ends with an exit criterion, so you know when a step is truly done.
Run them in order where you can. Steps 3 and 4 often overlap, because profiling shows what is worth keeping. Step 7, by contrast, cannot start until steps 1 to 6 give you something to rehearse.
1. Set Scope, Owners and Production Constraints
First, decide what is in and what is out. Name the plants, the systems, the data families and the depth of history to carry. Then name an owner for each data domain, such as a materials planner for the item master and a quality manager for lot records.
Production constraints belong in scope too. Write down peak seasons, planned shutdowns, shift patterns and month-end close. A plant that ships its biggest orders in November should not cut over then.
Exit criterion: a signed scope document with a named business owner per domain and plant manager sign-off on the cutover window.
2. Inventory Systems, Interfaces and Dependencies
List every system that touches plant data and every interface between them. Include the small ones too, such as a spreadsheet that feeds the label printer or a script that posts scrap counts each night. Those are the links that break quietly after go-live.
For each interface, record its direction, its frequency and who depends on it. Then draw the object dependency chain from materials through to open orders, as described earlier.
Exit criterion: an interface register that plant IT and operations both agree is complete.
3. Profile Master Data Across Plants
Master data is where plant migrations tend to go wrong. For example, the same bearing can exist as three item numbers in three plants, each with its own description and unit of measure. One plant counts it in pieces, while another counts it in boxes of ten.
Profiling tools count duplicates, blank fields, invalid units and orphan records before mapping starts. The results then show how much cleansing lies ahead and which plant’s version should become the standard.
Fix the data in the source where you can, so the fix survives into the next rehearsal.
Exit criterion: a profiling report per domain, an agreed golden record rule and a cleansing backlog with owners.
4. Decide What Moves and What Gets Archived
Open orders, current inventory and active master data must move, because the plant runs on them. A decade of closed orders usually needs to stay readable, not editable.
The deciding question, then, is retention. Regulated plants must keep certain records for set periods, and auditors must also be able to read them. A searchable read-only archive often meets that need at far lower cost than migrating every closed record.
Exit criterion: a retention matrix per data family that states migrate, archive or retire, signed by quality and finance.
5. Choose the Approach and the Coexistence Model
Pick between big bang, phased and parallel options, and decide how old and new systems coexist while the move runs. The next two sections compare the approaches and give a decision framework, so this step records the choice and the reason behind it.
Coexistence, however, is the part teams forget. If plant A moves before plant B, intercompany orders must flow between two ERPs for weeks, and someone has to design that bridge.
Exit criterion: a written approach decision with the coexistence design and its end date.
6. Define Business-Level Acceptance and Reconciliation
Row counts prove that records arrived. They do not, however, prove the plant can run. Acceptance tests should therefore use numbers managers already trust. Examples include inventory value by plant, open order counts by status and BOM cost roll-ups for top items.
Agree the tolerance for each check before testing starts. Zero tolerance on inventory quantity is normal, while a small rounding gap on standard cost may be fine. For validation methods in more depth, see this guide to ensuring data quality during data migration.
Exit criterion: a reconciliation pack listing each check, its tolerance and the owner who signs it off.
7. Rehearse With Mock Cutovers
A mock cutover runs the full sequence on production-sized data: extract, transform, load, reconcile and sign off. Time every step so you can compare runs. The first rehearsal tends to show that at least one step takes far longer than planned.
Then run another rehearsal after fixing what the first one found. Keep going until the timings fit the window and the reconciliation pack passes without manual patches.
Exit criterion: a clean rehearsal that fits the outage window with margin to spare.
8. Plan Rollback and Hypercare
Decide in advance what failure looks like and what happens when it occurs. For example, a rollback trigger might be an inventory variance above tolerance or an order release failure in one plant. The trigger needs a named decision maker and a deadline, such as Sunday at noon.
Hypercare is the support period after go-live, when small data errors surface fast. Plan floor support for each shift, a fast path for data fixes and a daily review of open issues with the plant manager.
Exit criterion: a rollback plan tested in rehearsal and a hypercare rota that covers every shift.
Migration Approaches Compared
Every migration approach trades speed against risk in its own way. A big bang finishes fast but bets the whole plant on one weekend. A phased move spreads the risk but adds months of coexistence between old and new systems.
ERP moves also add a second choice: convert the existing system or rebuild it. For example, a brownfield conversion keeps your configuration and history. A greenfield reimplementation starts clean, and a selective data transition sits between the two.
Picture two plants of the same company. One has clean data and a two-week holiday shutdown, so a single cutover is realistic. The other runs year-round and carries three item masters from past acquisitions, so it needs a slower, staged path.
The Seven Options Side by Side
| Approach | How it works | Best for | Main risk | Downtime profile |
|---|---|---|---|---|
| Big bang | All data and users move in one cutover | One plant, clean data, short scope | Everything fails at once | One long window |
| Phased by plant | Plants move one at a time | Multi-plant estates with different calendars | Intercompany flows across two systems | A short window per plant |
| Phased by data domain | Domains such as finance or quality move separately | Loosely coupled systems | Broken links between domains | Several short windows |
| Parallel run | Old and new systems run side by side for a period | High-risk, regulated processes | Double entry and staff fatigue | Little or none, but high effort |
| Brownfield (system conversion) | The existing ERP is converted in place | Sound processes with heavy history | Old bad data carried forward | One conversion window |
| Greenfield (reimplementation) | A new system is built and selected data loaded | Broken processes, major redesign | Longer program and more change | Cutover of the selected data |
| Selective data transition | Chosen units, years or objects are moved | Carve-outs and consolidations | Complex scoping and tooling | Planned per scope |
Read the table from its last two columns. If your plant cannot afford a long window, big bang is already out. If your team cannot staff double entry, a long parallel run is out as well.
Brownfield versus greenfield is mostly a question about how sound your processes are. Good processes on bad data favor a conversion with heavy cleansing. Broken processes favor a rebuild, even though it takes longer.
Kanerika Service
Data Migration Services
Kanerika helps plants choose between big bang, phased and coexistence approaches, then runs the migration with profiling, rehearsed cutovers and reconciliation.
Explore Migration ServicesDecision Framework: Which Approach Fits Your Plants
The right approach follows from a few facts about your plants, not from a vendor preference. Match your situation to a row below, then check the disqualifier before you commit.
Read the Disqualifier column before the Pick column. Take a single plant whose rehearsal ran 11 hours against an 8-hour window. It lands in the third row, not the first, because the disqualifier decides, not the plant count.
| Situation | Pick | Why | Disqualifier |
|---|---|---|---|
| Single plant, load fits the outage window | Big bang | Fastest path, no coexistence | Rehearsal timing exceeds the window |
| Several plants on different calendars | Phased by plant | Each plant picks its own quiet period | Heavy intercompany flows with no bridge design |
| Large data, short outage | Preload plus change capture | Bulk moves early; only changes move at cutover | The source cannot expose changes reliably |
| Critical lot traceability | Phased with parallel checks | Genealogy is verified before the old system retires | No staff for parallel validation |
| Historian data for analytics | Separate copy pipeline | Keeps OT systems out of the cutover | Analytics needs the data on day one and no feed is ready |
| Dirty master data after acquisitions | Cleanse first, then phase | Keeps duplicates out of the new system | The deadline leaves no time to cleanse |
For a broader scoring model that covers any platform, use this data platform migration decision framework. This section stays with plant-specific signals, and the most common one is a dataset that will not fit the window.
Worked Example: A Dataset That Does Not Fit the Outage Window
The numbers below are illustrative assumptions, chosen to show the arithmetic rather than describe a real project. They use decimal units, so 1 TB equals 1,000,000 MB.
- The source holds 12 TB of history and transactions to move.
- Measured throughput in rehearsal is 80 MB per second.
- A full bulk load takes 12,000,000 MB divided by 80 MB per second: 150,000 seconds, or about 41.7 hours.
- The plant has an 8-hour cutover window, so a full load cannot fit.
- Changes since a preload come to about 600 GB: 600,000 MB divided by 80 is 7,500 seconds, or about 2.1 hours.
- The pick is a preload of history in the weeks before cutover, change capture to keep it current, then a final delta inside the window.
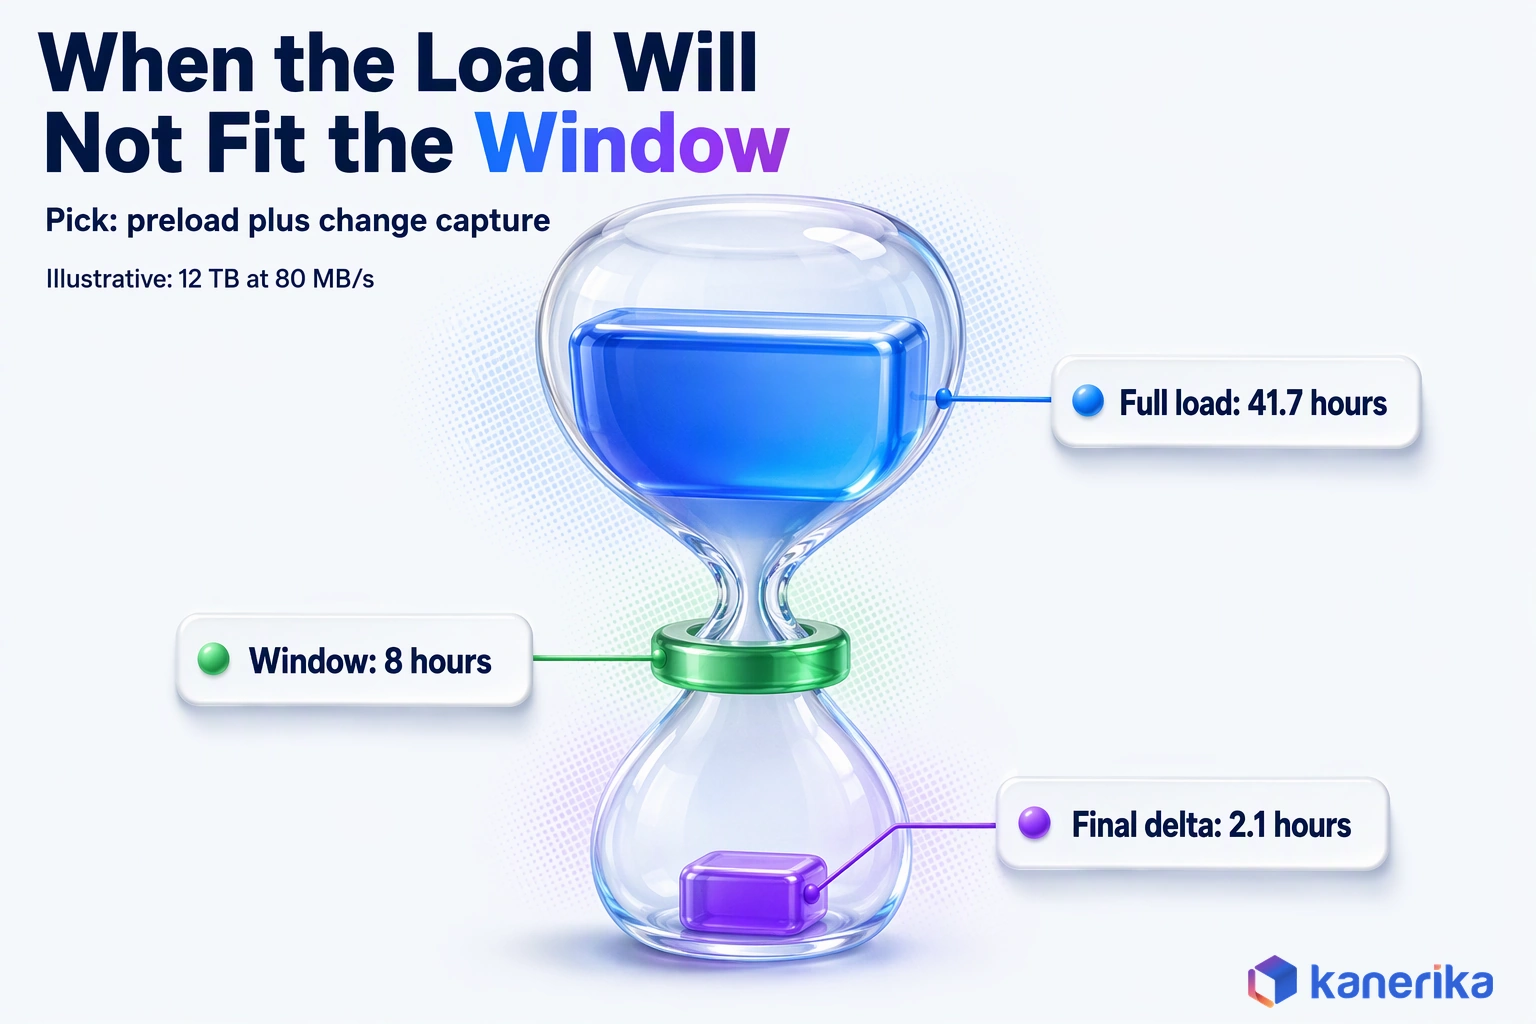
The 2.1-hour delta leaves about 5.9 hours for reconciliation, sign-off and a rollback decision. That margin is what makes the plan safe, far more than the speed of the network.
Run the same sum with your own rehearsal figures. If the delta alone takes more than half the window, shrink it with more frequent syncs or split the cutover by plant.
Plant-Floor Data: Historian, SCADA, IoT and MES
Plant-floor data is the part of a manufacturing migration that general guides tend to skip. It is high in volume, tied to equipment and read by people who may never open the ERP. It also lives next to systems that control physical machines.
The first rule is to separate the analytics copy from the control systems before anything moves. The historian or SCADA system that runs the line keeps running. You copy its data to a new platform for analysis, and you never pull large loads straight from PLCs during production.
The second rule is to move history once and then stream the changes. Bulk-load past readings in batches during quiet hours, then switch to an incremental feed that carries only new and changed records.
Streaming Changes Into Microsoft Fabric
On Microsoft Fabric, Open Mirroring is one way to run that feed. Your application writes changes to a landing zone, and Fabric’s replication engine converts them into Delta Parquet in OneLake. The source side decides what to send, so new, changed and deleted records all need handling.
| Source | Volume pattern | Migration pattern | Check |
|---|---|---|---|
| Historian | Very high, steady per tag | Bulk history by period, then an incremental feed | Tag counts and value ranges per period |
| SCADA events and alarms | Bursty around shifts and faults | Batch export of history, live feed for new events | Event counts per line per day |
| IoT sensors | High, many small messages | Stream to a landing zone, compact into tables | Timestamp gaps per device |
| MES | Moderate, tied to orders | Migrate open work, archive closed history | Open work orders match ERP orders |
Tag names also deserve attention of their own. A historian that grew over many years may call the same oven temperature by four names across lines. Map them to one naming standard during the move, or every dashboard built later inherits the mess.
The MES sits in a special spot, because it holds open work orders that must match the ERP at cutover. Treat its open work as a transaction family and its closed history as an archive candidate.
Preserving Lot Traceability and Compliance Records
Traceability is the ability to follow a lot from its raw materials to the customer who received it. In a recall, that chain lets a plant pull one batch instead of a whole month of output. A migration must therefore move the links between records as well as the records themselves.
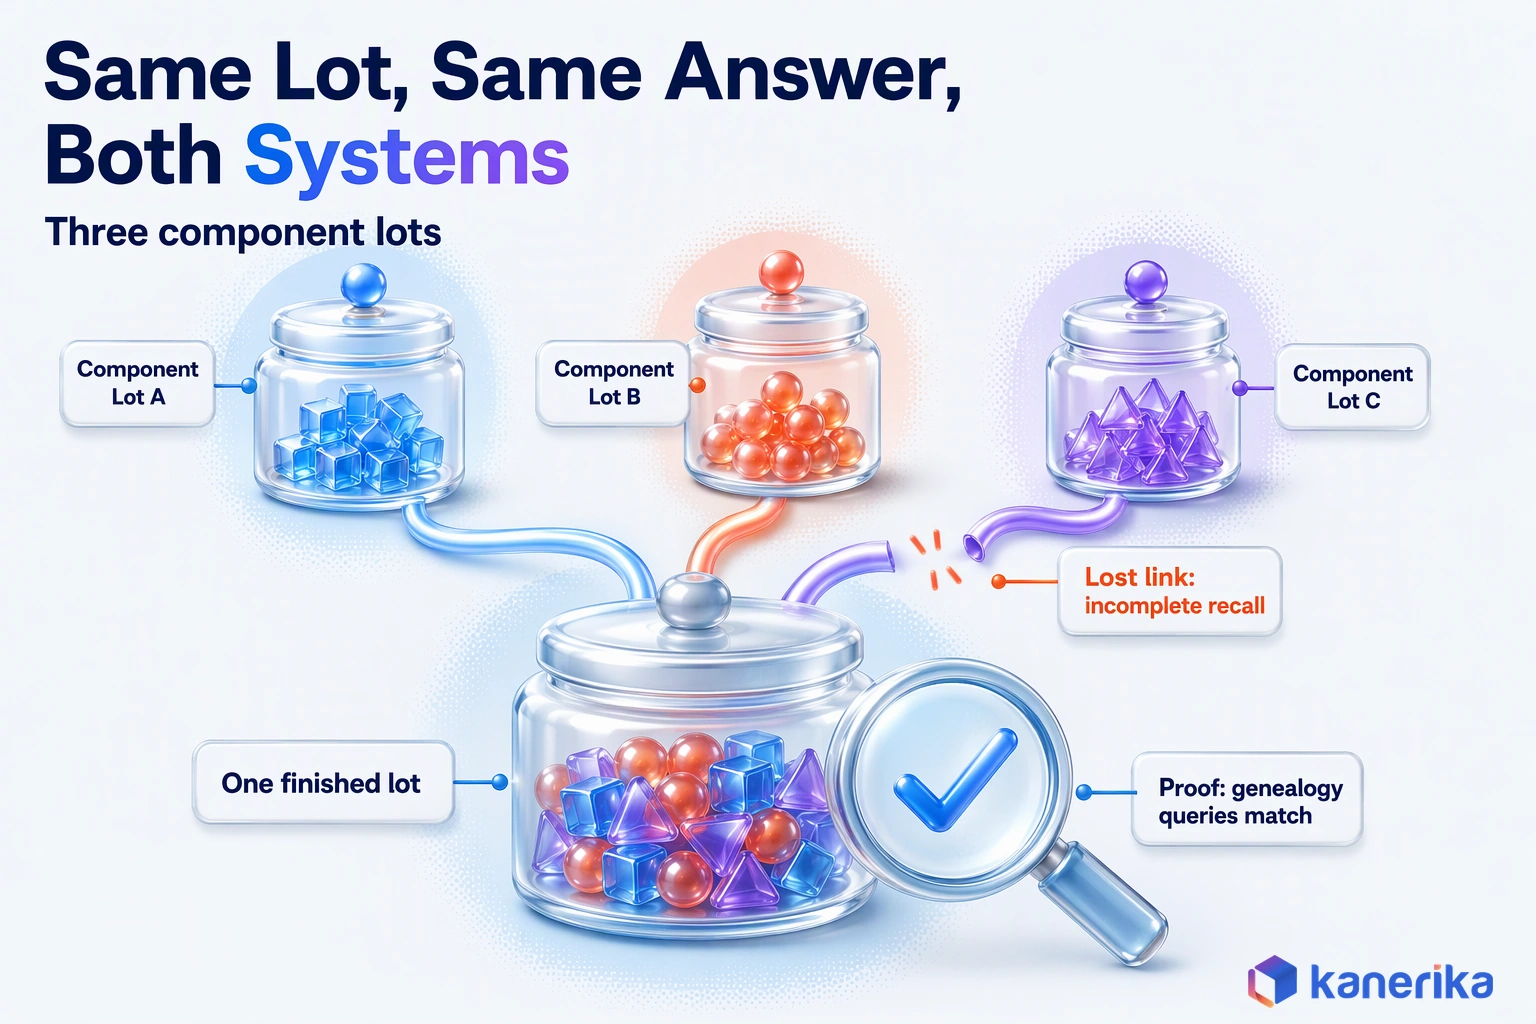
For instance, consider a lot of finished goods made from three component lots. If the new system keeps the finished lot but loses one component link, the genealogy query returns an incomplete answer. Nobody notices until a supplier issues a recall.
Audit Trails in FDA-Regulated Plants
FDA-regulated plants in food, pharmaceuticals and medical devices also face an extra rule. Under 21 CFR 11.10(e), electronic record systems need secure, computer-generated, time-stamped audit trails. Record changes must not obscure previously recorded information.
During a migration, the audit trail must move with the record or stay readable in an archive. A migrated record that shows only its latest value, with no trace of who changed it, can fail an inspection.
| Record type | What must survive | How to prove it |
|---|---|---|
| Lot and batch records | Parent and child lot links, quantities, dates | Run the same genealogy queries before and after; results must match |
| Serial numbers | Links from serial to order, customer and components | Trace a sample of serials end to end in both systems |
| Inspection results | Results, specs, inspector and timestamp | Compare counts and pass or fail totals per period |
| Deviations and CAPAs | Status, approvals, linked lots | Reconcile open items by status and owner |
| Audit trails | Who changed what, when, and the prior value | Confirm the trail is migrated or archived in readable form |
The genealogy test is the strongest proof you can give an auditor, because it tests links rather than counts. Pick a sample of lots, especially lots from a past recall drill, and run the forward and backward trace in both systems. The answers should match line for line.
Regulated finance carries a similar burden of proof, as this look at data migration in fintech shows. The records differ, but the rule is the same: an auditor must be able to rebuild what happened.
Cutover Runbook for a Running Plant
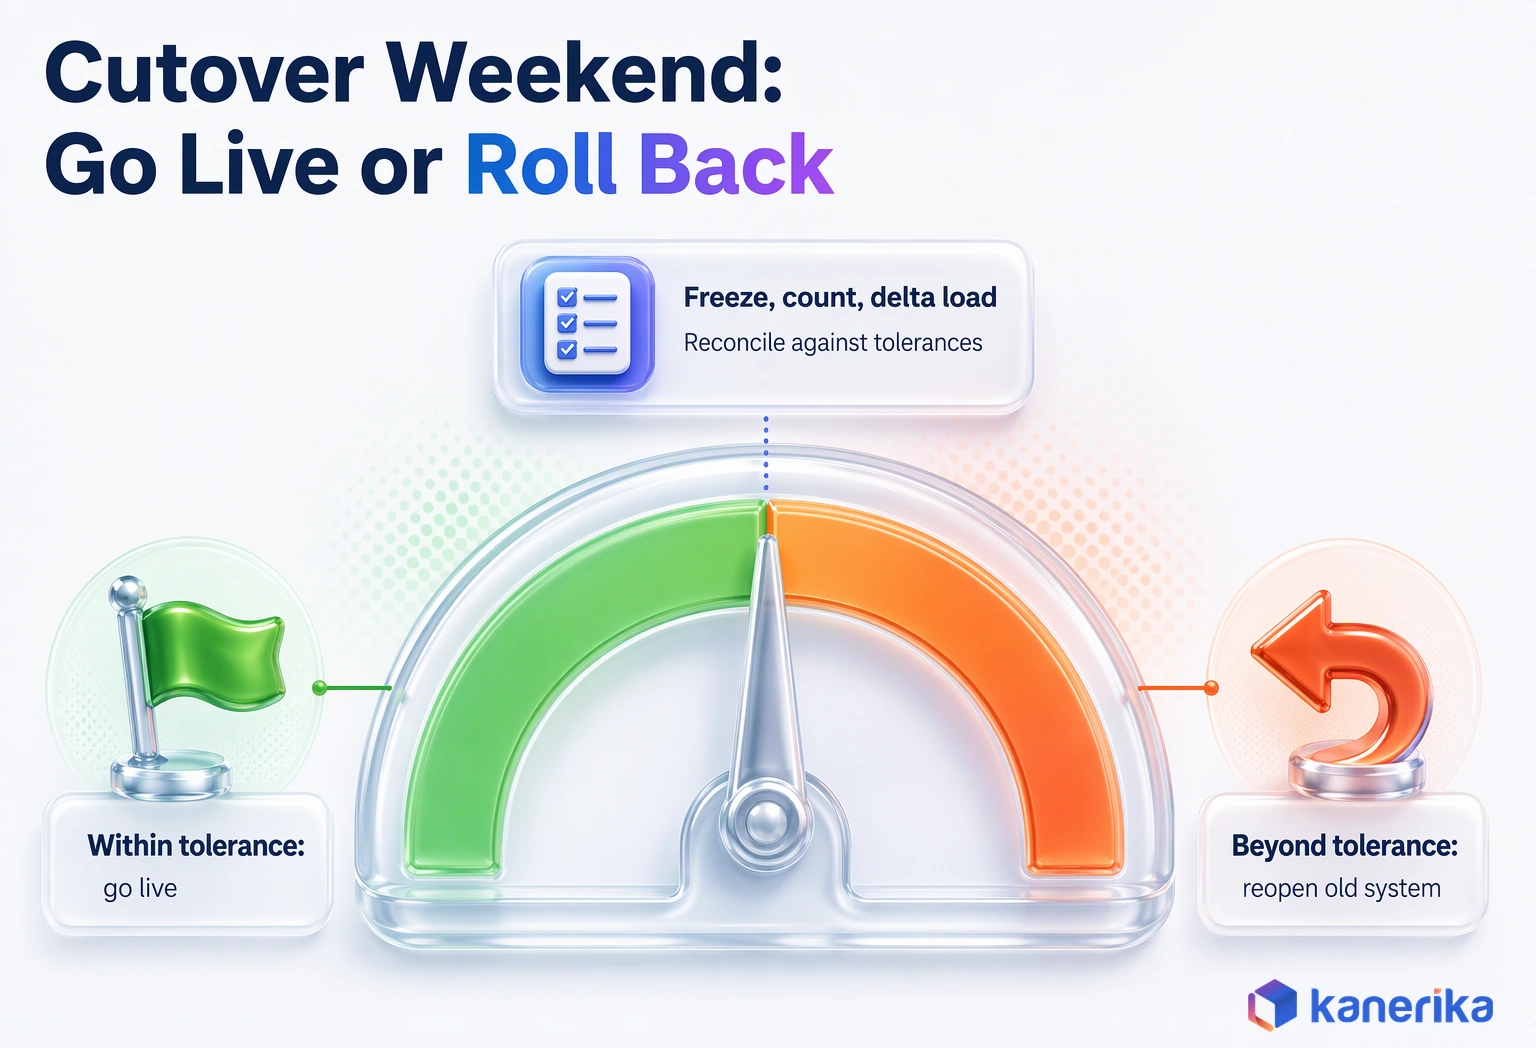
A cutover runbook is the hour-by-hour script for the switch from the old system to the new one. Its center is the freeze: the moment open orders and stock stop changing in the old system.
The runbook below assumes a weekend window aligned to shift changes. Adjust the timing to your own plant calendar, but keep the order of the steps.
Give every step an owner and a planned duration, both taken from the last rehearsal. If a step runs long on the night, the cutover manager then knows at once how much margin is left before the rollback deadline.
- Transaction freeze. Stop new orders, goods movements and confirmations in the old system at a set time, ideally at a shift change.
- Count key stock. Count high-value and fast-moving items so the new system opens from a known balance.
- Final delta load. Load the changes since the last preload, in dependency order.
- Reconcile. Run the reconciliation pack: inventory value by plant, open order counts, BOM roll-ups and lot genealogy samples.
- Go or no-go call. The named decision maker reviews the results against the tolerances agreed in planning.
- Rollback trigger. If a check fails beyond tolerance and cannot be fixed by the deadline, reopen the old system and reverse the interfaces.
- Hypercare. Staff each shift with super users, a data fix desk and a daily issue review with the plant manager.
Keeping Every Shift Informed
Communication belongs in the runbook too. Supervisors need to know when the freeze starts and which paper fallback to use during the window. They also need to know whom to call on the first shift after go-live. A one-page brief per shift, posted at each line, heads off most of the confusion on Monday morning.
Keep a timed log of every step during the real cutover, just as in rehearsal. If the plant moves in phases, that log becomes the starting estimate for the next plant’s window.
The stock count is an easy step to cut when time runs short. It also prevents the most arguments later, because it gives the new system an opening balance that nobody can dispute.
Finally, treat the go or no-go call as a genuine decision point. If reconciliation shows a gap, the person who signs needs the authority and the time to say no.
Cost and Effort: What Drives the Estimate
The cost of a plant migration depends more on data condition and plant count than on raw volume. A clean single plant can cost less than a small but messy one. Price ranges from other projects mislead for that reason, so build the estimate from your own drivers.
The formula itself is simple, though. Multiply role hours by internal or partner rates, then add infrastructure, licenses and a contingency for what profiling has not yet revealed.
| Cost driver | Sizing input | What inflates it |
|---|---|---|
| Discovery | Systems, interfaces, plants | Undocumented interfaces and spreadsheets |
| Mapping | Objects and fields in scope | Custom fields and plant-specific rules |
| Cleansing | Duplicate and error rates from profiling | Several item masters after acquisitions |
| Engineering | Pipelines, transforms, loads | Hand-coded transforms with no reuse |
| Interfaces | Count and complexity of links | Coexistence bridges for phased moves |
| Testing | Reconciliation checks and test cycles | Late changes to scope or rules |
| Mock cutovers | Number of rehearsals | Rehearsals that fail and must repeat |
| Cutover staffing | People per shift and hours | Weekend and overtime rates |
| Hypercare | Weeks of support, shifts covered | Repeated data fixes after go-live |
| Archive | Volume and retention years | Search and audit access requirements |
A practical way to test the estimate is to price one plant in detail first. Its actual hours for discovery, cleansing and rehearsal then become the basis for the next plant, adjusted for its data quality and interface count. Estimates built this way also tend to improve with each wave, because the team learns where the effort really goes.
Two drivers, in particular, deserve early attention. Cleansing grows with every acquired plant that brought its own item master. Mock cutovers grow with every rehearsal that fails, so effort spent on steps 3 and 6 lowers the cost of step 7.
Migration ROI Calculator
Estimate Your Migration ROI
Use Kanerika’s migration ROI calculator to compare effort, cost and timeline for an automated migration against a manual one before you size the budget.
Calculate Migration ROI →Risks and Common Mistakes
A migration risk usually shows an early signal well before go-live. A risk register lists those signals, the control for each and the person who owns it. Review it weekly with the business owners, not only with IT.
The risks below are the ones plant projects meet again and again. Each has a cheap control if you act on the signal early.
| Risk | Early signal | Control | Owner |
|---|---|---|---|
| Duplicate master data | Profiling finds one item under several numbers | Golden record rule and cleansing backlog | Master data lead |
| Broken dependencies | Test orders fail to release | Load in dependency order; test end to end | Migration lead |
| Missed interfaces | A team mentions a feed nobody listed | Interface register signed by plant IT and operations | Plant IT lead |
| Lost traceability links | Genealogy queries differ between systems | Before and after genealogy tests | Quality manager |
| Cutover overrun | Rehearsal timings exceed the window | Preload plus change capture; more rehearsals | Cutover manager |
| Inventory mismatch at go-live | Count variances in rehearsal | Count key stock at the freeze | Plant controller |
| Weak hypercare | No named support on night shift | A rota that covers every shift | Plant manager |
| OT disruption | Load jobs touch control systems | Copy from the historian, never from PLCs in production | OT engineer |
The costliest mistake, though, is starting without business owners. When IT owns every decision, nobody with plant authority signs the reconciliation, and problems surface on the floor after go-live.
Measuring Data Migration in Manufacturing After Go-Live
Success after go-live has three layers: the data is right, the plant runs well and people use the new system. Measure all three against a baseline you capture before cutover, or nobody can say whether a change is good or bad.
Take a baseline of order cycle time, inventory accuracy and overall equipment effectiveness (OEE) for a few weeks before the move. OEE shows data errors fast, since a wrong routing can leave a work center idle while it waits for released orders. After go-live, compare the same measures week by week until they settle. A short dip during hypercare is common, while a dip that lasts beyond it points to a data or process gap.
| Layer | KPI | What it tells you |
|---|---|---|
| Data | Reconciliation pass rate | Share of checks within tolerance |
| Data | Duplicate rate in master data | Whether cleansing held after go-live |
| Plant | OEE | Whether equipment time is lost to system issues |
| Plant | Order cycle time | Whether orders flow as fast as before |
| Plant | Inventory accuracy | Whether system stock matches physical stock |
| Adoption | Transactions in the new system versus workarounds | Whether people trust the system |
| Adoption | Open hypercare tickets by week | Whether issues are closing |
Set targets from your own baseline rather than from industry averages. A plant should first get back to its pre-migration level, and only then aim to improve on it.
Where Automation and AI Help, and Where People Decide
Automation earns its place in the repeatable parts of a migration. Profiling, mapping suggestions, code conversion, data loads and reconciliation checks all repeat at scale, and tools do them faster and more consistently than people.
Migration accelerators package this kind of automation for platform work. For example, Kanerika states that its FLIP accelerator automates data platform migration up to 80%. Any such figure covers repeatable platform tasks, while plant decisions stay with people.
| Automate | People decide |
|---|---|
| Profiling and duplicate detection | Golden record rules per domain |
| Mapping suggestions | Mapping sign-off by the data owner |
| Code conversion and bulk loads | Which history to archive or retire |
| Change capture and delta loads | Tolerances for each reconciliation check |
| Reconciliation reports | The go or no-go call at cutover |
AI also adds a further layer. It can suggest field matches, flag likely duplicates and summarize reconciliation gaps. Still, each suggestion needs someone who knows the plant to accept or reject it. For more depth on this split, see our guide to the role of automation in migration.
Kanerika Service
FLIP Migration Accelerator
FLIP automates data platform migration work such as conversion and validation, so your team spends its time on mapping sign-off and cutover decisions.
Explore FLIPHow Kanerika Runs Manufacturing Data Migrations in Stages
Kanerika runs plant migrations as a sequence of stages, each with a sign-off before the next begins. The stages also mirror the planning steps above, with automation applied wherever the work repeats. Our data migration services and manufacturing practice work as one team on these projects.
- Assess. Map systems, interfaces, plants and data families, and agree scope with business owners.
- Profile and map. Profile master data across plants, set golden record rules and map source to target.
- Automate with FLIP. Convert and load with FLIP where the source and target are supported, and script the rest.
- Rehearse. Run mock cutovers on production-sized data until timings and reconciliation pass.
- Cut over. Execute the runbook, with plant sign-off at the go or no-go call.
- Hypercare. Support each shift and track data KPIs against the baseline.
Case Study: Live QAD ERP Data in Microsoft Fabric With Open Mirroring
A global manufacturer ran QAD ERP across multiple sites and regions and wanted that data current in Microsoft Fabric for reporting. Standard data pulls missed deleted records and slowed down on the largest tables. Each site’s database also needed its own setup.
Case Study
Live QAD ERP Data in Microsoft Fabric with Open Mirroring
Kanerika connected 200+ QAD tables across a global manufacturer’s sites to Microsoft Fabric, fixing seven QAD-specific issues before rollout with zero duplicate records on reloads.
Read the Case Study →Kanerika built and tested a QAD connection on the client’s live systems, using Microsoft’s Open Mirroring. It sends new, changed and deleted records to Fabric, gives each site its own space and logs every run with alerts on errors.
The team found and fixed seven QAD-specific issues on live systems before rollout. It connected more than 200 QAD tables to Fabric and avoided duplicate records on reloads. Read the QAD Open Mirroring case study for the full detail.
This project also shows the coexistence pattern from the plant-floor section in practice. The ERP keeps running, and analytics get a current copy of its data without a big bang.
Case Study: SAP Data Integration for an Edible Oil Manufacturer
A prominent edible oil manufacturer and distributor ran SAP for its main transactions across numerous plants. It also ran non-SAP systems, and staff synced financial and HR data by hand. Insights arrived late and did not always agree, which weakened decisions across production, distribution and sales.
Kanerika consolidated the SAP and non-SAP sources, brought financial and HR data into sync and automated the integration. The results were 60% less data integration time, a 30% increase in productivity and 20% improved business performance, as the full case study describes.
Go/No-Go Checklist: Are You Ready to Start?
Use this checklist before you commit to a first production load. Each item maps to one of the planning steps, and a “no” on any of them is a reason to wait.
Checklist
Data Migration Checklist
Kanerika’s data migration checklist covers scope, data validation, cutover planning and post-move verification, so you can test your plan against it before the first load.
Get the Checklist →- Scope, plants and history depth are written down and signed.
- Every data domain has a named business owner.
- The interface register is complete and agreed by plant IT and operations.
- Master data is profiled, with a golden record rule and a cleansing backlog.
- A retention matrix states what moves, what is archived and what is retired.
- The approach and the coexistence design are chosen and documented.
- Reconciliation checks, tolerances and sign-off owners are agreed.
- A mock cutover has passed inside the outage window.
- Lot genealogy queries return the same answers in both systems.
- The rollback trigger, decision maker and hypercare rota are in place.
The Verdict on Data Migration in Manufacturing
Data migration in manufacturing succeeds or fails on decisions made before the first load. Settle scope and owners, map interfaces, clean master data and decide what to archive. Then pick the approach, define business checks, rehearse and plan the rollback.
A single plant whose load fits its window can go big bang. A multi-plant estate, or one with data too large for the window, should phase by plant with a preload and change capture.
So, what should you settle before you start? All eight steps, each with its exit criterion met, before the first production record moves.
Frequently Asked Questions
What is data migration in manufacturing?
Data migration in manufacturing is the move of plant records, such as materials, BOMs, open orders, machine readings and lot histories, from one system to another. The goal is to switch systems without stopping production or losing traceability. It usually covers the ERP, MES, historian and quality systems, and it is planned around shifts and cutover windows.
Why is data migration important for manufacturing companies?
Plants run on their data. Production orders, inventory balances and quality records decide what gets built, shipped and released each shift. A clean migration lets a manufacturer move off an unsupported ERP, merge plants after an acquisition or bring plant data into analytics. A poor one can stall order release, distort inventory and break recall traceability.
What are the four types of data migration?
The four commonly cited types are storage migration, database migration, application migration and cloud migration, and some lists add business process migration. A manufacturing project often mixes several, for example an application move from an old ERP to a new one that also moves the database and sends plant data to a cloud analytics platform.
What is the best approach for data migration?
There is no single best approach. Big bang suits one plant whose load fits its outage window. Phased by plant suits estates with different calendars or high risk per site. When data is too large for the window, preload history and use change capture so only a small delta moves at cutover. Disqualifiers matter as much as fit.
What are the stages of data migration?
A typical sequence is assess, profile and map, build and automate, test and reconcile, rehearse, cut over and hypercare. In a plant, each stage ends with a sign-off by business owners. Mock cutovers sit between testing and go-live, and hypercare continues until data KPIs and plant KPIs return to their pre-migration baseline.
How do you migrate manufacturing data without stopping production?
Preload master data and history in the weeks before cutover, then keep it current with change capture. Freeze transactions at a shift change, load only the final delta and reconcile inside a short window. Plant-floor data moves on a separate copy pipeline, so the historian and SCADA systems that run the line are never interrupted.
What data should manufacturers migrate versus archive?
Migrate active master data, open orders, current inventory and open quality items, because the plant needs them to run each shift. Archive closed orders and old transactions in a searchable read-only store if they only need to stay readable. Base each decision on retention rules, audit needs and how often people actually look up the history.
How do you preserve lot traceability during a data migration?
Move the links between lots, not just the lot records. Migrate parent and child lot relationships, serial links and audit trails together. Then run the same forward and backward genealogy queries in both systems on a sample of lots, including some from a past recall drill. The answers must match before the old system retires.
How do you migrate historian and SCADA data?
Keep the control systems running and copy their data to the new platform instead of moving them. Bulk-load past readings in batches during quiet hours, then switch to an incremental feed for new and changed records. Never pull large loads from PLCs during production, and map inconsistent tag names to one standard while the data moves.
How much does a manufacturing data migration cost?
Cost depends on data condition, plant count, interfaces and rehearsals more than on raw volume. Estimate it bottom up by multiplying role hours for discovery, mapping, cleansing, engineering, testing, cutover and hypercare by your rates. Then add infrastructure, licenses, archive storage and a contingency for issues that profiling has not yet revealed.
How do you validate migrated manufacturing data?
Go beyond row counts. Compare inventory value by plant, open order counts by status, BOM cost roll-ups and lot genealogy results between the old and new systems. Agree a tolerance and an owner for each check before testing starts. A check passes only when its business owner signs it, and the full pack must pass before go-live.
What should a manufacturing migration rollback plan include?
A rollback plan needs a clear trigger, such as an inventory variance above tolerance or a failed order release, plus a named decision maker and a deadline. It lists the steps to reopen the old system, reverse interfaces and handle transactions entered in the new one. Test the plan during a mock cutover, not on go-live weekend.
What is an example of data migration?
A common example is a plant moving from an old ERP to a new one over a cutover weekend. The team loads cleansed materials, BOMs and routings first, then open production orders and inventory balances. It reconciles inventory value by plant and open order counts, and the new system goes live only after the go or no-go call.
What are the 6 Rs of data migration?
The 6 Rs are cloud migration strategies, namely rehost, replatform, repurchase, refactor, retire and retain, and the 7 Rs add relocate. They describe what happens to each application. For plant data, they help decide whether a system moves as is, gets rebuilt on a new platform or is retired, with its history kept in a read-only archive.
What are data migration strategies?
The main strategies are big bang, phased by plant or by data domain, parallel run and preload with change capture. ERP moves also choose between brownfield conversion, which keeps the existing configuration and history, and greenfield reimplementation, which starts clean. Selective data transition sits between the two. The right pick depends on outage windows, data quality and plant count.
Which tool is used for data migration?
No single tool covers a plant migration. Teams combine profiling and cleansing tools for master data, ETL or ELT pipelines for loads, change capture or mirroring tools for live sync and reconciliation tools for proof. ERP vendors add their own migration utilities, and Kanerika’s FLIP automates data platform migration work. Choose tools by source, target and data family.
What are the common challenges in manufacturing data migration?
The usual challenges are duplicate master data across plants, records that depend on each other, open orders that change until cutover and outage windows too short for a full load. Plant-floor data adds volume and naming problems. Regulated plants must also keep lot genealogy and audit trails intact, which needs testing before and after the move.
Which manufacturing systems are typically involved in data migration?
The ERP and PLM hold business data such as materials, BOMs, costs and orders. The MES, historian and QMS hold what the plant actually made, measured and inspected. SCADA and IoT platforms add machine events and sensor readings, and BI tools sit on top. A migration often touches several of these, along with the interfaces between them.
How can manufacturers reduce risks during data migration?
Name business owners per data domain, profile and clean master data early and load records in dependency order. Agree business-level reconciliation checks with tolerances before testing. Rehearse the cutover on production-sized data until it fits the window. Set a rollback trigger with a named decision maker, and staff hypercare on every shift after go-live.
How long does a manufacturing data migration typically take?
Duration depends on plant count, data quality, the approach and the number of rehearsals needed. A single plant with clean data moves faster than a group of plants carrying several item masters. Phased moves stretch the timeline but cut risk per plant. Build the estimate from discovery, cleansing, testing and mock cutover effort rather than from averages.