TL;DR
Use semi-supervised learning when a small labeled set gives a credible baseline and your unlabeled data looks like production. When either condition is missing, label more data first. The model learns from those labels first, then from patterns in the unlabeled records. Self-training is the safest first method, and scikit-learn includes it. Each round must beat a clean, human-labeled test set, or its new labels go back out. Govern pseudo-labels like any training data, with an audit sample and a record of model-labeled rows.
Key Takeaways
- Semi-supervised learning trains on a small labeled set plus a large unlabeled set, so it cuts labeling volume without dropping evaluation.
- It pays off only when the supervised baseline is already credible and the unlabeled data matches what the model will see in production.
- Self-training with a high confidence threshold is the simplest starting point, while consistency methods suit images and audio with valid augmentations.
- A clean labeled holdout decides every round, because confident wrong pseudo-labels compound as the model retrains on them.
- Active learning and LLM-generated labels sit next to it: one picks what humans label next, the other adds noisy labels that need the same gates.
- Regulators expect training data that is relevant, representative and as error-free as possible, so pseudo-labels need an audit trail.
A Backlog of 400,000 Documents and 2,000 Labels
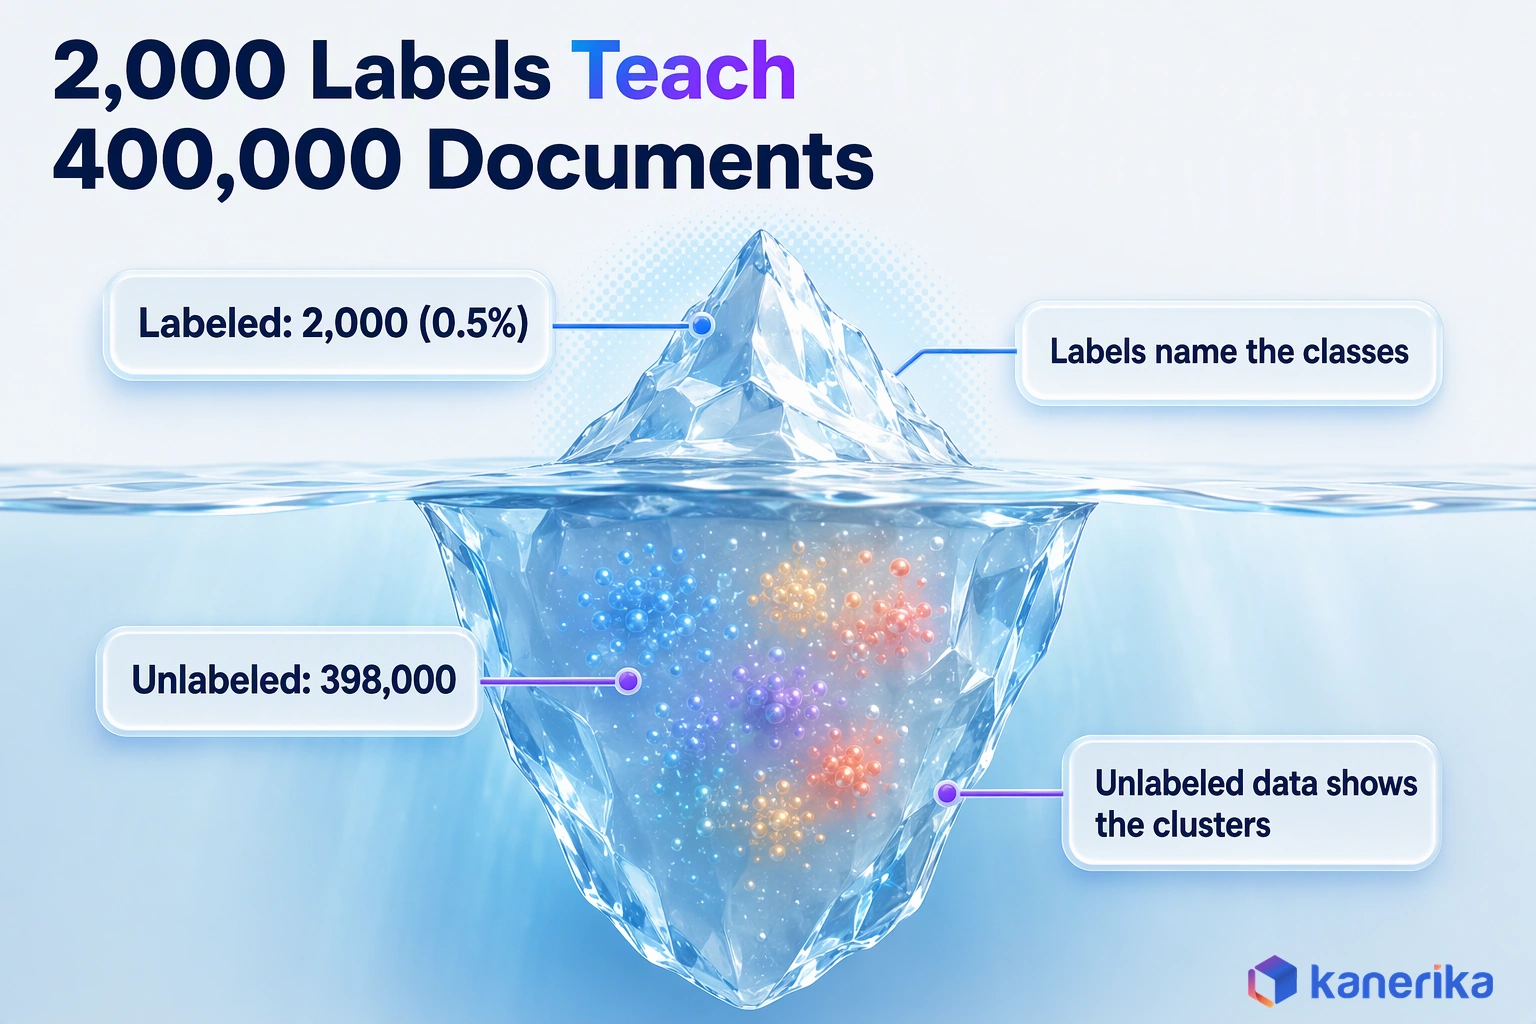
Picture an insurance operations team with 400,000 scanned claim documents waiting to be routed. Each one belongs in a queue, such as medical bills, police reports, repair estimates or correspondence. Over two months, the team’s specialists have hand-labeled 2,000 of them, which is half a percent of the backlog.
A supervised classifier trained on those 2,000 documents works, but only just. It routes the common document types well but stumbles on the rest. Hiring annotators to label another 50,000 would take a quarter, and the specialists who know the queues have day jobs.
The other 398,000 documents are not useless, though. They carry the same layouts, vocabulary and patterns as the labeled ones, but without a tag. The scenario is illustrative, but the question it raises is real for any enterprise data team: can those unlabeled records teach the model something?
That question is what semi-supervised learning answers. This guide covers how it works, which technique to pick, when to use it, what it saves and how to govern it.
What Is Semi-Supervised Learning?
Semi-supervised learning (SSL) is a way to train a model on a small labeled dataset and a much larger unlabeled one at the same time. The labeled part tells the model what the classes mean. The unlabeled part shows where the data naturally clusters and where the boundaries between classes probably fall.
A Plain Definition
Take a support desk that receives 30,000 tickets a month and has labeled 1,500 of them by queue. A purely supervised model sees only those 1,500 examples. An SSL model also reads the other 28,500 tickets and notices, for example, that refund requests share phrasing even when nobody tagged them.
The model then uses that structure so that it can label more data or shape its decision boundary. The labels still anchor everything, so a bad seed set produces a bad model. What changes, then, is how far a good seed set can stretch.
In practice, the unlabeled data is usually the cheap part. Logs, tickets, documents, images and sensor readings pile up on their own, while labels need a specialist’s time. Work on unstructured data such as text and scans is where that gap tends to be widest.
Kanerika Service
Data Engineering Services
Kanerika builds the pipelines that collect, clean and version unlabeled logs, documents and images, so ML teams train on data they can trust and trace.
Explore Data EngineeringSemi-Supervised vs Supervised, Unsupervised, Self-Supervised and Weak Supervision
These five terms get mixed up because each one changes how much human labeling a model needs. The table therefore separates them by what the model learns and where enterprises use it. For the wider map of AI, ML and deep learning, see our guide to AI vs ML vs deep learning vs neural networks.
| Approach | Labels needed | What it learns | Enterprise example |
|---|---|---|---|
| Supervised | Every training row | Mapping from inputs to known labels | Credit decision model trained on past outcomes |
| Unsupervised | None | Clusters, anomalies and structure | Customer segmentation, outlier detection |
| Semi-supervised | A small labeled set plus many unlabeled rows | Labeled mapping, shaped by unlabeled structure | Document routing with a few thousand tagged files |
| Self-supervised | None from humans; the data creates its own task | General representations, later fine-tuned | Language model pretraining on raw text |
| Weak supervision | Noisy labels from rules, heuristics or models | A model that tolerates imperfect labels | Keyword rules or LLM prompts that tag tickets |
Self-supervised and semi-supervised are easy to confuse. Self-supervised learning builds a pretraining task from raw data, such as predicting a masked word. Semi-supervised methods still depend on human labels; they just use fewer of them.
How Semi-Supervised Learning Works
Every SSL method rests on one bet: the unlabeled data has a shape, and that shape lines up with the classes you care about. When the bet holds, unlabeled rows sharpen the model. When it fails, they mislead it with total confidence.
The Four Assumptions
The smoothness assumption says that points close together in feature space should share a label. For instance, two invoices with nearly identical line items are probably the same document type. It breaks when tiny differences decide the class, as with a fraud pattern hidden inside a normal-looking transaction.
The cluster assumption says that data forms groups and each group tends to hold one class. Its cousin, the low-density assumption, adds that good decision boundaries run through sparse regions rather than crowded ones. Both fail when classes overlap heavily, so the clusters never separate cleanly.
The manifold assumption says that high-dimensional data, such as images or text embeddings, actually sits on a simpler surface. Learning that surface from unlabeled data also makes the labeled examples go further. It weakens when the unlabeled pool comes from somewhere else.
That last failure is the one enterprises hit most often. For example, an unlabeled pool from a different region, season, product line or source system describes a different distribution. The model then learns the wrong shape and still applies it to production data with high confidence.
The Training Loop
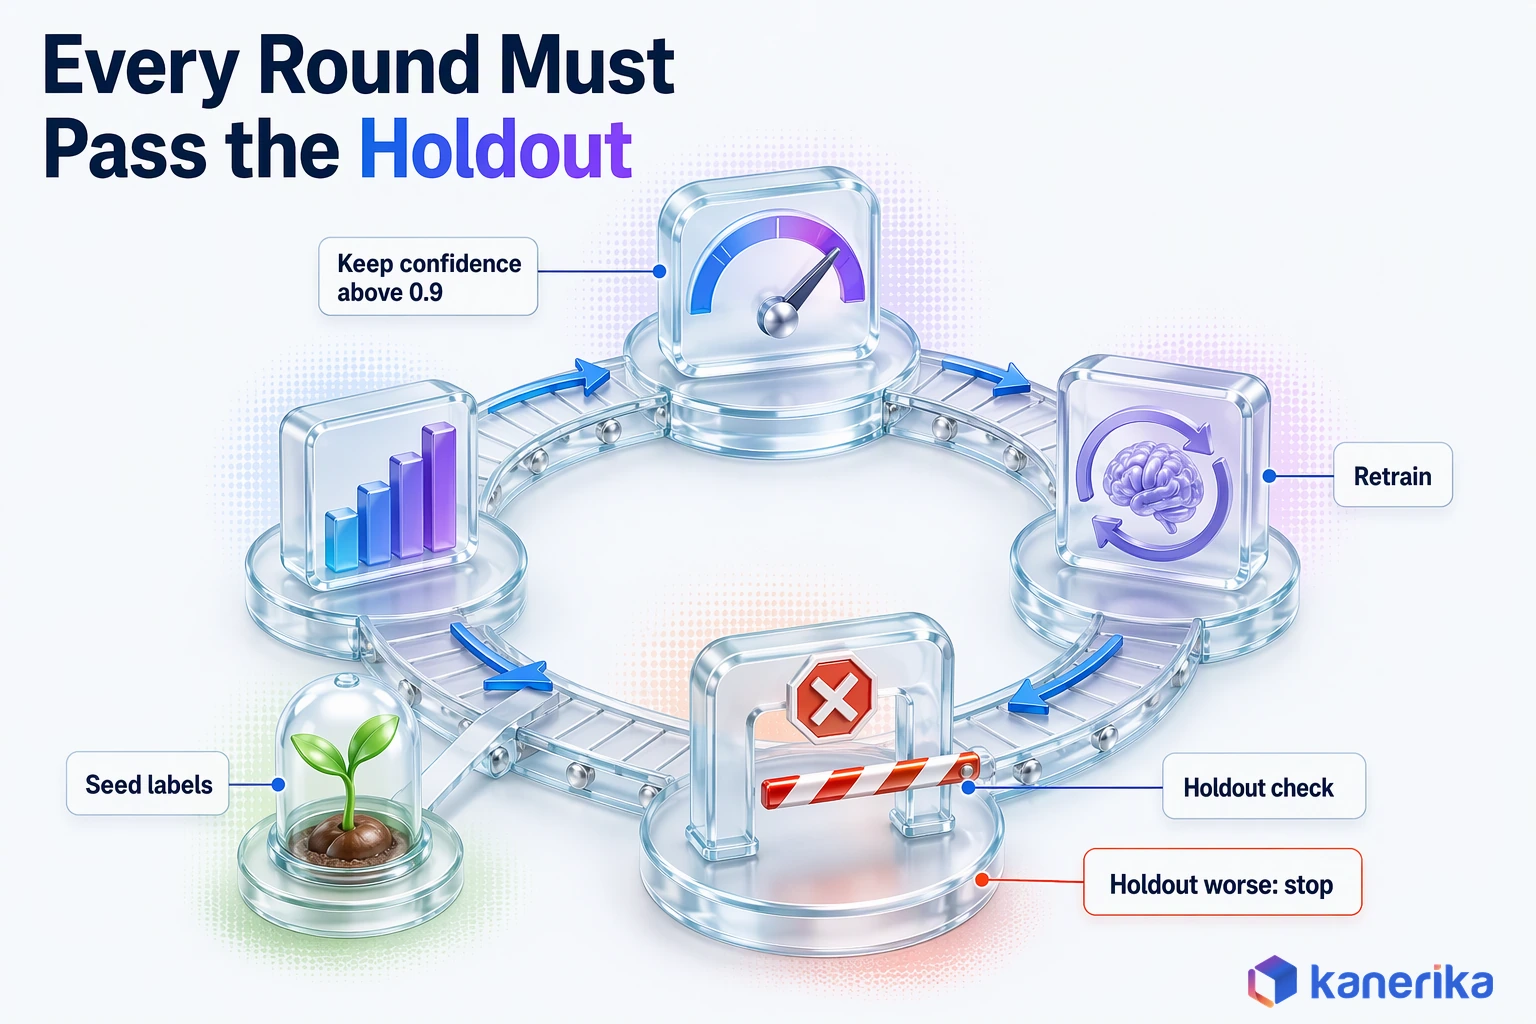
Self-training, the most common enterprise pattern, follows a short loop. Each step has a gate, and in practice the gates matter more than the model choice.
- Label a seed set. Cover every class, including the rare ones, with enough examples to train a baseline.
- Train a supervised baseline. Then score it on a clean labeled holdout that never touches training.
- Predict on the unlabeled pool. Keep only predictions above a confidence threshold, such as 0.9, as pseudo-labels.
- Retrain on labels plus pseudo-labels. Mark which rows were labeled by the model and in which round.
- Check the holdout. Keep the round only if holdout metrics hold or improve, overall and per class.
- Stop on a rule. Stop when no new rows pass the threshold, when a round limit hits, or when the holdout gets worse.
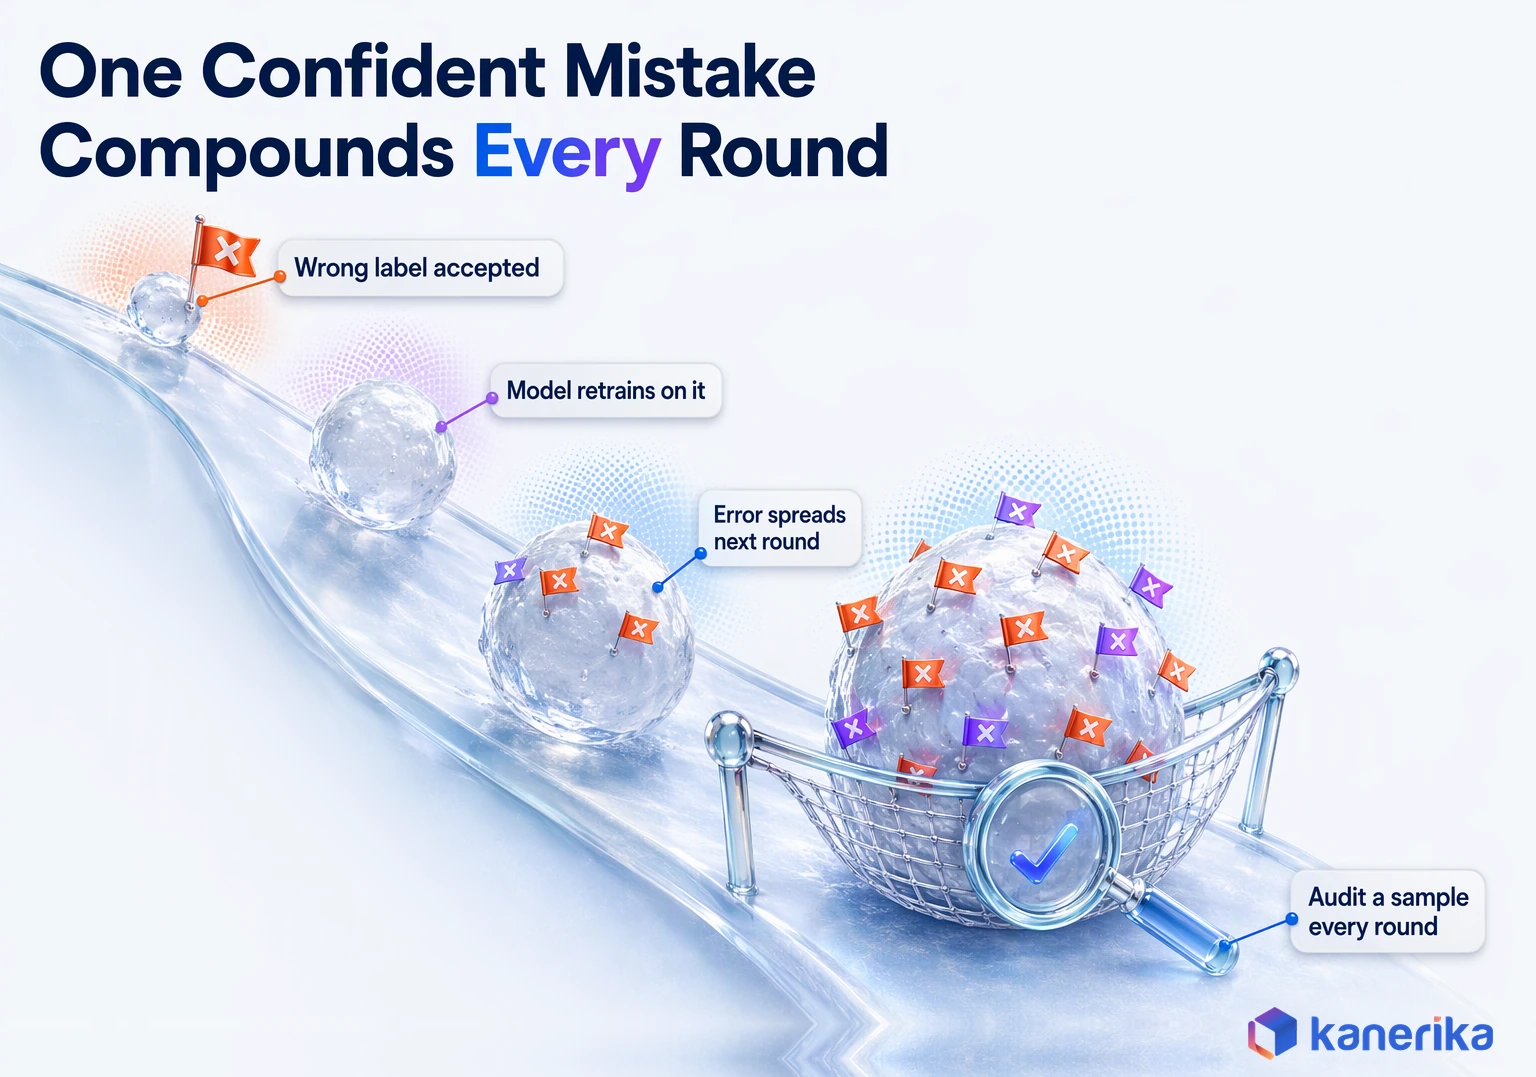
The holdout is the part teams cut corners on, and it is the part that protects them. Because pseudo-labels come from the model itself, the training data can no longer tell you whether the model is right. Only labels a person assigned can do that, so the holdout stays human-labeled.
Transductive vs Inductive Use
Transductive use means labeling one fixed pool and stopping there. The 400,000-document backlog is a transductive job, because once every document has a queue, the work is done.
Inductive use means training a model that will score new data next month and next year. That is the harder case, since the model must generalize beyond the pool it learned from. It also needs monitoring and retraining triggers, which we cover later in the governance section.
Semi-Supervised Learning Techniques Compared
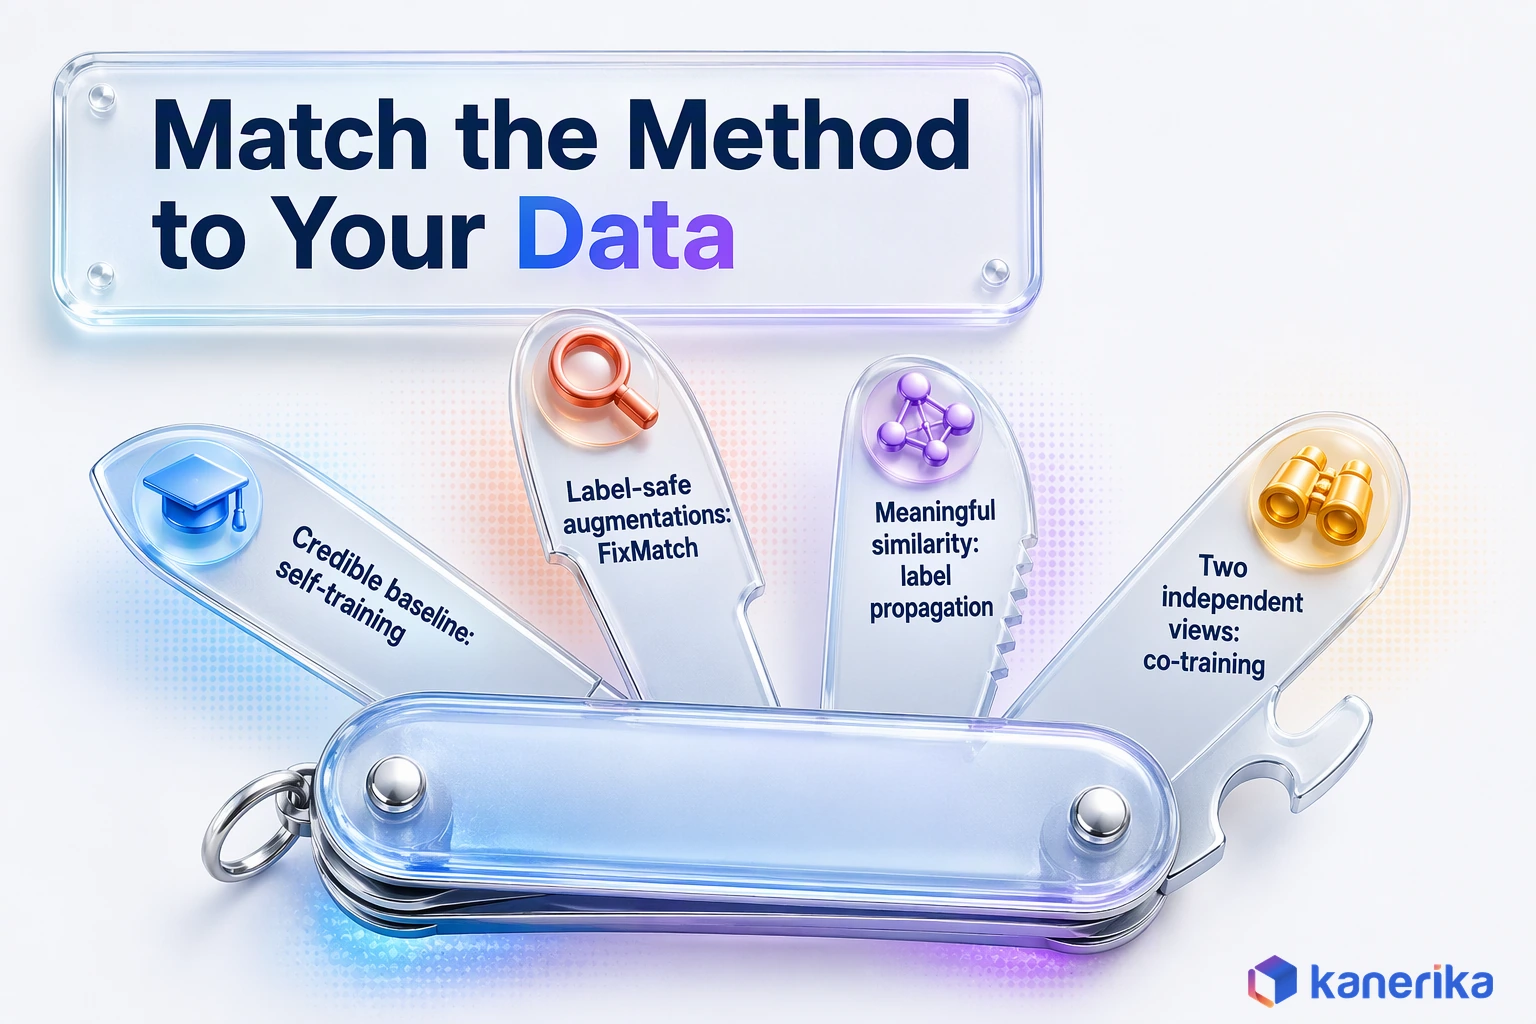
The techniques differ mainly in what they ask of your data. Some need a confident baseline, some need augmentations that keep the label intact, and some need a meaningful notion of similarity between rows. The table sets them side by side before we look at the three families teams use most.
| Technique | Best fit | Main risk | Effort |
|---|---|---|---|
| Self-training and pseudo-labeling | Tabular data and text with a credible baseline | Confident wrong labels reinforce themselves | Low |
| Co-training | Data with two independent views, such as text and metadata | Views that are not truly independent | Medium |
| Label propagation and label spreading | Data with a meaningful similarity graph | Graph cost on large datasets; poor similarity measures | Medium |
| Consistency regularization (FixMatch) | Images and audio with label-preserving augmentations | Augmentations that change the true label | High |
| Teacher-student (Noisy Student) | Large vision or speech models with plenty of compute | Training cost and long iteration cycles | High |
| Hybrid pipelines | Mature teams combining active learning, weak labels and SSL | Too many moving parts to audit | High |
Self-Training and Pseudo-Labeling
Self-training wraps any probabilistic classifier. The model labels the unlabeled rows it is most sure about, adds them to training and then repeats. In scikit-learn this is the SelfTrainingClassifier, which defaults to a 0.75 threshold and up to 10 rounds.
It can also add a fixed number of rows per round through its k_best criterion, set to 10 by default. Since version 1.6, the wrapped model goes in the estimator parameter rather than base_estimator. The documentation also advises a well-calibrated classifier when you select by threshold, because raw scores from some models overstate confidence.
Treat the default threshold as a starting point and set your own for each use case. On high-consequence work, teams usually raise it and accept that fewer rows get pseudo-labeled in each round.
Graph Methods: Label Propagation and Label Spreading
Graph methods treat every row as a node and connect similar rows with weighted edges. Labels flow from labeled nodes to their neighbors until the graph settles. The two versions in the scikit-learn semi-supervised guide differ in two ways. LabelPropagation uses the raw similarity graph. LabelSpreading normalizes it and adds regularization, so it copes better with noisy labels.
Clamping decides whether the original labels can change. LabelPropagation keeps them fixed, while LabelSpreading lets them soften slightly, which helps when a few seed labels are wrong. Either way, the method lives or dies on whether your similarity measure reflects what makes two records the same class.
The scikit-learn digits example makes this concrete. LabelSpreading gets 40 labeled handwritten digits and 300 unlabeled ones, then infers labels for the 300 with an overall accuracy of 0.90. Recall on the digit 8 is only 0.68, though, so check the weakest class as well as the average.
Consistency Regularization and Teacher-Student Models
Consistency methods teach the model to give the same answer for an input as well as for a slightly altered copy of it. For example, a product photo that is cropped, flipped or brightened is still the same product. FixMatch, published by Sohn and colleagues in January 2020, combined this idea with pseudo-labels.
It reached 94.93% accuracy on the CIFAR-10 image benchmark with 250 labels, and 88.61% with only 40, which is four per class. Those are research benchmarks on clean data, though, not a promise for your documents. Still, they show how far good augmentations can carry a tiny label set.
Teacher-student training takes the self-training idea to scale. In Noisy Student (Xie and colleagues, 2019, revised 2020), a teacher labels unlabeled images and a larger, noised student learns from them. It reached 88.4% top-1 accuracy on ImageNet, 2.0 percentage points above a model trained with 3.5 billion weakly labeled Instagram images.
Generative Models: VAEs and GANs
Generative approaches learn how the data itself is produced and use that knowledge to place the class boundary. In June 2014, Kingma and colleagues applied deep generative models to this problem. Their variational autoencoders (VAEs) learned from a few labels and many unlabeled rows at once.
GANs followed in June 2016. In Improved Techniques for Training GANs, Salimans and colleagues trained the discriminator to sort real images into classes and also to flag generated ones. They reported state-of-the-art semi-supervised results on MNIST, CIFAR-10 and SVHN at the time.
GAN training is notoriously unstable, which is why that paper focused on training techniques. Most enterprise teams start with the simpler methods above for that reason. Our explainer on generative vs discriminative models covers how the two families differ.
Worked Example: Pseudo-Labeling a Ticket Classifier in Python
A small, honest pilot is the best way to learn whether SSL helps your data, because it measures your own records. The example below routes support tickets into queues, using scikit-learn’s TF-IDF features and logistic regression. It trains a supervised baseline and a self-training model, then scores both on the same labeled holdout.
The setup assumes a list of ticket texts and a label array y, where each unlabeled row carries the integer -1. That marker is how scikit-learn tells labeled rows apart from unlabeled ones. X_test and y_test form a holdout that a person labeled and that never enters training.
import numpy as np
from sklearn.feature_extraction.text import TfidfVectorizer
from sklearn.linear_model import LogisticRegression
from sklearn.pipeline import make_pipeline
from sklearn.semi_supervised import SelfTrainingClassifier
from sklearn.metrics import classification_report

# texts: all tickets; y: queue id for labeled rows, -1 for unlabeled rows
labeled = y != -1
baseline = make_pipeline(TfidfVectorizer(min_df=2), LogisticRegression(max_iter=1000))
baseline.fit(np.array(texts)[labeled], y[labeled])

self_train = make_pipeline(
    TfidfVectorizer(min_df=2),
    SelfTrainingClassifier(LogisticRegression(max_iter=1000), threshold=0.9, max_iter=10),
)
self_train.fit(texts, y)

print(classification_report(y_test, baseline.predict(X_test)))
print(classification_report(y_test, self_train.predict(X_test)))

st = self_train[-1]
print("rows pseudo-labeled:", int((st.labeled_iter_ > 0).sum()))
print("stop reason:", st.termination_condition_)
The threshold sits at 0.9 rather than the 0.75 default, which trades volume for safety. Compare the two classification reports class by class, not just on overall accuracy. A gain on common queues can hide a loss on the rare ones.
The labeled_iter_ attribute records the round in which each row got its label: zero for human labels, a positive number for pseudo-labels and -1 for rows never labeled. Then pull a random sample of pseudo-labeled tickets from it and have a specialist check them. Results vary widely by dataset, so treat this as a test harness rather than a promise of gains.
Kanerika Service
Machine Learning Services
Kanerika machine learning engineers build and measure pilots like this one on your own data, from seed labels and baselines to holdout reviews and monitored production models.
Explore ML ServicesEnterprise Use Cases: Where Semi-Supervised Methods Pay Off
SSL earns its place wherever raw data piles up faster than experts can label it. In each case, the label needs a specialist, a regulator-grade review or a rare event to confirm. The table lists the patterns we see most, with the label bottleneck stated plainly.
| Use case | Why labels are scarce | Typical method |
|---|---|---|
| Document and invoice classification | Only finance or operations staff know the right category | Self-training on text features |
| Fraud and anomaly detection | Confirmed fraud takes weeks to establish and is rare | Anomaly scores plus self-training on confirmed cases |
| Manufacturing defect inspection | Defects are rare and need an inspector to confirm | Consistency regularization on images |
| Support ticket routing | Queue definitions change and tagging lags behind | Self-training or label spreading |
| Speech and medical imaging | Transcription and clinical labels need trained experts | Teacher-student and consistency methods |
Document routing is the friendliest starting point, because text features are cheap and holdouts are easy to build. In practice, routing a ticket or invoice is one step in a larger workflow, and AI automation tools often handle the steps that follow.
Talk to Kanerika
Which Workflow Should Go Semi-Supervised First?
Talk to Kanerika about the document, fraud, inspection or ticket-routing workflow where scarce labels hurt most, and scope a pilot with a frozen holdout and a stop rule.
Schedule a Demo →Vision work follows the same logic, only with images. Defect inspection and AI video surveillance both generate endless footage, while confirmed events stay rare. Teams working in computer vision tend to reach for consistency methods first. For analytics teams that apply ML to forecasting and segmentation instead, our guide to machine learning for business analytics covers that ground.
When to Use Semi-Supervised Learning: A Decision Framework
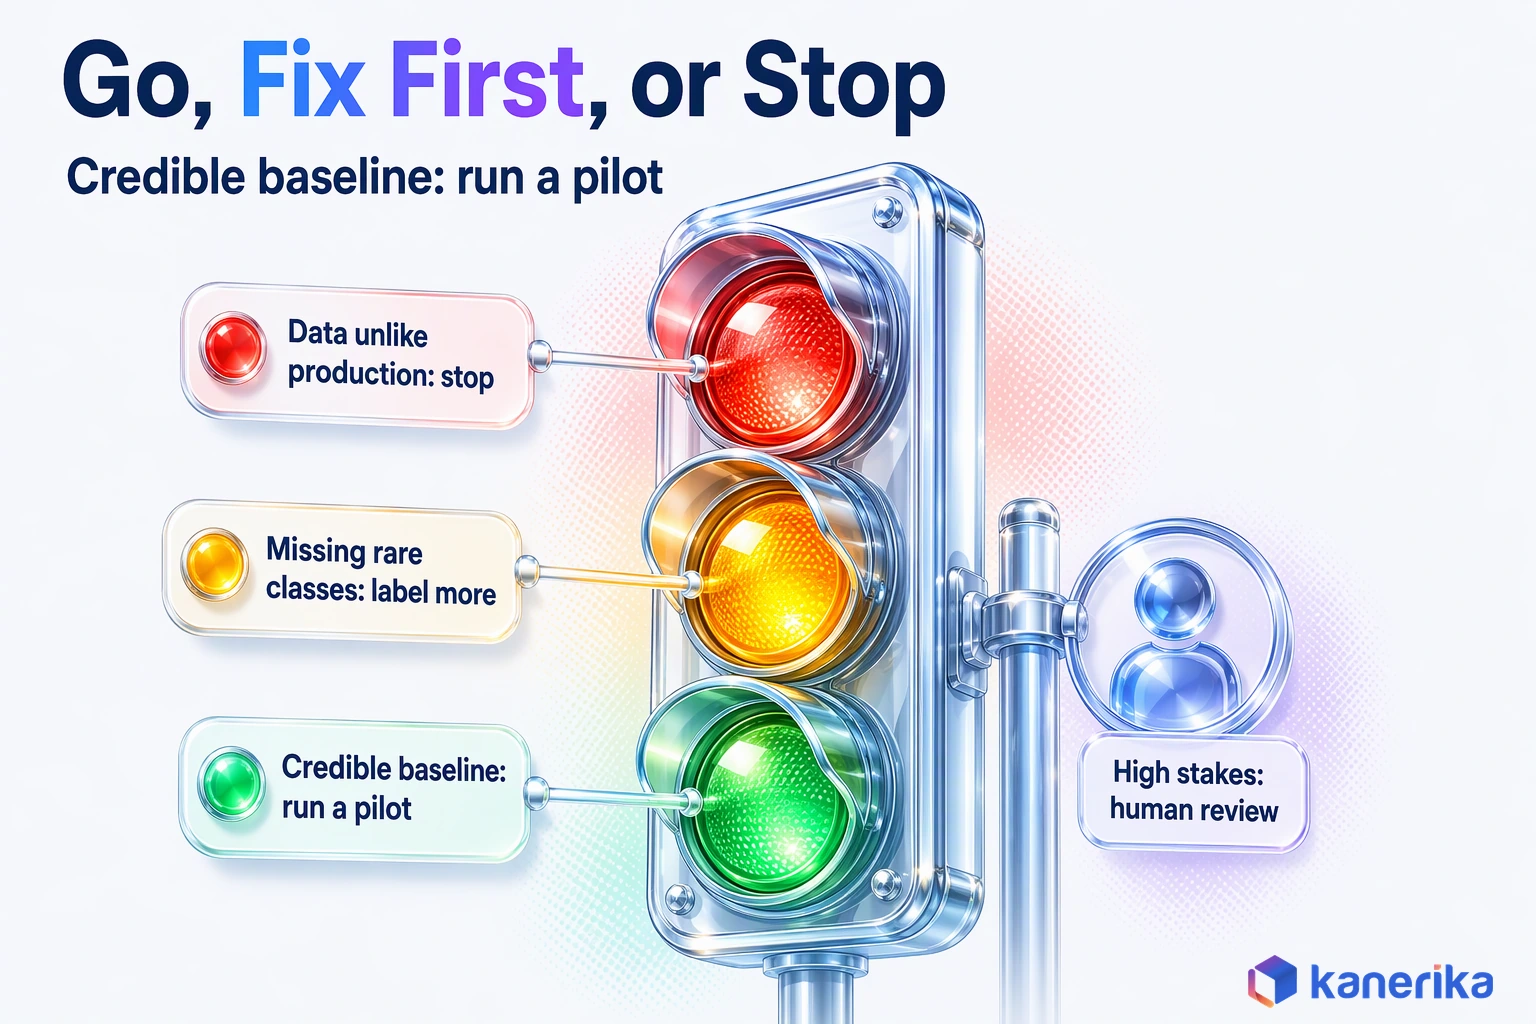
Whether SSL is worth a pilot depends on two things you can check this week. How good is your supervised baseline, and does your unlabeled data look like production? SSL multiplies what a good seed set already knows. It cannot rescue a model that has never seen a class.
Scenario-to-Approach Table
Start from the scenario you actually have, then check the gate in the last column before spending anything. Each row picks a side, even where the answer is to stop.
| Your scenario | Pick | Gate before you proceed |
|---|---|---|
| Credible supervised baseline, large in-distribution unlabeled pool | Use SSL: pseudo-labeling pilot | Holdout and per-class metrics agreed in advance |
| Images or audio with augmentations that keep the label | Use SSL: consistency regularization | Augmentations reviewed by a domain expert |
| Rows with a meaningful similarity measure | Use SSL: label propagation or spreading | Graph fits in memory; neighbors make sense on inspection |
| Two independent views of each record | Use SSL: co-training | Each view trains a decent model on its own |
| Weak baseline, or rare classes missing from the labels | Not yet: label more or use active learning first | Every class has enough seed examples |
| Unlabeled data unlike production data | Do not use SSL | Fix data sourcing before any modeling |
| High-consequence decisions with weak evaluation | Do not use SSL: supervised baseline plus human review | A trusted holdout and an accountable reviewer |
Notice that four rows say yes and three say not yet or no. That ratio is deliberate, since stopping is a valid result. A pilot that stops at the gate has still done its job, because it saved a quarter of work on a model that would not have held up.
Advantages and Limitations
The trade-offs are clearest side by side. Read the right column as a list of gates to pass before a pilot starts.
| Advantages | Limitations |
|---|---|
| Uses data you already store, at no labeling cost | Depends on assumptions that can quietly fail |
| Cuts the number of rows specialists must label | Confident wrong pseudo-labels reinforce themselves |
| Often lifts accuracy on common classes | Can amplify class imbalance and miss rare classes |
| Works with standard libraries such as scikit-learn | Needs a clean holdout and an audit trail to trust |
The Business Case in Label Hours
Hours are the easiest unit for this case, since every team prices its specialists differently. The formula is short: hours saved equal records not hand-labeled, times minutes per label, divided by 60. Subtract the hours spent reviewing a sample of pseudo-labels.
Here is how that looks with the hook’s numbers and assumed rates. Suppose a pilot lets the team skip hand-labeling 50,000 documents at two minutes each. That is 100,000 minutes, or about 1,667 hours.
A reviewer then checks a 1,000-document sample at three minutes each, which costs 50 hours. That leaves a net of roughly 1,617 specialist hours. Plug in your own volumes and minutes; the method matters more than our assumptions.
Labels are only one part of that case. Whether a data team can turn its unlabeled archive into training data at all often depends on how mature its data foundation is, the theme of our State of Enterprise AI 2026 episode on data foundations, maturity stages and ROI.
Semi-Supervised Learning vs Active Learning and LLM-Generated Labels
Three methods compete for the same labeling budget, and they work better together than apart. Active learning decides which rows a person should label next, so expert time goes where it counts. SSL uses the rows that stay unlabeled, while LLM-generated labels add a third, noisier source.
Active learning ranks unlabeled rows by how much a label would teach the model, often the ones it is least sure about. That makes it a natural first step when a baseline is weak or a rare class is thin. Once the seed set is solid, SSL takes over the confident bulk.
The scikit-learn active learning with label spreading example shows both working together. It starts with 40 labeled digits out of 330 and asks for labels on the five most uncertain points each round. After four rounds, with 60 labels in hand, accuracy on the remaining rows rose from 0.87 to 0.96.
LLM-generated labels are a form of weak supervision. A prompt can tag thousands of tickets in an hour, but its mistakes are systematic rather than random. Run those labels through the same confidence gates, holdout checks and audit samples as any pseudo-label. The generative-model section above explains why a language model labels differently from a classifier trained only on the boundary.
| Method | What it decides | Best moment to use it |
|---|---|---|
| Active learning | Which rows a person labels next | Weak baseline, thin rare classes |
| Semi-supervised learning | How unlabeled rows shape the model | Credible baseline, large in-distribution pool |
| LLM or rule-generated labels | A fast, noisy first label for many rows | New categories with no history; always audited |
All three still begin with a human-labeled seed set. Good data annotation tools make that seed set faster to build and easier to review, and they keep the record of who labeled what.
Risks, Governance and Common Mistakes
Pseudo-labels are training data that no person has checked, and that changes the governance picture. A wrong human label is one mistake, whereas a wrong pseudo-label can be copied into thousands of rows. The controls below keep that from happening quietly.
Risk-to-Control Table
Each risk below has happened in real pilots, and each has a control that costs far less than the cleanup.
| Risk | What happens | Control |
|---|---|---|
| Confirmation bias | Confident wrong pseudo-labels feed the next round | High threshold, per-round audit sample, holdout gate |
| Class imbalance amplification | Common classes win more pseudo-labels; rare ones shrink | Per-class thresholds and per-class holdout metrics |
| Distribution shift | Unlabeled pool differs from production data | Compare feature distributions before training |
| Leakage | Holdout rows also sit in the unlabeled pool | Deduplicate across splits; freeze the holdout |
| No audit trail | Nobody can say which labels came from the model | Store source, round and confidence for every label |
What Regulators and Frameworks Expect
Frameworks do not mention pseudo-labels by name, but their data rules apply to them directly. The NIST AI Risk Management Framework 1.0 was released on January 26, 2023. Its Map and Measure functions ask teams to document where training data comes from and to test systems on data that represents real use. For SSL, that means recording which labels the model made and scoring it on a human-labeled holdout.
In Europe, Article 10 of the EU AI Act sets data rules for high-risk systems. It says training, validation and testing data sets shall be relevant and sufficiently representative. They should also be, to the best extent possible, free of errors and complete.
So a team that cannot say which labels a model generated for itself will struggle to show its training data meets either test. Pseudo-label controls belong inside a wider machine learning governance program, next to model inventories, approvals and monitoring. They also inherit the usual data governance challenges around ownership and lineage.
Common Mistakes
The same five errors show up across SSL pilots, and each one is cheap to prevent early.
- Skipping the baseline. Without a supervised score, nobody can tell whether the unlabeled data helped.
- Reusing training rows as the holdout. The model then grades its own homework.
- Keeping the default threshold on high-stakes work. Raise it and accept fewer pseudo-labels per round.
- Reading only overall accuracy. Rare classes can get worse while the average improves.
- Throwing away the pseudo-label record. Without source and round per label, audits and rollbacks are guesswork.
Underneath all five sits label quality. If the seed labels disagree with each other, every later round inherits that confusion, which is why the cleanup work comes first.
How Kanerika Delivers Semi-Supervised Learning
We run SSL as a staged program, so each stage earns the right to start the next. The order follows the gates in this guide, and the first two stages often decide that more labels come before any SSL.
- Data and label readiness audit. We profile the labeled and unlabeled pools, check class coverage and look for distribution gaps.
- Supervised baseline and method pick. We train a baseline, agree on holdout metrics and choose the technique from the decision table.
- Controlled pilot with a holdout. We run pseudo-labeling rounds against a frozen holdout and review audit samples with your specialists.
- Governance and monitoring sign-off. We record label sources, rounds and confidence, and align controls with your model risk process.
- Rollout with retraining triggers. We set drift and accuracy triggers that start a new round or a human review.
This work sits within our machine learning services, and the readiness audit leans on data engineering to clean and join sources first. It also fits a wider enterprise AI roadmap rather than standing alone as an experiment.
As of November 2026, our machine learning services page counts 100+ AI/ML solutions delivered, with 65% faster time-to-production and a 95% model adoption rate. The rule behind the first stage is written on that page too: “Kanerika fixes data quality, pipeline, and integration gaps before model development.”
Case Study: Fraud Detection With Scarce Labels
A fraud project shows the same label-scarce condition. The client, a mid-sized US insurer rated A+ by AM Best for financial strength, faced fraud losses and weak credit assessment. Kanerika built ML anomaly models, including Isolation Forest and an autoencoder, together with credit-risk and forecasting models.
Fraud labels are scarce by nature, since a case is confirmed only after investigation. Isolation Forest and an autoencoder both learn what normal records look like, so neither needs a confirmed fraud label to start. That matches the first gates in this guide: with too few labels for a supervised baseline, a label-free detector goes first.
The company recorded a 33% decrease in financial losses and a 25% reduction in overall risk exposure, and its customer base grew 37%. That project used anomaly detection rather than SSL. The cases investigators confirm over time are exactly the seed set a later semi-supervised model, built on top of the anomaly scores, would need.
Case Study
33% Fewer Financial Fraud Losses with AI Modeling & Forecasting
Kanerika built ML anomaly, credit-risk and forecasting models for a mid-sized US insurer with an AM Best A+ rating, cutting financial losses 33% and overall risk exposure 25%.
Read the Case Study →Is Semi-Supervised Learning Right for Your Team?
For most enterprise teams, the answer comes down to three questions about data and evaluation. Answer them honestly before you budget a pilot, since each one is a gate.
- Does a supervised baseline already work? If not, label more or try active learning first.
- Does the unlabeled data look like production? If not, fix sourcing before any modeling.
- Can you hold out clean labels and audit pseudo-labels? If not, the risk outweighs the hours saved.
When all three answers are yes, a pseudo-labeling pilot is worth a few weeks, with a frozen holdout and a stop rule. Otherwise, any no means fix that gap first and come back. So is semi-supervised learning right for your team? Yes, when a credible baseline, production-like unlabeled data and a clean holdout are all in place; otherwise label first.
Frequently Asked Questions
What is semi-supervised learning?
Semi-supervised learning is a machine learning approach that trains a model on a small set of labeled examples plus a much larger set of unlabeled ones. The labels teach the model what each class means, while the unlabeled data shows how records cluster. Teams use it when raw data is plentiful but expert labels are slow or expensive.
What is the difference between supervised learning and semi-supervised learning?
Supervised learning needs a label on every training row, so its accuracy is capped by how many rows people can label. Semi-supervised learning starts from a smaller labeled set and adds unlabeled rows through pseudo-labels, consistency checks or similarity graphs. Both still need a clean labeled holdout, because only human labels can confirm whether the model is right.
What is semi-supervised clustering?
Semi-supervised clustering groups data mostly without labels but uses a few known labels or constraints to guide the result. A constraint might say two records must share a cluster, or must never share one. It helps when pure clustering produces groups that do not match business categories, such as customer segments that marketing and finance both recognize.
Where does semi-supervised learning fit among the types of machine learning?
Machine learning is usually split into supervised, unsupervised and reinforcement learning, and all three sit within artificial intelligence. Semi-supervised learning sits between supervised and unsupervised, because it combines a few labels with many unlabeled rows. Self-supervised learning and weak supervision are related variants that also reduce how much hand labeling a model needs before training.
Is generative AI semi-supervised?
Not in the strict sense. Large language models are mainly pretrained with self-supervised learning, predicting missing or next words in raw text without human labels. They are then fine-tuned with labeled examples and human feedback. Generative models can, however, produce labels that feed a semi-supervised pipeline, as long as those labels pass the same confidence and audit gates.
How does semi-supervised learning work?
A team labels a seed set and trains a supervised baseline. The model then predicts on unlabeled data and keeps only predictions above a confidence threshold as pseudo-labels. It retrains on labels plus pseudo-labels and is scored on a clean labeled holdout after every round. The loop stops when no new rows qualify or holdout results get worse.
How much labeled data does semi-supervised learning need?
There is no fixed number, because it depends on how many classes you have and how separable they are. FixMatch reached 88.61% accuracy on the CIFAR-10 benchmark with only 40 labels, but that was clean research data. In enterprise work, aim for a seed set that trains a credible baseline and covers every class, including rare ones.
How do you evaluate a semi-supervised learning model?
Freeze a holdout of rows that people labeled and that never enter training or the unlabeled pool. Score the supervised baseline and every semi-supervised round on that holdout, per class as well as overall. Also review a random sample of pseudo-labels with a specialist, since the training metrics cannot reveal errors the model introduced itself.
Is semi-supervised learning the same as self-supervised learning?
No. Self-supervised learning needs no human labels, because it builds a training task from the raw data, such as predicting a masked word or a hidden image patch. Semi-supervised learning still depends on a small set of human labels. The two often meet, with a self-supervised model providing features that a semi-supervised classifier then uses.
Can LLM-generated labels be used for semi-supervised learning?
Yes, but treat them as weak labels rather than ground truth. A large language model can tag thousands of records quickly, yet its mistakes are systematic and can repeat across a whole category. Pass LLM labels through confidence thresholds, compare results on a human-labeled holdout, audit a sample, and record which labels came from the model.
What is the difference between semi-supervised and unsupervised learning?
Unsupervised learning uses no labels at all and finds clusters, anomalies or structure on its own, which a person must then interpret. Semi-supervised learning adds a small labeled set, so the model learns named classes such as invoice types or fraud cases. In short, unsupervised methods describe the data, while semi-supervised methods predict labels you defined.
When should I use semi-supervised learning?
Use it when a supervised baseline trained on your existing labels is already credible and you hold a large pool of unlabeled data that matches production. Document routing, ticket classification and defect inspection are common fits. Label more first when rare classes are missing, and avoid it when the unlabeled data comes from a different region, season or system.
What are the disadvantages of semi-supervised learning?
The main drawback is that confident wrong pseudo-labels feed the next training round and reinforce themselves. It can also amplify class imbalance, because common classes win more pseudo-labels than rare ones. Results depend on assumptions about data structure that fail quietly, and teams need a frozen holdout plus an audit trail to trust the model they produce.
Which methods fall under semi-supervised learning?
The main families are self-training or pseudo-labeling, co-training on two views of the data, graph methods such as label propagation and label spreading, consistency regularization such as FixMatch, and teacher-student training such as Noisy Student. Many enterprise teams start with self-training, because it wraps an ordinary classifier and is available in scikit-learn as SelfTrainingClassifier.
What is an example of a semi-supervised learning model?
A support ticket classifier is a simple example. A team labels 1,500 tickets by queue, trains a logistic regression baseline, then wraps it in scikit-learn’s SelfTrainingClassifier with a 0.9 confidence threshold. The model labels the unlabeled tickets it is most sure about, retrains, and is scored against a held-out set of tickets that people labeled.
Can semi-supervised learning improve accuracy?
It often improves accuracy when the baseline is credible and the unlabeled data matches production, as research benchmarks like FixMatch show. It can also make a model less accurate, because wrong pseudo-labels compound and rare classes can shrink. That is why every round should be compared with the supervised baseline on a clean holdout, class by class.
What is the difference between semi-supervised learning and active learning?
Active learning chooses which unlabeled rows a person should label next, usually the ones the model is least sure about. Semi-supervised learning uses the rows that stay unlabeled to shape the model itself. They work well together, with active learning strengthening a weak seed set first and semi-supervised methods then handling the large, confident bulk of the data.
What is the difference between semi-supervised learning and weak supervision?
Weak supervision gives many rows noisy labels from rules, heuristics, other models or LLM prompts, and trains a model that tolerates the noise. Semi-supervised learning starts from a smaller set of trusted human labels and lets the model label unlabeled rows itself. Teams often combine them, but both need confidence gates, holdout checks and audit samples.