TL;DR
A sound multi-cloud data migration strategy moves live systems with bulk copy plus change data capture, phases merger estates by data domain, and leaves low-change analytics data in place behind federation. Move in dependency-aware waves, so each group of tables travels with the pipelines and reports that read it. Validate business outputs such as revenue totals and report parity before any consumer cuts over, not just row counts. Exit-fee waivers from AWS, Google Cloud and Azure, and the EU Data Act from January 12, 2027, cut the cost of leaving. Parallel running, validation and people still set the budget. The hardest challenges are continuous inflow during cutover, business-rule reconciliation, and keeping identity, keys and residency rules intact across providers.
Key Takeaways
- Multi-cloud data migration moves datasets, pipelines and their consumers between providers, and federation is a third option when moving buys nothing.
- Most estates go multi-cloud by accident through mergers and team choices, and exit-fee waivers now make a planned move cheaper.
- Pick the approach per workload: bulk copy for static data, bulk plus CDC for live systems, phased waves for large estates.
- An eight-step plan with business-level validation and a written rollback trigger list keeps cutover safe.
- Egress is often the smallest cost line you can control, while parallel running, validation and people decide the budget.
- Continuous inflow, reconciliation, cross-cloud identity and residency are the challenges that need a named control before the first byte moves.
One Customer Table, Three Clouds
Picture a mid-size insurer three years after two acquisitions. The finance dashboards run on Azure. The data science team trains churn models on Google Cloud, and the policy system of record writes to Amazon S3. Each team chose well for itself, but nobody chose the whole.
Then the board asks for one governed customer table before an AI rollout. Suddenly the company needs to know which copy is right, what it costs to move each one, and whether some data should move at all.
That is the real shape of a multi-cloud data migration. It is less about servers and more about data mechanics. How do bytes travel, how do changes keep flowing during the move, and how do you prove the target is right? And when should data stay where it is?
This guide covers strategy, approaches, a step-by-step cutover plan, tools, cost, challenges and a decision framework you can apply to your own estate.
What Multi-Cloud Data Migration Is
Multi-cloud data migration moves datasets, their pipelines and their consumers from one cloud provider to another. It also covers consolidation, where data spread across two or three providers is pulled into one governed home. In practice, the unit of work is the data product, not the virtual machine.
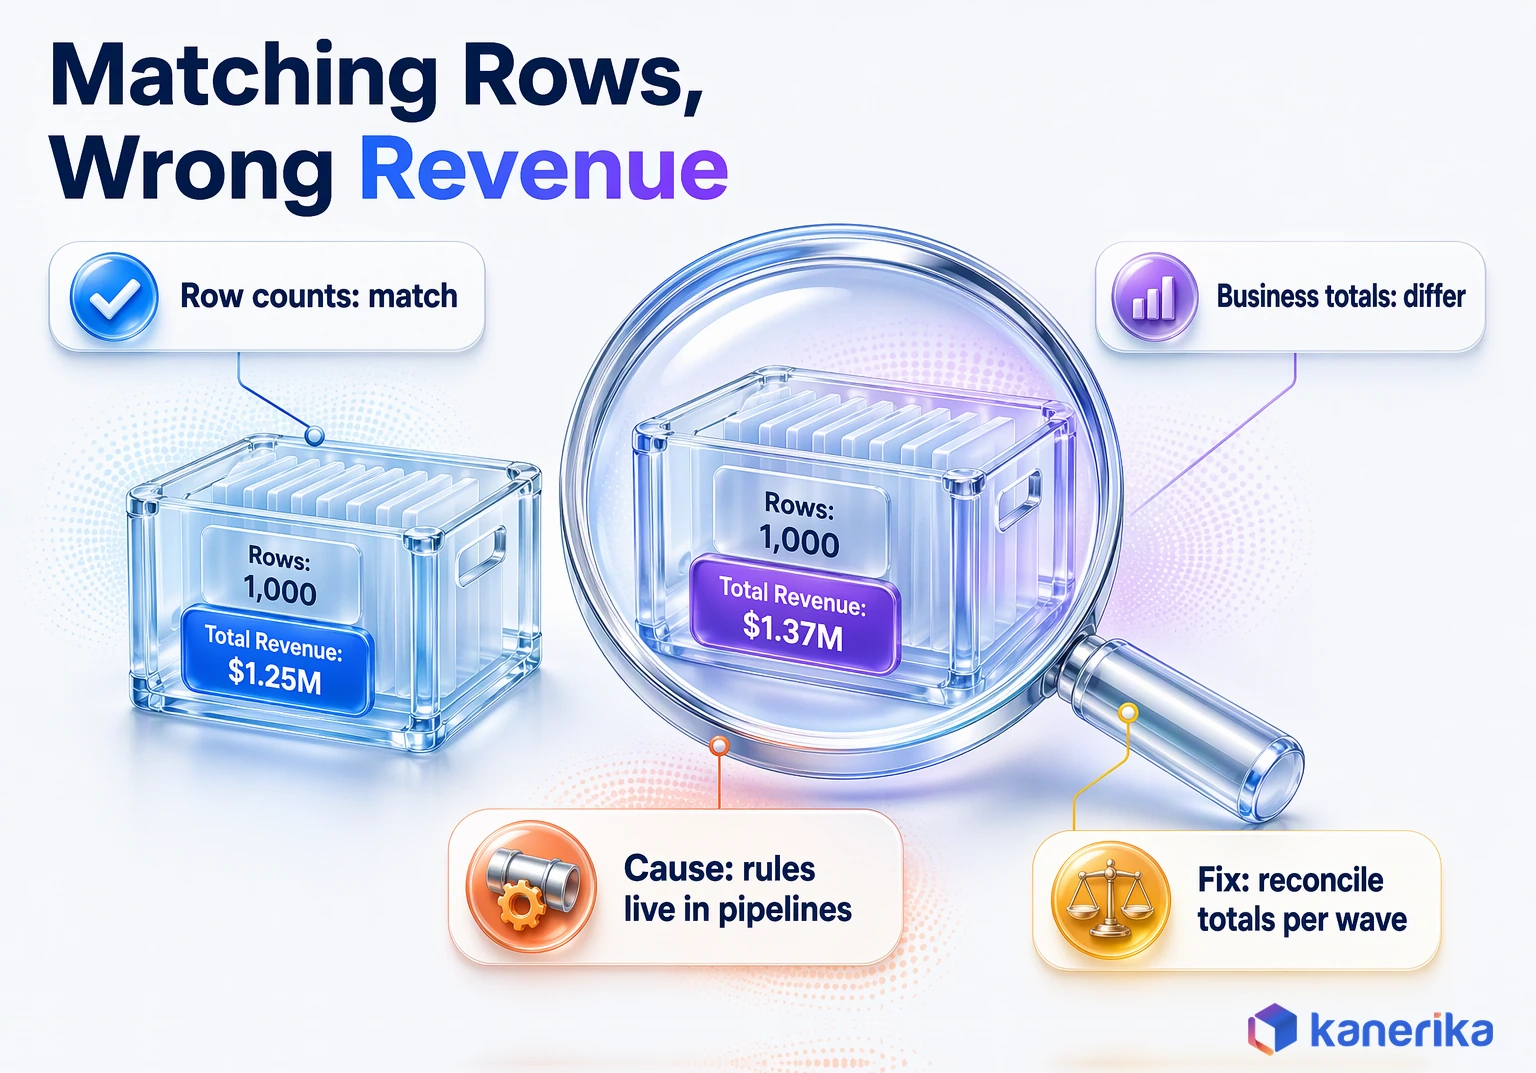
That distinction matters because application re-hosting and data migration fail in different ways. For example, a re-hosted app either starts or it does not. A migrated table can load without errors and still return a different revenue total. Somewhere on the way, a date type or a rounding rule changed.
For the server and application side, see our guide to cloud migration best practices; for the general discipline, start with what data migration involves.
Migrate, Replicate or Federate: Three Different Decisions
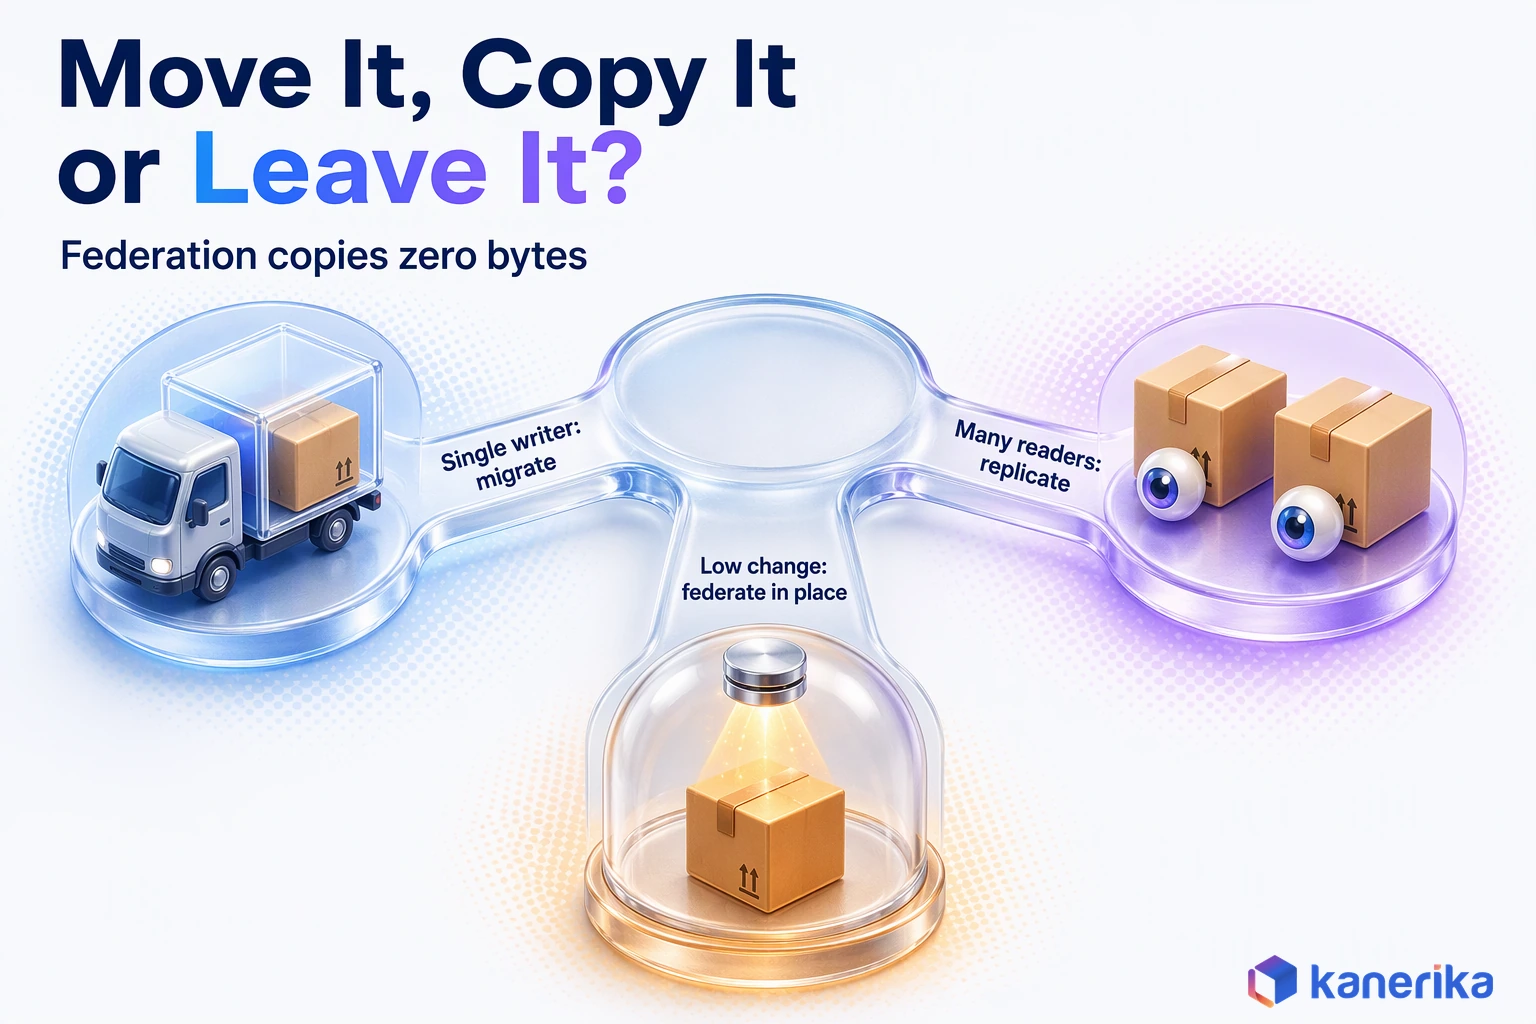
Not every cross-cloud data problem needs a migration. Some data should move once, some should be copied and kept in sync, and some should stay put while another platform reads it in place. Treating all three as “migration” is how teams end up paying egress to copy data that nobody needed to own twice.
| Option | What moves | When it fits | Main risk |
|---|---|---|---|
| Migrate | Data, pipelines and consumers move, then the source is retired | Exiting a provider, consolidating after a merger, one system of record | Cutover errors and a long parallel run |
| Replicate | A copy is kept in sync on a second cloud | Read-heavy analytics or disaster recovery on another provider | Ongoing egress and two copies that drift apart |
| Federate | Nothing moves; the target platform queries data in place | Low-change data read by another cloud’s analytics tools | Query latency and dependence on the source provider |
Federation became practical once analytics platforms learned to read other clouds’ storage directly. Microsoft Fabric, for example, supports OneLake shortcuts to Amazon S3, S3-compatible storage, Azure Data Lake Storage Gen2, Azure Blob Storage and Google Cloud Storage. The data stays where it is. A shortcut is not free, since reads still cross a network, but it removes a copy you would otherwise have to govern.
Multi-Cloud vs Hybrid vs Single-Cloud Migration
A single-cloud migration moves data from on-premises systems, or from one region, into one provider. The target is uniform, so tools, identity and encryption follow one model from start to finish.
A hybrid migration instead keeps part of the estate on premises or in a private cloud and connects it to a public cloud. The hard parts then become network links, latency and keeping two security models aligned over the long term.
A multi-cloud migration spans two or more public providers. Every control you take for granted inside one cloud, such as identity, key management and lineage, now has to work across a boundary. That is why the governance and validation work is heavier here than in either of the other two patterns.
Why Enterprises Move Data Between Clouds in 2026
Most large companies already run on more than one cloud, and the reasons are rarely a grand design. Flexera’s 2026 State of the Cloud report, published on March 18, 2026, surveyed 753 cloud decision-makers. It found that 88% of organizations use multi-cloud and 73% use hybrid cloud. Flexera also noted that multi-cloud often grows unintentionally, through mergers, siloed teams and inherited architecture, as its 2026 report summary explains.
Unplanned sprawl is what usually triggers a data move. A company that bought its way into three clouds wants one governed copy of customers, products and finance. AI makes that urgent, because models pull data toward the platform where the GPUs and governance tools live. The insurer from the opening, for example, needs its S3 policy data next to its churn models on Google Cloud before the AI rollout. So the second wave of multi-cloud work is often consolidation rather than expansion.
Exit Fees and the EU Data Act
The economics of leaving a provider changed in 2024. Google Cloud announced on January 11, 2024 that it eliminated data transfer fees for customers migrating off Google Cloud, for all customers globally. AWS followed on March 5, 2024 with free data transfer out to the internet when moving off AWS, requested through AWS Support. On September 30, 2025, it removed the earlier 100 GB per month threshold for contacting Support.
Microsoft announced a similar waiver for customers leaving Azure on March 13, 2024. You request it through Azure Support with your subscription ID and estimated volume. It covers data transfer out over the internet, and the credit lands after you cancel all subscriptions on the account.
Regulation also points the same way in Europe. The EU Data Act has applied since September 12, 2025, and it removes switching charges, egress included, from January 12, 2027. Until then, providers may charge only reduced, at-cost fees for switching. For the wider set of forces shaping these projects, see our roundup of data migration trends.
Benefits and Their Trade-Offs
The benefits are real, but each one carries a trade-off you should name up front:
- Cost control: moving data to the cheapest fit for each workload saves money, but only if you count dual running and egress honestly.
- Resilience: a second provider limits the blast radius of an outage, at the price of two operating models.
- Residency: regional choice helps meet data residency rules, but every new region adds a transfer rule to track.
- Bargaining power: a credible exit path improves contract talks, yet it only counts if your data is portable.
Still, which provider should own which workload is a separate question, and our AWS vs Azure vs Google Cloud comparison covers it in depth. The rest of this guide assumes that choice is made and focuses on moving the data safely.
On-Demand Webinar
Cloud Migration Strategies: Accelerate Your Business Outcomes
A Kanerika solutions architect walks through cloud migration strategies, common challenges and how to plan a move that keeps the business running.
Watch the Webinar →Choosing a Multi-Cloud Data Migration Approach
The right approach depends on three things: how much data you have, how fast it changes, and how much downtime the business will accept. For example, a static archive and a live order system on the same estate should never share one approach. Most real programs mix two or three patterns, one per workload group.
| Approach | Downtime | Data volume fit | Complexity | Cost driver | Pick it when |
|---|---|---|---|---|---|
| Bulk one-time copy | Hours to days, unless the data is static | Any size of cold or archive data | Low | Egress and transfer time | Data no longer changes, such as archives and closed periods |
| Bulk plus change data capture (CDC) | Minutes, during a short write freeze | Large, live databases | Medium to high | Replication compute and lag monitoring | The source keeps taking writes during the move |
| Phased by data domain | Low per wave | Large estates with many consumers | High coordination | Parallel running across waves | Dozens of teams and reports depend on the data |
| Rebuild or refactor on the target platform | Planned per pipeline | Pipelines and models, not raw storage | High | Engineering effort and testing | The target engine differs and old pipelines would carry debt |
| Federate in place | None | Low-change data read occasionally | Low | Read traffic and query latency | Another cloud only needs to read the data, not own it |
The 7 Rs Applied to Data
AWS’s prescriptive guidance groups migration choices into seven strategies, the 7 Rs, and they map neatly onto data. You retire datasets nobody reads and retain those that must stay on the source cloud. Then you rehost storage as-is, relocate whole environments, and repurchase where a managed service replaces a self-run one. Replatform moves data to a new managed engine with light changes, while refactor rebuilds pipelines and models for the target.
In most multi-cloud estates, retire and retain decisions cut the scope before a single transfer job runs.
If the bigger question is which data platform to land on, our data platform migration decision framework scores the options. This section therefore assumes the target is chosen and asks only how the data gets there.
Datasheet
FLIP Migration Accelerators for Faster Data Platform Migration
When the approach is replatform or refactor, FLIP automates the conversion of pipelines and reports to the target platform, cutting manual rebuild effort.
View the Datasheet →Step-by-Step Multi-Cloud Data Migration Plan
A cross-cloud move succeeds or fails on sequence. Each step below produces something the next step needs, so skipping one usually shows up later as a failed cutover. The plan also assumes a live estate with both static and changing data.
Prepare the Move: Steps 1 to 4
- Inventory data, consumers and dependencies. List every dataset with its size, change rate, owner and the pipelines, reports and models that read it. Group tables that must move together into waves, because a report that reads two clouds at once during a move is where errors hide.
- Write the migration contract. Agree success criteria, allowed downtime and the consistency target for each wave before any data moves. A finance ledger might need exact totals and a 30-minute freeze, while a clickstream archive can tolerate a day of lag.
- Prepare the target landing zone. Set up networking, identity federation, customer-managed keys and storage layout on the target cloud. Map where each regulated dataset is allowed to live before anything is copied.
- Pilot on representative data. Move one wave that includes awkward types, large tables and a few real reports. Measure throughput, lag and validation results, then fix the plan rather than the data.
Move, Cut Over and Retire: Steps 5 to 8
The second half of the plan is where data actually moves and consumers switch platforms.
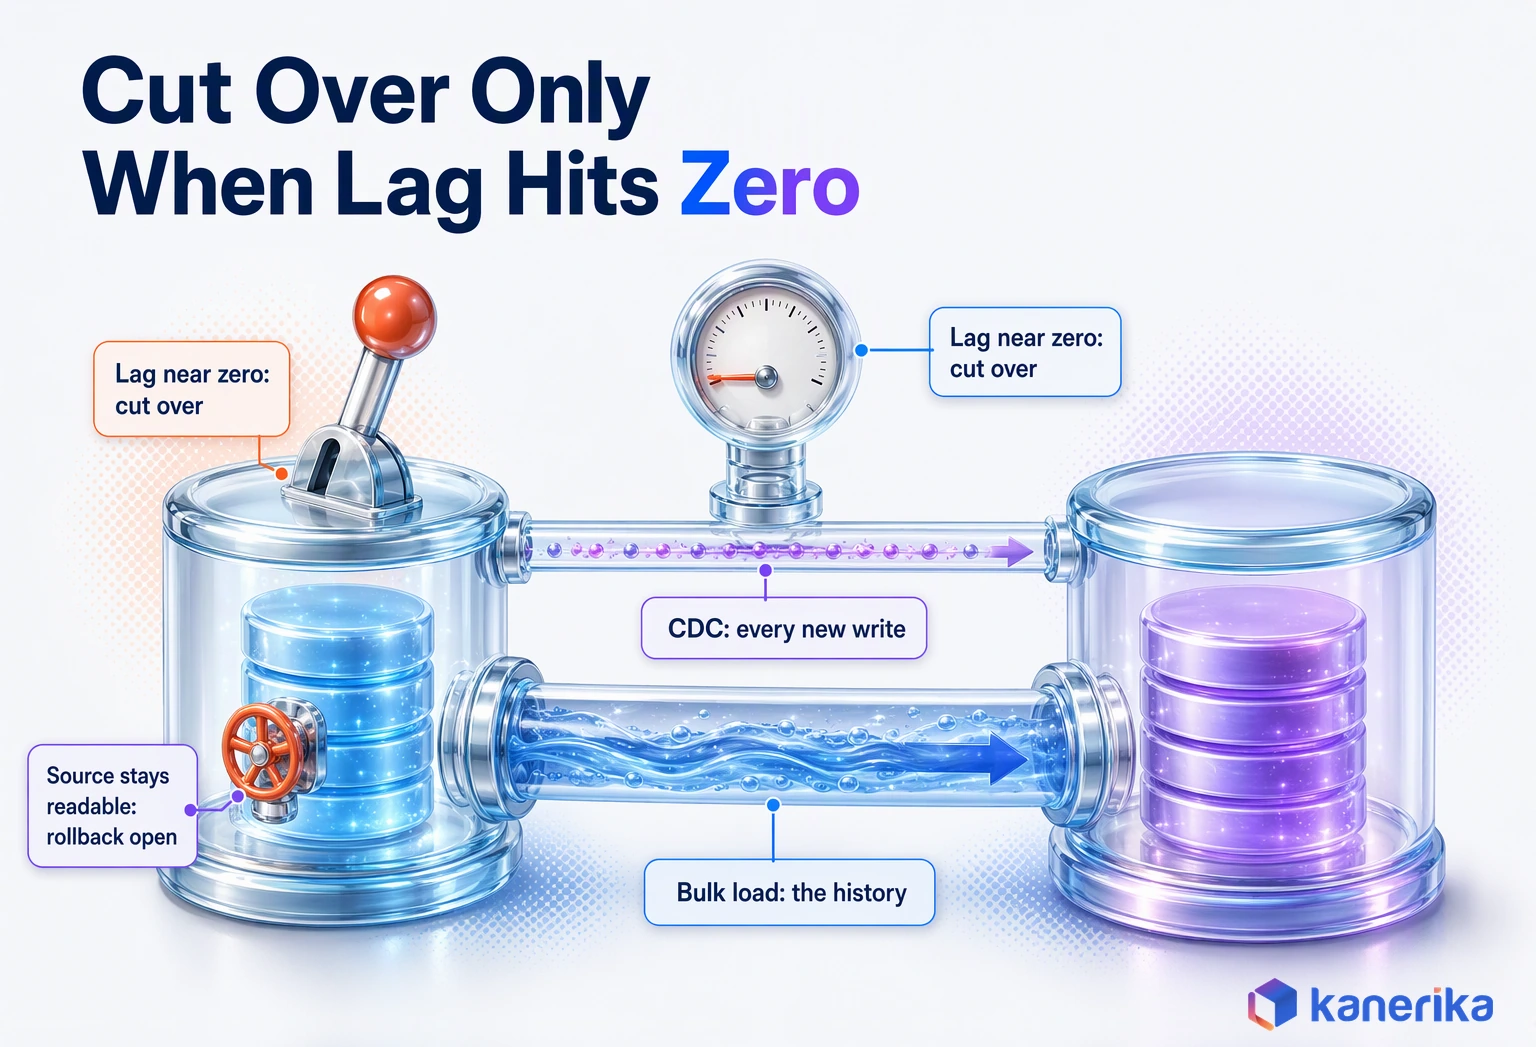
- Bulk load with checkpoints. Copy historical data in restartable chunks, recording what has landed so a failure resumes instead of restarting. Run checksums per chunk as you go.
- Catch up with CDC and watch the lag. Start change data capture from a known point so writes made during the bulk load reach the target. Track replication lag as a business metric, since cutover is only safe once lag stays near zero.
- Reconcile and cut over by wave. Run the validation suite, freeze writes briefly, apply the last changes and repoint consumers for one wave at a time. Keep the source readable so the rollback path stays open.
- Stabilize, then decommission. Watch the new platform through at least one full business cycle, such as a month-end close. Retire source storage and pipelines only after that, and capture the exit waiver or cost savings you planned.
Steps five and six are where most of the calendar time goes. Teams that script them, along with the checks in step seven, cut weeks from each wave. That is why automation in data migration pays back fastest on cross-cloud work.
One more habit separates smooth programs from painful ones: a short written log per wave. It records what moved, what failed, which checks passed and who signed off. The next wave then starts from that record instead of from memory, and the auditors get their evidence for free.
Validate More Than Row Counts
Row counts are the first check, never the last. A table can carry exactly the right number of rows and still be wrong. Perhaps a timestamp lost its time zone, or a different engine rounded a decimal column. So validation has to prove the data means the same thing on the target.
| Check | What it proves | Example |
|---|---|---|
| Row counts | Nothing was dropped or duplicated in bulk | Orders table has the same count per day on both sides |
| Checksums or hashes | Values arrived byte-for-byte | Hash of each partition matches source and target |
| Schema and data types | Engines did not silently convert types | Decimal precision and time zones survive the move |
| Null and key rules | Integrity rules still hold | No orphan order lines without a customer |
| Business totals | The numbers the business uses still agree | Monthly revenue and open receivables match to the cent |
| Report parity | Consumers see the same answer | The top 20 dashboards return identical figures |
| Permissions | Access rules moved with the data | A sales user cannot see payroll tables on the new cloud |
Set a tolerance for each check before you run it. Counts and keys should match exactly, while a floating-point average may differ in the last decimal place because engines round differently. Writing the tolerance into the migration contract stops a debate about whether a small difference is a defect.
Run the same suite in the pilot, after the bulk load and again just before cutover. For deeper patterns on profiling and quality rules, see our guide on how to ensure data quality during data migration.
Checklist
Data Migration Checklist for Enterprise Teams
A step-by-step checklist for scoping, validating and cutting over a data migration, including the reconciliation checks that go beyond row counts.
Get the Checklist →Cutover and Rollback Design
Every cutover has a point of no safe return: the moment new writes land only on the target. Before that point, rolling back means repointing consumers to the source. After it, rolling back means copying new data back, which is slow and risky. Good plans therefore make that point late and visible.
So design the window around it. A short write freeze lets CDC drain the last changes, and a dual-run period lets both platforms answer the same queries while you compare results. The rollback decision should be mechanical, written down before the weekend starts, not argued at 2 a.m.
- Replication lag stays above the agreed limit at the end of the freeze window.
- Business totals or report parity checks fail on any critical dataset.
- Error rates or latency for consuming applications pass a set threshold.
- A permission check exposes restricted data on the target.
If any trigger fires, the team then rolls back without a meeting. That one rule removes most of the pressure from cutover night.
Tools for Moving Data Across Clouds
Each major provider ships a service that pulls data from its rivals, because each one wants to be your destination. So the inbound tools are cheap or free and well documented. The right category depends on whether you move files, live databases or nothing at all.
| Category | Examples | Best for | Watch-outs |
|---|---|---|---|
| Native object and file transfer | AWS DataSync, Google Storage Transfer Service, AzCopy | Bulk copies of files and objects between providers | Egress on the source side and request charges |
| Database replication and CDC | AWS Database Migration Service ongoing replication | Live databases that keep taking writes | Type mapping, lag and supported source versions |
| Federation | OneLake shortcuts in Microsoft Fabric | Reading data in place from another cloud | Read latency and reliance on source availability |
| Offline transfer devices | Provider shipping appliances | Very large estates on thin network links | Shipping time and chain-of-custody controls |
| Validation and reconciliation | Scripted checks or a migration accelerator | Proving totals, types and parity at scale | Scripts that only count rows |
The right native tool depends on where the data is going, since each one lands data in its own cloud. Moving into AWS, AWS DataSync transfers data with Google Cloud Storage, Azure Blob Storage and Azure Files. For Google Cloud, Storage Transfer Service accepts Amazon S3, S3-compatible storage and Azure Blob Storage as sources.
For Azure, Microsoft’s AzCopy copies objects from Amazon S3 to Azure Storage server to server with the Put Block From URL API. So the data does not flow through your own machine’s bandwidth.
Kanerika Service
Data Migration Services
Kanerika plans and runs data migrations between cloud providers, with dependency-mapped waves, change data capture and automated reconciliation before every cutover.
Explore Migration ServicesDatabases need a different tool, since files cannot keep a live system in sync. AWS DMS supports ongoing replication through change data capture tasks, which is the pattern step six depends on. Test your choice in the pilot with real types and volumes, since vendor throughput numbers rarely match messy production data.
How to Choose Between Native Tools
A simple rule settles most tool choices. Use the target cloud’s own transfer service when you pull files into it, because it runs inside the destination and reports progress there. Use a replication tool for anything that still takes writes, and try federation before either when the data only needs to be read.
Two practical checks then round out the choice. Confirm in the provider’s own documentation that the tool supports your exact source, including versions and storage tiers. Then decide how a failed job restarts, since a transfer that runs for days should expect at least one interruption. Tools that track completed chunks turn that into a non-event.
Cost and Effort: Egress, Parallel Running and People
Most budget surprises in a cross-cloud move come from the lines nobody priced before the work began. Industry research compiled in Kanerika’s State of Enterprise Data Platform Migrations 2026 report finds 80% of migrations that proceed exceed budget by 150% or more. Egress gets the headlines, yet it is often the easiest line to shrink. Running two platforms in parallel, proving the data is right and paying the people who do it usually cost more.
| Cost line | What drives it | How to reduce it |
|---|---|---|
| Egress and transfer | Volume leaving the source cloud | Retire unused data first, compress, and request the exit waiver |
| Request and API charges | Millions of small objects | Bundle small files before transfer |
| Target storage and compute | Landing, staging and transformation jobs | Size staging for the wave, not the whole estate |
| Dual running | Both platforms live during parallel run | Shorter waves and a clear decommission date |
| Validation | Reconciliation runs and report comparisons | Automate the suite and reuse it per wave |
| People | Engineers, testers and business sign-off time | Fixed migration contract and fewer reruns |
The exit waivers also have a narrow scope. They apply when you leave a provider, under that provider’s conditions. They do not cover the steady stream of data you send between clouds every day in a multi-cloud setup.
If you replicate or federate across providers for the long term, that traffic is a running cost. It belongs in your cloud cost management plan.
Worked Example: Moving a 100 TB Analytics Estate
The numbers below are illustrative. Every input is an assumption chosen to show the method, so price your own move with each provider’s calculator and current rates.
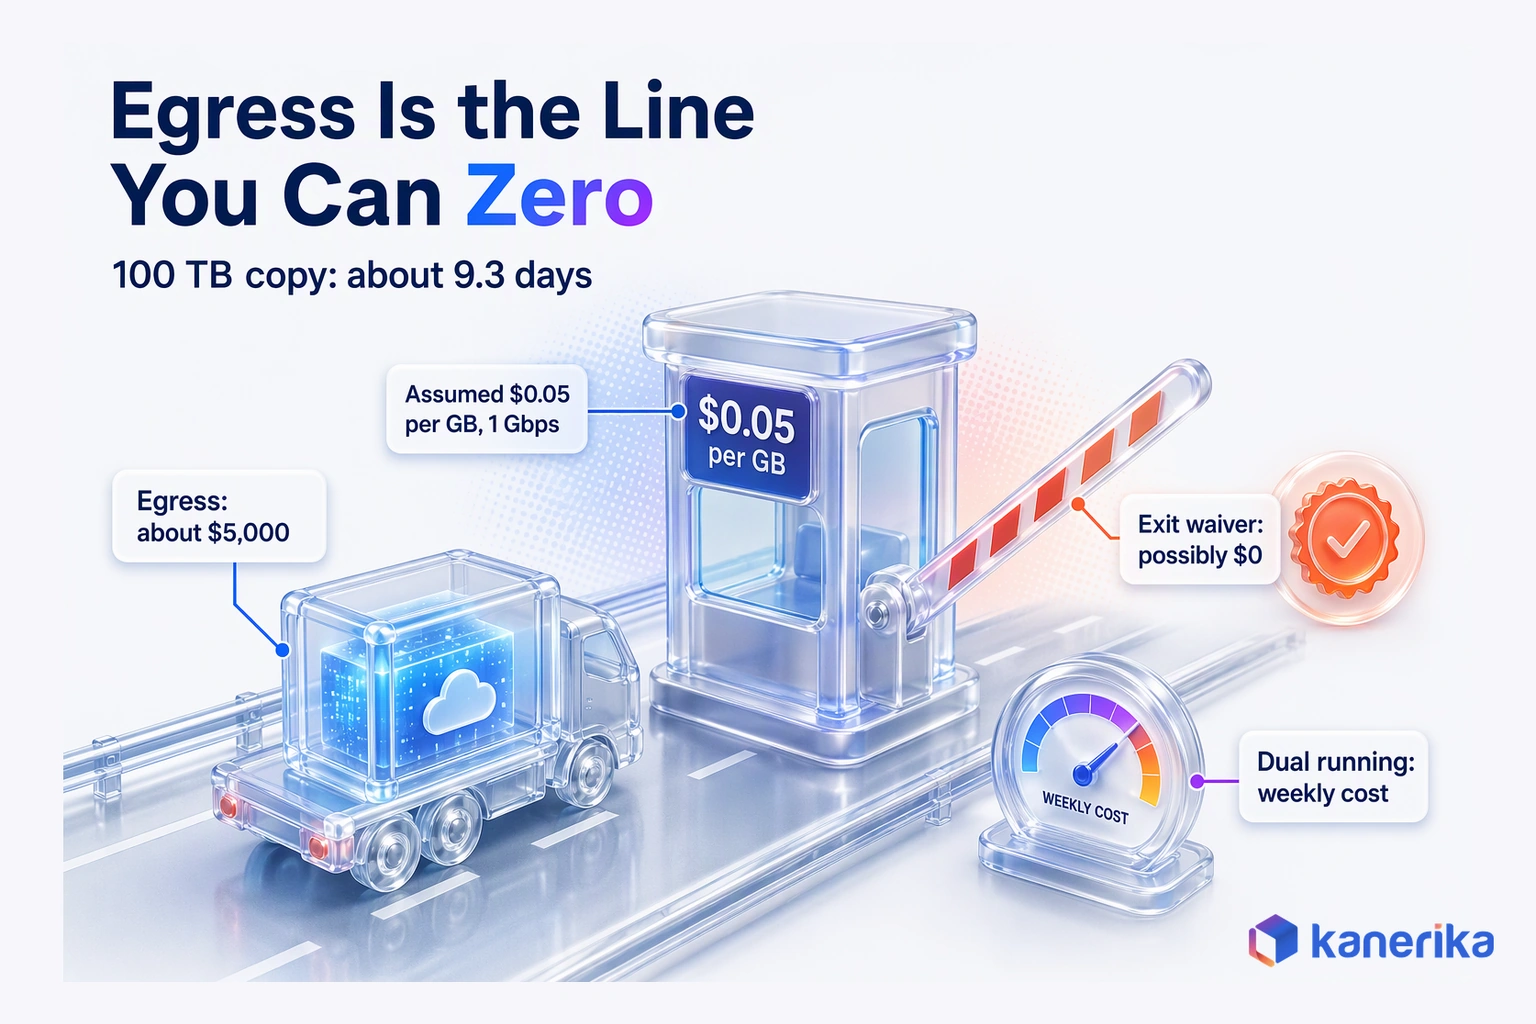
- Assume the estate: 100 TB of historical data, 1 TB of changed data per day, and 1 Gbps of effective throughput between clouds.
- Bulk copy time: 100 TB is 800,000 gigabits, so at 1 Gbps the copy takes 800,000 seconds, or about 9.3 days.
- Daily catch-up: 1 TB is 8,000 gigabits, which takes about 2.2 hours at the same rate, so CDC can keep up comfortably.
- Egress: at an assumed blended $0.05 per GB (list rates start higher and step down with volume), 100,000 GB of bulk data costs about $5,000 to move out.
| Item | Assumption | Result |
|---|---|---|
| Bulk transfer time | 100 TB at 1 Gbps effective | About 9.3 days |
| Daily change transfer | 1 TB per day at 1 Gbps | About 2.2 hours per day |
| Bulk egress | Assumed blended $0.05 per GB, 100,000 GB | About $5,000, possibly $0 with an exit waiver |
That $5,000 also excludes request charges, target compute, weeks of dual running and the people who validate the result. It could also fall to zero if the source provider’s exit waiver applies to your move. So the example makes the practical point clearly: plan around time and effort, then treat egress as the line you negotiate.
Migration ROI Calculator
What Would Your Cross-Cloud Move Cost and Return?
Estimate the savings and payback of your migration from your own data volumes, platforms and team size before you commit to a plan.
Calculate Migration ROI →Effort and Timeline Beyond the Transfer
Of course, transfer time is the easy part to estimate. In the example the bulk copy takes under two weeks. The full program runs longer, though, because of pilots, validation cycles and the stabilization period in step eight. Waiting for one month-end close can add up to a month of parallel running if finance data is in the wave.
Plan people time per wave instead of for the whole estate. Each wave needs a data owner to sign off totals, engineers to run transfers and CDC, and testers to compare reports. When the migration contract names those roles, waves stop waiting on approvals and dual running ends on the date you set.
Budget follows the waves as well. A first wave that finishes on time is the best evidence for the plan. So pick a pilot wave that is real but not the most critical system. Later waves reuse its runbook, scripts and validation suite, and each one usually gets cheaper. Automation is the other lever. Kanerika’s State of Enterprise Data Platform Migrations 2026 report says FLIP automates 60 to 85% of migration work (Kanerika-reported), against under 20% in industry research.
Challenges of Multi-Cloud Data Migration and How to Handle Them
Cross-cloud moves inherit every normal migration risk and also add a few of their own. The table pairs each challenge with what typically goes wrong and the control that prevents it. None of these controls is exotic, yet teams skip them under schedule pressure. Industry research compiled in Kanerika’s State of Enterprise Data Platform Migrations 2026 report finds platform-specific inexperience a factor in 42% of failed migrations.
| Challenge | What goes wrong | Control |
|---|---|---|
| Data gravity and egress | Large datasets are slow and costly to move, so teams copy everything anyway | Retire first, federate low-change data, request exit waivers |
| Schema and type drift between engines | Decimals, dates and strings change meaning on the new engine | Type mapping in the pilot, plus checksum and total checks |
| Continuous inflow during cutover | Writes made during the move never reach the target | CDC from a known point, lag monitoring, short write freeze |
| Identity and key management | Access rules or encryption keys do not carry across providers | Identity federation and customer-managed keys per cloud |
| Residency and transfer rules | Regulated data lands in a region it may not enter | A residency map signed off before the first transfer |
| Skills gap and tool sprawl | Each team brings its own scripts and nobody owns the whole | One runbook, one validation suite, named wave owners |
| Cost visibility | Dual running and transfer charges appear after the fact | Tag migration resources and review spend each wave |
The Two Challenges That Sink Most Projects
Most of the table can be fixed late; these two cannot, because by the time they show up the source has moved on.
The first is continuous inflow. A live system keeps taking orders, payments and updates while you copy it. A bulk load that ignores them ends with a target that is stale on day one. CDC solves it, but only if you start capture from a known point and treat lag as something the business signs off.
The second is business-rule reconciliation. Large estates carry thousands of context-specific rules, such as how a refund nets against an invoice or which currency rate applies on which date. Those rules live in pipelines and reports, not in the data, so a perfect byte copy can still produce wrong totals.
The fix is to validate the outputs the business uses, rule by rule. That is exactly the pattern in the case study later in this guide.
Both failures share one root: the team measured the move by bytes landed rather than by answers matched. Fix that metric, and most of the other controls in the table follow naturally.
Governance, Security and Data Residency Across Clouds
Governance is where a multi-cloud estate either becomes manageable or stays three separate estates with a shared bill. The goal is simple to state: one set of rules that follows the data, whichever provider stores it.
Identity comes first, before keys or catalogs. Federate your corporate identity provider into each cloud so people and services keep one identity, with roles mapped consistently. Encryption follows, with customer-managed keys held in each provider’s key service, so you control rotation and revocation on every side of the move.
Network design belongs in the same conversation. Private connections between clouds keep transfer traffic off the public internet and make throughput more predictable, which matters when a bulk copy runs for days. Decide early whether each wave travels over a private link or encrypted public endpoints, because that choice shapes both cost and security reviews.
Then make the data itself traceable. A single catalog and lineage view across clouds shows where each dataset came from and who reads it. Classification labels such as “personal data” or “payment data” should travel with the data, so access rules apply on arrival rather than weeks later. Our guide to enterprise data governance covers the operating model behind this.
Residency and Ownership During the Move
Residency needs its own map, drawn before the first byte moves. List each regulated dataset, the regions it may live in and the transfers it may make. For EU data, the Data Act’s switching rules make leaving a provider cheaper from January 12, 2027. They do not change where personal data is allowed to go.
Ownership during the move needs the same clarity. For each wave, name who approves access on the target, who rotates keys after cutover and who signs the residency map. Those three names prevent the most common governance gap, where the old cloud’s rules lapse before the new cloud’s rules are live.
- One identity per person and service, federated into every cloud.
- Customer-managed keys in each provider, with a rotation owner named.
- One catalog and lineage view that spans all providers.
- Classification labels that move with the data.
- A signed residency map before any transfer job runs.
Talk to Kanerika
Mapping Identity, Keys and Residency Across Clouds?
Kanerika reviews one migration wave with your team, from the residency map and key ownership to the CDC plan and rollback triggers, and shows where the risk sits.
Schedule a Demo →Decision Framework: Migrate, Replicate or Leave Data in Place
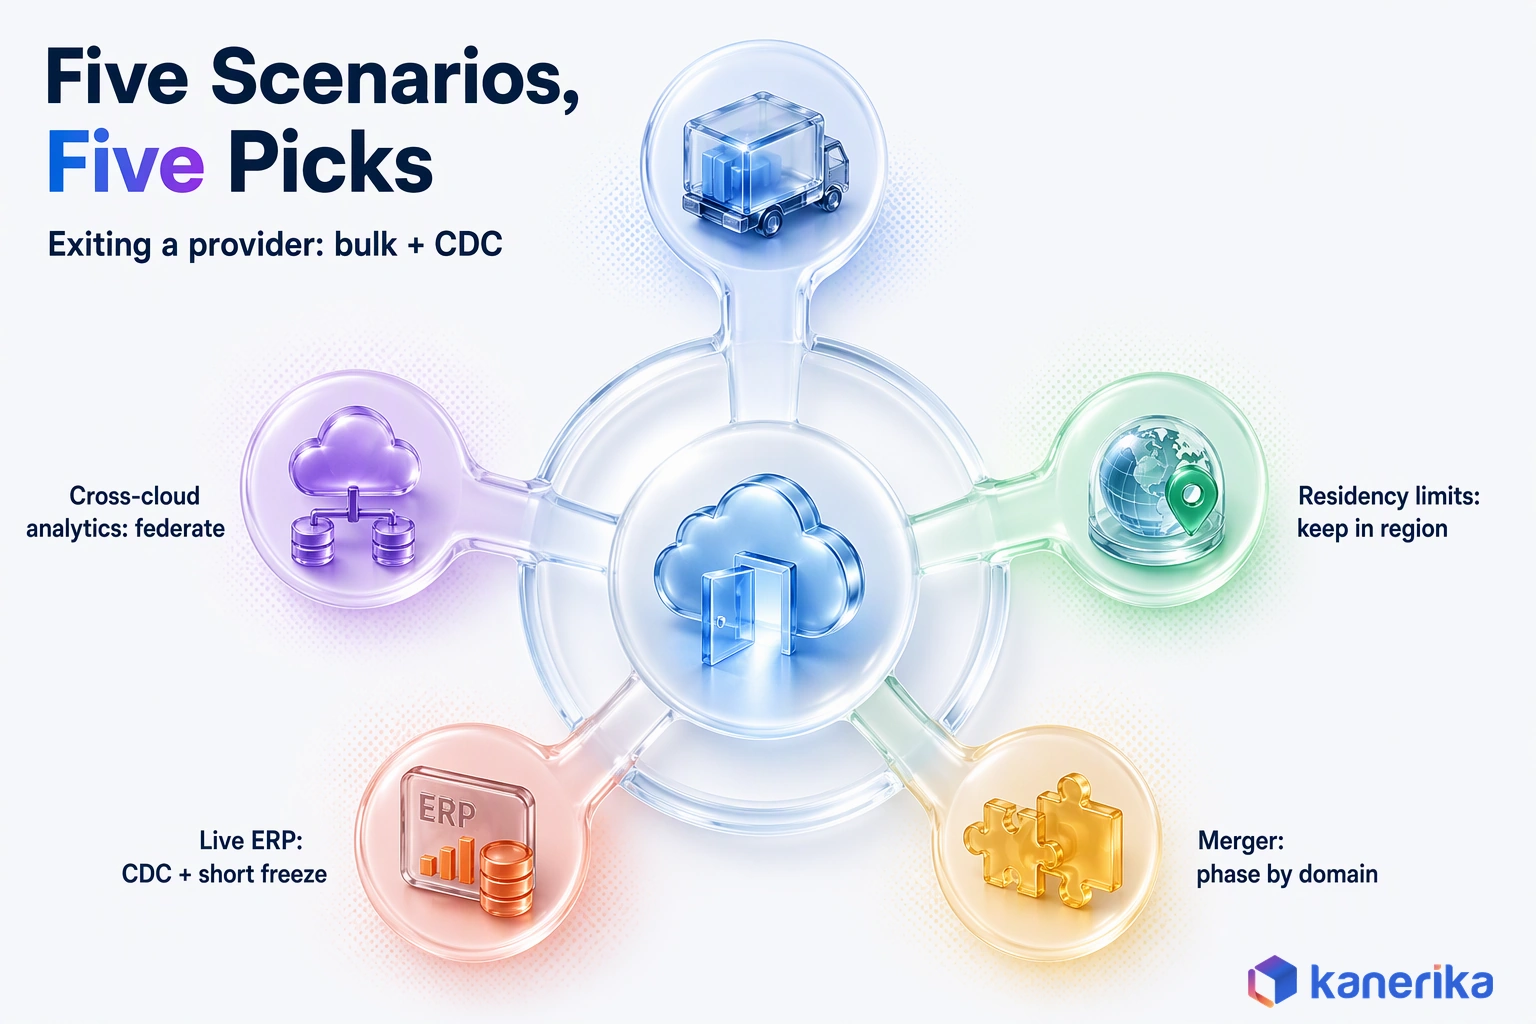
A strategy is only useful when it tells you what to do on Monday. The table below gives one pick per common scenario, with the reason and the mistake to avoid. Use it to sort your workloads into waves before you choose tools.
| Scenario | Pick | Why | Avoid |
|---|---|---|---|
| Exiting a provider at contract end | Bulk copy plus CDC, with the exit waiver requested | History moves in bulk, CDC keeps it current, and the waiver can remove egress | Starting transfers before the waiver request is approved |
| Analytics needs data from another cloud, low change | Federate in place through shortcuts | No copy to govern and no bulk egress | Nightly full copies of data that changes monthly |
| Regulated data with residency limits | Keep it in region and replicate a masked subset | Analytics gets what it needs without moving restricted fields | Copying full tables “for now” |
| ERP or OLTP system with continuous writes | CDC with a short write freeze | Keeps the source live until the last minute | A big-bang weekend copy with no catch-up |
| Post-merger consolidation | Phased migration by data domain | Each domain cuts over with its own consumers and sign-off | Moving all domains in one wave |
The ERP row deserves extra care, because order, inventory and finance tables change every minute and feed many downstream systems. Our guide to manufacturing data migration walks through that pattern for plant and ERP data.
Notice also that “leave it in place” wins two of the five rows. Federation and in-region replication are real strategy choices, not a failure to migrate. A plan that moves less data is usually faster, cheaper and easier to govern.
How Kanerika Runs Multi-Cloud Data Migrations
Kanerika runs cross-cloud moves as a staged program, where each stage ends with evidence the client can check. Our data migration services follow four stages:
- Assess and map dependencies. We inventory datasets, pipelines and consumers, then group them into waves by dependency and risk.
- Design the target. Identity federation, key management and the residency map are agreed before any transfer starts.
- Pilot and run in parallel. Automated reconciliation compares business totals and reports between source and target on every run.
- Cut over by wave and decommission. Consumers move one wave at a time against written rollback triggers, then the source is retired.
One engagement, for example, shows the pattern well. The client is a global leader in spend management, running freight and parcel audit across North America, Latin America, Asia and Europe. It operated a Legacy platform and a Modern platform side by side.
The company wanted one new cloud-native platform built on multi-node distributed databases, without disrupting its customers.
The challenges were the ones this guide warns about: voluminous, context-specific business rules and data that kept flowing in while the migration ran. Kanerika preserved functionality and data integrity, kept the inflow synchronized, and validated both data and business rules through reconciliation before the old platforms were sunset.
Error resolution time fell 60% and infrastructure cost fell 32%. Application performance improved 46%, with a 20% efficiency gain, as the cross-cloud migration case study details.
Logistics and audit estates share these traits, with high transaction volumes and rules that differ by carrier and region. Our guide to data migration in transportation and logistics covers that sector in more depth.
Case Study
60% Faster Error Resolution with Cloud App Migration
A global spend management leader consolidated Legacy and Modern platforms onto one cloud-native platform, with reconciliation-validated data and business rules, cutting error resolution time 60% and infrastructure cost 32%.
Read the Case Study →The Bottom Line
The strategy is clear once you stop treating every dataset the same way. Move live systems with bulk copy plus CDC, and phase large estates by data domain. Validate business outputs rather than row counts. Test federation first, so you only move data that needs a new home.
The challenges are just as predictable: continuous inflow during cutover, business-rule reconciliation, egress you did not plan for, and governance that must hold across providers. Exit waivers and the EU Data Act lower the cost of leaving, but they do not do the validation for you.
Start with the inventory and one real pilot wave. That pilot gives your multi-cloud data migration strategy evidence behind its waves, CDC checks and federate-first test. Then name a control for each of the four challenges and plan the cutover around them before the first byte moves.
Frequently Asked Questions
What is multi-cloud data migration?
Multi-cloud data migration is the process of moving datasets, their pipelines and the reports or models that read them from one cloud provider to another. It also covers consolidating data spread across several providers into one governed home. The work centers on data mechanics such as bulk transfer, change capture, validation and cutover, rather than on re-hosting applications.
What are the 7 Rs of cloud migration?
AWS groups migration choices into seven strategies called the 7 Rs. They are retire, retain, rehost, relocate, repurchase, replatform and refactor. For data, retire removes datasets nobody reads, retain keeps some on the source cloud, and the other five describe how much the data and its pipelines change as they move to the target platform.
How long does it take to move 100 TB between clouds?
At an assumed 1 Gbps of effective throughput, 100 TB takes about 800,000 seconds, or roughly 9.3 days of continuous transfer. A daily change of 1 TB needs about 2.2 hours at the same rate. The full program takes longer because pilots, validation cycles and a stabilization period through at least one month-end close come first.
How do you validate data after a cross-cloud migration?
Start with row counts, then compare checksums per partition, check schema and data types, and test null and key rules. Next, compare business totals such as monthly revenue and confirm that key dashboards return identical figures. Finally, verify permissions so restricted data stays restricted on the new cloud. Run the same suite in every wave.
How do you manage data residency during a multi-cloud migration?
Draw a residency map before any transfer runs. List each regulated dataset, the regions it may live in and the transfers it may make, and have it signed off. Keep restricted data in region and replicate a masked subset for analytics. Classification labels should travel with the data so access rules apply on arrival.
How do you roll back a multi-cloud data migration?
Keep the source readable and writable until the point of no safe return, when new writes land only on the target. Before that point, rollback means repointing consumers to the source. Write the rollback triggers down in advance, such as lag above the limit, failed totals or exposed permissions, so the team acts without debate.
Should you migrate data or federate it in place?
Federate when another cloud only needs to read data that changes rarely, because nothing is copied and there is no second dataset to govern. Migrate when you are exiting a provider, consolidating a system of record or need fast writes on the target. Many programs federate first and migrate only the data that truly needs a new home.
Do cloud providers still charge egress fees when you leave?
Google Cloud, AWS and Azure each announced free data transfer for customers leaving their platform in 2024, with conditions such as contacting support. These waivers cover the exit, not ongoing traffic between clouds. In the EU, the Data Act removes switching charges including egress from January 12, 2027, with reduced at-cost charges allowed before then.
How is multi-cloud different from hybrid cloud and single cloud?
A single-cloud setup runs everything on one public provider. Hybrid cloud connects on-premises or private infrastructure to a public cloud. Multi-cloud spans two or more public providers, so identity, encryption keys, lineage and cost tracking must work across provider boundaries. That boundary is why multi-cloud data moves need heavier governance and validation than the other two patterns.
What is an example of a multi-cloud data migration?
A company runs finance dashboards on Azure, trains machine learning models on Google Cloud and keeps its system of record in Amazon S3. Before an AI rollout, it consolidates customer data into one governed platform. It bulk copies history, uses change data capture for live tables, federates low-change data in place, and retires the leftover copies afterward.
What are the steps in a multi-cloud data migration?
A practical plan has eight steps. Inventory data, consumers and dependencies, then agree success, downtime and consistency targets. Prepare the target landing zone with networking, identity and keys, and pilot on representative data. Bulk load with checkpoints, catch up with change data capture, reconcile and cut over by wave, then stabilize before you decommission the source.
Which tools are used for multi-cloud data migration?
Native transfer services handle files and objects, such as AWS DataSync, Google Storage Transfer Service and AzCopy, which copies Amazon S3 data to Azure Storage server to server. AWS Database Migration Service handles live databases through ongoing replication. OneLake shortcuts in Microsoft Fabric read data in place, and scripted checks or accelerators handle validation and reconciliation.
What types of data migration happen in a multi-cloud move?
Four types usually run together. Storage migration moves files and objects between providers. Database migration moves tables and keeps them in sync with change data capture. Application migration moves the pipelines, reports and services that use the data. Cloud-to-cloud migration ties these together, so each wave moves data and its consumers as one unit.
When should you use CDC instead of a bulk transfer?
Use change data capture when the source keeps taking writes during the move, such as an ERP, order or payment system. A bulk transfer alone copies a snapshot that goes stale at once. The usual pattern is a bulk load of history followed by CDC from a known point, then a short write freeze at cutover.
Can you migrate data between clouds without downtime?
Near-zero downtime is possible for most workloads. Bulk load the history while the source stays live, keep the target current with change data capture, and cut over during a short write freeze once replication lag is near zero. Some systems still need a brief pause, so agree the allowed window in the migration contract beforehand.
How much does multi-cloud data migration cost?
Cost depends on six lines, namely egress, request charges, target storage and compute, dual running, validation and people. In an illustrative 100 TB move at an assumed $0.05 per GB, egress is about $5,000 and may fall to zero under an exit waiver. Parallel running, validation and staff time usually decide the final budget.