TL;DR
Sovereign AI is control over the data, models, compute, access and jurisdiction behind AI, so adopt it for regulated workloads, not every workload. It works by keeping prompts, embeddings, logs and model weights inside an approved boundary, together with customer-held keys and audited operator access. Choose public cloud with regional controls when an internal assistant touches no regulated data. Pick a sovereign cloud or a dedicated managed environment when regulated data must stay under one jurisdiction. Run a customer-operated private deployment, often with open-weight models, when no outside operator may touch the data or the model. Enterprises adopt it one workload at a time: classify the data, choose the least costly model that meets its controls, then test the exit.
Key Takeaways
- Sovereign AI means control over the data, model, compute, operator access and legal jurisdiction of an AI workload, rather than just where data is stored.
- Countries use the term for domestic AI capacity, while enterprises use it to decide which workloads need stronger control.
- Prompts, logs, embeddings, fine-tuning sets and agent tool calls are the usual paths by which AI data leaves an approved boundary, so each one needs a control.
- Five deployment models run from public cloud with regional controls to customer-operated private AI, and each one trades cost for control.
- Choose the least costly model that meets a workload’s mandatory controls, then prove it with location checks, access reviews and a tested exit.
- No single law covers the topic, so GDPR, the EU AI Act, the CLOUD Act, HIPAA and NIST guidance together shape the requirements.
Why Sovereign AI Is Now an Enterprise Question
The Clinical Assistant That Sent Patient Notes Abroad
Picture a US health system that rolls out an AI assistant for its clinicians. It summarizes discharge notes, drafts referral letters and answers policy questions. The pilot goes well, so usage climbs fast.
Then the privacy office reviews the vendor’s architecture. Prompts, completions and debug logs flow to a model endpoint the vendor runs in another jurisdiction, where support engineers can open the logs. Nobody approved that path, because the contract only covered where the main database lived.
No breach happened. Even so, the team could not prove who could read patient text. Nor could it say which country’s law applied, or how to move the workload if the vendor changed its terms.
That gap is what sovereign AI is meant to close. This guide explains what the term means for countries and for enterprises, as well as how a sovereign architecture works. It then compares five deployment models and shows how to pick one per workload. A worked healthcare example, the relevant regulations and a pre-production checklist follow.
What Is Sovereign AI?
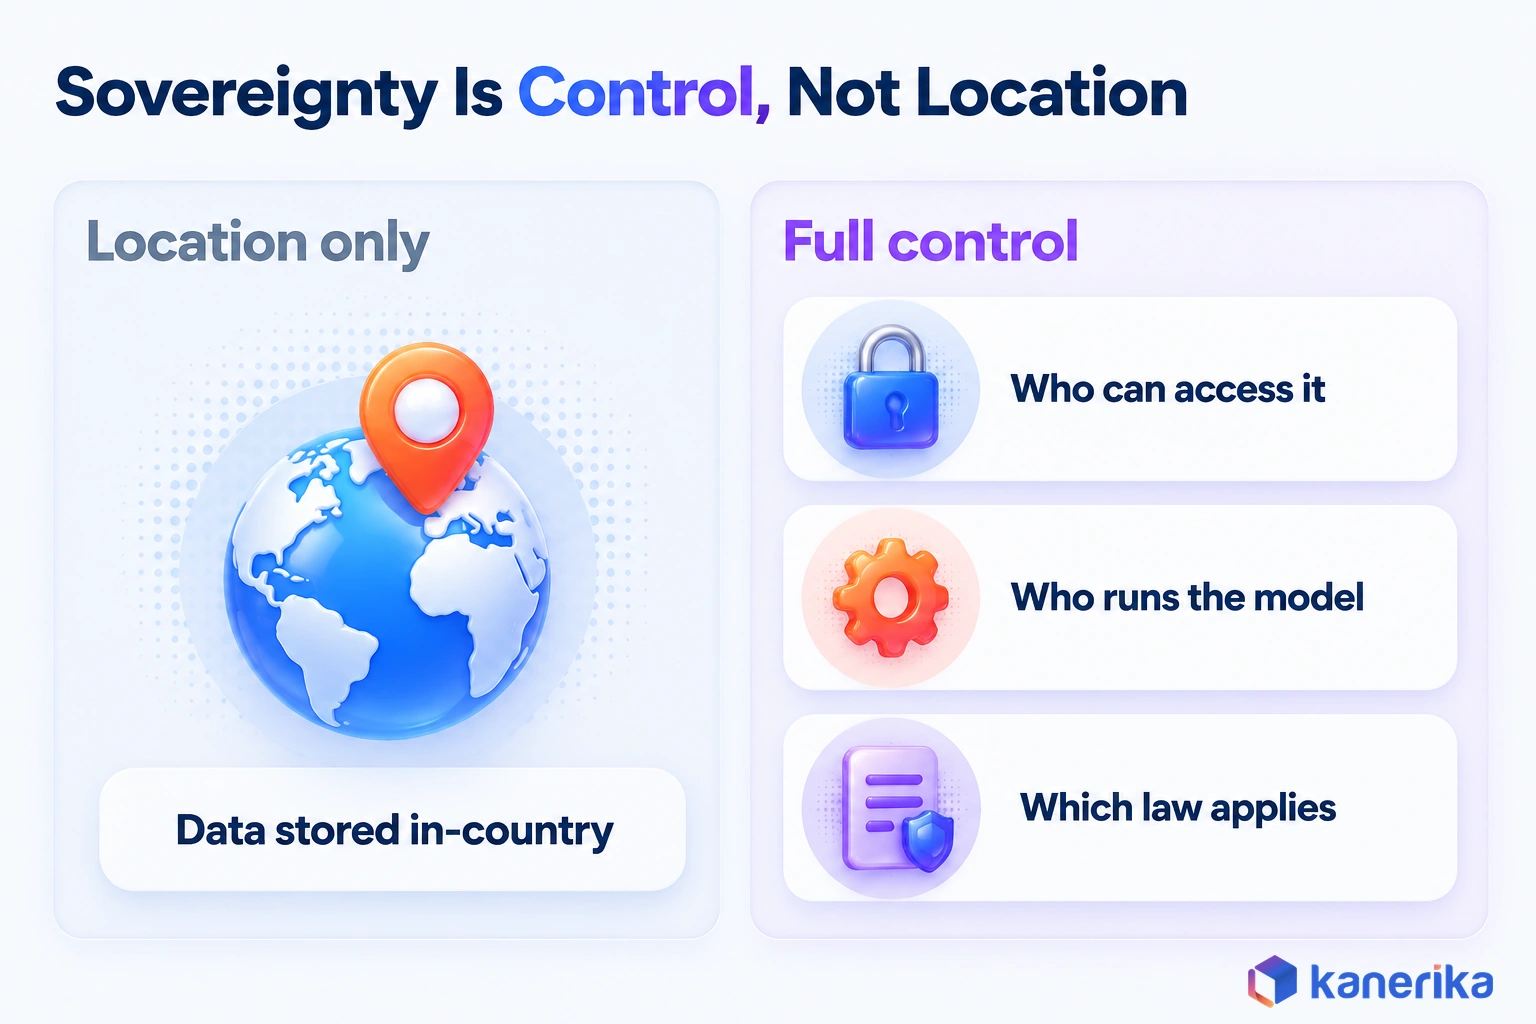
Sovereign AI is the ability to decide who controls an AI system and under which rules it runs. The phrase carries two meanings, one national and one enterprise, and they overlap more than they differ.
NVIDIA’s version is national, and it stresses a fit with each country’s language, culture and regulations. It defines the idea as countries “building and running artificial intelligence using national infrastructure, data, talent and business networks.”
NVIDIA founder Jensen Huang also pushed the idea into the mainstream at the 2024 World Governments Summit in Dubai. There he argued that every country must own the production of its own intelligence, which he called sovereign artificial intelligence.
For enterprise AI programs, however, the question is narrower and more practical. The organization has to prove control over five things for each AI workload. Those are its data, its model, its compute, the people who operate it and the governing law.
A bank, for example, does not need a national model to care about any of this. Instead, it needs to know where a customer prompt goes, who can read it and which court could order it disclosed. That framing turns a policy idea into an engineering decision, because some workloads need all five controls while many need only one or two.
The Five Control Layers of Sovereign AI
Control works as a stack of layers, so the whole system is only as sovereign as its weakest layer.
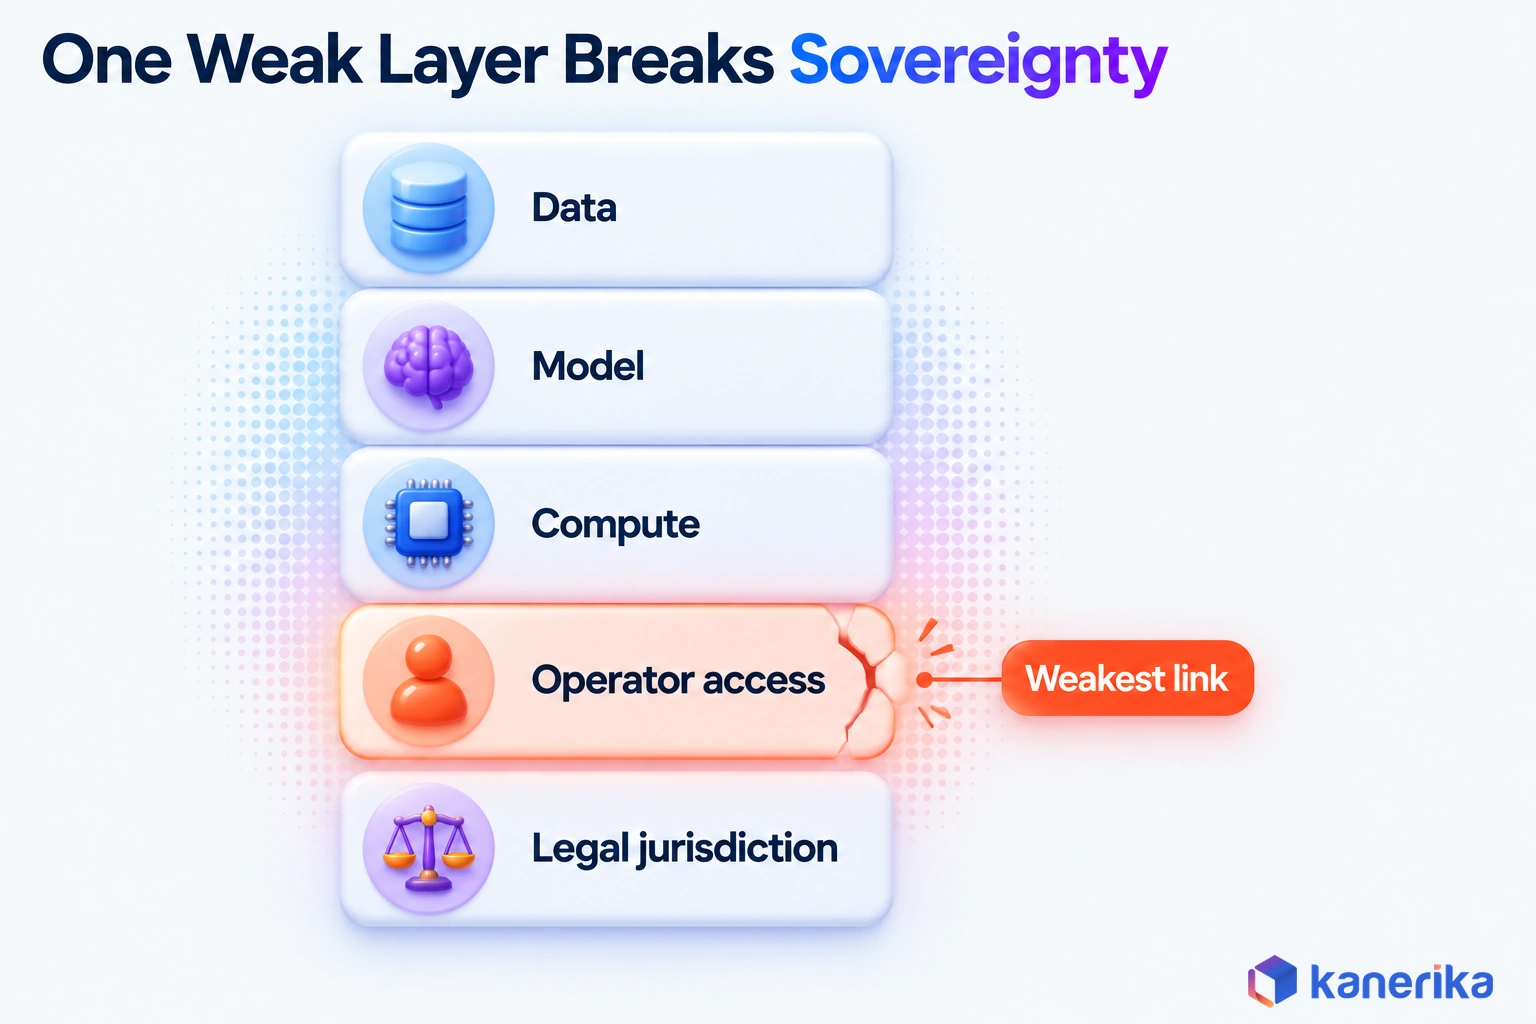
Take a model hosted in the right region but administered by a vendor team in another country. The data layer looks fine, but the operations layer is open. Encrypting everything while the provider holds the keys has a similar flaw, since the provider can still be compelled to decrypt.
The table below turns each layer into something an auditor can check, such as a log or a contract clause. If a row has no evidence behind it, that layer is not under control yet.
| Layer | What control means | Evidence to ask for |
|---|
| Data | You decide where training data, prompts, outputs and embeddings are stored and processed | A data flow map with every processing location |
| Model | You can choose, inspect, retrain or replace the model, including its weights where needed | Model inventory, license terms and export rights |
| Compute | Training and inference run on infrastructure in an approved location | Region pinning settings and provider attestations |
| Operations and admin access | Only approved people can operate, support or debug the system | Access logs and an approval workflow for vendor support |
| Legal jurisdiction | You know which laws can compel access to the data and the model | Contract terms, subprocessor list and a legal review |
In practice, the operations and legal rows are the ones teams skip. They are also the hardest rows to prove after the fact, because the evidence sits in vendor contracts and support logs rather than in your own settings.
Sovereign AI vs Data Sovereignty vs Sovereign Cloud vs Private AI
These four terms get used interchangeably, but each controls a different part of the system, and the gaps between them are where projects go wrong.
Data sovereignty is the principle that data falls under the laws of the place where it is collected or stored. Keeping data in-country is a start, but it says nothing about the model, the operators or the logs. Governance programs usually handle it through data sovereignty and cross-border transfer controls, especially for personal data.
A sovereign cloud adds operational and legal controls to infrastructure, such as in-region staff and restricted provider access. Private AI is about isolation: your data is kept apart from other tenants and out of the vendor’s training, usually by contract. Hosted private LLMs are a common example. The AI-level term, in contrast, is the broadest of the four. It covers the whole system, including the model and its outputs, so it needs both architectural and legal control.
| Term | What it controls | What it can leave open |
|---|
| Data sovereignty | Where data is stored and which law covers it | The model, the inference path and operator access |
| Sovereign cloud | Infrastructure location, operations staff and provider access | Which model runs and where prompts and logs go |
| Private AI | Isolation of your data from other customers and from vendor training | Jurisdiction and who operates the platform |
| Sovereign AI | Data, model, compute, operations and jurisdiction for each workload | Cost and capability, which both rise with control |
A quick test helps when the labels blur. Suppose a foreign authority served your AI vendor with a lawful order: could it reach your prompts? If the honest answer is “we are not sure,” you have private AI at best.
Datasheet
Elevate Data Governance, Compliance and Security of Your Organization
See how Kanerika approaches data governance, compliance and security, the controls the data layer of sovereign AI depends on.
View the Datasheet →
Why Sovereign AI Matters in 2026
The topic moved from policy debate to buying requirement because several pressures arrived together. Rules gained firm dates, governments wrote sovereignty into procurement, and AI agents began acting on data instead of only reading it.
Five forces stand out, especially for a US enterprise with global operations:
- The EU AI Act now runs on fixed dates. The AI Act entered into force on August 1, 2024. Prohibited practices and AI literacy duties applied from February 2, 2025, rules for general-purpose AI models from August 2, 2025, and most remaining provisions from August 2, 2026.
- The AI Omnibus moved the high-risk deadlines. Proposed on November 19, 2025 and in force since July 27, 2026, it pushed Annex III high-risk obligations to December 2, 2027. High-risk AI inside regulated products (Annex I) then follows on August 2, 2028.
- The US CLOUD Act reaches US-based providers. Enacted in March 2018, the CLOUD Act speeds lawful access to electronic data held by US-based global providers. European buyers weigh that when they choose a US vendor, and US firms face the mirror question with providers under other countries’ laws.
- Governments are writing sovereignty into requirements. Gartner predicts that by 2028, 65% of governments worldwide will introduce some technological sovereignty requirements, according to its September 2025 forecast. It also expects 35% of countries to be locked into region-specific AI platforms by 2027, up from 5%, per a January 2026 prediction.
- AI agents widen the exposure. An agent with tool access can call external APIs, write to business systems and also hand context to other models. Each call is therefore a new path out of your boundary, so AI agent infrastructure needs the same location rules as the model.
What These Forces Mean for a US Enterprise
For a US enterprise, these forces land hardest when AI runs through only one or two providers. Then a single change in a provider’s pricing, policy or legal exposure reaches every workload at once.
These pressures sit inside the wider set of enterprise AI trends for 2026, where governance and agent adoption now move together. The practical result for a US enterprise is simple. Region settings and contract clauses are no longer enough evidence on their own. Instead, auditors and customers ask how the AI system itself is controlled.
AI Assessment
How Ready Is Your AI Program for Sovereign Controls?
Score your data, governance and AI maturity in a few minutes and see which workloads are ready for stronger control and which need groundwork first.
Start Your AI Assessment →
Where Governments Are Investing
National programs show what sovereignty looks like when a whole country pursues it. They fund domestic compute, local-language models and the skills to run them, and they also shape what cloud providers sell to everyone else.
Europe treats sovereignty as both regulation and infrastructure. The AI Act sets the rules, while providers build region-specific clouds for European customers. AWS, for example, describes its AWS European Sovereign Cloud as “a new, independent cloud for Europe” built for data residency, operational autonomy and resiliency.
India took the model route. Under the IndiaAI Mission, the Government of India selected Sarvam to build India’s sovereign LLM, a choice Sarvam announced on April 26, 2025. That model is built for Indian languages and contexts, so it matches the NVIDIA definition closely.
In the Middle East, countries like the UAE and Saudi Arabia are investing in sovereign cloud platforms and AI research centers. These efforts are part of broader digital transformation plans. To support these initiatives, reliable web developers for UAE businesses play a crucial role in creating secure and scalable digital solutions.
For enterprises, these programs matter less as models to copy than as signals. They show which regions will expect local hosting, local operations or local models from the vendors that serve them.
Which Industries Need Sovereign AI Most
Industries differ less in whether they need control than in which layer they need it on. No law requires every industry to adopt sovereign controls; the pressure comes from the data each one handles.
| Industry | Typical concern | Example workload |
|---|
| Healthcare | Protected health information under HIPAA and patient trust | Clinical note summaries, prior-authorization drafts |
| Banking and insurance | Customer data, model risk management and cross-border supervision | Fraud triage, credit memo drafts, complaint analysis |
| Government and defense contractors | Controlled data and federal requirements such as FedRAMP | Document review, analyst support tools |
| Manufacturing | Trade secrets in designs, process data and supplier contracts | Engineering copilots, quality root-cause analysis |
| Multinationals | Conflicting national rules on employee and customer data | HR assistants, global customer service agents |
In practice, one company often sits in two rows. A US health insurer with staff in Europe handles HIPAA data in claims and GDPR data in HR. That is why the decision has to be made per workload, not per company.
How Sovereign AI Works: A Reference Architecture
A sovereign system is an ordinary AI stack with a boundary drawn around it and a control on every crossing. The layers are familiar, but each one now has a known location, a known operator and a known legal owner.
Read the stack from the bottom up. Data covered by an enterprise data governance program sits in approved stores with classification labels. A retrieval layer then turns documents into embeddings and keeps them in a vector database inside the same boundary.
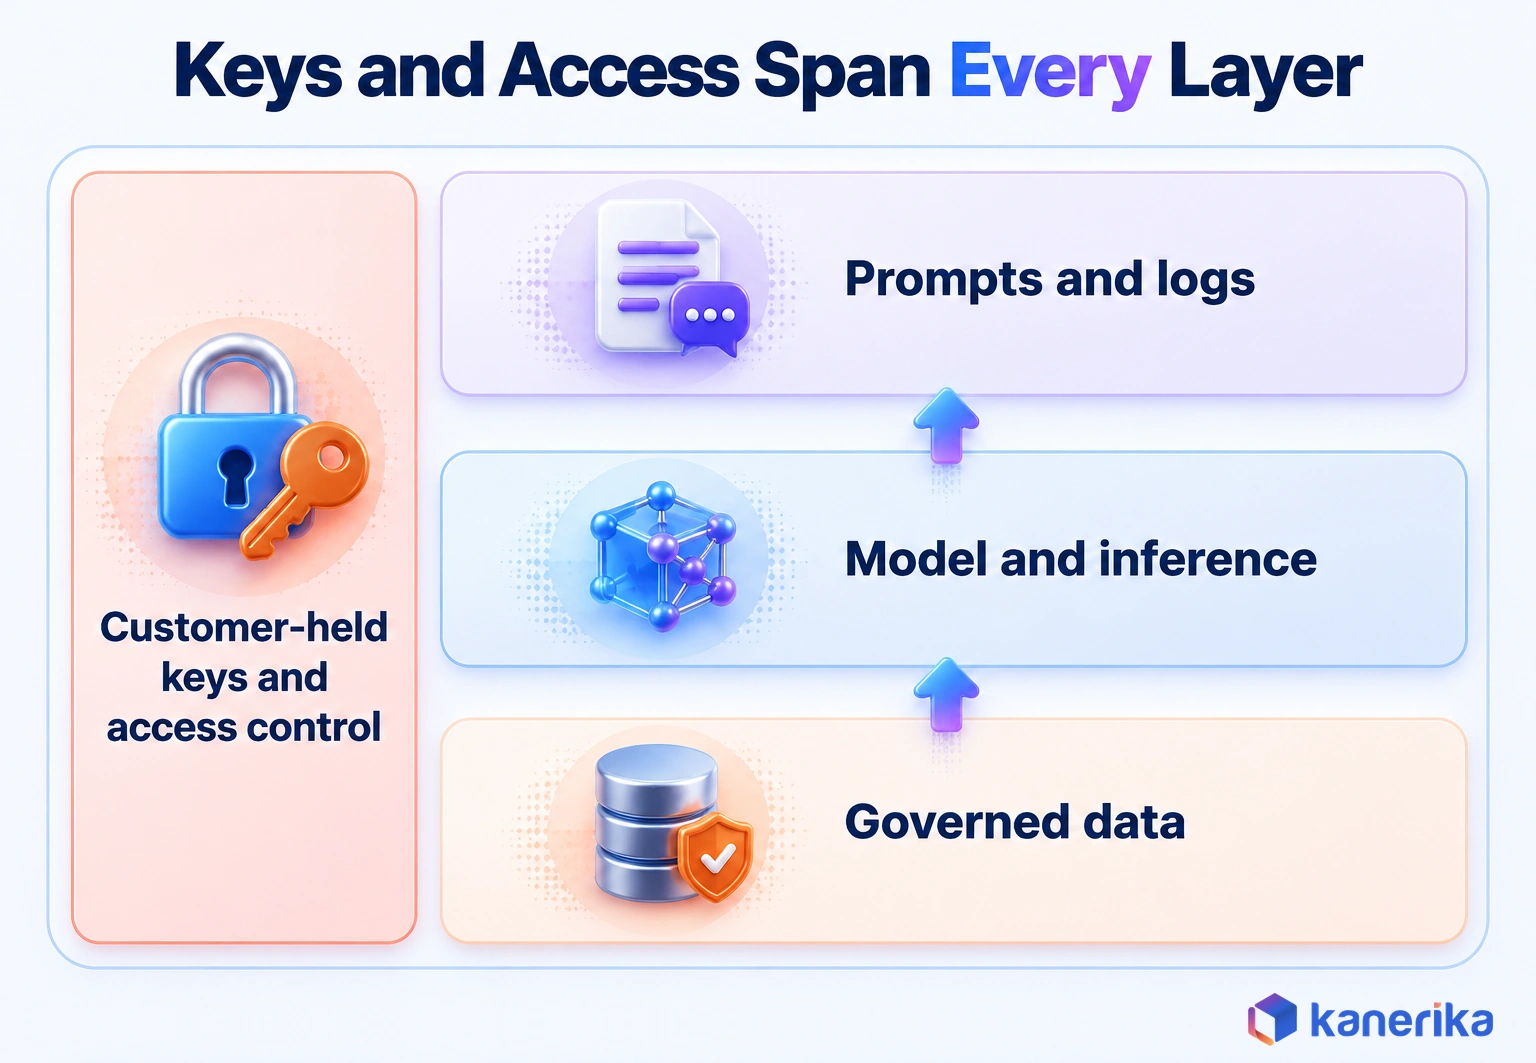
After that, the model, whether hosted or open-weight, runs inference on approved compute. Prompts, completions and logs then land in storage you control, where they can be audited.
Two controls run across every layer. Identity and access management decides who and what can call each component. Key management decides who can read data at rest and in transit, ideally through customer-held keys. That is why it matters more than region settings alone.
Training adds one more choice. When data cannot move to a central location, federated learning lets a model learn from data where it lives and share only model updates. It is not required for a sovereign design, but it helps when several entities or countries each hold part of the data.
Where AI Data Leaves the Boundary
Sovereignty usually fails through quiet data paths that nobody mapped, and AI systems create more of those paths than traditional applications do.
The OWASP Top 10 for LLM Applications 2025 ranks sensitive information disclosure second, as LLM02. Check each of these paths before any workload goes live:
- Prompts: they travel wherever the model endpoint is, even though they often hold the most sensitive text in the system.
- Completions: model outputs can repeat or summarize regulated data, so they need the same handling as the input.
- Logs and telemetry: debug logs, traces and usage analytics often ship to a vendor’s monitoring service by default, unless someone turns that off.
- Fine-tuning sets: training data copied to a vendor environment for tuning may remain there until someone deletes it.
- Embeddings in vector stores: embeddings are derived from source documents and can reveal what they contain, so they need the same location rules.
- Agent tool calls: an agent that calls a search API, a SaaS tool or another model sends context outside the boundary with every call. Review each tool as a data path under your agentic AI security controls.
- Vendor support access: a support ticket can open logs or environments to an engineer in another jurisdiction.
An LLM gateway is one of the most practical AI guardrails for several of these paths at once. It sits between applications and models, so it can enforce which endpoints are allowed, redact sensitive fields and keep its own audit log.
Watch on YouTube
Can LLM Gateways Make Enterprise AI Safer?
A Kanerika discussion on LLM gateways and whether they make enterprise AI safer. Watch it alongside this list of the paths AI data takes out of your boundary.
Gateways do not solve vendor support access or fine-tuning copies, which still need contract terms and access reviews. They do give security teams one place to see and block traffic that would otherwise leave quietly. Host the gateway inside your boundary, since outside it the gateway becomes one more path out.
Resilience and Exit: Keys, Backups and Model Portability
Sovereignty also means being able to keep running, or to leave, when a provider changes course. After all, a system you cannot exit is not fully under your control.
Three controls carry most of the weight. Customer-held keys let you revoke a provider’s ability to read your data. Immutable backups of data, embeddings and configuration let you rebuild elsewhere, while a tested exit plan proves the first two actually work.
Access approval tools have limits, though. Microsoft’s Customer Lockbox documentation, updated in July 2026, says external legal demands for data do not trigger a Lockbox request. Keys and jurisdiction, not approval workflows, decide legal reach.
Open-weight models also add a portability lever. Because you hold the weights, you can move the model between clouds or bring it on-premises without asking the original provider. You also take on hosting, patching, evaluation and ML model management, so run the exit test before production rather than after a dispute starts.
A practical exit test is smaller than it sounds. Restore one workload’s data, embeddings and configuration into a second environment, then point a test application at it and compare the answers. Record how long the rebuild took and what broke, because that time is your real recovery window. Repeat the test after any change of model or provider.
Five Deployment Models Compared
Five common deployment models run from a public AI service at one end to a stack you operate yourself at the other. Between those poles, each buys a different level of control at a different price.
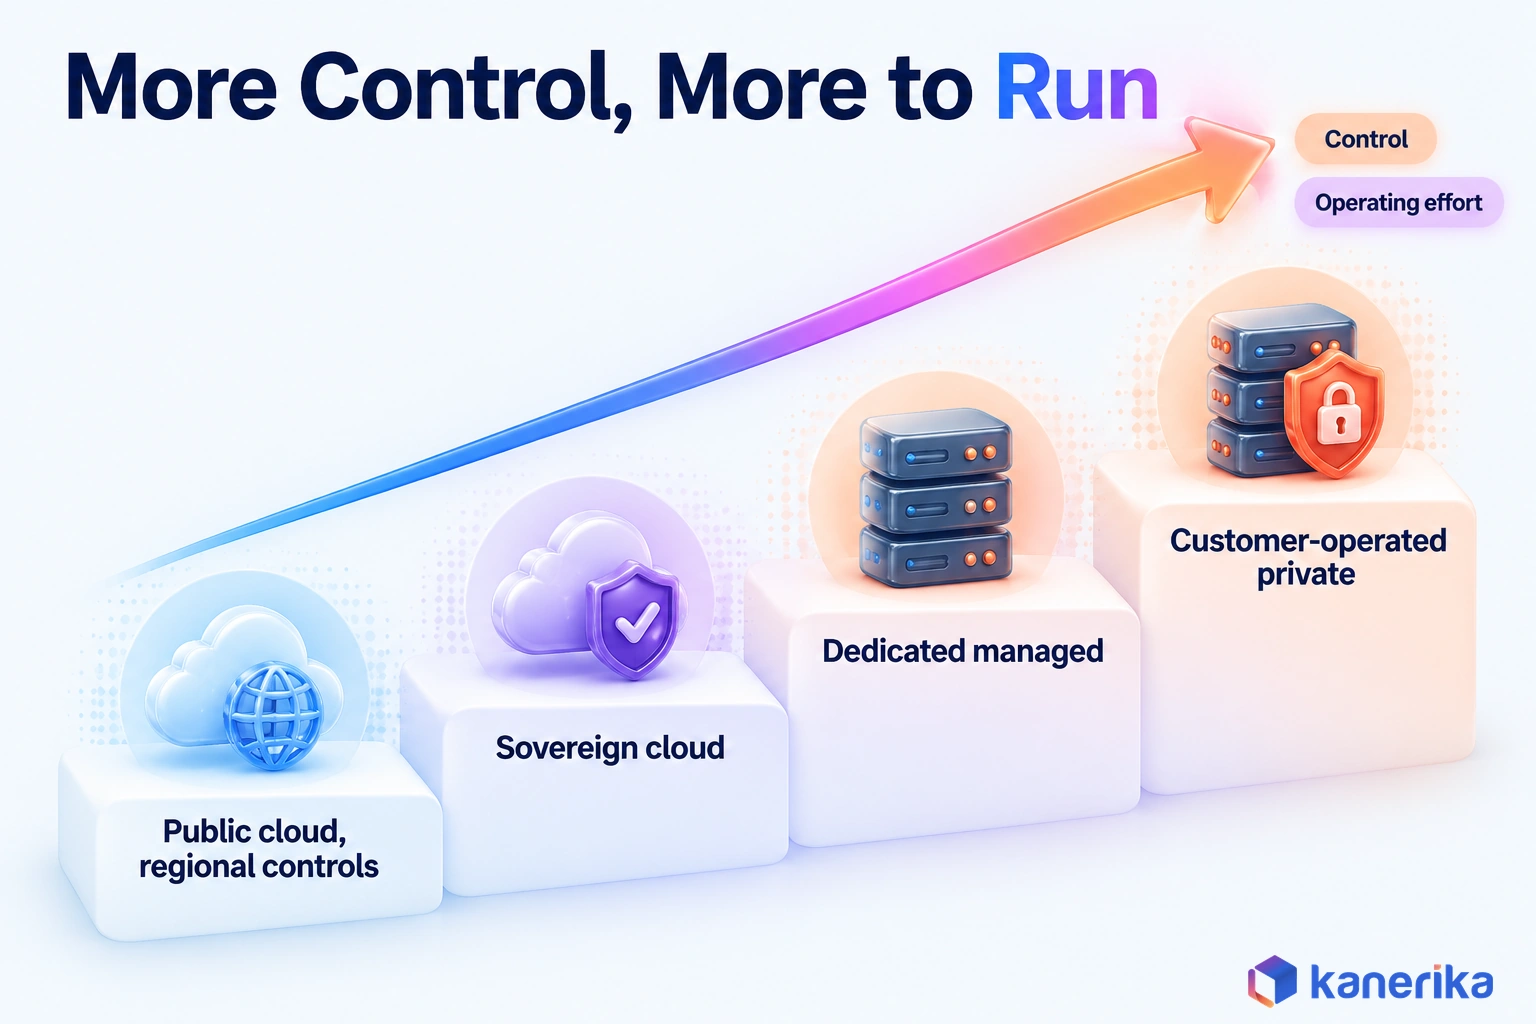
The graphic shows four of them as steps, because the fifth, hybrid, combines those steps by workload rather than adding a new one. The table compares all five. Because availability varies by region and service, the example offerings only illustrate each category, so check any product against the workload in question.
| Deployment model | Best fit | Main advantage | Main trade-off | Example offerings |
|---|
| Public cloud with regional controls | Low-risk workloads with no regulated data | Fastest start, lowest cost, newest models | Provider operates the stack, and foreign legal reach may apply | Region-pinned AI services from major clouds |
| Sovereign cloud | Regulated data that must stay under local law and local operations | Managed service with in-region operations and restricted access | Narrower service catalog and higher prices | Microsoft Sovereign Public Cloud, AWS European Sovereign Cloud |
| Dedicated managed environment | Sensitive workloads that need isolation but not self-operation | Single-tenant capacity and customer-held keys, with the vendor still operating it | Cost of reserved, dedicated capacity | Dedicated capacity from a cloud or model provider |
| Customer-operated private | Highest-sensitivity data, including disconnected sites | Full control of data, model, compute and access | You staff and run everything, often with smaller models | Microsoft Sovereign Private Cloud with Azure Local, Foundry Local, open-weight models on your hardware |
| Hybrid | Portfolios with mixed data classes | Each workload gets only the control it needs | Two or more environments to govern | A gateway that routes by data class across the models above |
How One Vendor Spans Several Models
Microsoft’s sovereignty portfolio, as listed in October 2026, shows how one vendor can span several rows. It lists Sovereign Public Cloud, Sovereign Private Cloud with Azure Local for hybrid or fully disconnected use, Microsoft 365 Local and Foundry Local. It also lists External Key Management and Customer Lockbox, which add key custody and access approval to existing services. Lockbox lets customer approvers approve or deny a Microsoft engineer’s request to access their data.
The model itself is part of this decision. The same open-weight model can run in any row, while the most capable hosted models are often offered only as public cloud services. Our guide to enterprise LLM deployment models covers how to pick the model itself.
Kanerika Service
Private LLM Development and Deployment
Kanerika builds, fine-tunes and deploys language models in the environment you choose, with access control, logging and evaluation set up from the start.
Explore LLM Development Services
How to Choose the Right Approach for Each Workload
The right approach starts with the workload, not the vendor. Classify each AI use case by the data it touches and the harm a leak would cause. Then pick the least costly model that meets its mandatory controls.
That rule sounds obvious, yet programs often run it backwards. They choose one platform for everything, then overpay for low-risk assistants or under-protect regulated ones. Deciding per workload, in contrast, avoids both mistakes.
Before comparing platforms, answer four questions for each workload. What data classes does it touch? Which laws or contracts apply to that data? Who must be able to operate it, and who must not? What would it cost to leave the provider in a year?
A Workload-Based Decision Framework
The table below maps common scenarios to a recommended deployment model, such as a sovereign cloud for EU personal data. Treat it as a starting point that your legal and security teams then confirm.
| Scenario | Recommended model | Why |
|---|
| Internal productivity assistant with no regulated data | Public cloud with regional controls | Region settings and contract terms cover the risk at the lowest cost |
| Customer chatbot handling personal data of EU residents | Sovereign cloud in the EU | Keeps processing and operations under EU law for GDPR transfers |
| Regulated records, such as health or financial data, that still need a managed service | Dedicated managed environment with customer-held keys | Isolation and key custody without building an operations team |
| Defense work, trade secrets or disconnected sites | Customer-operated private | No outside operator can reach the data, the model or the logs |
| A portfolio with all of the above | Hybrid, with a gateway routing by data class | Each workload pays only for the control it needs |
Notice that sovereign controls appear in four of the five rows, but at very different strengths. So the framework does not ask whether to adopt them; it asks how much control each workload needs.
Three thresholds settle most borderline cases. If a workload touches no regulated data, no trade secrets and no agent tools, keep it in public cloud with regional controls. If a foreign order served on your vendor could reach its prompts or logs, start with a sovereign cloud or dedicated environment. When its exit test takes longer than its recovery time objective, fix backups and portability before launch, whichever model you chose.
Worked Example: A US Healthcare Company
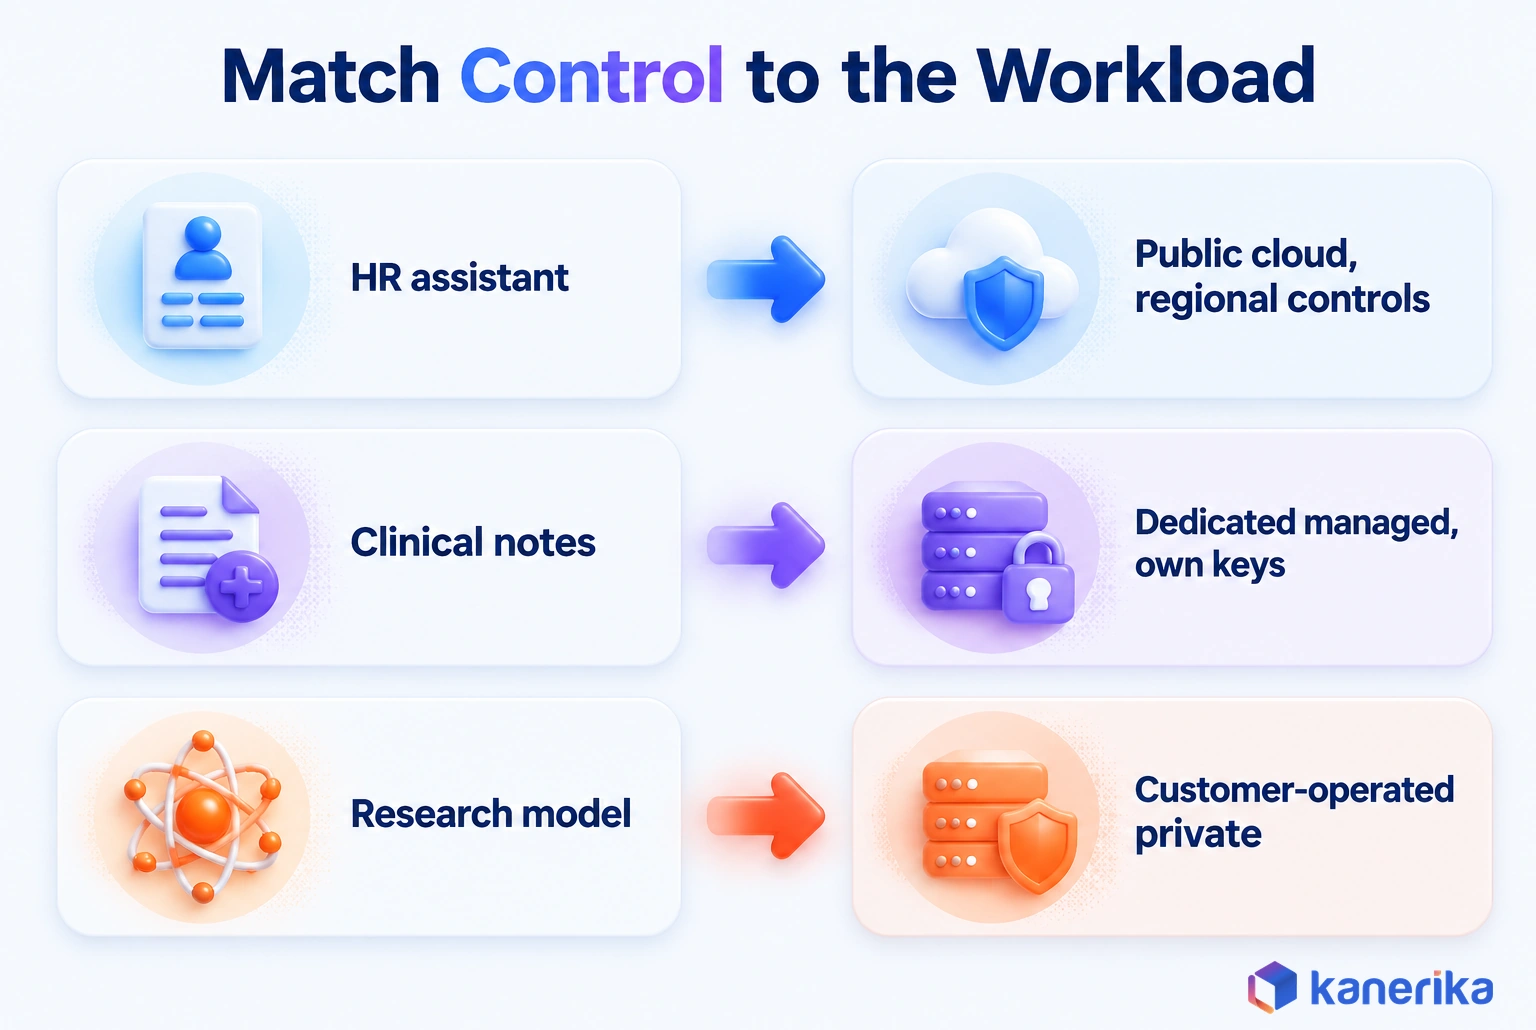
Consider a US healthcare company with three AI workloads on its roadmap. Each touches different data, so each lands in a different model.
- HR policy assistant: employees ask about leave, benefits and expense rules. The data is internal policy text with no patient information, so public cloud with regional controls is enough, with prompt logs kept in a US region.
- Clinical notes summarizer: clinicians summarize visit notes that contain protected health information. HIPAA does not require a sovereign cloud, but it does require safeguards and a business associate agreement with the vendor. So a dedicated managed environment with customer-held keys and approved support access fits.
- Research model on proprietary data: data scientists fine-tune a model on de-identified records and internal research, so the weights themselves become intellectual property. A customer-operated private deployment of an open-weight model therefore keeps both the data and the model in-house.
The result is three environments instead of one. That costs more to govern than a single platform, but it is usually cheaper than running all three workloads in the most restrictive model. It also puts the strongest controls where the risk actually sits.
How to Measure Whether It Is Working
Sovereign controls need evidence, not intentions. Track a short set of measures for each workload, then review them every quarter.
- Inference location verified: the share of model calls confirmed to run in approved regions, checked from logs rather than settings.
- Admin access exceptions: the count of vendor or cross-border access events, each with an approval record.
- Exit test passed: the date of the last successful rebuild in a second environment.
- Unmapped data paths: new outbound connections from agents or tools that appeared since the last review.
- Cost per workload: the full run cost, so the price of control stays visible next to its benefit.
A workload that cannot produce these numbers is not ready for an audit, however good its architecture diagram looks.
Benefits and Trade-offs
Stronger control is worth paying for when it changes an outcome, such as passing an audit or winning a regulated customer. It also carries real costs, and an honest plan names both.
The benefits are concrete:
- Compliance evidence: you can show regulators and auditors where data went and who touched it, using logs and access records you own.
- Customer trust: security questionnaires from regulated customers get answered with evidence rather than vendor assurances.
- Local-language and domain models: control over the model lets you tune it for your language, terminology and workflows.
- Resilience: customer-held keys, backups and portable models reduce dependence on any one provider’s terms.
The trade-offs, though, are just as concrete:
- Compute: private and dedicated deployments need GPU capacity that you reserve or buy before launch.
- Talent: someone has to run, patch, monitor and evaluate the models, since the provider no longer does it. Mature machine learning operations practice keeps that load manageable.
- Capability gap: the newest frontier models may not be available in a sovereign or private setting.
- Cost: duplicated environments and extra tooling raise the total bill.
Many of these trade-offs overlap with wider AI adoption challenges, such as skills gaps and unclear ownership, and with familiar data governance challenges. Sovereignty adds a layer to those problems rather than creating a separate one, so the same owners should handle both.
What It Costs
Cost depends on how many workloads need which level of control, so the useful estimate is built from five cost drivers rather than a list price.
- GPU capacity and hosting, reserved or owned, sized for peak inference and any fine-tuning
- Staff for platform operations, security, model evaluation and on-call support
- Licenses for sovereign or dedicated cloud tiers, models and gateways
- Governance tooling, from data governance tools for classification to access reviews, logging and audit evidence
- Duplicated environments for hybrid setups, disaster recovery and exit tests
Gartner’s January 2026 prediction says nations building a sovereign AI stack need to spend at least 1% of GDP on AI infrastructure by 2029. That is a national benchmark and says nothing about an enterprise budget.
For a company, then, the useful comparison is per workload. Weigh the added cost of control against the cost of the risk it removes, and revisit the answer when a workload’s data or regulation changes.
Kanerika Service
AI Strategy and Assessment
Kanerika helps you inventory AI use cases, classify the data each one touches and set the control level it needs before you commit to a platform.
Explore AI Strategy Services
Regulations, Standards and a Pre-Production Checklist
Several privacy, AI and security rules each govern one part of the control picture, and together they set the requirements for a sovereign AI workload.
| Rule or standard | Scope | Why it matters here |
|---|
| GDPR | Personal data of people in the EU | Transfer rules and a lawful basis for prompts, logs and training data |
| EU AI Act | AI systems placed on the EU market | Risk tiers, with Annex III high-risk duties from December 2, 2027 and Annex I from August 2, 2028 |
| US CLOUD Act | US-based providers that hold electronic data | Speeds lawful access to data held by those providers |
| HIPAA | US protected health information | Safeguards and business associate agreements for AI vendors |
| NIST AI RMF and NIST-AI-600-1 | Voluntary US framework for AI risk | Released January 26, 2023, with a Generative AI Profile on July 26, 2024 |
| ISO/IEC 42001 | AI management systems | A certifiable standard for governing AI across its life cycle |
| FedRAMP | Cloud services used by US federal agencies | The authorization baseline for AI services sold to government |
Read these together rather than one at a time. The NIST AI Risk Management Framework and ISO/IEC 42001 give you the management structure. Gartner’s AI TRiSM framing covers similar trust, risk and security ground. GDPR, HIPAA and the AI Act then set the hard obligations that structure has to meet. For example, a European subsidiary of a US company may face GDPR transfer rules and CLOUD Act exposure on the same workload.
The Pre-Production Governance Checklist
Before any AI workload goes live, get a named sign-off on eight points. Each one maps to a control layer, so a missing answer shows exactly where the gap is.
- Control level: record which deployment model the workload uses and why.
- Asset inventory: list the data sources, models, vector stores, gateways and agent tools in scope.
- Processing locations: confirm where prompts, completions, logs, embeddings and backups are processed and stored.
- Admin and vendor access test: attempt access as a vendor support role, then confirm it is blocked or approved per policy.
- Contracts and subprocessors: review data processing terms, subprocessor lists and any foreign-law exposure.
- Encryption and logging: confirm key custody, encryption in transit and at rest, and tamper-evident audit logs.
- Exit test: rebuild the workload in a second environment from backups, then record how long it took.
- Owners: name a business owner, a technical owner and a reviewer for the quarterly control check.
Teams with an existing governance program or AI security framework can fold these points into current reviews rather than form a new committee. Kanerika’s AI governance checklist also covers oversight and accountability in more detail. The checklist works best as a gate in the release process, so no workload reaches users without it.
Checklist
AI Governance Checklist
Review oversight, access control, audit trails and accountability for each AI workload before it goes to production.
Get the Checklist →
How Kanerika Helps Enterprises Build Sovereign AI
Kanerika helps enterprises decide which AI workloads need sovereign controls, then builds those controls on the platforms they already run. The work follows four stages, and each one has a clear output.
- Assess and classify: inventory AI use cases, classify their data and set the required control level for each one.
- Select and design: choose the deployment model per workload and design the boundary, key management and access paths.
- Implement and validate: build on Microsoft Fabric, Databricks, Snowflake or a private environment, then test locations, access and exit.
- Operate and expand: run the control measures every quarter, then bring new workloads through the same review.
Stage one often runs as an AI strategy and assessment engagement, while private model builds draw on Kanerika’s LLM development services. Microsoft Purview often anchors the classification and lineage work in the first stage. These platforms supply governance and data controls, but they do not make an AI workload sovereign on their own. The boundary, the access model and the evidence still have to be designed.
Audit evidence across jurisdictions is the part of this work Kanerika has already delivered for a regulated client. For an AI-powered regulatory compliance provider serving financial institutions across multiple jurisdictions, Kanerika built an AI regulatory management platform. The results were 60% less manual compliance work, 40% faster regulatory response and 5X better audit traceability.
That project was a compliance platform rather than a sovereign deployment. Still, the audit trail and multi-jurisdiction rule handling it required are the same capabilities a sovereign program depends on.
Case Study
60% Less Manual Compliance Work with AI
Kanerika built an AI regulatory management platform for a compliance provider serving financial institutions across multiple jurisdictions, with 40% faster regulatory response and 5X better audit traceability.
Read the Case Study →
Is Sovereign AI Worth It for Enterprises?
Sovereign AI is worth it where a workload needs control that a standard cloud service cannot prove. Still, it is not a blanket rule for every assistant or chatbot.
Think of it as control over data, models, compute, operator access and jurisdiction, applied one workload at a time. It works through a mapped boundary with customer-held keys and audited access, as well as a tested exit. The best way to adopt it is to start small. Pick one high-value, high-risk workload, classify its data and choose the least costly model that meets its controls. Measure the evidence for a quarter, then widen the scope. If that first workload passes its access review and exit test, it becomes the template for every workload after it.
Frequently Asked Questions
What is sovereign AI?
Sovereign AI is the ability of a country or an organization to control the AI systems it relies on. For an enterprise, that means control over five layers of each workload: the data, the model, the compute, the people with admin access and the law that governs it. Storing data locally covers only the first of those layers.
Who controls sovereign AI?
Control sits with whoever owns the five layers of an AI workload. In a national program, that is usually a government or domestic institutions. In an enterprise, it is the company itself, which decides where data and models run, who may operate them and which contracts and laws apply. Vendors can run parts, but only under approved terms.
What is India's sovereign AI?
India’s main sovereign AI effort runs under the IndiaAI Mission. Through it, the Government of India selected Sarvam to build the country’s sovereign large language model, as Sarvam announced on April 26, 2025. The aim is a model built for Indian languages and contexts, developed within the national AI program rather than licensed from a foreign provider.
Is DeepSeek a sovereign AI?
DeepSeek is a family of models from a Chinese AI company, and some are released as open weights. A model is not sovereign by origin alone. With a hosted DeepSeek service, the provider controls the data path. If you self-host the open weights, you control the data, compute and access, although the model’s origin still deserves a review.
Is sovereign AI the same as sovereign cloud?
No. A sovereign cloud controls the infrastructure layer: where servers sit, who operates them and which provider staff can access them. Sovereign AI covers the whole AI system on top of that, including which model runs, where prompts, logs and embeddings go, and who can change the model. A sovereign cloud is often one part of it.
Is sovereign AI the same as private AI?
Not quite. Private AI usually means your data is isolated from other customers and excluded from vendor model training, often through contract terms. Sovereign AI goes further by also controlling the jurisdiction, the operators and the infrastructure through both architecture and legal terms. A private AI service run by a foreign provider can still fall under another country’s laws.
Does sovereign AI require on-premises infrastructure?
No. On-premises or customer-operated infrastructure gives the most control, but it is only one option. Sovereign cloud regions and dedicated managed environments with customer-held keys can meet the needs of many regulated workloads. On-premises makes sense when no outside operator may touch the data or the model, such as defense work or disconnected sites.
Which companies offer sovereign AI platforms?
Offerings fall into a few categories: hyperscaler sovereign clouds, dedicated managed environments, national model builders and open-weight models you run yourself. Microsoft’s portfolio includes Sovereign Public Cloud, Sovereign Private Cloud with Azure Local and Foundry Local. AWS describes its AWS European Sovereign Cloud as an independent cloud for Europe. Check each offering against your workload’s data, location and access requirements.
Who coined the term sovereign AI?
No single source is widely credited with coining the term. It gained wide attention after NVIDIA founder Jensen Huang argued at the 2024 World Governments Summit in Dubai that every country must own the production of its own intelligence, which he called sovereign artificial intelligence. NVIDIA now describes it as countries building AI on national infrastructure, data and talent.
How much does sovereign AI cost?
There is no standard price, because cost depends on how many workloads need which level of control. The main drivers are GPU capacity, staff to operate and evaluate models, licenses, governance tooling and duplicated environments. Gartner’s figure of at least 1% of GDP by 2029 applies to nations building a full stack, not to enterprise budgets.
Why is sovereign AI important for governments and businesses?
For governments, it protects national data, supports local languages and reduces dependence on foreign technology. For businesses, it provides evidence that regulated data stays under the right law and out of unapproved hands. Firm EU AI Act dates, the reach of the US CLOUD Act and AI agents with tool access have all raised the stakes for both.
How is sovereign AI different from traditional AI models?
The difference is not the model type but who controls it. A traditional AI service runs wherever the provider chooses, under the provider’s operations and legal jurisdiction. A sovereign deployment fixes where the model and its data run, who can operate and support it, and which laws apply. The same model can be used either way.
Which countries are investing in sovereign AI?
Investment is spread across several regions. The European Union pairs the AI Act with region-specific cloud offerings, such as the AWS European Sovereign Cloud. India, under its IndiaAI Mission, selected Sarvam to build a sovereign large language model. Gulf states such as the UAE and Saudi Arabia are funding sovereign cloud platforms and AI research centers.
Which industries can benefit most from sovereign AI?
Industries that handle sensitive or regulated data benefit most. Healthcare protects patient information under HIPAA, while banking and insurance manage customer data and cross-border supervision. Government contractors face federal requirements, manufacturers guard trade secrets and multinationals juggle conflicting national rules. The need is usually set per workload, not for a whole company or sector.
Can enterprises adopt sovereign AI or is it only for governments?
Enterprises can adopt it, and many of the controls are built for them. Sovereign cloud offerings, dedicated managed environments, customer-held keys and open-weight models all let a company control where AI runs and who can reach it. The practical approach is to start with one high-risk workload rather than rebuild the whole AI portfolio at once.
Is sovereign AI safe?
Sovereign AI reduces specific risks, such as foreign legal access, unapproved vendor access and data leaving through logs or agent tool calls. It does not make a system safe by itself. Models still need testing for accuracy, bias and misuse, and a self-operated environment needs strong security operations, because the provider no longer handles them for you.














