TL;DR
LangChain vs LangGraph comes down to control: pick LangChain’s create_agent for standard tool-calling agents, and pick LangGraph when a workflow needs explicit state, branching, approvals or crash recovery. Since both reached 1.0 on October 22, 2025, create_agent runs on the LangGraph runtime, so the two are layers of one stack. LangChain gives you model integrations, tools and middleware, including human approval of tool calls, in very little code. LangGraph gives you typed state, conditional edges, checkpoints and interrupts, at the price of more code to write and test. Both libraries are free under the MIT license, and model tokens usually cost far more than LangSmith tracing. Start with create_agent, then move a workflow to LangGraph once it must pause for a person, resume after a failure or coordinate several agents.
Key Takeaways
- LangChain 1.0 and LangGraph 1.0 shipped on October 22, 2025, and create_agent now runs on the LangGraph runtime.
- Use LangChain’s create_agent for RAG answers and tool-calling assistants that finish within one request.
- Use a LangGraph StateGraph for approval flows, multi-day threads and multi-agent supervisors.
- Human-in-the-loop exists in both: middleware in LangChain, interrupts with checkpoints in LangGraph.
- AgentExecutor moved to langchain-classic, and LangChain 0.3 gets only maintenance fixes until December 2026.
- Both libraries are MIT-licensed, while LangSmith plans and model tokens are billed separately.
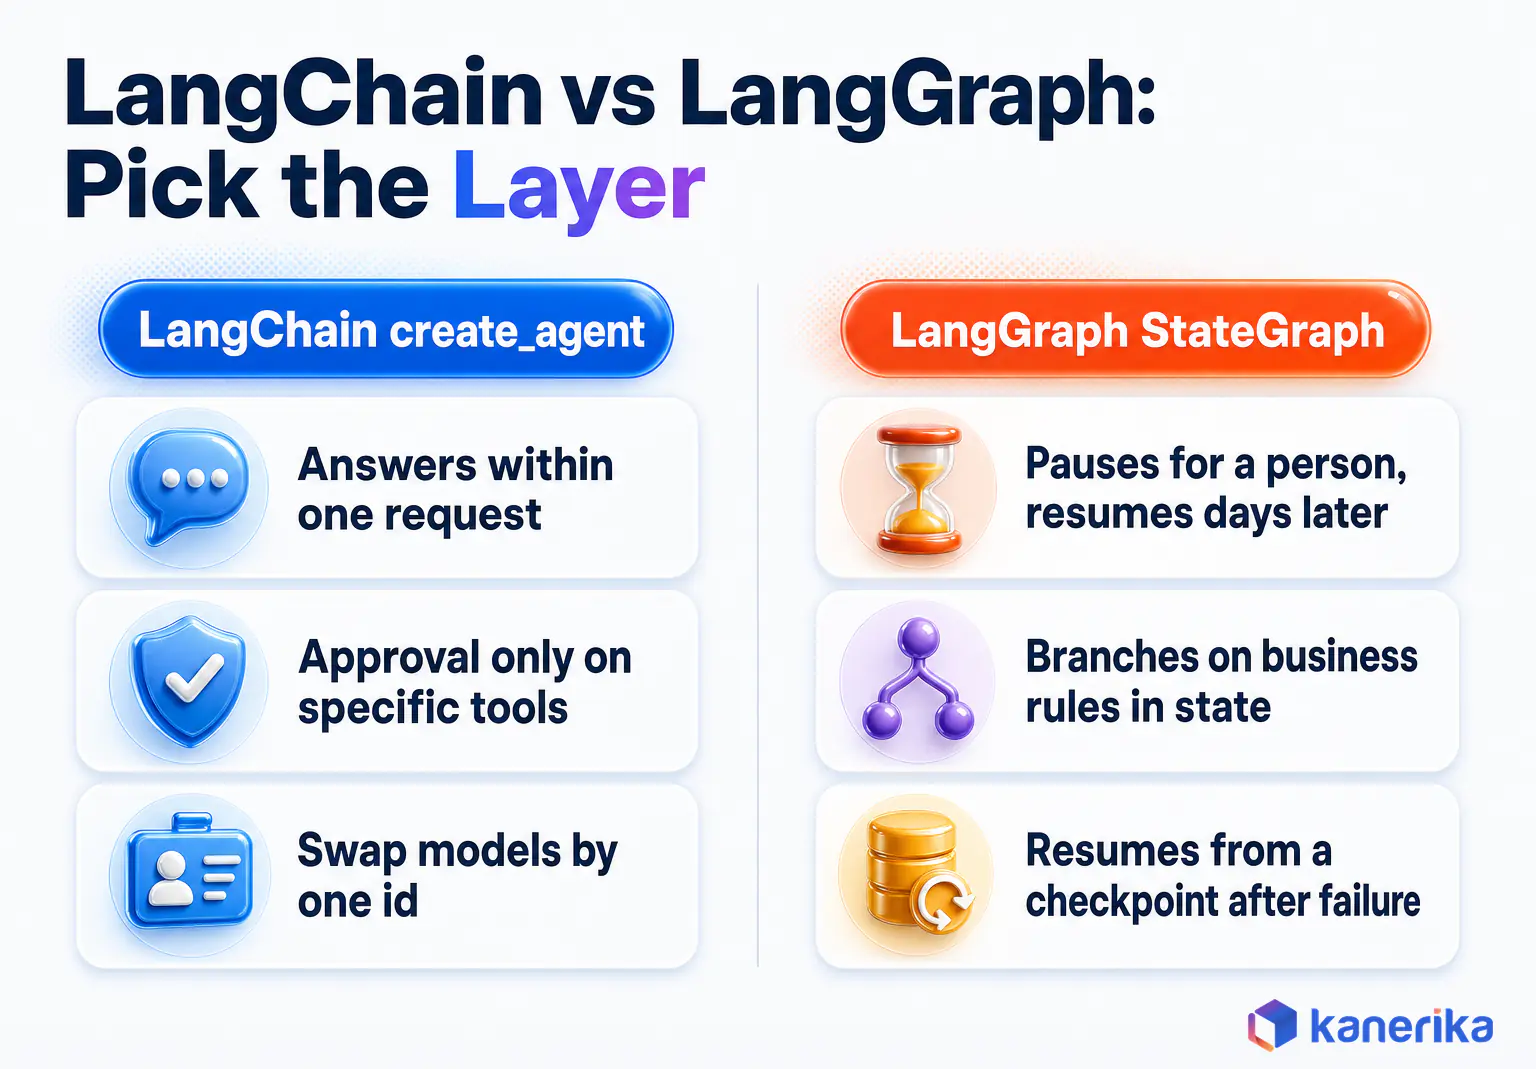
A Support Agent That Outgrew Its Loop
Picture a support team that ships a ticket agent in two weeks. It reads the ticket, searches the help center, calls a refund tool and replies to the customer.
A single agent loop handles that job well. The model decides which tool to call, the framework runs it, and the answer goes back to the customer within seconds.
Then finance asks for one change. Refunds above $100 now need a manager’s approval, and the manager may answer hours later.
Suddenly the agent must stop mid-run, save its place and resume after the decision. It must survive a server restart in between, and it must log who approved what.
That shift, from a quick loop to a workflow with memory and checkpoints, is the real LangChain vs LangGraph question. This guide explains both frameworks after their 1.0 releases, shows the same agent written both ways and maps common workflows to the right layer. For the wider field, our guide to AI agent frameworks compares the other options.
What Is LangChain?
LangChain is a high-level Python and JavaScript framework for building applications and agents on top of large language models. Its first release reached PyPI in late 2022, and the project has grown around one idea: get a working agent with very little code.
In practice, a developer picks a model, lists the tools the agent may call and writes a system prompt. LangChain then runs the loop for you. It calls the model, executes the tool the model asked for, feeds the result back and stops when the model gives a final answer.
Scale is also part of the appeal. In its 1.0 announcement, the LangChain team said its libraries see 90 million monthly downloads. That is a vendor figure, but it explains why so many tutorials, integrations and answers already exist.
What LangChain 1.0 Changed
The 1.0 release on October 22, 2025 trimmed LangChain down to a smaller, more stable core. The LangChain v1 migration guide lists four changes that matter for this comparison.
- create_agent is the standard agent API. It replaces create_react_agent from langgraph.prebuilt, which is now deprecated.
- Middleware wraps model and tool calls. You add behavior such as human approval without writing your own loop.
- Legacy code moved to langchain-classic. AgentExecutor and the older chains live there, so existing apps keep running.
- The API is frozen until 2.0. LangChain promises no breaking changes in the 1.x line.
Even so, the library has kept moving inside that promise. As of November 2, 2026, the current release on PyPI is langchain 1.4.8.
Model and Tool Integrations
Integrations are where LangChain saves the most time. Each model provider ships as its own package, such as langchain-openai, langchain-anthropic and langchain-google-genai, and you select a model by its API id.
Once the provider packages are installed, one agent can move from Claude Sonnet 5.5 to GPT-6.1 Sol or Gemini 4 Argon by changing a single string. The tools, prompt and middleware stay the same, so side-by-side model trials are cheap.
Tools follow one pattern too. A tool is a typed Python function, and LangChain can also load tools from servers that speak the Model Context Protocol.
For retrieval, LangChain also connects to most vector stores, which our vector database comparison reviews. If your app is mostly retrieval-augmented generation, read our LangChain vs LlamaIndex breakdown too.
Kanerika Service
Build LLM Applications on Your Own Data
Kanerika designs, fine-tunes and deploys LLM applications with the access controls and monitoring production needs.
Explore LLM DevelopmentWhat Is LangGraph?
LangGraph is a low-level orchestration runtime for long-running, stateful agents. Where LangChain hides the loop, LangGraph asks you to draw it as a graph of steps that share one state object.
For example, take the refund agent from the opening. In LangGraph, “assess the ticket”, “ask a manager” and “issue the refund” become three nodes. Edges decide which node runs next, and the state carries the ticket id, the amount and the approval between them.
That explicit shape is the point, because you can see every path the agent may take. You can also test each step on its own and stop the run at any node. It is the same discipline that good AI agent orchestration asks for in any stack.
LangChain said in October 2025 that companies such as Uber, LinkedIn and Klarna use LangGraph. As of October 30, 2026, the current release on PyPI is langgraph 1.2.19, under the MIT license.
State, Nodes and Edges
Three building blocks make up every LangGraph app. Once they click, the rest of the library reads like plumbing around them.
- State is a typed object, often a TypedDict, that every node reads and updates.
- Nodes are plain functions that take the state and return the fields they changed.
- Edges connect nodes. A conditional edge calls a routing function to pick the next node, and edges may loop back to form cycles.
Graphs can also nest. A subgraph is a compiled graph used as a node inside a larger one. As a result, a team can own one piece, such as a billing flow, without touching the rest.
Cycles also matter more than they look. An agent that retries a failed tool call is a loop by nature. So is one that asks a reviewer to try again, and LangGraph lets you write that loop on purpose.
What LangGraph Adds for Production
The graph model pays off once an agent runs for real users. For that reason, LangGraph builds four production needs into the runtime itself.
- Checkpointers save the state after each step, per conversation thread. The Postgres checkpointer, langgraph-checkpoint-postgres, reached version 3.2.0 on October 14, 2026.
- Interrupts pause a run at a node, wait for human input and resume from the saved state.
- Streaming sends tokens and intermediate state updates to the user interface while the graph runs.
- LangSmith Studio, formerly LangGraph Studio, draws the graph and lets you step through a run visually.
Tools also plug into a graph the same way they plug into an agent. If your tools live behind MCP servers, our tutorial shows how to connect LangGraph agents to MCP servers.
How LangChain and LangGraph Fit Together
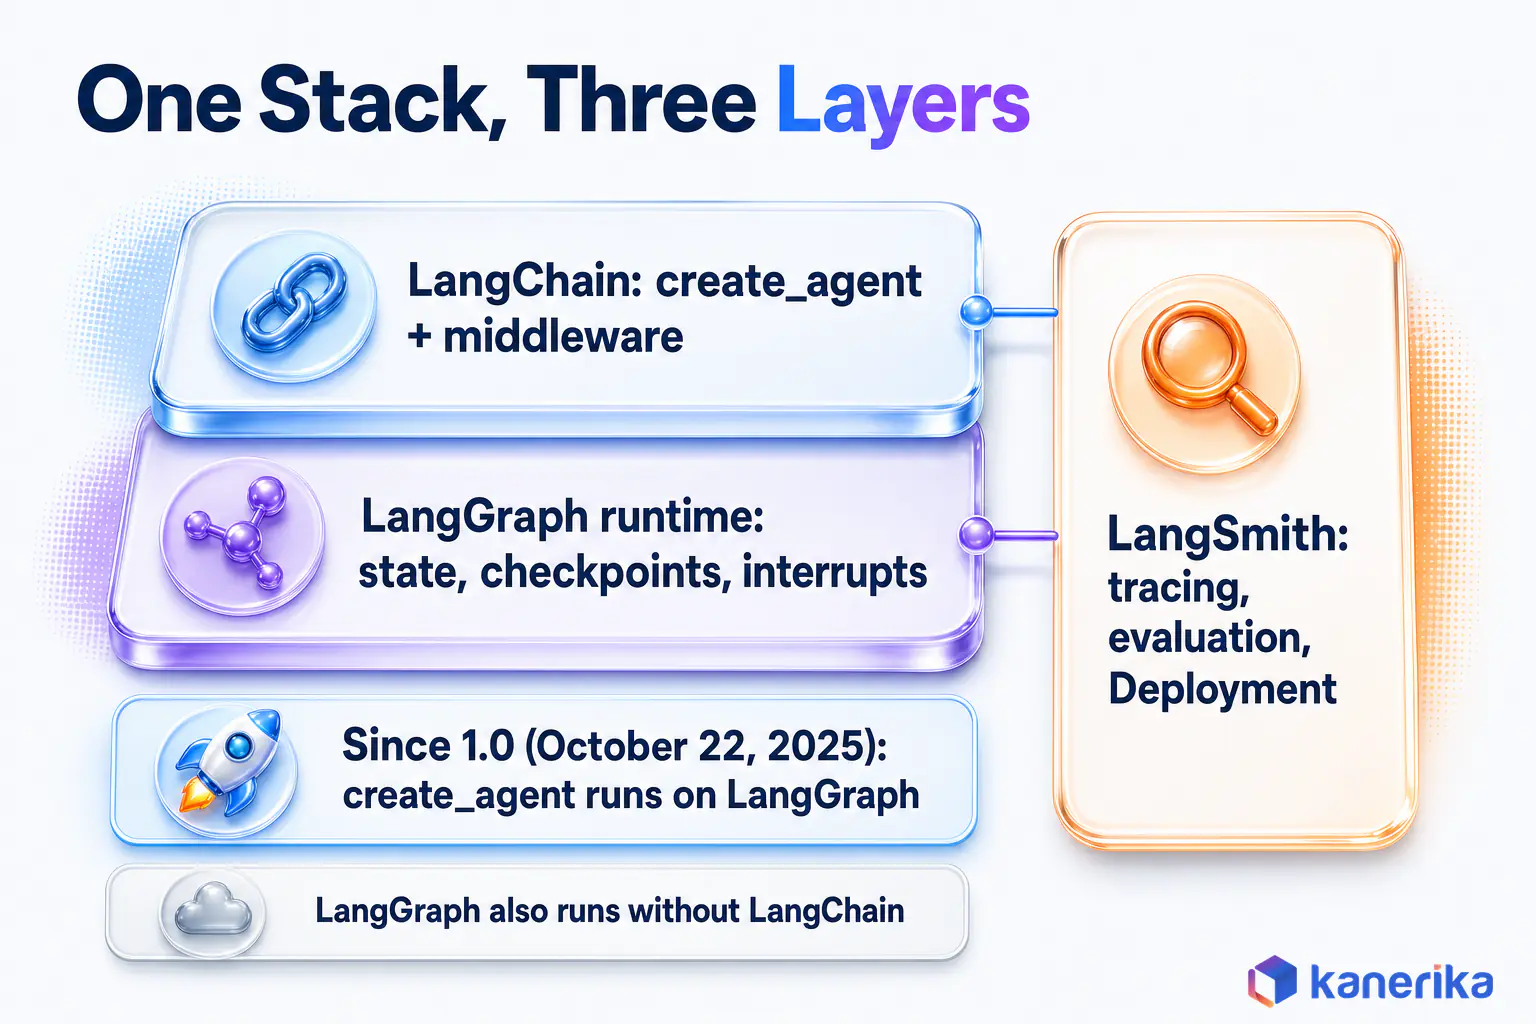
The simplest way to see the relationship is as a stack of three layers. LangChain sits on top, LangGraph runs underneath it, and LangSmith watches both.
According to the 1.0 announcement, create_agent is “built on the LangGraph runtime”. So when you call create_agent, you already get a compiled LangGraph graph with checkpoint support. Choosing LangChain first therefore never locks you out of LangGraph later.
The reverse also holds. LangGraph works without LangChain at all, so a team can call model SDKs directly inside its nodes and still use checkpoints and interrupts.
A common path combines the two. A team builds a research agent with create_agent, then drops that agent into a larger StateGraph as one node. The graph handles approvals and retries around it, while the inner agent keeps its simple loop.
LangSmith is the third layer, and it is a commercial product rather than a library. It traces runs, scores them in evaluations and hosts agents through LangSmith Deployment. In October 2025, LangChain renamed LangGraph Platform to LangSmith Deployment and LangGraph Studio to LangSmith Studio, as its changelog notes. Pricing and APIs did not change.
Seen this way, the framework question becomes an architecture question. Our AI agent architecture guide covers where memory, tools and control logic should live.
LangChain vs LangGraph: Core Differences
The two frameworks differ mainly in how much of the agent’s behavior you write down yourself. LangChain picks sensible defaults for the loop, while LangGraph makes you state every step and transition.
For example, a tool-calling assistant shows the gap well. In LangChain it is one create_agent call, whereas in LangGraph the same assistant is a small graph you assemble node by node. The table below compares ten areas, and later sections refer back to it.
Table 1: LangChain vs LangGraph across ten areas, checked November 3, 2026 against the official docs.
| Area | LangChain | LangGraph |
|---|---|---|
| Purpose | Build agents and LLM apps quickly | Orchestrate long-running, stateful agents |
| Abstraction level | High: the loop is built for you | Low: you define every node and edge |
| Main API | create_agent | StateGraph |
| Control flow | The model chooses the next tool | Your edges and routing functions choose |
| State | Message history plus optional custom fields | Any typed schema you design |
| Persistence | Pass a checkpointer to create_agent | Checkpointer per graph, state saved after each step |
| Human approval | Human-in-the-loop middleware on tool calls | interrupt() at any node, resume with Command |
| Multi-agent | Agents can call other agents as tools | Supervisors, subgraphs and explicit handoffs |
| Debugging | LangSmith traces of each model and tool call | LangSmith traces plus Studio graph view and state replay |
| Learning curve | Hours for a first agent | Days to design state and edges well |
Read the table as a ladder rather than a scorecard. Each LangGraph cell spells out what LangChain leaves to its defaults or to your own code. So the real question is whether those defaults still fit your workflow.
When they stop fitting, the change is usually visible in the requirements first. Someone asks for an approval step, a retry policy or an audit log, and the hidden loop becomes a liability.
Checklist
Check Your Agentic AI Readiness
Score your data, tools, approvals and governance before an agent reaches production.
Get the Checklist →LangChain vs LangGraph: The Code Difference
Code makes the trade-off concrete. Below is the refund agent from the opening, written once with create_agent and once as a StateGraph.
Both snippets are illustrative, not benchmarked. The helpers lookup, refund_amount_for and payments stand in for your own code, and the model string is any provider id your account can call.
# Illustrative, not benchmarked: LangChain 1.x create_agent
from langchain.agents import create_agent
from langchain.agents.middleware import HumanInTheLoopMiddleware
from langgraph.checkpoint.memory import InMemorySaver

def search_help_center(query: str) -> str:
    """Return the top help-center article for a query."""
    return lookup(query)

def issue_refund(ticket_id: str, amount: float) -> str:
    """Refund a customer for a ticket."""
    return payments.refund(ticket_id, amount)

agent = create_agent(
    model="anthropic:YOUR_MODEL_ID",  # any provider, selected by API id
    tools=[search_help_center, issue_refund],
    system_prompt="Resolve support tickets politely and briefly.",
    middleware=[HumanInTheLoopMiddleware(interrupt_on={"issue_refund": True})],
    checkpointer=InMemorySaver(),
)

agent.invoke(
    {"messages": [{"role": "user", "content": "Please refund ticket 4812."}]},
    config={"configurable": {"thread_id": "ticket-4812"}},
)
That is a complete agent with an approval gate on one tool. The middleware pauses before issue_refund runs, and a person can then approve, edit or reject the call.
However, what you cannot easily express here is the business rule itself. “Only refunds above $100 need approval” ends up inside a prompt or a custom middleware, rather than in a visible step.
# Illustrative, not benchmarked: the same flow as a LangGraph StateGraph
from typing import TypedDict
from langgraph.graph import StateGraph, START, END
from langgraph.checkpoint.memory import InMemorySaver
from langgraph.types import interrupt, Command

class TicketState(TypedDict, total=False):
    ticket_id: str
    amount: float
    approved: bool
    reply: str

def assess(state: TicketState) -> dict:
    return {"amount": refund_amount_for(state["ticket_id"])}

def route(state: TicketState) -> str:
    return "approval" if state["amount"] > 100 else "refund"

def approval(state: TicketState) -> dict:
    decision = interrupt({"ticket": state["ticket_id"], "amount": state["amount"]})
    return {"approved": decision == "approve"}

def refund(state: TicketState) -> dict:
    if state.get("approved", True):
        payments.refund(state["ticket_id"], state["amount"])
        return {"reply": "Your refund is on its way."}
    return {"reply": "A manager declined this refund."}

builder = StateGraph(TicketState)
builder.add_node("assess", assess)
builder.add_node("approval", approval)
builder.add_node("refund", refund)
builder.add_edge(START, "assess")
builder.add_conditional_edges("assess", route, ["approval", "refund"])
builder.add_edge("approval", "refund")
builder.add_edge("refund", END)
graph = builder.compile(checkpointer=InMemorySaver())

config = {"configurable": {"thread_id": "ticket-4812"}}
graph.invoke({"ticket_id": "4812"}, config)      # pauses at the approval node
graph.invoke(Command(resume="approve"), config)  # resumes after the manager answers
The graph version takes more code. In exchange, the $100 rule is a routing function you can unit-test, and the pause happens at a named step with the full state saved.
In production, you would also swap InMemorySaver for the Postgres checkpointer. Then the second invoke works even if it runs on a different server, days after the first.
Kanerika Service
Plan a Production AI Agent
Kanerika scopes the workflow, designs approval points and builds agents on the right layer of the stack.
Explore Agentic AI ServicesMigrating from AgentExecutor and create_react_agent
Many live apps still run on pre-1.0 patterns. AgentExecutor now lives in langchain-classic, and the LangChain release policy keeps LangChain 0.3 in maintenance until December 2026, with security patches and critical fixes only.
That leaves a short runway, so a staged path works better than a big-bang rewrite. A sequence that keeps risk low looks like this.
- Pin and inventory. List every AgentExecutor, legacy chain and create_react_agent call, and pin current versions.
- Switch imports to langchain-classic. Old code keeps working on 1.x while you plan the real move.
- Rebuild simple agents with create_agent. Move tools and prompts across, and replace custom callbacks with middleware.
- Move stateful flows to a StateGraph. Anything with approvals, retries or long waits becomes explicit nodes with a checkpointer.
- Compare traces before cutover. Run old and new versions on the same recorded inputs in LangSmith, then retire the classic code.
As a rule, simple agents finish their move at step 3. Only the few with real workflow logic need the graph treatment.
State, Memory and Persistence Compared
State is what an agent knows right now, and persistence is whether that knowledge survives the request. The two frameworks share the same machinery here, but they expose different amounts of it.
To make this concrete, think of three layers of memory. Short-term state is the message list and fields inside one run. Checkpointed threads save that state after every step, so a conversation can continue tomorrow. A long-term store keeps facts across threads, such as a customer’s preferred language.
With create_agent, short-term state is mostly the message history, and you add a checkpointer to keep threads. With a StateGraph, by contrast, you design the state schema yourself. The ticket amount, approval flag and retry count then become typed fields, not text buried in messages.
That difference also matters for cost and accuracy. Typed fields keep prompts short, because the agent does not reread a long transcript to find one number. Our context engineering guide explains how to decide what goes into the prompt at each step.
The long-term store, on the other hand, solves a different problem. Suppose the refund agent learns that a customer prefers email over chat. Saving that fact in the store lets next month’s ticket start with it, even though the old thread is long closed.
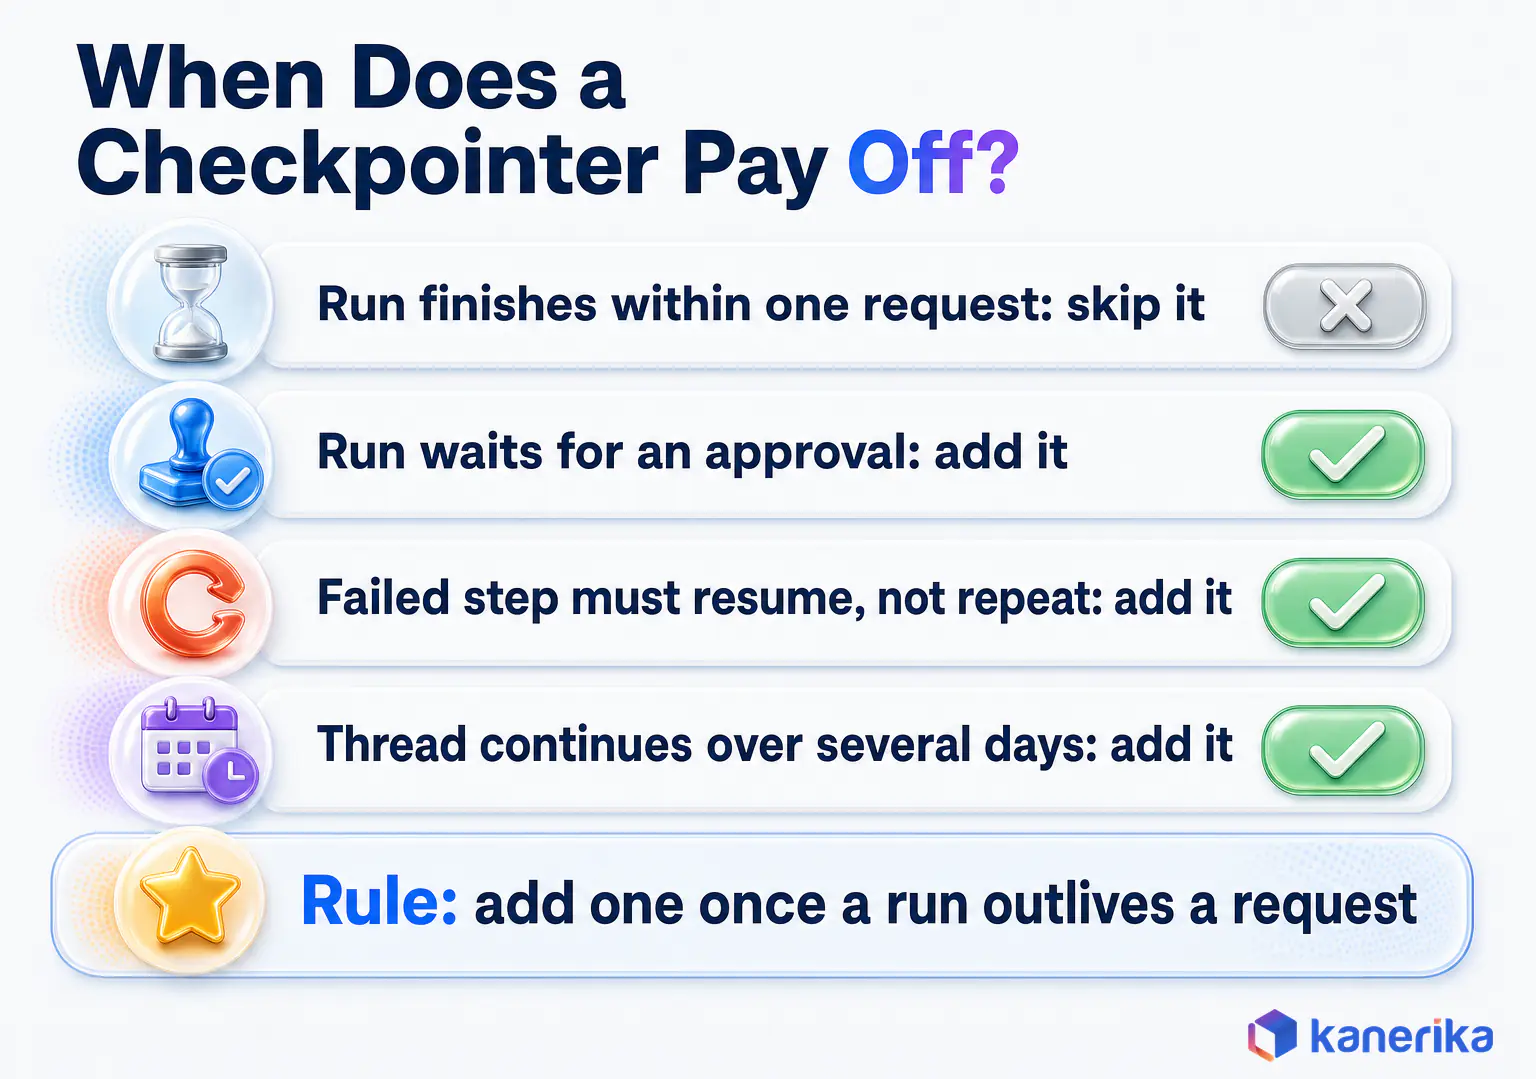
Persistence is not free, though. Each checkpoint is a database write, and a Postgres checkpointer adds a table to back up, secure and clean. So for a stateless question-and-answer bot, that overhead buys nothing.
The useful rule, therefore, is simple. Add a checkpointer once a run can outlive one request: approvals, retries after failure, or threads that continue over several days.
Human-in-the-Loop, Failure Recovery and Governance
Production agents need a way for people to step in, a way to recover from failures and a record of what happened. Both frameworks cover the first need, but LangGraph covers the other two in far more depth.
Approvals in Each Framework
LangChain’s human-in-the-loop middleware works at the tool-call level. Before a chosen tool executes, the run pauses, and a reviewer can approve, edit or reject the call. For the refund agent, that is enough when every refund needs a look.
LangGraph interrupts, by contrast, work at any node. You can pause before a refund, after a draft reply or when a confidence score drops, and you can show the reviewer the full state. Because the state is checkpointed, the reviewer can answer an hour or a week later.
Recovery, Retries and Audit Trails
Failure recovery follows a similar pattern. If a payment API times out on step four, a checkpointed graph resumes at step four instead of starting over. That avoids repeated tool calls, which can mean duplicate refunds or emails.
Retries also become a design choice. For example, a graph can send a failed call to a retry node that counts attempts. After the third attempt, it routes the ticket to a human instead. In a plain loop, that policy usually hides in exception handlers that nobody reviews.
Governance teams also care about the trail. Every checkpoint records a state transition, so you can replay who approved what and what the agent saw at that moment. Our agentic AI governance guide shows how to turn that trail into policy.
For a reference framework, many teams map controls to the NIST AI Risk Management Framework. AI RMF 1.0 was released on January 26, 2023, and its Generative AI Profile, NIST-AI-600-1, followed on July 26, 2024.
Five Controls to Put in Place
For an agent team, five controls cover the day-to-day side of that mapping.
- Approval points on every irreversible action, through middleware or an interrupt.
- Scoped tools that can only reach the data and systems a task needs.
- Checkpointed state so failed runs resume instead of repeating side effects.
- Traces and audit logs kept for every run, with reviewer decisions attached.
- Output checks such as the AI guardrails that block unsafe replies before they reach a user.
None of these controls requires LangGraph on day one. Still, they get easier once each step and decision is a named node rather than a hidden turn inside a loop.
Which Framework Fits Which Workflow?
The best way to choose is to describe the workflow first and the framework second. Ask how long a run lasts, who must approve it and what happens when a step fails.
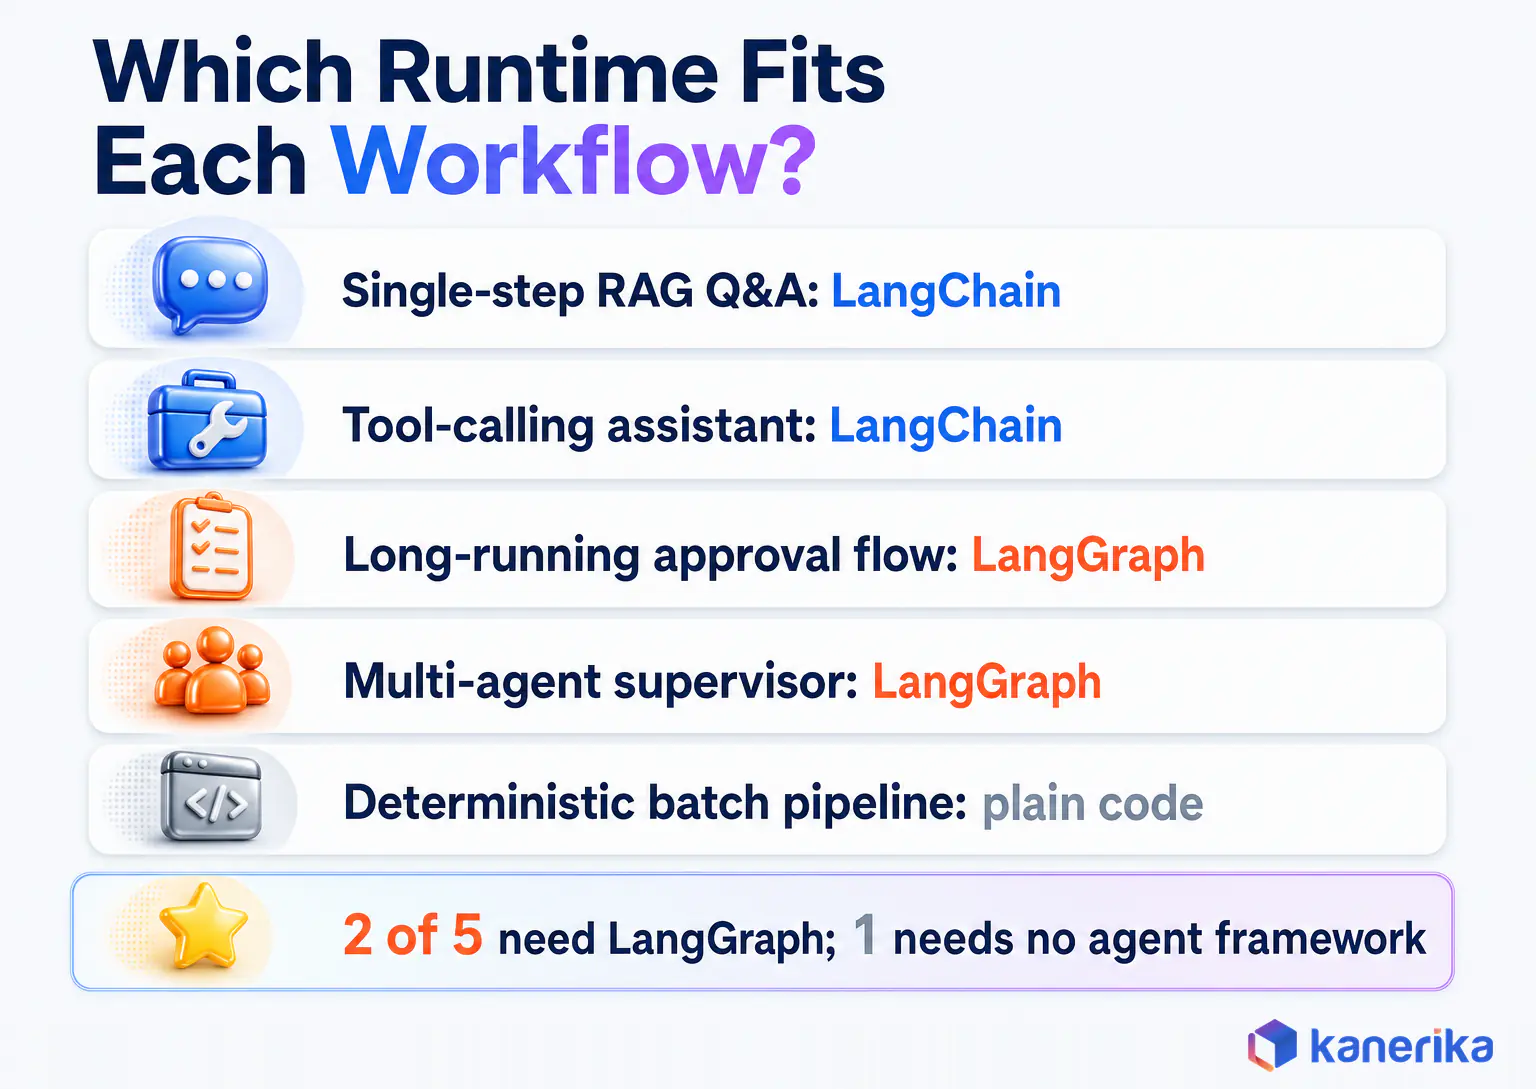
For instance, a document question-and-answer bot answers within seconds and holds no state between calls. A procurement agent that waits for two approvals over three days is a different animal, even if both call the same model.
Table 2: LangChain vs LangGraph by workflow type, with the reason for each pick.
| Workflow | Pick | Why |
|---|---|---|
| Single-step RAG question answering | LangChain | One retrieval and one answer per request; no state to keep |
| Tool-calling assistant | LangChain | create_agent runs the loop; middleware adds approval on risky tools |
| Long-running approval flow | LangGraph | Interrupts and checkpoints let a run wait days and resume safely |
| Multi-agent supervisor | LangGraph | Explicit handoffs and shared state between specialist agents |
| Deterministic batch pipeline | Neither: plain code | Fixed steps need a scheduler, not an agent framework |
Two of the five rows land on LangGraph, and one needs no agent framework at all. Retrieval-heavy agents that plan several searches sit between the first two rows, which our agentic RAG guide covers.
The supervisor row deserves a note. Picture a claims workflow where one agent reads documents, another checks policy rules and a supervisor decides who works next. LangGraph models each agent as a node and the supervisor as a router, so every handoff is visible in the trace.
Our guide to multi-agent AI systems explains when splitting work across agents beats one larger agent.
Choose LangChain When
LangChain is the faster path whenever the defaults match the job. These four cases are the clearest fits.
- The agent answers within one request and keeps no state between calls.
- Approval is needed only on specific tool calls, which middleware already handles.
- You want to trial several models quickly by swapping one model id.
- The team is new to LLM apps and needs a working prototype this sprint.
Choose LangGraph When
LangGraph earns its extra code when the workflow itself is the product. These four cases point to it.
- A run must pause for a person and resume hours or days later.
- Business rules decide the next step, and auditors need to see those rules.
- Failed steps must resume from a checkpoint without repeating side effects.
- Several agents hand work to each other, as in the multi-agent workflows we describe elsewhere.
When a Different Framework Fits
Sometimes neither layer of the LangChain stack is the right home. A few alternatives come up often in the same evaluations.
PydanticAI is an MIT-licensed agent framework marked Production/Stable on PyPI, at version 2.65.0 as of November 3, 2026. Teams that already validate data with Pydantic, for example, often like its typed style.
The OpenAI Agents SDK is also MIT-licensed. It first appeared on PyPI in March 2025 and reached version 0.24.0 on October 15, 2026. Our OpenAI AgentKit overview covers the wider OpenAI tooling.
For conversation-style multi-agent systems, see our AutoGen vs LangChain comparison and the CrewAI, AutoGen and Microsoft Agent Framework comparison. Teams on Microsoft’s stack should also read Semantic Kernel vs LangChain.
If the project is mostly search over documents, our review of LlamaIndex, LangChain and Haystack for RAG is the better starting point. Even then, the agent layer often ends up on LangChain or LangGraph.
LangChain vs LangGraph: Pros, Cons and Limitations
Each framework’s strengths are the other’s costs. The table pairs them so you can weigh them against your own workflow.
Table 3: Pros and cons of each framework as of November 2026.
| Framework | Pros | Cons |
|---|---|---|
| LangChain | Fast start with create_agent; many provider packages; middleware for approval; no breaking changes until 2.0 | Hidden loop limits custom control flow; business rules drift into prompts; history of API churn before 1.0 |
| LangGraph | Explicit state and routing; checkpoints and interrupts at any node; resumable runs; testable nodes | More boilerplate; state design takes skill; persistence adds a database to run |
Three limitations are worth planning for: one per framework and one shared. First, LangChain’s API changed often before 1.0, so many online examples still use deprecated calls such as create_react_agent. Second, graph code grows quickly, and a large StateGraph without naming rules becomes hard to read. Third, debugging either framework without tracing is slow, because the interesting behavior lives inside model calls you cannot step through.
Fortunately, the 1.x stability promise eases the first problem. Code review rules handle the second, and a tracing tool such as LangSmith handles the third.
Performance is a related worry, and the honest answer depends on the workflow. A checkpoint write after every step adds some latency and storage, which a one-shot answer does not need. On the other hand, for a run that may fail halfway, that same overhead is what saves you from starting over.
Talk to Kanerika
Talk to Kanerika About Your Agent Architecture
Get a working plan for create_agent, LangGraph or both, matched to your workflows and approval points.
Talk to Kanerika →Testing, Observability and Cost in Production
An agent is only as good as your ability to see and measure it. So testing, tracing and cost tracking deserve as much design time as the framework choice.
Testing Nodes and Tracing Runs
LangGraph nodes are plain functions, which makes them easy to test. LangChain agents are harder to unit-test, so teams lean on traces and evaluations instead.
- Unit-test routing and nodes. Call the route function with sample states and assert the next node, with no model involved.
- Record and replay runs. Save real inputs and outputs in LangSmith so every change runs against the same cases.
- Score traces with evaluations. Grade tool choice, final answers and step counts on a fixed test set, as our AI agent evaluation guide explains.
- Watch production traces. Alert on failed tools, long runs and cost spikes, using the patterns in our AI agent observability and LLMOps observability guides.
The first item is where LangGraph pays back its extra code. A routing function such as route() in the refund example can be tested in milliseconds, with no API key and no model bill.
How to Run Your Own Comparison
Published speed claims rarely match your workload, so test the two frameworks on your own task. This method keeps the comparison fair, and it reports no results of ours.
- Pick one real task, such as the refund flow, and write 30 or more test inputs with expected outcomes.
- Build it twice, once with create_agent and once as a StateGraph, using the same model and prompts.
- Measure steps per run, input and output tokens, and end-to-end latency for each input.
- Inject failures, such as a tool timeout on step three, and record which version recovers without repeating work.
- Count lines of code and review time, then weigh those costs against the reliability gap you measured.
Then read the results per workflow, not as one winner. If both versions pass the same cases at similar cost, keep create_agent and its smaller codebase. If the graph recovers from failures that break the loop, the extra code has earned its place.
What It Costs to Run Them
Both libraries cost nothing to use, since LangChain and LangGraph are open source under the MIT license. Instead, the bills come from LangSmith, if you use it, and from model tokens.
The LangSmith pricing page lists a free Developer plan with one seat and up to 5,000 base traces a month. The Plus plan costs $39 per seat a month, includes up to 10,000 base traces and adds LangSmith Deployment. Enterprise pricing is custom, and usage above each allowance is pay as you go.
Model tokens usually dominate the bill, and an LLM gateway is the usual place to control them. A gateway gives one place to cap spend, log every model call and route cheap steps to cheaper models. The episode below covers how gateways make enterprise AI safer.
Prices differ widely by model, so the model choice moves the bill far more than the framework does. Table 4 shows list prices for current models.
Table 4: Model prices per million tokens, input and output, as of November 2, 2026.
| Model | Input per 1M tokens | Output per 1M tokens | Note |
|---|---|---|---|
| Claude Opus 5.5 | $4 | $20 | 1M-token context |
| Claude Sonnet 5.5 | $2 | $10 | 1M-token context |
| Claude Haiku 5.5 | $0.10 | $0.50 | Price for prompts up to 100K tokens; 1M-token context |
| GPT-6.1 Sol | $2 | $10 | 1,050,000-token context |
| GPT-6 Luna | $0.10 | $0.50 | Low-cost tier |
| Gemini 4 Argon | $2 ($4 from December 1, 2026) | $10 ($20 from December 1, 2026) | Lower price runs through November 30, 2026 |
| Gemini 3.8 Flash | $0.75 | $3.75 | Listed price through December 31, 2026 |
A Worked Cost Estimate
A quick estimate shows why tokens dominate. For example, assume one agent run uses 20,000 input tokens and 2,000 output tokens. On Claude Sonnet 5.5 that costs $0.04 plus $0.02, or $0.06 a run, so 10,000 runs a month come to $600.
By contrast, the same volume on Claude Haiku 5.5 costs $0.003 a run, or $30 a month. Next to either figure, a $39 LangSmith seat is small, and the framework itself adds nothing.
LangGraph can move the token bill in both directions. Typed state keeps prompts lean, while extra nodes may add model calls. Our AI agent development cost guide breaks down the full budget, from build effort to monthly run costs.
How Kanerika Builds Production AI Agents
Kanerika builds agents for enterprises as a delivery partner, and the framework is one decision inside a larger method. Our agentic AI services follow four stages, each of which shapes the LangChain vs LangGraph choice.
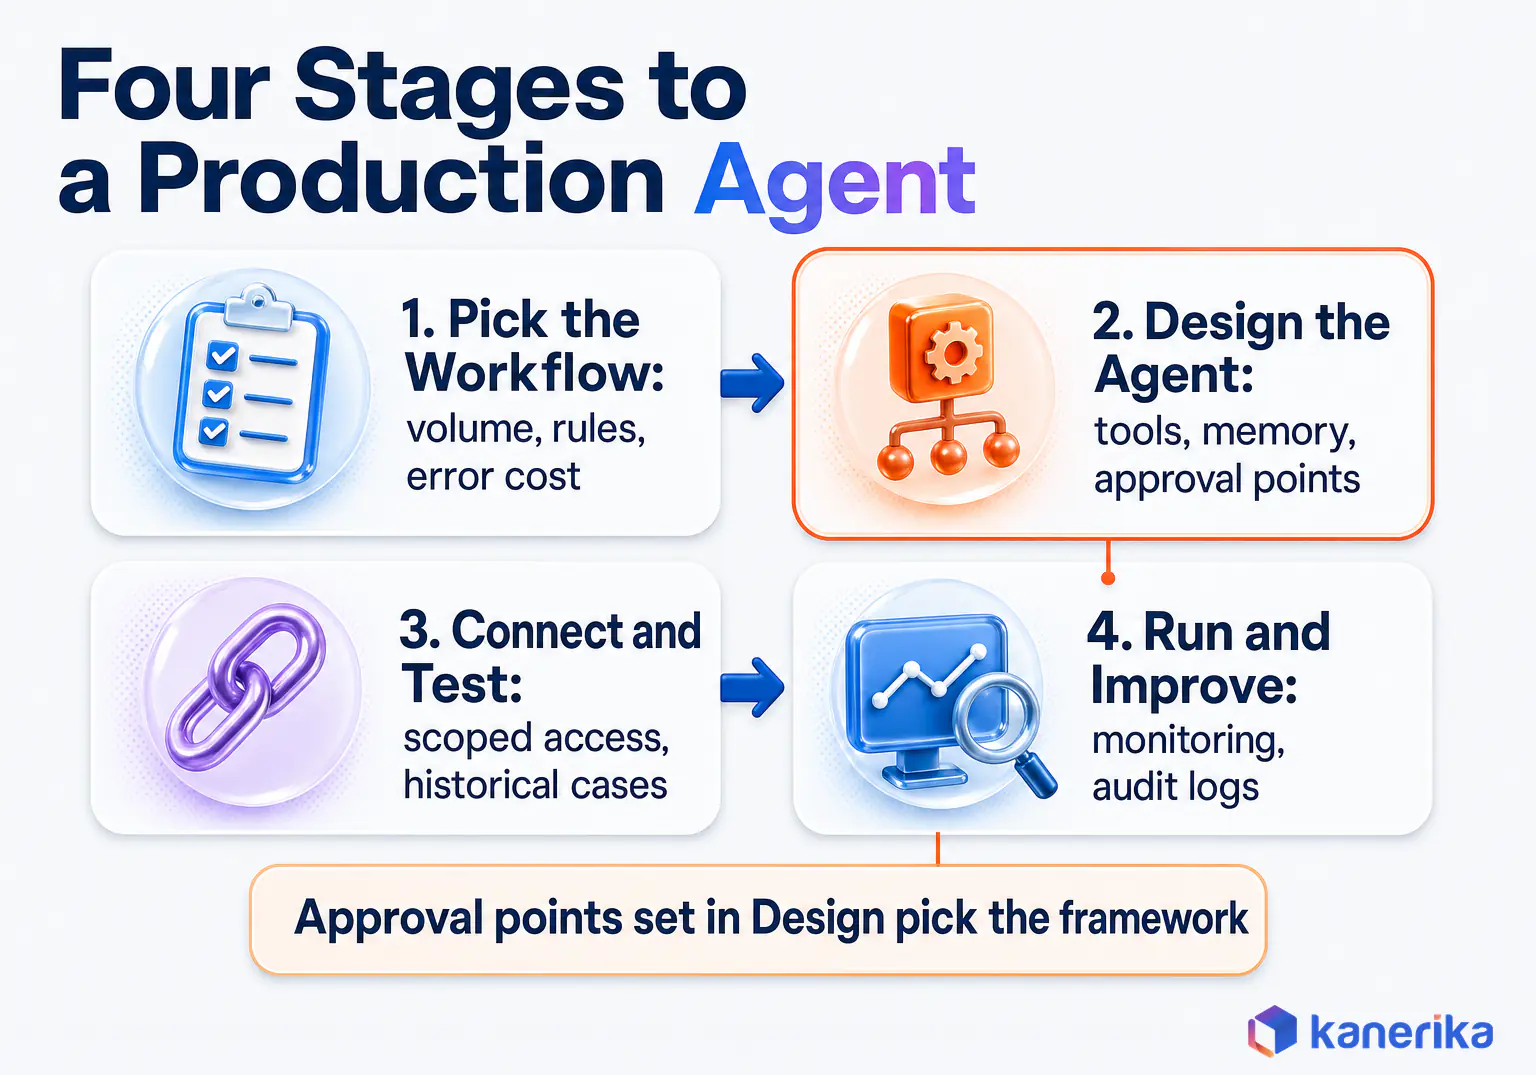
Four Stages, From Workflow to Running Agent
- Pick the Workflow. Rank candidates by volume, clear rules and the cost of errors, and start where a baseline is measurable.
- Design the Agent. Decide the tools it can call, what it remembers and where a person approves.
- Connect and Test. Give scoped access to ERP, CRM and documents, and score the agent on historical cases before go-live.
- Run and Improve. Add monitoring, audit logs and a review loop once the agent is live.
In practice, the Design stage is where the framework gets chosen. If the agent needs a short approval point, it becomes HITL middleware on one tool. For a long wait, it becomes a LangGraph interrupt with a checkpoint instead. For custom model work behind the agent, our LLM development team handles fine-tuning and private deployments.
Proof: 43% Faster Retrieval for an Investment Bank
Kanerika’s own agents run in client deployments. KlarityIQ handles document intelligence, Karl answers questions over data, and Klara supports compliance work. The company holds ISO 27001 and ISO 27701 certification, SOC 2 Type II attestation and CMMI Level 3.
For example, one investment bank needed fast answers across unstructured RFI documents and structured databases. Kanerika deployed KlarityIQ for the documents and Karl for database queries, through chat interfaces that share one interaction model, with role-based access control applied at the retrieval layer.
The investment bank case study reports “43% faster information retrieval across documents and databases” and “100% role-based compliance achieved at the point of retrieval”. It also reports a “35% improvement in workforce efficiency”.
The design choice behind those numbers also applies to any agent framework. Access rules were enforced where data is fetched, so the chat layer never had to decide who may see what. The same placement works for a create_agent tool or a LangGraph node.
Guidance From Our Agent Projects
Three habits carry over to any LangChain or LangGraph build. First, put access control inside the retrieval and tool layer, not around the agent. That way, a clever prompt cannot reach data the user may not see.
Second, decide approval points before choosing the framework. The number and length of those pauses usually settles the choice on its own.
Third, keep business logic in plain functions. Nodes then stay small and testable, and the same rules can move between create_agent and a StateGraph without a rewrite.
Case Study
43% Faster Document Retrieval for an Investment Bank
KlarityIQ and Karl behind one chat interface, with role-based access control applied at the retrieval layer.
Read the Case Study →Wrapping Up
LangChain and LangGraph are two layers of the same stack, so the choice is about control rather than loyalty. Start with create_agent when a run finishes in one request, and use the decision table above to spot the workflows that need more.
Then move to a StateGraph when the agent must wait for people, resume after failures or coordinate other agents. For your own workflows, the LangChain vs LangGraph answer is the layer that matches how much control each run needs.
Frequently Asked Questions
Is LangGraph replacing LangChain?
No. LangGraph is the runtime underneath LangChain. Since the 1.0 releases on October 22, 2025, LangChain’s create_agent runs on LangGraph. LangChain stays the faster way to build a standard agent. LangGraph is the layer you use for explicit state, branching and checkpoints. Both projects come from the same team, and both follow a stable 1.x release line.
Can I use LangChain and LangGraph together?
Yes, and most production teams do. You can build an agent with create_agent and add it to a StateGraph as one node. The graph then handles approvals, retries and checkpoints around it. LangChain provider packages and tools also work inside any LangGraph node. LangSmith traces both layers in the same run, so debugging stays in one place.
Does moving from LangChain to LangGraph require a full rewrite?
No. Tools, prompts and provider packages carry over unchanged. A create_agent agent can even run as a single node inside a new StateGraph. You then pull the parts that need control, such as approvals or retries, into their own nodes. Keeping business logic in plain functions makes this step small. Most teams migrate one workflow at a time.
Which is better for multi-agent systems?
LangGraph is usually the better fit for multi-agent systems. It models each agent as a node and a supervisor as a router, with shared typed state. Handoffs are explicit, so traces show which agent did what. LangChain can still let one agent call another as a tool. That simpler pattern suits small setups of two or three agents.
Are LangChain and LangGraph free to use?
Yes. Both libraries are open source under the MIT license, so there is no fee to use them. LangSmith is a separate paid product with a free Developer plan. That plan has one seat and up to 5,000 base traces a month. Model tokens are billed by your model provider and usually make up most of the cost.
Can you use LangGraph without LangChain?
Yes. LangGraph is a standalone library under the MIT license. Nodes are plain Python functions, so they can call any model SDK, database or API directly. You still get typed state, conditional edges, checkpoints and interrupts. Many teams add LangChain later only for its provider packages or tool helpers. Installing langgraph alone is enough to build and run a graph.
What is the performance difference between LangChain and LangGraph?
There is no fixed speed gap, because create_agent already runs on the LangGraph runtime. The real difference is the overhead you choose to add. Checkpoints write state after each step, which adds some latency and storage. In exchange, a failed run resumes instead of restarting. Measure steps, tokens and latency on your own workflow before deciding which to use.
Is AgentExecutor still usable after LangChain 1.0?
Yes, through the langchain-classic package. AgentExecutor and the older chains moved there in the 1.0 release. LangChain 0.3 stays in maintenance until December 2026, with security patches and critical fixes only. New code should use create_agent instead. Plan a staged migration, and compare traces of the old and new versions in LangSmith before the final cutover.
What is LangSmith Studio, formerly LangGraph Studio?
LangSmith Studio is the visual debugger for LangGraph apps. It draws your graph, shows the state at each step and lets you re-run a thread from any step. LangChain renamed it from LangGraph Studio in October 2025. The tool and its pricing did not change with the new name. It also works with agents built using create_agent.
What is LangSmith Deployment, formerly LangGraph Platform?
LangSmith Deployment is the LangChain hosting service for running agents in production. It was called LangGraph Platform, and some older posts call it LangGraph Cloud. LangChain renamed it in October 2025 and kept pricing and APIs the same. The LangSmith Plus plan at $39 per seat a month includes Deployment. Self-hosting the open-source libraries remains an option.
How does human-in-the-loop work in LangChain and LangGraph?
In LangChain, human-in-the-loop middleware pauses before chosen tools run. A reviewer can approve, edit or reject each call. In LangGraph, an interrupt can pause the run at any node and show the full state. A checkpointer saves that state, so the reviewer can answer hours or days later. The run then resumes with a Command.
Which framework should teams new to LLM development start with?
Start with LangChain and its create_agent API. A first working agent needs only a model id, a few tools and a system prompt. That teaches tools, prompts and tracing without designing a graph. Once a workflow needs approvals, retries or long waits, move that part to LangGraph. The skills carry over because both share one runtime.
Is LangGraph production-ready?
Yes. LangGraph reached 1.0 on October 22, 2025, and the current release is langgraph 1.2.19 from October 30, 2026. It is MIT-licensed and listed as Production/Stable on PyPI. The 1.0 release came with a promise of no breaking changes until 2.0. LangChain also says companies such as Uber, LinkedIn and Klarna use LangGraph.