TL;DR
In the LlamaIndex vs LangChain vs Haystack choice, pick LlamaIndex for document-heavy retrieval, LangChain plus LangGraph for agents, and Haystack for auditable pipelines. No framework wins every workload, so the right pick follows your hardest problem. As of November 2026, the current releases are LlamaIndex 0.14.25, LangChain 1.4.8 and Haystack 3.4.1. All three libraries are free and open source under MIT or Apache 2.0 licenses. The real spend sits in managed platforms, model tokens and engineering time, and tight retrieval cuts the token bill most. Run a bake-off on your own corpus before you commit, and combine frameworks behind a thin interface when needs split.
Key Takeaways
- Start with LlamaIndex when your hardest problem is finding the right passage across thousands of documents.
- Build on LangChain with LangGraph when the work involves multi-step agents, tools and human approvals, then trace it in LangSmith.
- Choose Haystack when auditors need to see every step, because its typed components and explicit graph serialize to YAML.
- Budget for tokens before licenses. In this guide’s illustrative example, sending 3 chunks instead of 8 saves about $7,500 a month at 50,000 queries a day.
- Tutorials from 2024 and 2025 break on current releases, because Haystack 3.0 and LangChain 1.x removed or moved older classes.
- Decide on evidence from a bake-off on your own corpus, and combine frameworks at a clean seam when one cannot cover every need.
Not Sure Which RAG Framework Fits Your Workload?
Picture a legal operations team with 40,000 supplier contracts in a shared drive. Their first goal is simple, at least on paper. Lawyers want to ask which agreements carry an uncapped indemnity and then get a cited answer in seconds.
Their second goal sits further out on the roadmap: an agent that drafts renewal notices and routes each one to a manager for approval. Those two goals pull toward different tools, and a regulated buyer will also ask how every answer was produced.
The retrieval problem rewards deep indexing, the agent problem rewards orchestration, while the audit question rewards explicit pipelines. This guide weighs LlamaIndex vs LangChain vs Haystack against exactly that mix. It also uses current versions, real platform prices and a method for testing on your own data.
What Each RAG Framework Was Built to Do
Each framework started from a different problem, and that origin still shapes what it does best. Knowing the design center also tells you where a framework feels easy and where you will write glue code yourself.
If you are still deciding whether retrieval belongs in your stack at all, our guide to RAG vs LLM covers that earlier question. The three sections below assume you have already chosen retrieval-augmented generation, so they skip that debate.
1. LlamaIndex: Built for Retrieval Precision
LlamaIndex began as a way to connect language models to private data, and retrieval is still its center of gravity. It also ships data connectors for common sources, several index types and query engines that combine retrieval, reranking and answer synthesis in a few lines.
Its cloud companion, LlamaParse, turns messy PDFs with tables and images into clean text and structure before indexing. The library is MIT licensed, and version 0.14.25 shipped on September 21, 2026, according to the llama-index release page on PyPI.
For this reason, teams whose work lives in documents usually find LlamaIndex the shortest path to accurate answers. The LlamaIndex documentation walks through each index type and when to use it.
2. LangChain and LangGraph: Built for Workflow Composability
LangChain grew up as a toolkit for chaining model calls, prompts and tools, and it also has the largest integration catalog of the three. Its expression language, LCEL, pipes components together, so a retriever, a prompt and a model become one runnable chain.
For anything stateful, the project pairs LangChain with LangGraph. LangGraph models an agent as a graph of steps with saved state, and it can also pause a run for human review. LangSmith then adds tracing and evaluation on top of both.
LangChain 1.4.8 shipped on November 2, 2026, per its PyPI page. LangGraph 1.2.19 shipped on October 30, 2026, per the LangGraph release page, and both also use the MIT license.
3. Haystack: Built for Production Pipelines
Haystack, maintained by deepset, treats a RAG system as a pipeline of typed components joined in an explicit graph. Every connection is declared, so the pipeline can be validated before it runs and serialized to YAML for review and version control.
That design makes Haystack the easiest of the three to audit, because the file that runs in production is the file a reviewer reads. Haystack 3.4.1 shipped on October 21, 2026 under Apache 2.0, per the haystack-ai package page. For teams that want hosting, deepset also sells a managed platform.
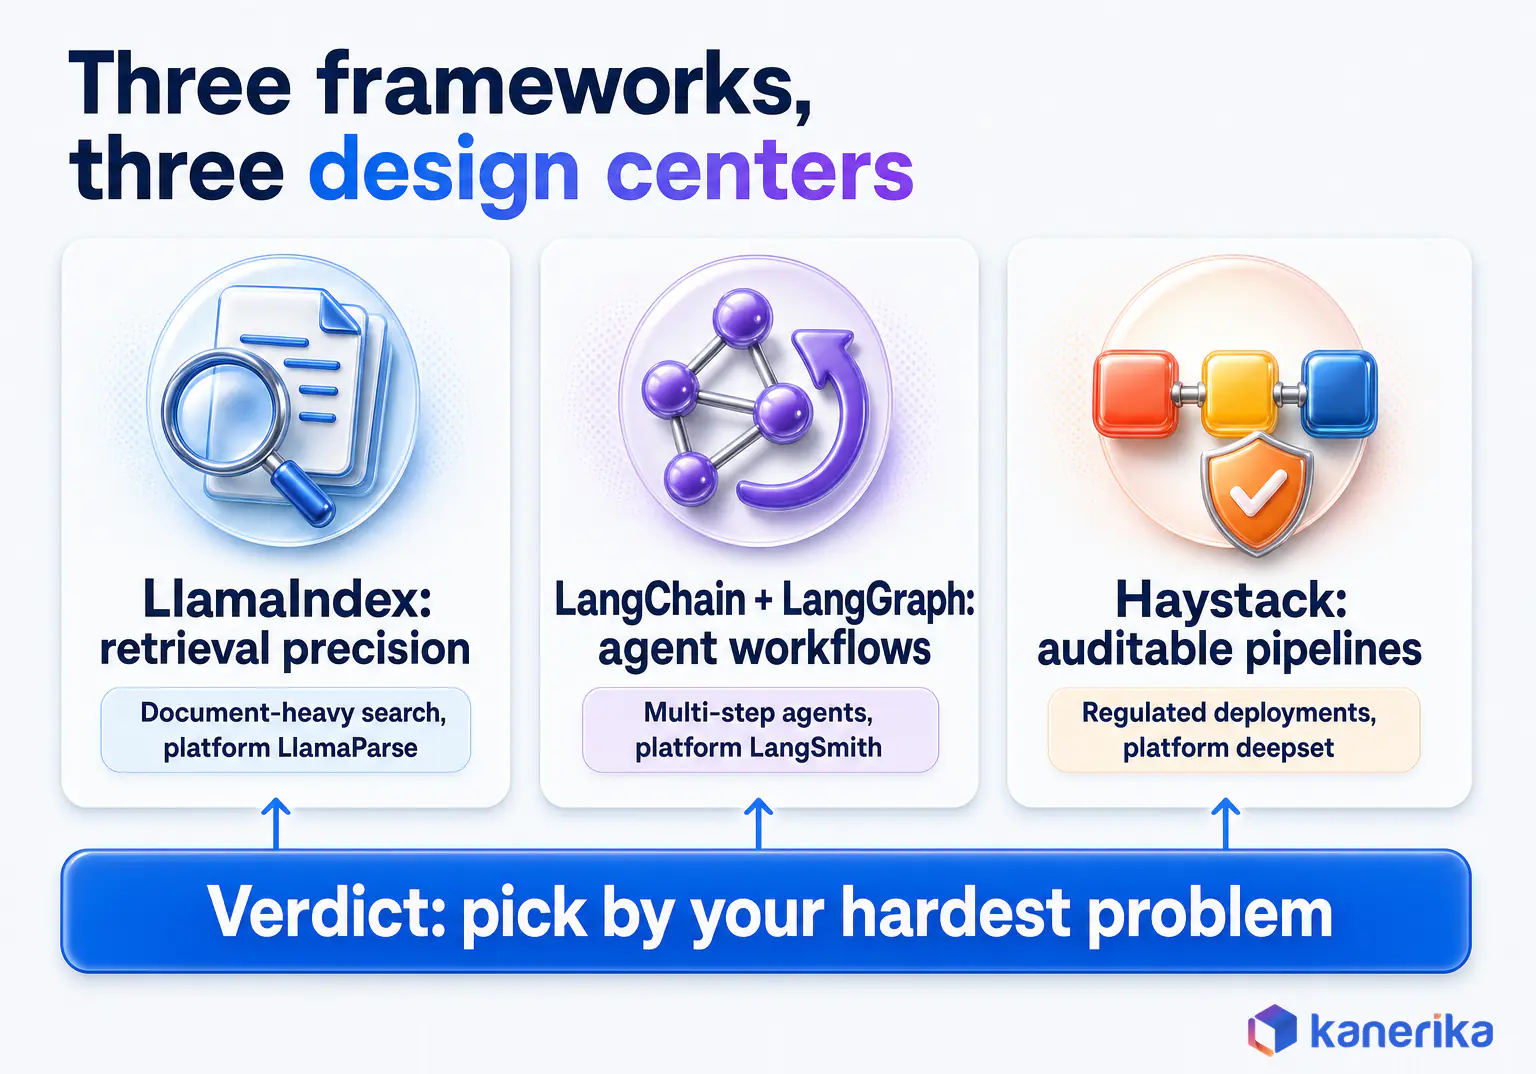
LlamaIndex vs LangChain vs Haystack at a Glance
The short answer is that LlamaIndex leads on retrieval depth, LangChain on orchestration breadth and Haystack on pipeline transparency. All three can build a working RAG system, so the table shows where each one makes the job easier.
Treat the entries as an editorial reading of each project’s documented features, rather than benchmark results. For a deeper two-way view, see our LangChain vs LlamaIndex comparison.
| Dimension | LlamaIndex | LangChain + LangGraph | Haystack |
|---|---|---|---|
| Primary focus | Retrieval and indexing | Orchestration and integrations | Production pipelines |
| Architecture | Indexes and query engines | LCEL chains plus LangGraph graphs | Typed components in an explicit graph |
| Ingestion | Deep connectors, LlamaParse for complex PDFs | Broad document loader catalog | Converters and preprocessors as components |
| Hybrid retrieval | Built-in retriever options | Assembled from retrievers | BM25 and embedding retrievers plus a joiner |
| Reranking | Node postprocessors, cross-encoders | Compression retriever with rerank integrations | Ranker components |
| Agents | Agent workflows centered on retrieval | LangGraph, the most mature agent runtime here | Agent component with hooks (3.0) |
| State | Workflow context | Checkpointed graph state | Pipeline and agent state |
| Evaluation | Built-in evaluation modules | LangSmith datasets and evaluators | Evaluator components |
| Observability | Callbacks and third-party tracers | LangSmith | Opt-in tracing connectors (3.0) |
| Managed platform | LlamaParse cloud | LangSmith | deepset |
| License | MIT | MIT | Apache 2.0 |
| Best fit | Document-heavy knowledge bases | Multi-step agents and tool use | Regulated, audited deployments |
Read the table by your hardest requirement rather than by counting strengths. A team with clean data and complex workflows should weigh the agent row first, while a team with 40,000 scanned contracts should weigh ingestion.
How Mature Each Framework Is in Late 2026
Maturity here means release pace, license, community size and how often the API shifts under you. All three repositories had commits on November 3, 2026 and none is archived, so the real question is API stability.
| Signal | LlamaIndex | LangChain + LangGraph | Haystack |
|---|---|---|---|
| Latest release | 0.14.25 (September 21, 2026) | LangChain 1.4.8 (November 2, 2026), LangGraph 1.2.19 (October 30, 2026) | 3.4.1 (October 21, 2026) |
| License | MIT | MIT | Apache 2.0 |
| Python floor | 3.10 or later | 3.10 or later | 3.11 or later |
| GitHub stars, rounded (November 3, 2026) | About 53K | About 149K (LangGraph about 44K) | About 27K |
| Maintainer | LlamaIndex | LangChain | deepset |
| Managed platform | LlamaParse cloud | LangSmith | deepset Studio and Enterprise |
Breaking changes tell you more than stars do. Haystack 3.0, released on July 20, 2026, removed the legacy generators and TransformersSimilarityRanker. It also merged AsyncPipeline into Pipeline, made tracing opt-in and moved 30 components into integration packages, per the Haystack 3.0 release notes.
LangChain made a similar cut once it reached version 1. The LangChain v1 migration guide moves legacy retrievers and chains into a separate langchain-classic package and sets Python 3.10 as the floor.
Both moves are healthy signs, since the projects are paying down old design debt. They also mean a tutorial from 2024 or 2025 may fail on a fresh install, so pin versions and plan time for each upgrade. LlamaIndex still ships on a 0.x version line, which makes its changelog worth reading before every minor upgrade.
Kanerika Service
RAG Development Services
Weighing LlamaIndex, LangChain and Haystack for production? Kanerika designs, builds and hardens enterprise RAG, from bake-offs to tracing and access control.
Explore RAG DevelopmentWhy Retrieval Quality Decides RAG Accuracy
A RAG system can only answer as well as the passages it retrieves. When the wrong chunks reach the model, it writes a fluent, confident answer from the wrong evidence. That is how many AI hallucinations start in enterprise search.
Consider, for example, a pharmacist asking about contraindications for Drug X. If retrieval returns the dosage page and misses the warnings page, no prompt or model upgrade will fix the answer afterward. Retrieval quality comes from two decisions: how you chunk and index the content, and how you search and rerank it.
Chunking and Indexing
Chunking decides what a single retrievable unit looks like. Small chunks match precisely but lose context, while large chunks keep context but dilute the match and cost more tokens per query.
LlamaIndex has the most built-in options here, such as hierarchical and sentence-window parsers that retrieve a small match and expand it to the surrounding text. LangChain covers similar ground, though with text splitters you assemble yourself. Haystack exposes splitting as a DocumentSplitter component, so the chunking rule sits visibly in the pipeline.
Hybrid Search and Reranking
Hybrid search runs keyword search (BM25) and vector search together, then merges the results. Keywords catch exact product codes and drug names that embeddings blur, while vectors catch paraphrases that keywords miss.
A cross-encoder reranker then rescores the merged list and keeps only the best few passages. All three frameworks support this pattern, although the effort differs between them.
LlamaIndex treats hybrid retrieval as configuration, whereas LangChain treats it as composition and Haystack as declared components. Our guide to advanced RAG covers further techniques, such as query rewriting and parent-document retrieval.
The Same RAG Query in All Three Frameworks
The clearest way to compare APIs is to build the same thing three times. Each example below retrieves the top 10 passages, reranks them down to 3 and then answers the Drug X question on current releases.
All three samples use the post-migration imports from the maturity section above, so check every import before you copy older tutorial code.
LlamaIndex (0.14.25)
from llama_index.core import VectorStoreIndex, SimpleDirectoryReader
from llama_index.core.retrievers import VectorIndexRetriever
from llama_index.core.query_engine import RetrieverQueryEngine
from llama_index.core.postprocessor import SentenceTransformerRerank

# Load and index documents
documents = SimpleDirectoryReader("./docs").load_data()
index = VectorStoreIndex.from_documents(documents)

# Configure retrieval with reranking
retriever = VectorIndexRetriever(index=index, similarity_top_k=10)
reranker = SentenceTransformerRerank(
    model="cross-encoder/ms-marco-MiniLM-L-6-v2", top_n=3
)
query_engine = RetrieverQueryEngine(
    retriever=retriever,
    node_postprocessors=[reranker]
)

response = query_engine.query("What are the contraindications for Drug X?")
What the code reveals is that retrieval and reranking are settings on one query engine. The framework hides the plumbing, which is the point of LlamaIndex, though you see less of what happens inside.
LangChain (1.x)
from langchain_chroma import Chroma
from langchain_openai import OpenAIEmbeddings, ChatOpenAI
from langchain_classic.retrievers import ContextualCompressionRetriever
from langchain_cohere import CohereRerank
from langchain_core.runnables import RunnablePassthrough
from langchain_core.output_parsers import StrOutputParser

# Build retriever with reranking via compression
vectorstore = Chroma(embedding_function=OpenAIEmbeddings())
base_retriever = vectorstore.as_retriever(search_kwargs={"k": 10})
compressor = CohereRerank(model="rerank-v5.0-fast", top_n=3)
retriever = ContextualCompressionRetriever(
    base_compressor=compressor,
    base_retriever=base_retriever
)

# Assemble RAG chain
llm = ChatOpenAI(model="gpt-6.1-sol")
rag_chain = (
    {"context": retriever, "question": RunnablePassthrough()}
    | prompt_template
    | llm
    | StrOutputParser()
)

response = rag_chain.invoke("What are the contraindications for Drug X?")
Here the chain is explicit composition with the pipe operator, while reranking arrives through a separate Cohere integration. You control every link, and you also maintain every link, including the prompt_template defined elsewhere in the script.
Haystack (3.x)
# pip install haystack-ai sentence-transformers-haystack
from haystack import Pipeline
from haystack.components.retrievers.in_memory import (
    InMemoryBM25Retriever, InMemoryEmbeddingRetriever
)
from haystack.components.embedders import OpenAITextEmbedder
from haystack.components.joiners import DocumentJoiner
from haystack.components.builders import ChatPromptBuilder
from haystack.components.generators.chat import OpenAIChatGenerator
from haystack_integrations.components.rankers.sentence_transformers import SentenceTransformersSimilarityRanker

# store: an InMemoryDocumentStore with embedded documents
# template: chat messages with query and documents variables

# Define pipeline as explicit graph
pipeline = Pipeline()
pipeline.add_component("text_embedder", OpenAITextEmbedder())
pipeline.add_component("bm25_retriever", InMemoryBM25Retriever(document_store=store, top_k=10))
pipeline.add_component("embedding_retriever", InMemoryEmbeddingRetriever(document_store=store, top_k=10))
pipeline.add_component("joiner", DocumentJoiner())
pipeline.add_component("ranker", SentenceTransformersSimilarityRanker(model="cross-encoder/ms-marco-MiniLM-L-6-v2", top_k=3))
pipeline.add_component("prompt_builder", ChatPromptBuilder(template=template))
pipeline.add_component("llm", OpenAIChatGenerator(model="gpt-6.1-sol"))

# Connect components
pipeline.connect("text_embedder.embedding", "embedding_retriever.query_embedding")
pipeline.connect("bm25_retriever", "joiner")
pipeline.connect("embedding_retriever", "joiner")
pipeline.connect("joiner", "ranker")
pipeline.connect("ranker", "prompt_builder.documents")
pipeline.connect("prompt_builder.prompt", "llm.messages")

question = "What are the contraindications for Drug X?"
result = pipeline.run({
    "text_embedder": {"text": question},
    "bm25_retriever": {"query": question},
    "ranker": {"query": question},
    "prompt_builder": {"query": question},
})
Every component and every connection is declared, including the joiner that merges keyword and vector results. The code is longer, but in exchange the pipeline can be drawn, validated and saved to YAML for an audit file.
Talk to Kanerika
Get a Framework Recommendation for Your Corpus
Kanerika’s RAG engineers run a bake-off on a sample of your corpus, then recommend LlamaIndex, LangChain, Haystack or a combination.
Talk to a RAG Engineer →What a RAG Framework Really Costs
The framework license is the smallest line in a RAG budget. LlamaIndex and LangChain are MIT licensed and Haystack is Apache 2.0. So the money goes to managed platforms, model tokens and the engineers who run the system.
Platform Pricing
The table lists the tiers shown on the LangSmith pricing page, the LlamaIndex pricing page and the deepset pricing page on November 3, 2026.
| Platform | Entry tier | Paid tier |
|---|---|---|
| LangSmith (LangChain) | Developer: $0 per seat, 1 seat, 5K base traces a month | Plus: $39 per seat a month, 10K base traces a month; Enterprise is custom |
| LlamaParse (LlamaIndex) | Pay-as-you-go: $0 a month plus 10K free credits, then $1.50 per 1K credits | Pro: $500 a month, $1.25 per 1K credits |
| deepset (Haystack) | Studio: $0, 1 workspace, 1 user, 100 pipeline hours, 50 files | Enterprise: custom pricing |
A Worked Token Example
Tokens are where retrieval quality turns into money. Every chunk you send to the model is input you pay for on every query, so chunk count multiplies straight into the bill.
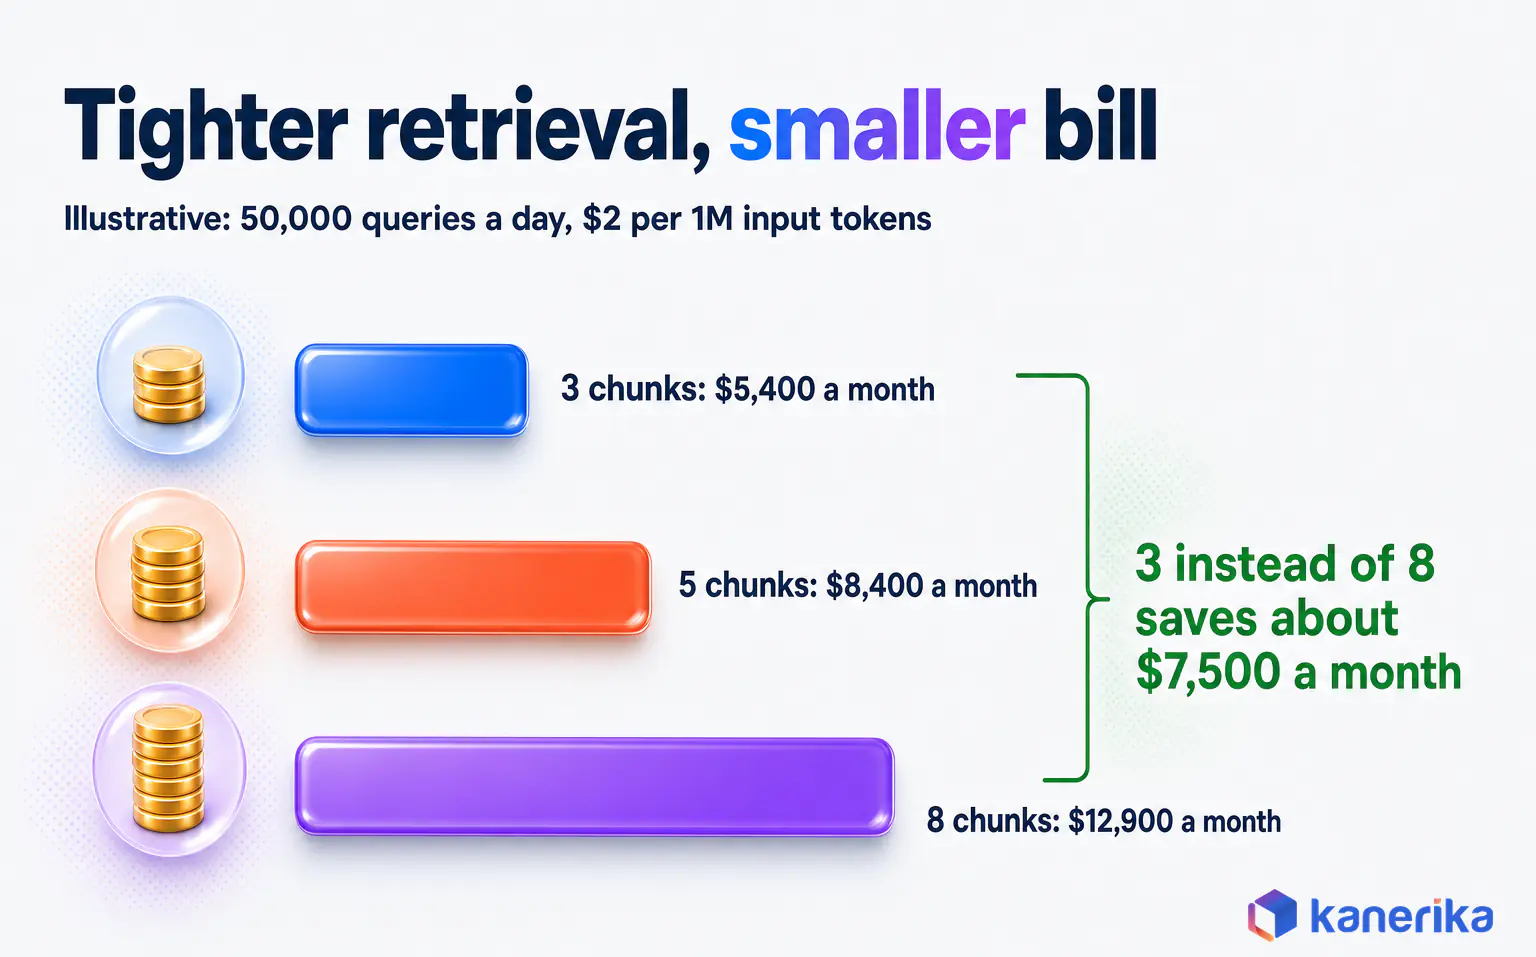
The worked example uses illustrative assumptions: 50,000 queries a day, 500-token chunks, 300 tokens of prompt and question, 400 output tokens and a 30-day month. Prices are $2 per 1M input tokens and $10 per 1M output tokens, the list price of both GPT-6.1 Sol and Claude Sonnet 5.5.
| Chunks per query | Tokens in per query | Daily input cost | Monthly input cost |
|---|---|---|---|
| 3 | 1,800 | $180 | $5,400 |
| 5 | 2,800 | $280 | $8,400 |
| 8 | 4,300 | $430 | $12,900 |
Output adds $200 a day at every row, because answer length does not change with chunk count. Tight retrieval with 3 chunks saves about $7,500 a month on input alone compared to 8 chunks.
The model choice scales that gap. On Claude Opus 5.5, at $4 and $20 per million tokens, the gap doubles, while on GPT-6.1 Terra, at $1 and $5, it halves. Batch processing on Sol and Opus 5.5 is also 50% cheaper for work that can wait.
Large context windows tempt teams to skip retrieval work. Claude Opus 5.5 and Gemini 4 Argon accept up to 1M tokens, while GPT-6.1 Sol accepts 1,050,000. Even so, stuffing in more chunks raises the bill without fixing retrieval. Our guide to context engineering covers how to decide what earns a place in the prompt.
How Each Framework Handles Multimodal RAG
Multimodal RAG means retrieving from content that is more than plain text, such as scanned PDFs, tables, charts and images. Most enterprise documents fall into this group, so parsing quality often decides accuracy before retrieval even starts.
Take, for instance, a 200-page annual report where the deciding figure sits in a table on page 87. A text-only parser flattens that table into noise, while a layout-aware parser keeps rows and columns intact. Vision-capable models such as Mistral Large 4, which accepts text and image input, can then read charts directly.
| Capability (editorial assessment) | LlamaIndex | LangChain | Haystack |
|---|---|---|---|
| Complex PDF parsing | Strong, through LlamaParse | Through loader integrations | Through converter components |
| Table and chart extraction | Strong | Moderate | Moderate |
| Image and text retrieval | Native multimodal indexes | Assembled from integrations | Configurable in the pipeline |
| Vision-capable model calls | Supported | Yes, through model integrations | Yes, through generator components |
| Structured data plus text | Strong | Composable | Explicit pipeline |
For document-heavy estates, the parsing layer deserves its own test before the framework decision. Our guides to intelligent document processing and multimodal models cover the wider options.
Datasheet
KlarityIQ: Your Document Intelligence Agent
Working with scanned PDFs, contracts and RFI documents? Get the specifications for KlarityIQ, Kanerika’s document intelligence agent for unstructured files.
View the Datasheet →RAG Evaluation: Don’t Skip This
Evaluation is how you learn whether a RAG system works before your users tell you. Without a scored test set, every change to chunking, prompts or models is a guess.
The most widely used method is RAGAS. The RAGAS paper on arXiv was first posted on September 26, 2023 and revised on April 28, 2025. It scores faithfulness to the retrieved context, answer relevance and context recall, and several of its metrics also need no human-written reference answer.
| Evaluation capability | LlamaIndex | LangChain | Haystack |
|---|---|---|---|
| Built-in evaluators | Evaluation modules for faithfulness and relevance | LangSmith datasets and evaluators | Evaluator components |
| RAGAS use | Supported | Works with RAGAS | Compatible |
| Running in CI | Scripts in your test suite | LangSmith experiments | An evaluation pipeline |
Pick the metrics before you pick the tools. Our LLM evaluation framework guide explains how to build the test set and score it.
How to Run a Fair Bake-Off on Your Own Corpus
A bake-off only means something when every variable except the framework stays fixed. Use the method below, and report the results you measure on your data instead of vendor benchmarks.
- Use the same corpus for all three builds, a representative sample of your real documents that also includes the messy ones.
- Fix the embedding model, the LLM and the chunk size, so the framework is the only thing that changes.
- Write 100 to 200 questions with labeled answers and source passages, drawn from real user queries.
- Measure faithfulness and context recall for quality, p95 latency for speed and cost per answered query for spend.
- Record the engineering hours each build took, since that cost returns every time the system changes.
Then pick the framework that clears your quality bar at the lowest cost per answered query. If two tie, then choose the one your team found easier to debug.
What Changes When RAG Hits Production
A prototype answers questions, whereas a production system answers them reliably, quickly and traceably for thousands of users. Most of that gap is engineering around the framework, and the frameworks still differ in how much of it they carry for you.
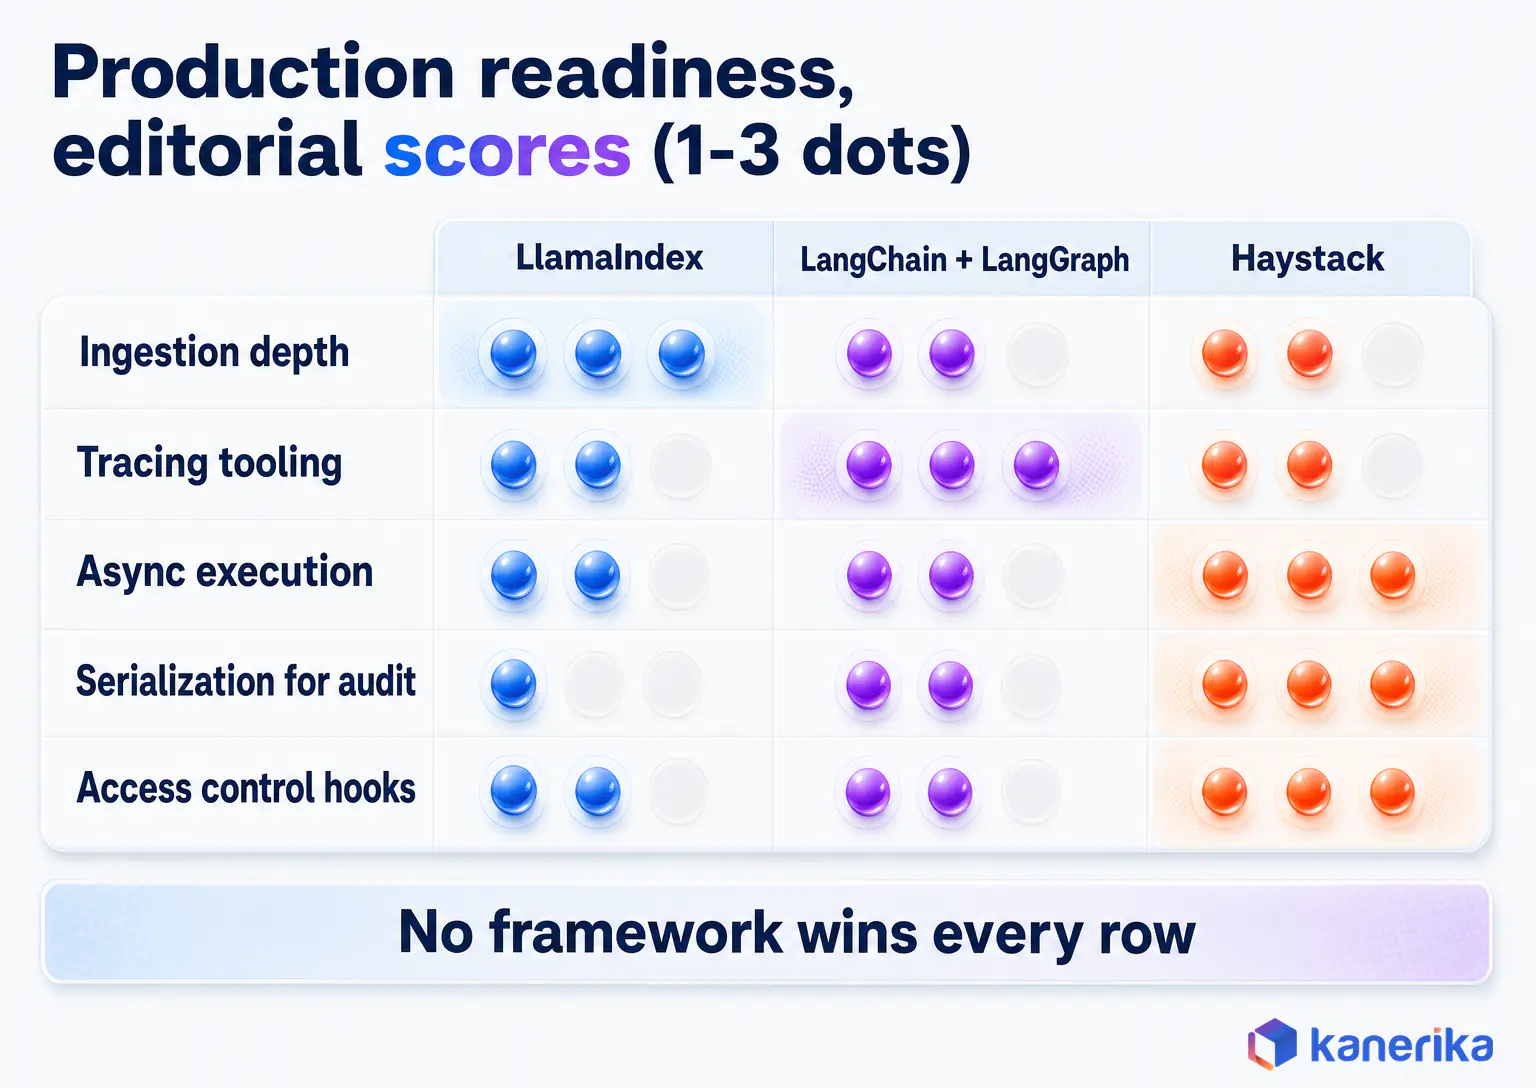
In our editorial assessment, LlamaIndex leads on ingestion depth while LangChain leads on tracing tooling through LangSmith. Haystack leads on serialization and audit evidence, and no framework wins every row. Those ratings reflect documented features, so confirm them against your own build during the bake-off.
Five Areas to Get Right
- Tracing. You need to see which chunks were retrieved and what the model received for any answer. LangSmith covers LangChain, LlamaIndex uses callbacks and third-party tracers, while Haystack 3.0 turns tracing on through OpenTelemetry or Datadog connector components.
- Async execution. Concurrent traffic needs async calls. Haystack 3.0 merged AsyncPipeline into the single Pipeline class, while LangChain and LlamaIndex expose async methods.
- Serialization. Haystack pipelines serialize to YAML, so the deployed graph can be versioned and reviewed. LangGraph and LlamaIndex configurations mostly live in code instead.
- Caching. Cache embeddings and repeated answers so that both cost and latency drop.
- Latency budget. Set a p95 target and split it across retrieval, reranking and generation, because reranking often costs more milliseconds than teams expect.
Test all five under production-like load before launch. A pipeline that answers in one second for one user can slow sharply when fifty users hit the reranker at once, and only load testing reveals it.
Version everything that shapes an answer, such as the prompt, the chunking settings, the embedding model and the reranker. When an answer changes, you can then trace it to one specific change.
Observability becomes its own discipline once traffic grows. Our guides to LLMOps observability and AI observability tools compare the tracing stacks in detail. Good tracing also shortens every later framework upgrade, because you can compare traces before and after.
Security and Compliance in Regulated Industries
In regulated industries, the central question is who may see each retrieved passage, and whether you can prove it later. A RAG system that retrieves a document the user may not read has already leaked it, even if the model never quotes it.
The safest design enforces access control at the retrieval layer. Each chunk carries the permissions of its source document, and the retriever filters by the user’s role before anything reaches the model. Filtering after generation is too late, because the model has already read the text.
Model access needs the same discipline. An LLM gateway, for example, centralizes keys, logging and policy across providers. Private LLMs keep sensitive data inside your own boundary when no external call is allowed.
Four Controls Auditors Ask About
- Access control at retrieval. Apply metadata filters by role or group on every query.
- Audit trails. Log the query, the retrieved chunk IDs, the prompt and the answer.
- Data residency. Keep indexes and model calls in approved regions.
- Self-hosting. All three frameworks run inside your own infrastructure, which matters for on-premises and air-gapped deployments.
Haystack’s explicit pipelines make audit evidence easiest to produce, because the YAML file shows every step. LlamaIndex and LangChain can meet the same bar with metadata filters and tracing, though you assemble more of it yourself.
A simple test exposes most permission gaps. Log in as a junior analyst and ask for a figure that only finance leadership may see, then note the reply. If the answer appears, or the model hints that it exists, the filter sits in the wrong place.
To map these controls to a recognized standard, use the NIST AI Risk Management Framework 1.0, released on January 26, 2023. Its Generative AI Profile, NIST-AI-600-1, followed on July 26, 2024.
The OWASP Top 10 for LLM and GenAI lists the attack classes, such as prompt injection, that a RAG system must be tested against. Retrieval permissions should also follow your wider enterprise data governance rules, and our LLM security guide covers the threat model in depth.
Agentic RAG, Where the Frameworks Diverge Most
Agentic RAG lets a model decide what to retrieve, when to retrieve again and which tool to call next. That freedom is where the three frameworks differ most, because each one models control flow in its own way.
LangGraph models an agent as a state machine, a graph of steps with saved state after each one. It can pause for human approval and resume later, which suits long, multi-step work.
LlamaIndex builds its agents on workflows, event-driven steps that keep retrieval at the center. Its agents work best when most of the job is finding and reading documents.
Haystack 3.0 gives its Agent component hooks such as before_llm and before_tool. A human approval step becomes a before_tool hook that holds a risky action until a person signs off. That hook also lives in the same auditable pipeline.
Agent loops cost more than single retrievals, since each extra step is another model call with its own tokens and latency. Start with plain RAG. Add an agent only when one retrieval pass cannot answer, such as a question needing both a contract clause and a CRM record.
Tool access is also converging. The Model Context Protocol gives agents a standard way to reach tools and data, so one tool server can sit behind whichever framework calls it.
Our LangChain vs LangGraph guide explains when the graph layer is worth adding. The AutoGen vs LangChain comparison covers the conversational alternative to that design.
For the wider picture, see AI agent frameworks compared, plus our guides to agentic RAG and multi-agent AI systems.
Checklist
Agentic AI Readiness Checklist
Before an agent retrieves and acts on enterprise data, review approvals, access, evaluation and monitoring with this downloadable checklist.
Get the Checklist →Team Skill and Framework Fit
The best framework on paper still fails if your team cannot run it. Match the choice to the skills you have now and the ones you can realistically hire.
| Team profile | Starting framework | Why |
|---|---|---|
| First RAG build, small team | LangChain | Largest community and the most worked examples |
| ML team focused on document retrieval | LlamaIndex | Deepest indexing and parsing options |
| Compliance-first enterprise team | Haystack | Explicit pipelines produce audit evidence |
| Team already running LangChain | Stay, and add a LlamaIndex retriever | Lowest switching cost |
Check the Python floor too, since Haystack needs Python 3.11 or later while LlamaIndex and LangChain need 3.10 or later. All three frameworks here are Python-first, so read our guide for .NET teams weighing Semantic Kernel if your stack runs on .NET.
When to Combine Frameworks: Patterns That Work in Production
Combining frameworks works when each one owns a clear layer and the layers meet at a narrow interface. It fails when two frameworks fight over the same job, such as both managing prompts or both holding state.
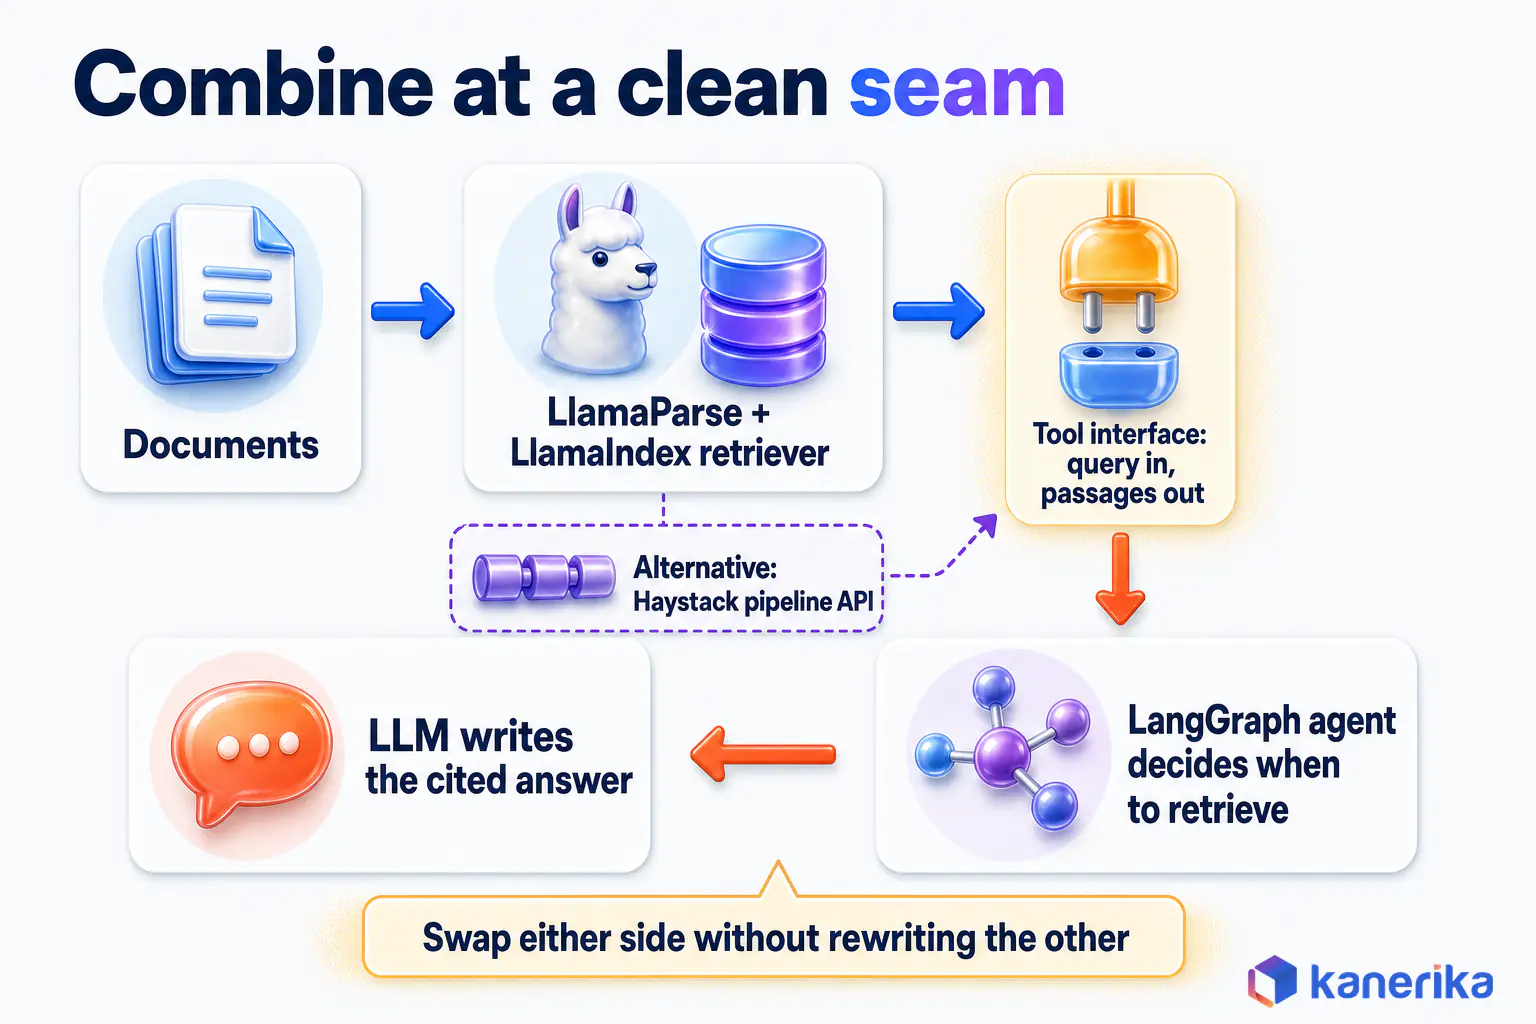
- LlamaIndex retriever wrapped as a LangGraph tool. LlamaIndex builds and queries the index, then a thin wrapper exposes its query engine as a tool. LangGraph decides when to call it, alongside tools such as a CRM lookup.
- Haystack pipeline served behind an API. The audited retrieval pipeline runs as its own service with a versioned YAML definition. Any agent calls it over HTTP and never touches the pipeline internals.
- LlamaParse ingestion feeding any store. LlamaParse turns complex PDFs into clean text and structure. The output lands in a vector store that LangChain or Haystack then queries.
In short, the common thread is the seam. Define one retrieval interface that takes a query and returns passages with sources and scores, then keep every framework object behind it.
With that seam in place, either side can be swapped without rewriting the other. Teams coordinating several agents across such services should also read our guide to AI agent orchestration.
The True Cost of Switching Frameworks
Switching frameworks costs far less when the retrieval interface was clean from the start. The effort depends on which layer moves, so the table rates it as Low, Medium or High.
| Move | Relative effort | What changes | What survives |
|---|---|---|---|
| Add a LlamaIndex retriever to a LangChain app | Low | Retrieval layer only | Orchestration, prompts, tools |
| LangChain to LlamaIndex | Medium | Retrieval and indexing | Business logic, prompts |
| LlamaIndex to LangChain | Medium | Orchestration and tool wiring | Retrieval, reusable as a tool |
| Add a Haystack pipeline for sensitive flows | Medium | Selected retrieval flows | Main application |
| LangChain or LlamaIndex to Haystack | High | Pipeline definitions and components | Documents, prompts, evaluation set |
Your documents and evaluation set survive any move, which helps because they are the most expensive assets to rebuild. Embeddings survive too when you keep the same embedding model. Keep the seam from the previous section, and a later switch then stays a contained project.
4 Questions to Ask Before Committing to a RAG Framework
Four questions settle most framework decisions, and a fifth asks whether you need one at all. Answer them in order, then use the weighted matrix at the end to turn the answers into a score.
1. What Is the Primary Retrieval Challenge?
If answers fail because the right passage is never found, the problem is retrieval, and LlamaIndex is the natural start. If answers fail because the system cannot act on what it found, the problem is orchestration, and LangGraph fits better.
2. What Does the Production Environment Look Like?
A Kubernetes estate with strict change control favors pipelines that serialize and version cleanly, which is Haystack’s strength. On the other hand, a product team shipping every week may prefer LangChain’s integrations and LangSmith’s tracing.
3. What Are the Data Governance Requirements?
If an auditor must see how every answer was produced, choose the framework that makes that evidence cheapest, which is often Haystack. Whatever you pick, still enforce permissions at retrieval and log the chunk IDs behind each answer.
4. What Can the Team Operate and Maintain?
Pick the framework your team can debug during an outage. LangChain’s larger community means more answered questions online, while Haystack’s explicit graph means fewer hidden moving parts.
Do You Need a RAG Framework at All?
Sometimes the honest answer is no. A small corpus, one model and no agents can run on a vector database SDK and about 100 lines of your own code.
Frameworks pay off when you add many sources, rerankers, evaluation and agents, because each one saves glue code. If the knowledge rarely changes, compare retrieval with tuning the model itself in our RAG vs fine-tuning guide.
Turn the Answers Into a Weighted Score
The weights and the 1 to 5 scores below are illustrative starting weights, so adjust them to your workload.
| Criterion (weight) | LlamaIndex | LangChain + LangGraph | Haystack |
|---|---|---|---|
| Retrieval complexity (30%) | 5 | 3 | 4 |
| Agent and orchestration need (25%) | 3 | 5 | 3 |
| Auditability (25%) | 3 | 3 | 5 |
| Team skill fit (20%) | 3 | 5 | 3 |
| Weighted score | 3.60 | Highest: 3.90 | Close second: 3.80 |
Change the weights and the leader changes, which is the point of the exercise. For example, the contract team from the opening might weight retrieval at 40%, agents at 20%, auditability at 30% and team skill at 10%.
Those weights give Haystack 4.0, LlamaIndex 3.8 and LangChain 3.6. That result suggests testing LlamaParse ingestion together with a Haystack pipeline in the bake-off.
How Kanerika Approaches Enterprise RAG Framework Selection
Kanerika treats framework selection as an evidence problem. The choice is made on the client’s own documents and questions, scored against the same kind of weighted matrix shown above.
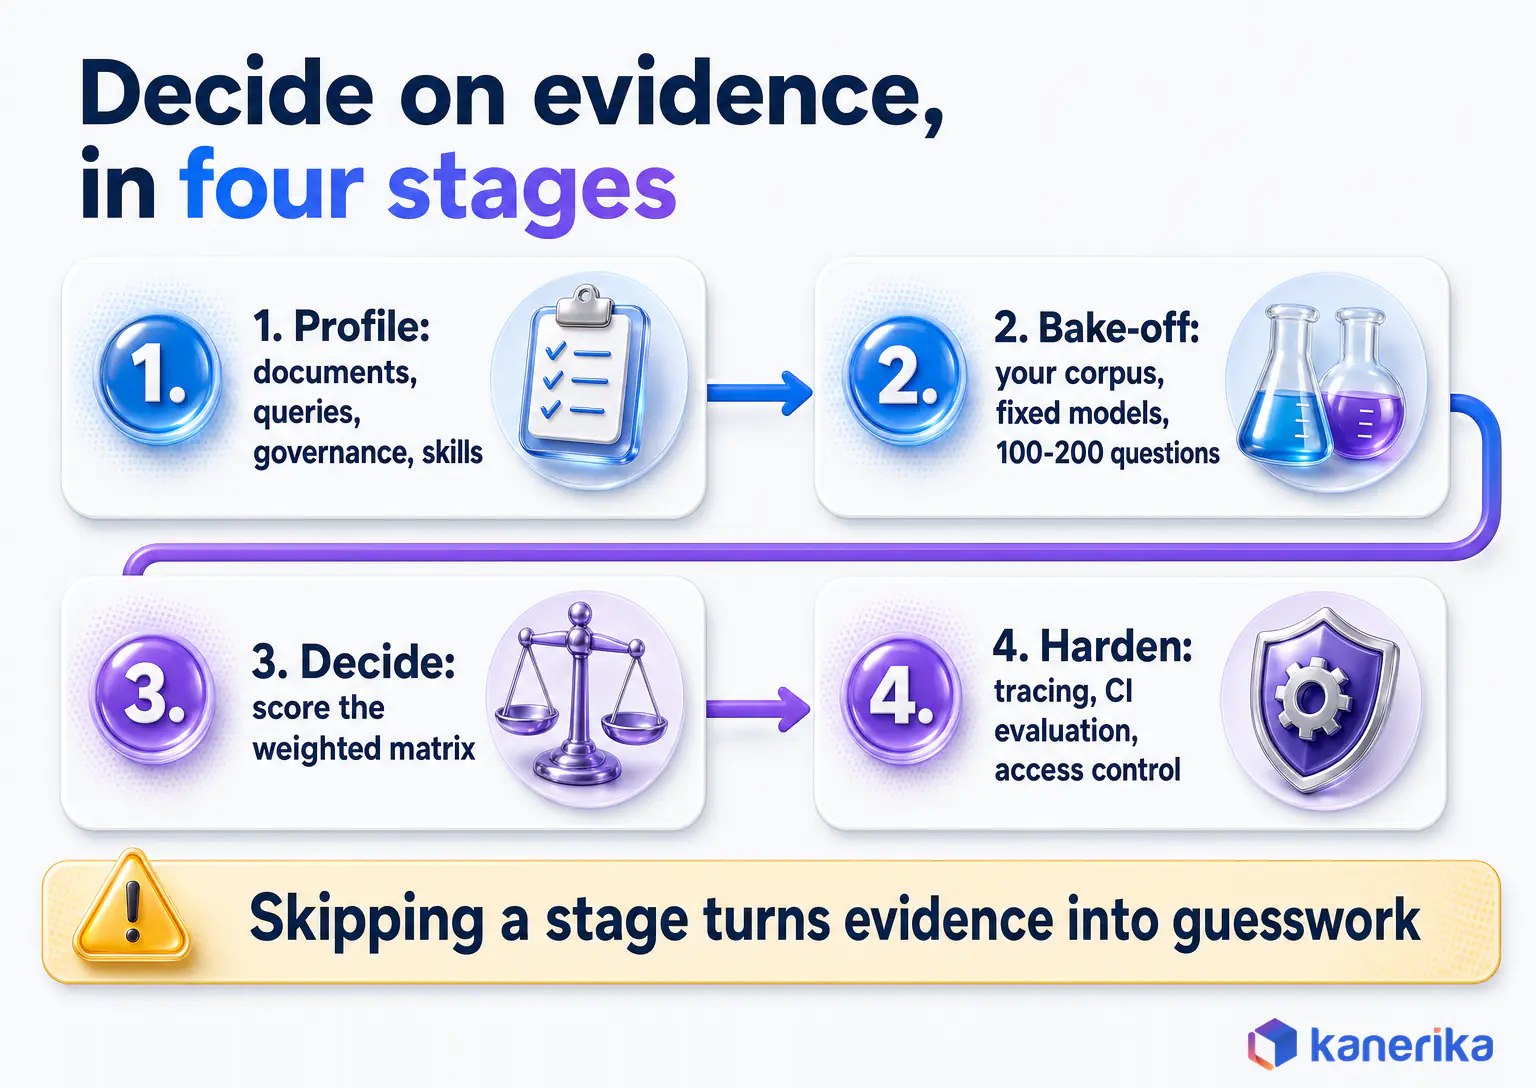
Our RAG development services follow four stages:
- Workload profiling. We map document types, query patterns, governance rules, infrastructure and team skills before naming any framework.
- Retrieval-first proof of concept. We run the bake-off method from the evaluation section on the client’s own corpus, with fixed models and a labeled question set.
- Framework decision. The decision is documented against the weighted matrix. When needs split, we combine frameworks behind a thin retrieval interface.
- Production hardening. We add tracing, evaluation in CI, role-based access control at the retrieval layer and cost monitoring.
The order matters more than the tools. Profiling first ties the choice to the real workload, then the bake-off replaces opinion with scores on real questions.
Two Kanerika agents often sit on top of the result. KlarityIQ, a document intelligence agent, handles unstructured files, while Karl, a data insights agent, answers questions over structured databases.
The same team also handles wider model work, from model choice to fine-tuning, through our LLM development services.
Case Study: 43% Faster Document Retrieval for an Investment Bank
One Kanerika engagement shows why the retrieval layer decides outcomes. The client was an investment bank answering requests for information across documents and databases.
Challenge
The bank handled unstructured RFI documents and structured data largely by hand, so answers depended on a few specialists who knew where things lived. Access controls sat outside the retrieval step, so enforcing who could see what took extra manual checks.
Solution
Kanerika deployed KlarityIQ for the documents and Karl for the databases, together with chat interfaces across both. Role-based access control was applied at the retrieval layer, so each user retrieves only what their role allows.
Results
The published investment bank document retrieval case study reports three outcomes:
- 43% faster information retrieval across documents and databases
- 100% role-based compliance achieved at the point of retrieval
- 35% improvement in workforce efficiency
The case study does not name a RAG framework, so read it as evidence for two lessons from this guide. Access control belongs in the retriever, while retrieval quality is what users feel first.
For teams comparing these frameworks, the practical step is to test permission filtering inside the bake-off itself. A framework that retrieves well but makes role filters awkward will cost more in compliance work than it saves in accuracy.
Talk to Kanerika
Book a RAG Assessment
Bring your documents and hardest questions. Kanerika scores your workload against this guide’s matrix and shows which framework fits.
Book a RAG Assessment →The Verdict on LlamaIndex vs LangChain vs Haystack
The LlamaIndex vs LangChain vs Haystack decision comes down to your hardest problem. Choose LlamaIndex when retrieval precision over large document sets matters most, and choose LangChain with LangGraph when multi-step agents, tools and approvals drive the design.
Choose Haystack when every step must be explicit, versioned and auditable. Combine them when needs split, with LlamaIndex retrieving, LangChain orchestrating or a Haystack pipeline serving audited retrieval behind an API.
Prove the choice with a bake-off on your own corpus, because the RAG framework that fits in 2026 is the one your own numbers pick.
Frequently Asked Questions
Which RAG framework is best for enterprise document search?
LlamaIndex is usually the strongest start for enterprise document search. It has deep data connectors, several index types and LlamaParse for complex PDFs with tables. Haystack is the better pick when every retrieval step must be auditable. Whichever you choose, test it on your own documents with a labeled question set before you commit.
What is the difference between LlamaIndex, LangChain, and Haystack?
LlamaIndex focuses on retrieval, with indexes and query engines built to find the right passage. LangChain focuses on composing models, prompts and tools, and LangGraph adds stateful agents on top. Haystack builds RAG as an explicit pipeline of typed components that serializes to YAML. In short, they optimize for retrieval, orchestration and auditability.
Do you actually need a RAG framework?
Not always. A small corpus, one model and no agents can run on a vector database SDK and about 100 lines of your own code. Frameworks earn their place when you add many data sources, rerankers, evaluation and agents. At that point they save more glue code than they cost to learn and maintain.
Are LlamaIndex, LangChain, and Haystack free to use?
Yes, all three libraries are free and open source. LlamaIndex and LangChain use the MIT license, and Haystack uses Apache 2.0. The costs sit around them, in managed platforms such as LlamaParse, LangSmith and deepset, plus model tokens and engineering time. At high query volume, model tokens often cost more than the platforms.
Can you use LlamaIndex and LangChain together?
Yes, and it is a common production pattern. LlamaIndex builds and queries the index, and a thin wrapper exposes its query engine as a tool. A LangChain or LangGraph agent then decides when to call that tool alongside others. Keep one clean retrieval interface between them so either side can be replaced later.
Which framework is best for agentic RAG?
LangChain with LangGraph is the most mature choice for agentic RAG. LangGraph saves state after each step, retries failed steps and pauses for human approval. LlamaIndex agent workflows suit agents that mostly retrieve and read documents. Haystack 3.0 adds an Agent with hooks such as before_tool, which can hold a risky action for human sign-off.
Is LangChain good for production RAG?
Yes, when you pin versions and add tracing and evaluation. LangChain 1.x moved legacy retrievers into the langchain-classic package, so older tutorials may break on a fresh install. LangSmith adds tracing and evaluation, with a free Developer tier and a Plus tier at $39 per seat a month. LangGraph then handles stateful and agentic flows.
How much does switching RAG frameworks cost?
The cost depends on which layer moves. Adding a LlamaIndex retriever to a LangChain app is low effort, while moving a whole system to Haystack is high effort because every pipeline gets redefined. Documents, prompts and the evaluation set survive any move. A clean retrieval interface from the start keeps a later switch contained.
Which RAG framework is best for regulated industries?
Haystack is often the best fit for regulated industries. Its pipelines declare every component and connection, and they serialize to YAML for review and version control. Haystack 3.0 also adds step-level tracing spans for agents. Any of the three can pass an audit, though, if you enforce access control at retrieval and log the chunks behind each answer.
How do you evaluate RAG framework quality?
Build a labeled set of 100 to 200 real questions with known answers and source passages. Keep the corpus, embedding model and LLM fixed, then compare frameworks on faithfulness, context recall, p95 latency and cost per answered query. RAGAS provides standard metrics for this work, and each framework can run the scoring in CI.
Which RAG framework is easiest to get started with?
LlamaIndex usually gets a working document Q&A running in the fewest lines of code. LangChain has the largest community, so answers to beginner questions are easy to find. Haystack asks you to declare each component, which takes longer at first and pays back in production. Check the Python floor too, which is 3.11 for Haystack.
Which RAG framework handles document-heavy PDFs best?
LlamaIndex is the strongest choice for document-heavy PDFs, mainly through LlamaParse. LlamaParse keeps tables and layout intact before indexing, which protects accuracy on reports and contracts. It runs on credits, with 10,000 free and then $1.50 per 1,000 on pay-as-you-go. Its parsed output can also feed a LangChain or Haystack store.