
Data Engineering Services in London for Dependable, Governed Data
Kanerika is a data engineering consultancy for London businesses that need governed, reliable data. Our data engineering services in London cover pipeline builds, lakehouse platforms, and data integration work across cloud and legacy on-premises systems, so reporting, regulatory returns, and AI models draw on trusted inputs.
Faster data processing
Better data quality
Quicker analytics delivery












Data Engineering Services in London for Regulated, High-Volume Data
London businesses run on timely, trustworthy data. We rebuild pipelines, platforms, and governance around your current stack, from data pipeline development to lakehouse design and regulatory controls, scoped to your data volumes and sector rules, and hand over working, monitored pipelines.
Data Pipeline Development
- Batch and event feeds into one platform
- Failures trigger alerts and automatic reruns
- Checked before analysts use it
Data Quality and Observability
- Data tests built into every pipeline run
- Lineage maps show where data came from
- Drift and gaps caught early
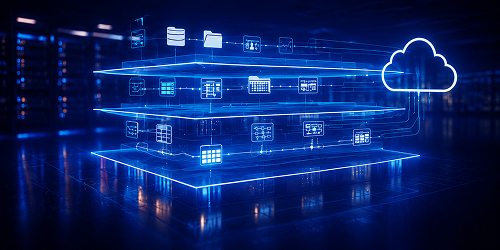
Data Lakehouse Architecture
- Bronze, silver, and gold layers per domain
- Table schemas validated as data lands
- Partitioned for fast queries
ETL and ELT Modernization
- Old ETL jobs rebuilt in the cloud
- Source controlled with unit tests
- Run history and alerts after release
DataOps and Release Automation
- Pull requests gate every change
- Test suites run on each build
- Contracts define what producers deliver
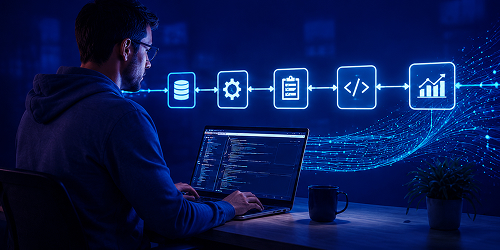
Real-Time and Streaming Data
- Streams processed as events arrive
- Pipelines sized for operational demand
- Live figures on every dashboard
How London Businesses Engage Our Data Engineers
Begin with a fixed-scope build, move to phased modernisation, or add embedded engineers beside your data team.
Pipeline Audit and Design
- Review current pipelines and gaps
- Agree target design and tooling
- Receive a build-ready blueprint
Build and Modernize
- Replace legacy ETL with cloud-native jobs
- Lakehouse implementation with streaming layers
- Release tested pipelines into production
Ongoing Support
- Embed engineers alongside your data staff
- Track pipeline health and data quality
- Pick up new workstreams on demand
Data Engineering Results That Hold Up Under Audit
Read how our data engineering approach shortens pipeline delivery, reduces data debt, and gives analysts dependable inputs across sectors.
Independent Microsoft Fabric Architecture Review Before a Dynamics 365 Go-Live
Impact:
- ~136 Findings documented before go-live
- ~30 Days estimated for pre-cutover remediation
- 6 Weeks to an independent, evidence-based go/no-go view
Bringing Live QAD ERP Data into Microsoft Fabric with Open Mirroring
Impact:
- 7 QAD data issues resolved before rollout
- 0 Duplicate records when data is reloaded
- 200+ QAD tables connected to Fabric
Detecting Rental Transaction Risk Early with AI-Powered Risk Intelligence
Impact:
- ~500 Risk findings surfaced
- ~1.2M Financial exposure identified
- 6 Risk categories used to classify findings
The IMPACT Method Behind Dependable Data Delivery
Each London engagement follows IMPACT, with defined checkpoints from design choices through testing to live, monitored data platforms.
INNOVATE
Data Engineering for London's Core Sectors
Retail
Merge store, online, and warehouse data so planners at London retailers get one view across their supply chains.
What Makes Kanerika a Reliable Data Partner in London?
Engineers who build production lakehouses meet the standards London businesses expect. Our consultants hold Microsoft, Databricks and Snowflake partner credentials, and every project follows certified delivery practices.
Kanerika is a Microsoft Solutions Partner with an in-house MVP who contributes to Fabric, so platform advice rests on hands-on delivery.
We hold Databricks Consulting Partner and Snowflake Select Tier status, supported by lakehouse and pipeline deployments running in production.
Our ISO 27001, 27701, 9001, SOC 2 Type II and CMMI Level 3 credentials give London businesses governance and audit evidence for regulators and internal auditors.
Empowering Alliances
Our Strategic Partnerships
The pivotal partnerships with technology leaders that amplify our capabilities, ensuring you benefit from the most advanced and reliable solutions.



Frequently Asked Questions (FAQs)
How should a business choose a partner for data engineering services in London?
Look for engineers who have run production pipelines on your target platform, not only designed them. Ask about regulated-data experience, handover standards, and who stays after go-live. Kanerika builds and operates what it designs, and the same delivery model extends to our data engineering services across the UK as you add sites, offices, and regions.
What timeline should a London business plan for a data engineering build?
Expect 8 to 16 weeks for a focused build or an ETL migration. A full enterprise lakehouse programme with governance and DataOps takes six months or more. The spread comes from the number of source systems, data volumes, and compliance scope, and we fix milestones at kickoff.
Should we choose Snowflake, Databricks, or Fabric for our London data platform?
The choice follows your skills, workloads, and existing licences. Snowflake suits SQL-led teams, Databricks suits code-first Spark and machine learning work, and Fabric suits organisations standardised on Microsoft and Power BI. Kanerika engineers work on all three, and our data integration services in London connect the source systems feeding whichever you pick.
When does a London organisation need a data lakehouse?
A lakehouse fits when your data is too varied for a warehouse but too valuable to leave loose in a lake. It keeps raw files and curated tables together, with schema checks and fast queries. Kanerika builds on Databricks with Delta Lake, Snowflake with Iceberg, and Fabric with OneLake, so data analytics services in London can sit on the same governed layer.
How do you collaborate with London businesses across time zones?
Most work happens remotely, with onsite workshops in London when they add value. Our engineers keep working hours that overlap with UK business hours, so standups, reviews, and incident calls fit your day. A shared backlog and a weekly review keep decisions moving.
How does UK GDPR affect a data engineering project?
UK GDPR and the Data Protection Act 2018 govern how pipelines collect, store, and move personal data. We build in classification, minimisation, retention rules, and audit logging from discovery. For FCA and PRA regulated firms, lineage supports reporting and operational resilience. Legal advisers confirm how each rule applies.
Do we own the pipelines and transformation logic after delivery?
Your statement of work sets the terms. In most engagements, everything we write for you, including pipeline code, data models, configuration, and runbooks, lands in your repositories and cloud tenancy. Reusable tooling such as FLIP stays with Kanerika, while anything configured specifically for your business is yours to keep.
How is data secured during a data engineering project?
Security is designed in from discovery: data classification, encryption in transit and at rest, access controls, lineage, and audit logging. Certifications include ISO 27001, ISO 27701, SOC 2, and CMMI Level 3. For NHS and public sector work, controls can align with the NHS Data Security and Protection Toolkit.
What happens at handover and after go-live?
At handover you receive tested pipelines, runbooks, lineage documentation, and monitoring dashboards. Afterwards, support can be ad hoc or retained, covering monitoring, incident response, and new workstreams as your priorities change.
Should a London business hire in-house or use a data engineering consultancy?
Hire in-house when you have a stable roadmap, time to recruit, and steady demand. Use a consultancy when deadlines are fixed, scarce skills are missing, or a platform move needs a burst of capacity. Many organisations blend both: Kanerika builds the foundation, your in-house data team learns it alongside us, and our data strategy consulting in London helps decide what to build next. You choose how long we stay involved, and can scale it later.
What does a data engineering engagement cost in London?
Cost depends on source systems, data volumes, pipeline complexity, and the target platform. Assessments and focused builds typically start in the low five figures, while larger programmes run well into six figures. Work is scoped in phases and priced after a short discovery call, so you see the cost of each milestone clearly before approving it. Accelerators such as FLIP reduce manual effort and keep spend predictable across the whole programme.
Is Your London Business Ready for Data Pipelines You Can Trust?
Book a free assessment covering architecture, platform choice, and a delivery plan for your London estate.

