TL;DR
Data stewardship is day-to-day accountability for what data means, how good it must be and who may use it. The owner decides, the steward runs the rules and the custodian then builds them into systems. Run it centralized when one domain dominates, hybrid when regulated business units share data, and federated when domain teams are strong. A RACI matrix and an issue workflow turn those roles into a working framework. Size steward time from workload, such as open issues, rather than a fixed ratio. Track coverage, resolution time and rule pass rates, and give AI data a named steward too.
Key Takeaways
- Data stewardship is operating accountability for the meaning, quality and permitted use of a defined set of data.
- Governance sets policy and decision rights, stewardship runs them every day, while data management builds and operates the systems.
- Owners decide, stewards define and monitor, and custodians implement; Microsoft’s governance catalogs use the same split.
- Choose a centralized, federated or hybrid model from five criteria, such as regulatory load and domain team capacity.
- Estimate steward effort from workload counts, then measure progress with coverage, resolution time, rule pass rate, adoption and access turnaround.
- AI datasets, RAG sources and agent context need the same owner, steward and change control as any reporting table.
One Metric, Three Numbers, No Owner
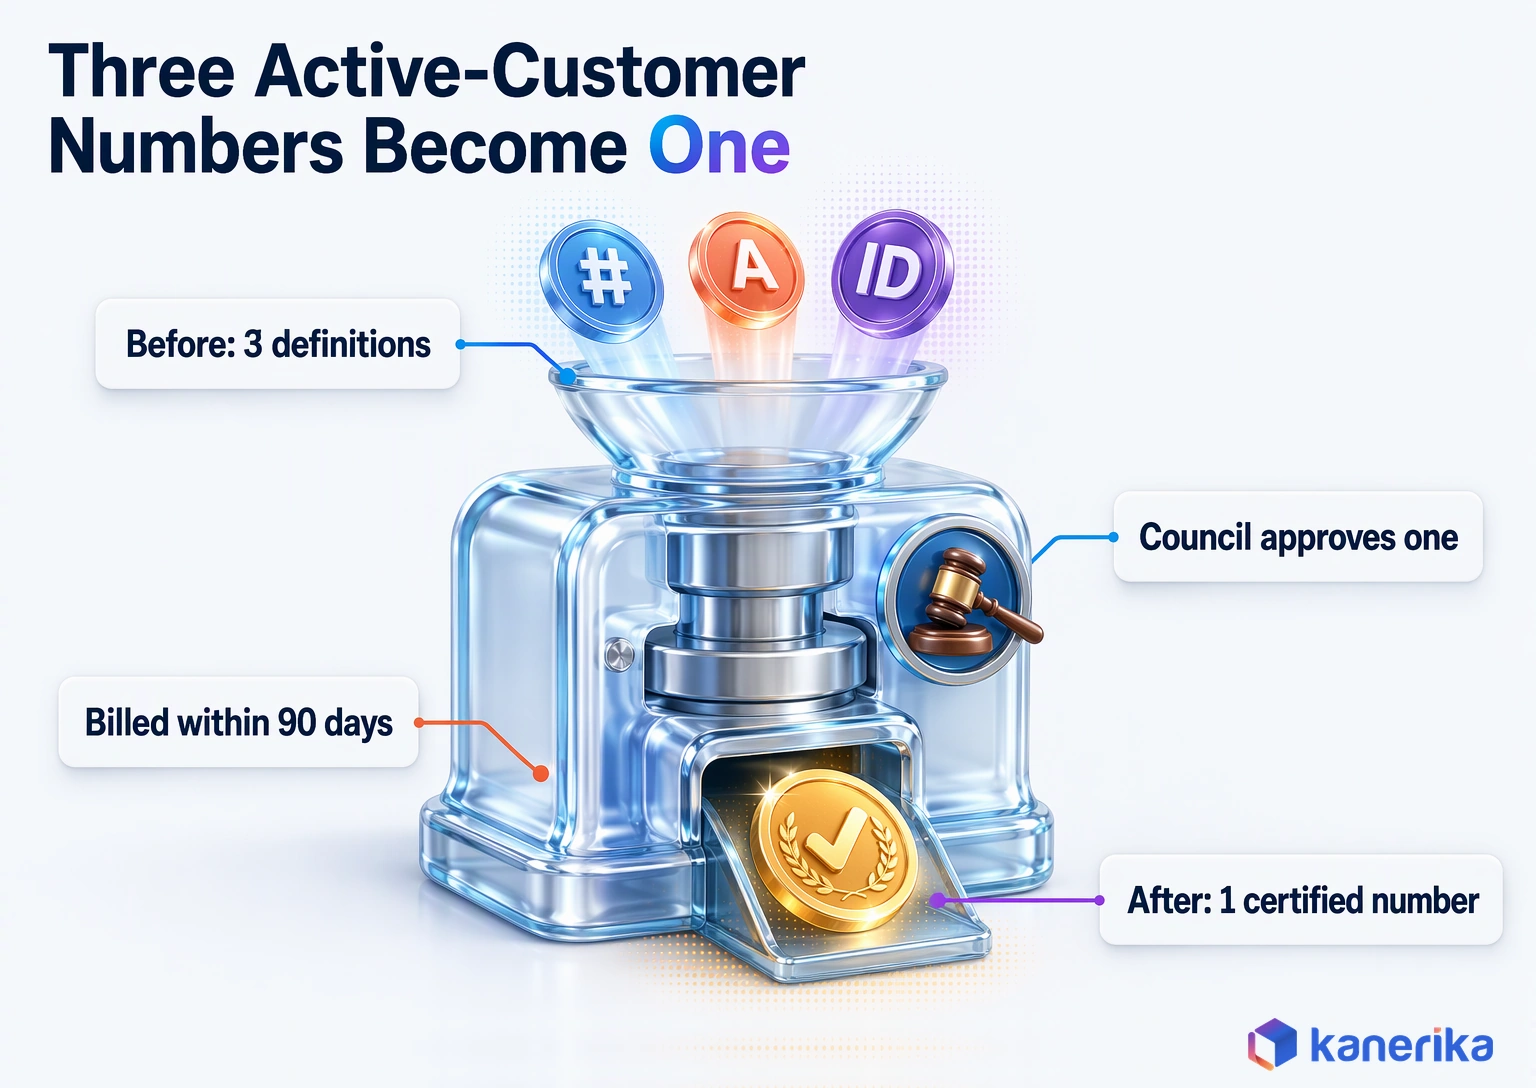
Picture a quarterly board pack with three numbers for “active customers” on three different pages. Finance counts anyone billed in the last 90 days. Sales counts anyone with an open contract, while the AI team counts anyone who logged in during the last 30 days.
Each number is still correct by its own logic. The problem is that nobody holds the right to decide which one the company means. So the board spends twenty minutes on a definition, and the churn model still trains on a third version nobody approved.
That gap is the job data stewardship exists to close. This guide therefore covers the roles, the operating models and a RACI matrix. It then walks through a daily workflow, sizing, AI data and the KPIs that show the program works.
What Is Data Stewardship?
Data stewardship is the operating accountability for the meaning, quality and permitted use of a defined set of data. A data steward is the named person who keeps that set of data fit for use, day after day, under rules the organization has agreed.
The definition is narrower than people expect, but that helps. Stewardship does not own the database, write the policy or buy the catalog. Instead, it owns the decisions in between: what a field means, how good it must be, who may use it, and what happens when it breaks.
A useful test is to ask who answers when a report looks wrong. If the answer is “the data team” or “IT”, then nobody is stewarding that data yet. But if a named person can explain the definition and fix the rule, stewardship is working.
What a Data Steward Decides, and What They Escalate
Stewards hold real decision rights inside their domain, because otherwise they become note-takers. The rights below keep everyday work moving without a committee meeting. Anything that changes policy, risk or another domain goes up the chain instead.
Within their domain, a steward decides on:
- Business definitions and calculation rules for the terms the domain uses.
- Quality rules, such as the thresholds that trigger an alert.
- Classification of fields as public, internal, confidential or restricted, within the published scheme.
- Triage and priority when someone raises a quality issue.
By contrast, a steward escalates:
- Policy changes, such as a new retention period or a new sensitivity class.
- Access exceptions that fall outside the approved roles.
- Disputes with another domain over a shared definition.
Writing these lists down matters more than their exact wording. When a steward knows where their authority stops, they act faster inside it and escalate earlier outside it.
Business, Technical and Domain Stewards
Most programs use three kinds of steward, and the difference is where each one sits. Business stewards carry the meaning, while technical stewards carry the plumbing. Domain stewards then coordinate both across one area of the business.
| Type | Sits in | Owns | Example |
|---|---|---|---|
| Business data steward | A business function such as finance or sales | Definitions, business rules and quality thresholds | A finance analyst who defines “net revenue” and also approves changes to it |
| Technical data steward | Data engineering or the platform team | Lineage, metadata and rule checks in pipelines | An engineer who turns the revenue rule into a pipeline test and then tracks its lineage |
| Domain data steward | A business domain with its own data products | Coordination across business and technical stewards | A customer-domain lead who settles which “customer” record is the master |
Smaller firms often merge the business and domain roles into one person. That works well, as long as a technical counterpart is named for each critical dataset.
Datasheet
Elevate Data Governance, Compliance and Security of Your Organization
A Kanerika datasheet on how ownership, classification, access policies and audit evidence fit together, the structure stewards work inside every day.
View the Datasheet →Data Stewardship vs Data Governance vs Data Management
These three terms overlap in conversation, yet they describe different layers of the same system. Governance sets policy and decision rights, and stewardship runs those rules every day. Data management builds and operates the systems that hold the data.
Think of a city.Governance is the council that passes the parking rules, while stewardship is the traffic office that applies them street by street. Data management is the road crew that then paints the lines. Each one fails without the other two, so each one needs different people.
| Layer | Main question | Typical output |
|---|---|---|
| Data governance | Who may decide what, under which policy? | Policies, decision rights and a governance council |
| Data stewardship | Is this data defined, fit for use and used as permitted? | Definitions, quality rules, resolved issues and classifications |
| Data management | How is the data stored, moved and secured? | Pipelines, platforms, backups and access controls |
This guide stays on the stewardship layer. For the policy side, the pillars of data governance lay out the framework. The boundary between the other two layers is covered in data governance vs data management. Frameworks such as DAMA-DMBOK and the EDM Council’s DCAM also describe all three layers in more depth.
Data Owner vs Data Steward vs Data Custodian
Three roles carry most of the accountability for any dataset, so confusing them is a common reason programs stall. The owner is accountable, and the steward is responsible for daily fitness. The custodian runs the technology.
| Aspect | Owner | Steward | Custodian |
|---|---|---|---|
| Accountability | Final say on the data’s value, risk and use | Daily fitness for use, such as meaning, quality and classification | Safe storage, movement and technical controls |
| Typical title | VP or director of a business unit | Senior analyst, domain lead or data product manager | Data engineer, DBA or platform administrator |
| Decides | Who may access the data and for what purpose | Definitions, quality rules and issue priority | How controls are built and run |
| Does not decide | Field-level rules and daily triage | Policy changes or access outside approved roles | Business meaning or who should get access |
| Reports to | The governance council or executive sponsor | The data owner, while keeping a dotted line to governance | IT or platform leadership |
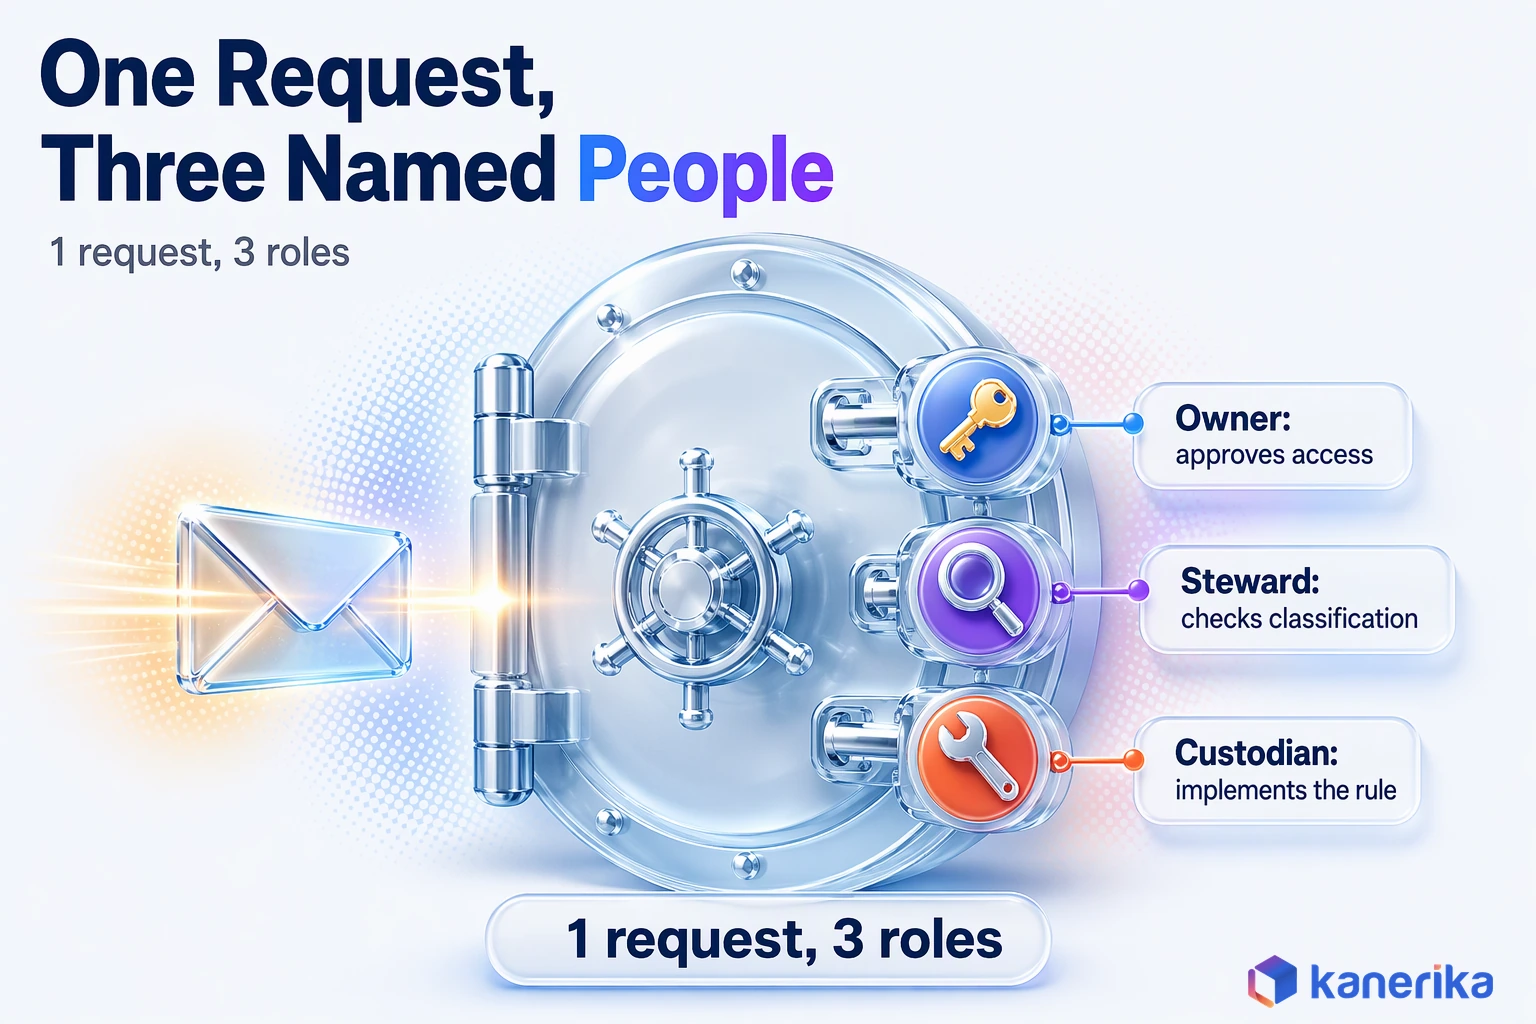
Access, for instance, shows the split clearly. The owner approves which roles may see salary data, while the steward checks that the classification is right. The custodian then implements the rule, for example through Power BI row-level security on the reports that expose it.
How Microsoft Purview Names These Roles
Microsoft Purview builds these roles into its Unified Catalog. Its governance roles documentation lists a Governance Domain Owner, a Data Product Owner, a Data Steward and a Data Quality Steward. The Data Quality Steward manages quality rules, scans, thresholds and alerts.
Microsoft also advises assigning at least two people as governance domain owners, so one absence never blocks a decision. Our guide to data governance with Microsoft Purview shows how those roles map to domains.
Microsoft announced in November 2026 that Purview’s data governance features, Unified Catalog included, move into the Microsoft Fabric OneLake catalog. Support for them ends on November 12, 2027. The role split still applies; only the tool that holds it changes.
Why Data Stewardship Matters More in 2026
Stewardship used to be a reporting hygiene topic, but three pressures have pushed it up the agenda. Each one turns an ownership gap into a cost that someone outside the data team will notice.
AI and analytics now consume the same shared data. A definition that once only confused a dashboard can now steer a model or an agent. So before anyone trains or grounds AI on a dataset, someone has to answer where it came from. That person also has to confirm whether the use is allowed.
Regulation asks for documented data practice. Article 10 of the EU AI Act requires governance and management practices for the training, validation and testing data of high-risk AI. Those practices cover design choices and data collection processes, as well as the origin of data. Similarly, GDPR Article 32 asks for security of processing, such as pseudonymization, encryption and the ongoing confidentiality, integrity and availability of systems. Those controls only land on the right fields if a steward has classified those fields first.
Bad data still has a price. In a 2016 Harvard Business Review article, Thomas C. Redman cited IBM’s estimate that poor-quality data cost the U.S. economy $3.1 trillion that year. The figure is old, but the mechanism has not changed, as the costs of bad data quality show.
The benefits follow from those pressures. Clear ownership means fewer conflicting numbers and faster answers to auditors. It also gives AI inputs that someone can defend, and it gives engineers one person to call when a rule needs to change.
Kanerika Service
Data Governance Services
Kanerika sets up owner, steward and custodian roles, decision rights and catalog rules so governance policy becomes daily practice across your data domains.
Explore Data Governance ServicesStewardship Operating Models: Centralized, Federated and Hybrid
An operating model decides where stewards sit and who they answer to. The choice matters because the same steward behaves differently in a central team than inside a sales department.
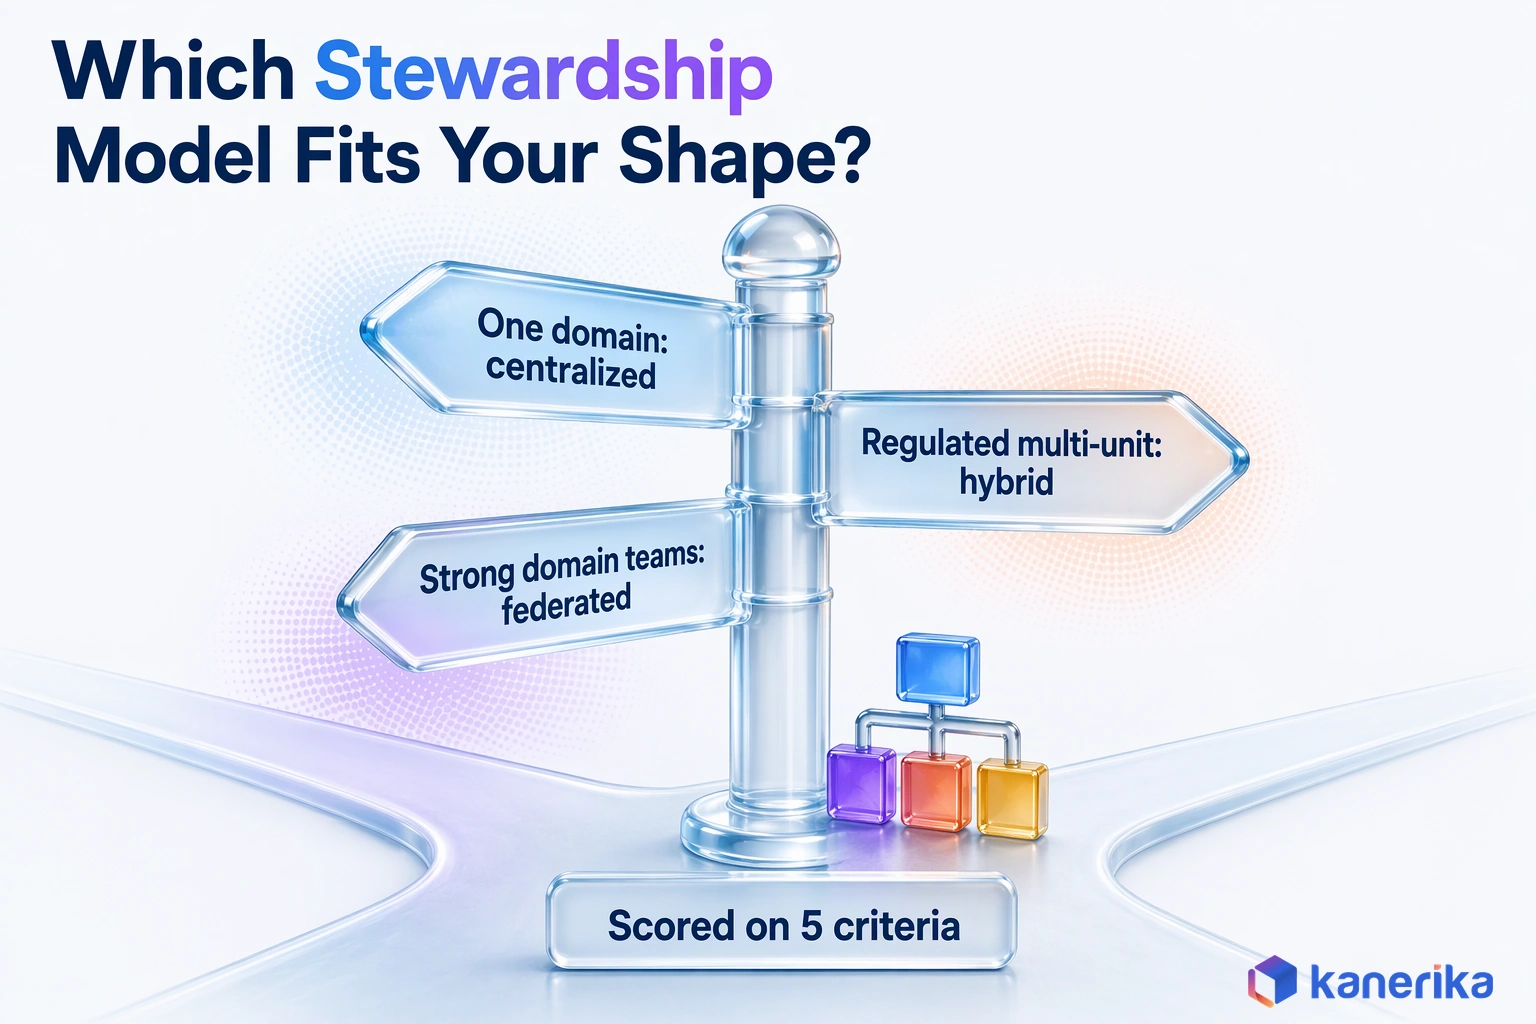
In a centralized model, one data office employs or directs all stewards. In a federated model, by contrast, each business domain names and funds its own stewards under shared standards. A hybrid model keeps a central council for policy and shared terms, while domains run their own day-to-day stewardship.
| Model | How it works | Main risk | Safeguard |
|---|---|---|---|
| Centralized | One data office sets rules and also staffs stewards | Bottlenecks, since the team sits far from business context | Named business contacts per domain and a service-level target for requests |
| Federated | Domains name and fund their own stewards | Definitions drift apart between domains | A shared glossary as well as a cross-domain escalation path |
| Hybrid | A central council for policy and shared terms, while domains handle daily work | Unclear split of authority between center and domains | A written RACI and a council that meets on a fixed cadence |
In practice, none of these models is the right answer for every company. Each one moves the same work to a different place, so the better question is which risk your organization handles best. The decision framework below answers it with five criteria you can score yourself.
How to Choose a Stewardship Model: A Decision Framework
Picking a model is easier when you score your own organization against a few plain criteria. Five factors predict which model will hold up, and none of them needs a consultant to measure.
| Criterion | Centralized fits | Federated fits | Hybrid fits |
|---|---|---|---|
| Number of business domains | One to three | Many, each with its own products | Many, though with shared core entities |
| Regulatory load | Light or a single regime | Light to moderate | Heavy, often under several regimes |
| Domain team capacity | Low, with few data-literate staff | High, since domains have staffed data teams | Uneven across units |
| Decision authority | Held centrally | Held by domain leaders | Split by policy and by domain |
| Platform maturity | One platform, still with an early catalog | Mature, self-service platform | Mixed estate during migration |
Count which column wins most rows, then test the result against three common shapes. The scenarios below are illustrations, not client stories.
Three Worked Scenarios
A single-domain mid-market firm on one platform. A distributor runs finance, sales and inventory from one ERP feeding one warehouse. It has two data analysts but no domain data teams, so a centralized model fits. One small team can then own the glossary and quality rules without slowing anyone down.
A regulated bank with several business units. Retail, commercial and wealth units share customer and account data under heavy regulation. A hybrid model fits here, because a central policy council owns classification and shared terms while each unit stewards its own products. The council’s written RACI also stops the center and the units from overruling each other.
A product-led company with strong domain teams. Each product line already has engineers, analysts and a product manager who own their data. A federated model fits, as long as a shared glossary covers the few entities every team touches. Pushing these teams into a central queue would instead slow them and push the work into side channels.
Whichever model wins, write the reason down. When the company changes shape, that note tells you which criterion moved and whether the model should move with it.
Data Stewardship Roles in a RACI Matrix
A RACI matrix turns role descriptions into answers for specific tasks. R does the work and A is accountable for the outcome. C is consulted before the decision, while I is informed after it.
The matrix below covers seven tasks that cause most ownership disputes. Use it as a starting point and adjust the letters to your model, but keep exactly one A per row.
| Task | Owner | Steward | Custodian | Council | Consumer |
|---|---|---|---|---|---|
| Define a business term | A | R | I | C | C |
| Set a quality rule and threshold | A | R | C | I | C |
| Fix a quality issue at the source | A | C | R | I | I |
| Approve and provision access | A | C | R | I | I |
| Classify sensitive data | C | R | C | A | I |
| Approve a dataset for AI training or retrieval | A | R | C | C | I |
| Retire a dataset | A | R | R | I | I |
In the access row, the owner approves (A), the custodian provisions (R) and the steward checks the classification (C). Two other rows deserve a closer look.Classification sits with the council because the scheme is a policy, even though the steward applies it field by field. AI approval stays with the owner since the owner carries the risk, while the steward gathers the evidence.
If a row has no clear A in your company today, that row is where the next dispute will start.
Talk to Kanerika
Which Rows in Your RACI Have No Clear Owner?
Kanerika reviews one data domain with your team, maps owners, stewards and custodians to the tasks that cause disputes, and shows where decision rights are missing.
Schedule a Demo →How Stewardship Works Day to Day: The Issue-to-Resolution Workflow
Most stewardship time goes into one loop: something looks wrong, and someone has to make it right for good. A shared workflow keeps that loop the same across domains, so issues do not depend on who happens to notice them.
- Detect: a quality rule fails, a monitor fires or a user reports a problem.
- Log: the issue goes into one tracker together with the dataset, rule and impact.
- Triage: the steward sets priority based on business impact and affected users.
- Assign: the issue then goes to the custodian, the source system team or the owner.
- Root cause: the team finds the point where the bad value first entered the data.
- Fix at source: the correction lands in the source system or pipeline instead of a report.
- Validate: the rule reruns and the steward confirms it passes on fresh data.
- Close and document: the steward finally updates the definition, rule or lineage note in the catalog.
Worked Example: Fixing “Active Customer”
Here is how the “active customer” problem from the opening runs through that loop. The issue is logged as a definition conflict on a board metric, so the customer-domain steward gives it high priority. Because three domains are involved, it goes to the data owner and, under a hybrid model, to the governance council.
Root cause shows the conflict is real rather than a bug, since each team wrote its own filter into its own report. The council approves one definition, billed within 90 days, and names two variants for sales and product use. Engineers then move the logic into one certified dataset in the warehouse.
Validation compares the old and new counts and explains the gap to each team. The steward closes the issue once the definition, its owner and its lineage are in the catalog. At the next board meeting, all three pages show one number.
How to Implement a Data Stewardship Program in Phases
A program that starts everywhere usually finishes nowhere. So phase it by use case, which keeps the first results visible and gives each phase a clear exit test before the next one starts.
- Pick one use case and its critical data elements. Choose a report, model or process that hurts today, then list the critical data elements it depends on. Exit when the list is agreed and every element has a source.
- Name owners and stewards. Assign one owner and at least one steward per element, with time allocations in writing. Exit once every element has names and signed time commitments.
- Publish definitions and rules in the catalog. Write each definition, its quality rules and its classification where users can find them. Exit when the use case’s consumers can look up every term.
- Run the issue workflow for one quarter. Log, triage and resolve real issues through the workflow above. Exit when issues close at source and the KPIs below have a baseline.
- Expand domain by domain. Add the next use case, while reusing the RACI, templates and tooling from the first. Exit criteria repeat for each new domain.
Phase three is also where stewardship meets engineering. Quality rules belong in pipelines as tests rather than in spreadsheets, which is why data engineering best practices such as automated validation matter here. Where the program sits on a wider scale is covered by the data governance maturity model.
How to Choose Stewards
Good stewards share three traits, and seniority is not one of them. First, they know the subject well enough to explain an odd value without opening a ticket. They also have the standing to refuse a request that breaks a rule. Finally, their manager has agreed in writing how many hours they spend on it.
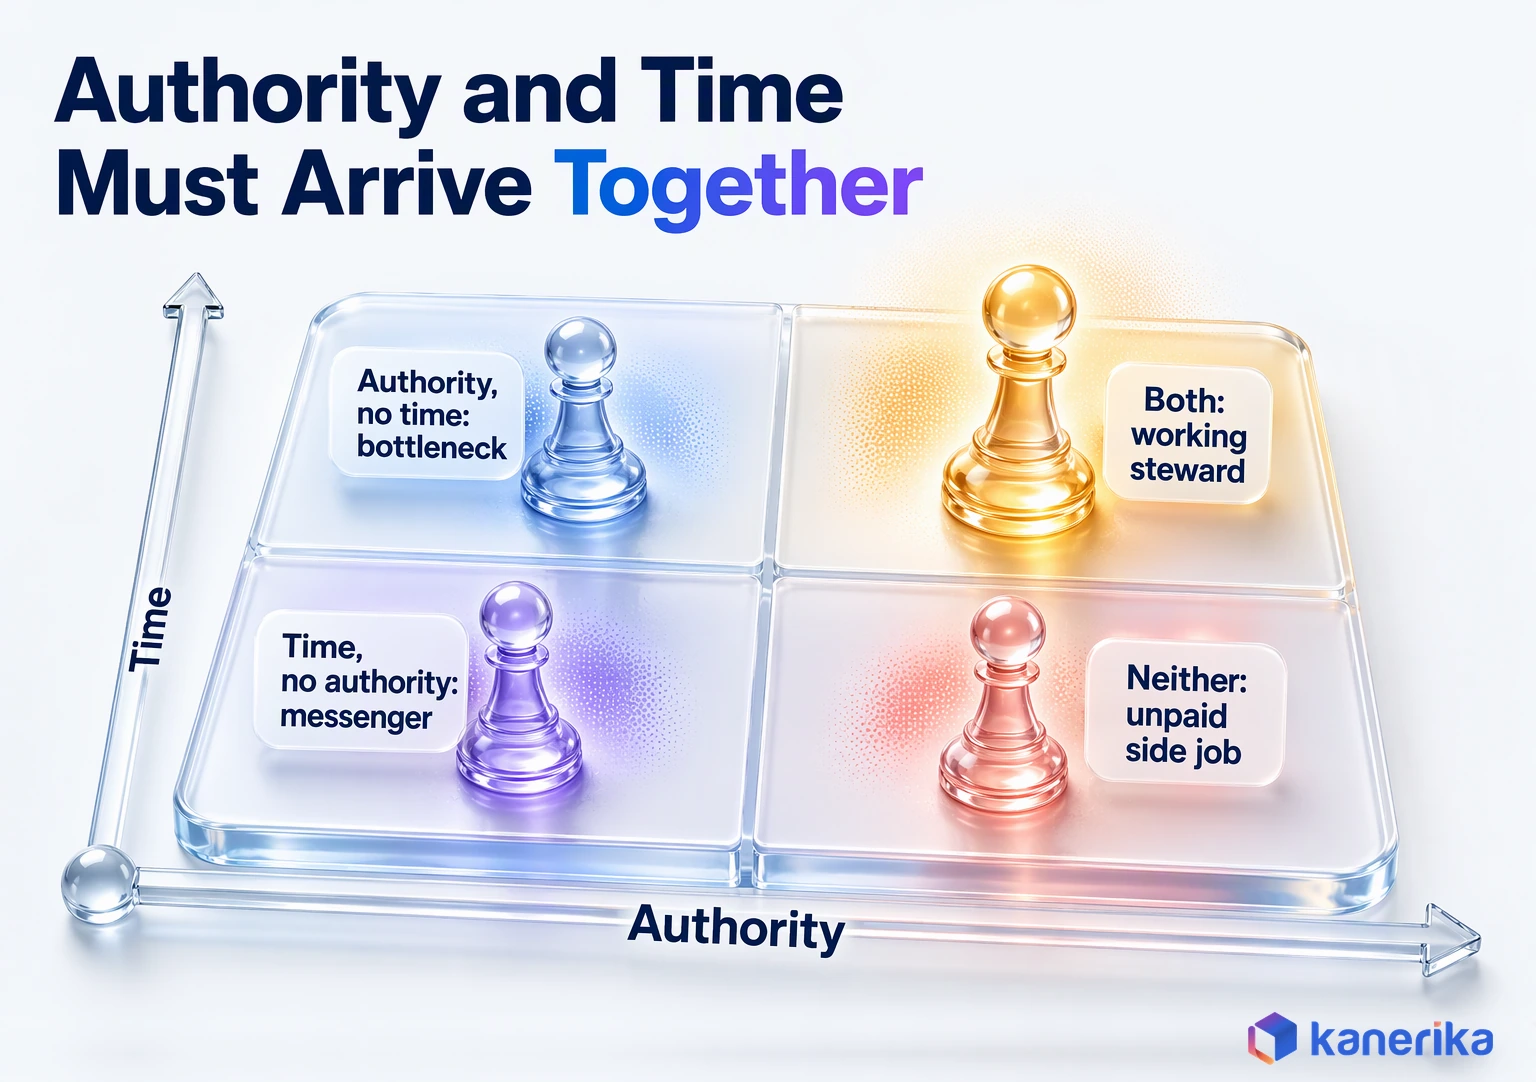
That last point is the one programs skip most often. Without a written allocation, stewardship becomes an unpaid side job, so it drops away during the first busy month. A short role charter, signed by the steward’s manager, prevents most of that.
Checklist
Data Governance Checklist
Kanerika’s data governance checklist covers ownership, definitions, quality rules and access policies, the groundwork every stewardship program needs before it scales.
Get the Checklist →Size the Effort From Workload, Not a Fixed Ratio
There is still no reliable industry ratio of stewards to employees or to datasets. A better approach counts the work itself, then converts it into hours. Four inputs cover most of it: critical data elements, the review cycle for each, open issues per month and change requests.
Take an illustrative domain with 120 critical data elements on a quarterly review cycle, at about 15 minutes per element. That is 30 hours a quarter, so roughly 10 hours a month. Add 25 issues a month at 2 hours each for triage and follow-up, which comes to 50 hours. Then add 8 change requests at 3 hours each, for another 24 hours.
The total is 84 hours a month. Compared to a working month of roughly 160 hours, that is about half of one person’s time. The numbers here are assumptions for the example, so replace each one with your own counts after the first quarter of the workflow.
Data Stewardship for AI: Training Data, RAG Sources and Agent Context
AI systems are new consumers of old data, and they raise the stakes of every gap in ownership. A model trained on an unapproved extract fails quietly, and so does an agent grounded on a stale policy document. Worse, both fail at scale.
The fix is to treat AI datasets like any other critical data. Training sets, RAG sources such as document libraries, and the context an agent reads all need a named owner and steward. Each one also needs a record of where the data came from, which mirrors the EU AI Act’s wording on the origin of data.
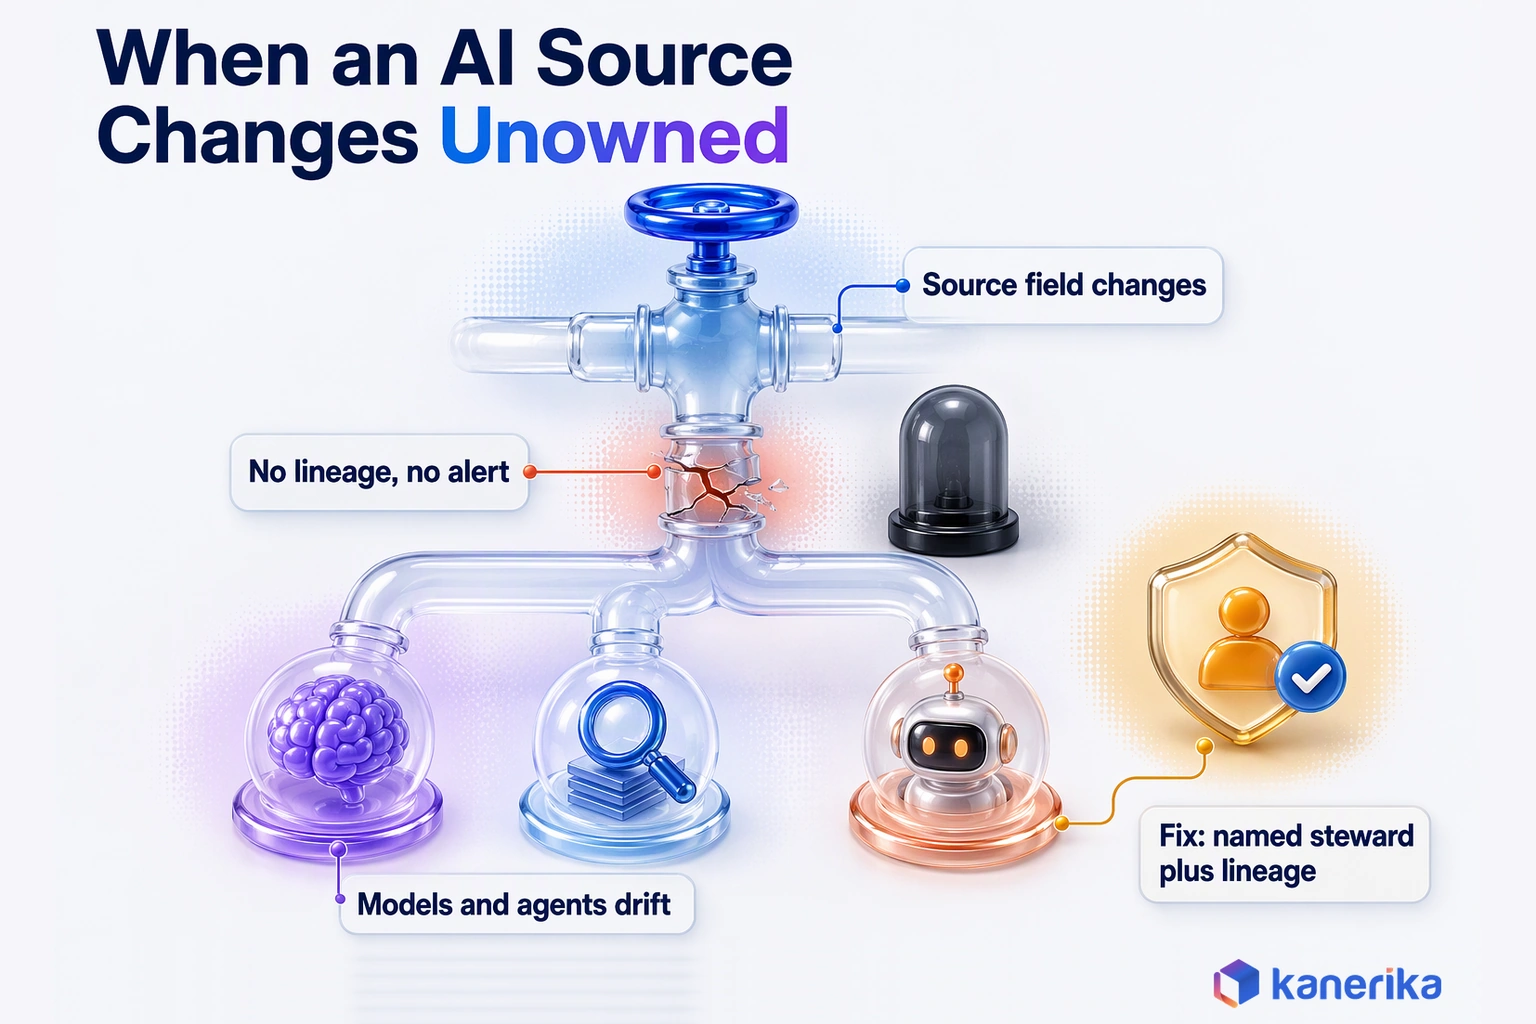
Above all, change control matters. When a source system changes a field, the steward has to know which models and indexes read it, and that depends on lineage. NIST first released its AI Risk Management Framework on January 26, 2023, and it is now under revision. The framework treats this as part of managing AI risk across the life cycle.
A Checklist for AI Data
A short checklist keeps AI data inside the program, so that new models do not create a second, unmanaged estate:
- Every training set, RAG source and agent knowledge base has a named owner and steward.
- The catalog records the origin, collection method and permitted use of each source.
- Sensitive fields are classified before data enters a training set or an index.
- Lineage links each source to the models, indexes and agents that consume it.
- A source change triggers a review of every downstream AI asset.
- Retired sources are removed from indexes as well as from reports.
Platform choice makes some of these steps easier, but it helps less than people hope. For the tooling side, see our guide to AI governance tools as well as how AI in data management changes daily operations.
Measuring Stewardship: KPIs That Show Progress
A program that cannot show progress soon loses its budget. The KPIs below measure whether stewardship is happening, and each one comes with a formula so that two teams calculate it the same way.
| KPI | Formula | Cadence | Owner |
|---|---|---|---|
| Critical-element coverage | Elements with a named owner, steward, definition and rule ÷ critical elements in scope | Monthly | Program lead |
| Mean time to resolve issues | Sum of days from log to close ÷ issues closed in the period | Monthly | Domain steward |
| Quality rule pass rate | Records passing a rule ÷ records tested by that rule | Daily or per load | Technical steward |
| Definition adoption | In-scope reports and datasets using the certified definition ÷ all in-scope reports and datasets | Quarterly | Business steward |
| Access review turnaround | Median days from access request to decision | Monthly | Data owner |
Keep operational measures apart from business outcomes. The table tracks activity and control, whereas outcomes are things like fewer restated reports, shorter audit preparation or faster model approval. Report both, but never claim an outcome the operational numbers cannot explain.
Set your own targets after one quarter of baseline data. Published benchmarks rarely match your scope, so a target copied from elsewhere tends to be gamed or ignored.
Data Steward Tools: Catalog, Quality, MDM and Lineage
Tools make stewardship visible and repeatable, but they do not create it. Each tool category supports one or two steps of the workflow, so it helps to map them before buying anything.
| Category | Supports these workflow steps | Examples |
|---|---|---|
| Data catalog and glossary | Publish definitions, record owners, then close and document | Microsoft Purview, Collibra, Alation and Informatica |
| Data quality and observability | Detect and validate | Rule engines and monitors inside the platform or pipeline |
| Master data management | Fix at source for shared entities such as customer or product | MDM hubs that hold golden records |
| Lineage | Root cause, as well as change impact for reports and AI assets | Catalog lineage views and pipeline metadata |
| Issue tracking | Log, triage and assign | The ticketing tool your teams already use |
Microsoft Purview, Collibra, Alation and Informatica appear here as examples of catalog and governance platforms, not as a ranking. For a closer comparison, see our reviews of data governance tools and the AI data catalog. The split between monitoring and quality is also explained in data observability vs data quality.
Ownership also extends to operational data. Logs and telemetry have retention rules and sensitive fields, so Azure monitoring tools need a named steward as much as any sales table. Where mastered data needs full history and audit trails, data vault modeling keeps every change traceable.
Kanerika Service
Purview Governance and the Move to Fabric
Kanerika configures governance domains, steward roles, classification and quality rules in Purview today, and carries them into the Fabric OneLake catalog as Microsoft moves governance there.
Explore Purview ServicesWhat tools cannot replace is decision rights and time. A catalog can show an empty owner field, but it cannot fill it, and an alert cannot triage itself. So budget for steward hours before licenses, and the tools will then have something to support.
Common Stewardship Challenges and How to Fix Them
Stewardship programs tend to fail in the same few ways, whatever the industry. The good news is that each failure shows early symptoms, so you can fix it before the program loses trust.
| Challenge | Symptom | Fix |
|---|---|---|
| Stewardship as an unpaid side job | Issues sit untouched during busy months | Written time allocation, signed by the steward’s manager |
| No decision rights | Stewards take notes while others decide | Publish the decides and escalates lists for each domain |
| Tool-first rollout | A catalog full of empty owner fields | Name owners and stewards before the catalog goes live |
| Definitions without enforcement | The glossary says one thing, but reports say another | Turn rules into pipeline tests and certify datasets |
| Steward burnout | One person holds every domain’s issues | Size effort from workload and also add a backup steward |
| Cross-domain disputes | The same argument returns every quarter | A council with a fixed cadence as well as a written escalation path |
Behind most of these sits a simple principle: authority and time must arrive together. A steward with authority but no time becomes a bottleneck, while one with time but no authority becomes a messenger. More patterns appear in our list of common data governance challenges and in these data governance principles.
Another frequent mix-up is treating integrity and quality as one problem. In practice, the difference between data integrity vs data quality decides whether a custodian or a steward owns the fix.
How Kanerika Runs Stewardship Programs
Kanerika runs stewardship as a staged program, and every stage ends with something the client can use on its own. We start with one use case and its critical data elements. Then we set up owner, steward and custodian roles, together with a RACI the business signs off.
On Microsoft estates, we configure governance domains and steward roles in Purview Unified Catalog today, and in the Fabric OneLake catalog as Microsoft moves governance there. We then build classification and quality rules for the data in scope. The issue workflow and KPIs go live next, and the engagement closes with user guides so teams can run the program themselves. Our data governance services and Microsoft Purview practice cover both the operating model and the platform work.
For a top North American healthcare organization, Kanerika built a centralized Purview catalog and a classification framework covering data classifications, steward roles and usage policies. The work produced a 90% increase in compliance adherence, a 57% reduction in data discovery time, 70% better data accessibility and 35% higher data accuracy.
Case Study
90% Compliance Adherence for Healthcare with Purview
A top North American healthcare organization got a centralized Purview catalog with steward roles and usage policies, cutting data discovery time 57% and raising data accuracy 35%.
Read the Case Study →Kanerika holds ISO 27001, ISO 27701 and ISO 9001:2015 certifications, as well as SOC 2 Type II compliance and a CMMI Level 3 appraisal. It is also a Microsoft Solutions Partner for Data and AI. Sector detail is covered in data governance in healthcare and data governance in banking.
Bottom Line
Data stewardship is less about software than about who decides. So name an owner, a steward and a custodian for each critical dataset, and write down what each one may decide.
Then let the company’s shape pick the model. One dominant domain points to centralized, regulated units sharing data point to hybrid, and strong domain teams point to federated. Run the RACI, the workflow and the KPIs one domain at a time.
Start with the metric that caused your last board-meeting argument, the way “active customer” did, and run it through the workflow this quarter.
Frequently Asked Questions
What is data stewardship?
Data stewardship is the operating accountability for the meaning, quality and permitted use of a defined set of data. Named stewards keep definitions current, set quality rules, classify sensitive fields and resolve issues at the source. It turns governance policy into daily practice, so every critical dataset has a person who can explain it and fix it.
Is data stewardship the same as data governance?
No. Data governance sets the policies and decides who holds which decision rights. Data stewardship runs those rules every day by defining terms, monitoring quality and handling issues within a domain. Data management then builds and operates the systems. Governance without stewardship produces policies nobody applies, while stewardship without governance has no authority behind it.
How does data stewardship support AI?
Stewardship gives every training set, RAG source and agent knowledge base a named owner and steward. They record where the data came from, how it was collected and what use is permitted, and they classify sensitive fields before data enters a model or index. Lineage lets a source change trigger a review of every model and agent that reads it.
Who is accountable for data quality?
The data owner is accountable for the quality of a dataset, while the steward is responsible for defining quality rules and thresholds and for triaging failures. Custodians and source system teams carry out the fixes at the source. Consumers report problems they find. A RACI matrix with one accountable person per task keeps these lines from blurring.
What is the difference between a data steward, data owner, and data custodian?
The data owner is accountable for a dataset and approves who may use it and why. The data steward keeps it fit for use by managing definitions, quality rules, classification and issue triage. The data custodian, usually an engineer or administrator, implements storage, movement and access controls. Owners decide, stewards define and monitor, and custodians build the controls.
What are the three operating models for data stewardship?
The three models are centralized, federated and hybrid. A centralized model places stewards in one data office, which suits a single domain on one platform. A federated model lets each domain fund its own stewards under shared standards. A hybrid model keeps a central council for policy and shared terms while domains handle their daily stewardship work.
What tools does a data steward use?
Stewards mainly work in a data catalog and business glossary, such as Microsoft Purview, Collibra, Alation or Informatica. They also rely on data quality rules and monitors, master data management for shared entities like customer, lineage views for impact analysis, and an issue tracker. Tools support the workflow, but they cannot replace decision rights or steward time.
How long does it take to stand up a data stewardship program?
Timing depends on scope, so plan by phases rather than a fixed date. Start with one use case and its critical data elements, then name owners and stewards and publish definitions in the catalog. Run the issue workflow for one full quarter to set a baseline. After that, expand one domain at a time using the same templates.
What does a data steward do day to day?
A data steward reviews failed quality rules and new issues, sets their priority and assigns each one to the right team. They answer questions about definitions, approve changes to business terms and check that fixes land at the source. They also update the catalog with definitions, lineage notes and classifications, and they escalate cross-domain disputes or access exceptions.
What is the difference between a business data steward and a technical data steward?
A business data steward sits in a function such as finance or sales and owns the meaning of the data, including definitions, business rules and quality thresholds. A technical data steward sits in data engineering and owns how those rules run in practice through pipeline tests, metadata and lineage. Most critical datasets need one of each, working as a pair.
How many data stewards does an enterprise need?
There is no reliable fixed ratio, so size stewardship from workload instead. Count critical data elements, monthly issues, change requests and review cycles, then estimate the hours each one takes. One illustrative domain with 120 elements, 25 issues and 8 changes a month needed about 84 hours, which is roughly half of one person’s working time.
How do you measure data stewardship success?
Track five operational KPIs with fixed formulas. These are critical-element coverage, mean time to resolve issues, quality rule pass rate, definition adoption and access review turnaround. Report business outcomes separately, such as fewer restated reports or shorter audit preparation. Set targets only after one quarter of baseline data, because copied benchmarks rarely match your own scope.