TL;DR
Choose Databricks if most of your effort goes into preparing data before any model is trained. Choose Amazon SageMaker AI if your data already sits in AWS and your team mainly builds models. Both platforms can train, track and serve machine learning models. Databricks runs on AWS, Azure and Google Cloud, and SageMaker runs only on AWS. In December 2024, AWS renamed its ML service SageMaker AI and reused the SageMaker name for a wider platform. The simplest Databricks vs SageMaker test is to ask which team will run these models after launch.
Key Takeaways
- Amazon renamed its machine learning service to Amazon SageMaker AI on 3 December 2024 and gave the name Amazon SageMaker to a new unified data, analytics and AI platform.
- Databricks sells one platform that covers data engineering, analytics and AI. AWS instead sells a set of services that you assemble, now presented through a single studio.
- Databricks bills in Databricks Units on top of cloud compute you also pay for. SageMaker AI bills per second, per component, with Savings Plans available.
- Both platforms now run managed MLflow. However, only AWS charges an hourly fee for the tracking server that hosts it.
- Databricks is a managed platform with a split control plane and compute plane, so the SaaS or PaaS question keeps coming up in security reviews.
- Plenty of enterprises run both, so the useful question becomes which platform owns governance and which one owns model serving.
The Comparison Changed Under Everyone’s Feet
AWS documentation opens with a sentence that quietly invalidates most of what has been written about this decision. “On December 03, 2024, Amazon SageMaker was renamed to Amazon SageMaker AI.” The same page adds that Amazon released “the next generation of Amazon SageMaker”.
It calls that product “a unified platform for data, analytics, and AI”. Both lines come from the Amazon SageMaker AI Developer Guide.
As a result, two products now share one family name. A 2024 article about “Amazon SageMaker” and a 2026 article about “Amazon SageMaker” describe two different things. Google’s People Also Ask box on this query now asks “Is SageMaker deprecated?”
Databricks moved too. It shipped Agent Bricks, renamed Delta Live Tables to Lakeflow pipelines, and reported a $7 billion revenue run-rate in August 2026. This Databricks vs SageMaker guide therefore compares both as they exist today, sourced to vendor documentation.
Databricks vs SageMaker: The Short Answer
The two platforms started from different ends of the same problem. Databricks began as a place to process large volumes of data and grew upward into machine learning. Amazon, by contrast, began with a managed machine learning service and grew outward into data and analytics.
That history still shapes both products. It also explains why one feels like a single workspace and the other feels like a set of well-integrated services.
Where Databricks Wins
Databricks is the stronger choice when heavy data preparation sits between raw sources and any model. Delta Lake gives transactional guarantees on object storage, while Spark handles distributed processing at volumes that would need separate AWS services to match. Delta Lake is also open source, so those tables are not locked to a single engine.
It also wins on portability. The platform runs the same way on AWS, Microsoft Azure and Google Cloud, so a multi cloud mandate does not force a rewrite. Governance is the third advantage, because Unity Catalog covers tables, volumes, models and functions under one permission model.
Case Study
Zero-Downtime Databricks Migration for Retail Analytics
How a large US retailer moved off distributed PostgreSQL and Cassandra onto Databricks with zero production downtime, decommissioned 100% of its legacy infrastructure and centralized governance and lineage.
Read the Case Study →Where Amazon SageMaker Wins
SageMaker AI wins when the data already sits in Amazon S3 and Amazon Redshift, and when the team knows AWS identity and networking. Nothing has to be re-platformed, so access control stays inside IAM policies the security team already reviews.
Deployment is the second advantage. For example, SageMaker AI offers four distinct inference modes out of the box, including a serverless option that removes capacity planning entirely. Organisations with existing AWS commitments also get Savings Plans, which Databricks cannot apply to its own consumption charge.
What Actually Decides It
Feature tables rarely settle this, which is why a structured enterprise AI platform evaluation looks past them. In practice, two questions do most of the work. Where does the data that feeds your models physically live today, and which team will still be responsible for those models eighteen months after launch?
If the answer to the second question is a central data engineering group, Databricks usually fits, because the same people own the pipelines and the models. If the answer is a platform or cloud team that already runs AWS, SageMaker AI usually fits, because the operating model does not change.
Table 1: Databricks and Amazon SageMaker at a Glance
| Dimension | Databricks | Amazon SageMaker AI |
|---|---|---|
| What you buy | One platform covering data, analytics and AI | A managed ML service inside a wider AWS platform |
| Storage foundation | Delta Lake on your object storage | Amazon S3, with SageMaker Lakehouse on Apache Iceberg |
| Governance | Unity Catalog across data and AI assets | IAM, AWS Lake Formation and SageMaker Catalog |
| Experiment tracking | Managed MLflow 3, no separate server charge | Managed MLflow on an hourly tracking server |
| Serving | Mosaic AI Model Serving, optional scale to zero | Real time, serverless, asynchronous and batch |
| Clouds | AWS, Azure, Google Cloud | AWS only |
| Billing shape | DBUs plus separate cloud infrastructure | Per second per component, Savings Plans available |
| Best fit | Data engineering heavy, multi cloud, central platform team | AWS native, ML focused, existing AWS operating model |
What Changed in Databricks and SageMaker Since 2024
Both vendors reorganised their products in the last two years. Comparisons written before those changes describe features that have moved, been renamed, or been folded into something larger.
Amazon Split SageMaker Into Two Products
The service that trains and hosts models is now Amazon SageMaker AI. Its APIs, CLI commands, IAM policy prefixes, CloudFormation resource names and console URLs all kept the old sagemaker spelling for backward compatibility, so nothing broke in existing accounts.
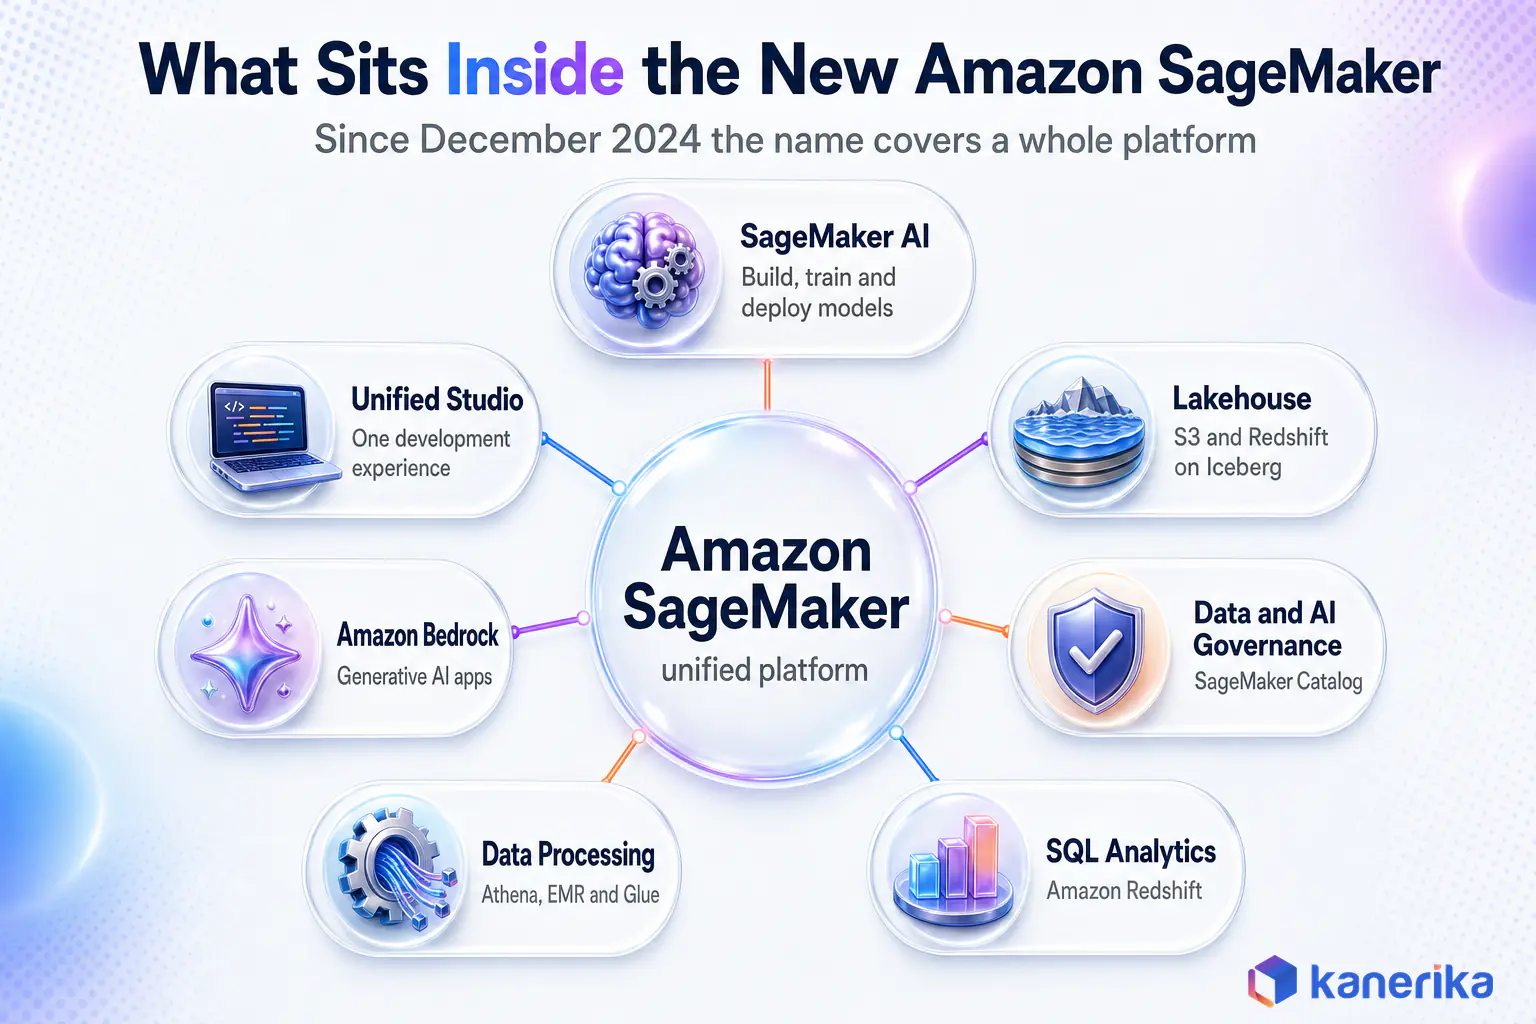
Meanwhile, the name Amazon SageMaker now belongs to a larger platform. Specifically, AWS lists seven capabilities inside it.
They are SageMaker AI, SageMaker Lakehouse, SageMaker Data and AI Governance, and SQL Analytics on Amazon Redshift. The other three are SageMaker Data Processing on Athena, EMR and AWS Glue, SageMaker Unified Studio, and Amazon Bedrock.
SageMaker Unified Studio is, above all, the part that changes daily work. AWS describes it as “a unified development experience that brings together AWS data, analytics, artificial intelligence (AI), and machine learning (ML) services”, with projects as the unit of collaboration.
Databricks Moved From Lakehouse Analytics Into Agent Production
Three changes matter for this decision. Delta Live Tables became Lakeflow Spark Declarative Pipelines, and Databricks Workflows became Lakeflow Jobs, both under the Lakeflow name. Existing pipeline code still runs, and Databricks also states plainly that “there is no migration required to use Lakeflow pipelines”.
Agent Bricks arrived as a way to build agents against enterprise data. It offers a Knowledge Assistant for domain chatbots and a Supervisor Agent that orchestrates Genie Agents, model endpoints, Unity Catalog functions and MCP servers. At the same time, MLflow 3 became the tracking layer, adding logged models, tracing and agent evaluation.
The commercial signal also moved with the product. Databricks reported a $7 billion revenue run-rate growing more than 80% year over year on 13 August 2026, with over 1,000 customers consuming at more than $1 million run-rate each.
The Rename Trap in Scoping and Contracts
This is where the rename stops being trivia. For example, a statement of work that says “Amazon SageMaker” and was drafted from a 2024 reference describes a managed training and hosting service. However, the same words signed in 2026 can reasonably be read as the whole unified platform, including Redshift, Glue, EMR and Bedrock.
Two consequences follow. Budget estimates built on the narrow reading come in low, because the broad reading pulls in analytics and data processing charges. Security reviews also widen, since the unified platform touches services the original review never covered.
The fix is cheap. In practice, write “Amazon SageMaker AI” whenever you mean model training and hosting, and spell out the individual AWS services whenever you mean the platform. Do the same in architecture diagrams, because a box labelled SageMaker no longer tells a reviewer what is inside it.
What Is Databricks in 2026?
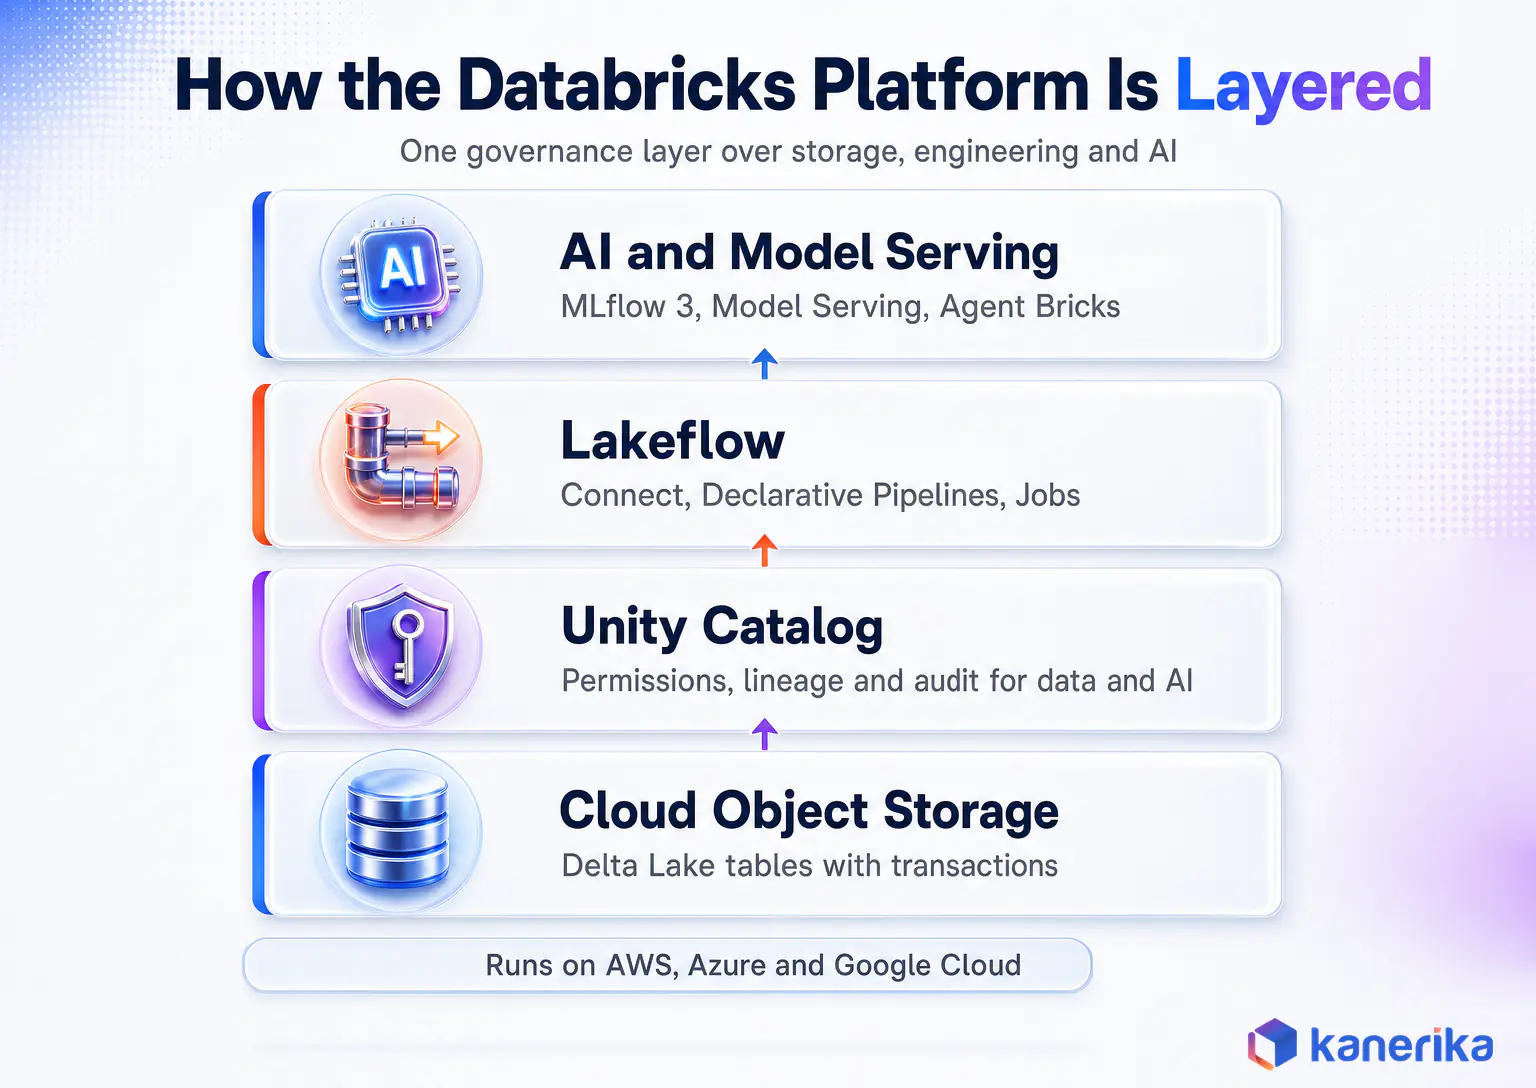
Databricks calls itself “a unified, open analytics platform for building, deploying, sharing, and maintaining enterprise-grade data, analytics, and AI solutions at scale”. In practice it is three stacks sharing one governance layer and one compute model.
The Lakehouse Foundation: Delta Lake and Unity Catalog
Delta Lake sits on your own object storage and adds transactions, schema enforcement and time travel to files that would otherwise be plain Parquet. That is also what allows analytics and training to read the same tables without a nightly copy into a warehouse.
Unity Catalog, in turn, is the governance layer above it. It secures tables, views and volumes alongside models, functions and services, under a three level catalog.schema.object namespace. It has also been on by default for every workspace created since 8 November 2023.
The practical effect, then, is one permission model for a feature table and the model trained on it. Row and column filters, attribute based policies, lineage and audit logging all apply to both, because they live in one catalog. Teams moving off an older Hive metastore can follow a Unity Catalog migration playbook rather than rebuilding permissions by hand.
The AI Stack: Model Serving, Managed MLflow and Agent Bricks
Model Serving handles four endpoint types. Custom models packaged in MLflow format, and Databricks-hosted foundation models billed per token. Provisioned throughput covers workloads that need guaranteed performance, and external models such as OpenAI’s route through the same governed gateway.
Databricks documents the serving tier as able to “support over 25K queries per second with an overhead latency of less than 50 ms”. Endpoints can also scale to zero, which the endpoint configuration guide flags as unsuitable for production because capacity is not guaranteed and the next request pays a cold start.
Next, managed MLflow 3 records runs, parameters, metrics and traces. Agent Bricks then builds on that for generative work, and production ML pipelines on Databricks tend to wire the registry in Unity Catalog straight into a serving endpoint.
The Data Engineering Stack: Lakeflow
Lakeflow covers three jobs. Lakeflow Connect brings source data in first, Lakeflow Spark Declarative Pipelines then transforms it, and Lakeflow Jobs finally orchestrates the whole run on a schedule or a trigger.
Even so, the declarative style is the part that changes how teams work. You describe the tables you want and the expectations they must meet, and the runtime then works out the execution order and the incremental refresh. Our guide to Databricks Lakeflow walks through the pipeline model in more depth.
One naming note for anyone reading older material. Python code that says import dlt still runs, though Databricks now recommends from pyspark import pipelines as dp for forward compatibility with Apache Spark Declarative Pipelines.
What Is Amazon SageMaker in 2026?
Answering this properly means answering it twice, once for the service and once for the platform. The service is what most teams mean when they say SageMaker. The platform, on the other hand, is what AWS now sells under that name.
Amazon SageMaker AI, the Renamed Machine Learning Service
AWS describes SageMaker AI as “a fully managed machine learning (ML) service” for building, training and deploying models into “a production-ready hosted environment”. It also carries the pieces practitioners already know, including Studio notebooks, built-in algorithms, automatic model tuning, JumpStart, Canvas and Ground Truth.
Deployment is where the service is strongest, as the SageMaker AI inference guide lays out. Real time endpoints serve low latency traffic, and serverless inference removes capacity management at the cost of cold starts.
Asynchronous inference queues requests with payloads up to 1 GB and processing times up to one hour. Batch transform handles offline scoring.
Everything binds to AWS identity. MLflow REST operations, for example, appear as IAM actions under a sagemaker-mlflow prefix, so an existing policy review covers them without a new access model.
SageMaker Unified Studio
Unified Studio is the single front door to those services. First, an administrator sets up a domain, invites users through single sign on or IAM, and work happens inside projects that hold shared data, compute and artefacts.
For a team that previously moved between the Redshift console, Glue, EMR, Athena and SageMaker Studio, this is a real reduction in context switching. It does not, however, merge the billing lines underneath, which matters when you model cost.
SageMaker Lakehouse and Data and AI Governance
SageMaker Lakehouse is AWS’s answer to the lakehouse pattern. AWS describes it as built on “an open lakehouse architecture, fully compatible with Apache Iceberg”, unifying data across S3 data lakes, S3 Tables and Amazon Redshift warehouses.
Data reaches it three ways. Zero-ETL integrations with operational databases and applications, query federation to other sources, and catalog federation for remote Iceberg tables. That means any Iceberg-compatible engine can read the same data in place.
Finally, governance sits in SageMaker Catalog, which AWS built on Amazon DataZone. Compared with Unity Catalog, the scope is narrower on the AI side, since model and function permissions still live largely in IAM rather than in the catalog itself.
Databricks vs AWS SageMaker: Feature by Feature
Every row below traces to published vendor documentation. Where a real limit or unit exists, it is stated instead of an adjective.
Table 2: Capability Comparison, Databricks and Amazon SageMaker AI
| Capability | Databricks | Amazon SageMaker AI |
|---|---|---|
| Ingestion and transformation | Lakeflow Connect, Declarative Pipelines, Lakeflow Jobs | AWS Glue, EMR and Athena, orchestrated separately |
| Distributed processing | Spark is native to the platform | Spark runs on EMR or Glue, called from SageMaker AI |
| Experiment tracking | Managed MLflow 3 with tracing and agent evaluation | MLflow 3.0 tracking servers and MLflow Apps on 3.10 |
| Model registry | Registry inside Unity Catalog, same permissions as data | SageMaker Model Registry, auto-registered from MLflow |
| Real time serving | Documented at 25K+ QPS, under 50 ms overhead latency | Real time endpoints with auto scaling on traffic |
| Idle cost control | Scale to zero, not advised for production | Serverless inference, async endpoints scale to zero |
| Large payload inference | Batch scoring through jobs on the lakehouse | Async inference up to 1 GB and one hour per request |
| Foundation models | Pay per token APIs, provisioned throughput, external models | JumpStart in SageMaker AI, Amazon Bedrock alongside it |
| Agent tooling | Agent Bricks, Knowledge Assistant, Supervisor Agent | Bedrock Agents, assembled with SageMaker AI hosting |
| Governance scope | Data and AI assets in one catalog with lineage | IAM, Lake Formation and SageMaker Catalog on DataZone |
| Audit trail | Unity Catalog activity logging | CloudTrail management and data events, EventBridge |
| Cloud availability | AWS, Azure and Google Cloud | AWS regions only |
Data Engineering and Pipelines
Databricks treats pipelines as first class objects inside the same workspace as the models. One team writes the ingestion, the transformation and the training job, and one scheduler then runs all three.
AWS instead distributes the same work across Glue, EMR, Athena and Step Functions, with SageMaker Pipelines covering the machine learning steps. The parts are strong individually, but the integration effort is real. Teams comparing broader options often review data engineering tools before committing either way.
Experiment Tracking and the Model Registry
Both platforms now run MLflow, which removes what used to be a clear Databricks advantage. Instead, the difference is where the registry lives and what governs it.
On Databricks the registry is a Unity Catalog object, so a model inherits the same permission model as the tables it was trained on. On AWS, models register into SageMaker Model Registry and permissions come from IAM, which is familiar but separate from whatever governs the underlying data.
Kanerika Service
Databricks Consulting and Implementation
Lakehouse architecture, Unity Catalog governance and production ML pipelines on Databricks, delivered by a Databricks Consulting Partner.
Explore Databricks Services →Model Deployment and Inference
This is the clearest split in the whole comparison. First, AWS gives you four named inference shapes with documented limits. Databricks, for its part, gives you one serving surface that covers custom models, foundation models and agents through the same endpoint type.
Table 3: Inference Options Side by Side
| Workload shape | Amazon SageMaker AI | Databricks |
|---|---|---|
| Interactive, low latency | Real time endpoint, billed by instance hour | Model Serving endpoint sized CPU, CPU_MEDIUM or GPU |
| Spiky with idle gaps | Serverless inference, billed by the millisecond | Scale to zero on the endpoint, cold start on wake |
| Large inputs, long processing | Asynchronous inference, up to 1 GB and one hour | A job on the lakehouse writing results to a table |
| Offline scoring of a whole table | Batch transform, billed only while the job runs | Batch inference from a notebook or Lakeflow job |
| Foundation model calls | JumpStart hosting, or Bedrock as a separate service | Pay per token, or provisioned throughput when guaranteed |
Read that table as a map of cost shapes. A model serving bursty internal traffic costs very little on SageMaker serverless inference and quite a lot on an always-warm endpoint. The same logic decides whether Databricks scale to zero is worth the cold start.
Governance, Lineage and Access Control
Unity Catalog applies one policy surface to tables, volumes, models, functions and services, with lineage tracked as those assets are used. Row filters, column masks and attribute based policies also sit in the same place.
AWS, on the other hand, spreads the same responsibilities across IAM for permissions, Lake Formation for table level control, SageMaker Catalog for discovery, and CloudTrail for the audit trail. Nothing is missing, although the joins between them are yours to maintain. Teams running formal controls often pair this with a wider data governance programme.
Performance, Scaling and Ease of Use
Both platforms scale well past what most enterprises need, so raw ceilings rarely decide anything. The real difference, therefore, shows in who does the tuning.
For example, Databricks exposes cluster configuration, autoscaling policies and spot instance strategy, which gives a skilled team room to cut cost and gives an unskilled team room to waste it. SageMaker AI abstracts more of that away, which lowers the floor and also lowers the ceiling on fine grained optimisation.
Skills follow the same pattern. Databricks asks for Spark and distributed computing knowledge to get real value, while SageMaker AI asks for AWS fluency. Neither is harder in the abstract, so the one your team already has is the cheaper one.
Multi-Cloud and the Azure Databricks Question
Databricks runs the same platform on AWS, Azure and Google Cloud, and Azure Databricks is also a first party Azure service billed through Microsoft. For an organisation already standardised on Azure, that is mainly a procurement advantage.
SageMaker AI, however, is available only in AWS regions, which costs nothing inside an AWS estate. It becomes a constraint the moment a merger, a customer requirement or a sovereignty rule puts workloads somewhere else. Organisations weighing broader platform moves sometimes compare this against AWS, Azure and Google Cloud as a whole.
Databricks Managed MLflow vs AWS Managed MLflow
MLflow used to be shorthand for “the Databricks way of tracking experiments”. AWS now offers it as a managed capability too, which turns it into a like-for-like comparison.
How Databricks Runs MLflow 3
MLflow on Databricks is part of the workspace rather than a resource you provision. Logging a model creates a LoggedModel that persists across its lifecycle, tracing records inputs, outputs and metadata at every intermediate step, and the registry lives in Unity Catalog.
Agent Evaluation runs on top of the same tracking data, so generative work is measured with the same machinery as a classification model. There is no separate server to size, start or stop.
How AWS Runs MLflow on SageMaker AI
AWS gives you two shapes. A classic MLflow Tracking Server, available on MLflow 3.0, 2.16 or 2.13, and a newer MLflow App on MLflow 3.10. The tracking server’s compute and metadata store run in the SageMaker AI service account, while artefacts land in an S3 bucket in your own account.
Sizing is explicit. AWS recommends a Small server for up to 25 users, Medium for up to 50 and Large for up to 100. Sustained throughput is 25, 50 and 100 transactions per second respectively.
Tracking servers launch into a single availability zone, and SageMaker AI MLflow enforces a 200 MB download size limit.
Integration is the payoff. Models registered in MLflow can auto-register into SageMaker Model Registry and deploy to a SageMaker AI endpoint through ModelBuilder, while CloudTrail and EventBridge log and route the activity.
The Billing Difference Nobody Mentions
Here is the line that changes budgets. AWS pricing states that for MLflow “customers pay for compute based on the size of the Tracking Server and number of hours it was running”. It publishes a Small server at $0.60 per hour and a Medium at $1.40, plus $0.10 per GB-month for metadata storage.
Run a Small tracking server continuously and that is roughly $432 a month before anyone logs a single experiment. Uptime drives the charge, which surprises teams who expect a tracking tool to bill by use.
Two practical responses exist. Stop the tracking server when the team is not using it, since AWS exposes start and stop operations for exactly this reason. Otherwise, size it honestly against concurrent users rather than headcount.
On Databricks the question does not arise, because tracking is part of the platform charge.
Generative AI and Agents: Where the Platforms Diverge Most
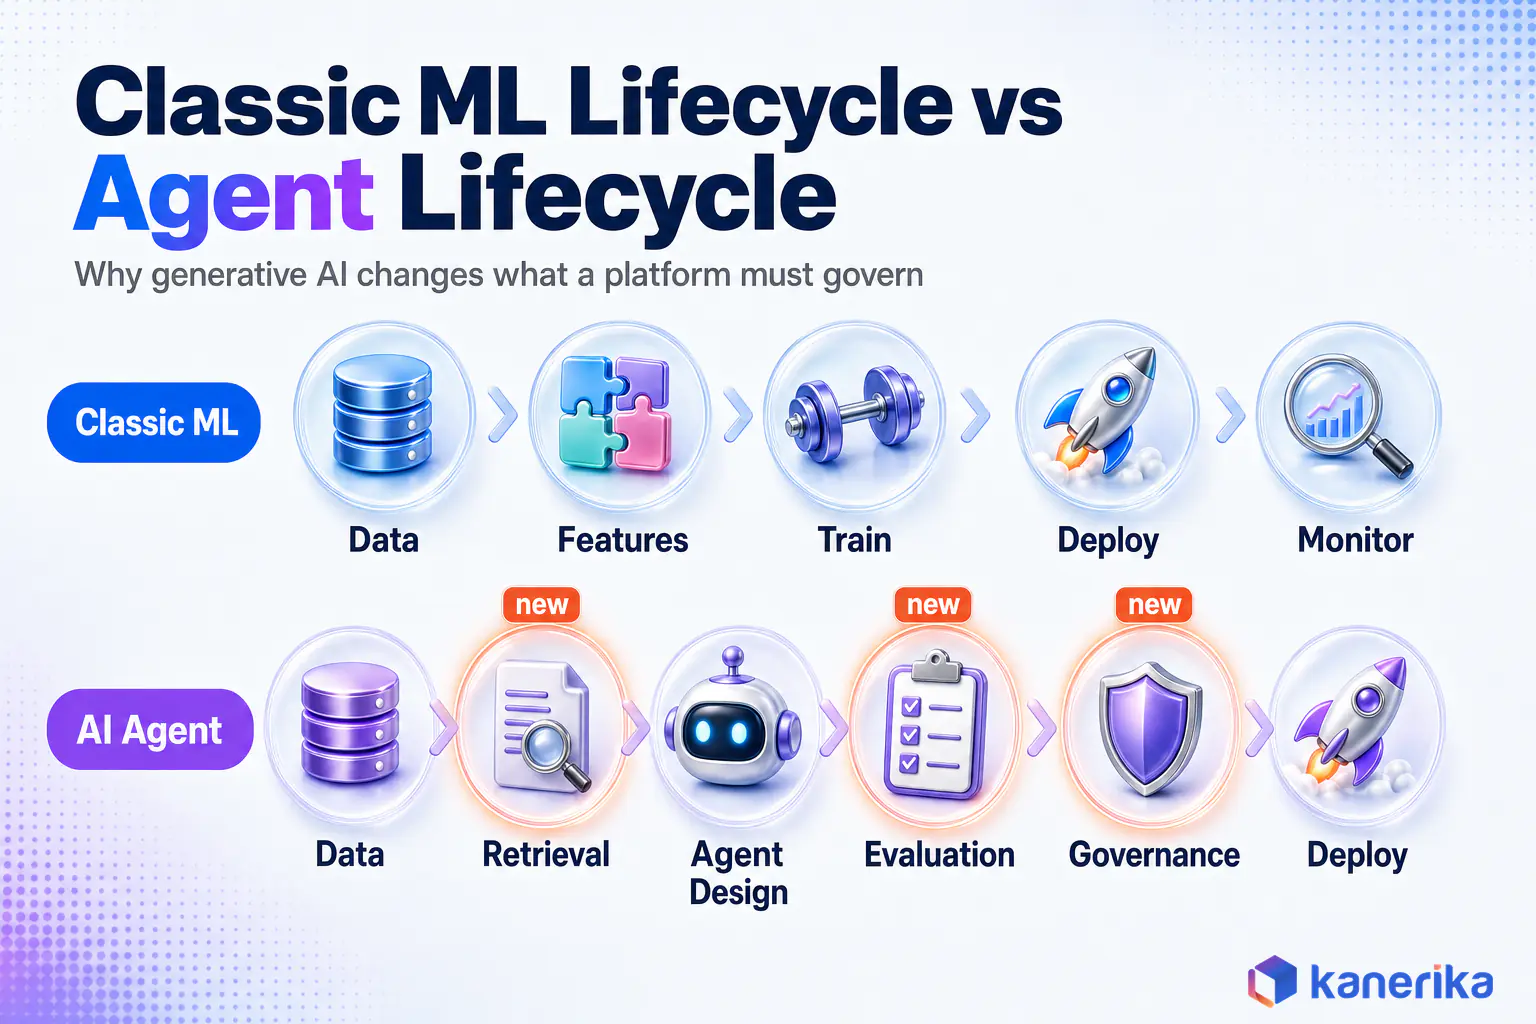
Classic machine learning looks similar on both platforms. Generative AI does not, because the two vendors made different bets about where agents should be built.
Building Agents on Databricks
Databricks put agent building inside the data platform. Agent Bricks grounds agents in enterprise data, and Databricks describes it as a way to “optimize quality and cost with synthetic data, custom evaluation, and automated tuning”.
Two agent types ship today. Knowledge Assistant builds domain specific chatbots through a guided interface, and Supervisor Agent orchestrates Genie Agents, agent endpoints, Unity Catalog functions, MCP servers and custom agents. Related Agent Services carry a Beta label, so check the stage before you design around them.
The governance story is the differentiator. An agent that calls a Unity Catalog function inherits the permissions on that function, so the same access rules that protect a table protect the tool an agent can invoke. Our guide to generative AI on Databricks covers the retrieval side in more detail.
Building Generative AI on SageMaker and Bedrock
AWS splits the work. Foundation models, agents and guardrails live in Amazon Bedrock, which is listed as one of the capabilities inside the new Amazon SageMaker. SageMaker AI handles fine tuning, custom model hosting and JumpStart deployments.
That split gives more model choice and a wider set of managed guardrails than any single vendor platform offers. It also means a generative application spans at least two services, with permissions, quotas and cost lines in both, and a generative AI security review has to cover each of them.
For teams building retrieval pipelines, the architecture questions are the same on either platform, and an enterprise AI architecture reference helps separate them from the hosting choice. Chunking, embedding, ranking and evaluation decide quality far more than the hosting choice does, which is why a retrieval augmented generation architecture deserves its own design review.
Evaluation is the one area where the two vendors have converged. AWS positions managed MLflow tracing on SageMaker AI as a way to record the inputs, outputs and metadata at every step of a generative application. Databricks runs Agent Evaluation on the same MLflow tracking data it uses for classical models.
What separates them is where the traces live, and whether the permissions on those traces match the permissions on the data the agent read. Decide this before the first agent ships.
Is Databricks SaaS or PaaS?
This question turns up in almost every security review, and the honest answer is that Databricks behaves like both depending on which compute you pick.
The Control Plane and Compute Plane Split
Databricks documents two planes. “The control plane includes the backend services that Databricks manages in your Databricks account”, covering the web application and management services. “The compute plane is where your data is processed.”
Where that compute plane sits is the whole answer. With classic compute, “the compute resources are in your AWS account in what is called the classic compute plane”, so you keep the VPC and the networking. With serverless compute, those resources “run in a serverless compute plane in your Databricks account” instead.
So classic compute reads as platform as a service, because you own the infrastructure boundary. Serverless compute reads as software as a service, because Databricks owns it. Both share one governance layer through Unity Catalog metastores.
Why the Answer Matters in a Security Review
Reviewers are asking a narrower question than the label suggests. They want to know whose network the data is processed in, whose account holds the logs, and which controls your team can still apply.
Answer with the plane split. Name the compute type per workload, state which account it runs in, and the review usually moves on. Amazon SageMaker AI has no equivalent ambiguity, since everything runs inside your AWS account under your IAM policies.
Databricks vs SageMaker Pricing: How the Bills Actually Differ
Neither vendor publishes a number you can compare directly, because the two bills have different shapes. Understanding the shape matters more than any list price.
How Databricks Bills
Databricks defines its unit precisely. “A Databricks Unit (DBU) is a normalized unit of processing power on the Databricks Lakehouse Platform used for measurement and pricing purposes.” The number consumed “is driven by processing metrics, which may include the compute resources used and the amount of data processed”.
Two things surprise finance teams. DBUs measure compute, not storage, and cloud infrastructure is billed separately. Databricks states that if you run it against your own cloud account “you will still be charged by your cloud provider for resources, like compute instances, used within your account”.
In addition, rates vary by cloud, region and SKU group, Azure pricing is set by Microsoft, and Committed Use Contracts give discounts that can span multiple clouds. Billing granularity is per second. Cost control work usually starts with cluster policies and job sizing, which our guide to Databricks cost optimization goes through step by step.
Talk to Kanerika
Model Your Databricks vs SageMaker Cost Before You Commit
We build the comparison from both vendors’ published units, including the second cloud bill on Databricks and the hourly MLflow tracking server on AWS.
Book a Meeting →How Amazon SageMaker AI Bills
SageMaker AI is pay as you go with “no minimum fees and no upfront commitments”, and most components bill per second for partial hours. Serverless inference is the exception, billing by the millisecond.
The components also bill separately. Training, notebooks and Studio bill by instance hour, and real time inference adds data transfer on top. Asynchronous inference bills by instance hour with scale to zero, batch transform only while the job runs, storage per GB-month, and data processing per GB.
Committed spend is where AWS pulls ahead. Amazon SageMaker Savings Plans are published as reducing costs “by up to 64%” across eligible services, which is a lever Databricks consumption pricing does not offer in the same form.
Table 4: What Drives the Bill on Each Platform
| Cost area | Databricks | Amazon SageMaker AI |
|---|---|---|
| Unit of charge | DBUs, per second granularity | Instance seconds per component |
| Underlying compute | Billed again by your cloud provider | Included in the SageMaker AI instance rate |
| Experiment tracking | Part of the platform, no separate server | MLflow server by the hour, from $0.60 for Small |
| Idle serving capacity | Scale to zero available, cold start on wake | Serverless inference bills only per millisecond used |
| Storage | Your own object storage, billed by the cloud | Per GB-month on SageMaker volumes, plus S3 |
| Commitment discounts | Committed Use Contracts, can span clouds | SageMaker Savings Plans, published up to 64% |
| Price variation | By cloud, region and SKU group | By AWS region and instance family |
SageMaker Alternatives and Databricks Alternatives in 2026
Shortlists rarely contain two names. Four other platforms come up often enough that leaving them out makes a comparison look narrower than the decision really is.
Table 5: Alternatives to Databricks and Amazon SageMaker
| Platform | Best for | Main limitation |
|---|---|---|
| Microsoft Fabric | Microsoft estates that live in Power BI and OneLake | Capacity licensing ties analytics and AI to one SKU |
| Google Vertex AI | Teams standardised on Google Cloud and Gemini models | Single cloud, same lock-in shape as SageMaker AI |
| Snowflake | Warehouse-first shops adding AI beside existing SQL | Less suited to heavy custom training workloads |
| Dataiku or H2O.ai | Mixed analyst and data scientist teams wanting visual flow | A separate layer to govern on top of your data platform |
| Open-source MLflow on EKS | Teams that want tracking without a managed service charge | You own upgrades, availability and access control |
Microsoft Fabric is the alternative that comes up most in our own engagements, because so many enterprises already run Power BI and its capacity-based pricing is familiar. If that describes your estate, a Microsoft Fabric evaluation belongs on the shortlist beside both.
For a wider view, see our list of Databricks alternatives. For a Databricks-specific shortlist, our comparisons of Databricks and Snowflake and of Dataiku and Databricks cover the two matchups buyers raise most often after this one.
Can You Run Databricks and SageMaker Together?
Yes, and a good number of enterprises do. The pattern that works puts Databricks on the data side and SageMaker AI on the serving side, or the reverse, with a clean handover between them.
The usual split looks like this. Databricks owns ingestion, transformation, feature tables and governance in Unity Catalog. SageMaker AI hosts the endpoints that application teams call, because those teams already work in AWS and their runbooks assume it.
Two costs come with that. You pay both platforms, and you maintain a boundary where model lineage stops being automatic. Someone has to record which Unity Catalog model version became which SageMaker endpoint, because neither platform does it for the other.
The pattern earns its keep when the split follows an existing team boundary. It becomes expensive when it exists only because nobody would decide, which is the version we are asked to untangle most often.
How to Choose Between Databricks and SageMaker: Six Steps
Run these six checks in order. Each one narrows the field, and the first three settle most decisions before anyone books a demo.
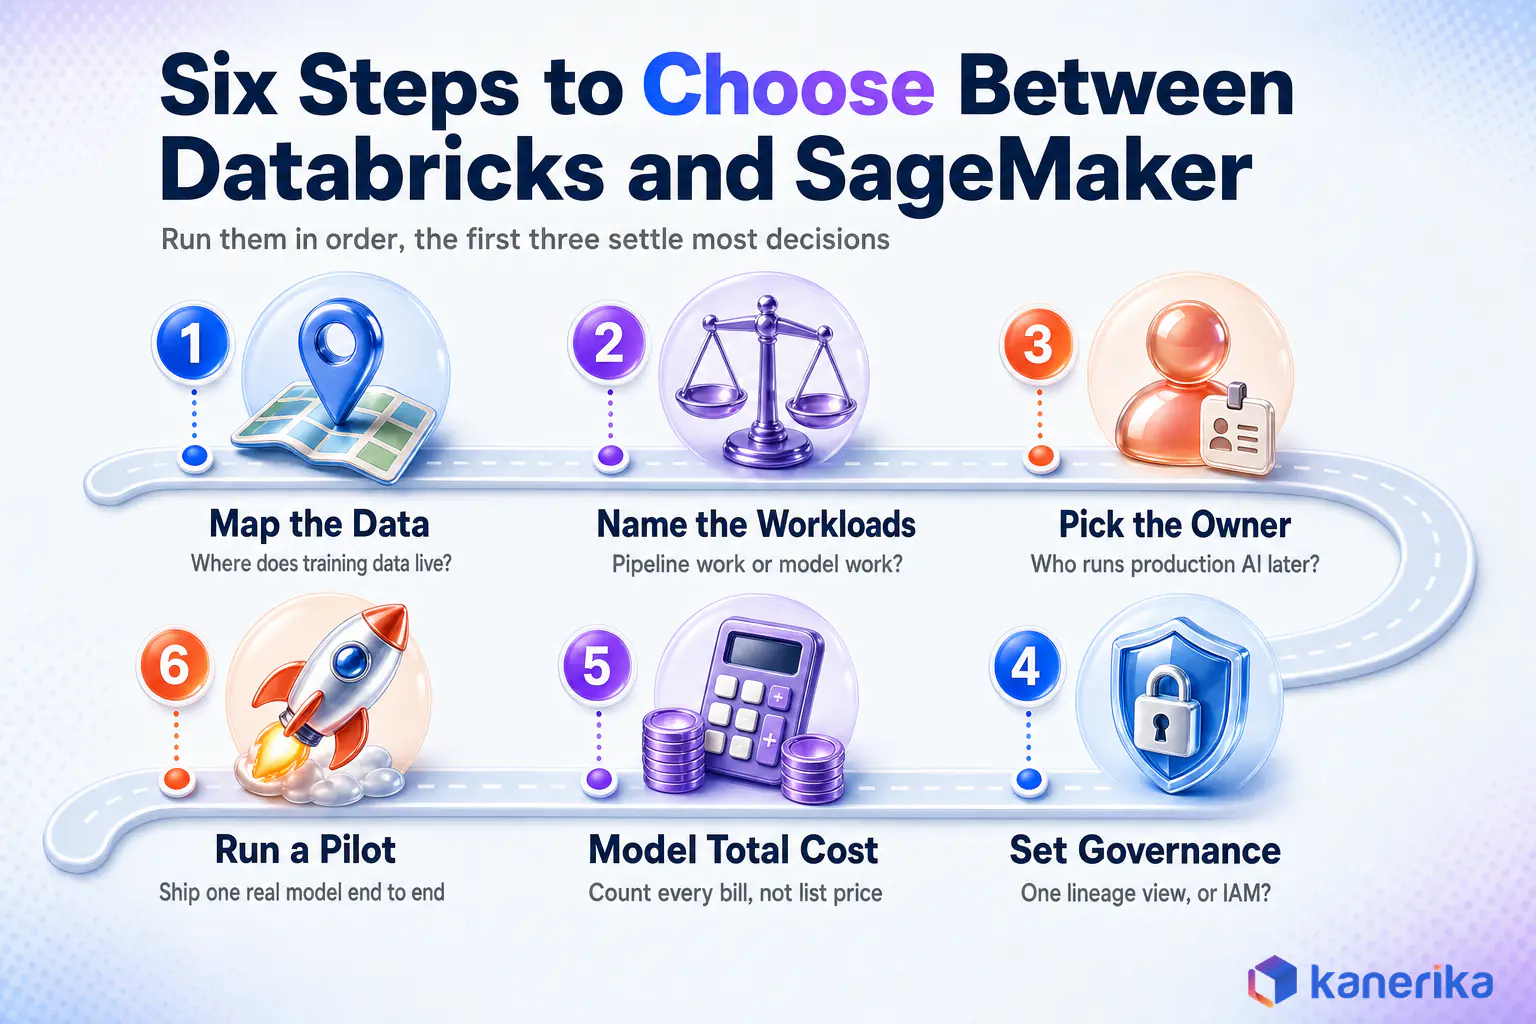
- Map where the training data physically lives. If most of it already sits in S3 and Redshift, SageMaker AI starts ahead. If it is spread across clouds or sitting in files that need heavy transformation first, Databricks starts ahead.
- Name the workloads honestly. Count how much of the effort is pipeline work versus model work. A 70/30 split toward pipelines points at Databricks, and the reverse points at SageMaker AI.
- Decide who owns production AI in eighteen months. A central data platform team favours Databricks. A cloud or application platform team already running AWS favours SageMaker AI.
- Write down your governance requirement. If auditors need one lineage view across tables, features and models, Unity Catalog does that natively. If IAM and CloudTrail already satisfy the auditors, AWS costs less to prove.
- Model the total cost. Include the second cloud bill on Databricks and the hourly MLflow tracking server on AWS. Both are easy to miss and both change the ranking.
- Run one production-shaped pilot. Take a real pipeline and a real model, ship them end to end on the front runner, and measure the time from raw data to a served prediction.
Step six is the one teams skip and later regret. A notebook demo proves almost nothing about deployment, monitoring or the handover to whoever runs it at 3am.
When Databricks Is the Right Call
Choose Databricks when data preparation dominates the work, or when terabyte-scale transformation sits in front of training. It also fits when the same group needs SQL analytics and machine learning on one copy of the data.
It is also the answer when portability is a stated requirement, or when governance across data and AI assets has to be provable in one place. The same applies when agent work needs to inherit data permissions rather than re-implement them.
When Amazon SageMaker AI Is the Right Call
Choose SageMaker AI when the data is already in AWS, the team knows IAM and VPC design, and the work is mostly modelling rather than pipeline building. Compliance programmes built on AWS attestations also carry over without a new review.
Deployment variety is the other trigger. Traffic that is spiky, asynchronous with large payloads, or purely batch maps to a named SageMaker AI inference mode with published limits, which makes capacity planning a short conversation.
How Kanerika Helps Enterprises Make and Execute This Call
Kanerika is a Databricks Consulting Partner and a Microsoft Solutions Partner for Data and AI. We are brought in at two moments, before the platform is chosen and after a first attempt has stalled, and the second is more common than the first.
Free Checklist
Databricks Readiness Checklist
Check your data estate, governance and team skills against what a Databricks rollout needs, before you commit to the platform.
Get the Checklist →How We Run the Decision
Our sequence is deliberately short. We start with a two week assessment that inventories where training data lives, what the pipelines actually do today, and who is on the hook for production models after launch.
Next we build a cost model from both vendors’ published units rather than from a sales quote, including the second cloud bill on Databricks and the hourly tracking server on AWS. Then we ship one production-shaped pilot on the front runner, instrumented end to end.
Governance is designed in the same pass as the pilot. That means deciding which catalog is authoritative, how lineage is recorded across the boundary if both platforms stay, and who approves a model into production. Our MLOps consulting and data engineering teams run those two workstreams together.
What This Looks Like in Delivery
An AI-powered sales intelligence platform came to us with a familiar shape of problem. Its document processing logic was trapped in JavaScript, its pipelines were fragmented across MongoDB and Postgres, and unstructured PDFs needed manual handling before anything downstream could use them.
Our team rebuilt the document workflows in Python on Databricks, connected the disconnected sources into one view, and reworked the PDF, metadata and classification steps. The published outcomes were 80% faster document processing, 95% improved metadata accuracy and 45% accelerated time-to-insight.
The instructive part is what decided the platform. The client’s bottleneck was never model quality. It was the data work in front of the models, which is exactly the condition under which Databricks wins this comparison.
The Mistakes We See Most
Three recur. Teams size an MLflow tracking server by total headcount instead of concurrent users and pay for capacity nobody touches. Teams enable scale to zero on a production endpoint and then field complaints about the first request of the morning.
The third is the one that costs most. A platform gets chosen on a feature comparison, and nobody names the team that will own the models. Eighteen months later the pipelines and the endpoints answer to different managers with different priorities.
Case Study
80% Faster Document Processing With Databricks Workflows
How an AI-powered sales intelligence platform cut document processing time by 80% and improved metadata accuracy by 95% after moving its workflows onto Databricks.
Read the Case Study →Wrapping Up
Databricks and Amazon SageMaker AI are no longer competing on the same ground they were in 2024. Amazon rebuilt SageMaker into a platform and renamed the old service, while Databricks pushed from lakehouse analytics into agent production.
The deciding factors in Databricks vs SageMaker stayed stable through all of it. They are where your training data lives, how much pipeline work sits in front of your models, and which team will still own production AI in eighteen months. Answer those three honestly and the platform choice usually makes itself.
For a second opinion on your own estate, bring your current architecture diagram to a working session and test these three questions against it.
Frequently Asked Questions
Is SageMaker equivalent to Databricks?
No. Amazon SageMaker AI is a managed machine learning service for building, training and hosting models inside AWS. Databricks is a full data platform that covers ingestion, transformation, analytics and AI on one governed copy of your data. They overlap on model work and differ sharply on data engineering and multi cloud reach.
What is the difference between Amazon SageMaker and Amazon SageMaker AI?
Amazon SageMaker AI is the machine learning service, which AWS renamed in December 2024. Amazon SageMaker now names the wider platform around it, including Lakehouse, Unified Studio and Bedrock. In a Databricks vs SageMaker decision, Databricks usually meets SageMaker AI on model work and the full platform on data work.
Which companies use SageMaker?
AWS publishes named customer stories on its own site, and those pages are the only reliable source for who uses the service. Adoption concentrates in organisations already running on AWS, particularly across financial services, healthcare, retail and media. Check the AWS customer references directly rather than trusting a secondhand list.
What are the alternatives to SageMaker?
The realistic alternatives are Databricks, Microsoft Fabric, Azure Machine Learning, Google Vertex AI and Snowflake. Dataiku and H2O.ai suit mixed analyst teams who want a visual flow. Self managed open source MLflow on Kubernetes works when you want experiment tracking without a managed service charge and can own the upgrades.
What are the main SageMaker competitors in 2026?
Databricks is the main competitor for data heavy machine learning. Google Vertex AI competes inside Google Cloud estates and Azure Machine Learning inside Microsoft estates. Microsoft Fabric competes for the wider platform decision rather than the model service alone. Snowflake competes where analytics and AI sit on the same warehouse.
Who is AWS' competitor to Databricks?
AWS answers Databricks with a set of services rather than one product. Amazon SageMaker AI covers machine learning, SageMaker Lakehouse covers the lakehouse pattern on Apache Iceberg, and Glue, EMR and Athena cover data processing. SageMaker Unified Studio presents all of them through a single development experience for project teams.
Why choose Databricks over AWS?
Choose Databricks when data preparation dominates the work, or when you need the same platform on more than one cloud. It also helps when auditors want one lineage view across tables, features and models. Unity Catalog governs data and AI assets together, which removes a join that AWS leaves you to maintain.
Is Databricks good for machine learning?
Yes. Databricks offers managed MLflow 3 for experiment tracking, a model registry inside Unity Catalog, distributed training on Spark clusters and Model Serving for deployment. It helps most when heavy data engineering sits in front of the models. Teams training small models on clean data will see a smaller benefit.
What is SageMaker good for?
Amazon SageMaker AI suits teams whose data already lives in AWS and whose work is mostly modelling. It covers training, tuning, hosting and monitoring with managed infrastructure. Its deployment range is the standout, offering real time, serverless, asynchronous and batch inference, each with published limits and its own billing shape.
What is a major weakness of Databricks?
Cost predictability is the common complaint. Consumption pricing plus a separate cloud infrastructure bill makes forecasting harder than a single line item. The platform also rewards Spark and distributed computing skill, so teams without it can overspend on badly sized clusters. Cluster policies and job sizing address most of that.
Is Databricks good for ETL?
Yes, and it is one of the platform’s strongest areas. Lakeflow Connect ingests source data. Lakeflow Spark Declarative Pipelines handles transformation with expectations and incremental refresh, and Lakeflow Jobs orchestrates the whole run. Delta Lake adds transactional guarantees, so analytics and model training can safely read exactly the same tables.
Does Databricks do MLOps?
Yes. Managed MLflow 3 records runs, parameters, metrics and traces for every experiment. The model registry lives in Unity Catalog, so models inherit the permissions of the data behind them. Lakeflow Jobs schedules retraining and Mosaic AI Model Serving hosts the result. Agent Evaluation extends the same machinery to generative work.
Is SageMaker deprecated?
No. Nothing was deprecated. AWS renamed the machine learning service to Amazon SageMaker AI and reused the Amazon SageMaker name for a larger platform. Existing API calls, CLI commands, CloudFormation resources and IAM policies continue to work unchanged. The confusion comes from the naming, not from any product being withdrawn.
Is Databricks just Apache Spark?
No. Spark remains the processing engine, and the platform adds a great deal around it. Delta Lake provides transactional storage and Unity Catalog provides governance and lineage. Lakeflow provides pipelines and orchestration, while Mosaic AI provides serving and agent tooling. Serverless SQL warehouses also run analytics without anyone configuring a cluster.
What is the difference between Databricks MLflow and AWS MLflow?
Both run managed MLflow. Databricks includes MLflow 3 in the workspace and keeps the model registry inside Unity Catalog. AWS runs MLflow on a tracking server you size and pay for by the hour, or as a newer MLflow App. On AWS, artefacts are stored in your own S3 bucket.
Does AWS charge for MLflow?
Yes. AWS bills the MLflow tracking server by the hour for as long as it runs. The rate depends on the server size you chose, and metadata storage is charged per gigabyte each month. A continuously running server costs money even with no experiments logged, so stop it when the team is idle.
Can SageMaker use open-source MLflow?
Yes. SageMaker AI supports standard MLflow clients. The managed tracking servers run MLflow 3.0, 2.16 or 2.13, while the newer MLflow Apps run version 3.10. You can also self manage open source MLflow on Kubernetes and point it at SageMaker AI training jobs if you prefer to own the upgrades.
Can Databricks replace SageMaker?
It can for most workloads, and the migration is rarely free. Databricks covers training, tracking, the registry and serving, so the functional gap is small. What moves with it is the data platform, the governance model and the operating model. Plan the change as a platform move rather than a tool swap.
Can you use Databricks and SageMaker together?
Yes, and many enterprises do. A common split gives Databricks ingestion, transformation, feature tables and governance, while Amazon SageMaker AI hosts the endpoints that application teams call. You pay both platforms and you maintain the boundary yourself, because neither one records lineage across it. Document the handover explicitly before go live.
What is SageMaker Unified Studio?
It is the single development experience inside the new Amazon SageMaker platform. AWS describes it as bringing together data, analytics, artificial intelligence and machine learning services in one place. Administrators create a domain and invite users through single sign on, and work then happens inside projects that hold shared resources.
Which is cheaper, Databricks or SageMaker?
Neither is reliably cheaper, because the two bills have different shapes. Databricks charges in Databricks Units on top of a separate cloud infrastructure bill. Amazon SageMaker AI charges per second per component and offers Savings Plans. Model your own workload against both, including idle serving capacity and experiment tracking costs.
Is SageMaker available outside AWS?
No. Amazon SageMaker AI runs only in AWS regions. That is efficient inside an AWS estate. It becomes a constraint when a merger, a customer requirement or a data sovereignty rule places workloads somewhere else. Databricks runs the same platform on AWS, Microsoft Azure and Google Cloud without a rewrite.
Who is Databricks' biggest competitor?
Snowflake is the closest competitor for data platform work. For machine learning, the main rivals are Amazon SageMaker AI, Azure Machine Learning and Google Vertex AI. Microsoft Fabric competes when an organisation already runs Power BI. The strongest rival in any deal is usually the platform where the buyer’s data already lives.
Is SageMaker AI or ML?
Amazon SageMaker AI is primarily a machine learning service. It handles data preparation, training, tuning, hosting and monitoring for classical and deep learning models. Generative work is served mainly through JumpStart inside the service and Amazon Bedrock beside it. The AI in the name marks the rename, not a change in purpose.
What is the Microsoft equivalent of SageMaker?
Azure Machine Learning is the closest Microsoft equivalent to Amazon SageMaker AI for training, tuning and deploying models. For the wider Amazon SageMaker platform, Microsoft Fabric is the nearer match. It combines data engineering, warehousing, analytics and AI in one service built around the shared OneLake storage layer for every workload.
What is equivalent to SageMaker in Azure?
Azure Machine Learning covers the same ground as Amazon SageMaker AI. It offers managed compute, experiment tracking, a model registry and managed endpoints. Azure Databricks is the better option when heavy data engineering sits in front of the models. Microsoft Fabric fits when analytics and AI need to share one platform.
Is Databricks part of AWS?
No. Databricks is an independent company. It runs on AWS, Microsoft Azure and Google Cloud, so you can buy it through a cloud provider without it being a cloud provider product. On Azure it is sold as a first party service called Azure Databricks and is billed through Microsoft rather than Databricks.
Is Databricks a SaaS or PaaS?
It behaves as both, depending on the compute you choose. The control plane always runs in the Databricks account. With classic compute, processing happens in your own cloud account, which reads as platform as a service. With serverless compute, processing happens in the Databricks account, which reads as software as a service.
Why is Databricks so successful?
Databricks built the lakehouse pattern, which let one governed copy of data serve warehousing and machine learning. Its founders created Apache Spark and the company later released Delta Lake and MLflow as open source. Running identically on three clouds widened the market, and Unity Catalog gave enterprises one governance layer.