TL;DR
Before you build a data analytics pipeline, agree the decision it supports, the metric definition, its owner and how old the number may be. Those answers then pick the design: incremental batch loads unless someone must act within seconds. The pipeline itself is the repeatable path from source systems to an approved number on a dashboard.
After that, set quality gates on that path that can stop a wrong number from publishing. Choose ELT for SQL teams, ETL for fields that need masking and a managed platform for the plumbing. Prove one flow end to end, from source to signed-off dashboard, before adding more sources.
Key Takeaways
- A data analytics pipeline is finished only when a trusted metric reaches the person who acts on it.
- Write down the decision, the metric definition and the maximum data age before you compare any tools.
- Incremental batch loads fed by change data capture cover most dashboards, and streaming earns its cost only when someone acts within seconds.
- Quality gates should warn, reject or stop publishing, so a wrong number never reaches a dashboard silently.
- Managed platforms such as Microsoft Fabric, Databricks and Snowflake handle the plumbing, while metric ownership stays with your team.
- Prove one flow end to end, with reconciliation and sign-off, before you add the next source.
Watch on YouTube
Microsoft Fabric Case Study: Order Lead Time Analytics for Manufacturing
A two-minute look at how Kanerika joined three SAP systems into one governed Fabric pipeline and a self-updating Power BI report, the end state this guide works toward.
The Revenue Tile That Refreshed on Time and Was Still Wrong
Picture a sales director opening the Monday dashboard. Every tile refreshed on schedule, and the pipeline log shows green ticks from end to end.
The revenue figure is still higher than the one finance reports. Over the weekend, the order system started marking returns with a new status code. The pipeline loaded every row, but the revenue logic had never seen that code, so returned orders still counted as sales.
Nothing crashed, and that is exactly the problem.
A data analytics pipeline can run perfectly and still publish a wrong number. Preventing that wrong number is mostly settled before the first load. It depends on what the metric means, how old it may be, which checks can stop it and who signs it off. The sections below therefore take those decisions in the order a build meets them.
What Is a Data Analytics Pipeline?
A data analytics pipeline is the repeatable path that takes data from source systems to approved metrics in dashboards, reports and decisions. It collects records, cleans and joins them, applies agreed business rules and serves the result where people work.
Three benefits follow when it works. Every team reads one version of the numbers. Decisions rest on fresher data, and analysts stop spending their mornings on manual exports and spreadsheet fixes.
The general idea of moving data between systems is covered in Kanerika’s guide to data pipelines. This post stays on the analytics side, where the output is a number that someone trusts enough to act on.
Data Analytics Pipeline vs Data Pipeline vs ETL Pipeline
The three terms overlap, and the overlap tends to cause scoping arguments later. A data pipeline is any automated data movement. An ETL pipeline is one pattern for doing it, while an analytics pipeline is defined by what it delivers at the end.
| Term | Purpose | End output | Typical owner | Read more |
|---|
| Data pipeline | Move data reliably so systems stay in sync | Delivered to a lake, warehouse or app | Engineering team | Data pipeline vs ETL |
| ETL pipeline | Extract, transform, then load in that order | Cleaned tables loaded into a warehouse | Data engineering | ETL pipeline explained |
| Data analytics pipeline | Turn source data into governed metrics so people can act | Approved KPIs in dashboards, alerts and apps | Data engineering, together with a named metric owner | This guide |
ETL is one pattern inside the analytics picture. ELT, which loads first and transforms inside the warehouse or lakehouse, feeds analytics just as often.
Kanerika’s guide to different types of data pipelines also covers batch, streaming and hybrid designs in more depth.
The Stages of a Data Analytics Pipeline, From Source to Decision
There is no universal stage count. Some teams describe five stages and others three, depending on where they draw the lines, so this guide follows one sales order through six.
One easy way to understand the stages is to follow a single sales order until a manager acts on it. Each stage hands a specific output to the next, and each one needs its own check and its own owner.
The order starts as a row in an ERP or CRM. It lands in raw storage, then gets cleaned and matched to a customer. Next it feeds a revenue measure and appears on a dashboard. There, someone decides whether to chase a late shipment or raise a forecast.
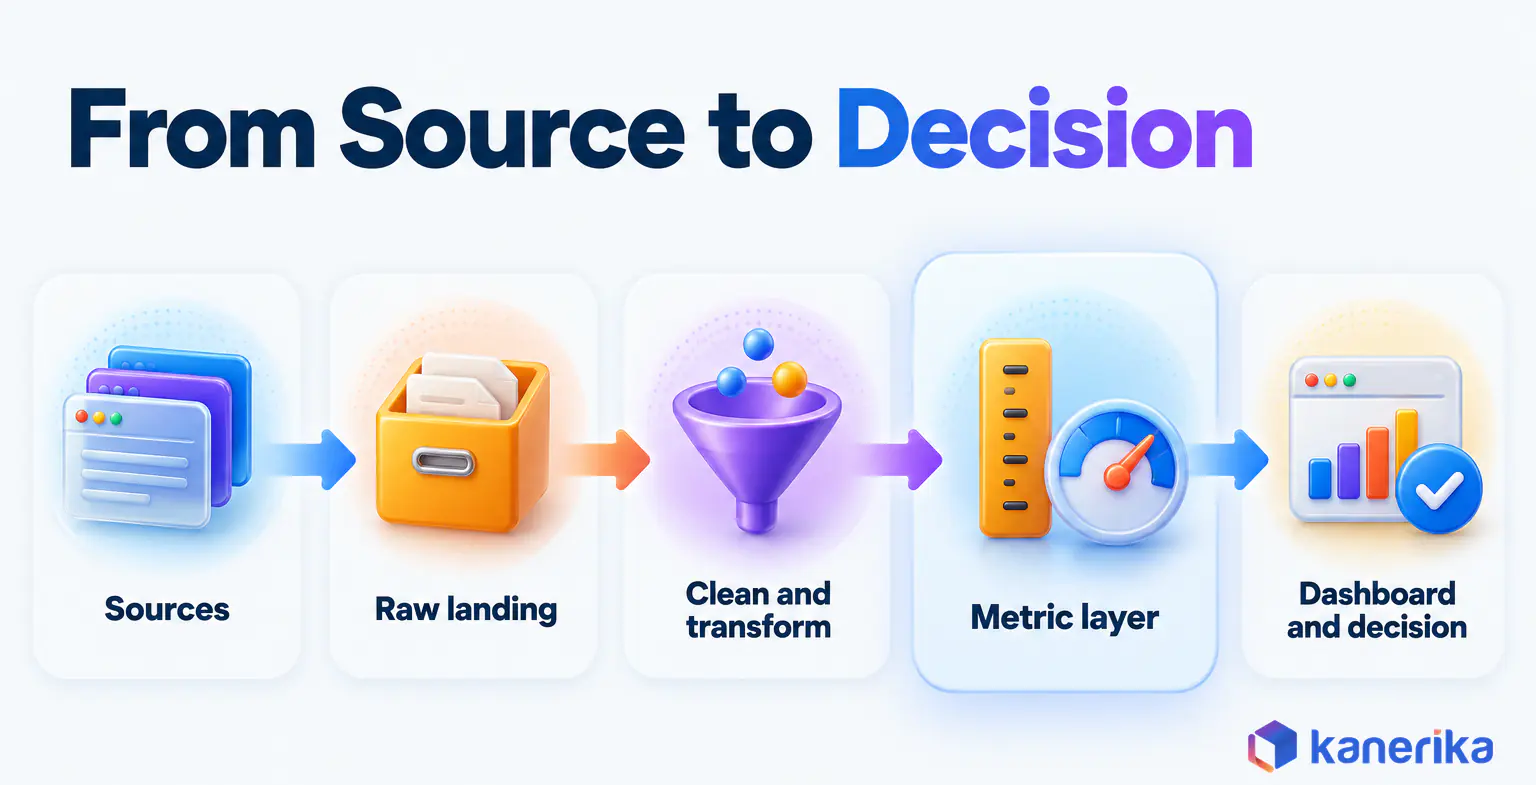
| Stage | Output | Check before moving on | Owner |
|---|
| Sources and collection | Agreed list of systems, tables and fields before any load | Source contract signed, so change patterns are known | Source system owner |
| Ingestion and raw landing | Raw copies and a load history | Row counts match the source extract | Data engineering |
| Cleaning and transformation | Clean, joined tables | Duplicates, nulls and rejected rows reported | Data engineering |
| Metric layer | One definition per KPI, with grain and owner | Totals reconcile to the system of record | Metric owner in the business |
| Serving | Dashboards and reports at the agreed freshness | Data age shown, and still within target | BI team |
| Decisions and feedback | Actions, alerts, app and AI uses | Users confirm the number drives the decision | Business owner |
The sections below walk through each stage with a concrete example, starting where the data is born.
Sources and Collection
Collection decides what the pipeline is allowed to know, so it starts with a list of systems rather than a list of tools.
Sales and service data often starts in a CRM platform such as Creatio or another system of record, alongside ERP orders and finance ledgers. Product events from apps and websites, partner spreadsheets and HR data often join them later.
For each source, write down who owns it, how its rows change and how often its schema changes. A source that hard-deletes cancelled orders needs a different load design from one that only appends new rows. Kanerika’s guide to cloud data integration also compares connector patterns for these sources.
Ingestion and Raw Landing
Ingestion copies source data into storage you control, without changing it. The first load is usually a full copy, and later loads pick up only what changed.
Change data capture, or CDC, is the common way to find those changes. SQL Server change data capture records inserts, updates and deletes on tracked tables, so the pipeline also sees a cancelled order.
CDC can feed a batch job every 15 minutes or a streaming flow. It finds changes efficiently, and the load schedule still decides how fresh the data is. Keep the raw landing untouched and keep a load history, so you can replay any day when something breaks.
Cleaning, Conforming and Transformation
Transformation is where raw rows become tables that a business user would recognize. It removes duplicates, standardizes codes, joins orders to customers and applies business rules, such as what counts as a return.
Many teams therefore organize this work in layers. Microsoft describes the medallion lakehouse architecture as bronze for raw data, silver for enriched data and gold for curated data. Kanerika’s guide to medallion architecture design explains how to set up those layers, and the data transformation guide covers the techniques used inside them.
Rows that fail a rule should go to a rejected-records table rather than disappear. A silent drop is how a revenue total shrinks without anyone noticing.
The Metric Layer: Semantic Models and Shared Definitions
The metric layer is where the pipeline earns trust or loses it. It holds one written definition per KPI, the grain at which it is measured and the person who owns it.
Take net revenue, for example. Finance may define it after returns and discounts at the invoice line, while sales counts booked orders by day. Both views are reasonable, but only one of them can carry the name net revenue on a shared dashboard.
The metric layer records that choice and calculates the measure once, usually in a semantic model that every report reads from. Good data modeling tools help here, since they make the grain and the relationships visible before anyone builds a chart. Skip this layer and each report author writes a private formula, which is how two dashboards end up showing two revenue numbers.
Serving: Dashboards, Refresh and Freshness at the Point of Use
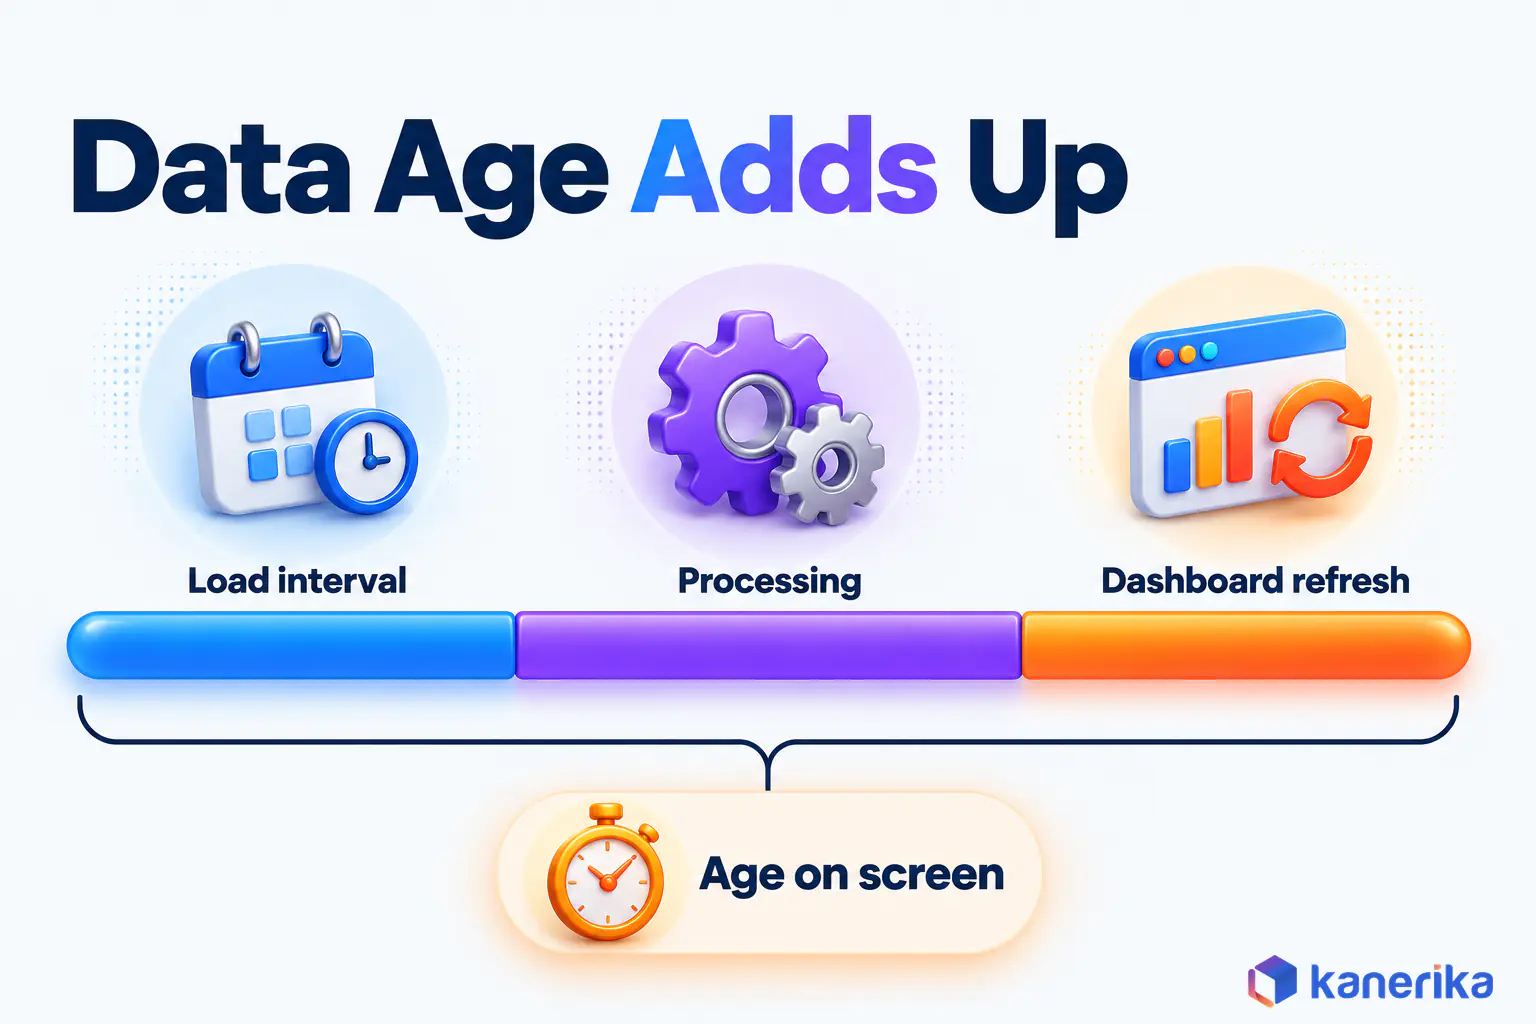
Serving is the stage users actually see, so freshness has to be measured here rather than upstream. Three clocks matter: when the data arrives, when processing finishes and when the dashboard refreshes.
The dashboard clock is the one teams forget. Power BI allows 8 scheduled refreshes a day on shared capacity and up to 48 on Premium, PPU or Fabric capacity. Even 48 refreshes means one every 30 minutes, which puts a floor under how fresh an imported report can be.
Direct Lake is one alternative in Microsoft Fabric. This storage mode loads Delta tables from OneLake into memory for a Power BI semantic model, which helps when importing the full volume is impractical. Whatever the mode, show the data age on the report so users know how old the number is.
Decisions and Feedback
The last stage is the reason the pipeline exists, because someone does something with the number. A planner reorders stock, a finance lead holds a payment run, or an alert fires when on-time delivery drops below target.
Other consumers also reuse the same governed metrics. Apps read them through an API, and AI assistants answer questions from them. An AI data pipeline adds steps for models, yet it should still draw on the same approved definitions.
Feedback closes the loop. When a user questions a number, the question goes to the metric owner and becomes a new test in the pipeline.
Components and the Tools That Fill Each Role
It helps to think in roles before products, because every platform fills the same seven jobs in its own way. The table maps each role to options worth evaluating on Fabric, Databricks, Snowflake and open-source stacks.
Treat it as a list of things to test rather than a ranking. Some teams run two platforms, so test the roles on both.
| Role | Job | Microsoft Fabric | Databricks | Snowflake | Open source |
|---|
| Ingestion | Copy source data in, in full and then incrementally | Data Factory pipelines and Dataflow Gen2 | Lakeflow pipelines for batch and streaming loads | COPY INTO for files, Snowpipe for continuous loads | Custom loaders scheduled by Airflow |
| Storage | Hold raw, cleaned and curated tables | OneLake lakehouse with Delta tables | Delta tables in the lakehouse | Snowflake tables | Object storage with an open table format |
| Transformation | Clean, join and apply business rules | Dataflow Gen2, notebooks, SQL and dbt jobs | Lakeflow pipelines in SQL or Python | Dynamic Tables refreshed to a target lag | dbt models written as SQL select statements |
| Orchestration | Run steps in order, with retries and failure alerts | Data Factory pipelines | Lakeflow Jobs with schedules and triggers | Tasks and task graphs, or target lag on Dynamic Tables | Apache Airflow |
| Semantic layer and BI | Define metrics once and serve reports | Power BI semantic models, Direct Lake | Connect a BI tool such as Power BI | Connect a BI tool such as Power BI | Your BI tool and semantic layer |
| Quality and observability | Catch wrong, late or missing data before users see it | Run history, plus checks you add | Pipeline run monitoring, plus checks you add | Refresh history, plus checks you add | Tests you write and maintain |
| Governance | Control access, lineage and retention | Workspace roles and Power BI row-level security | Unity Catalog permissions and lineage | Role-based access control | Access rules you build and run |
What Each Platform Brings to the Pipeline
The product names change often, so read each one against the role it fills and the decision it serves. Fabric Data Factory supports both ETL and ELT, and its Dataflow Gen2 tool includes more than 300 low-code transformations. In the same suite, Direct Lake also matters at the serving stage, where the refresh clock sits.
On Databricks, Lakeflow pipelines extend Apache Spark Declarative Pipelines for batch and streaming work in SQL and Python. Snowflake Dynamic Tables materialize a query and refresh it to a declared target lag. That target lag is, in other words, the maximum data age decision written into the table definition.
In open-source stacks, Apache Airflow authors, schedules and monitors workflows, while dbt builds modular models from SQL select statements. Like the SQL and dbt jobs in Fabric, dbt suits the SQL-first teams that the ELT-in-a-warehouse row below describes.
Quality and observability tools vary the most between stacks. Kanerika’s comparison of data pipeline monitoring tools and its guide to data observability cover that layer in detail.
What to Decide Before You Build
Every later choice in a data analytics pipeline depends on eight decisions. Each one is cheap to settle on paper and expensive to change after go-live.
Put the answers on one page that the business owner and the engineering lead both sign. If any line is blank, the build is not ready to start.
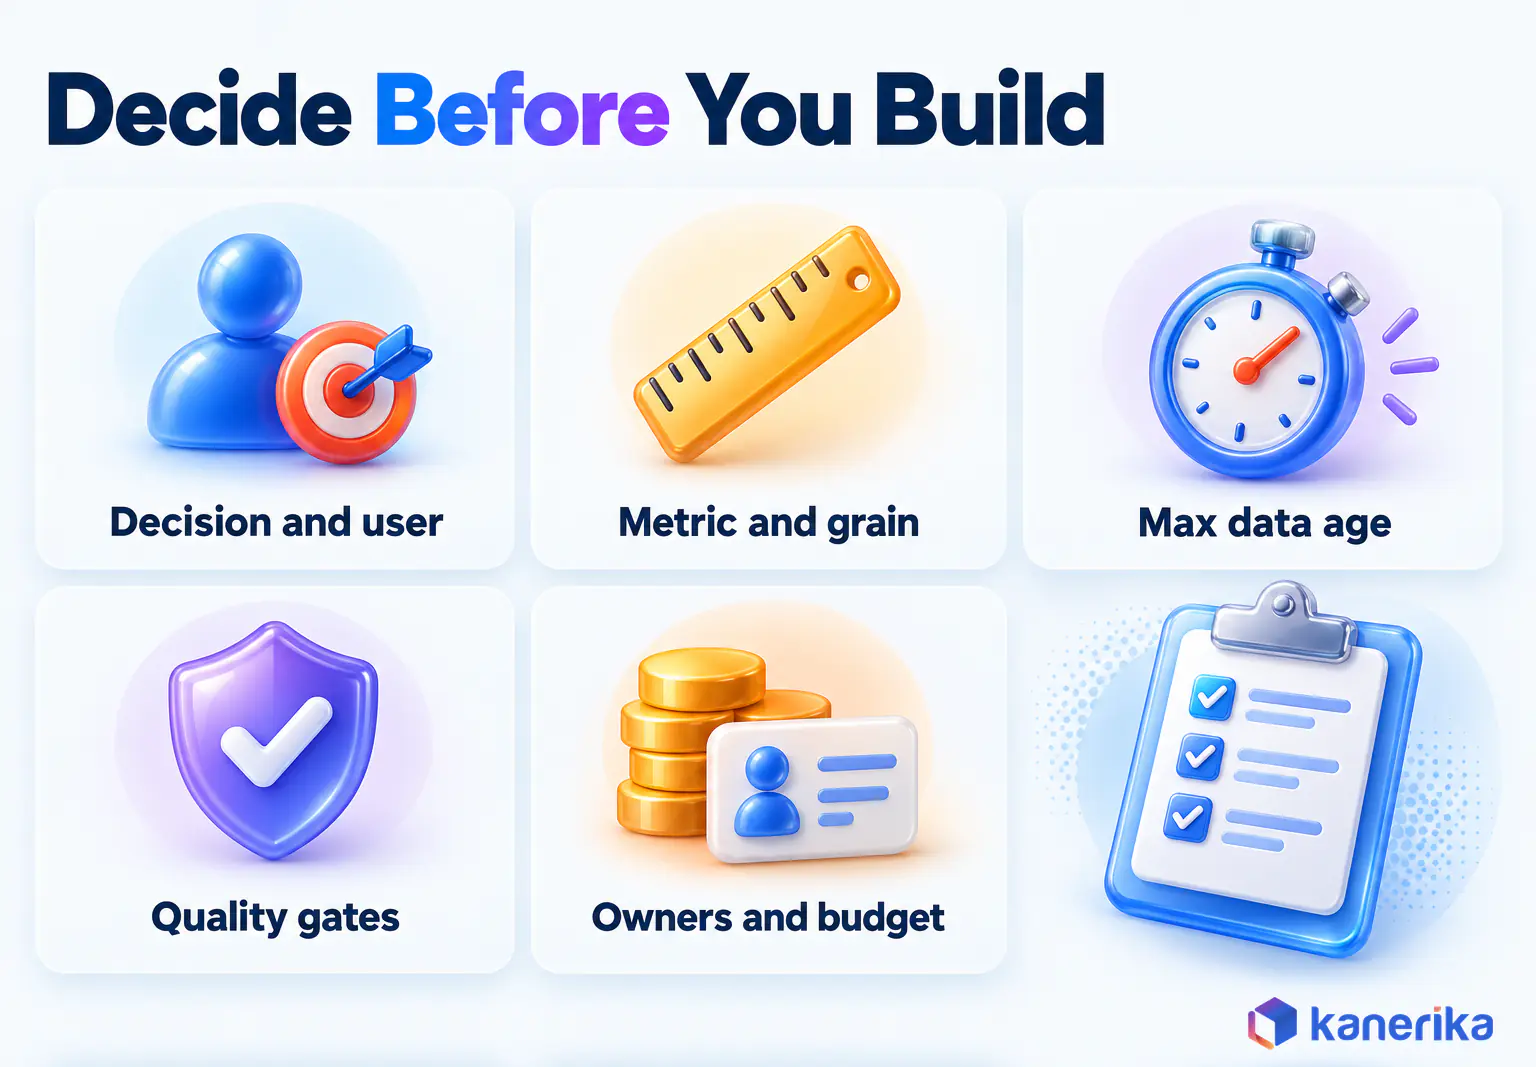
The graphic shows the five that most often stall a build; the list below adds sources, sensitive fields and recovery.
Eight Questions for the One-Page Decision Sheet
- The decision and the user. Which decision will this pipeline support, and who makes it? Without a named decision, the build drifts toward loading every table.
- The metric definition and grain. What exactly is measured, and at what level of detail, such as order line by day? Leave it vague, and two reports then compute two different totals.
- Sources and change patterns. Which systems hold the data, and do they update, append or delete rows? A source that hard-deletes rows needs CDC with delete handling, or cancelled orders stay in the totals.
- Maximum data age. How old can the number be at the moment someone reads it? It therefore sets the load pattern, the refresh schedule and most of the running cost.
- Quality thresholds. Which checks warn, which reject records and which stop publishing? Skip this, and a wrong number then publishes as readily as a right one.
- Sensitive fields and access. Which columns are personal or confidential, and who may see which rows? The answer also decides whether masking happens before landing, which favors ETL.
- Recovery targets. How long can the dashboard stay stale after a failure, and how far back must you replay? This also sets how much load history the raw layer must keep.
- Named owners and budget. Who owns each stage, who answers support calls and what may the pipeline cost to run each month? Otherwise, failures wait until users complain.
The sections that follow take the hardest of these in turn, beginning with freshness, because it drives cost more than any other answer.
How Fresh Does the Number Need to Be?
Freshness is a business question first and a technical one second. Ask how quickly someone acts on the number, then add up the time each stage takes.
A finance close report read once a day does not need minute-level data. A store manager moving staff during a lunch rush might need sales no more than 30 minutes old. Fraud checks that block a card payment, in contrast, need seconds.
| Pattern | When people act | Example | Cost and support load |
|---|
| Batch, hourly or daily | Hours to a day after the event | Daily sales report, month-end close | Lowest, since reruns are simple |
| Micro-batch every 5 to 15 minutes, often fed by CDC | Within the hour | Store trading dashboard, inventory status | Moderate, because there are more runs to monitor |
| Streaming, continuous | Within seconds | Fraud alerts, machine shutdown alerts | Highest, due to always-on compute and on-call support |
Most analytics dashboards land in the first two rows. Streaming is worth its cost when an automated action or a person must respond within seconds, not when a chart simply looks better live.
Remember that the clocks add up. The age of a number on screen is the wait for the next load, plus processing time, plus the wait for the next dashboard refresh.
ETL or ELT, Warehouse or Lakehouse?
Once freshness is settled, the next choice is where transformation happens and where the data lives. ETL transforms data before loading it, while ELT loads raw data first and transforms it inside the platform.
| Option | Fits when | Watch out for |
|---|
| ETL into a warehouse | Sensitive fields must be masked before they land, and sources are few and stable | Every logic change needs a pipeline redeploy |
| ELT in a warehouse | The team works mostly in SQL, while the data is mostly structured | Raw copies of sensitive data still need their own access controls |
| ELT in a lakehouse with medallion layers | Data mixes structured and semi-structured formats, and data science also shares the store | Needs clear ownership of each layer and regular file housekeeping |
Kanerika’s ETL vs ELT comparison covers the trade-offs in detail. The guide to data pipeline architecture then shows how each pattern fits into a wider design.
Quality Gates: When to Warn, Reject or Stop Publishing
A quality gate is a rule with a consequence attached. Without the consequence, a failed check is just a log line that nobody reads.
Set three levels of response. A warning flags the dashboard but keeps it live, and a rejection moves bad rows to a quarantine table. A stop holds the last good version until someone fixes the cause. The thresholds below are illustrative, so set your own with the metric owner.
| Check | Example threshold (illustrative) | Action | Owner |
|---|
| Row count vs source | Difference above 0.5% | Warn, then investigate | Data engineering |
| Row count vs source | Difference above 2% | Stop publishing until fixed | Data engineering |
| Duplicate business keys | Any duplicate order ID | Reject to quarantine, then review | Data engineering |
| Required field missing | More than 1% of rows | Warn, then reject | Data engineering |
| Revenue total vs finance ledger | Mismatch above 0.1% | Stop publishing until reconciled | Metric owner |
| Data age at the dashboard | Older than the agreed target | Show a banner until it clears | BI team |
| Unannounced schema change | Any new, dropped or renamed column | Stop and alert the source owner | Source system owner |
| Unmapped code value | Any status or type code missing from the mapping table | Stop publishing the affected measure | Metric owner |
That check, for example, would have caught the Monday revenue tile in the opening story.
Silent row drops do the most damage because the totals still look plausible. Count rows in and out of every stage, and then report the difference. A data quality framework gives these checks a home and an owner.
Security, Privacy and Access
Security decisions belong before the build, since every copy of the data inherits them. A field left unprotected in the raw layer stays exposed in every layer that copies it.
- Classify fields as public, internal, confidential or personal before ingestion.
- Run pipelines under least-privilege service accounts, never a personal login.
- Apply row-level security so each user sees only their own region, team or customers.
- Set retention rules that cover raw, cleaned, backup and final tables.
- Keep secrets and personal data out of logs and error messages.
Buying a platform does not make the pipeline compliant. The platform gives you controls, and your team still decides how to use them. Kanerika’s guide to data governance principles explains how to assign that ownership.
Checklist
Data Engineering Checklist
A downloadable checklist for planning and reviewing data engineering work, from sources and access to quality checks, before a pipeline goes live.
Get the Checklist →
Build, Buy or Managed Service?
Build versus buy is really a question of what your team wants to own. Many organizations buy the plumbing and build only the parts that carry their own business rules.
| Option | Fits when | You own | Trade-off |
|---|
| Custom stack of open-source tools you run | Strong engineering team, unusual sources or strict hosting rules | Everything: code, servers, upgrades and on-call | Most control, but the highest support load |
| Managed platform such as Fabric, Databricks or Snowflake | You want connectors, compute and monitoring provided | Business logic, metric layer and access rules | Faster start, although consumption costs need watching |
| Partner-built on a managed platform | You need a first flow live soon and lack in-house capacity | Metric definitions and sign-off, with a handover plan | Faster delivery, so plan knowledge transfer early |
| Cloud vs on-premises | Elastic workloads suit cloud, while strict residency rules or existing hardware suit on-premises | Configuration and cost in the cloud; hardware and patching on-premises | Hybrid setups are common when an ERP stays on site |
Whichever route you take, automate scheduling, retries and alerts from the first release. The guide to data pipeline automation explains how those pieces fit together.
Worked Example: A Retail Dashboard With a 30-Minute Freshness Target
Here is how the decisions fit together in one illustrative case. A retailer wants store managers to see sales and stock by store during trading hours, with data no older than 30 minutes.
- Decision and user. Store managers decide when to move staff and when to request stock transfers.
- Metric and grain. Net sales and units on hand by store and hour, owned by the retail finance lead.
- Sources. Point-of-sale transactions and the inventory tables in the ERP. Both update rows, so CDC captures changes and deletes.
- Load pattern. CDC-fed incremental loads every 15 minutes rather than streaming. Nobody acts within seconds, so streaming would add cost without changing a decision.
- Freshness arithmetic. Assume processing takes up to 10 minutes. A sale made just after a load starts waits up to 15 minutes, then 10 more, so the worst case is about 25 minutes. That leaves 5 minutes for the serving stage, so the next step decides the target.
- Serving. An imported Power BI model refreshed 48 times a day could add up to 30 more minutes and break the target. The team tests Direct Lake with automatic updates turned on, so the report picks up new gold-table versions without a scheduled import refresh. It then measures data age on the report before go-live.
- Quality gates. Stop publishing if store sales drift from point-of-sale totals beyond the agreed threshold, and show a warning once data age passes 30 minutes.
- Owners. Retail finance owns the metric, data engineering owns the loads and the BI team owns the report.
The result is a pipeline sized to the decision. It is fast enough for the store manager and far cheaper to run than a streaming design.
Kanerika Service
Data Engineering Services
Kanerika designs and builds data analytics pipelines on Microsoft Fabric, Databricks and Snowflake, from source contracts and CDC loads to governed semantic models.
Explore Data Engineering Services
Data Analytics Pipeline Use Cases by Industry
The pattern is the same in every industry, and what changes is the decision at the end. Each example below names the decision the pipeline supports.
- Retail Analytics: Sales, stock and promotion data feed store dashboards, helping managers decide on transfers, markdowns and staffing.
- Healthcare Analytics: Admission, bed and staffing data help operations teams decide where to move nurses before a ward runs short.
- Financial Analytics: Ledger, payment and forecast data support daily cash decisions and flag unusual transactions for review.
- Manufacturing Analytics: Machine, quality and order data show which lines are falling behind, so planners can reschedule before a delivery date slips.
- Logistics Analytics: Shipment, carrier and warehouse data reveal late routes and help teams decide when to switch carriers.
- Game Analytics: Session and in-game event data show where players stall or quit, helping game developers improve game character design and user experience.
Whatever the industry, the first build should serve one of these decisions end to end, which is where the next section starts.
How to Build Your First Data Analytics Pipeline
A first pipeline should be narrow and complete. One decision, one metric and one trusted dashboard teach a team more than ten sources landed in raw storage.
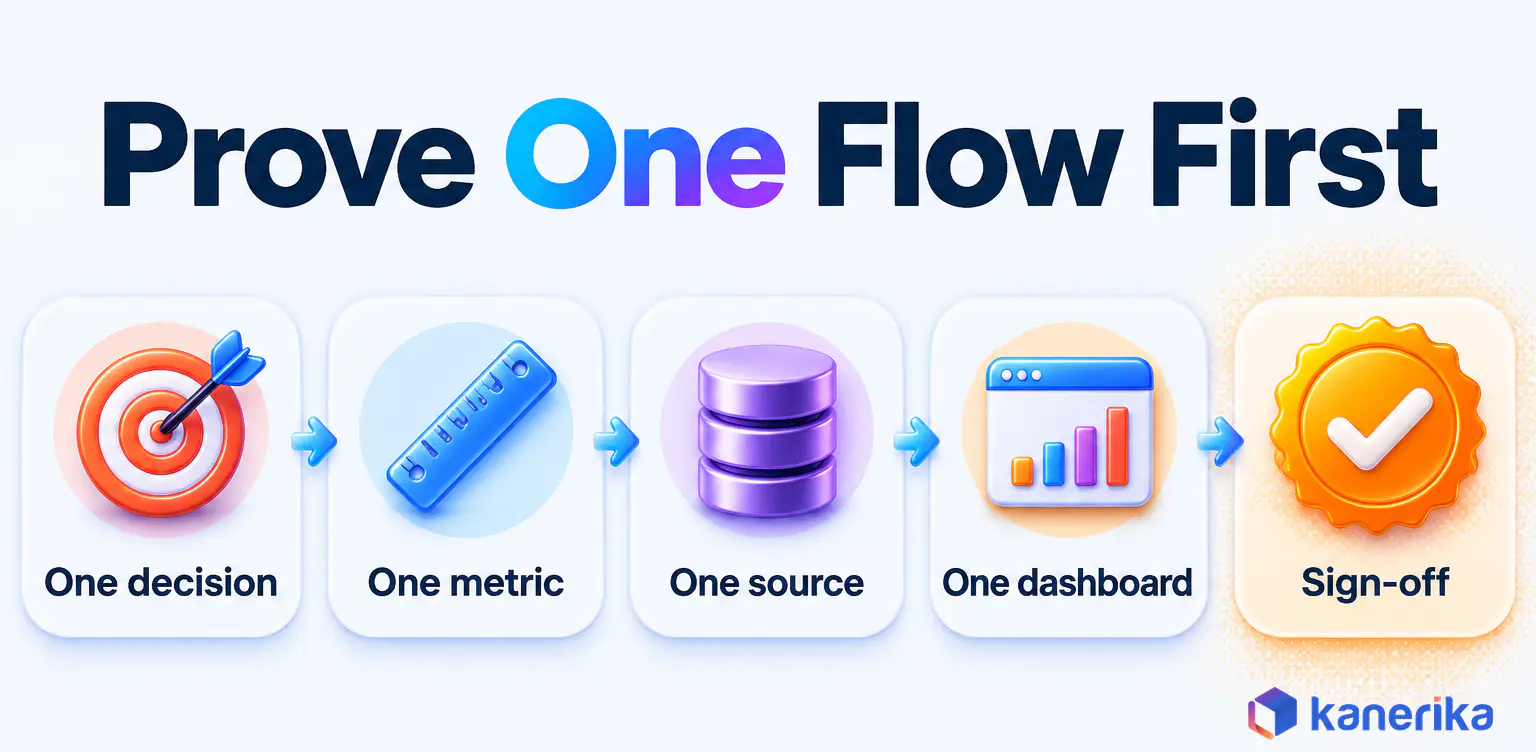
Work through the steps in order, and do not start the next one until the current one has an owner who agrees it is done.
- Pick one decision and one metric. Agree the definition, grain and owner in writing.
- Profile the real data. Look at nulls, duplicates, odd codes and volumes in production extracts, not samples.
- Agree a source contract. Cover fields, change patterns, delete behavior and who announces schema changes.
- Build ingestion with load history. Land raw copies and record every load so any day can be replayed.
- Write transformations with reconciliation. Compare totals to the source and route failed rows to a rejected-records table.
- Publish through the real BI path. Use the production semantic model, workspace and security, not a demo copy.
- Test the hard cases. Try peak volume, a missed run, a partial failure and a late-arriving file.
- Release with owners and sign-off. The metric owner confirms the numbers, and support knows who to call.
Steps 2 and 3 are the ones teams most often rush. Both are cheap compared with fixing a number that is already published.
Production Acceptance Tests
Before go-live, run tests that prove the pipeline behaves well on a bad day. Each test also needs evidence and a named person who signs it off.
| Test | Expected behavior | Evidence | Sign-off |
|---|
| Rerun the same load | Totals stay unchanged, so nothing is counted twice | Row counts and totals before and after | Data engineering |
| Backfill last quarter | History corrected while current reports stay untouched | Current-month totals compared before and after | Metric owner |
| Missed scheduled run | Next run catches up, and a data age warning shows meanwhile | Load history and dashboard banner | BI team |
| Partial failure mid-load | No half-loaded tables published until the load completes | Last good version still served | Data engineering |
| Reconciliation after recovery | Totals match the source again | Reconciliation report | Metric owner |
| Peak volume | Load still finishes within the freshness target | Run duration at peak | Data engineering |
| Access by role | Users see only the rows they are allowed to see | Test accounts for each role | Data owner |
Keep the evidence with the release notes. When someone questions a number months later, it shows what was tested and who agreed.
Checklist
Data Analytics Checklist
A downloadable checklist to plan an analytics build, define metrics and owners, and check reports before you release them.
Get the Checklist →
What a Data Analytics Pipeline Costs to Build and Run
Cost has two parts: the effort to build the first flow, and the recurring bill to run it. The second part surprises teams more often, because it grows with every refresh, every source and every user.
| Cost component | What drives it | How to control it |
|---|
| Build effort | Number of sources, metric complexity and source data quality | Start with one decision and one metric, then expand |
| Compute for loads and transformations | Load frequency, data volume and inefficient queries | Incremental loads that process only what changed |
| Storage | Raw history, copies across layers and retention | Retention rules for each layer, especially raw history |
| Dashboard refresh and serving | Refresh count, model size and concurrent users | Match refresh to the freshness target rather than the maximum |
| Monitoring and support | Number of pipelines and on-call hours | Alerts on real failures only, with named owners |
| Backfills and reprocessing | Logic changes, late data and recovery | Partitioned tables, so you replay only what changed |
| Licenses and platform capacity | The platform’s pricing model and the number of environments | Review capacity use monthly and resize |
Price the running cost per month before you approve the build. A pipeline that loads every 15 minutes runs 96 times a day, and each run uses compute whether or not the data changed.
That arithmetic is why the freshness decision sits so high on the list. Halving the interval doubles the number of runs, so ask for the business reason before you shorten it.
Talk to Kanerika
Want a Second Opinion on Your Pipeline Plan?
Kanerika reviews your decision, metric definitions, freshness target and running-cost estimate before you commit to a build.
Book a Working Session →
Common Mistakes and How to Prevent Them
The costly pipeline failures are usually quiet ones. The jobs run and the dashboard loads, but the number is wrong, late or visible to the wrong people.
| Mistake | Impact | Prevention | Owner |
|---|
| Unannounced schema changes | Columns load empty or joins break | Source contract plus a schema-change gate | Source system owner |
| Bad joins and duplicates | Inflated totals that still look plausible | Unique-key checks and reconciliation to source | Data engineering |
| Ignoring late data and deletes | Totals drift away from the source over time | CDC with delete handling and a late-data window | Data engineering |
| Retries that double count | Revenue or units counted twice | Loads that can rerun safely, keyed on business IDs | Data engineering |
| Sensitive data in logs | Personal data exposed outside access controls | Mask fields in error messages and review logs | Security |
| No lineage | Nobody can trace a wrong number to its source | Record lineage from source to report | Data engineering |
| Unlimited retries and full scans | Runaway compute costs | Retry limits and incremental reads | Data engineering |
| No support owner | Failures wait until users complain | A named owner and an on-call rota | Business and IT leads |
| Streaming without a business need | High cost with no better decision | Match the pattern to the action time | Architecture lead |
Lineage deserves a special mention, because it is the first thing you need when an executive questions a figure. Kanerika’s guide to data lineage explains how to record it. For tuning once the pipeline is live, see the guide to data pipeline optimization.
How Kanerika Builds Data Analytics Pipelines
Kanerika builds pipelines in the same order this guide recommends: the decision first, then one proven flow, then scale. The method has four short stages, and each one ends with a sign-off.
- Assess. Agree the decision, the metric definitions and the owners, then profile the real source data. The output is the signed one-page decision sheet described earlier in this guide.
- Prove one flow. Build one source-to-dashboard path with reconciliation and the acceptance tests above. The metric owner signs off on real numbers, not a demo copy.
- Harden. Add quality gates, row-level security, monitoring and recovery runbooks. Support owners are named before the first user relies on the report.
- Expand. Add sources and metrics on the same governed model, one flow at a time. Each new flow passes the same tests as the first one.
Proof: One Governed Pipeline Across Three SAP Systems
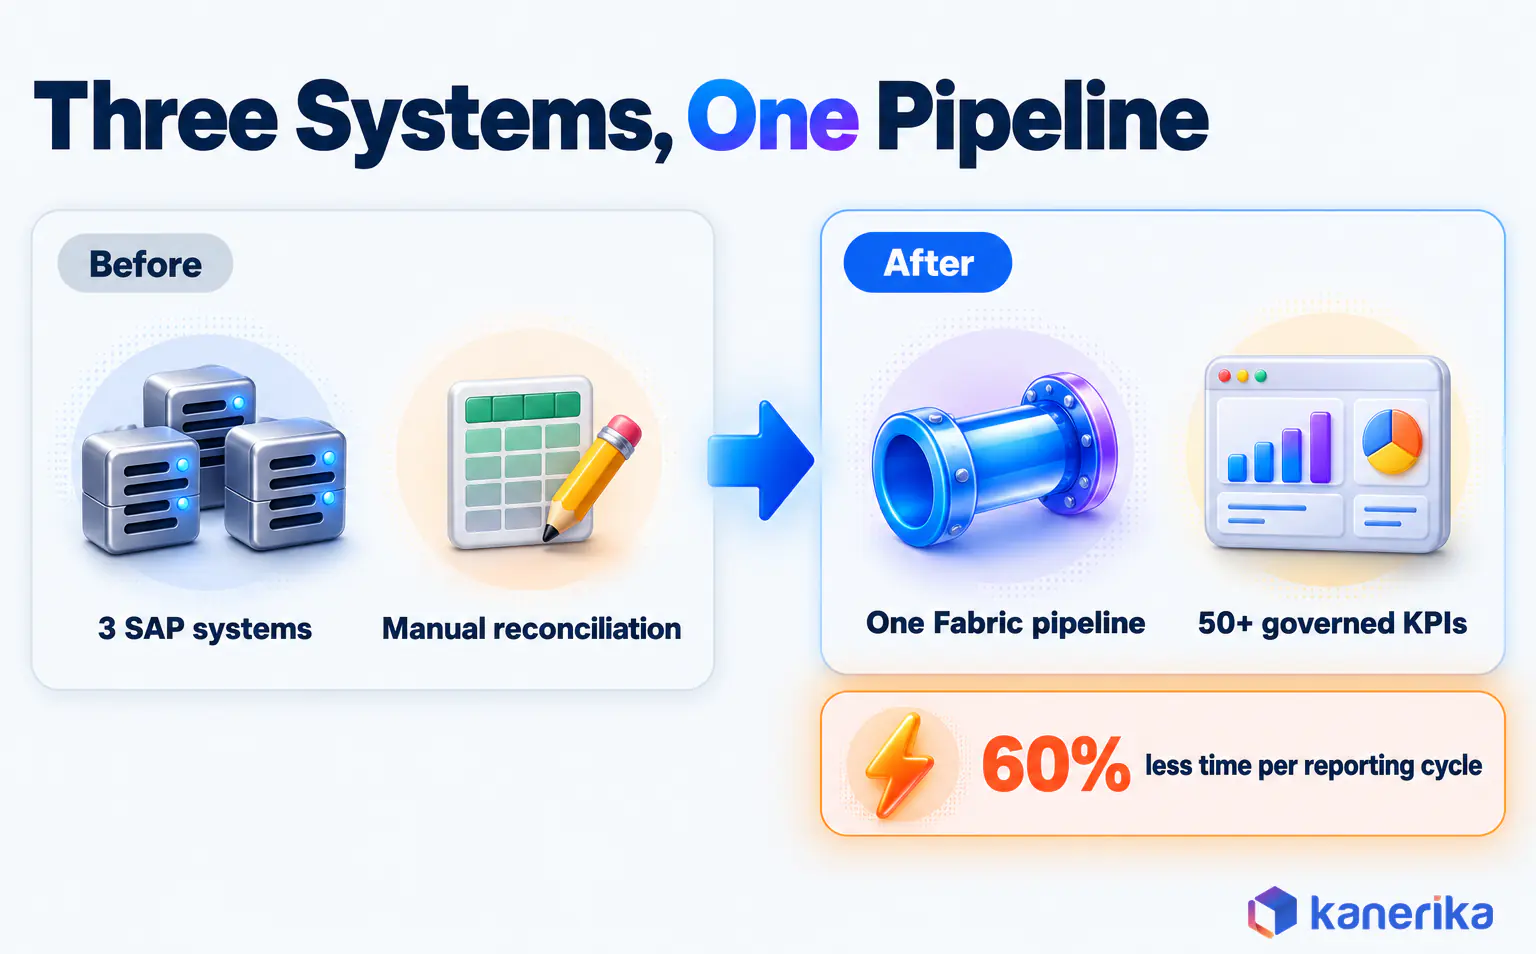
One manufacturing engagement shows the method at work. A global thermal-management manufacturer ran its order journey across three disconnected SAP systems: Cloud for Customer, CPQ and S/4HANA. Its teams reconciled lead-time data by hand in every reporting cycle.
Kanerika built one governed pipeline on Microsoft Fabric. About 35 source tables flow into a medallion architecture across development, test and production. The pipeline bridges Opportunities, Quotes and Orders, so a deal can be followed from first quote to shipped order.
A self-updating Power BI report replaced the manual pulls, with more than 50 standardized KPIs and four levels of row-level security. The result was a 60% reduction in time spent per reporting cycle, as described in the order lifecycle visibility case study.
Each piece maps to a stage in this guide. The SAP tables are the sources, and the medallion layers do the transformation. The standardized KPIs form the metric layer, while row-level security governs who sees each number.
Kanerika’s data analytics services cover this work from assessment to support. Its data engineering services handle the platform build underneath.
Whoever builds it, the order of work holds. Know the decision, the metric, the data age limit and the owners before you build a data analytics pipeline. Then the tools become the easy part.
Case Study
60% Less Reporting Effort Across 3 SAP Systems on Fabric
A global thermal-management manufacturer replaced manual lead-time reconciliation across three SAP systems with one governed Fabric pipeline and a self-updating Power BI report on 50+ KPIs.
Read the Case Study →
Frequently Asked Questions
What is a data analytics pipeline?
A data analytics pipeline is the repeatable path that moves data from source systems to approved metrics in dashboards and reports. It collects records, cleans and joins them, applies agreed business rules and serves the result where people work. The pipeline is complete only when someone can trust a number enough to act on it.
How does a data analytics pipeline work?
It works in stages. Data is copied from sources such as ERP and CRM systems into raw storage. Transformation cleans and joins it, and a metric layer applies one definition per KPI. Dashboards then serve those metrics at an agreed freshness. Checks at each stage stop wrong or late data from reaching the people who make decisions.
How many types of data pipelines are there?
Pipelines are usually grouped by how often they move data and by where transformation happens. By timing, the common types are batch, micro-batch and streaming. By transformation, the common patterns are ETL and ELT. Many real pipelines are hybrids, such as change data capture feeding micro-batch loads into a lakehouse every few minutes.
Should I use batch or streaming for an analytics pipeline?
Start from how quickly someone acts on the number. If people act within hours, batch is enough. If they act within the hour, micro-batch every 5 to 15 minutes usually fits. Choose streaming only when a person or an automated action must respond within seconds. Streaming costs more to run and needs on-call support.
What is CDC in a data pipeline?
CDC stands for change data capture. It records the inserts, updates and deletes made to source tables, so the pipeline can load only what changed. SQL Server, for example, offers CDC on tracked tables. CDC can feed batch, micro-batch or streaming loads. The load schedule still decides how fresh the data on a dashboard is.
Which tools are used to build a data analytics pipeline?
Tools are best chosen by role. Ingestion and orchestration options include Fabric Data Factory and Apache Airflow. Transformation options include Dataflow Gen2, Databricks Lakeflow pipelines, Snowflake Dynamic Tables and dbt. Power BI semantic models often serve the metrics. Pick the platform your team can support, then test each role on your own data.
Is Databricks a data pipeline tool?
Databricks is a data and AI platform that includes pipeline features. Its Lakeflow pipelines extend Apache Spark Declarative Pipelines and handle batch and streaming work in SQL or Python. Teams use it for ingestion, transformation and lakehouse storage. A BI tool such as Power BI usually sits on top to serve dashboards to business users.
Do data analysts build data pipelines?
Analysts often build the later stages, such as SQL transformations, semantic models and dashboards. Data engineers usually own ingestion, orchestration, security and recovery. Tools like dbt and Dataflow Gen2 let analysts take on more of the transformation work themselves. A clear split of ownership matters more than job titles, so name an owner for each stage.
How do you build a data analytics pipeline?
Start with one decision and one metric, and agree its definition and owner. Profile the real data, then agree a source contract that covers changes and deletes. Build ingestion with a load history and transformations with reconciliation. Publish through the production BI path, test failures and reruns, and release only after the metric owner signs off.
How much does a data analytics pipeline cost?
Cost depends on the number of sources, data volume, load frequency and the platform’s pricing model. Plan for two parts. The first is the build effort for the first flow. The second is the recurring bill for compute, storage, dashboard refresh, monitoring and backfills. Estimate the monthly running cost before you approve the build.
How long does it take to build a data analytics pipeline?
There is no fixed duration, because timelines depend on source complexity, data quality and how quickly metric definitions are agreed. A narrow first flow with one decision and one metric moves far faster than a broad build. Profiling the data and agreeing the source contract usually take longer than teams plan, so allow time for both.
How do you monitor data quality in an analytics pipeline?
Put checks at every stage and attach an action to each one. Compare row counts with the source, test for duplicate keys and missing fields, and reconcile totals to the system of record. Show data age on the dashboard. Decide in advance which failures warn, which reject records and which stop the dashboard from publishing.
What are the stages of a data analytics pipeline?
There is no universal count, so different guides list three, five or six stages. A practical split is sources, ingestion and raw landing, cleaning and transformation, the metric layer, serving and decisions. Each stage hands a clear output to the next one. Each stage also needs its own quality check and a named owner.
What is a semantic layer in a data analytics pipeline?
A semantic layer holds the shared business definitions that reports use. It defines each KPI once, along with its grain, its relationships and its owner. In Power BI this is usually a semantic model. Without it, every report author writes their own formula, and two dashboards can show two different numbers for the same metric.
What are the main components of a data analytics pipeline?
The main components are ingestion, storage, transformation, orchestration, a semantic or BI layer, quality monitoring and governance. Ingestion copies data in, and storage holds it in layers. Transformation applies business rules, and orchestration runs the steps in order. The semantic layer defines metrics once. Monitoring and governance keep the data correct, fresh and secure.
What is an example of a data analytics pipeline?
Picture a retailer that wants store sales and stock no older than 30 minutes. Change data capture picks up point-of-sale and inventory changes every 15 minutes. Transformation cleans the rows and calculates net sales by store and hour. A Power BI report shows the result with its data age, and store managers use it to move staff.
What is the difference between a data pipeline and an ETL pipeline?
A data pipeline is any automated flow that moves data between systems. An ETL pipeline is one kind of data pipeline that extracts, transforms and then loads data in that order. So ETL is a data pipeline, while plenty of data pipelines are not ETL. Some load raw data first, and others stream events continuously.
What is an ETL pipeline in data analytics?
In analytics, an ETL pipeline extracts data from source systems, transforms it into clean and consistent tables and loads it into a warehouse for reporting. The transformation happens before loading. Teams often choose it when sensitive fields must be masked before they land. It remains a common pattern for stable, structured sources with well-known business rules.
What is the difference between ETL and ELT?
ETL transforms data before loading it into the target system. ELT loads raw data first and transforms it inside the warehouse or lakehouse, usually with SQL. ELT suits teams that work in SQL and want raw history kept for reprocessing. ETL suits cases where sensitive fields must be masked before they reach shared storage.
Is ETL obsolete?
No. ETL is still a sound pattern for sensitive data that must be cleaned or masked before it lands, and for stable sources with fixed rules. ELT is common on cloud warehouses and lakehouses because compute there scales easily. A team can run both patterns side by side, choosing per source and per data type.
Will AI replace ETL?
AI does not remove the work that ETL does. Data still has to be moved, cleaned and checked before anyone reports on it. AI assistants can help write transformation code, suggest field mappings and flag unusual values. The business rules, quality thresholds and final sign-off still need people who understand what the numbers mean.




