TL;DR
Build your cloud architecture on one public cloud with managed services, and move to hybrid or multi-cloud only when a named constraint forces it. The architecture is the blueprint for how compute, storage, networking, identity and data connect to run your workloads. Five decisions are costly to undo: deployment model, service model per workload, landing zone and identity, data placement with recovery targets, and three-year cost.
Regulated data, strict latency, an on-premises estate you must keep or a provider-only service are the constraints that justify that complexity. Design against the AWS, Azure or Google Cloud well-architected pillars, then test failover and cost before go-live. Flexera puts wasted cloud spend at 29% in 2026, so build the cost model into the design from day one.
Key Takeaways
- Cloud architecture is the design layer: it decides which services run where, how they connect, who can reach them and how they recover.
- Default to one public cloud on managed services; hybrid and multi-cloud need a named reason such as residency, latency or an estate you must keep.
- Pick the most managed service model each workload can tolerate, because every layer you run yourself is a layer you patch and staff.
- Build the landing zone and identity model before the first workload arrives, since retrofitting them later is a migration project of its own.
- AWS, Azure and Google Cloud test the same qualities in their well-architected frameworks: security, reliability, cost, operations and performance.
- Model cost over three years per workload, including data transfer, licences and people, and tag every resource to an owner from day one.
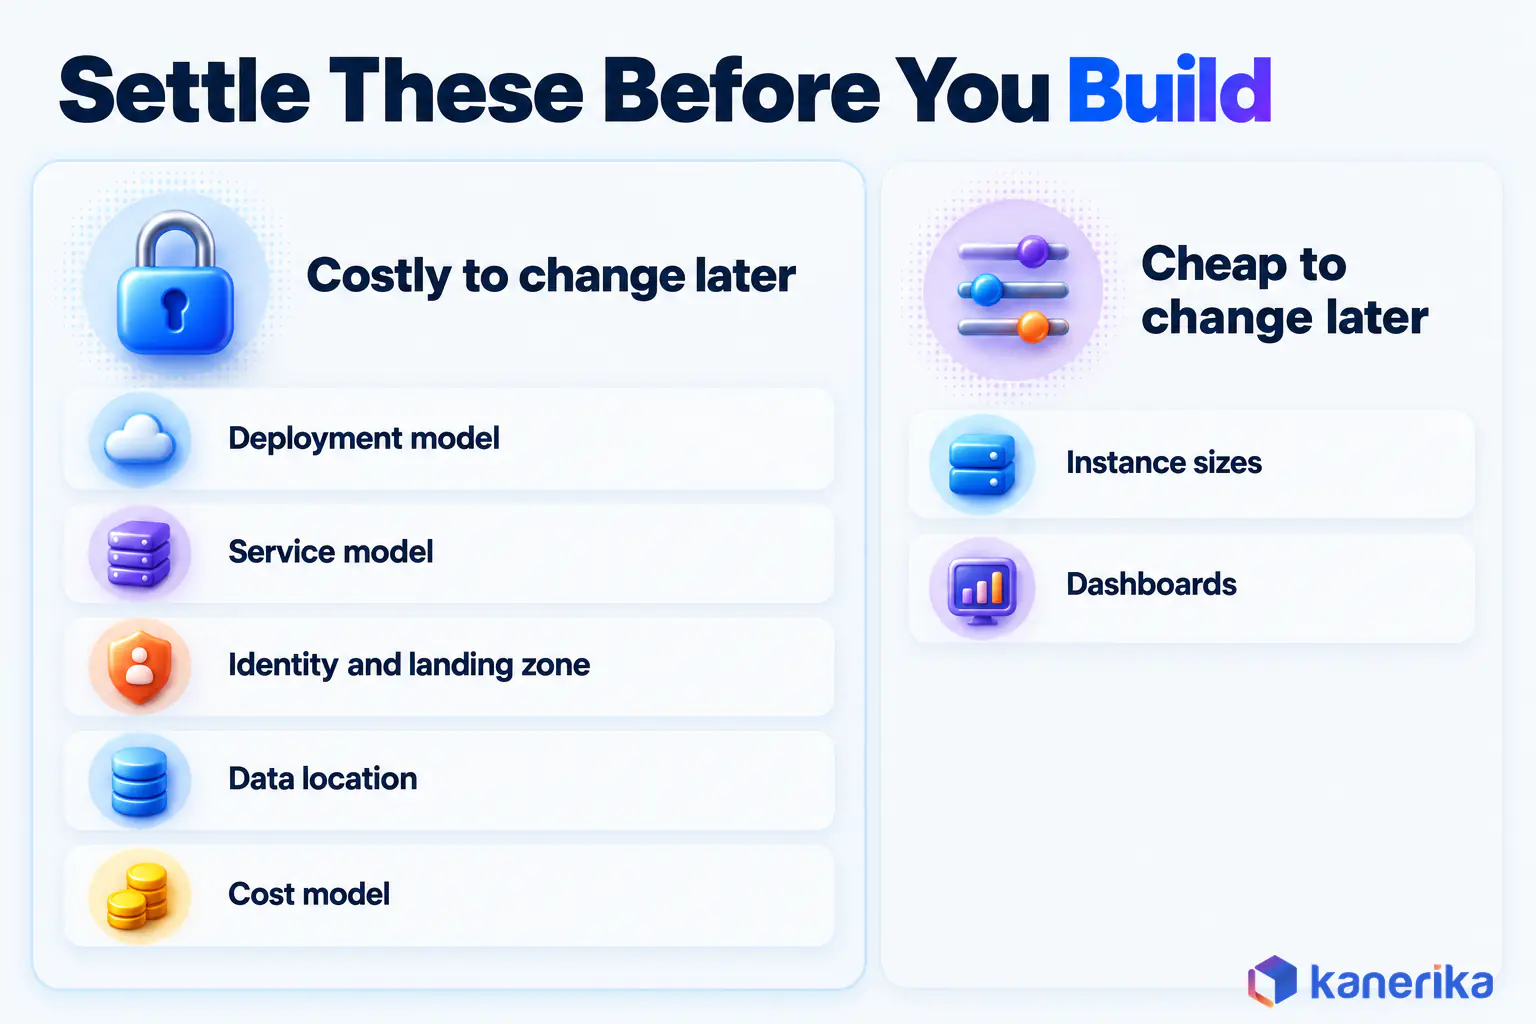
Before You Approve the Build: The Decisions You Cannot Cheaply Undo
Picture a US manufacturer moving its analytics to the cloud while its ERP stays on-premises for another 18 months. The data team wants a lakehouse by spring, finance wants a predictable monthly bill and security wants written recovery targets first.
Each request then lands on the design. The timeline depends on how soon a landing zone and identity model exist. The bill depends on storage tiers and plant-to-cloud traffic, while the recovery targets set how many regions the design spans.
None of this is hard once it is written down. It gets expensive when it is decided by default, one console click at a time, and then surfaces at the first audit or invoice.
What Is Cloud Architecture?
Think of it as the plan a team agrees on before it rents a single server. It records which services run where, how they talk to each other, who can reach them and what happens when one of them fails.
Cloud architecture is the blueprint that defines how cloud computing components connect to deliver applications and services. It sits inside the broader discipline of software architecture, covering the front-end interfaces users touch, the back-end compute and storage that do the work, and the network that ties them together. Each layer has a job, and the design decides how well they work as a system.
A good architecture also writes down its reasons. If a workload sits on a managed database instead of a virtual machine, the design notes why and what would change it. That record also lets a new engineer or an auditor understand the estate without reverse-engineering it.
Cloud Architecture vs Cloud Infrastructure vs Cloud Computing
The three terms get used interchangeably, yet they answer different questions. Cloud computing is the delivery model and cloud infrastructure is what is actually deployed, while the architecture is the design that connects the two.
| Term | Question it answers | What it produces |
|---|
| Cloud computing | How are IT resources delivered? | On-demand, pay-per-use access to compute, storage and services over a network |
| Cloud infrastructure | What is running right now? | The deployed servers, networks, storage and managed services |
| Cloud architecture | How should it all fit together, and why? | Diagrams, decision records, standards and the reference designs teams build from |
The most cited definition of the delivery side still comes from the US National Institute of Standards and Technology. Its SP 800-145 definition of cloud computing lists five essential characteristics: on-demand self-service, broad network access, resource pooling, rapid elasticity and measured service. It also names three service models and four deployment models, and those categories still frame most design conversations.
Case Study
25% Lower Storage Costs for Steel Manufacturing on Azure
How a North American steel mill services provider moved Dynamics AX data to Azure Data Lake with multi-factor authentication and pay-as-you-go storage, cutting storage expenses by 25% and lifting productivity by 40%.
Read the Case Study →
How Cloud Architecture Works: Layers and Core Components
The easiest way to see how the pieces fit is to follow one request. A sales manager in Chicago opens a dashboard, and once she clicks, the numbers appear within a second or two.
That request starts at the front end, in this case the browser the manager uses. It crosses the network through a DNS lookup, a content delivery network and a load balancer before it reaches the back end. There, an application service first checks the manager’s identity, then queries a data store and sends the result back.
Every hop is a design choice. Each one has a cost, a security boundary and a way to fail, which is why the architecture names an owner for every hop.
Front End, Back End, Network and Delivery Model
Most explanations, in practice, split the design into four building blocks. The front end covers web and mobile apps and partner APIs. The back end, in contrast, holds the compute, storage and logic that the user never sees. A network then joins them, and the delivery model decides whether those resources come from a public cloud, a private one or a mix.
| Component | Main decision | What to document |
|---|
| Front end | Web, mobile or API access, and where it is served from | Supported clients, CDN use, session handling |
| Back-end compute | Virtual machines, containers or serverless functions | Sizing rules, scaling limits, patch ownership |
| Storage and data | Object, block, file or managed database, and its tier | Data classes, retention, backup and recovery targets |
| Network | Hub-and-spoke or flat, public or private endpoints | IP plan, traffic paths, firewall and DNS ownership |
| Identity and security | One identity provider, role model, key management | Who can do what, emergency access, audit logging |
| Operations | Monitoring, logging, infrastructure as code, cost tags | Alert owners, tag policy, change process |
Checklist
Microsoft Azure Checklist
Documenting components for an Azure build? Use this checklist to assess cloud readiness, security, cost management and operations before the first workload lands.
Get the Checklist →
The Layered View: Hardware, Virtualization, Application and Services
Another common way to explain the design is a stack of four layers. The provider’s hardware sits at the bottom, and a virtualization layer above it then slices that hardware into virtual machines, containers and storage volumes. The application layer holds your workloads, and the service layer on top exposes everything as IaaS, PaaS or SaaS with metering.
You design the upper two layers directly, so they carry most of your decisions. The lower two you still choose, though indirectly, through your provider, regions and instance types.
Cloud Service Models: IaaS, PaaS, SaaS and Serverless
A service model answers one plain question: how much of the stack do you want to run yourself? NIST defines three service models, and serverless has since become a fourth option that architects plan around.
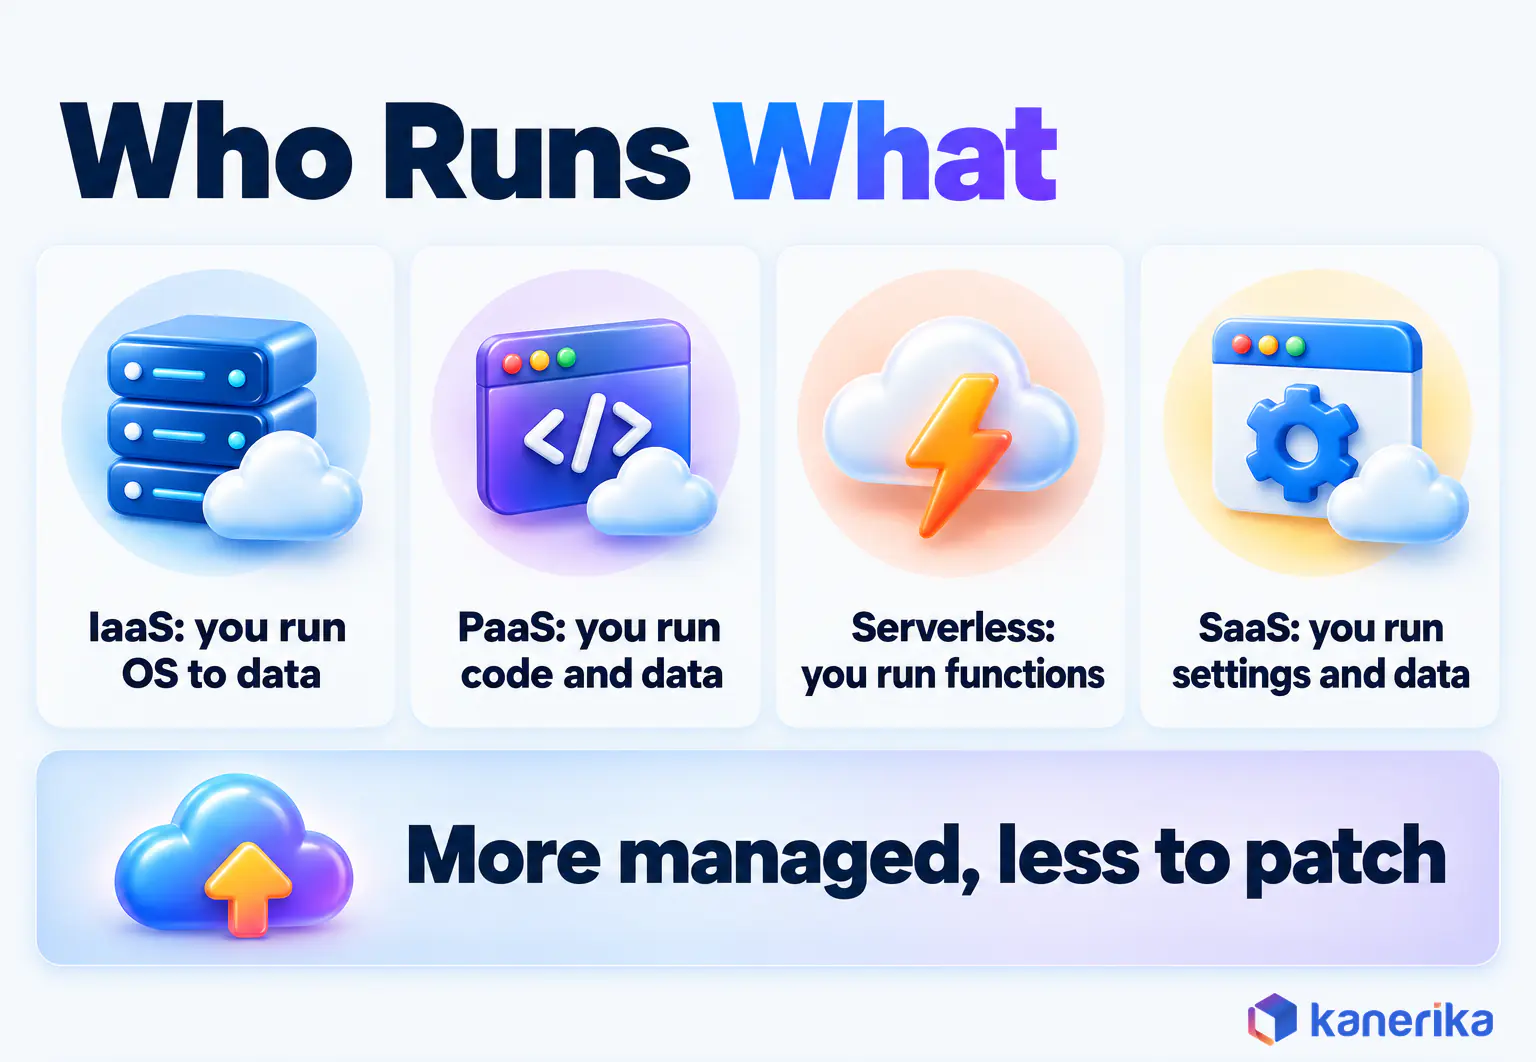
With infrastructure as a service (IaaS), the provider runs the hardware and virtualization while your team runs everything from the operating system up. Platform as a service (PaaS) hands the operating system and runtime to the provider, so your team ships code and manages data. Software as a service (SaaS) is a finished application, so you only configure it and fill it with your data. Our IaaS vs PaaS vs SaaS comparison also covers each model in more depth.
Serverless computing sits between PaaS and SaaS, though closer to PaaS. You write functions or define containers, and the provider runs, scales and bills them per request or per second of use.
| Model | Provider manages | You manage | Typical example |
|---|
| IaaS | Hardware, virtualization, physical network | Operating system, runtime, middleware, apps, data | Virtual machines for a rehosted legacy app |
| PaaS | Everything up to the runtime | Application code, data, access | Managed database or app hosting service |
| Serverless | Servers, scaling, runtime | Functions, events, data, access | Event-driven API or file-processing job |
| SaaS | The whole application | Configuration, users, data | CRM, email and collaboration suites |
The rule of thumb is short. Pick the most managed model that still gives the workload the control it needs. Every layer you run yourself is a layer you patch, monitor and staff.
Cloud Deployment Models: Public, Private, Hybrid and Multi-Cloud
The deployment model decides where your workloads physically run, as well as who else shares that hardware. It comes first among the five decisions because it shapes almost everything after it, from the network design to the skills your team needs.
NIST also lists four deployment models: private, community, public and hybrid. Community clouds, shared by organizations with common requirements, are rare outside government, so most teams weigh multi-cloud as the fourth option instead.
| Model | Fits when | Main benefit | Main trade-off |
|---|
| Public cloud | New workloads, variable demand, fast delivery | Managed services, global regions, no hardware to run | Less control of hardware; spend grows without guardrails |
| Private cloud | Strict isolation, steady demand, an existing data center | Full control of hardware and tenancy | You run and refresh the whole stack yourself |
| Hybrid cloud | Some systems must stay on-premises or in-country | Keeps those systems while new work moves | Two environments to secure, connect and monitor |
| Multi-cloud | A required service, contract or acquisition sits on another provider | Access to each provider’s strengths | More skills, more tooling, more data transfer cost |
When One Public Cloud Is Enough
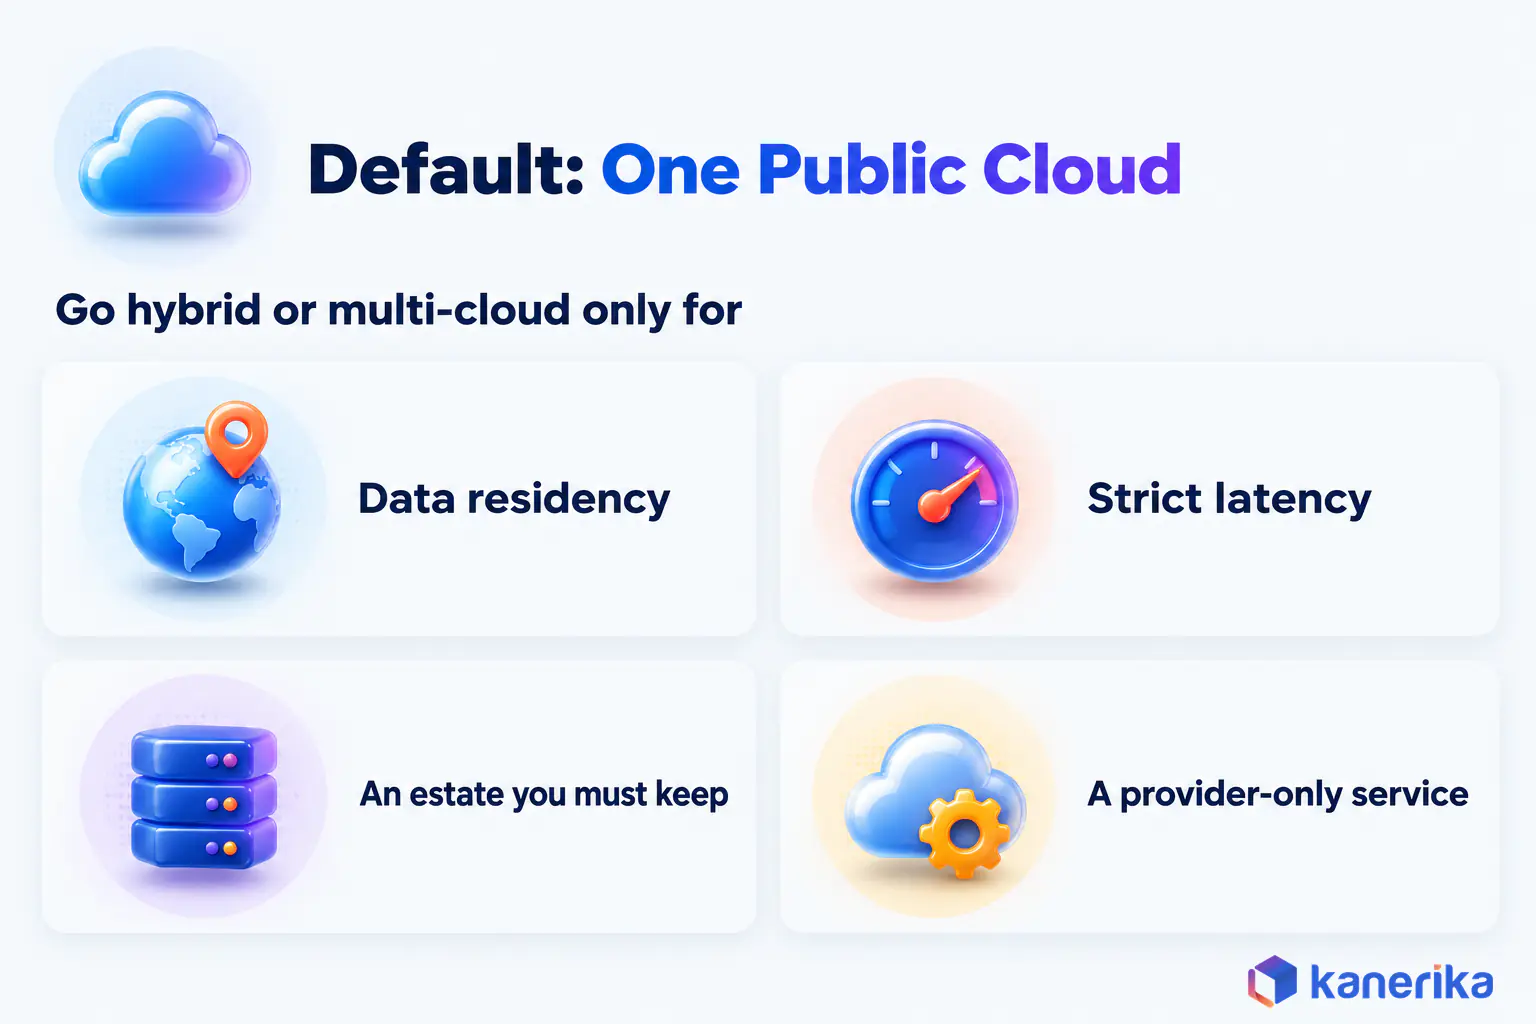
For a new workload, start on one public cloud and use its managed services, especially for data and identity. You then get one identity system, one network model, one bill and one set of skills to hire for.
Resilience comes from spreading the workload across availability zones and, where the recovery target demands it, a second region of the same provider. That covers the failures most designs actually face, such as a zone or a single service going down.
Teams often add a second provider in order to avoid lock-in, yet the bigger risk is usually data gravity and skills. Open data formats and infrastructure in code therefore buy most of the exit options for a fraction of the complexity.
When Hybrid or Multi-Cloud Earns Its Complexity
Hybrid is common because many estates still hold systems that cannot move yet. Flexera reported in March 2026 that 73% of organizations operate hybrid environments. Gartner predicted in late 2024 that 90% of organizations will adopt a hybrid cloud approach through 2027.
Being common still does not make it the right default. Choose hybrid cloud or multi-cloud when you can name the constraint that forces it:
- Data residency or sovereignty rules that a public region cannot meet.
- Latency limits, such as plant-floor systems that must answer in milliseconds.
- An on-premises or acquired estate that will take years to retire.
- A capability that only one provider offers and the business depends on.
Unless someone can name the constraint, the extra environment adds cost without adding value. Kubernetes can make workloads portable, but it does not make data, identity or networking portable.
Common Cloud Architecture Patterns
A pattern is a proven layout for a recurring problem, and the right one depends mostly on the workload’s shape. A steady internal app, a spiky customer API and a nightly data pipeline, for example, each want something different.
The six patterns below cover most enterprise workloads, at least at the infrastructure level. Code-level structure, such as how a service splits its modules, belongs to software architecture design patterns and sits one level below these choices.
| Pattern | Best fit | Trade-off |
|---|
| N-tier (web, app, data) | Steady line-of-business apps and rehosted legacy systems | Simple to run, but scales as a block rather than per feature |
| Microservices | Large products with several teams releasing independently | Team speed, paid for with more network calls, monitoring and versioning |
| Event-driven | Orders, sensor feeds and workflows that react to changes | Loose coupling, but end-to-end tracing gets harder |
| Serverless | Spiky or occasional jobs, APIs and file processing | No idle cost, but cold starts and per-call limits |
| Hub-and-spoke network | Any estate with several teams or subscriptions | Central control of traffic and security; the hub needs an owner |
| Lakehouse analytics | Shared data for BI, data science and AI | One governed copy of data, which needs governance from day one |
Compute choice then follows the pattern. Virtual machines suit software that expects a full server and containers suit portable, densely packed services, while serverless suits short bursts. Most estates use all three, and the architecture says which workload gets which.
A Reference Architecture for an Enterprise Data and AI Platform
A reference architecture is a reusable blueprint that teams copy instead of starting from a blank page. For many enterprises the first one worth drawing is the data and AI platform, because analytics is often the first large workload to move.
The layers below follow the manufacturer from the opening, with plant and ERP data on-premises and analytics in the cloud. Identity, data governance and monitoring are not boxes at the end of the diagram. They run across every layer.
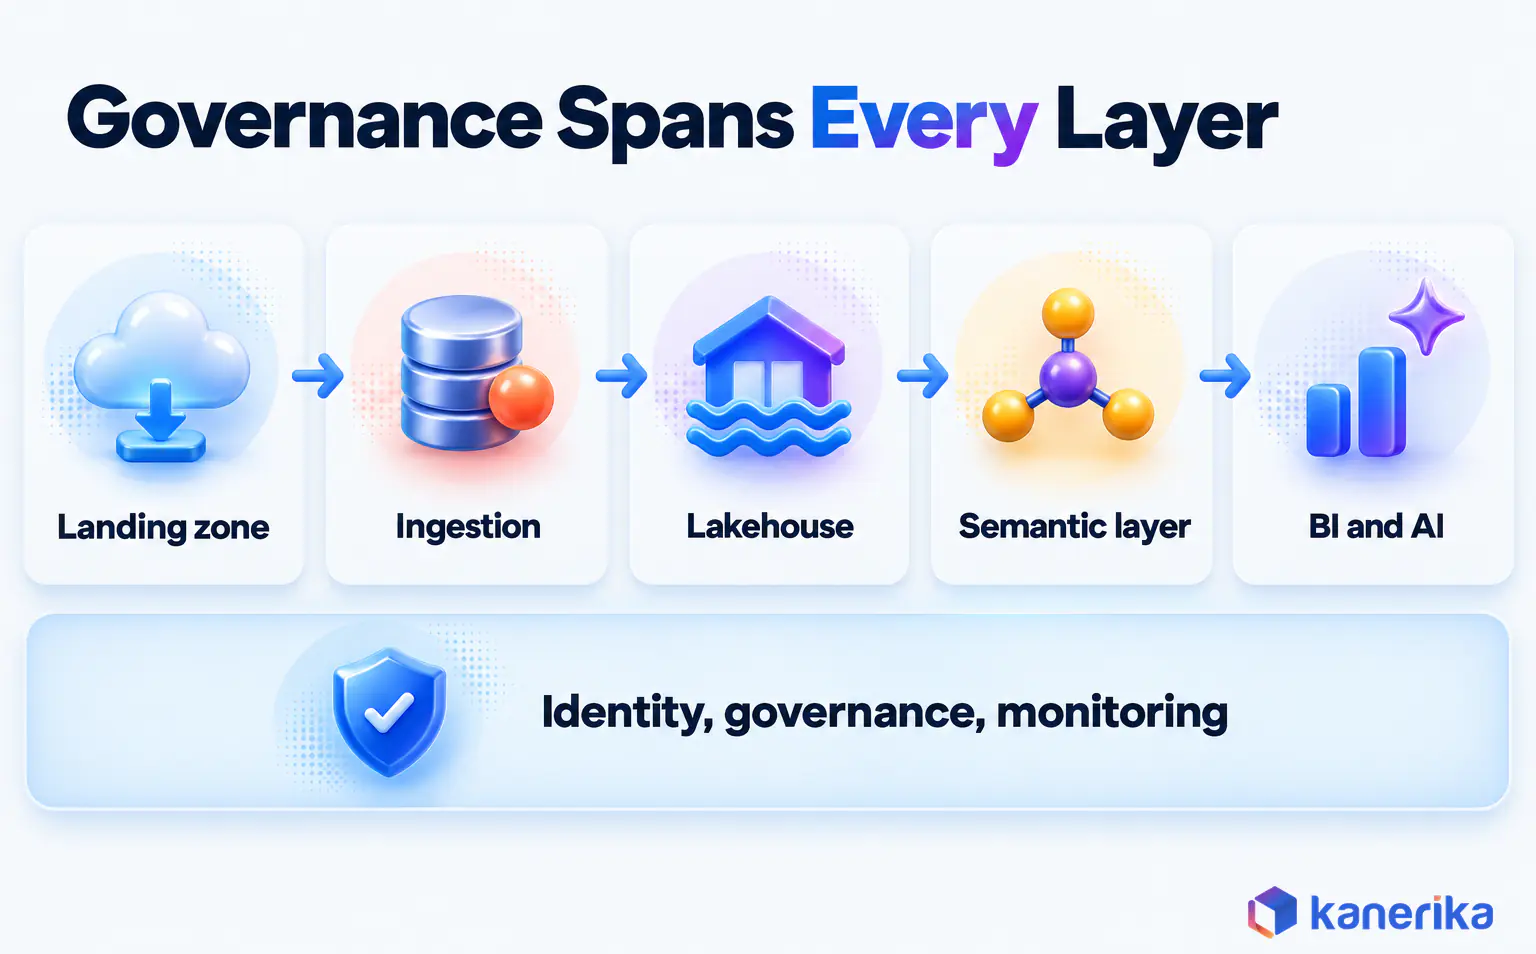
- Landing zone. Accounts or subscriptions, the hub network, guardrail policies and the identity provider, all set up before any data arrives.
- Ingestion. Batch and change-data-capture pipelines from the ERP, plant systems and SaaS apps, running over a private connection. Our cloud data integration guide also compares the tools for this layer.
- Lakehouse or warehouse. Raw, cleaned and curated zones in open table formats, with storage tiers matched to how often data is read. A cloud data warehouse still suits estates where most of the work is SQL reporting.
- Semantic layer. Governed business definitions, such as revenue or scrap rate, so every report uses the same numbers.
- BI and AI. Dashboards, notebooks and model endpoints that read from the curated zone, never from raw copies.
The platform choice changes the names rather than the shape. A Databricks lakehouse architecture and a Microsoft Fabric architecture both map onto these five layers, with different services filling each box.
Well-Architected Pillars: What AWS, Azure and Google Cloud Agree On
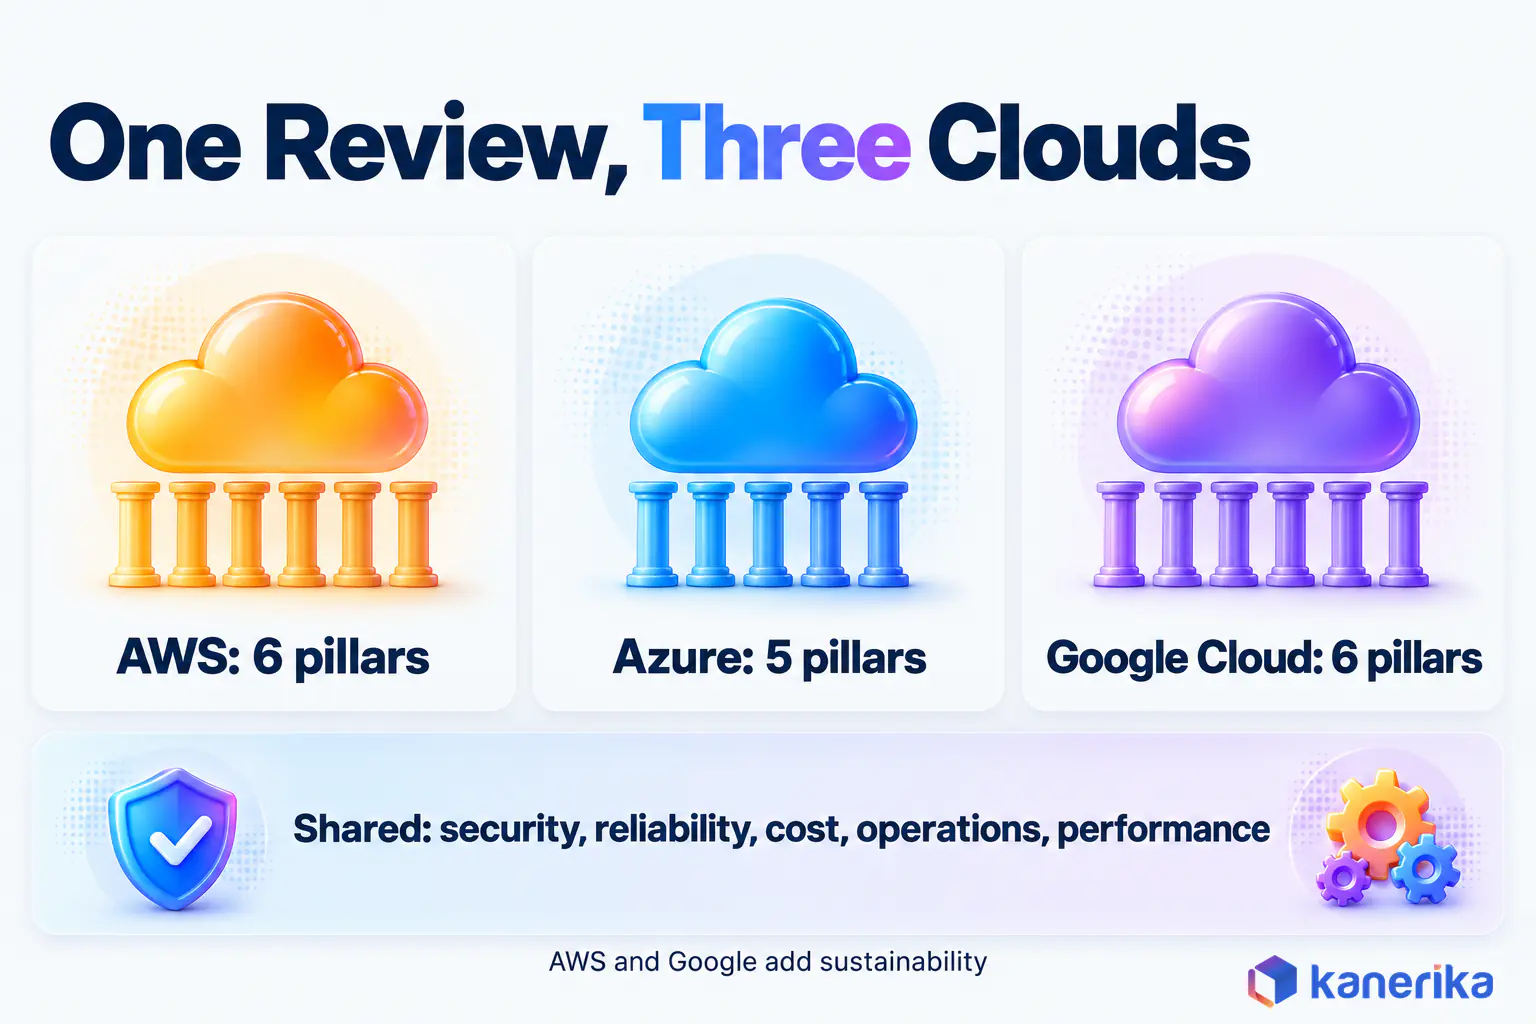
Each major provider also publishes a framework for judging whether a design is sound. The names and counts differ, but they test the same handful of qualities, so one review checklist can cover all three.
The table compares the AWS Well-Architected Framework, the Azure Well-Architected Framework and the Google Cloud Well-Architected Framework, which adds cross-pillar perspectives.
| Provider | Pillars | What they are |
|---|
| AWS | 6 | Operational excellence, security, reliability, performance efficiency, cost optimization, sustainability |
| Azure | 5 | Reliability, security, cost optimization, operational excellence, performance efficiency |
| Google Cloud | 6 | Operational excellence; security, privacy and compliance; reliability; cost optimization; performance optimization; sustainability |
When someone asks for the five pillars of cloud architecture, they usually mean Azure’s list: reliability, security, cost optimization, operational excellence and performance efficiency. AWS and Google also add sustainability as a sixth.
Run a pillar review at design time and again before go-live. Fixing a reliability gap on paper costs far less than fixing it in production.
Benefits of a Well-Designed Cloud Architecture
The benefits of cloud get quoted so often that they lose meaning. Each one only shows up when a specific design choice produces it, and the table pairs the two.
Month-end reporting shows how that works. A finance team runs heavy queries for a few days a month, so servers sized for that peak sit idle for weeks. Autoscaled managed compute grows for the close and shrinks afterwards, so the bill follows the work.
| Benefit | The design choice that produces it |
|---|
| Elastic scale | Autoscaling, serverless or managed services, with limits set per service |
| Lower run cost | Rightsized instances, storage tiers, commitments for steady load, ownership tags |
| Resilience | Multi-zone deployment, tested backups, a recovery runbook per workload |
| Security and compliance | One identity provider, least-privilege roles, policy as code, encryption by default |
| Faster delivery | Infrastructure as code, deployment pipelines, reusable landing zone templates |
| Room for AI | Governed data in open formats, close to the compute that will use it |
How to Design a Cloud Architecture Before You Build
Design is the stage where everything is cheapest to change, so it deserves more time than it usually gets. The six steps below take a team from requirements to a design it can defend, especially to finance, security and the business.
- Capture requirements and recovery targets. For each workload, record users, data classes, peak load, compliance needs and two recovery numbers. The recovery time objective (RTO) is how long the workload can be down. The recovery point objective (RPO), in contrast, is how much data you can afford to lose.
- Build the landing zone and identity model. Set up accounts or subscriptions, the hub network, guardrail policies and one identity provider before the first workload lands.
- Place workloads and map data flows. Choose a service model per workload, then draw where data moves, how often and across which boundaries. Traffic between regions and out of the cloud is a cost line, so count it here. Our data pipeline architecture guide also works through a full example.
- Write the infrastructure as code. Define networks, policies and services in versioned templates and deploy them through a pipeline. Our guide to cloud automation tools compares Terraform, OpenTofu, Bicep, CloudFormation and the platforms that govern them.
- Plan observability and disaster recovery. Decide what gets logged, who receives alerts and which recovery tier each workload belongs to.
- Validate before go-live. Run a load test, a failover test and a cost test against the three-year model, then review the design against the well-architected pillars.
Teams that skip step 2 pay for it later. Workloads then arrive in ad hoc accounts with their own networks and admin users. Pulling them into a governed structure afterwards becomes a migration project in its own right.
Recovery Tiers and a Failover Test
Recovery targets are easier to agree on in tiers than one workload at a time. The values below are illustrative rather than a standard, while the patterns come from the AWS disaster recovery whitepaper.
| Tier | Example workloads | Illustrative RTO | Illustrative RPO | Recovery pattern |
|---|
| Tier 1: mission-critical | Order capture, customer-facing APIs | 15 minutes | 1 minute | Warm standby or multi-site active/active |
| Tier 2: business-important | Finance reporting, the lakehouse | 4 hours | 15 minutes | Pilot light with continuous replication |
| Tier 3: internal | Dev and test, archives | 24 hours | 24 hours | Backup and restore from nightly backups |
Each step down the table trades recovery speed for a smaller standby bill, so tiers also belong in the three-year cost model. A failover test then proves the numbers:
- Before the test, pick one workload, agree a test window with its owner and note its tier targets.
- Record the last committed transaction, then take the primary zone or region out of service.
- Promote the standby and repoint DNS or the load balancer while the clock runs.
- Confirm users can sign in and the newest data matches the recorded transaction, then fail back and log the measured RTO and RPO.
Landing Zone Guardrails as Policy
A guardrail is a landing zone rule enforced as policy, so a risky deployment is blocked instead of found in an audit. On Azure, the common ones exist as built-in Azure Policy definitions, so the work is choosing values rather than writing code. Our Azure security best practices guide also covers the wider control set.
| Guardrail | Built-in Azure Policy | What it prevents |
|---|
| Region control | Allowed locations | Data landing outside approved regions |
| Approved services | Not allowed resource types | Unreviewed services reaching production |
| Instance sizes | Allowed virtual machine size SKUs | Oversized or GPU instances launched by mistake |
| Public exposure | Storage accounts should disable public network access; Network interfaces should not have public IPs | Public storage and directly exposed virtual machines |
| Ownership tags | Require a tag on resources; Inherit a tag from the resource group if missing | Spend nobody can trace to an owner |
Kanerika Service
Azure Cloud Solutions
Kanerika’s Azure team designs landing zones aligned to Microsoft best practice, with subscription architecture, role-based access and policy in place before workloads move.
Explore Azure Cloud Solutions
Who Owns the Design: The Cloud Architect Role
A cloud architect owns these decisions as well as the record of why they were made. The role turns business needs into a target design, picks services and patterns, sets standards for security and cost, and reviews changes against them.
Good architects therefore spend as much time with finance, security and application owners as with engineers. In a small company the role may be a senior engineer’s part-time job. In a larger one it often sits in a cloud center of excellence. Flexera’s 2026 cloud survey found that 71% of organizations run one. Teams that hand day-two operations to a partner can also compare the options in our guide to Azure managed services.
What Cloud Architecture Costs and Where Budgets Leak
There is no list price for an architecture, because the cost is whatever the design commits you to run. The useful question is rather what each workload will cost over three years, including the people who keep it running.
Build that model per workload, then add shared costs such as the landing zone, monitoring and support plans. Compare the total against the current on-premises cost, counting hardware refresh, data center space and the licences you would retire.
| Cost driver | What moves it | Design lever |
|---|
| Compute | Instance size, hours running, pricing model | Rightsizing, autoscaling, commitments for steady load, shutdown schedules |
| Storage | Volume, tier, replication, retention | Lifecycle rules to cooler tiers; deleting stale copies |
| Data transfer | Traffic between regions and zones, and out to the internet | Keep chatty services together; cache at the edge |
| Licences | Bring-your-own versus included, per-core rules | Check licence terms before choosing instance families |
| Support and tools | Provider support tier, monitoring and security tools | Match the tier to how critical the workload is |
| People | Skills to run IaaS versus managed services | Prefer managed services where the team is thin |
Waste is the biggest leak. Flexera’s 2026 findings put wasted cloud spend at 29%, the first increase in five years, and tied the rise to cloud AI workloads. The same research also found that 63% of organizations have established FinOps teams.
Platform consolidation is another lever that only shows up at design time. Running analytics on one governed platform, rather than several overlapping services, removes duplicate storage and duplicate pipelines from the bill.
Watch on YouTube
How Microsoft Fabric Helps Reduce Cost & Boost Data Performance: A Case Study
Kanerika’s team shows how consolidating analytics on Microsoft Fabric cut cost and lifted data performance, a design-time answer to the waste figures above.
Three Habits That Stop Budget Leaks
Three habits keep a design honest. First, tag every resource with an owner and a cost center, so every spike has a name attached. Second, set a budget with alerts for each workload, which surfaces an overrun in days rather than at month-end.
Third, review the bill monthly with the people who can change the design. Our guide to cloud cost management also covers the operating side.
The first habit works best as a written tag policy with four required keys. Owner holds an email, cost-center a finance code, environment one of prod, test or dev, and data-class a sensitivity level.
On AWS, for example, tag policies in AWS Organizations can fix the case and allowed values of a key such as CostCenter. They can also block noncompliant tagging on chosen resource types.
Cloud Architecture Mistakes That Cost the Most
The expensive mistakes are rarely exotic. They are ordinary shortcuts taken under deadline pressure, and each one has a symptom that shows up months later.
| Mistake | Symptom | Fix |
|---|
| Lift-and-shift without rightsizing | A cloud bill above the old data center cost | Rightsize from a few weeks of usage data; move steady load to commitments |
| No landing zone | Dozens of accounts, each with its own network and admins | Build the landing zone first, then migrate stray accounts into it |
| Flat network | One compromised host can reach everything | Hub-and-spoke with segmented subnets and private endpoints |
| Untagged spend | Nobody can say who owns a cost spike | Enforce tags with policy and block untagged deployments |
| Untested disaster recovery | Recovery takes far longer than the RTO on paper | Run failover drills on a schedule and record the results |
| Accidental multi-cloud | Two of everything, with nobody expert in either | Name the constraint, or consolidate |
Over-broad admin roles, public storage buckets and keys stored in code are easy to create and easy to miss in a fast build. A review against the control areas of ISO/IEC 27001, such as access, encryption and logging, catches most of them. Our guide to data security best practices also covers the controls in more depth.
Talk to Kanerika
Get Your Cloud Architecture Reviewed
Talk to Kanerika’s cloud and data team about your landing zone, network, identity model and cost model, and which of these mistakes your design is exposed to.
Schedule a Demo →
Where Cloud Architecture Is Heading in 2026
Spending keeps climbing, and that growth is also changing what a good design looks like. Synergy Research Group estimated cloud infrastructure services spending at $129 billion in the first quarter of 2026. That is an annual run rate above half a trillion dollars. Three shifts matter more than the rest for architects.
AI Workloads Reshape Compute and Cost
AI changes three design questions at once. GPU capacity is scarce and expensive, so it needs reservations, quotas and a plan for idle time. Training and retrieval also need data close to compute, which affects where the lakehouse sits.
Inference may then run in the cloud, at the edge or inside a SaaS product, depending on latency and cost. The cost risk is real, since Flexera tied the 2026 rise in wasted spend to cloud AI workloads. That matters because 81% of the organizations it surveyed use generative AI.
A planning use case such as generative AI in supply chain shows the pattern. The model is the easy part, while governed data and predictable inference cost decide whether it scales.
Sovereign Cloud and Data Residency
Data residency has moved from a legal footnote to an architecture input, especially in regulated industries. Gartner forecast in February 2026 that worldwide sovereign cloud IaaS spending will reach $80 billion in 2026, up 35.6% from 2025.
For the design, that means deciding early, before any migration, which data classes must stay in-country. It also means choosing between a provider’s sovereign region, a local provider or a private cloud. Each of those choices is hard to reverse once data has landed.
Checklist
Data Modernization Checklist
Deciding where data lives and how it moves into a governed cloud platform? Use this checklist to plan the platform, governance and migration steps before any data lands.
Get the Checklist →
Edge and Event-Driven Designs
Some workloads cannot wait for a round trip to a distant region. Plant-floor quality checks, retail checkout and connected vehicles push compute toward the edge, while the cloud handles aggregation, training and long-term storage. Event-driven designs suit this split, since devices publish events and cloud services react to them.
Decision Framework: Which Cloud Architecture Should You Build?
Every design starts from the same default and moves off it only when there is a reason. The table gives a starting design for six common scenarios, with the caution that most often derails each one.
| Scenario | Starting design | Caution |
|---|
| New customer-facing app | One public cloud, PaaS and serverless, spread across zones | Set per-service limits and budgets before launch |
| Legacy line-of-business app | Rehost on IaaS, then rightsize and modernize in stages | Plan waves and cutover before the first move |
| Regulated or residency-bound data | Hybrid or a sovereign region, with private connectivity | Map data classes to locations before any data moves |
| Analytics and AI platform | Lakehouse on one cloud, inside a governed landing zone | Put GPU and storage growth in the three-year model |
| Global low-latency service | One provider, several regions, edge caching | Replication cost and conflict handling |
| Acquired or mixed estate | Multi-cloud with one identity and one monitoring layer | Set a consolidation date, or the mix becomes permanent |
The legacy row is where most enterprises start, so it deserves a closer look. Our guide to cloud migration best practices covers the waves, testing and cutover that turn that starting design into a finished move.
If a workload fits two rows, take the more constrained design for the affected data only. A regulated customer table can sit in a sovereign region while the rest of the application stays on the default.
Choosing a Provider in 2026
Provider choice comes after the design, not before it. Synergy’s first-quarter 2026 figures show three providers well ahead of the rest.
| Provider | Share of Q1 2026 cloud infrastructure services spend |
|---|
| Amazon Web Services | 28% |
| Microsoft (Azure) | 21% |
| Google Cloud | 14% |
Together, those three hold 63% of the market. Pick the one whose managed services, regions and partner skills fit your workloads, and whose identity model your team already knows. Our AWS vs Azure vs Google Cloud comparison also covers the head-to-head detail.
Data platforms deserve a separate look, since the analytics service often ties you to a provider more tightly than compute does. Microsoft Fabric is Microsoft SaaS that runs on Azure with Entra ID sign-in, while BigQuery is a Google Cloud service. Databricks and Snowflake run on AWS, Azure and Google Cloud, so the analytics choice can lock the provider decision or leave it open.
How Kanerika Designs and Builds Cloud Architecture
Kanerika works where cloud design meets data and AI: the landing zone, the data platform and the governance that runs across both. The work moves through four stages, and each one ends with a decision the client signs off.
- Assess. Inventory workloads, data sources, costs and constraints. The stage delivers a workload register with RTO, RPO and residency needs recorded for each workload.
- Design the target. Draw the landing zone, network, identity model and data platform. The deliverable is then a target design, with decision records as well as a three-year cost model attached.
- Build in phases. Stand up the landing zone in code, then move data and reports in waves, each with its own cutover plan. FLIP, Kanerika’s migration accelerator, automates much of the data movement and pipeline conversion, so engineers spend their time on design and testing.
- Validate, govern and optimize. Run failover and cost tests, set policy and tagging, and review spend and performance after go-live. The stage hands over measured test results, the enforced policy set and a spend baseline.
Kanerika is a Microsoft Fabric Featured Partner and an Infrastructure Azure Solutions Partner, which covers the landing zone and data platform stages. It also holds the Analytics on Azure Advanced Specialization and the data warehouse migration to Azure Specialization. When the design holds regulated data, its ISO 27001, ISO 27701, SOC 2 Type II and CMMI Level 3 certifications matter as well.
Case Study: 25% Lower Storage Costs for a Steel Services Company on Azure
A North American industrial steel mill services provider with a 96-year history ran on a legacy system. It offered limited encryption options, made data processing expensive and was inefficient for real-time analysis.
Kanerika organized the company’s Dynamics AX data on Azure and stored it in Azure Data Lake behind multi-factor authentication, with Power BI dashboards on top.
| Result | Change |
|---|
| Storage expenses | 25% lower |
| Productivity | 40% higher |
| Revenue | 2.5% higher |
One design decision, in particular, did most of the cost work. The legacy system demanded significant processing power and was highly priced, so Kanerika moved storage to Microsoft’s pay-as-you-go model. The case study credits that model with optimizing storage expenses, while the identity controls on the data lake were also set up front. You can read the full story in the steel services cloud integration case study.
Kanerika Service
Data Architecture Services
Kanerika designs the data side of your cloud architecture, from landing zone and lakehouse to the semantic layer and governance, so analytics and AI scale on one platform.
Explore Data Architecture Services
What to Settle Before You Build
A cloud design is cheapest to change while it is still on paper. The opening’s manufacturer would write down one public cloud, plus a hybrid link to the ERP for its last 18 months on-premises. Its lakehouse runs on managed PaaS behind one landing zone and identity provider. Its wider cloud transformation strategy then sets the roadmap around that design.
Each data class gets its own RTO and RPO, and the three-year cost model counts plant-to-cloud data transfer. Before you approve your own build, get the same five answers in writing:
- Deployment model, plus the named constraint behind it if it is not one public cloud.
- Service model for each workload.
- Landing zone and identity design.
- Where each data class lives, with its RTO and RPO.
- A three-year cost model per workload, including people and data transfer.
Start from one public cloud on managed services. Move to hybrid or multi-cloud only when residency, latency, an estate you must keep or a provider-specific service forces it. So what should you know before you build a cloud architecture? Five decisions settled in writing, one sensible default and a failover and cost test that proves the design before go-live.
Frequently Asked Questions
What do you mean by cloud architecture?
Cloud architecture is the design that decides how compute, storage, networking, identity and data services connect to run an organization’s workloads in the cloud. It covers which services run where, how they talk to each other, who can reach them and how they recover from failure. It also records the reasons behind each of those choices.
What is an example of cloud architecture?
A common example is an enterprise data platform on one public cloud. A landing zone sets up accounts, the network and identity. Pipelines bring in ERP and plant data, a lakehouse stores it in raw, cleaned and curated zones, and a semantic layer feeds Power BI dashboards and AI models, with governance running across every layer.
What is a cloud landing zone?
A cloud landing zone is the prepared foundation that workloads land in. It includes the account or subscription structure, the hub network, guardrail policies, logging and one identity provider with role-based access. Building it before the first workload arrives prevents a sprawl of ad hoc accounts that is expensive and slow to consolidate later on.
How much does cloud architecture cost?
There is no fixed price, because cost depends on what the design commits you to run. Build a three-year model per workload covering compute, storage, data transfer, licences, support and people, then add shared costs such as the landing zone and monitoring. Compare that total with current on-premises costs, including hardware refresh and space.
How do you design a cloud architecture step by step?
Start by capturing requirements and recovery targets for each workload. Then build the landing zone and identity model, place workloads and map data flows, and write the infrastructure as code. Plan observability and disaster recovery next. Finally, validate with load, failover and cost tests and review the design against the well-architected pillars before go-live.
What is the difference between cloud architecture and cloud infrastructure?
Cloud architecture is the design, while cloud infrastructure is what actually gets deployed. The architecture decides which services to use, how they connect and why, and records that in diagrams and decision records. The infrastructure is the running servers, networks, storage and managed services that the design describes, usually built from code.
How does cloud architecture support AI workloads?
AI workloads need three things from the architecture. They need GPU capacity with reservations and quotas, governed data stored close to the compute that trains or queries it, and an inference placement that balances latency and cost. A cost model matters too, since Flexera linked the 2026 rise in wasted cloud spend to AI workloads.
Which are the three main components of a cloud architecture?
The three main components are the front end, the back end and the network. The front end is what users touch, such as web apps, mobile apps and APIs. The back end holds compute, storage, databases and application logic. The network connects them through virtual networks, gateways, private links and the internet edge.
What are the four layers of cloud architecture in cloud computing?
The four layers are hardware, virtualization, application and services. Hardware is the provider’s data centers, servers and network gear. Virtualization pools that hardware into virtual machines, containers and storage. The application layer runs your workloads, and the service layer exposes everything as IaaS, PaaS or SaaS, with metering so you pay for actual use.
What are the four types of cloud architecture?
The four types usually meant are public, private, hybrid and multi-cloud. Public cloud runs on shared provider infrastructure, while private cloud is dedicated to one organization. Hybrid combines on-premises or private systems with public cloud, and multi-cloud uses more than one public provider. NIST’s own list names community cloud as the fourth model instead of multi-cloud.
What are the four types of cloud services?
The four types are infrastructure as a service (IaaS), platform as a service (PaaS), software as a service (SaaS) and serverless computing. With IaaS you run everything from the operating system up. PaaS leaves you code and data. SaaS is a finished application, and serverless runs your functions on demand, billed per request or per second.
What are the five pillars of cloud architecture?
The five pillars usually quoted come from the Azure Well-Architected Framework: reliability, security, cost optimization, operational excellence and performance efficiency. AWS uses the same five plus sustainability, for six pillars. Google Cloud lists six focus areas covering similar ground. Teams use these pillars as a checklist for design reviews and reviews before go-live.
What is a cloud architecture pattern?
A cloud architecture pattern is a proven layout for a recurring problem. Common patterns include n-tier apps, microservices, event-driven designs, serverless functions, hub-and-spoke networks and lakehouse analytics platforms. Each one fits a different workload shape, so a steady internal app, a spiky customer API and a nightly data pipeline usually need different patterns.
What does a cloud architect do?
A cloud architect turns business needs into a target cloud design. The role picks services and patterns, sets standards for security, reliability and cost, and reviews changes against them. Architects work closely with finance, security and application owners, and in larger companies they often sit in a cloud center of excellence that sets shared standards.
What is the difference between hybrid cloud and multi-cloud?
Hybrid cloud connects on-premises or private infrastructure with at least one public cloud, so some systems stay in your data center while others move. Multi-cloud uses two or more public providers, such as AWS and Azure. An estate can be both at once, and either choice adds complexity that should be justified by a named constraint.




