TL;DR
Databricks performance optimization works when you measure first and fix data layout before adding compute. Start with the query profile, which shows where the time goes. Store new tables with liquid clustering, and do not partition tables under 1 TB. Let Databricks clean up managed tables for you, and schedule cleanup for external tables. Fix slow joins from the query plan, then size compute by how long jobs run and wait. Test every change on the same data, one change at a time.
Key Takeaways
- Measure before you tune: the query profile, Spark UI and query history show whether time goes to reading, shuffling, spilling or queuing.
- Data layout is the biggest lever, especially for slow scans, and Databricks recommends liquid clustering for all new tables.
- Do not partition tables under 1 TB; partitioning helps only above 100 TB, and even then Databricks says to try liquid clustering first.
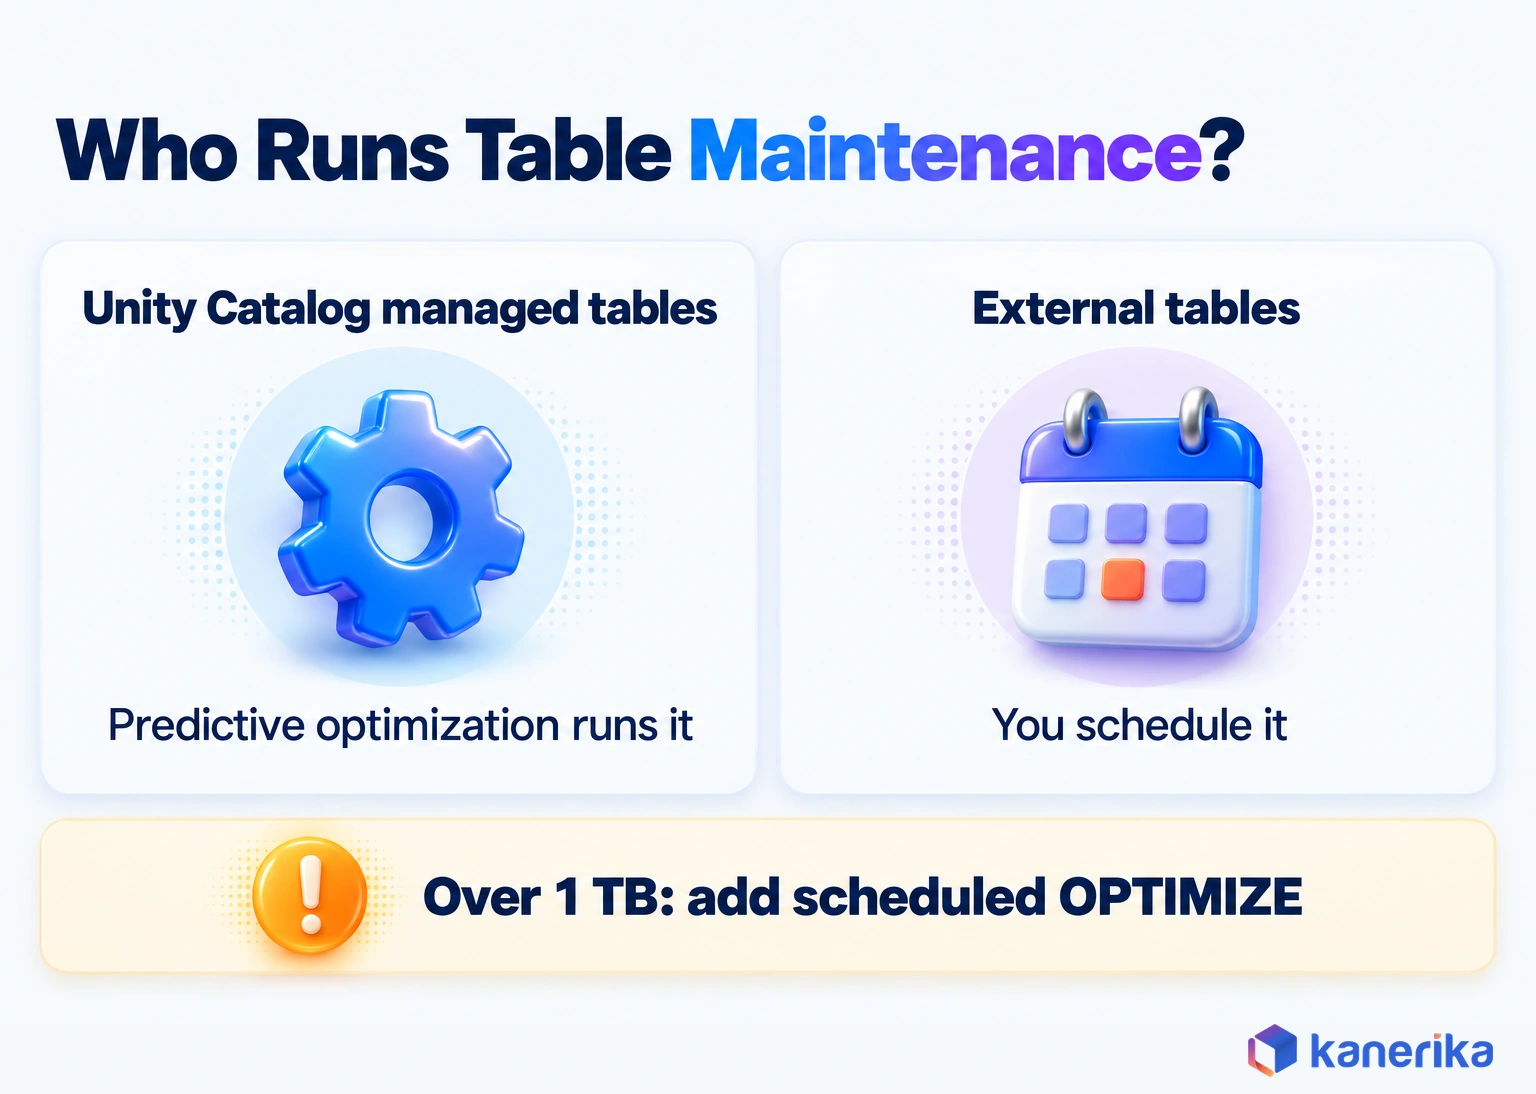
- Predictive optimization runs OPTIMIZE, VACUUM and ANALYZE on Unity Catalog managed tables, while external tables still need scheduled jobs.
- Adaptive query execution and Photon are on by default, so check the plan before changing settings, and keep UDFs off hot paths.
- Judge compute by runtime and queue time, and then prove each change with a one-variable benchmark.
Why a 20-Minute Job Becomes a 90-Minute Job
Picture a nightly sales job that finished in 20 minutes on the day it went live. Eighteen months later it runs for 90, and the morning dashboards load late, though nobody touched the code.
The tables grew. Every small daily write added more small files, until a filter that once skipped most of the table opened almost all of it.
The on-call engineer doubles the cluster. That makes the job a little faster, but the compute bill roughly doubles with it, because compute was never the bottleneck. The job was reading far more files than it needed, then shuffling them across the network. Query tuning is one part of wider Databricks best practices, which also cover governance, CI/CD and cost.
Databricks performance optimization is mostly about making a job do less work, and only then about doing that work faster. The sections below follow that order: diagnose, fix layout, keep tables healthy, tune queries, size compute, then prove the gain.
What Databricks Performance Optimization Covers in 2026
Databricks performance optimization is the work of making jobs and queries finish faster on the same data, with fewer surprises. It is not one setting, and it sits on top of the wider Databricks Data Intelligence Platform. Databricks’ own optimization guide names four root causes of slow workloads. They are reading more data than needed, shuffling data between nodes, a poor query plan, and rewriting unchanged files.
Each cause also maps to a layer you can work on. Think of them as four floors of one building. A problem on a lower floor also shows up as noise on every floor above it.
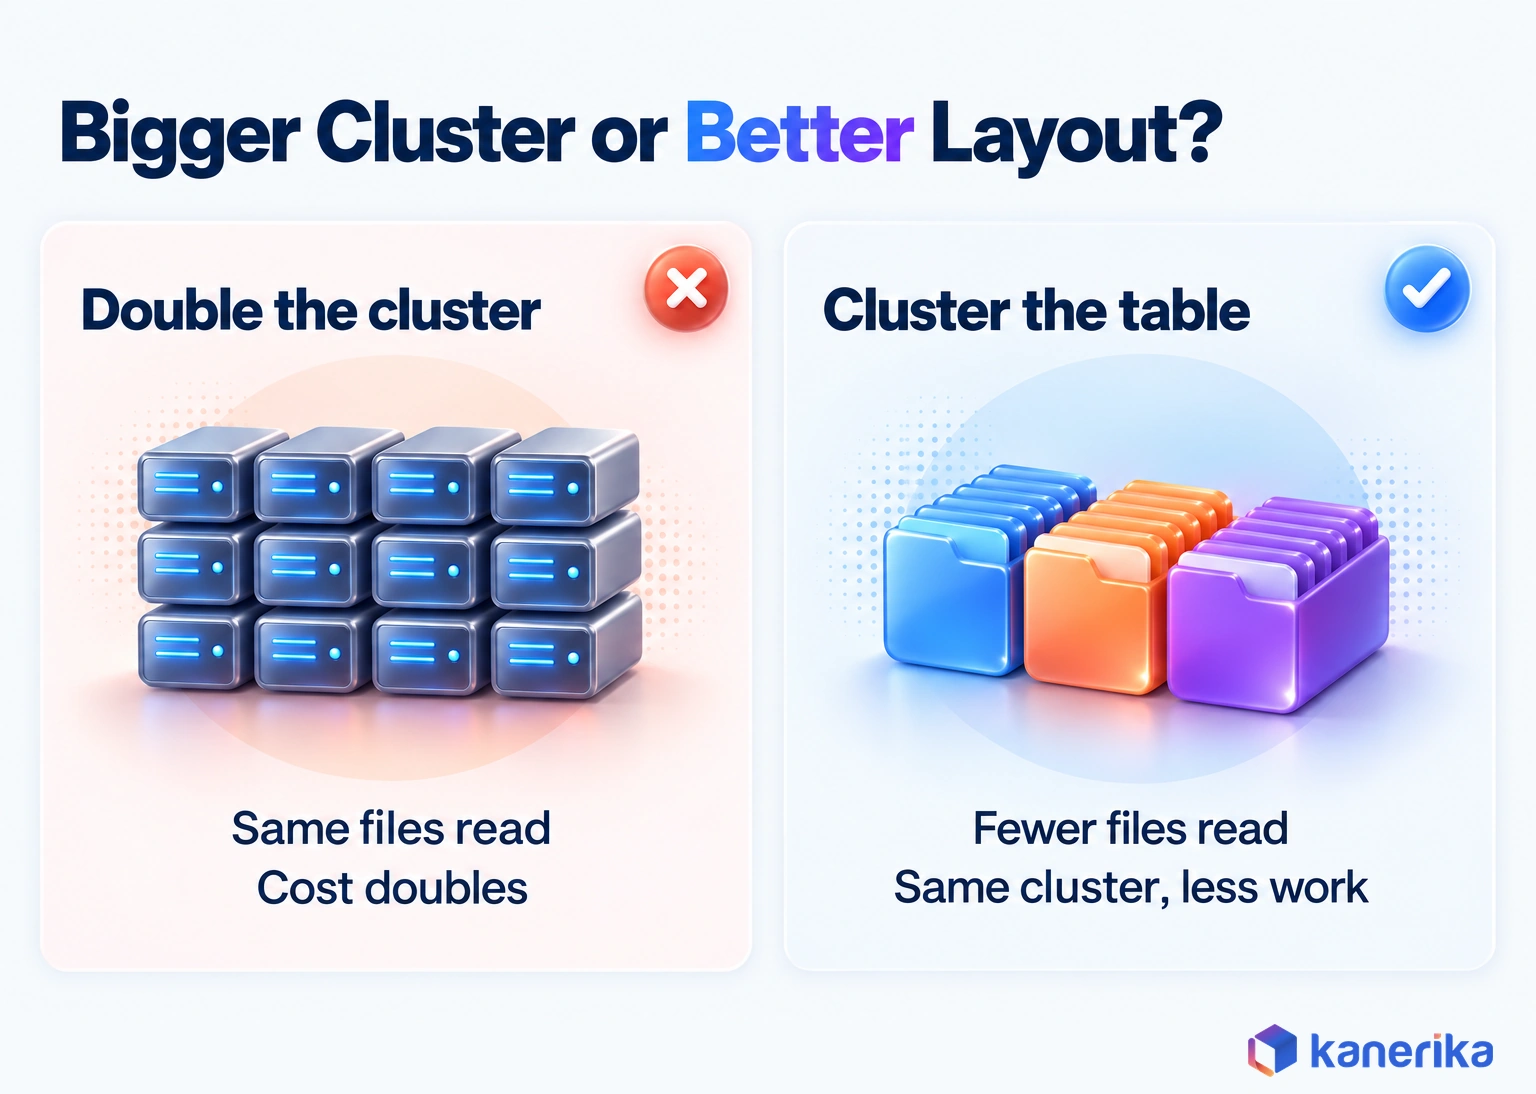
Data layout decides how many files a query has to open. Delta Lake records the minimum and maximum value of each column for every file. When rows with similar values sit together, the engine reads those statistics and skips whole files that cannot match the filter. The storage design behind this is covered in our guide to Databricks lakehouse architecture, and the wider trade-offs in data lake vs lakehouse.
Table maintenance keeps that layout healthy over time. Because writes leave behind small files, old file versions and stale statistics, each one slows the next read a little.
The query engine turns SQL or DataFrame code into a physical plan. Spark chooses join strategies, decides how many partitions to shuffle into, and hands work to Photon, Databricks’ vectorized engine, when the operators allow it.
Compute is the hardware that runs the plan. Instance type, cluster size, autoscaling and serverless start-up time all change how long work waits and how fast it runs once it starts.
What Changed Since the Old Playbook
Much of the Databricks tuning advice still in circulation predates the defaults described in the Databricks documentation. The table below shows which older habits have a better replacement, so you can check your own setup against it.
| Area | Older advice | Databricks documentation guidance |
|---|---|---|
| Data layout | Partition by date, then add Z-Order | Liquid clustering for all new tables, generally available for Delta on Databricks Runtime 15.4 LTS and above |
| Maintenance | Nightly OPTIMIZE and VACUUM on every table | Predictive optimization on Unity Catalog managed tables; scheduled jobs only where it does not apply |
| Engine | Turn Photon on cluster by cluster | Photon is on for serverless and SQL warehouses and on by default for classic compute |
| Caching | “Delta cache” or “DBIO cache” | The same feature, renamed disk cache |
| Monitoring | Ganglia metrics | The native compute metrics UI, with under one minute of delay |
None of these changes make tuning optional. They move the starting point, though, so check which defaults your workspace already uses before copying a fix from an older guide.
How to Diagnose a Slow Databricks Job or Query
Diagnosis means finding where the time goes before you change a single setting. For example, a dashboard query that takes 40 seconds could be scanning a whole table, waiting for a busy warehouse, or spilling to disk. Each cause needs a different fix.
Guessing is expensive because the obvious fix is often the wrong one. Five steps give you the evidence instead.
- Rank the workload. Use query history to find the slowest and most frequent statements. A query that runs 2,000 times a day at 8 seconds matters more than one monthly report.
- Open the query profile. The query profile shows the share of data pruned, time spent on scheduling, optimization and execution, and aggregated task time.
- Read the Spark UI for jobs. Look for the longest stage, its shuffle read and write sizes, any spill, and the gap between median and maximum task time.
- Check compute metrics. The native compute metrics UI covers all-purpose and jobs compute in near real time, so you can see whether CPU, memory or network is saturated.
- Record a baseline. Write down runtime, bytes read, shuffle bytes and spill before touching anything, or you will not be able to prove a gain later.
For SQL warehouses and serverless compute, the system.query.history table keeps 365 days of statements. A short query like the one below gives you a ranked starting list.
-- Slowest finished statements in the last 7 days
SELECT statement_text,
       total_duration_ms,
       waiting_at_capacity_duration_ms,
       read_bytes,
       produced_rows,
       spilled_local_bytes,
       shuffle_read_bytes
FROM system.query.history
WHERE start_time >= current_date() - INTERVAL 7 DAYS
  AND execution_status = 'FINISHED'
ORDER BY total_duration_ms DESC
LIMIT 20;
Two columns are especially telling on their own. A high waiting_at_capacity_duration_ms means the query sat in a queue, which is a compute problem. A high read_bytes against a small produced_rows means the query read far more than it returned, which is a layout problem.
Symptom-to-Fix Triage Table
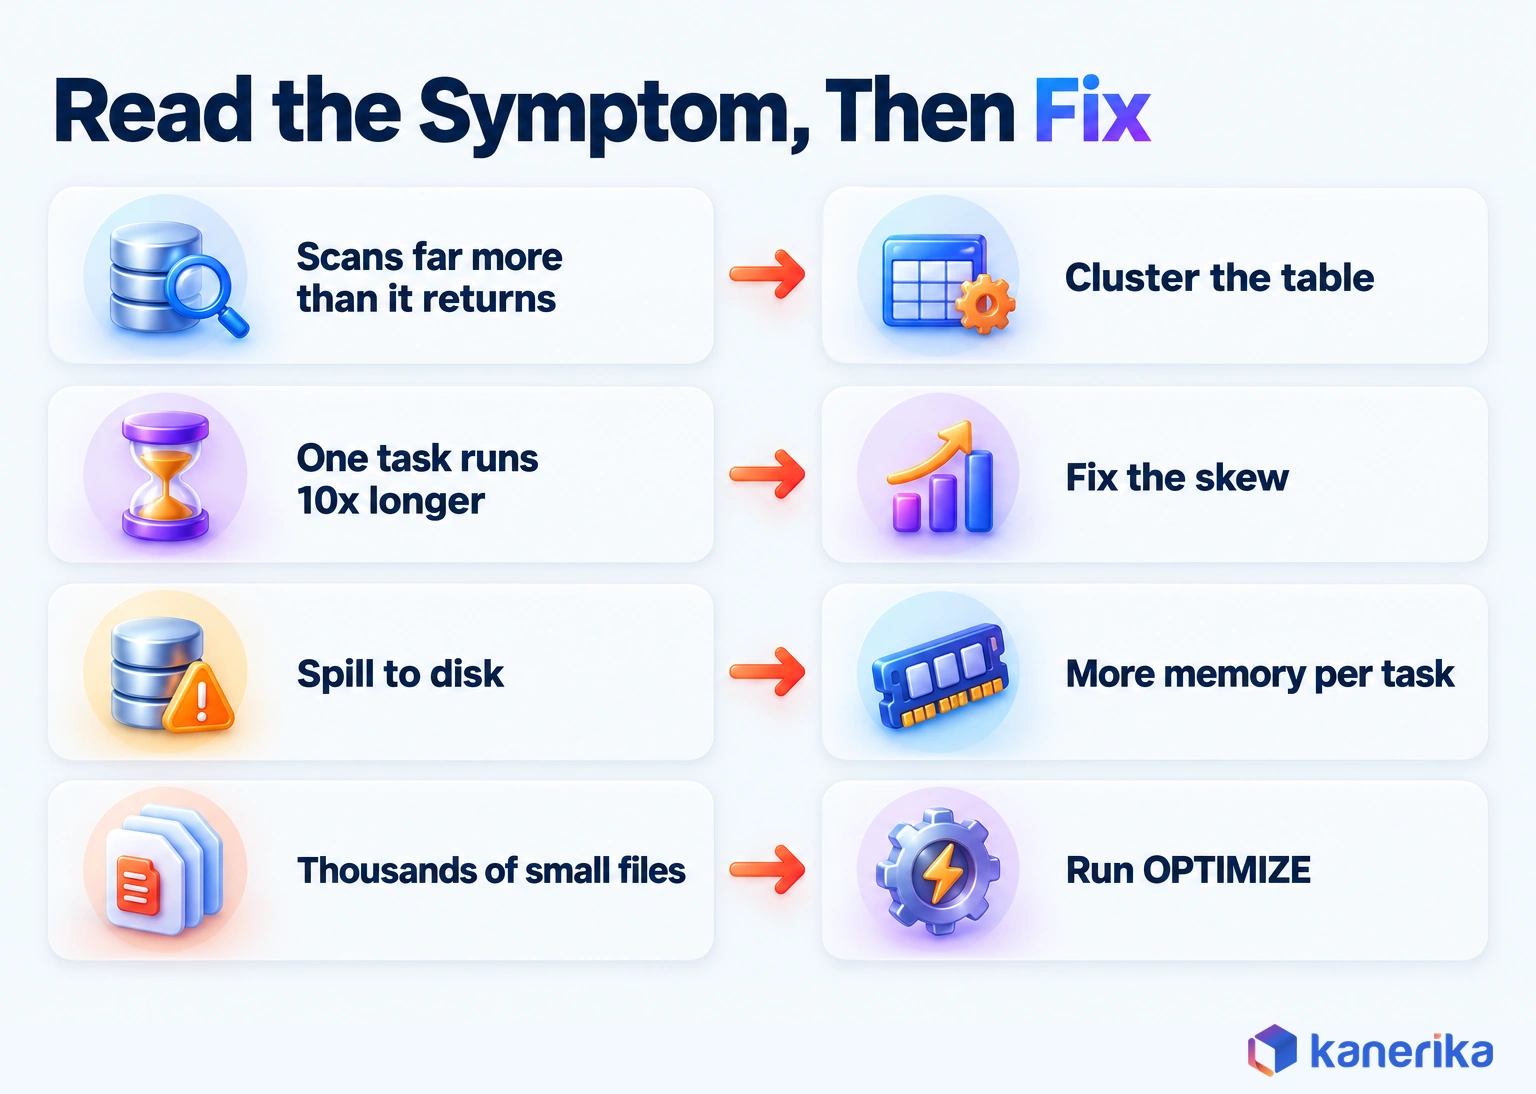
Once you know where the time goes, the first fix usually follows. This table maps the symptoms you will see most often to their likely cause.
| Symptom | Where you see it | Likely cause | First fix |
|---|---|---|---|
| Scans far more data than it returns | Query profile, low pruning share | Poor data layout | Liquid clustering on the filter columns |
| Long shuffle stage | Spark UI stage detail | Wide joins or aggregations | Broadcast the small side, filter earlier |
| Spill to disk | Spark UI, query profile | Too little memory per task | More shuffle partitions or memory-optimized nodes |
| One task runs 10x longer than the rest | Spark UI task summary | Data skew on a join or group key | Confirm AQE skew handling, then salt the key |
| Thousands of small files | Table detail, file count | Frequent small writes | OPTIMIZE or auto compaction |
| Queries queue at peak hours | Query history wait time | Not enough concurrent compute | Scale the warehouse out or move to serverless |
| Slow MERGE | Job runtime, files rewritten | Join on unclustered keys | Cluster on the merge key, narrow the match condition |
Use the table to pick a first suspect rather than to close the case. A slow MERGE can also be a skew problem, so confirm the cause in the profile before you apply the fix.
Data Layout: Liquid Clustering vs Z-Order vs Partitioning
Data layout decides how much of a table a query has to read, which makes it the biggest lever for most slow scans. If a dashboard filters on one customer and the rows for that customer are spread across every file, the engine has to open every file.
Clustering fixes that problem because it keeps rows with similar key values in the same files. The per-file statistics then show which files can be skipped, so a filter on one customer reads a handful of files instead of thousands.
Databricks gives a clear size rule in its partitioning guidance. Do not partition tables under 1 TB. Use liquid clustering for tables between 1 TB and 100 TB. Above 100 TB, partitioning might help.
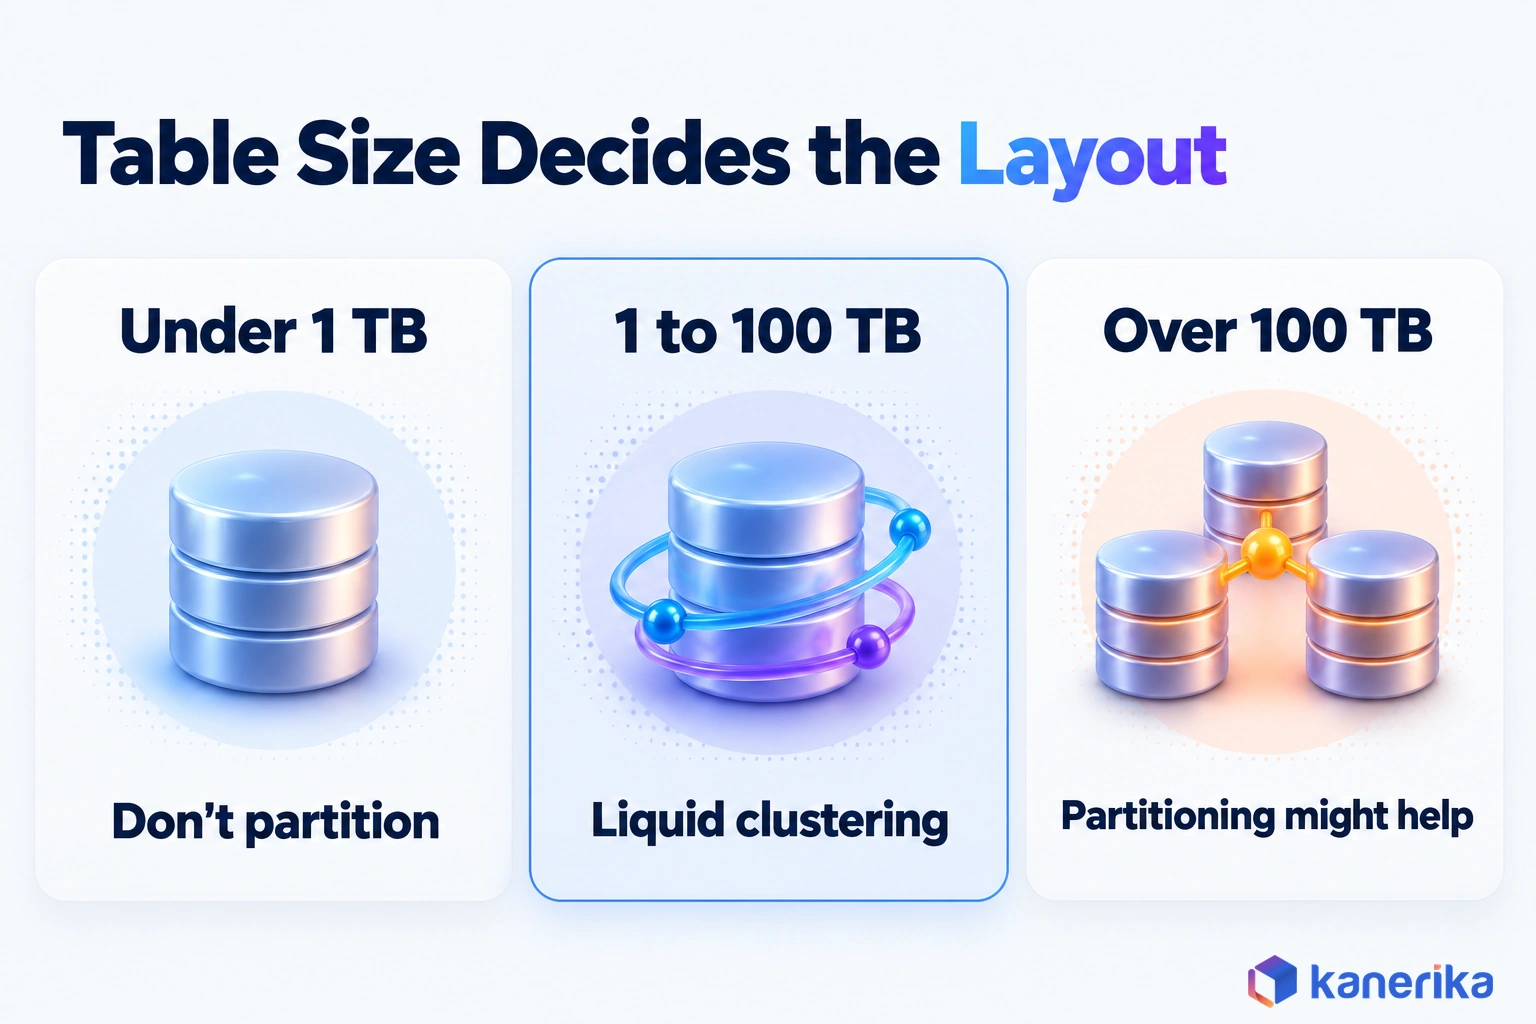
That rule also turns an old default upside down. Many teams still partition by date on every table, which creates thousands of tiny folders on small tables and makes reads slower, not faster.
How Liquid Clustering Works in Practice
Liquid clustering replaces both partitioning and Z-Order. Databricks recommends it for all new tables, including streaming tables and materialized views. It is generally available for Delta tables on Databricks Runtime 15.4 LTS and above, and in Public Preview for Iceberg on 16.4 LTS and above.
-- New table: cluster on the columns queries filter by
CREATE TABLE sales.orders (
  order_id    BIGINT,
  customer_id BIGINT,
  order_date  DATE,
  amount      DECIMAL(18,2)
)
CLUSTER BY (customer_id, order_date);

-- Query patterns keep shifting: let Databricks pick the keys
ALTER TABLE sales.orders CLUSTER BY AUTO;
Choose clustering keys from the columns that appear most in filters and join conditions, rather than from the columns that look important. When usage changes often, CLUSTER BY AUTO lets Databricks choose and adjust the keys from observed query patterns.
Existing partitioned tables do not need a rebuild from scratch. On Databricks Runtime 18.1 and above, ALTER TABLE ... REPLACE PARTITIONED BY WITH CLUSTER BY moves a large legacy table to clustering in place. Run OPTIMIZE afterwards, since the docs say the new clustering columns only pay off once it runs. Teams on 15.x or 16.x runtimes need to upgrade before they can use the command.
| Table situation | Layout choice | Why |
|---|---|---|
| New table of any size | Liquid clustering | Databricks’ recommendation for all new tables |
| Under 1 TB, partitioned by habit | Remove partitions, cluster instead | Small partitions mean many tiny files |
| 1 TB to 100 TB | Liquid clustering | Data skipping without partition maintenance |
| Over 100 TB with one dominant filter | Partitioning might help | The only band where Databricks still sees a case |
| Already Z-Ordered | Move to liquid clustering, do not combine them | Clustering replaces Z-Order rather than layering on it |
Layout changes also give the biggest wins on tables that are read far more often than they are written. Start with the two or three tables behind your slowest dashboards, since that is where skipped files turn straight into faster answers.
Talk to Kanerika
Want a Second Opinion on Your Table Layout?
Kanerika reviews your slowest Databricks tables and queries, recommends clustering keys and maintenance settings, and benchmarks each change before rollout.
Schedule a Demo →Table Maintenance: OPTIMIZE, VACUUM, ANALYZE and Predictive Optimization
Tables slow down as they age, because every write leaves new small files, old file versions and stale statistics behind. Maintenance is the routine work that undoes that drift before users notice it.
In practice, three commands do most of the work. Each one fixes a different kind of decay, so running one of them does not replace the others.
| Command | What it fixes | Who runs it |
|---|---|---|
| OPTIMIZE | Compacts small files into larger ones and applies clustering | Predictive optimization on managed tables; a scheduled job on external tables |
| VACUUM | Removes data files no longer referenced by the table, after a 7-day default retention | Same split |
| ANALYZE | Refreshes statistics the planner uses to pick join strategies | Same split |
Bin-packing OPTIMIZE is idempotent, so a second run on unchanged data has no effect. That makes it safe to schedule, though not free to run on tables that never change. VACUUM keeps 7 days of history by default, which also sets how far back time travel can reach after it runs.
Predictive optimization runs OPTIMIZE, VACUUM and ANALYZE automatically on Unity Catalog managed tables, both Delta and Iceberg. It is on by default for accounts created on or after November 11, 2024. Databricks planned to finish enabling older accounts by August 2026, so confirm it is on for your catalogs. Azure users will find the same rules in the Azure Databricks documentation.
Scheduling Maintenance for External Tables
External tables sit outside that service, so they still need scheduled maintenance jobs. Converting them to managed tables brings them into scope, and our Unity Catalog migration guide covers that move. Until then, a simple weekly job covers most of them.
-- Weekly maintenance for an external table
OPTIMIZE ext.clickstream_events;

-- Keeps the default 7 days of history
VACUUM ext.clickstream_events;

-- Fresh statistics for the query planner
ANALYZE TABLE ext.clickstream_events COMPUTE STATISTICS FOR ALL COLUMNS;
Size changes the advice too. For tables over 1 TB, Databricks recommends a scheduled OPTIMIZE even with other compaction turned on. Those features are not a full replacement for it.
Optimized Writes and Auto Compaction for Streaming and MERGE-Heavy Tables
Streaming sinks and change-data tables write small batches all day, so they create small files faster than a nightly job can clean them up. Two write-time features handle that problem as the data lands.
Optimized writes shape files to a better size during the write itself. Auto compaction then merges small files right after a write finishes. According to the file size tuning guide, both are always enabled for MERGE, UPDATE and DELETE operations, and they cannot be turned off there.
For Unity Catalog managed tables, Databricks also tunes target file sizes automatically. That is why older advice to hand-set a file size target rarely helps on managed tables.
Query and Spark Tuning: AQE, Joins, Shuffle, Skew and Spill
Once the layout is right, the remaining time usually sits in how Spark plans the work and moves data between nodes. A join between a large fact table and a small lookup table is the classic case. If Spark shuffles both sides, the job spends most of its time on the network.
Start with the plan Spark actually ran. Adaptive query execution (AQE) is enabled by default on Databricks. It adjusts post-shuffle partition counts, switches join strategies and splits skewed joins at runtime, using what it learns as stages finish.
AQE has also been on by default in open-source Apache Spark since version 3.2.0, as the Spark SQL performance tuning guide notes. So the question is rarely whether to enable it. Instead, the question is whether it changed the plan, which the final plan in the Spark UI SQL tab shows. Databricks advises changing AQE settings only when the defaults clearly do not fit.
Joins, Shuffle and Filtering
Joins, shuffles and filters are one problem seen from three sides. The more rows that reach a join, the more data Spark has to move between nodes, so most fixes here cut what reaches the shuffle.
Joins. Spark broadcasts a table to every node when it is below spark.sql.autoBroadcastJoinThreshold, which defaults to 10 MB. A broadcast avoids shuffling the large side. When a lookup table is a little larger but still small, a hint makes the choice explicit.
-- Broadcast the small region table instead of shuffling orders
SELECT /*+ BROADCAST(r) */
       r.region_name,
       SUM(o.amount) AS revenue
FROM sales.orders o
JOIN ref.regions r
  ON o.region_id = r.region_id
WHERE o.order_date >= '2026-01-01'
GROUP BY r.region_name;
Less data in, less data moved. Filter as early as possible, select only the columns you need, and pre-aggregate before a join when the detail rows are not used. Each step shrinks what every later stage has to shuffle.
Skew, Spill and Row Explosion
All three problems come down to some tasks doing far more work than the plan expected. The Spark UI shows it as a few tasks still running when their neighbors have finished.
Skew. When one key holds far more rows than the rest, one task does most of the work while the others wait. AQE splits many skewed joins on its own. When it cannot, add a random salt to the hot key on both sides, then aggregate the salted results back together.
Spill. Spill means a task ran out of memory and wrote intermediate data to local disk. More shuffle partitions make each task smaller, and memory-optimized instances give each task more room. Fix the cause before adding memory, though, because spill often follows skew.
Row explosion. An explode() on a large array can multiply rows from millions into billions without warning. A many-to-many join on a key that is not unique does the same. Check row counts before and after each join in the profile, and deduplicate join keys first.
Statistics. The planner picks joins from table statistics, the same ones the ANALYZE row in the maintenance table keeps fresh. Stale statistics can turn a cheap broadcast into a full shuffle, so run ANALYZE after large loads where predictive optimization does not already do it.
| Problem | Setting or pattern to check |
|---|---|
| Small table shuffled in a join | Broadcast threshold, BROADCAST hint, fresh statistics |
| Too many tiny shuffle partitions | AQE partition coalescing, enabled by default |
| One straggler task | AQE skew join handling, then key salting |
| Spill to disk | Shuffle partition count, memory per core |
| Rows multiply after a join | Join key uniqueness, explode() placement |
Photon: Where It Speeds Things Up and Where It Falls Back
Photon is Databricks’ vectorized query engine, written to run SQL and DataFrame operations faster than the standard Spark engine. Per the Photon documentation, it is on for serverless compute, SQL warehouses and serverless Lakeflow pipelines. It is on by default for classic all-purpose and jobs compute.
Photon still does not speed up everything. Knowing where it falls back saves hours of wondering why a job did not get faster.
- It does not run user-defined functions (UDFs), RDD APIs or Dataset APIs.
- For streaming, it supports stateless workloads only.
- Queries that already finish in under two seconds see no gain.
- Unsupported work falls back to Spark transparently, and results stay correct.
That fallback is silent, which is the catch. A Python UDF on a hot path can push the whole stage back to standard Spark. The fix is to replace UDFs with built-in functions where you can.
Kanerika Service
Databricks Consulting and Implementation
Kanerika designs, builds and tunes Databricks lakehouses, from data layout and table maintenance to Spark jobs and the monitoring that keeps them fast as data grows.
Explore Databricks ServicesDisk Cache vs Spark Cache
Caching sounds like a free speed-up, but the two caches on Databricks do different jobs. The disk cache, formerly called the Delta cache or DBIO cache, keeps copies of remote Parquet and Delta files on local storage. Databricks recommends it over Spark cache for repeated reads of those files.
Spark cache, called with .cache() or CACHE TABLE, holds a computed result in memory. Use it only for an intermediate result that the same job reads several times. Caching every DataFrame takes memory away from joins and can cause the very spill you were trying to avoid.
Compute Sizing for Speed: Instance Types, Autoscaling and Serverless
Compute is the last layer to tune, and the right test for it is runtime and queue time, not node count. Suppose a cluster doubles in size but runtime falls by only 10%. Each run then costs about 1.8 times as much (2 x 0.9), assuming cost tracks nodes times hours. Cloud waste of this kind is common. In the Flexera 2026 State of the Cloud Report, 753 respondents estimated that 29% of their IaaS and PaaS spend is wasted.
Next, match the instance family to what the profile shows. Memory-heavy jobs with spill want memory-optimized nodes. Shuffle-heavy jobs want fewer, larger nodes with strong network throughput, so less data crosses machines. Scan-heavy jobs on clustered tables usually benefit more from Photon and the disk cache than from extra workers.
| Workload | Symptom in the profile | Compute choice |
|---|---|---|
| Large joins and aggregations | Spill, long shuffle stages | Memory-optimized instances, fewer larger nodes |
| Scan-heavy BI queries | High bytes read, short shuffle | SQL warehouse with Photon, disk cache on |
| Spiky ad-hoc notebooks | Idle clusters, slow first query | Autoscaling or serverless |
| Steady nightly batch with a fixed SLA | Predictable runtime | Fixed-size jobs compute |
| Dashboards that queue at peak | High wait time in query history | Scale the warehouse out for concurrency |
Autoscaling suits spiky work, especially where the load swings and idle nodes would otherwise sit unused. A fixed size suits a steady job with a hard deadline, because scaling up mid-run adds delay. Serverless compute speeds start-up and scaling and minimizes idle time, which matters most for short jobs and interactive queries.
This post covers compute from the speed side only. For DBU budgets, cluster policies and spot instances, see our guide to Databricks cost optimization. If you also run Microsoft analytics tools, our Microsoft Fabric vs Databricks comparison shows which workloads suit each platform.
Kanerika Service
Data Engineering Services
Kanerika builds and runs batch and streaming pipelines with incremental loads, compaction and monitoring designed in, so jobs keep pace as volumes grow.
Explore ServicesStreaming and Incremental Workloads
Streaming and incremental jobs fail in a different way from batch jobs: they rarely crash, they just fall behind. A pipeline that processes each file in two minutes looks healthy until files arrive every ninety seconds.
Auto Loader is the Databricks tool for incremental data ingestion from cloud storage. Each run reads only the files that arrived since the last one. That keeps run time tied to the volume of new data rather than the size of the whole landing folder.
The trigger interval is the main trade-off. A shorter interval lowers latency, but every micro-batch writes its own small files and pays its own scheduling overhead. A longer interval writes fewer, larger files and uses compute more efficiently. Pick the slowest interval the business can accept, then let auto compaction tidy the sink tables.
Keep the Photon limit in mind as well. Photon only accelerates stateless streaming, so aggregations with state, such as windowed counts, run on the standard engine. For the design side of these flows, our guide to data pipelines covers batch, change data capture and streaming choices. Our piece on data pipeline architecture also shows how those stages fit together.
Spotting Stream Lag and Capping Auto Loader Batches
A stream that falls behind shows it in its backlog well before anyone notices late data. Auto Loader reports numFilesOutstanding and numBytesOutstanding at every batch, in the Raw Data tab of the streaming query progress dashboard. A backlog that grows run after run means the trigger or the compute cannot keep pace.
Many pipelines do not need second-level latency at all. For those, trigger(availableNow=True) processes everything that has landed and then stops, and it is the trigger Databricks recommends on serverless notebooks and jobs. A soft cap such as cloudFiles.maxBytesPerTrigger keeps a large backfill from turning into one huge micro-batch.
# Incremental batch: load what has landed, then stop
(spark.readStream.format("cloudFiles")
    .option("cloudFiles.format", "json")
    .option("cloudFiles.maxBytesPerTrigger", "10g")
    .load("s3://landing/orders/")
  .writeStream
    .option("checkpointLocation", "s3://checkpoints/orders/")
    .trigger(availableNow=True)
    .toTable("bronze.orders"))
The sink here is a bronze table, the raw landing layer of a medallion architecture, which keeps raw files apart from the cleaned tables dashboards read. If a stream must run continuously, the Auto Loader production guide warns that continuous triggers are especially expensive in directory listing mode. It points those streams to file events or file notification mode instead.
How to Measure Improvement: Benchmarks, KPIs and System Tables
An optimization only counts if you can show the before and after on the same work. Without a clean benchmark, a faster run might just reflect a quieter cluster or a warmer cache.
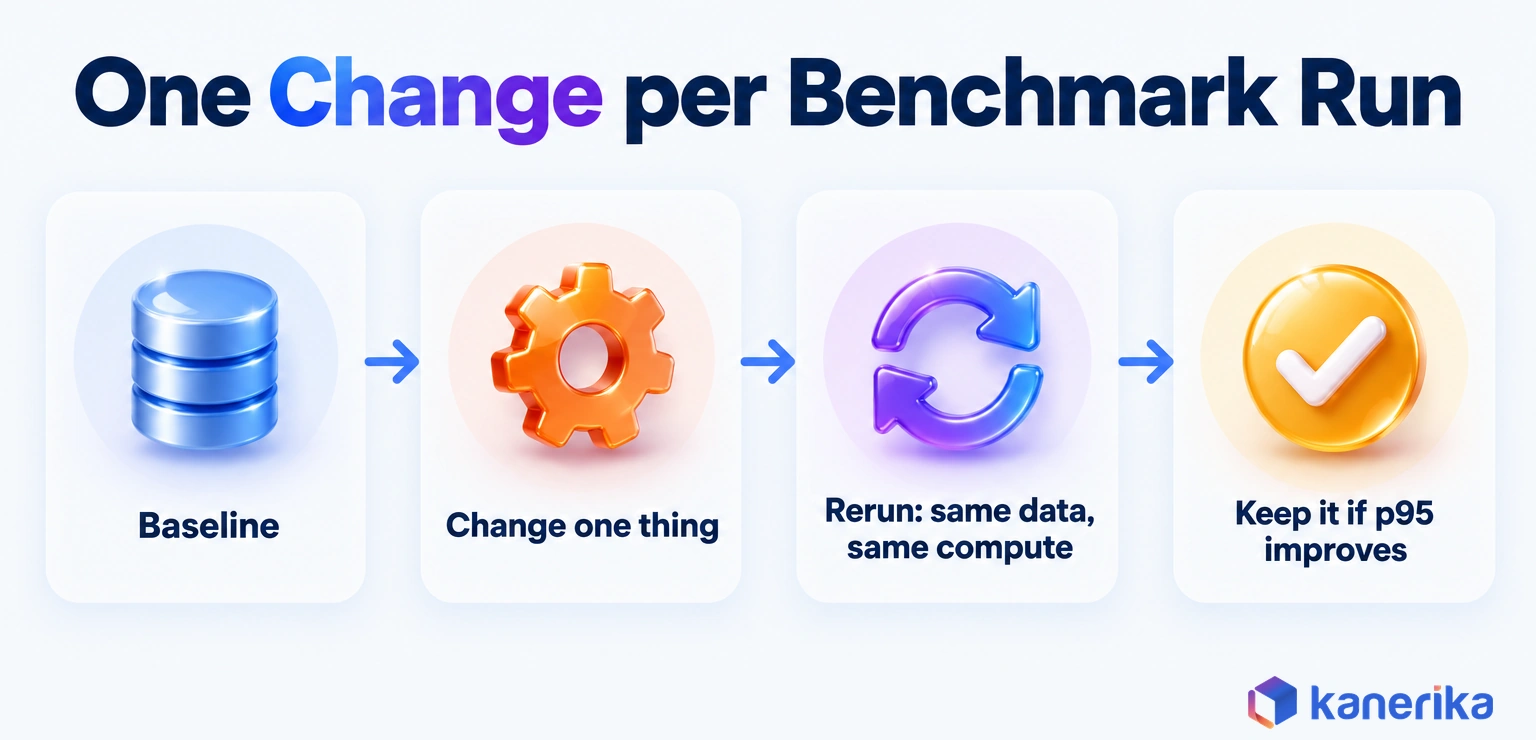
A simple protocol keeps the comparison fair:
- Use the same data, the same compute type and size, and the same time window.
- Run each test cold and warm, and report both, because the disk cache changes repeat runs.
- Change one variable per run, such as clustering keys or a join hint.
- Repeat each test several times and compare the middle result, not the best one.
- Keep the change only if the KPI moved and results are unchanged.
The KPIs That Prove a Gain
Six numbers cover most workloads, and each one also comes from a source you already have.
| KPI | What it tells you | Where to get it |
|---|---|---|
| p95 query latency | What users actually feel | system.query.history |
| Job duration | Whether the SLA holds | Jobs run history |
| Bytes read vs rows returned | How well data skipping works | Query profile, query history |
| Shuffle bytes and spill | How much data moves and overflows | Spark UI, query history |
| Queue time | Whether compute keeps up with demand | Query history wait columns |
| Cost per successful run | Whether speed came at a fair price | system.billing.usage |
Both system tables also keep 365 days of history, which is enough to compare a tuned job against its own record from months earlier. Put the KPIs on one dashboard and alert on regressions, so a slow drift gets caught in days rather than in the next quarterly review. Our guide to data observability covers how to turn those signals into alerts. Our roundup of data observability tools also compares the platforms that do it.
Which Databricks Performance Optimization Should You Apply First?
The right first fix depends on the scenario, not on a universal checklist. A slow dashboard and a lagging stream share almost no root causes, so they deserve different first moves.
Each row below answers the title question for one situation: what to get right first, and what number proves it worked.
| Scenario | Get this right first | Measure |
|---|---|---|
| Slow BI dashboard | Data layout: liquid clustering on the filter columns | p95 latency, bytes read vs rows returned |
| Nightly batch overruns its window | Diagnosis, then table maintenance and join fixes | Job duration, shuffle bytes, spill |
| Streaming lag | Trigger interval and auto compaction on sinks | Batch duration vs arrival rate |
| MERGE-heavy CDC tables | Clustering on the merge key, scheduled OPTIMIZE above 1 TB | Files rewritten per MERGE, job duration |
| Ad-hoc data science notebooks | Serverless or autoscaling, fewer UDFs | Start-up time, first-query latency |
| Costs spiked after a scale-up | Read the profile before keeping the bigger cluster | Cost per successful run, runtime change |
Compute leads in only one row, whereas in every other scenario the fastest route to a faster job runs through measurement, layout or maintenance first.
Checklist
Databricks Readiness Checklist
Download the Databricks Checklist to review platform, data and team readiness before you scale workloads, so layout, maintenance and operations are planned rather than patched.
Get the Checklist →Common Mistakes and Practices to Retire
Many slow Databricks estates are slow because of habits that were sensible years ago. Four of them cause most of the damage, and each one has a direct replacement.
| Habit | Replace with | What changes |
|---|---|---|
| Partitioning every table by date | Liquid clustering on the filter columns | Fewer tiny files, more files skipped per query |
| Scaling compute before reading the profile | Fixing the layout, skew or spill the profile shows | Runtime falls without a bigger bill |
| Nightly OPTIMIZE on every table | Predictive optimization on managed tables, schedules only on external ones | No compute spent on tables that never change |
| Python UDFs on hot paths | Built-in functions | Photon runs the stage instead of falling back to Spark |
Each replacement also leaves a number behind, such as bytes read or runtime. That lets the benchmark protocol above prove it worked, so nothing rests on a hunch.
How Kanerika Tunes Databricks Workloads
Kanerika treats Databricks tuning as an engineering process with evidence at every step. As a certified Databricks partner, our Databricks consulting and implementation practice lists 70% shorter ETL runtime among its client outcomes, and the work follows four stages.
- Baseline. We profile the top jobs and queries by runtime and frequency, then record the KPIs from the measurement section.
- Plan. We rank fixes by layer, starting with layout and maintenance, because those usually remove the most work.
- Implement and benchmark. We apply one change at a time and keep it only when the benchmark shows a gain with unchanged results.
- Monitor. System-table dashboards and regression alerts keep the gains from drifting away as data grows, and our managed service adds 24×7 monitoring and version upgrades.
Datasheet
Redefining Enterprise Data and AI Success with Kanerika and Databricks
See how Kanerika and Databricks help companies build a modern, scalable data platform that is easier to manage and ready for AI workloads.
View the Datasheet →What the Same Discipline Looks Like in Kanerika Projects
The same habits show up in migration work. For a retail client, Kanerika moved full history from PostgreSQL and Cassandra into Delta Lake tables with PySpark notebooks and Spark connectors. Timestamp-based change capture and Delta MERGE then kept the sources in sync until each application was cut over, in a zero-downtime Databricks migration. That is the MERGE-heavy pattern from the scenario table, where clustering on the merge key limits how many files each sync rewrites.
Slow batch pipelines are often why a migration starts. At one healthcare provider, batch-heavy Informatica pipelines were delaying audits, risk assessments and reporting. Kanerika moved those workflows to Azure Databricks with its migration accelerator and re-architected the pipelines. The Informatica to Databricks case study reports 71% higher reporting accuracy, 38% lower data handling costs and 64% faster decision-making.
Speed problems also sit upstream of Spark. In one financial services data modernization project, a leading provider ran fraud, risk and settlement monitoring on core data held in protected S3 storage with minimal metadata. KPI reporting ran three days behind, and experts reshaped data by hand in Excel.
Kanerika built Airflow 2.0 ingestion from S3, then processed and enriched the data in Databricks before it reached Dremio. The team also added row-level security, automated data quality rules and glossary mappings. Data lag fell by 90%, reporting latency fell by 96% from the old three-day cycle, and BI adoption rose by 100%.
It was not a Spark-tuning engagement, but the lesson carries over: the lost time sat in how data was stored and moved, not in compute. Teams still on older platforms can read our guide to migrating legacy systems to Databricks, which shows how to avoid carrying slow patterns across. FLIP also automates much of that migration.
Case Study
90% Less Data Lag with Databricks and Airflow
A leading financial services provider moved KPI reporting off a three-day cycle, cutting data lag by 90% and reporting latency by 96%, while BI adoption rose by 100%.
Read the Case Study →The Bottom Line on Databricks Performance
What, then, should you get right in Databricks performance optimization? Measure before you change anything, fix data layout first, let automated maintenance run, tune queries from the plan, and size compute last. That order is also how the 90-minute nightly job from the opening comes back down. Clustering and compacting its tables cut the files it reads, while doubling the cluster mostly doubled the bill. Get the order right, prove each gain with a benchmark, and faster jobs follow without a bigger cluster.
Frequently Asked Questions
How do you optimize Databricks performance?
Start by measuring where time goes with the query profile, Spark UI and query history. Then fix data layout with liquid clustering, let predictive optimization or scheduled jobs keep tables compact, and tune joins, shuffle and skew from the plan. Size compute last, judged by runtime and queue time, and benchmark every change one at a time.
What causes slow queries in Databricks?
Databricks names four root causes. A query reads more data than it needs, shuffles too much data between nodes, runs a poor query plan, or rewrites files that did not change. Poor data layout, small files, stale statistics, skewed keys and undersized memory are the most common reasons behind each of those four causes.
Is serverless Databricks faster than classic compute?
Serverless is usually faster to start and scale, and it minimizes idle time, so short jobs and interactive queries often finish sooner end to end. Once a long job is running, raw speed depends more on data layout, the query plan and Photon coverage than on the compute model. Benchmark both models on your own workload.
How do you find the slowest or most expensive queries in Databricks?
Query the system.query.history table, which keeps 365 days of statements from SQL warehouses and serverless compute. Sort by total duration, bytes read, spill or queue time to rank the worst offenders. For spend, join usage from system.billing.usage. Then open the query profile of each top statement to see why it is slow.
Does caching always improve Databricks performance?
No. The disk cache helps when the same Parquet or Delta files are read repeatedly, and Databricks recommends it over Spark cache for that pattern. Spark cache holds computed results in memory, so overusing it takes memory from joins and can cause spill. Cache only intermediate results that one job reads several times over.
How do you speed up MERGE in Databricks?
Cluster the target table on the merge key so each MERGE touches fewer files, and narrow the match condition with filters such as a date range. Optimized writes and auto compaction are always on for MERGE, which limits small files. For targets over 1 TB, keep a scheduled OPTIMIZE alongside those features to maintain read speed.
Which metrics prove a Databricks optimization worked?
Track p95 query latency, job duration, bytes read against rows returned, shuffle bytes, spill, queue time and cost per successful run. Measure them before and after one change, on the same data and compute, with cold and warm runs. If the metric improves and results stay the same, the optimization worked and is worth keeping.
How can I improve Spark performance in Databricks?
Reduce the data each stage moves. Filter early, select only needed columns, pre-aggregate before joins and broadcast small tables, since Spark broadcasts tables under 10 MB by default. Keep adaptive query execution on, check whether it changed the plan, and fix skew and spill in the Spark UI before you add more nodes to the cluster.
Does Photon speed up every Databricks query?
No. Photon is the vectorized engine that runs SQL and DataFrame work faster, but it skips user-defined functions, RDD APIs and Dataset APIs, and supports only stateless streaming. Queries that already finish in under two seconds see no gain. Unsupported work falls back to standard Spark automatically, and the results stay correct either way.
What is the difference between liquid clustering and Z-Ordering?
Both group similar values into the same files so queries can skip data. Z-Ordering is an older technique applied through OPTIMIZE, while liquid clustering is the newer layout that replaces both Z-Ordering and partitioning. Databricks recommends liquid clustering for all new tables, and the two should not be combined on the same table.
Should you still partition Delta tables in Databricks?
Usually not. Databricks advises against partitioning tables under 1 TB, recommends liquid clustering for tables between 1 TB and 100 TB, and says partitioning might help only above 100 TB. Partitioning small tables by habit creates many tiny files and folders, which makes reads slower rather than faster for most analytical queries and dashboards.
When should you run OPTIMIZE and VACUUM in Databricks?
On Unity Catalog managed tables, predictive optimization runs both automatically, so manual jobs are rarely needed. External tables need scheduled runs, often weekly. Tables over 1 TB also benefit from a scheduled OPTIMIZE. VACUUM keeps seven days of history by default, which limits how far back time travel can reach after it runs.
How does predictive optimization work in Databricks?
Predictive optimization watches how Unity Catalog managed tables are used and runs OPTIMIZE, VACUUM and ANALYZE when they will help. It works on Delta and Iceberg managed tables. Accounts created on or after November 11, 2024 have it on by default, while older accounts are on a gradual rollout, so check your account settings.
How do you fix data skew in Databricks?
First confirm the skew in the Spark UI, where one task runs far longer than the rest. Adaptive query execution splits many skewed joins automatically. When it cannot, add a random salt to the hot key on both sides of the join, then aggregate the results back together. Filtering out null or default keys also helps.
How do you choose the right cluster size in Databricks?
Choose by runtime and queue time rather than node count. Use memory-optimized nodes when jobs spill, fewer larger nodes for shuffle-heavy work, and Photon with disk cache for scan-heavy queries. Autoscaling suits spiky workloads, while fixed sizes suit steady jobs with firm deadlines. Benchmark each size on the same data before you settle on one.