TL;DR
A Databricks MLflow implementation should use Unity Catalog as its registry, both for new builds and for teams still on the legacy Workspace Model Registry. Teams on MLflow 2.x should upgrade to MLflow 3 and replace stage transitions with aliases such as Champion and Challenger. Give each environment its own catalog so dev, staging and prod models carry separate permissions. Log every model with a signature, because Unity Catalog requires one on each new version. Serve the Champion alias in batch or through Model Serving, and log traffic to inference tables for drift checks. Automate promotion with deployment jobs and Declarative Automation Bundles so no model reaches production by hand.
Key Takeaways
- Tracking is only the first step: a production setup also needs a registry, aliases, serving by alias, monitoring and automated promotion.
- Databricks labels the Workspace Model Registry as legacy and recommends Unity Catalog, where models are named catalog.schema.model.
- Unity Catalog does not support Staging and Production stages, so use one catalog per environment plus aliases.
- MLflow 3 treats models as first-class LoggedModel objects and also adds deployment jobs, GenAI tracing and evaluation.
- Cost comes from training compute, Model Serving, inference tables and profiling, all billed by usage rather than per MLflow seat.
- Move from MLflow 2.x in waves, starting with the code that still loads models by stage.
Two “Final” Models and One Audit Question
Picture a quarterly model review at a mid-sized lender. The chief risk officer asks a simple question: which version of the credit scoring model approved last quarter’s loan applications?
The data science lead then opens three notebooks. Two of them hold a model file called final, although one has a newer timestamp. Nobody can say which file the scoring job loaded, which data trained it or who approved the switch.
The model itself may still be excellent.
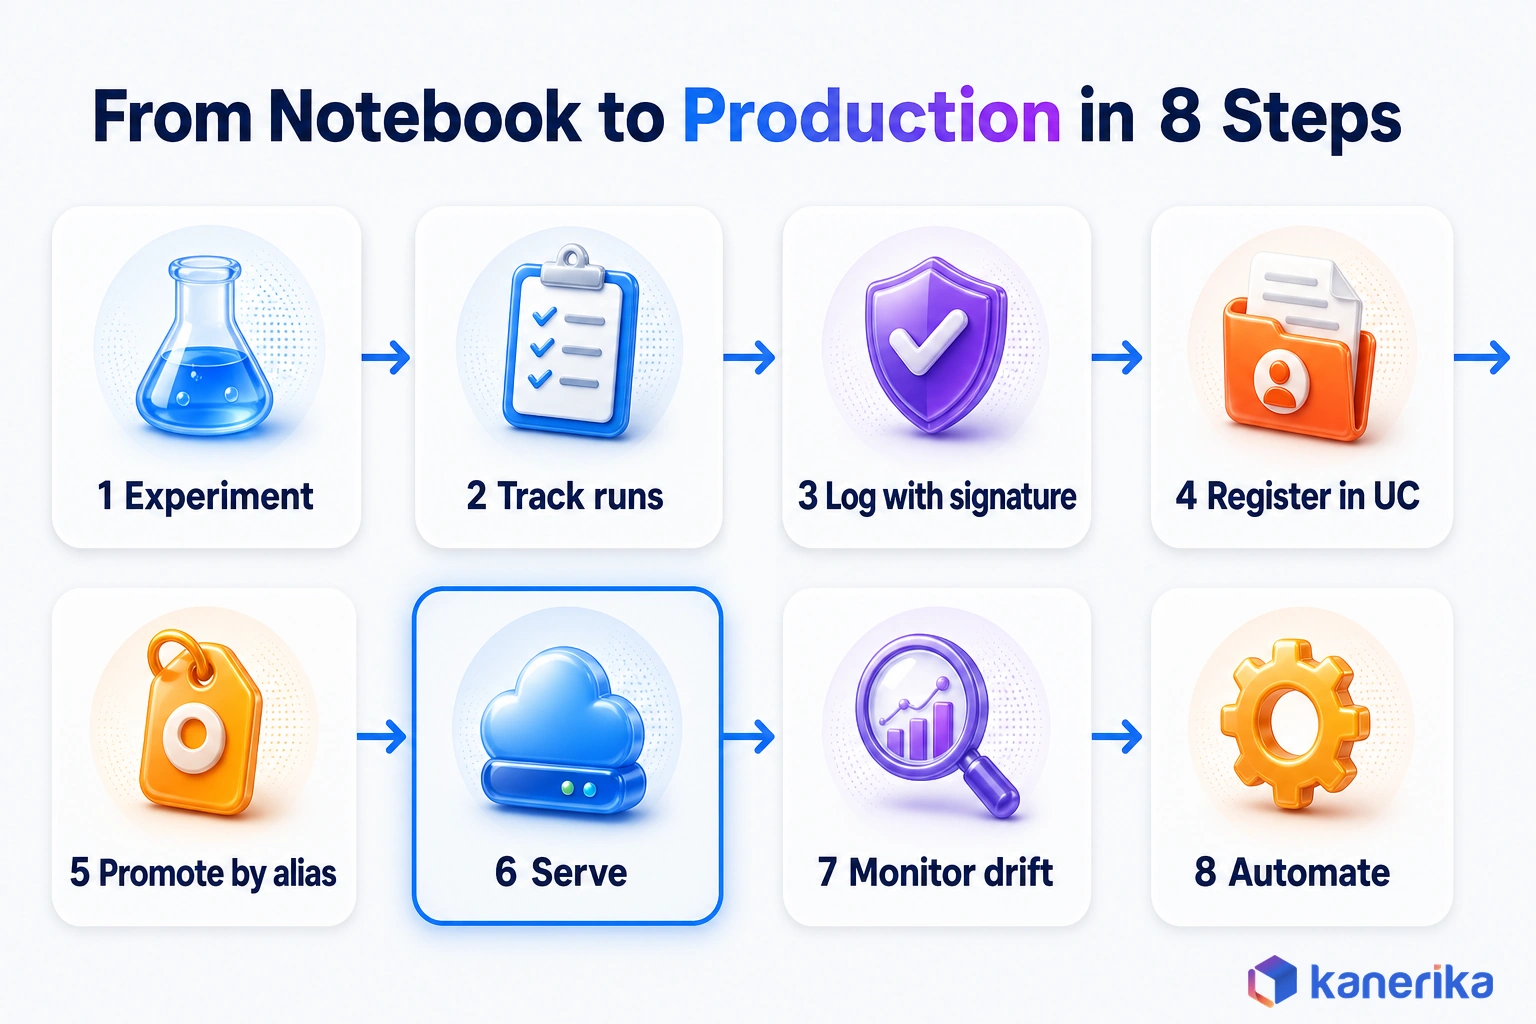
What is missing is the system around it: the record of runs, versions, approvals and deployments that MLflow on Databricks is built to keep. This guide walks through that system end to end. It starts with the decisions to make first and then moves through eight build steps with code. After that come the move from MLflow 2.x, the cost drivers and the mistakes that cause rework.
Why Databricks MLflow Implementation Is More Than Turning On Tracking
A Databricks MLflow implementation turns experiment logging into a governed path from notebook to production. Tracking is the easy part, since one autolog call records parameters and metrics for most common libraries.
The hard part starts once the best run is chosen. Before anything ships, somebody has to decide where models are registered and who can promote them. Serving code needs a reliable way to find the right version, and someone has to notice when predictions drift.
Skip those decisions and the gaps surface later, usually during an audit or an incident. Experiments end up scattered across personal folders, and models get promoted by copying files. Rollback then means guessing which artifact was live last week. A 2015 NeurIPS paper, Hidden Technical Debt in Machine Learning Systems, warns that real-world ML systems often carry large ongoing maintenance costs.
MLflow is also widely used, with more than 30 million monthly downloads according to the Databricks MLflow documentation. With that reach, most teams arrive with MLflow habits from open-source projects. Some of them, such as stage transitions and run-relative model paths, do not carry over to Unity Catalog. Getting those conventions right early saves months of cleanup.
What Databricks MLflow Is and What It Manages
MLflow is an open-source platform for the machine learning lifecycle, released under the Apache License 2.0 according to its PyPI listing. Databricks runs a managed version inside the workspace, so you do not host a tracking server yourself.
On Databricks, MLflow manages a small set of objects, so knowing them by name makes every later step easier to follow:
- Experiment: a container that groups related runs, such as every training attempt for one model.
- Run: one execution of training code, with its parameters, metrics, tags and artifacts.
- LoggedModel: in MLflow 3, a model stored as an object with its own ID, linked to runs, metrics and traces.
- Registered model: a named model in Unity Catalog, addressed as catalog.schema.model.
- Model version: a numbered snapshot of a registered model whose model files stay fixed once created.
- Alias: a movable label, such as Champion, that points to one version.
- Trace: a step-by-step record of a GenAI or agent request, used for debugging and evaluation.
MLflow ships often, and 3.17.2 reached PyPI on October 21, 2026. Pin one version per job environment, and make sure training and serving load models with the same client.
What MLflow 3 Added
MLflow 3.0.0 shipped on June 10, 2025, and it changed how models are stored. A model is now a LoggedModel with its own ID rather than a file inside a run’s artifact folder. You can log a model without an active run and, once it is registered in Unity Catalog, follow it across workspaces and experiments. That shift is why Step 3 below logs models with name= instead of a run-relative path.
Promotion changed with it. Deployment jobs use Lakeflow Jobs to manage evaluation, approval and deployment for a registered model. Databricks records those events in the Unity Catalog activity log. They are what replaces the old stage transitions in Step 8.
Generative AI gets the same treatment. MLflow 3 adds tracing for agent and LLM calls, evaluation with LLM judges and a prompt registry, which together form the GenAI layer of monitoring in Step 7. Our LLM evaluation framework guide explains how judge-based scoring works. A demand forecast and a support chatbot can therefore share one platform.
Kanerika Service
Databricks Consulting and Implementation
Kanerika’s certified Databricks team designs Unity Catalog, MLflow tracking and the registry layout, then takes your first models into governed production.
Explore Databricks ServicesOpen-Source MLflow vs Databricks-Managed MLflow
The open-source and managed versions share the same tracking and model APIs, so code written for one mostly runs on the other. The difference instead lies in everything around the API: security, recovery, encryption and where models get served.
| Feature | Open-source MLflow | Databricks-managed MLflow |
|---|---|---|
| Security | You supply your own governance layer | Databricks enterprise security |
| Disaster recovery | Not available | Databricks disaster recovery |
| Experiment tracking | MLflow Tracking API | Tracking API plus Databricks experiment tracking |
| Model registry | MLflow Model Registry | Registry built on Unity Catalog |
| Model deployment | You wire up external serving, such as SageMaker or Kubernetes | Databricks Model Serving or external serving |
| Agents and LLMs | MLflow LLM development | Also adds Custom Agents and Agent Evaluation |
| Encryption | Not available | Customer-managed keys |
Source: Databricks MLflow documentation, checked October 30, 2026.
Managed MLflow is the sensible default when your data and training already run on Databricks. Governance, lineage and serving come with the platform, while the registry uses the same permission model as your tables.
Open-source or hybrid setups still win in a few cases. A team that serves most models on Kubernetes might keep an external model registry, for instance, and use Databricks only for training. The same also goes for a company standardized on another cloud ML platform, a trade-off our Databricks vs SageMaker guide explores. If you are weighing those options, our comparison of MLOps tools covers the wider field.
How the Pieces Fit: A Reference Architecture
A production MLflow setup on Databricks works like a relay, where each stage hands a governed asset to the next. Seeing the whole chain before the build makes the order obvious, and it runs on the same Databricks lakehouse architecture as your analytics.
Data lands in Delta tables first, and then feature tables are built from them in Unity Catalog. After that, training jobs read those features, log runs to an experiment and register the best model under catalog.schema.model.
From there, an alias points to the version that serving should use. Batch jobs or a Model Serving endpoint load that alias, while inference tables record each request and response. Data profiling then compares new traffic with a baseline to flag drift.
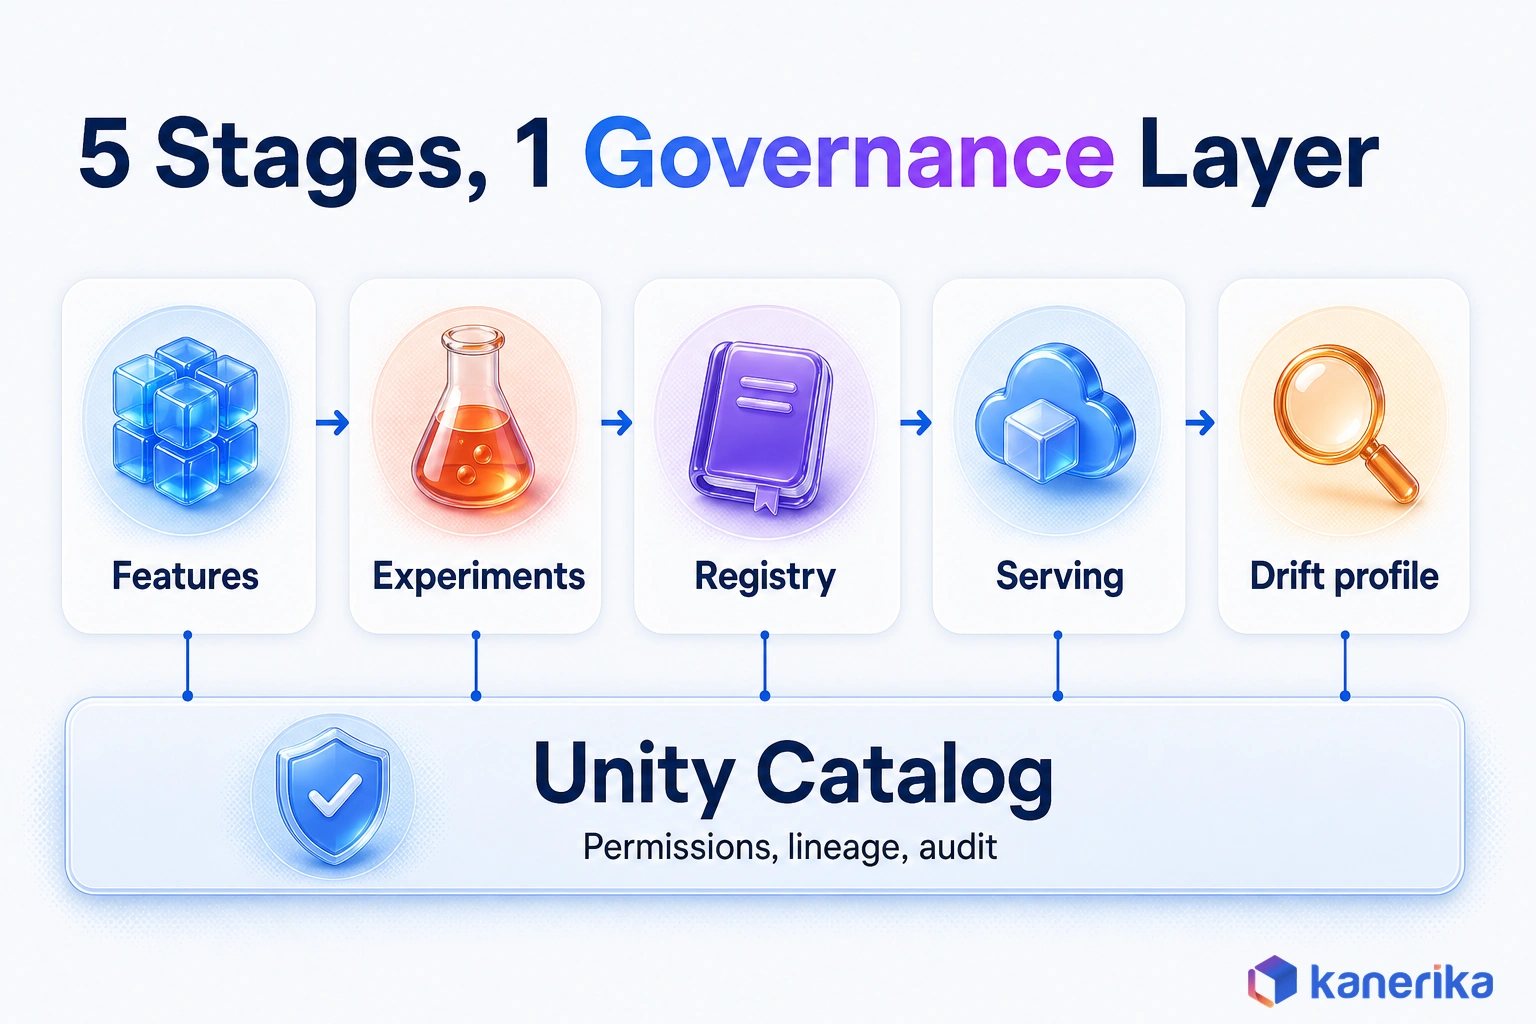
Unity Catalog sits under all of it. Tables, features, models and endpoints therefore share one permission system, one lineage graph and one audit trail.
Feature Store in Unity Catalog
Feature tables in Unity Catalog give each model a governed, reusable set of inputs. When you register features and models there, you get lineage, point-in-time joins and feature sharing across workspaces, according to the Databricks feature store guide.
Point-in-time joins matter more than they sound. They make sure training only sees feature values that existed at each label’s timestamp. That prevents the quiet leakage that makes offline scores look better than production ones.
The older workspace feature store is deprecated, so new builds should start in Unity Catalog. For feature table design in more depth, see our walkthrough of feature tables on Databricks.
Governance Through Unity Catalog
Registering models in Unity Catalog puts them under the same controls as your data. Privileges decide who can create, read or run each model, while lineage links a model version to the tables and notebooks that produced it.
Every action also lands in the audit log, which answers the review question from the opening scenario. Models are discoverable across workspaces too, so the production workspace loads the exact version development trained, without anyone copying files. Our guide to Databricks security covers the access rules, and our overview of Databricks Unity Catalog covers the wider governance model.
Decisions to Make Before You Build
Six decisions shape every Databricks MLflow implementation, and changing them once models reach production is slow. Settle them in a short design session before anyone writes training code.
The registry choice comes first. Databricks labels the Workspace Model Registry as legacy and recommends Unity Catalog instead, which does not support the old Staging and Production stages. Environments are therefore modeled as separate catalogs, and aliases mark which version is live inside each one.
| Decision | Options | Sensible default | Why |
|---|---|---|---|
| Registry | Unity Catalog, legacy workspace registry, external registry | Unity Catalog | Governance, lineage and cross-workspace access come built in |
| Environment layout | One catalog per environment, or one shared catalog | dev, staging and prod catalogs | Permissions follow the environment boundary |
| Naming | Free-form, or catalog.domain.model | prod.credit_risk.pd_model | Names stay readable when more teams join |
| Promotion | Manual copies, or aliases with a deployment job | Aliases plus a deployment job | Every promotion is approved and logged |
| Ownership | Individual users, or groups | A group owns each model | Access survives when staff change roles |
| Serving target | Batch scoring, real-time endpoint, or both | Batch first, an endpoint when latency demands it | It costs less and is simpler to run than an endpoint |
Ownership and Promotion Rules
Ownership deserves a second look. Databricks advises giving ownership of a registered model to a group that includes everyone who needs write access. Otherwise, the model stays tied to whoever created it, even after that person changes teams. Clear ownership is also a core control in any machine learning governance program.
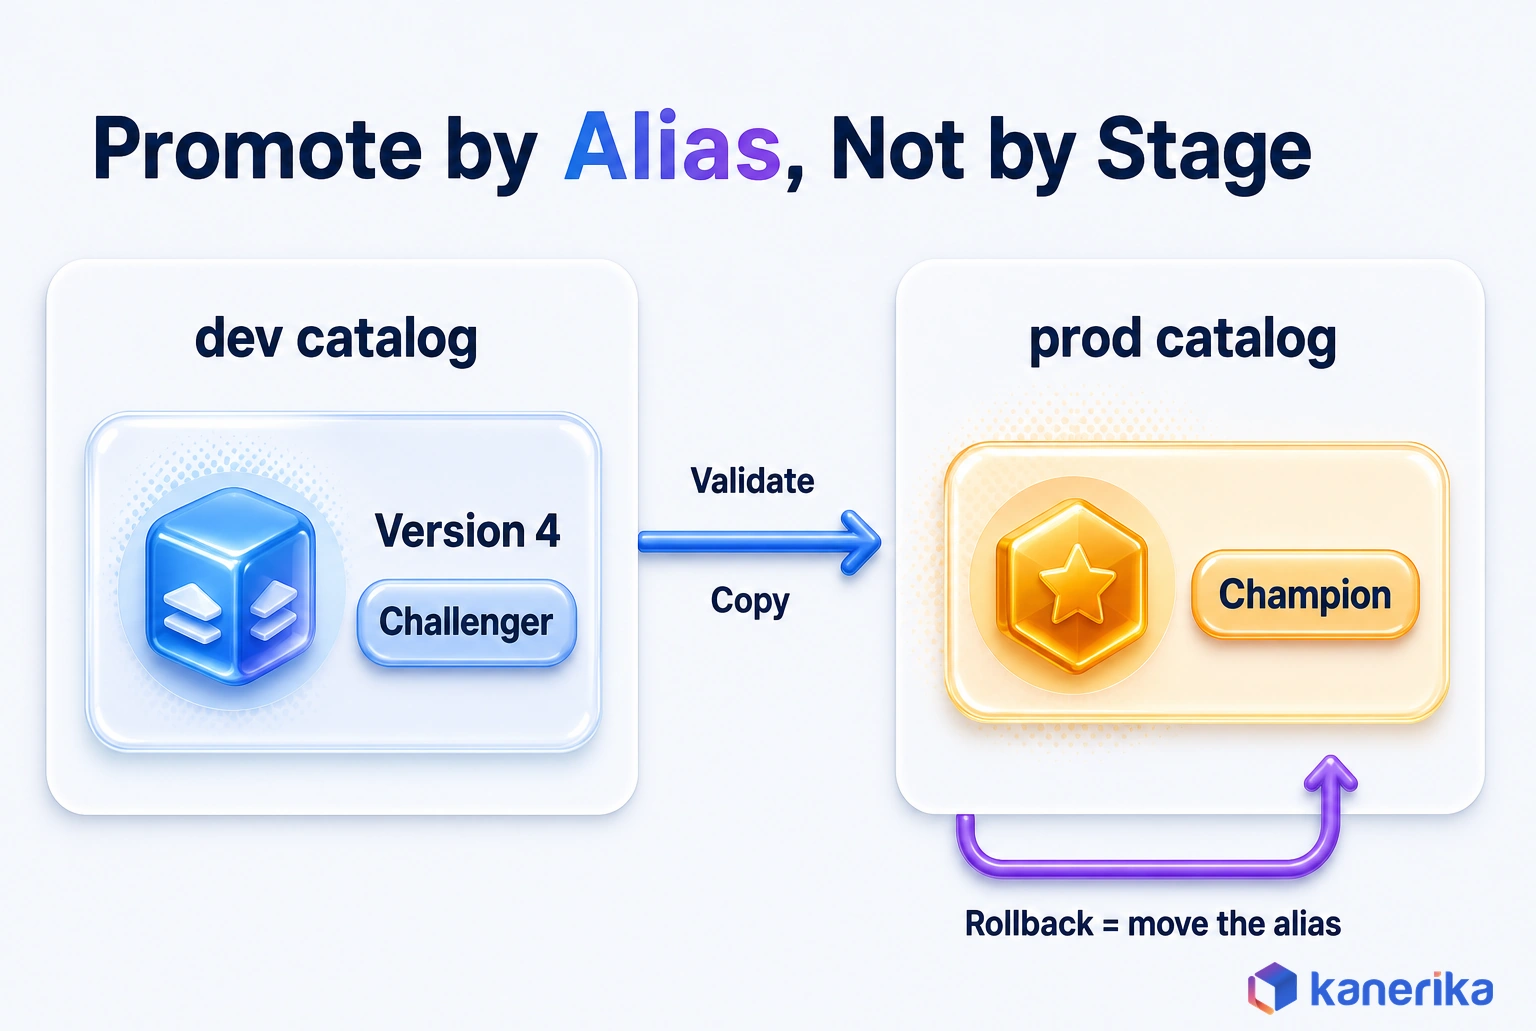
The promotion rule is worth drawing on a whiteboard before the build. A candidate earns the Challenger alias in dev, gets validated, then is copied into prod (the fallback when retraining in prod costs too much), where it takes the Champion alias. For the governance practices that sit above any single platform, such as approval policies and model documentation, see our guide to ML model management.
Prerequisites Checklist
Check the platform before the first notebook, because early blockers tend to be permissions or runtime versions rather than code. Work through this list with your workspace admin:
- A workspace attached to a Unity Catalog metastore that supports privilege inheritance. Every metastore created after August 25, 2022 does.
- Databricks Runtime 13.2 ML or above. On 11.3 LTS and above, install a current MLflow client before you start (3.17.2 was the newest PyPI release as of October 2026).
- MLflow 3 on the cluster or job, installed with %pip and then a Python restart.
- USE CATALOG and USE SCHEMA on the target schema, plus CREATE MODEL to register models.
- EXECUTE on a registered model for every user or job that loads it.
- Compute with access to Unity Catalog in Dedicated access mode (formerly single user), or dedicated group access mode on Runtime 15.4 LTS ML and above.
- A group or service principal for automation, so production jobs never run under a personal account.
For hands-on learning, Databricks Free Edition replaced Community Edition, which was retired in 2025. Free Edition is serverless-only and quota-limited, so it suits tutorials rather than a production pilot.
If the workspace, network or metastore is not ready yet, start with our guide to Databricks deployment. Then come back once the platform is in place.
Step-by-Step Databricks MLflow Implementation
The eight steps below follow the order a model moves through, from first experiment to automated release. Each one builds on the step before it, so resist the urge to start with serving.
The examples use a credit risk model called pd_model and three catalogs named dev, staging and prod. Swap in your own names as you go. Credit scoring is a familiar machine learning use case in fintech, which makes it a useful running example.
Step 1: Point MLflow at Unity Catalog and Create an Experiment
Install MLflow 3 and restart Python so the notebook picks up the new client.
%pip install "mlflow>=3.0" --upgrade
dbutils.library.restartPython()
Then set the registry to Unity Catalog and choose an experiment. MLflow 3 already defaults to databricks-uc, but setting it explicitly keeps older notebooks consistent.
import mlflow

mlflow.set_registry_uri("databricks-uc")
mlflow.set_experiment("/Shared/credit-risk/pd-model")
Keep experiments in a shared folder per project rather than in personal folders. Reviewers can then find every run without asking who trained what.
Step 2: Track Runs with Autologging and Manual Logging
Autologging records parameters, metrics and the model for many popular frameworks with a single call. Add manual logging for what autologging cannot know, such as the feature set version or a business metric.
from sklearn.ensemble import RandomForestClassifier
from sklearn.metrics import roc_auc_score

mlflow.autolog()

with mlflow.start_run(run_name="rf-baseline"):
    model = RandomForestClassifier(n_estimators=200, max_depth=8)
    model.fit(X_train, y_train)
    auc = roc_auc_score(y_test, model.predict_proba(X_test)[:, 1])
    mlflow.log_param("feature_set", "pd_features_v3")
    mlflow.log_metric("holdout_auc", auc)
    mlflow.set_tag("git_commit", git_sha)
Also tag each run with the dataset version and the Git commit. When a model misbehaves months later, those two tags are usually the fastest route to the cause.
Talk to Kanerika
Map Your MLflow Path to Production
Bring your current notebooks, registry and serving setup. Kanerika will walk through the catalog layout, alias rules and build order for your models.
Schedule a Demo →Step 3: Log the Model with a Signature
Unity Catalog requires a signature on every new model version. A signature records the input and output schema, so serving can reject a malformed request instead of returning a wrong answer.
In MLflow 3, pass name= instead of the deprecated artifact_path=. Autologging adds a signature for you, but explicit logging keeps the contract visible in code.
from mlflow.models import infer_signature

signature = infer_signature(X_train, model.predict(X_train))
model_info = mlflow.sklearn.log_model(
    sk_model=model,
    name="pd_model",
    signature=signature,
    input_example=X_train.head(5),
)
print(model_info.model_uri)  # models:/<model_id>
Step 4: Register the Model to catalog.schema.model
Registration turns a logged model into a versioned asset in Unity Catalog. Use the three-level name, and register into the dev catalog first.
mlflow.register_model(
    model_uri=model_info.model_uri,
    name="dev.credit_risk.pd_model",
)
Whoever registers the model needs USE CATALOG, USE SCHEMA and CREATE MODEL. Grant them to groups, and also grant EXECUTE to the jobs that will load the model. Registered models count as functions in Unity Catalog, so that grant uses ON FUNCTION.
GRANT USE CATALOG ON CATALOG dev TO `ml-engineers`;
GRANT USE SCHEMA ON SCHEMA dev.credit_risk TO `ml-engineers`;
GRANT CREATE MODEL ON SCHEMA dev.credit_risk TO `ml-engineers`;
GRANT EXECUTE ON FUNCTION prod.credit_risk.pd_model TO `scoring-jobs`;
Each registration creates a new numbered version. A version’s model files stay fixed after registration, so the record of what was trained stays intact. Its description, tags and aliases can still change.
Step 5: Evaluate and Promote with Aliases
Aliases replace the old stage transitions. Mark a candidate as Challenger and compare it with the current Champion on the same holdout data. Promote it only when it wins on the metric you agreed with the business.
Databricks’ first recommendation is to deploy the training code and retrain in prod; when retraining is too expensive, promote by copying the approved version. That copy goes into the prod catalog, where you then set the Champion alias. The person or job doing it needs EXECUTE on the source model. It also needs ownership of the destination model or the CREATE MODEL VERSION privilege on it.
from mlflow import MlflowClient

client = MlflowClient()
client.set_registered_model_alias("dev.credit_risk.pd_model", "Challenger", 4)

# after validation passes, copy version 4 into prod
prod_version = client.copy_model_version(
    "models:/dev.credit_risk.pd_model/4",
    "prod.credit_risk.pd_model",
)
client.set_registered_model_alias(
    "prod.credit_risk.pd_model", "Champion", prod_version.version
)
Rollback also becomes a single call. Point Champion back at the previous version, and every consumer picks it up on its next load.
Kanerika Service
MLOps Consulting Services
Kanerika sets up model registries, promotion workflows, serving and drift monitoring so your models keep running reliably after launch.
Explore MLOps ConsultingStep 6: Serve in Batch or Real Time
Serving code should load a model by alias rather than by version number. A promotion or rollback then needs no code change at all.
Batch scoring suits most forecasting and risk models, especially those that run on a schedule. Load the alias as a Spark UDF and score a whole table in one pass:
predict = mlflow.pyfunc.spark_udf(
    spark, "models:/prod.credit_risk.pd_model@Champion"
)
scored = applications_df.withColumn("pd_score", predict(*feature_cols))
scored.write.mode("append").saveAsTable("prod.credit_risk.pd_scores")
Real-time scoring uses Model Serving, which exposes a REST endpoint backed by the registered model. For example, a client call looks like this:
curl -X POST "https://<workspace-host>/serving-endpoints/pd-model/invocations" \
  -H "Authorization: Bearer $DATABRICKS_TOKEN" \
  -H "Content-Type: application/json" \
  -d '{"dataframe_split": {"columns": ["income", "debt_ratio"], "data": [[72000, 0.31]]}}'
Model Serving is billed in DBUs per hour. Start with batch unless a user or application truly needs an answer within milliseconds.
Step 7: Monitor with Inference Tables, Data Profiling and Tracing
Monitoring starts with a record of what the model saw and what it returned. Inference tables log requests and responses from served models into Unity Catalog Delta tables, as the inference tables documentation describes.
Those logs feed data profiling, which computes drift against a baseline table or between time windows. Before go-live, set the baseline to your training data. Then alert when an input distribution or the prediction mix moves past an agreed threshold. The Databricks data profiling guide covers the setup in detail.
GenAI applications, however, need one more layer. MLflow tracing captures each step of an agent or LLM call, while LLM judges score the answers for quality. A decorator is enough to start, and our guide to Databricks Mosaic AI covers the agent tooling around it:
import mlflow

@mlflow.trace
def answer_policy_question(question: str) -> str:
    context = retrieve_policy_passages(question)
    return call_llm(question, context)
For a wider view of tracing and evaluation options beyond MLflow, see our roundup of AI observability tools.
Step 8: Automate with Deployment Jobs and Declarative Automation Bundles
Manual promotion works for one model but breaks down at ten. Deployment jobs and bundles turn every step above into reviewed, repeatable code, the core idea behind MLOps orchestration.
A deployment job is a Lakeflow job linked to a registered model. It runs the evaluation, approval and deployment tasks for each new version, while Unity Catalog keeps the record of every event.
Declarative Automation Bundles, formerly Databricks Asset Bundles, define those jobs as YAML stored in Git. For example, a minimal bundle might look like this:
bundle:
  name: pd-model

resources:
  jobs:
    pd_model_deployment:
      name: pd-model-deployment
      tasks:
        - task_key: evaluate
          notebook_task:
            notebook_path: ./notebooks/evaluate.py
        - task_key: deploy
          depends_on:
            - task_key: evaluate
          notebook_task:
            notebook_path: ./notebooks/deploy.py

targets:
  dev:
    mode: development
  prod:
    mode: production
Deploy it with databricks bundle deploy -t prod from your CI pipeline, running as a service principal. MLOps Stacks builds on bundles if you want a ready-made project template, and our Databricks Asset Bundles guide covers the YAML in more depth. For the team practices that surround this pipeline, see our guide to machine learning operations.
Migrating from MLflow 2.x and the Workspace Model Registry
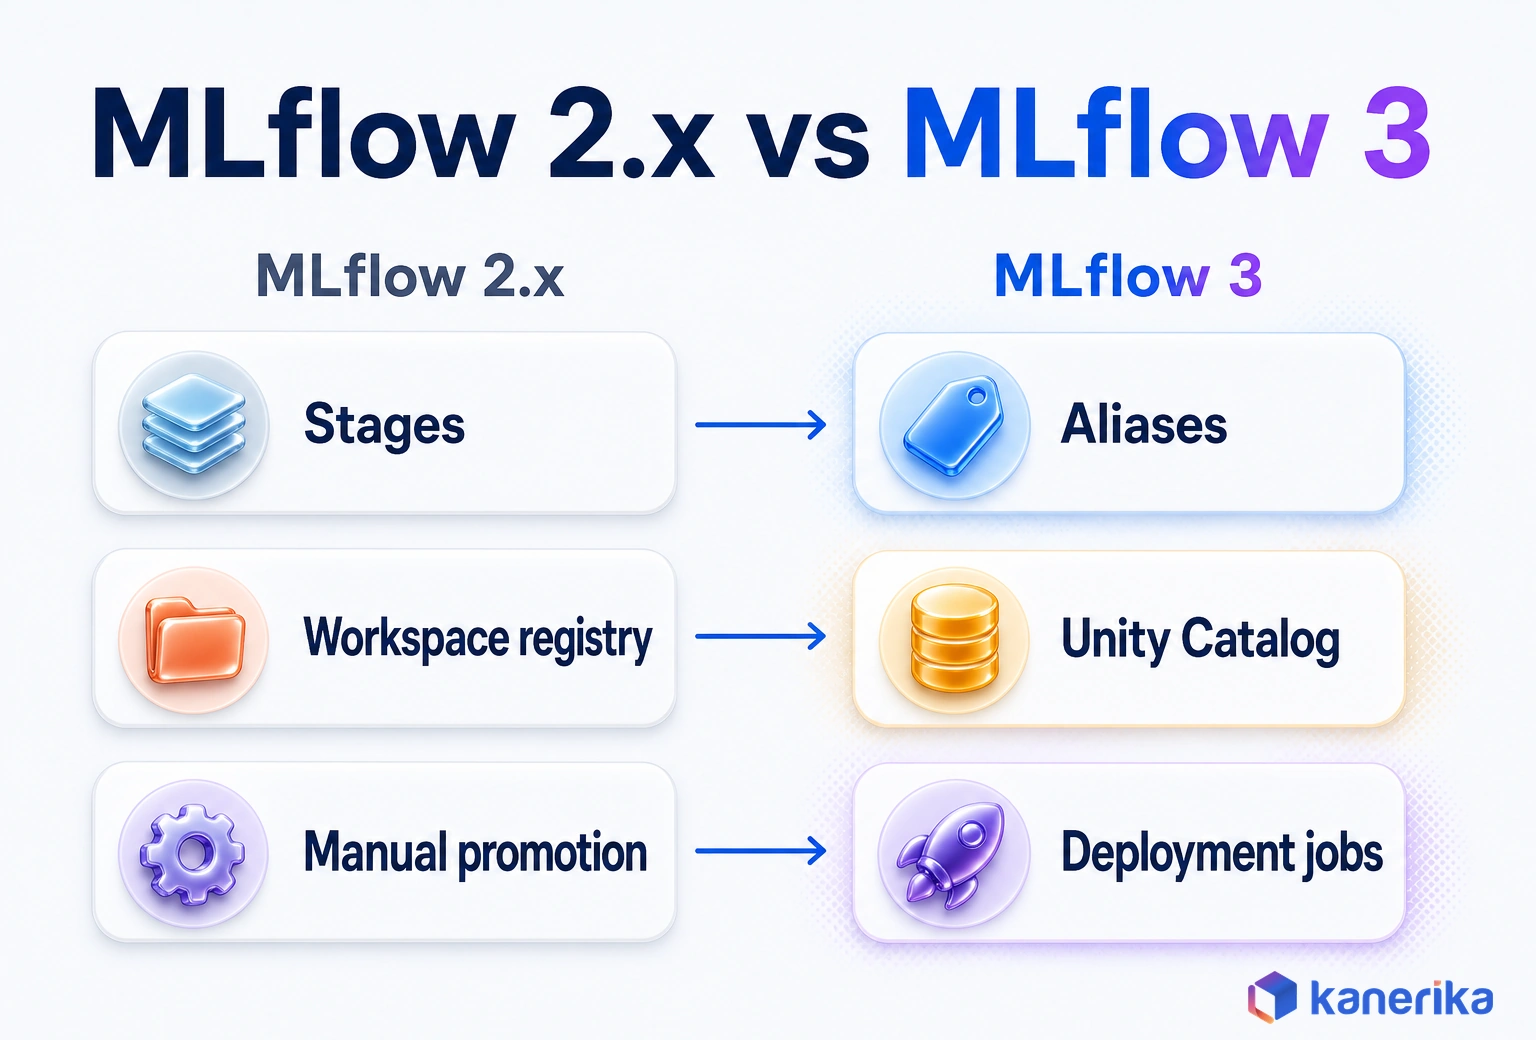
Many Databricks teams still run MLflow 2.x code against the workspace registry. Moving to MLflow 3 and Unity Catalog touches far more than a version number, so plan it as a small project with a test model. Teams moving tables at the same time can follow our Unity Catalog migration guide for the data side.
| Area | MLflow 2.x with workspace registry | MLflow 3 with Unity Catalog | What to change |
|---|---|---|---|
| Registry | Workspace Model Registry, legacy as of October 2026 | Unity Catalog, the default registry URI | Copy models into a catalog and schema |
| Lifecycle | Staging and Production stages | Aliases plus one catalog per environment | Map each stage to an alias and catalog |
| Model storage | Files under a run’s artifact path | LoggedModel with its own ID | Stop assuming every model sits inside a run |
| Logging call | artifact_path= | name= | Update every log_model call |
| Signature | Often skipped | Required for new versions | Use autologging or infer_signature |
| Promotion | Manual stage transitions | Deployment jobs on Lakeflow Jobs | Move approval into a job |
The biggest risk is code that depends on stages. A loader that asks for the Production stage stops working once the model lives in Unity Catalog, because stages do not exist there.
Find those calls first, map each stage to an alias and a catalog, and update the loaders before you move a single model. Then migrate in waves, starting with one low-risk model. Keep the old registry read-only until every consumer reads from Unity Catalog, and only then retire it. The MLflow 3 migration guide lists the API changes in detail. If your models still run on a platform outside Databricks, our guide to legacy systems to Databricks migration covers that earlier move.
What Drives Databricks MLflow Cost and Effort?
On Databricks, the bill comes from the compute and services an MLflow workflow uses, measured in Databricks Units (DBUs). Open-source MLflow itself is free under the Apache License 2.0. Five drivers account for most of the spend:
| Cost driver | Billed as | How to control it |
|---|---|---|
| Training compute | DBUs for cluster or serverless time | Job compute, auto-termination and right-sized clusters |
| Model Serving | DBUs per hour per endpoint | Batch first, then CPU where possible |
| Inference tables | Charges for each logged request and response | Log what monitoring needs and set retention |
| Data profiling | Serverless compute for each refresh | Refresh on the schedule decisions actually need |
| Storage | Cloud storage for artifacts, tables and logs | Retention rules on experiments and logs |
GPU endpoints add up fastest. The Databricks Model Serving pricing page lists a single T4 GPU at 10.48 DBUs per hour, before your contract rate is applied. So keep GPU serving for the models that truly need it, and see our Databricks cost optimization guide for the wider levers.
Effort is harder to price than compute, and it depends on a handful of factors:
- The number of models and teams moving onto the platform.
- How much MLflow 2.x code and stage-based loading needs to change.
- Whether models need real-time endpoints or only batch scoring.
- Regulatory review and model approval steps.
- How mature your CI/CD and Git practices already are.
A single team with a few batch models on a working Unity Catalog setup is a small project. A multi-team estate with stage-based code, real-time endpoints and formal model risk review is a program, so it needs a plan with waves and owners.
Common Databricks MLflow Implementation Mistakes
Each mistake below is cheap to avoid at design time and costly to fix once models are in production. They also tend to travel together, so fixing one usually exposes the next.
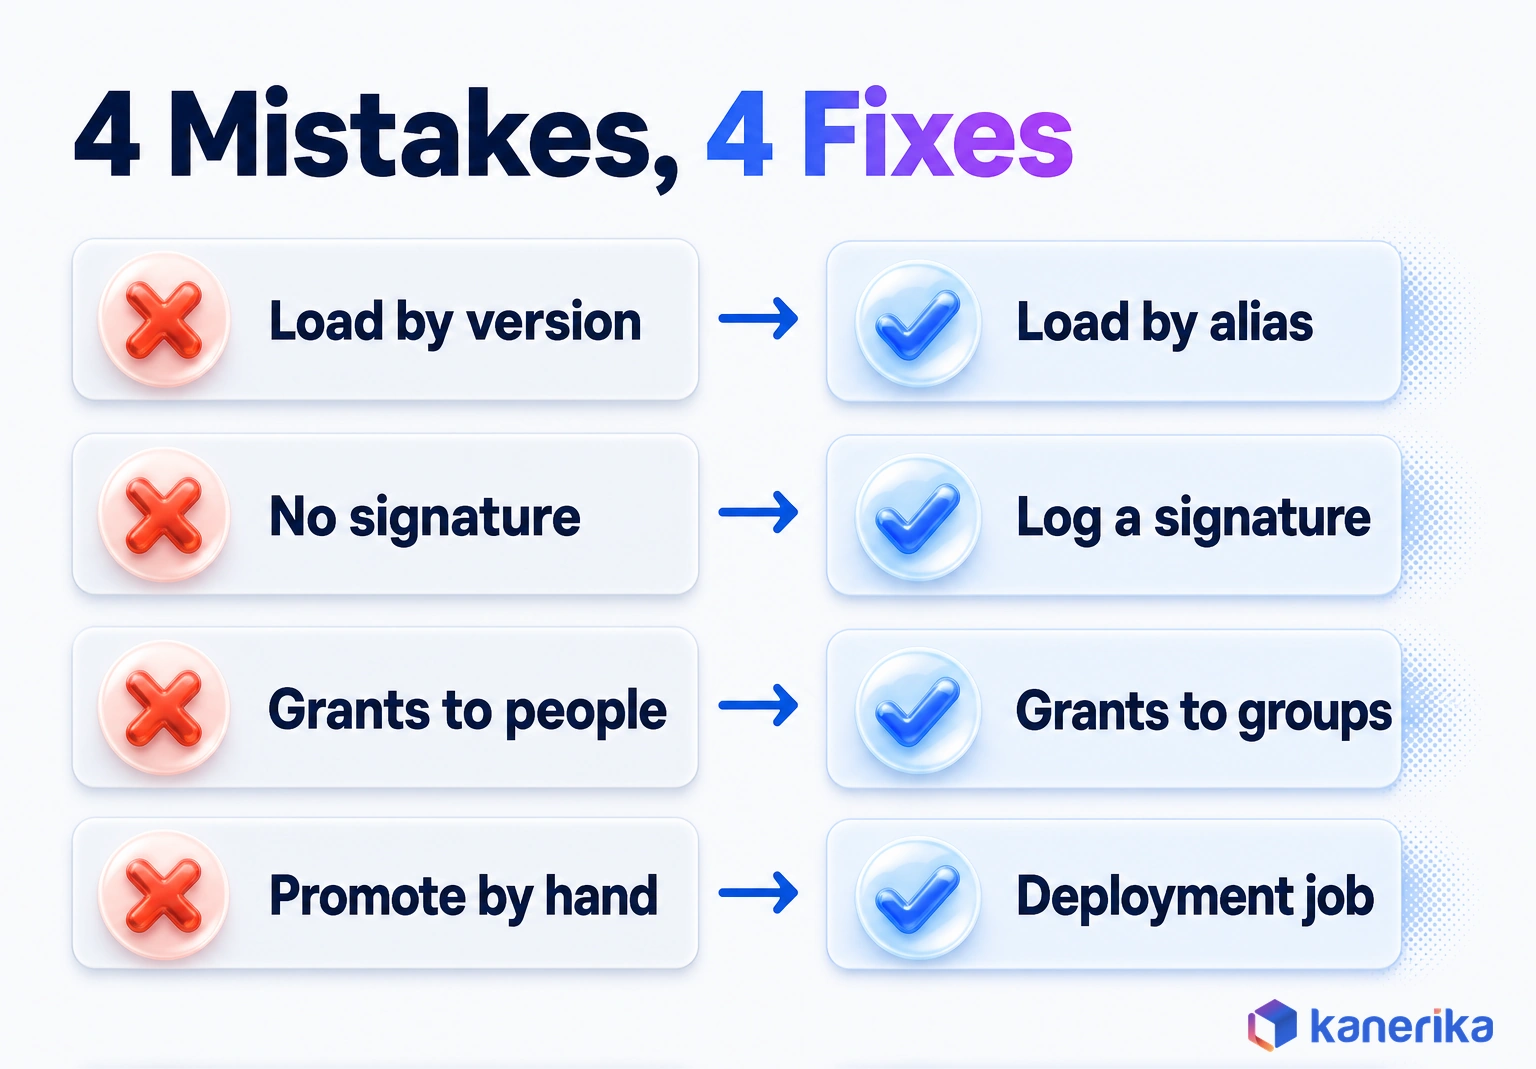
- Treating tracking as the whole job. Plan the registry, aliases, serving and monitoring before the first production model.
- Rebuilding stages with name suffixes. Models named pd_model_staging in one shared catalog lose the permission boundary. Use a catalog per environment and aliases instead.
- Loading models by version number. Hard-coded versions turn every promotion into a code release. Load by alias.
- Logging models without a signature. Unity Catalog rejects new unsigned versions. Use autologging or infer_signature.
- Granting access to individuals. Access breaks when people move on. Let groups own models and service principals run jobs.
- Going live without inference logging. Drift goes unseen until users complain. Turn on inference tables and a profiling baseline before launch.
- Promoting from a notebook by hand. Nothing records who approved the change. Use a deployment job and a bundle in Git.
Most of these trace back to treating a notebook as the product. Once the model is seen as one part of a governed system, the fixes follow naturally from the eight steps above.
Worked Example: A Demand Forecasting Model From Notebook to Production
Following one model through every step shows how the pieces connect. Take a retailer’s supply chain team that builds a weekly demand forecast for each store and product, a common job for machine learning in retail. The names and choices below are illustrative rather than client data.
The team creates a shared experiment and trains a gradient-boosted model with autologging on. Each run also carries a tag for the feature table version. The best run is then logged with a signature and registered as dev.supply_chain.demand_forecast.
A deployment job then scores the new version against the current Champion on recent weeks of actual sales. When the candidate wins on the agreed error metric, a planning lead approves it. After that, the version is copied to prod and the Champion alias moves.
Forecasts are only needed once a week, so scoring runs as a batch job that loads the Champion alias. Its output lands in a Delta table, while a data profile compares incoming features with the training baseline. A sudden shift from a promotion or a wave of store openings shows up before planners lose trust in the numbers.
| Step | What the team produces |
|---|---|
| 1. Experiment | /Shared/supply-chain/demand-forecast |
| 2. Tracking | Runs with parameters, metrics and feature-table tags |
| 3. Logged model | LoggedModel with a signature and an input example |
| 4. Registration | dev.supply_chain.demand_forecast, new version per release |
| 5. Promotion | Challenger in dev, Champion in prod after approval |
| 6. Serving | Weekly batch job loading the Champion alias |
| 7. Monitoring | Forecast output table with a drift profile against the baseline |
| 8. Automation | Bundle with training, deployment and scoring jobs in Git |
How Kanerika Implements Databricks MLflow
Kanerika is a certified Databricks partner, and our MLflow work starts with the system around the model rather than the model alone. Each engagement moves through five stages:
- Assessment: review current tracking, registry use, stage-based code and serving paths.
- Design: lay out catalogs per environment, naming, owner groups and alias rules in Unity Catalog.
- Pilot: take one model through all eight steps, from experiment to monitored production.
- Rollout: move the remaining models in waves, with deployment jobs and bundles in Git.
- Run: watch drift, cost and approvals, then tune the setup as the model count grows.
The same model-to-production focus runs through our delivery work. For a leading bank’s treasury team, Kanerika built and deployed a predictive model for daily cash inflows and outflows inside the bank’s Daily Funding Portal. Workforce productivity across treasury rose 20%, while processing delays fell 35%. Use of AI tools and data across the function also grew 40%.
To scope the work for your own models, see our Databricks services and MLOps consulting pages.
Case Study
20% Productivity Lift for Bank Treasury with AI Forecasting
Kanerika built and deployed a predictive model for daily cash inflows and outflows inside a bank’s Daily Funding Portal, raising productivity 20% and cutting processing delays 35%.
Read the Case Study →Bottom Line: Build the Path, Not Just the Experiment Log
A Databricks MLflow implementation succeeds when anyone can trace a production prediction back to its version, data, code and approver. Tracking alone never gets you there.
Start with Unity Catalog as the registry and one catalog per environment. Add signatures, aliases and serving by alias, then wrap the whole flow in deployment jobs and bundles. Settle those decisions before the first training run, and your Databricks MLflow implementation will answer the next audit question before anyone asks it.
Frequently Asked Questions
What is MLflow in Databricks?
MLflow in Databricks is the managed version of the open-source MLflow platform, built into every workspace. It tracks experiments and runs, stores models, registers them in Unity Catalog and connects them to Model Serving. Databricks uses it as its tool for experiment tracking and model management, so there is no separate tracking server to install or run.
How do I set up MLflow in Databricks?
Start with a workspace attached to a Unity Catalog metastore and a Databricks Runtime ML cluster, version 13.2 or above. Install MLflow 3 with pip and restart Python. Then set the registry URI to databricks-uc, create a shared experiment and call mlflow.autolog before training. Every run is then tracked and ready to register.
How much does Databricks MLflow cost, and is it free?
Open-source MLflow is free under the Apache License 2.0. On Databricks, you pay for the compute and services your MLflow workflow uses, billed in Databricks Units. The main drivers are training compute, Model Serving endpoints, inference table logging, data profiling refreshes and storage. Batch scoring and right-sized compute keep the bill under control.
What are the main components of MLflow?
MLflow has four main parts on Databricks. Tracking records runs, parameters and metrics, while models package trained models with signatures as LoggedModel objects. The registry versions models in Unity Catalog and manages aliases. MLflow 3 adds GenAI features such as tracing, evaluation with LLM judges and a prompt registry for agents and LLM applications.
How do I deploy MLflow models in Databricks?
Register the model in Unity Catalog, then set an alias such as Champion on the approved version. For batch scoring, load the alias as a Spark function in a scheduled job. For real-time use, create a Model Serving endpoint that returns predictions over REST. Wrap promotion in a deployment job so every release is approved and recorded.
What is the difference between MLflow and Databricks MLflow?
MLflow is the open-source project you can host anywhere. Databricks MLflow is the managed version inside a Databricks workspace. It uses the same APIs but adds enterprise security, disaster recovery, a registry built on Unity Catalog, Model Serving, customer-managed key encryption and agent evaluation. With open source, you supply governance, hosting and serving yourself.
Does Databricks MLflow require Unity Catalog?
Tracking works without it, but Databricks recommends Unity Catalog for the model registry and labels the Workspace Model Registry as legacy. MLflow 3 sets the registry URI to databricks-uc by default. Unity Catalog adds lineage, audit logs and cross-workspace access, and models need a metastore that supports privilege inheritance, which covers metastores created after August 25, 2022.
What is the difference between the Workspace Model Registry and Unity Catalog?
The Workspace Model Registry is the older, legacy registry scoped to one workspace, with Staging and Production stages. The Unity Catalog registry names models as catalog.schema.model, works across workspaces and shares the same permissions, lineage and audit log as your data. It replaces stages with aliases and separate catalogs for each environment.
What is a model alias in Databricks MLflow?
A model alias is a named, movable pointer to one version of a registered model, such as Champion or Challenger. Serving code loads the model by its name plus the alias, so it always gets the version the alias points to. Promoting or rolling back a model then means moving the alias, with no code change.
What changed between MLflow 2 and MLflow 3?
MLflow 3, released June 10, 2025, made models first-class LoggedModel objects with their own IDs, so a run is no longer required to log one. The log_model call uses name instead of artifact_path. It also added deployment jobs on Lakeflow Jobs, and the registry now defaults to Unity Catalog on Databricks, plus GenAI tracing and evaluation.
Can MLflow track LLMs and AI agents?
Yes. MLflow 3 traces each step of an LLM or agent request, including retrieval, tool calls and model responses, so you can debug failures. It also evaluates answers with LLM judges and versions prompts in a prompt registry. On Databricks, these features connect with Custom Agents and Agent Evaluation for production GenAI applications.
How do I monitor model drift for MLflow models in Databricks?
Turn on inference tables for the serving endpoint so every request and response lands in a Delta table in Unity Catalog. Then create a data profile on that table with your training data as the baseline. The profile computes drift over time windows, and you set alerts for when inputs or predictions move past agreed thresholds.
Is MLflow still relevant?
Yes. MLflow 3.17.2 was released on October 21, 2026, and the Databricks documentation reports more than 30 million monthly downloads. MLflow 3 also added LoggedModel objects, deployment jobs and tracing for GenAI and agents. It remains the default lifecycle tool on Databricks, and the project ships new releases often under the Apache License 2.0.
Is MLflow production ready?
Yes, when it sits inside a governed setup. On Databricks, production use means registering models in Unity Catalog, requiring signatures, serving by alias, logging traffic to inference tables and promoting through deployment jobs. Tracking alone is not a production system, so the readiness depends on how you implement the registry, approvals and monitoring around it.
Does MLflow integrate with Spark?
Yes. MLflow can log Spark MLlib models, and its pyfunc flavor loads any registered model as a Spark user-defined function. That lets you score a full Delta table in parallel with one line, such as a spark_udf call on the Champion alias. Batch scoring jobs on Databricks commonly use this pattern for forecasting and risk models.
Can MLflow track deep learning models in Databricks?
Yes. MLflow autologging supports common deep learning frameworks such as TensorFlow, Keras and PyTorch Lightning, recording parameters, metrics and the trained model. You can log extra artifacts, such as plots or checkpoints, by hand. Registered deep learning models are governed in Unity Catalog like any other model and can be served on GPU endpoints through Model Serving.
Which is better, MLflow or Kubeflow?
They solve different problems. MLflow focuses on tracking experiments, packaging models and managing a registry, and it runs managed on Databricks. Kubeflow is a Kubernetes-based platform for running ML pipelines and training workloads on clusters you operate. Teams on Databricks usually choose MLflow, while teams built around their own Kubernetes stack may prefer Kubeflow.
Is MLflow fully open source?
Yes. MLflow is released under the Apache License 2.0, and anyone can run it on their own infrastructure. Databricks-managed MLflow adds platform features on top, such as Unity Catalog governance, disaster recovery, customer-managed key encryption and Model Serving. Those additions belong to the Databricks platform, while the core MLflow APIs stay open source and shared.
What are the benefits of using MLflow with Databricks?
You get tracking, a registry and serving without hosting any of them yourself. Models live in Unity Catalog under the same permissions, lineage and audit log as your data. Aliases make promotion and rollback simple, inference tables capture production traffic, and deployment jobs record every approval. Security and disaster recovery come from the platform as well.
How does the MLflow model registry work in Databricks?
In Databricks, the MLflow model registry is built on Unity Catalog. Each model has a three-level name, catalog.schema.model, and every registration creates a new numbered version. Aliases such as Champion point serving code to a version, while separate catalogs represent environments. Privileges decide who can create, load or manage each model, and every action is audited.