TL;DR
Small language models win on narrow, high-volume, private or offline tasks, while frontier LLMs still win on open-ended reasoning and broad knowledge. Here, an SLM means up to about 15B dense parameters, or a mixture-of-experts model with active parameters in that range. Strong open options checked on November 3, 2026 include Gemma 4, Qwen3.5-9B, Phi-4-mini, Ministral 3, Granite 4.2, SmolLM3-3B and LFM3. On hosted APIs, Claude Haiku 5.5 input costs $0.10 per million tokens, one fortieth of Claude Opus 5.5 at $4. Self-hosting removes per-token fees but adds GPU and operations cost, so price the whole stack. We default to the small model, test it on your own traffic and escalate to a frontier model only when it fails.
Key Takeaways
- Small language models are compact transformer models, and our line sits at about 15B dense parameters or a MoE with that many active.
- Gemma 4, Phi-4-mini and LFM3 show the spread, from a 1.73B edge model to a 26B MoE with only 3.8B parameters active.
- Hosted small tiers cut input prices hard, since Claude Haiku 5.5 costs $0.10 per million input tokens while Claude Opus 5.5 costs $4.
- Pick an SLM when work is narrow, high-volume, latency-bound, private or offline, but keep a frontier model for open-ended reasoning and long planning.
- At 4-bit, budget about 0.5 bytes per parameter before overhead, so LFM3 fits in about 1 GB and an 8B model in about 4 GB.
- Kanerika builds SLM systems on governed retrieval, the same layer that made one investment bank’s document and database retrieval 43% faster.
Fifty Thousand Tickets a Day, One Expensive Model
Picture a support team that sends every incoming ticket to a frontier model. The model reads each message, tags the intent and then routes it to a queue. At 50,000 tickets a day it works well, but the invoice grows with every ticket.
Look at what the model is actually doing, though. It picks one label from a fixed list, then repeats that thousands of times an hour. That job needs consistency and speed far more than it needs broad world knowledge.
That gap between the task and the tool is where small language models earn their place. This guide explains what they are, which seven matter, what they cost and when to choose one.
What Is a Small Language Model?
A small language model is a language model sized to run on modest hardware while still handling real language tasks. It uses the same transformer design as large models, but with fewer parameters, tighter training data or both.
Parameters are the learned weights a model uses to predict the next token. So fewer weights mean less memory, faster answers and lower running cost. The trade, however, is a narrower store of knowledge and a lower ceiling on complex reasoning.
Phi-4-mini, for instance, has 3.8 billion parameters, small enough for one workstation GPU, plus a 128K-token context window.
Where the Size Line Sits
No standards body defines how small a small language model must be. Published guides disagree, with cut-offs at 7B, about 10B and 30B parameters, so any single number is a convention.
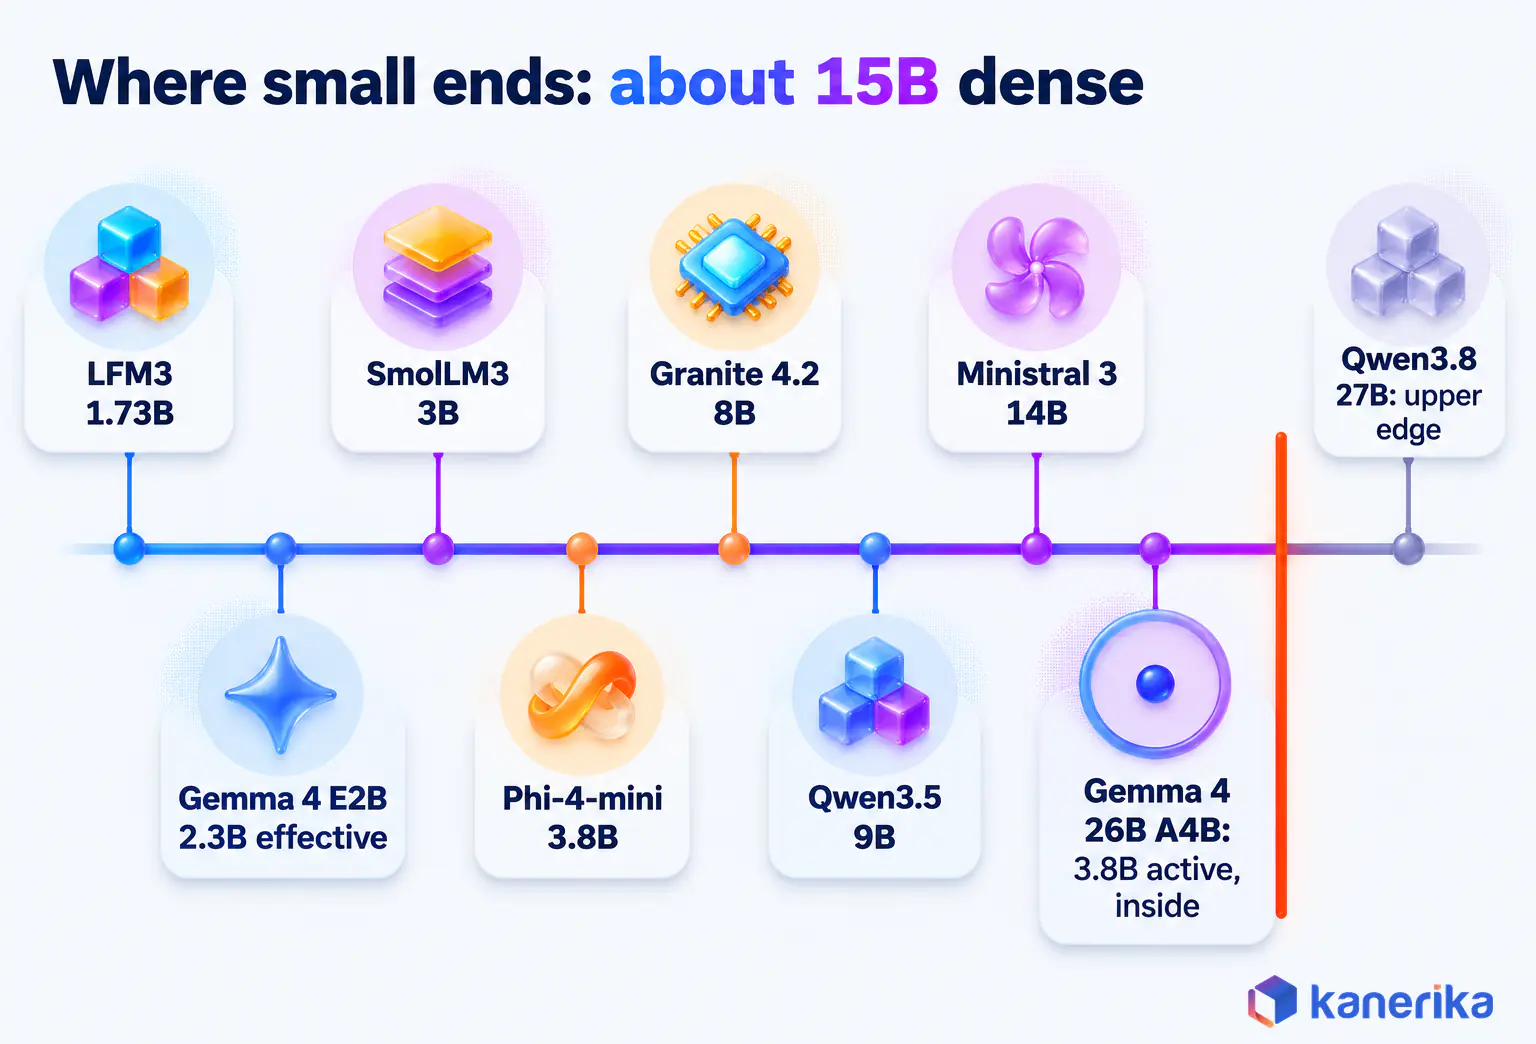
This guide uses one line throughout: up to about 15B dense parameters, or a mixture-of-experts (MoE) model whose active parameters fall in that range. The model must also run on one GPU, a laptop or a phone.
The MoE clause matters because total and active size can differ a lot. Gemma 4 26B A4B holds 25.2B parameters in total, yet only 3.8B are active for each token. Qwen3.8-27B, a dense model, sits just past the line as the upper edge of the small class.
How SLMs Relate to LLMs
Small and large models share an architecture, so the differences are matters of degree.
- Cost and speed. Fewer parameters mean fewer calculations per token, so answers arrive faster and cost less to serve.
- Knowledge breadth. A large model stores more facts, so it covers more topics without help from retrieval.
- Deployment. An SLM can run on a laptop, a phone or a private server, while frontier models mostly live behind vendor APIs.
For a side-by-side table across cost, accuracy and governance, see our full comparison of SLMs vs LLMs.
How Small Language Models Are Built
Small models come from five main routes, and most current releases combine two or three of them. All five start from the same transformer architecture that large models use, so what changes is how the weights are produced, compressed or activated.
| Technique | What it does | Example |
|---|---|---|
| Knowledge distillation | A small student learns from a larger teacher’s outputs | A ticket classifier trained on frontier-model labels |
| Pruning | Drops the least useful weights or layers | Dropping layers from a model, then retesting |
| Quantization | Stores each weight in fewer bits, such as 4-bit instead of 16-bit | GGUF 4-bit builds for laptops |
| Curated-data training from scratch | Trains a small model on carefully selected data | SmolLM3-3B on 11.2T tokens; the Phi family |
| Small-active MoE | Routes each token through a few expert blocks | Gemma 4 26B A4B, 3.8B active of 25.2B |
Distillation, in the first row, is the oldest route. Hinton, Vinyals and Dean described it in Distilling the Knowledge in a Neural Network, where a small student copies a larger teacher’s outputs.
Pruning and quantization shrink a model that already exists, while curated data and expert routing shape it from the start. Quantizing an 8B model to 4-bit, for example, cuts its weight memory to a quarter, so tests must confirm the quality.
Key Characteristics: Size, Memory, Speed and Data
Four numbers describe a small language model in practice: parameter count, memory footprint, speed and the data it needs.
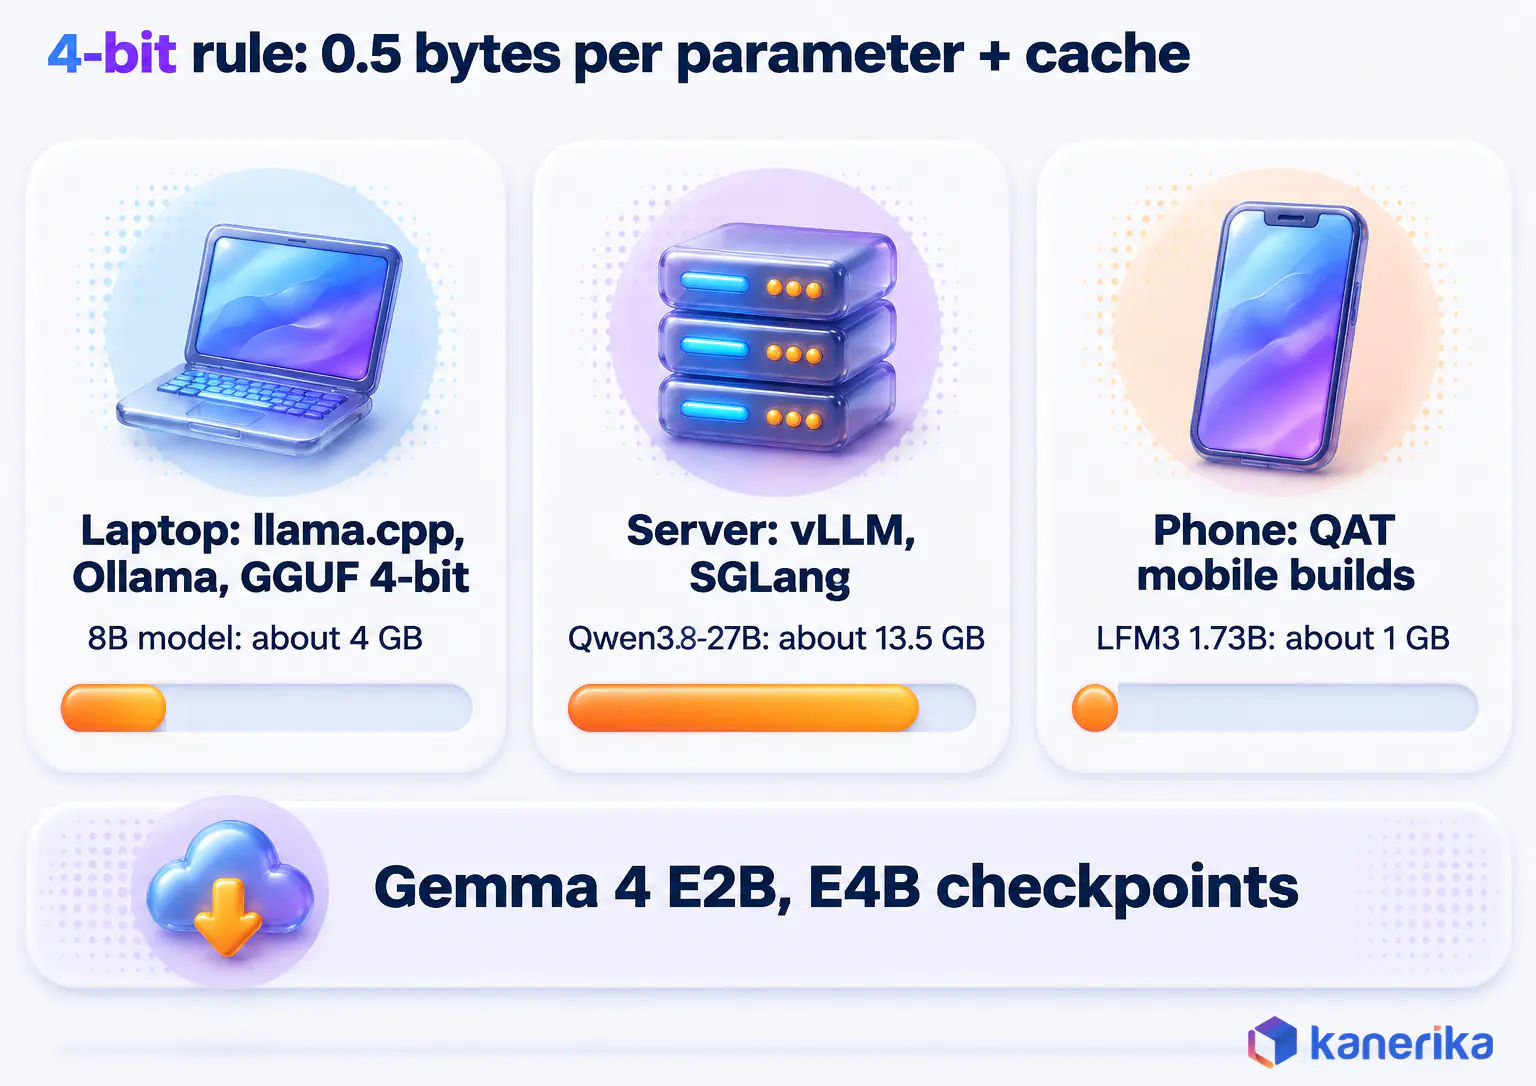
Memory is the easiest to estimate, since each parameter takes 2 bytes at 16-bit and about 0.5 bytes at 4-bit before overhead. So an 8B model needs about 16 GB for its weights at 16-bit and about 4 GB at 4-bit. LFM3, at 1.73B parameters, runs in about 1 GB of memory at 4-bit, which is why it fits on phones.
| Characteristic | Range among the top 7 | Why it matters |
|---|---|---|
| Parameters | 1.73B (LFM3) to 14B (Ministral 3), with Qwen3.8-27B as the upper edge | Sets memory, speed and knowledge breadth |
| Weight memory at 4-bit | About 1 GB for 1.73B, 4 GB for 8B, 7 GB for 14B, 13.5 GB for Qwen3.8-27B | Decides phone, laptop or server |
| Native context | 64K (SmolLM3-3B) to 262,144 tokens (Qwen3.5-9B) | Long inputs grow the cache, not the weights |
Speed follows from size, because a small model reads fewer weights per token. It therefore answers faster on the same hardware, which suits high-volume inference workloads.
Data needs run the other way, since a small model has less room for general knowledge and leans on task examples and retrieved documents.
Advantages of Small Language Models
The advantages of small language models all come from doing less computation per request. That one fact then shows up as lower cost, faster replies and more choice about where the model runs.
- Lower cost per request. Hosted small tiers price input at a fraction of frontier rates, and a self-hosted SLM needs one GPU. In the ticket example below, input on Haiku 5.5 runs about $5 a day against about $200 on Opus 5.5.
- Faster responses. Less work per token means replies arrive fast enough for autocomplete, chat and inline suggestions. A support agent waiting on a suggested reply mid-conversation is the person who notices.
- Data control. An SLM can run inside your own network, which makes private LLM deployment practical under strict residency rules. A hospital, for example, can run one over patient notes that may not leave its own network.
- Task fit after fine-tuning. A small model tuned on your labeled examples learns your formats, so a claims team can teach it the exact codes its system expects.
- Offline and edge use. Models such as Gemma 4 E2B are built for devices, so edge AI keeps working in a plant with no signal.
Top 7 Small Language Models in Late 2026
We checked the seven models below at their Hugging Face model cards on November 3, 2026. Each one falls inside our size line or sits at its edge, while each ships open weights.
Open-weight frontier models such as Mistral Large 4, Qwen3.8-Max and DeepSeek V4 are too large for this list. Our guide to open-source LLMs covers that class instead.
| Model | Vendor | Sizes | Native context | License | Best fit |
|---|---|---|---|---|---|
| Gemma 4 | E2B, E4B, 12B, 26B A4B (MoE) | 128K (E2B, E4B); 256K (12B, 26B) | Apache 2.0 | On-device and multimodal work | |
| Qwen3.5-9B, Qwen3.8-27B | Alibaba | 9B; 27B dense | 262,144, extensible to about 1M | Apache 2.0 | Multilingual, long documents |
| Phi-4-mini | Microsoft | 3.8B | 128K | MIT | Reasoning on tight hardware |
| Ministral 3 | Mistral AI | 3B, 8B, 14B | 256K | Apache 2.0 | One family at three price points |
| Granite 4.2 | IBM | 3B, 8B, 30B | 128K on 8B (512K extension) | Apache 2.0 | Tool calling in enterprise agents |
| SmolLM3-3B | Hugging Face | 3B | 64K, 128K with YaRN | Apache 2.0 | Fully open, auditable recipe |
| LFM3 | Liquid AI | 1.73B (plus 2B VL, Omni, Audio) | 256K | LFM Open License v1.0 | Edge devices and small agents |
1. Gemma 4 (Google)
Gemma 4 covers the widest size range of the seven. The E2B and E4B models target phones and laptops, with 2.3B and 4.5B effective parameters (5.1B and 8B counting embeddings). Above them sit a 12B dense model and the 26B A4B MoE, while a 31B dense model falls outside our line.
All sizes accept text and images, while E2B, E4B and 12B also take audio, so Gemma 4 suits multimodal AI on devices. Context also runs to 128K tokens on the small pair and 256K above. The Gemma 4 model card lists Apache 2.0, pre-training on 140+ languages and out-of-the-box support for 35+.
Pick this if you want one family that runs from a phone up to a single GPU and also takes images or audio.
2. Qwen3.5-9B and Qwen3.8-27B (Alibaba)
Qwen is the pick when inputs are long or arrive in many languages. Qwen3.5-9B has 9B parameters, a native context of 262,144 tokens extensible to 1,010,000, and support for 201 languages and dialects.
That window can take a full contract bundle in one prompt, so a reviewer can ask about clauses across every document at once.
Qwen3.8-27B is a dense model with the same 262,144-token native window and support up to 1M tokens. Both use Apache 2.0, so the 27B model is an easy next test when a 9B model falls just short. Both model cards also list a vision encoder, so the two models accept images and video alongside text.
Pick this if your inputs are long, such as contract bundles, or arrive in many languages.
Datasheet
KlarityIQ: Document Intelligence Agent
Specs and capabilities for KlarityIQ, Kanerika’s agent for extracting and searching detail across enterprise documents, the workload behind document extraction and RAG answering.
View the Datasheet →3. Phi-4-mini (Microsoft)
Phi-4-mini-instruct packs 3.8B parameters and a 128K context window under the MIT license. Microsoft built the Phi family around curated training data with a focus on reasoning.
Two siblings, Phi-4-mini-reasoning and Phi-4-mini-flash-reasoning, also ship under MIT for step-by-step reasoning work.
Pick this if you need reasoning on tight hardware and also want the simple MIT license.
4. Ministral 3 (Mistral AI)
Ministral 3 comes in 3B, 8B and 14B sizes, each with Instruct and Reasoning variants. All of them also carry Apache 2.0 and a 256K context window.
That spread lets a team test one family at three price points. The 14B model sits at the top of our size line, while the 3B model suits tight memory budgets.
Pick this if you want to test 3B, 8B and 14B from one family before you commit to a size.
5. Granite 4.2 (IBM)
IBM released Granite 4.2 on August 25, 2026 in 3B, 8B and 30B sizes. The 8B dense model has a 128K native context as well as an extension to 512K, under Apache 2.0.
Granite 4.2 also supports thinking and non-thinking modes and reasoning-augmented tool calling. Those features suit enterprise agents that call internal APIs, though the 30B size sits outside our line.
Pick this if your agent calls internal APIs, because you get reasoning-augmented tool calling under Apache 2.0.
6. SmolLM3-3B (Hugging Face)
SmolLM3-3B is the most transparent model on the list. Hugging Face pretrained it on 11.2 trillion tokens and then published the full training recipe under Apache 2.0.
Its default context is 64K tokens (65,536), and YaRN scaling stretches it to 128K. When a team needs to audit how a model was built, or reproduce it, this is the place to start.
Pick this if you must audit or reproduce how the model was trained.
7. LFM3 (Liquid AI)
LFM3-1.7B, published in October 2026, is the smallest model here at 1.73B parameters. Even so, it handles a 256K context and runs in about 1 GB of memory at 4-bit.
Liquid AI also ships VL, Omni and Audio variants at about 2B parameters for vision-language models and speech work. Check the terms first, because LFM3 uses the LFM Open License v1.0 instead of Apache 2.0 or MIT.
Pick this if the model must fit in about 1 GB on a device, and legal can also clear a custom license.
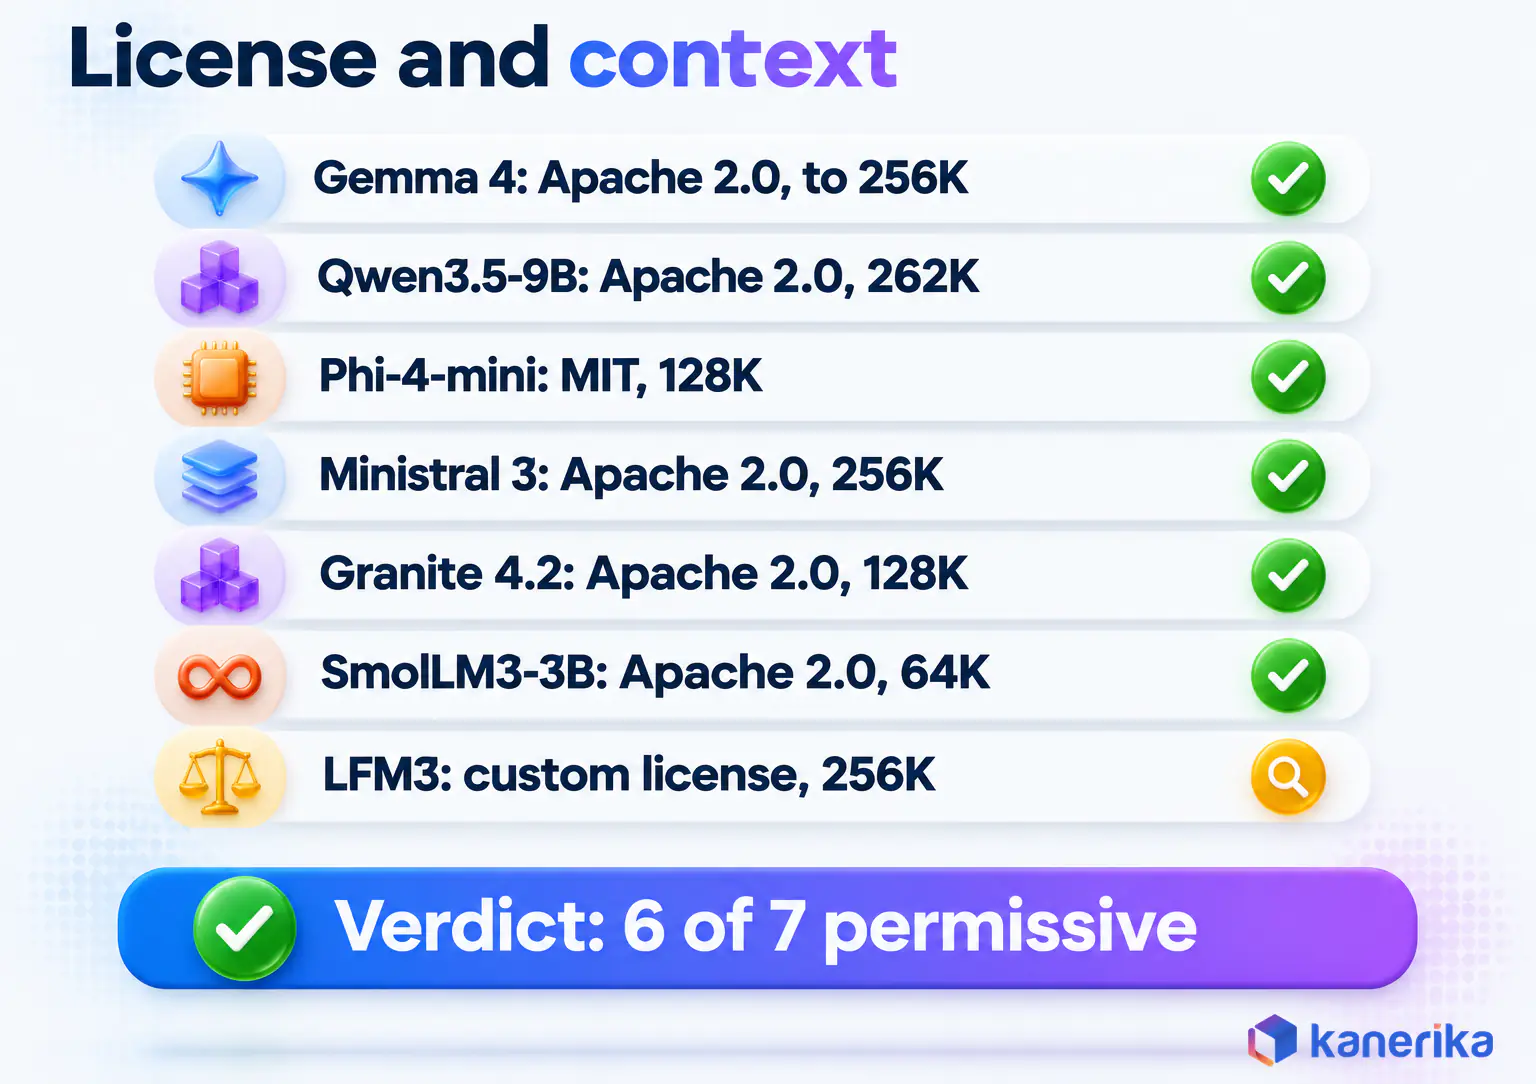
That leaves six of the seven under Apache 2.0 or MIT, so LFM3 is the only one that needs a license read before commercial use.
Small Language Model Use Cases
Small language models do best on jobs with a clear input, a clear output and a lot of repetition. The six workloads below fit that shape, since each runs at high volume.
- Ticket and intent classification. The model picks one label from a fixed list, then a router sends the ticket to the right queue.
- Document extraction. An SLM pulls fields such as dates, amounts and party names from invoices or contracts into a fixed schema. Validation rules then flag any malformed field.
- RAG answerer over company data. In retrieval-augmented generation, a search step finds the passages and the model writes the answer, so its own knowledge matters less.
- On-device assistant. A model like Gemma 4 E4B can answer questions from a manual on a tablet when the network drops out.
- Agent tool calls. In an AI agent architecture, many steps are small choices about which tool to call. A small model with tool calling, such as Granite 4.2, handles those quickly.
- Multilingual support. Gemma 4 supports 35+ languages out of the box, and Qwen3.5-9B lists 201 languages and dialects, so one small model can triage messages across regions.
Across all six, the task is narrow enough to test against known answers. The volume is also high enough that cost and speed decide the business case.
Which Small Model to Test First for Each Use Case
The table below pairs each workload with a first model to test and the signal that should send a request up to a frontier model.
| Use case | Output | First model to test | Escalate when |
|---|---|---|---|
| Ticket and intent classification | One label from a fixed list | The smallest model that passes your task set, such as Ministral 3 3B | Confidence is low or the label is not on the list |
| Document extraction | Fields in a fixed schema | Qwen3.5-9B for long documents | A field fails validation |
| RAG answerer | Short answer from retrieved passages | Any of the seven, since retrieval supplies the facts | The passages do not answer the question |
| On-device assistant | Answers offline | Gemma 4 E4B or LFM3 | The device is back online and the question goes beyond the manual |
| Agent tool calls | Which tool to call, with arguments | Granite 4.2 8B | The step needs a long multi-step plan |
| Multilingual triage | Language plus intent label | Qwen3.5-9B or Gemma 4 | The language is outside the model card’s list |
When to Choose an SLM Over a Frontier LLM
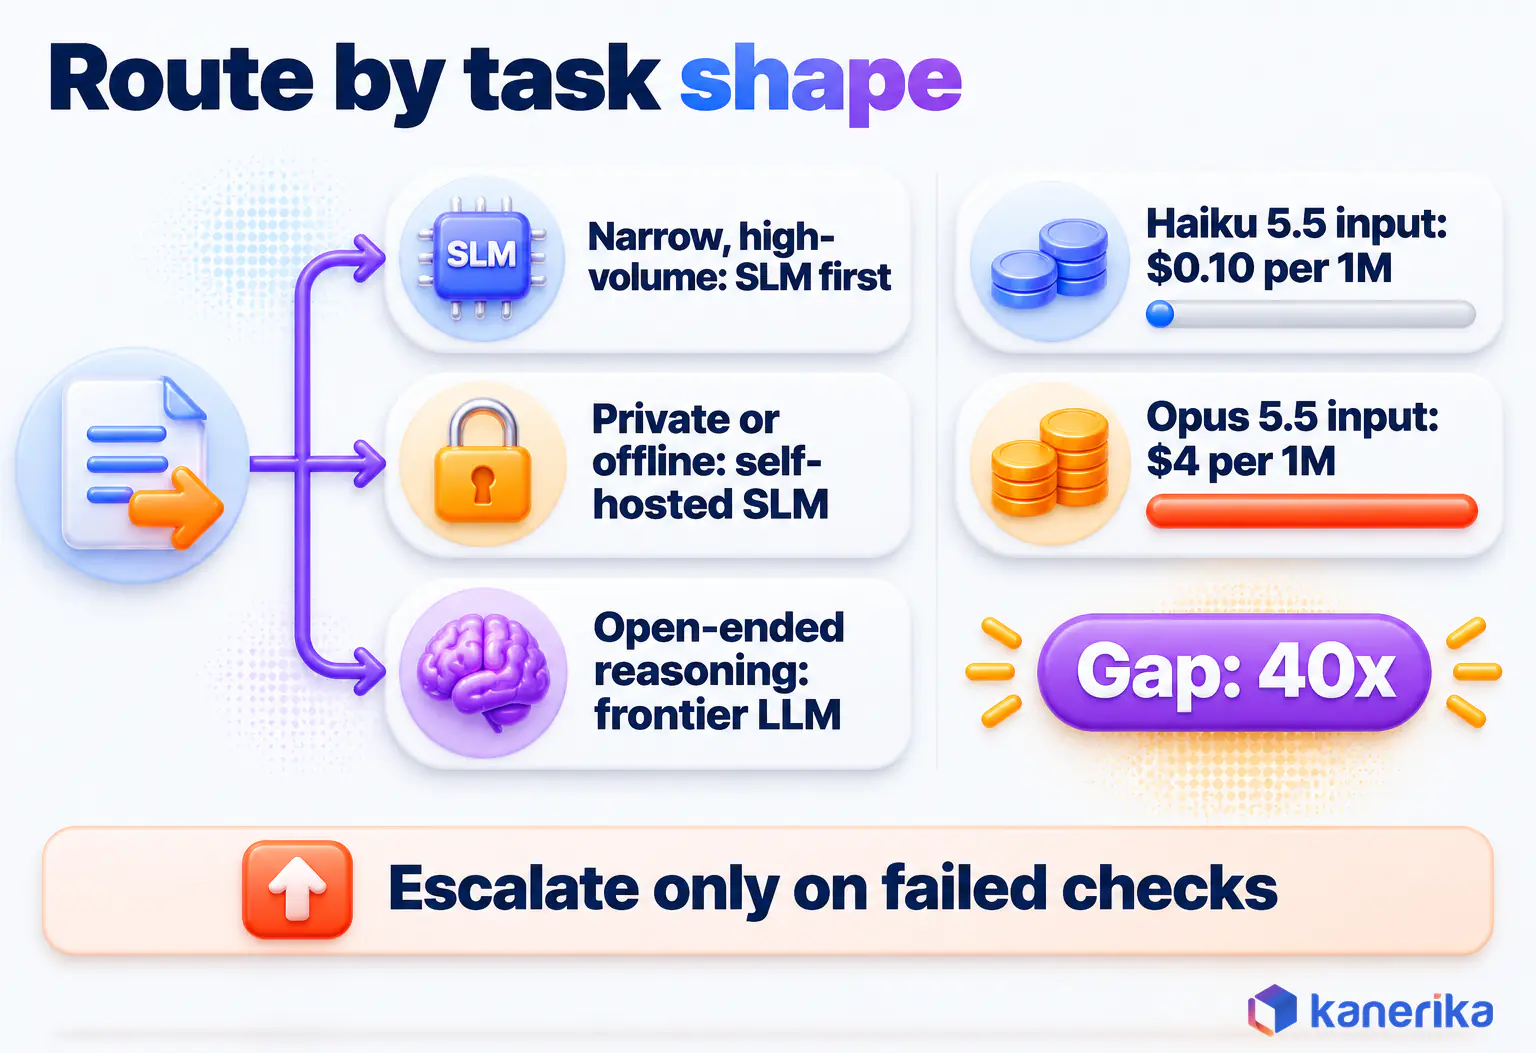
The choice between a small model and a frontier model comes down to the shape of the task. A narrow, repeated job favors the small model, while an open-ended, knowledge-heavy job favors the large one.
| Signal in the task | Choose | Why |
|---|---|---|
| Narrow task with a fixed output, such as labels or fields | SLM | Easy to test against known answers |
| Thousands of calls a day | SLM | Per-request savings multiply |
| Data must stay in your network | Self-hosted SLM | Weights run on your own servers |
| No network on site | On-device SLM | Runs on a laptop or phone |
| Open-ended reasoning or research | Frontier LLM | Higher reasoning ceiling |
| Long multi-step planning | Frontier LLM | Keeps a plan on track across many steps |
Many production systems use both, so the real question is which share of traffic each model gets. For the frontier side of that split, our ranking of top LLMs compares current large models on price and context.
Our position is direct. When you can write down the correct answer for a sample of requests, make the small model the default and test it first.
An SLM is the wrong choice only when the task needs open-ended reasoning, long planning or broad knowledge that retrieval cannot supply. For every other task, start small and let the frontier model earn its cost. The frontier model then becomes the fallback.
The Hosted Small Tier and What It Costs
Vendors also sell small, fast models through their APIs. They do not publish parameter counts, though, so treat these as a price tier rather than a size class.
| Model | Tier | Input per 1M tokens | Output per 1M tokens |
|---|---|---|---|
| Claude Haiku 5.5 | Small | $0.10 | $0.50 for prompts up to 100K; $2.50 above |
| GPT-6 Luna | Small | $0.10 ($0.01 cached) | $0.50 |
| Gemini 3.8 Flash | Small | $0.75 through Dec 31, 2026, then $1.50 | $3.75, then $7.50 |
| GPT-6.1 Sol | Frontier | $2 | $10 |
| Claude Opus 5.5 | Frontier | $4 | $20 |
Per the Anthropic pricing page, Haiku 5.5 input costs one fortieth of Opus 5.5, a 40x gap. Similarly, the OpenAI pricing page puts GPT-6 Luna input at one twentieth of GPT-6.1 Sol.
For the support scenario, if each ticket uses about 1,000 input tokens, 50,000 tickets make 50 million tokens a day. That comes to about $200 of input on Opus 5.5 but about $5 on Haiku 5.5, before output.
AWS customers also have a comparable tier in Amazon Nova. Self-hosting an open SLM removes per-token fees, but GPUs, monitoring and on-call staff still cost money, so compare the full stack.
Hybrid Routing: SLM First, Frontier on Escalation
Hybrid routing sends every request to the small model first and escalates only the hard ones. The router decides by task type, by the small model’s confidence, or by whether its output passes validation.
When the SLM must return JSON with a known schema, a validator rejects malformed answers and then forwards those requests to the frontier model.
An LLM gateway usually holds this logic, along with guardrails and logging. Because the small model is the default, the share of traffic it keeps decides how much of the price gap you actually capture.
Kanerika Service
LLM Development Services
Kanerika designs, adapts and deploys language models, small and large, with retrieval, routing and governance built in for enterprise workloads.
Explore LLM DevelopmentDeploying SLMs On-Premises and at the Edge
Where an SLM runs decides which tools you need, because laptops, servers and phones each have a standard toolchain.
On a laptop, for example, llama.cpp and Ollama run quantized GGUF files, usually at 4-bit. A developer can then pull an 8B model, about 4 GB at that precision, and test it with no network connection.
On a server, by contrast, vLLM and SGLang handle many concurrent users through batching and careful cache management. Qwen3.8-27B needs about 13.5 GB for its weights at 4-bit (the memory lanes above show all three targets). That fits on one data center GPU with room for cache. Our comparisons of vLLM vs Ollama and SGLang vs vLLM cover the trade-offs.
On phones, vendors ship mobile builds trained with quantization in mind. For example, Google publishes quantization-aware training (QAT) mobile checkpoints for Gemma 4 E2B and E4B on Hugging Face.
Whatever the target, plan for the cache as well as the weights. A long context window can need more memory than the quantized weights themselves, so size hardware for the longest prompt you expect.
Treat every self-hosted endpoint like an internal API, so it gets authentication, rate limits and logs from day one. Then name an owner for runtime upgrades, since each new version of vLLM or llama.cpp calls for a fresh run of your task set.
Kanerika Service
MLOps Consulting Services
Kanerika’s MLOps consulting helps enterprise AI teams keep models, small or large, running reliably in production after the pilot ends.
Explore MLOps ConsultingFine-Tuning and Distillation for SLMs
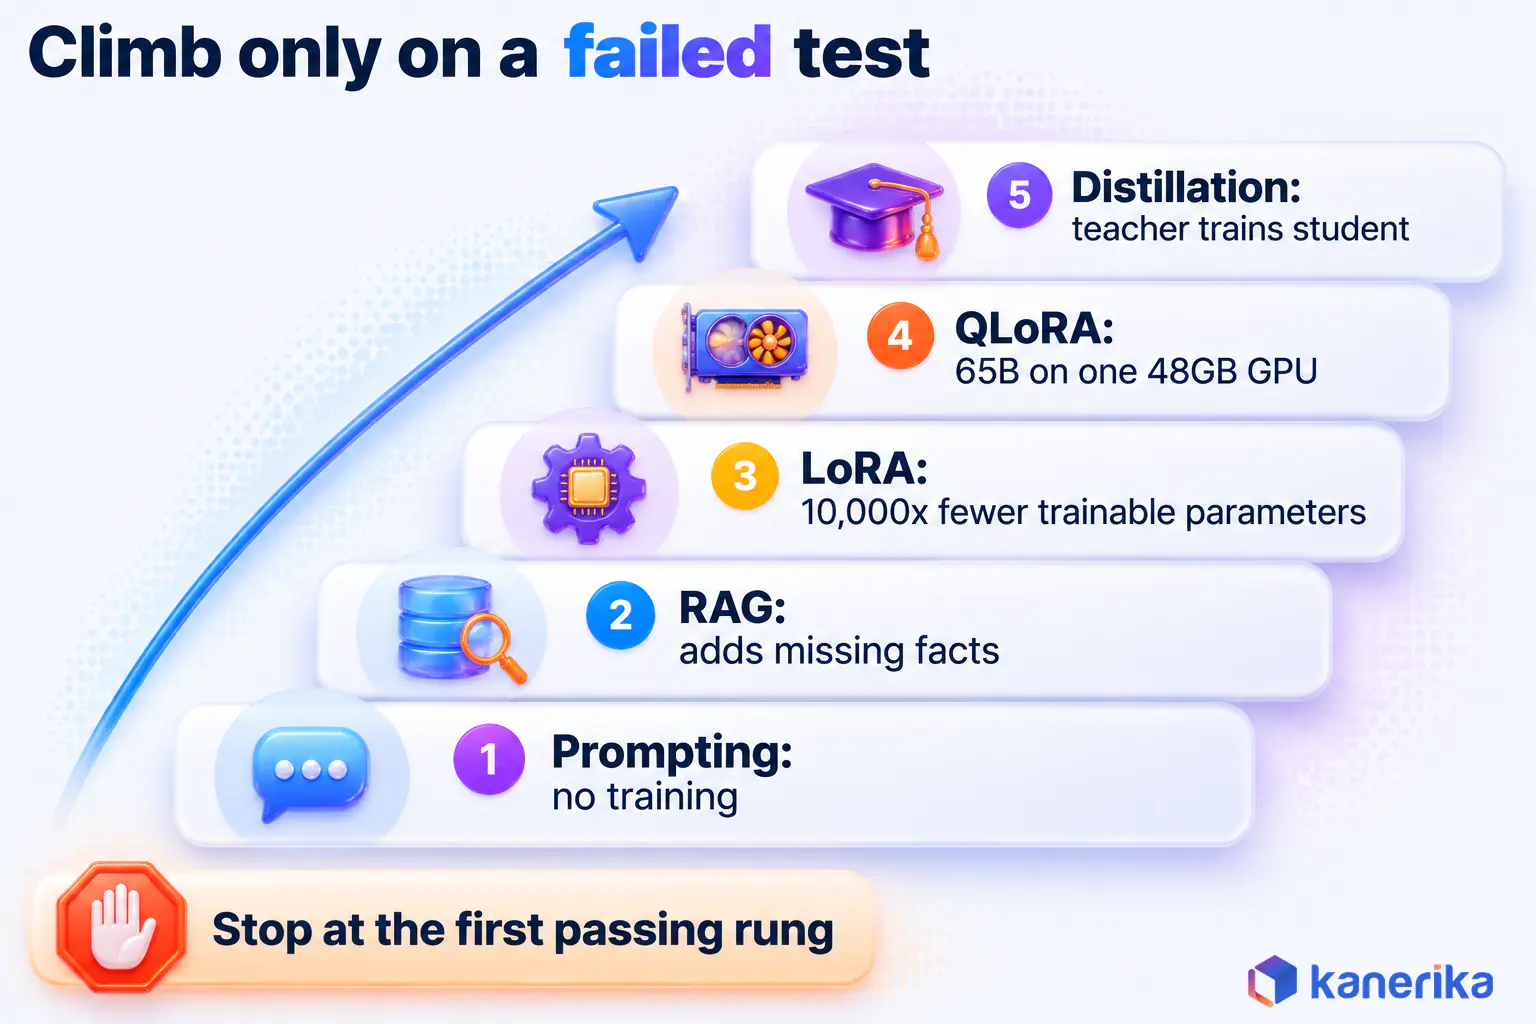
Adapting a small model works like a ladder, so start on the cheapest rung and climb only when tests show a gap.
- Prompting. Clear instructions and a few worked examples in the prompt. Try this first, since it needs no training at all.
- Retrieval. Add RAG when the model lacks facts about your business. Our guide to RAG vs fine-tuning explains when each approach fits.
- LoRA. Train small adapter weights on your labeled examples. The LoRA paper reports 10,000 times fewer trainable parameters and 3 times less GPU memory than fully fine-tuning GPT-3 175B.
- QLoRA. Train the same adapters over a frozen 4-bit base model. The QLoRA paper fine-tuned a 65B model on a single 48GB GPU, so an SLM needs far less.
- Distillation. Train the small model on outputs from a larger teacher model. This takes the most effort, so it pays off when one narrow task runs at very high volume.
LoRA and QLoRA belong to the wider family of parameter-efficient fine-tuning methods. On a small model the adapters are tiny, so one base model can serve several tasks with swappable adapters. Each rung up also adds labeled data to collect and a model version to maintain, so stop at the first rung that passes your tests.
Synthetic data also closes the label gap. A frontier model drafts and labels training examples, people review a sample, and then the SLM learns from the result. Check the teacher model’s license and terms before you use its outputs for training.
How to Evaluate a Small Language Model
Public leaderboards show how a model does on someone else’s test, while your own task set shows how it does on your work. So build that set first and treat benchmarks as a second opinion.
- Collect real examples. Pull 200 to 500 requests from real traffic, covering common cases as well as awkward ones. That range shows patterns but stays small enough to label by hand. At an investment bank, we saw requests split between detail buried in long RFI documents and figures held in databases. So cover every request type like that in your set.
- Write the expected answer. Label each example with the correct output, or with a rubric when several answers are acceptable.
- Score two or three candidates. Run a shortlist from the top 7, then compare accuracy on your set.
- Track running metrics. Measure latency, cost per 1,000 requests, refusal rate and format-error rate as well as accuracy.
- Check public benchmarks last. Use them to break ties and also to spot weaknesses that your own set missed.
Then keep the set after launch and re-run it on every model or prompt change, as our LLM evaluation framework describes. That way, regressions show up before users see them.
Limitations and Risks of Small Language Models
Small models have real limits, and most failures come from asking them to do a large model’s job.
- Reasoning ceiling. Long chains of logic and open-ended planning still favor frontier models, so route those requests up.
- Thinner world knowledge. A small model stores fewer facts, so outside the prompt it can give confident wrong answers. Ground it with retrieval first, and see our guide to LLM hallucination for mitigation patterns.
- Bias. Small models inherit bias from their training data and from any teacher model, so test outputs across customer groups and languages.
- License terms. Apache 2.0 and MIT are simple, but custom licenses such as the LFM Open License v1.0 add conditions. Have legal review the terms before a commercial launch.
- Endpoint security. A self-hosted model is a new internal service with its own attack surface, from prompt injection to exposed ports. Our LLM security guide covers the controls. For an investment bank, we chose to enforce access inside the retrieval layer. Controls outside it had reopened a compliance question with every new retrieval path.
Each of these risks has a known control, so together they keep a small model inside the work it does well.
Talk to Kanerika
Planning a Private SLM Deployment?
Talk to Kanerika about shortlisting small models, building an eval set from your own traffic and putting the right controls around a self-hosted endpoint.
Talk to an Expert →How Kanerika Builds Solutions on Small Language Models
At Kanerika, we treat model size as a design decision made after the task and the data are understood. The model is one part of a system that also includes retrieval, access control, routing and monitoring.
Governed retrieval is often the hardest part, and it is where our KlarityIQ document intelligence agent and our Karl data-insights agent come in. For an investment bank, KlarityIQ handled unstructured RFI documents, while Karl queried structured databases behind the same chat interface.
Role-based access control was applied at the retrieval layer, so each user saw only what their role allowed. The bank saw 43% faster information retrieval across documents and databases and 100% role-based compliance at the point of retrieval. Workforce efficiency also improved by 35%.
The case study does not name the model behind it. What carries over is the pattern, because an SLM deployment plugs into the same governed retrieval layer.
Six Stages of a Kanerika SLM Engagement
A typical engagement runs in six stages, and each one ends with a check before the next begins.
- Task and data audit. We find the narrow, high-volume requests and the data that may not leave the network. At the investment bank, we found analysts reading long RFI documents by hand and waiting on specialists for routine database queries.
- Model shortlist and eval set. We score two or three candidates from the top 7 on the client’s own examples.
- Retrieval and access control. We build governed retrieval with RBAC at the retrieval layer through our RAG development practice. For the bank, RBAC at that layer kept compliance intact as the architecture scaled to further sources.
- Adaptation. We start with prompting and RAG, then add LoRA only when the eval set shows a gap.
- Deployment and routing. We self-host on vLLM or use a hosted small tier, escalating hard requests to a frontier model.
- Monitoring. We track cost per request, format errors and drift through LLMOps observability.
Case Study
43% Faster Document Retrieval for an Investment Bank
An investment bank put its RFI documents and enterprise databases behind one governed chat, reaching 43% faster information retrieval and 100% role-based compliance at the point of retrieval.
Read the Case Study →For document-processing workflows, FLIP adds automated pipelines around the model, while our generative AI services cover the wider roadmap.
So when should you use a small language model? Use one when the task is narrow, frequent, private or offline. Test it on your own data, and keep a frontier model on call for the rest.
Frequently Asked Questions
What is a small language model?
A small language model is a compact transformer model that runs on modest hardware such as one GPU, a laptop or a phone. In this guide, that means up to about 15B dense parameters, or a mixture-of-experts model with active parameters in that range. SLMs suit narrow, high-volume tasks where cost, speed and data control matter.
How many parameters does a small language model have?
There is no official threshold, and published guides use cut-offs of 7B, about 10B or 30B parameters. This guide draws the line at about 15B dense parameters, or a mixture-of-experts model whose active parameters fall in that range. The strongest current options span LFM3 at 1.73B parameters up to Ministral 3 at 14B.
Can you fine-tune a small language model?
Yes, and small models are cheap to fine-tune. LoRA trains small adapter weights, and its authors report 10,000 times fewer trainable parameters than a full GPT-3 175B fine-tune. QLoRA trains adapters over a frozen 4-bit base and fine-tuned a 65B model on one 48GB GPU, so a small model needs far less hardware.
What is a small language model for education?
In education, a small language model can power tutoring, feedback and quiz tools that run on school laptops or inside a school’s own network. That keeps student data local and cuts the cost of each request. A model tuned on a curriculum gives consistent explanations, while teachers still review outputs because small models make confident mistakes.
Are small language models safe for regulated or private data?
They can be, because an SLM can run entirely inside your own network, so prompts and documents never reach a vendor. Safety still depends on the controls around the model, including authentication, role-based access at the retrieval layer, logging and output checks. Review the license too, since some models use custom terms rather than Apache 2.0 or MIT.
What is the difference between an SLM and an LLM?
An SLM has fewer parameters, so it costs less to run, answers faster and can be deployed on a laptop, a phone or a private server. An LLM stores broader knowledge and handles open-ended reasoning and long multi-step planning better. Many teams use both, sending routine requests to the SLM and escalating hard ones to a frontier model.
What is an example of a small language model?
Phi-4-mini from Microsoft is a common example, with 3.8B parameters, a 128K context window and an MIT license. Others include Google’s Gemma 4 E2B and E4B for phones and laptops, Qwen3.5-9B from Alibaba, Ministral 3 from Mistral AI, IBM Granite 4.2, SmolLM3-3B from Hugging Face and LFM3 from Liquid AI.
Are small language models AI?
Yes. Small language models are AI systems built on the same transformer architecture as large language models, trained to predict the next token from patterns in text. They are generative AI in the same sense as the large chat assistants, only smaller. Size changes cost, speed and knowledge breadth, while the underlying technique stays the same.
Where are small language models used?
Common uses include ticket and intent classification, document field extraction, answering questions over company data with retrieval, on-device assistants for offline field work, tool selection inside AI agents, and multilingual message triage. These jobs share a clear input, a clear output and high volume, so lower cost and faster responses pay off on every single request.
Are SLMs cheaper to run?
Usually, yes. On hosted APIs, Claude Haiku 5.5 charges $0.10 per million input tokens against $4 for Claude Opus 5.5, one fortieth of the price. Self-hosted SLMs avoid per-token fees and fit on a single GPU, but GPUs, monitoring and operations staff still cost money, so compare the full stack before you decide.
What is the difference between RAG and an SLM?
An SLM is a model, while retrieval-augmented generation is a technique that feeds a model relevant passages from your documents at query time. The two work well together. RAG supplies the facts a small model lacks, and the SLM writes the answer from those passages, which keeps answers grounded and lets a cheaper model handle knowledge-heavy questions.
Can a small language model run on a laptop or phone?
Yes. At 4-bit precision a model needs about 0.5 bytes per parameter before overhead, so LFM3 at 1.73B parameters runs in about 1 GB and an 8B model needs about 4 GB. Laptops run these models through llama.cpp or Ollama, and Gemma 4 E2B and E4B ship quantization-aware mobile checkpoints for phones.
Is DeepSeek an SLM or LLM?
DeepSeek’s V4 models are large language models. They are served as hosted models with a 1M-token context window, and they belong to the open-weight frontier class rather than the small class. Teams that need an open model on modest hardware should look at the small models in this guide instead, such as Qwen3.5-9B or Ministral 3.