TL;DR
AI sentiment analysis uses NLP and machine-learning models, including large language models (LLMs), to label the opinion in text as positive, negative, neutral or mixed. It works as a pipeline that cleans text, turns words into numbers, classifies them and tags the topic of each opinion.
The results then flow into dashboards, alerts and routing rules that teams act on. Because context-aware models read whole sentences, they catch sarcasm and negation that word-list tools such as VADER miss. Benchmarks show over 90% accuracy on clean sentences, but real tickets score lower, so test on your own data. Value comes when each score drives a named decision, such as which complaint a manager sees first.
Key Takeaways
- AI sentiment analysis labels opinion in text as positive, negative, neutral or mixed, often per topic or aspect.
- Every system runs the same pipeline of collecting, cleaning, embedding, classifying, extracting aspects and routing results.
- Context-aware models read whole sentences, so they catch sarcasm and negation that word lists miss.
- Accuracy above 90% on clean benchmarks does not carry over to messy production text without testing.
- Aspect-based analysis ties each opinion to a feature, so teams can see exactly what to fix.
- In the EU, emotion inference from staff voices or faces at work is banned, while text-only survey sentiment is not.
Why Words Alone Mislead Sentiment Scores
Picture a telecom provider in the middle of a regional outage. Its social team posts an update, and then the replies start to pile up within minutes.
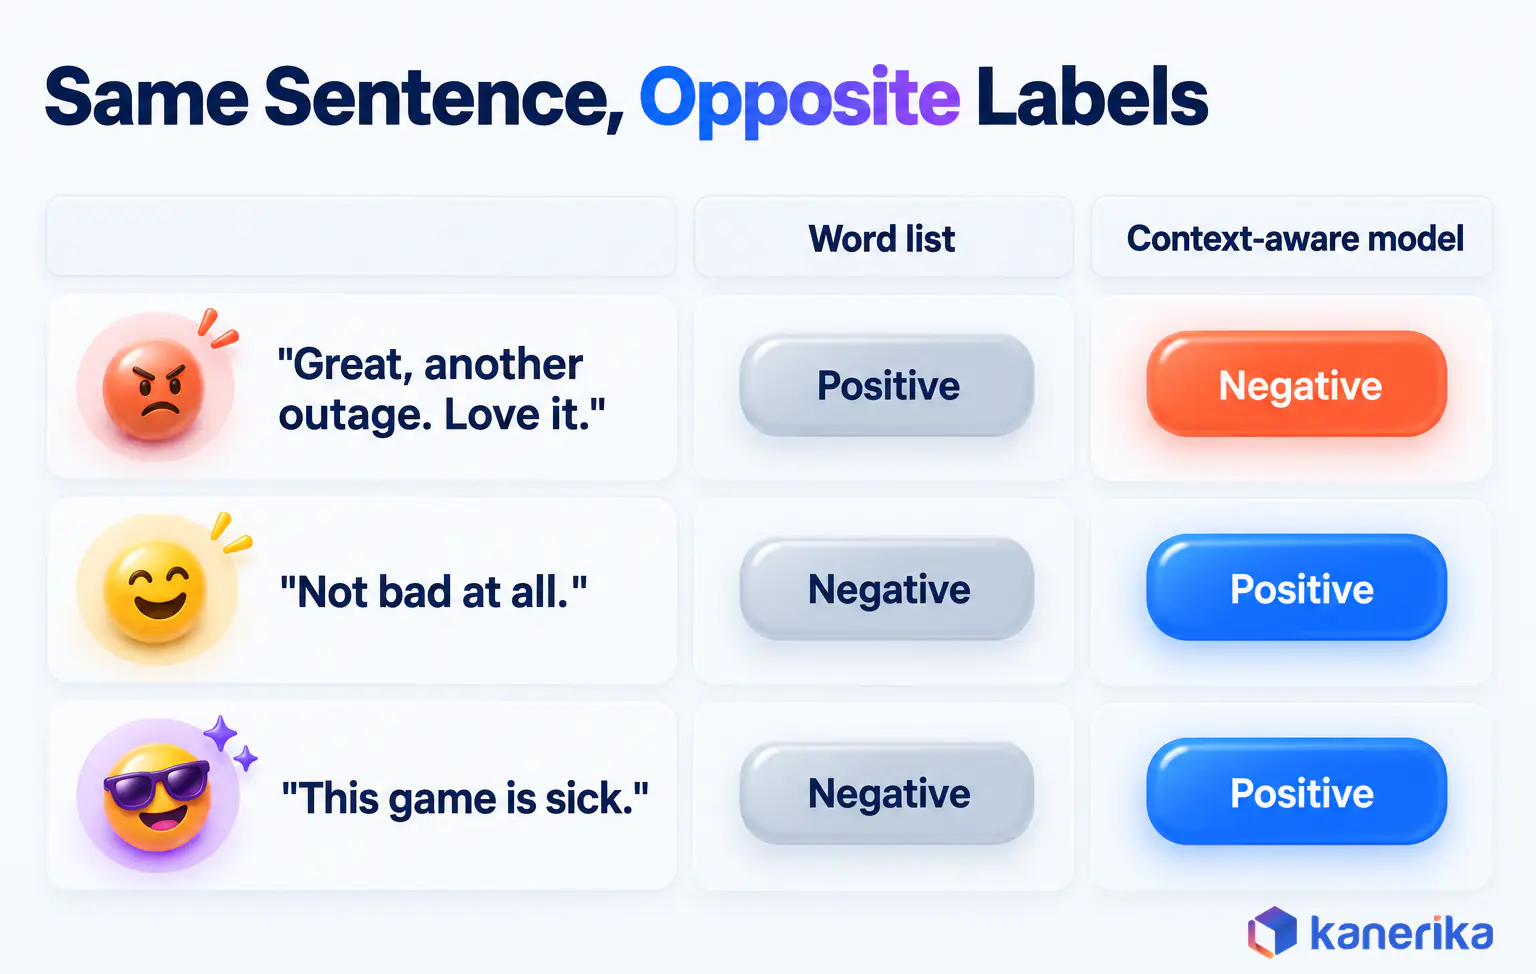
One reply reads “Great, another outage. Love it” with no emoji and no hashtag. A word-list tool sees “great” and “love” and so scores the post as positive. A context-aware model, by contrast, reads the whole line, spots the sarcasm and flags it as negative.
Multiply that gap by thousands of replies, and the dashboard tells the operations team that customers are happy during a failure. Closing the gap between the words and the meaning is the whole job of AI sentiment analysis. This guide explains what it is, how it works step by step, where it still fails and how to put it to work.
What Is AI Sentiment Analysis?
AI sentiment analysis is software that reads text and decides how the writer feels about a subject. It labels each review, ticket or post as positive, negative, neutral or mixed, and it often adds a score for strength.
The older name for the field is opinion mining, and it belongs to the wider discipline of natural language processing. It is also one branch of text analytics, which covers topics, entities and keywords as well as feelings. For a short definition, see the sentiment analysis glossary entry.
Early systems counted words from a fixed list. A review with “excellent” scored up, while one with “terrible” scored down.
Machine-learning models then changed the approach by learning from labelled examples. Transformer models such as BERT went further and read each word in the context of the whole sentence. So the “AI” part is really about context, because the model judges the phrase rather than the single word.
The payoff is scale with consistency. A support team can read a few hundred tickets a day. A model, however, can score millions overnight and apply the same rules to every one of them.
Speed matters too, since a spike in angry posts is useful at 9 a.m. and far less useful in next month’s report. That is also why sentiment often sits inside a wider AI data analysis program rather than on its own.
What the Output Looks Like
Different services return different shapes of answer, so it helps to know the common outputs before you design a report. Amazon Comprehend, for example, returns one of four labels (Positive, Negative, Neutral or Mixed) with a confidence score for each. Google Cloud Natural Language instead returns a score from -1.0 to 1.0, plus a magnitude that shows how strong the feeling is.
| Output | Example | Who uses it |
|---|---|---|
| Label | Negative, chosen from Positive, Negative, Neutral or Mixed | Support leads routing tickets |
| Score and magnitude | Score -0.8 when the feeling is strong | Analysts tracking trends |
| Aspect-level opinion | Battery negative but screen positive | Product managers fixing features |
| Emotion tag | Feelings such as anger, joy, fear or surprise | CX and brand teams, especially for replies |
AI Sentiment Analysis vs Traditional Lexicon Scoring
Lexicon scoring is the traditional method, and it still has a place. VADER, a popular open-source example, is a lexicon and rule-based tool tuned for social media text. It adds word scores into one compound score between -1 and 1. Anything at 0.05 or above counts as positive, anything at -0.05 or below as negative, and the band between is neutral.
That approach is fast, free and easy to explain to an auditor. Yet it has no real sense of context, so the outage reply from the opening scores as praise. AI models give up some of that transparency in return for an understanding of how words change meaning together.
| Factor | Lexicon scoring (such as VADER) | AI model (transformer or LLM) |
|---|---|---|
| Context handling | Word by word, although rules cover negation and emphasis | Reads the whole sentence as well as nearby text |
| Sarcasm | Usually misses it | Catches many cases, though not all |
| Setup effort | Minutes, because no training data is needed | Labelled data or prompt design, then testing |
| Explainability | Every point traces back to a word | Needs evidence spans or attribution tools |
| Best fit | Quick social monitoring and baselines | Tickets, reviews and surveys, especially mixed opinions |
Many teams keep a lexicon score as a cheap baseline. That way, any AI model has to beat a simple, known number before it earns a place in production.
How Does AI Sentiment Analysis Work? Step by Step
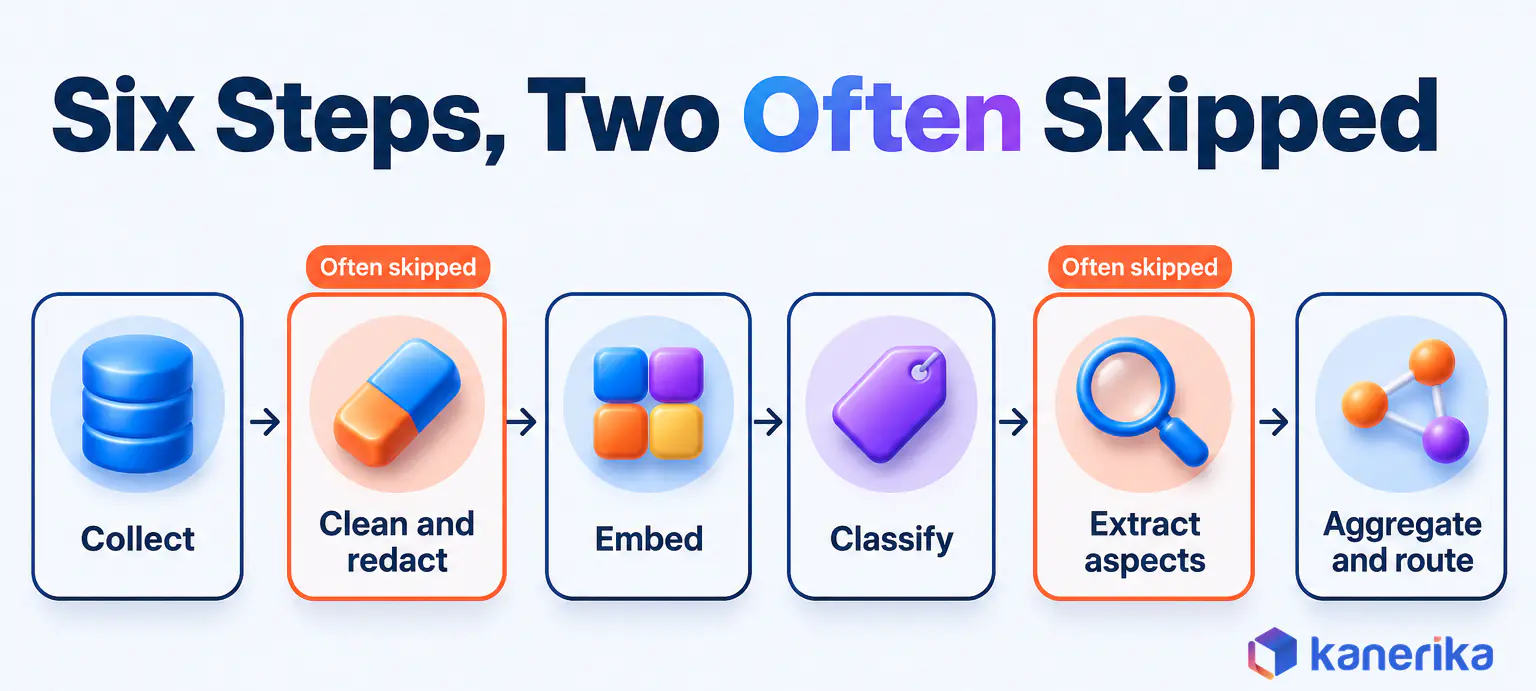
Every AI sentiment analysis system, from a cloud API to a custom model, runs the same basic pipeline. Think of it as a production line where raw text goes in one end and a decision-ready signal comes out the other. Because each stage removes one kind of noise, a weak stage early on shows up later as wrong scores.
Talk to Kanerika
Word List or AI Model for Your Text?
Kanerika reviews a sample of your tickets, reviews or survey comments and shows which scoring method holds up on them before you build anything.
Schedule a Demo →- Collect. Pull text from support tickets, product reviews, survey comments and social posts, as well as call transcripts from speech recognition.
- Clean and protect. Strip signatures and boilerplate, detect the language and redact personal data such as names, emails and account numbers.
- Represent. Split text into tokens and then convert them into embeddings, the numeric vectors a model can compare.
- Classify. Assign a label and a confidence score to each document or sentence.
- Extract aspects. Link each opinion to the thing it describes, such as billing, delivery or app speed, and flag mixed messages.
- Aggregate and act. Roll scores into dashboards, fire alerts on spikes and route negative cases to the right team.
Steps 2 and 5 are the ones teams skip most often. Skipping redaction creates a data privacy problem, while skipping aspect extraction leaves you with an average that hides the cause. A monthly “share positive” number tells a product manager nothing about what to fix.
Worked Example: One Support Ticket Through the Pipeline
Take a single ticket that says the app is fast now, but billing charged the customer twice and nobody called back. A basic tool would likely call this negative and stop there. The full pipeline does much more, as the table shows.
| Step | What happens | Output |
|---|---|---|
| Collect | Ticket pulled from the helpdesk with its ID and timestamp | Raw text plus metadata |
| Clean and protect | Customer name and card digits removed before scoring | Redacted English text |
| Represent | Text split into tokens and then embedded | Numeric vectors |
| Classify | Model reads the whole ticket | Mixed, but leaning negative |
| Extract aspects | Each opinion linked to its target | App speed positive, while billing and follow-up are negative |
| Aggregate and act | Complaint counted toward a duplicate-charge trend | Ticket routed to billing as high priority |
The useful output is not the “mixed” label at all. Instead, it is the fact that a duplicate-charge complaint just joined a growing trend, and that the billing team owns the fix.
What Are the Types of Sentiment Analysis?
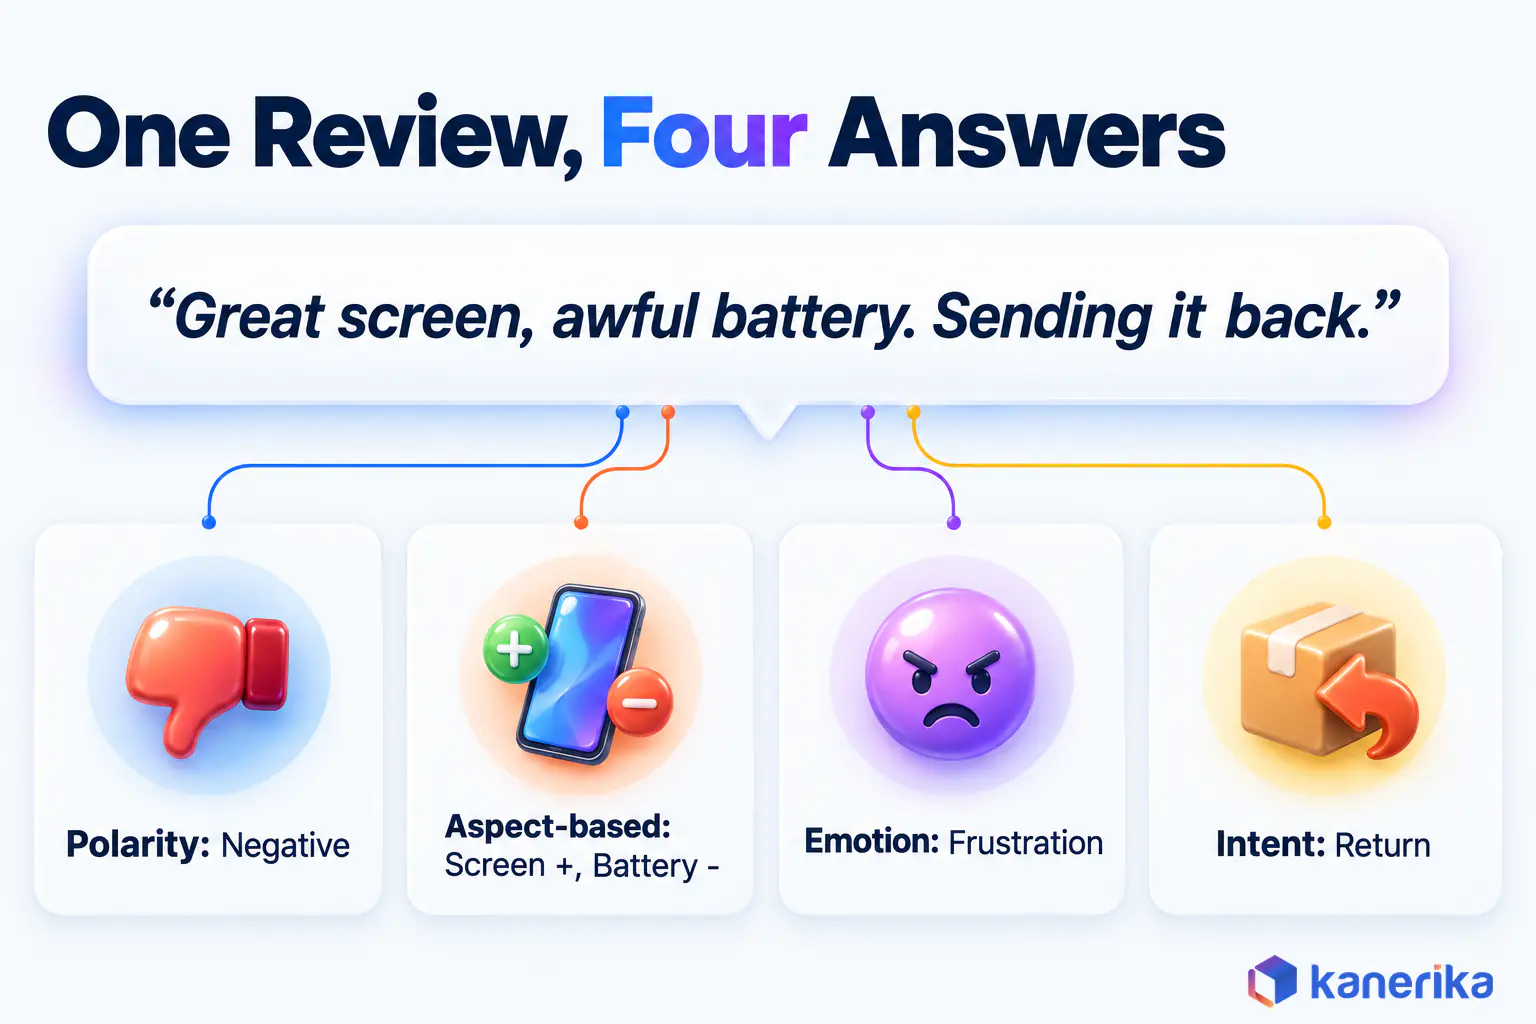
Sentiment analysis comes in several types, and they differ in how much detail they return. A brand team watching a launch may only need positive versus negative. A product team, on the other hand, needs to know which feature drew the complaint. So pick the type by the question you need answered, and only then pick the model.
| Type | What it returns | Question it answers |
|---|---|---|
| Polarity | Positive, negative or neutral, and sometimes mixed | Did people like the launch? |
| Fine-grained | A five-point scale from very negative to very positive | How strongly do reviewers feel? |
| Aspect-based (ABSA) | Sentiment per feature or topic | Which part of the product drives complaints? |
| Emotion detection | Emotions such as anger, joy, fear or sadness | Are customers angry or just disappointed? |
| Intent detection | Planned actions such as cancel, buy or complain | Who is about to leave? |
Emotion detection and sentiment are related, but they answer different questions. Sentiment asks whether the feeling is good or bad, whereas emotion asks which feeling it is. For instance, a ticket saying “I’m disappointed” and one saying “I’m furious” both read as negative. Even so, they need very different replies.
When Aspect-Based Sentiment Analysis Is Worth the Extra Effort
Aspect-based sentiment analysis (ABSA) splits one review into several opinions, each tied to a target. Researchers formalised the task in SemEval-2014 Task 4, a shared benchmark led by Pontiki and colleagues, and later ABSA work builds on that framing.
The extra effort pays off when one product has many parts that customers judge separately. A hotel review can praise the room, criticise the check-in queue and say nothing about price. A single “mixed” label loses all three signals, whereas ABSA keeps them. Under the hood, it relies on the extraction skills behind named entity recognition, since the model must first find the thing being judged.
ABSA is less useful when text is short and covers one topic, such as a one-line social post. In that case, plain polarity is cheaper and nearly as informative.
Which Sentiment Analysis Models and Methods Exist?
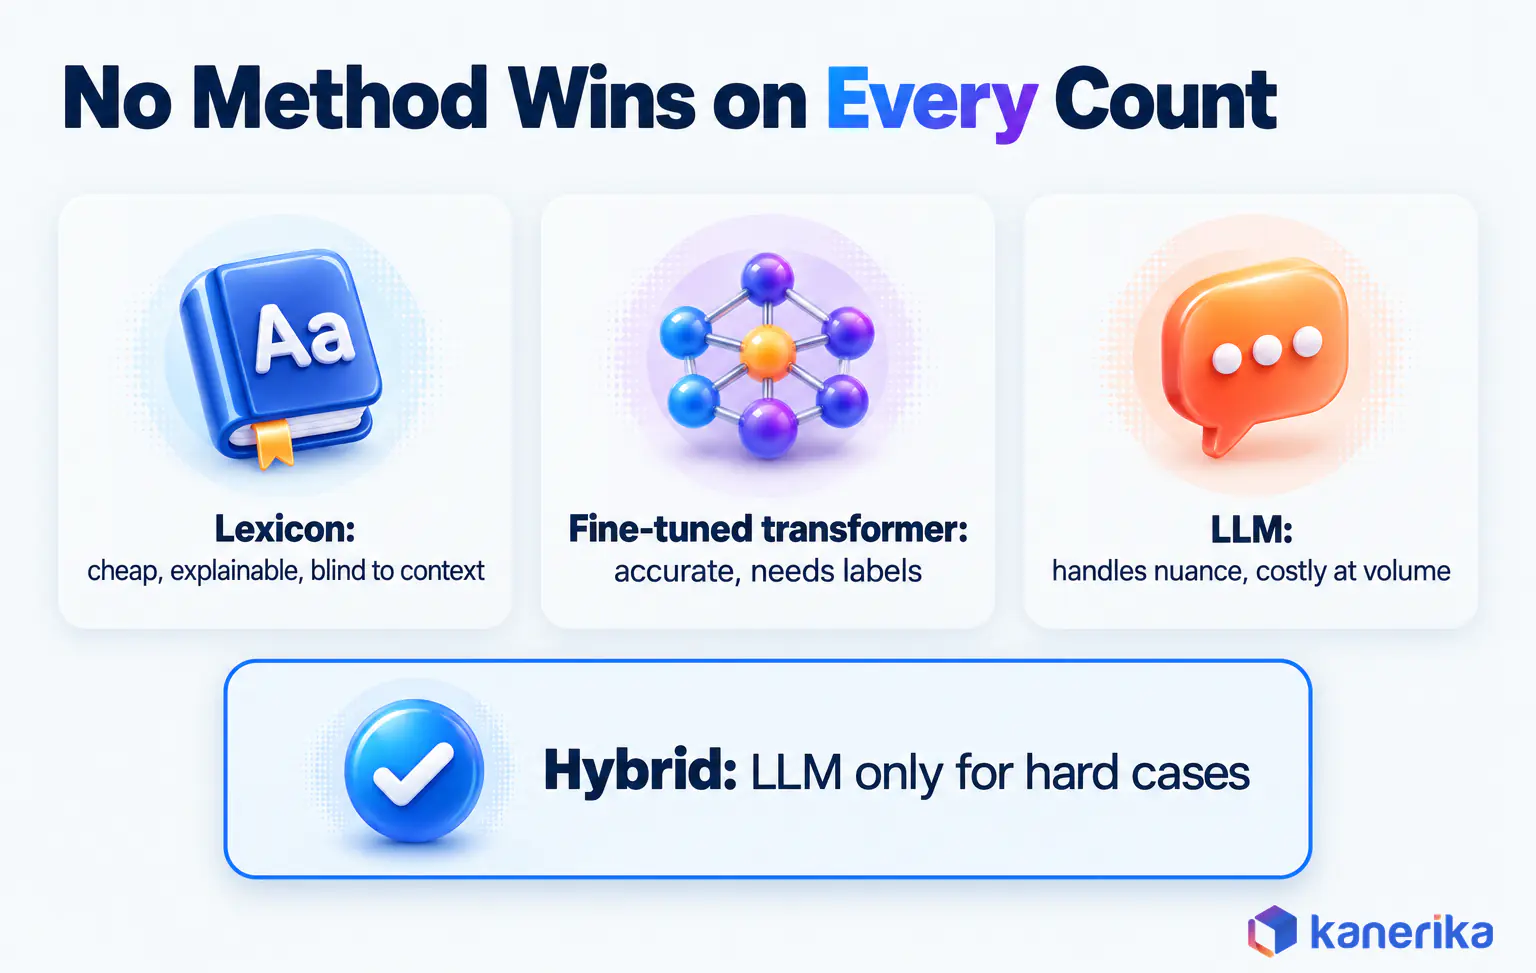
Sentiment methods have developed in layers, and every layer is still in use somewhere. Choosing between them is a trade-off between accuracy on messy text, running cost and how easily you can explain a result. If the labels are new to you, the guide to AI vs ML vs deep learning explains how the families relate.
| Method | How it works | Trade-off | Relative cost | Best for |
|---|---|---|---|---|
| Lexicon and rules (VADER) | Adds word scores, then applies rules for negation and emphasis | Fast, free and explainable, but misses context and sarcasm | Low | Social media baselines |
| Classical ML (Naive Bayes, logistic regression, SVM) | Learns word weights from labelled examples | Cheap to train, but weak on long context | Low | Stable text from one domain |
| Deep learning (LSTM, CNN) | Learns patterns across word sequences | Better context than classical ML, although it needs more data | Medium | Older pipelines with good training sets |
| Transformers (BERT family) | Pretrained language model fine-tuned on labelled data | High accuracy in-domain, but needs labels and GPU serving | Medium | High-volume tickets and reviews |
| LLM prompting (zero- or few-shot) | General model follows instructions and a few examples | No training and handles nuance, yet cost and latency grow per call | High at volume | Complex or changing tasks at low volume |
| Hybrid | Small model first, then an LLM for hard cases | Balances cost and accuracy, though it has more moving parts | Medium | Large enterprise programs |
For large programs, the hybrid row is often the practical answer. A small language model or a fine-tuned classifier scores the bulk of routine text. An LLM then handles the low-confidence or high-value cases. That split keeps cost close to the cheap rows, while accuracy on hard cases moves toward the expensive ones.
Can ChatGPT or Another LLM Do Sentiment Analysis?
Yes, for many jobs. A large language model can label polarity with no training data at all, and a few examples in the prompt often improve results further. The real question is where it holds up and where it slips.
A broad study by Zhang and colleagues in 2023 tested LLMs across 26 datasets. The models did well on simpler sentiment tasks and beat small models when only a few labelled examples were available. On complex or structured tasks, such as pulling out aspect and opinion pairs, they still lagged behind specialised models.
Two practical limits follow from that. First, you need a labelled test set to know whether a prompt works on your text. A model can sound confident and still be wrong. Second, cost grows with every call, so scoring millions of records needs a budget and a caching plan. Running an enterprise LLM inside your own estate is one way to control cost and keep customer text inside your own boundary.
A Structured-Output Pattern for LLM Sentiment
When an LLM does the scoring, ask it for structured output instead of free text. Here is an example of the fields to request for the support ticket from earlier. Because the schema is fixed, the same fields come back for every record.
{
  "overall_label": "mixed",
  "confidence": 0.86,
  "sarcasm_flag": false,
  "aspects": [
    {"aspect": "app speed", "sentiment": "positive", "evidence": "App is fast now"},
    {"aspect": "billing", "sentiment": "negative", "evidence": "billing charged me twice"},
    {"aspect": "follow-up", "sentiment": "negative", "evidence": "nobody called back"}
  ]
}
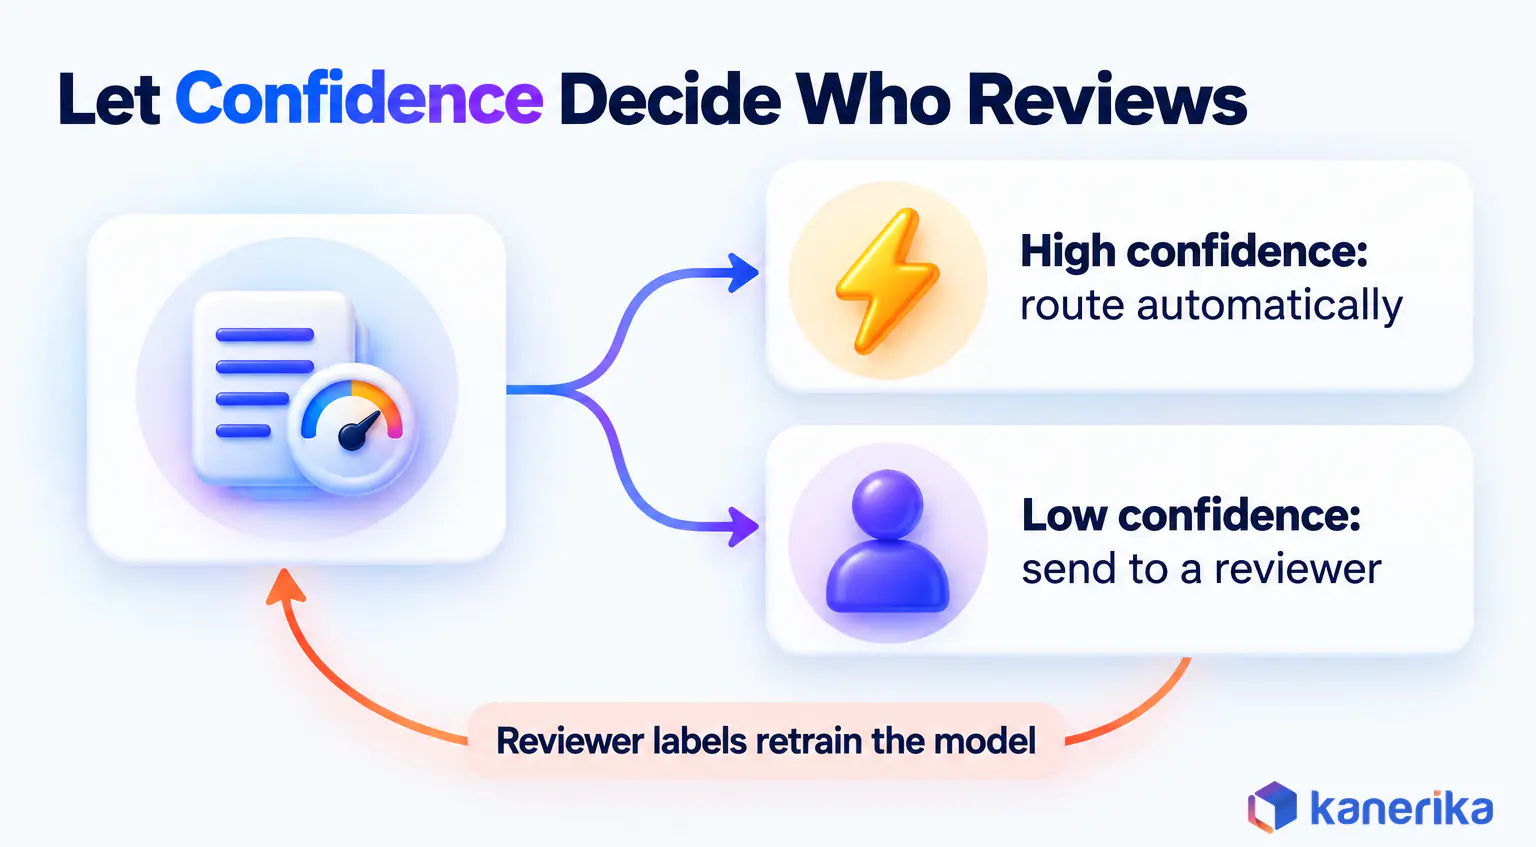
This format pays for itself in three ways. Its output loads straight into a table, so nobody has to tidy free-text answers. Each evidence span shows which words drove a label, which gives reviewers an audit trail. Finally, a confidence field lets you send uncertain cases to a person instead of a dashboard.
Checklist
Enterprise AI Checklist
Before an LLM scores customer text at scale, check data readiness, governance, security and model quality with Kanerika’s enterprise AI checklist.
Get the Checklist →How Accurate Is AI Sentiment Analysis?
Accuracy depends less on the model than on how closely your text matches the text the model learned from. A model that scores well on tidy movie reviews can stumble on support tickets full of product codes. So treat any headline accuracy figure as a ceiling rather than a promise.
Benchmark Accuracy vs What You Get in Production
Public benchmarks give a useful reference point. The DistilBERT model fine-tuned on SST-2 reports 91.3% accuracy on that dataset’s development set, compared to 92.7% for the larger BERT-base model. SST-2 is made of short, clean English sentences from movie reviews.
Production text is harder. It carries jargon, sarcasm, mixed opinions, typos and other languages, and each of those pulls accuracy down. The only number that matters is the one you measure on a labelled sample of your own records. Kanerika’s tools guide, linked further down, explains how to test a tool before you buy it.
Metrics That Matter Beyond Accuracy
Accuracy alone can mislead, especially when most text is neutral or positive. A model that calls everything positive can still score well if complaints are rare. The measures below show whether the model catches what you care about.
| Metric | What it tells you | Why it matters |
|---|---|---|
| Macro F1 | Average performance across all classes, weighted equally | Stops a large neutral class from hiding weak results |
| Recall on the negative class | Share of real complaints the model catches | Missed complaints are the costly errors, so watch this first |
| Agreement with human labellers | How often the model matches trained reviewers | Shows whether the task itself is well defined |
| Aspect-level accuracy | Whether opinions link to the right target | Drives product and service fixes |
| Calibration | Whether a 0.9 confidence is right about 90% of the time | Decides which cases can skip human review |
These sit alongside the wider AI performance metrics a model team already tracks. If your program also scores text with an LLM, the same discipline applies to prompts and model versions. The guide to building an LLM evaluation framework covers that wider testing setup.
Where Does AI Sentiment Analysis Still Struggle?
Language is slippery, so even strong models misread certain patterns. Knowing the common failure cases helps you design tests and decide where people stay in the loop. The table pairs each problem with an example sentence and a practical fix.
| Challenge | Example sentence | Mitigation |
|---|---|---|
| Sarcasm | “Great, another outage. Love it.” | Context-aware models and a sarcasm flag, then human review |
| Negation | “Not bad at all for the price.” | Transformer models; add negation cases to the test set |
| Domain words | “This game is sick.” / “The test came back positive.” | Fine-tuning on domain text, plus custom lexicon entries for edge cases |
| Mixed opinions | “Great screen, awful battery.” | Aspect-based analysis instead of one label |
| Multilingual and code-mixed text | “Delivery was late, bahut bura experience.” | Multilingual models, with a test set per language |
| Emojis | “Arrived on time 🙃” | Keep emojis through cleaning, since they often carry the tone |
| Label bias | Dialect phrases marked negative more often | Bias audits by group and dialect, and diverse labellers |
Domain words deserve special care. In a hospital, “positive” often signals bad news, while in gaming “sick” is praise. A general model cannot know which world it is in unless you show it examples from that world.
AI Sentiment Analysis Use Cases by Team
The same scores serve very different teams, and each team asks a different question of them. Support wants to know which ticket to open first. Product wants to know what to fix, while finance wants an early read on demand or risk.
| Team | Text source | Decision it drives |
|---|---|---|
| Customer support and CX | Tickets, chats and call transcripts | Routing and escalation |
| Product | Reviews, app store comments and feedback forms | Backlog priorities |
| Brand and marketing | Social posts, campaign replies and AI answers | Message and launch changes |
| Financial services | News, earnings-call transcripts and client notes | Demand and risk signals |
| HR | Engagement surveys and internal comments | Workplace fixes |
| Healthcare | Patient surveys and online reviews | Service quality fixes |
Customer Support and CX
Support teams use sentiment to sort the queue. A ticket that scores strongly negative, or mentions cancelling, jumps ahead of a routine password reset. Over time, a rising share of negative tickets from one account becomes a churn signal that feeds customer retention analytics before renewal.
The trick is to route on intensity and intent together. An angry how-to question needs a different reply from a calm cancellation notice, even though both read as negative. Teams can also pass these scores to AI agents for customer support, which draft the first reply.
Product Teams
Product managers get the most from aspect-level results. Instead of one satisfaction number, they see a trend per feature, such as onboarding improving while search gets worse. Those trends feed the backlog with evidence, so a debate about priorities starts from what customers actually wrote. Pair each trend with three or four real quotes, because a chart persuades less than a customer’s own words.
Brand and Marketing
Marketing teams track reaction to campaigns and launches day by day. When a sudden swing appears, it usually traces back to one message or one channel, so the fix can be quick. Sentiment works best here as one part of wider customer analytics and audience research.
AI sentiment analysis has also picked up a second meaning in marketing, where teams ask what tone ChatGPT, Gemini or Perplexity takes about their brand. An assistant might call a product “reliable but expensive”, which is sentiment aimed at an AI answer instead of a customer review. Treat those answers as one more text source in the same pipeline: collect them, label each one and track how the balance moves.
Kanerika’s project for a US IT solutions provider was not a sentiment pipeline but a close relative of one. Its AI market-research model gathered audience insight and tailored campaign messaging.
Case Study
21% Higher Conversion Rate with AI Marketing Analytics
Kanerika built an AI market-research model for a US IT solutions provider that gathered audience insight and tailored campaign messaging, delivering a 21% higher conversion rate, 5% market share growth and a 32% boost in customer engagement.
Read the Case Study →Financial Services
Banks and asset managers read tone in news stories and earnings-call transcripts as one input among many. A shift toward cautious language from a company’s management can prompt an analyst to look closer. Sentiment also works as a signal inside AI forecasting models, where a run of negative reviews may hint at softer demand. It should never drive a decision alone, since tone is noisy and easy to over-read. Sentiment signals are only one strand of a wider shift, which Kanerika traces in its guide to AI use cases in asset management.
HR and Employee Voice
Employee surveys and internal comments carry the same kind of signal, though it comes from inside the company.
In HR, Sentiment analysis is useful in determining how contented and engaged the employees are within the organization. Through feedback, surveys, and internal communication, organizations can measure where the problems lie, improve the employee environment, and suggestways of improving employee performance. Integrating an internal communication platform with sentiment analysis tools gives HR teams a centralized way to monitor employee feedback, identify trends, and respond to workplace concerns more effectively.
Because this text comes from staff, run it with clear consent, report only in aggregate and never score named individuals.
Healthcare and Patient Feedback
Hospitals and clinics read patient surveys and online reviews to find service problems that a star rating hides. Complaints about waiting times, discharge instructions or billing can then be tracked per site and per department, much like other data analytics in healthcare.
Medical language makes this harder, since words like “positive” or “negative” often describe a test result rather than a feeling. Strip protected health information before scoring, and keep the output at the level of themes, not patients.
How to Implement AI Sentiment Analysis in an Enterprise
A sentiment program succeeds or fails on choices made before any model runs. A team that starts with a tool can easily end up with a dashboard nobody opens. The roadmap below therefore starts with the decision and works back to the data.
- Set the objective and owner. Name the decision the scores will drive, such as ticket routing, and the person who owns it.
- Audit the data. List where the text lives, how much arrives each day and which languages appear. Check AI data quality and the personal data it holds, too.
- Build a label taxonomy. Decide the labels and the aspects that matter to your business, such as billing, delivery or onboarding.
- Choose the method. Match the method to volume, languages and explainability needs, using the methods table above.
- Evaluate on a labelled set. Have people label a sample of your own text, then measure macro F1 and negative recall before launch.
- Integrate with the data platform. Run scoring inside an AI data pipeline on Microsoft Fabric or Databricks, then report results in Power BI.
- Monitor for drift. Re-test on fresh samples every quarter, since new products, slang and campaigns change the text.
- Keep people on low-confidence cases. Send uncertain or high-impact records to reviewers, then feed their labels back into training.
Steps 3 and 5 take the most time, and they are also where most of the accuracy comes from. A clear taxonomy keeps labelling consistent, while a labelled set turns arguments about models into a measurement.
Where to Run It: API, Data-Platform Function or Open-Source Model
There are three places to run the scoring, and each suits a different team. Cloud language APIs are the quickest start, since you send text, get labels back and pay per call. For Microsoft users, Azure AI Language sentiment analysis and opinion mining retire on March 31, 2029, and new projects are directed to Microsoft Foundry.
Functions inside the data platform keep text where it already lives. In Microsoft Fabric, for instance, the ai.analyze_sentiment function labels text as positive, negative, mixed or neutral. It needs a paid F2 or larger capacity, or a P capacity, as well as Fabric Runtime 1.3 or later. Databricks has comparable Databricks AI functions for teams on that platform.
Self-hosted open-source models give the most control over data and cost at high volume, but your team owns serving and updates. The table below puts the main options side by side, and our sentiment analysis tools compared guide goes tool by tool.
| Option | Where it runs | What it returns | Best fit |
|---|---|---|---|
| Amazon Comprehend | AWS API, one call, a batch or an async job | Positive, Negative, Neutral or Mixed, with a score for each | Teams already on AWS |
| Google Cloud Natural Language | Google Cloud API | Score from -1.0 to 1.0 plus magnitude, also per entity | Tracking strength of feeling over time |
| Azure AI Language | Azure API or a Docker container | Sentence and document labels with confidence scores, plus opinion mining | Existing Azure workloads, since it retires on March 31, 2029 |
| Microsoft Fabric ai.analyze_sentiment | Fabric notebooks, SQL and Dataflow Gen2 | Positive, negative, mixed or neutral, or your own labels | Text already stored in OneLake |
| Open-source models | Your own servers | Depends on the model, such as positive or negative for DistilBERT SST-2 | High volume with strict data control |
Ethics, Privacy and Regulation
Sentiment analysis reads what people write about their own experiences, so it carries real privacy and fairness duties. The controls below apply to any program. They matter most when the text comes from employees or patients, and they fit inside broader AI governance.
Picture a retailer that scores its support chats. Before any model sees a transcript, the pipeline swaps names, emails and order numbers for placeholders. A line then reads “[NAME] says order [ORDER] arrived broken”, which still scores as negative but points to no one.
The same team would also compare negative rates by region and language. If one group’s chats come out negative far more often, reviewers read a sample to check whether the model is misreading a dialect rather than spotting real anger.
- Consent and notice. Tell customers and staff that their text may be analysed, and why.
- Data minimisation. Redact personal data before scoring and keep only the fields you need.
- Bias audits. Test results by group and dialect, so one community’s phrasing is not marked negative more often.
- Explainability. Keep evidence spans, so a reviewer can see why a label was given.
- Retention. Set how long raw text and scores are kept, then delete them on schedule.
Checklist
AI Governance Checklist
Sentiment programs touch customer and employee data. Use Kanerika’s AI governance checklist to review consent, bias, explainability and oversight before launch.
Get the Checklist →The EU AI Act adds a specific rule for workplaces and schools. Article 5(1)(f) prohibits AI systems that infer the emotions of people at work or in education, except for medical or safety reasons. That prohibition has applied since 2 February 2025.
The definition is narrower than it first sounds. Article 3(39) defines an emotion recognition system as one that works on biometric data. Text-only sentiment on an employee survey therefore sits outside that ban, while emotion inference from staff voices or faces sits inside it. For EU deployments, check the details with counsel before launch.
How Kanerika Builds Sentiment Analysis Into Your Data Platform
Kanerika starts every sentiment project from the decision the scores must drive, not from a model. If the goal is faster complaint handling, the first question is who acts on a negative score and how quickly.
Next comes a data audit of where the text lives, how much arrives, which languages appear and what personal data it carries. Kanerika then builds the pipeline inside the client’s Microsoft Fabric or Databricks estate, covering ingestion, PII redaction, scoring and aspect tagging. Because the work stays on the existing platform, sentiment data follows the same security and governance rules as every other table.
Before rollout, the model is tested on a labelled sample of the client’s own records. Results then flow into Power BI reports built by the data analytics team. Drift monitoring and LLM observability then check accuracy as products and language change.
A typical first release delivers four working parts. The first is a scoring pipeline on the client’s platform, and the second is a labelled evaluation set that proves accuracy on real records. A Power BI report then shows aspect trends, while a review queue holds low-confidence cases for people to check.
Some of the richest text sits in PDFs, emails and forms rather than in tidy tables. For those sources, Kanerika’s KlarityIQ document intelligence agent turns unstructured documents into usable data before scoring starts.
The same approach applies whether the text is tickets, reviews or survey comments. What changes is the label taxonomy, which Kanerika builds with the business owner rather than for them.
Kanerika Service
AI and Machine Learning Services
Kanerika designs and builds sentiment pipelines on your Microsoft Fabric or Databricks estate, from PII redaction and aspect tagging to tested models and Power BI reporting.
Explore AI/ML ServicesIs AI Sentiment Analysis Worth It in 2026?
The answer depends partly on where the field is heading, and three shifts will shape what comes next.
- Multimodal sentiment. Text and voice scored together in multimodal AI models, so tone of voice adds to the words.
- Native platform functions. Sentiment as a standard column in Fabric, Databricks and similar platforms.
- Agents that route on sentiment. AI agents that read a negative score and then open the right workflow without waiting for a person.
For organisations that handle large volumes of customer or employee text, the answer is yes, as long as the scores drive a named decision. Transformer and LLM models read context well enough to catch much of the sarcasm, negation and mixed opinion that defeated word lists. Platform functions have also turned scoring into a few lines of code rather than a separate project.
It is not worth it as a vanity dashboard, though. Without an owner, a labelled test set and drift checks, accuracy quietly decays and trust goes with it.
So what is AI sentiment analysis, and how does it work? In one line, it labels the opinion in text by cleaning, classifying and aggregating it into signals a team acts on. To make it work for you, start with one source and one decision, measure the result, then expand.
Frequently Asked Questions
What is AI sentiment analysis?
AI sentiment analysis is the use of natural language processing and machine-learning models to read text and judge the opinion in it. It labels reviews, tickets, surveys or posts as positive, negative, neutral or mixed. Many systems also score the strength of the feeling and link each opinion to a topic, such as price or delivery.
How does AI sentiment analysis work?
It works as a pipeline. Text is collected from sources such as tickets and reviews, then cleaned and stripped of personal data. The words are turned into numeric embeddings, and a model assigns a label and a confidence score. Aspect extraction links each opinion to its topic, and the results feed dashboards, alerts and routing.
Can AI detect sarcasm in text?
Partly. Context-aware models such as transformers and LLMs catch many sarcastic lines that word-list tools score as praise, for example a reply calling an outage great. They still miss sarcasm that depends on shared history or tone of voice. Add a sarcasm flag to outputs and send flagged cases to a human reviewer when stakes are high.
Does AI sentiment analysis work in multiple languages?
Yes, many models handle multiple languages, but quality varies by language and domain. Code-mixed text, where writers switch languages mid-sentence, is especially hard. Detect the language during cleaning, choose a multilingual model or one model per language, and build a separate labelled test set for each language you score. Never assume English accuracy carries over.
What is a real-life example of AI sentiment analysis?
A support team scores every incoming ticket and routes strongly negative ones to senior agents first. A ticket saying the app is fast but billing charged twice gets tagged positive for speed and negative for billing. The billing complaint joins a duplicate-charge trend, and the billing team receives it as a high-priority case.
Which tools are used for AI sentiment analysis?
Teams use four broad kinds of tool. Cloud language APIs score text per call. Data-platform functions, such as ai.analyze_sentiment in Microsoft Fabric, score text where it already lives. Open-source models run on your own infrastructure, and social listening suites add dashboards for business users. Kanerika’s sentiment analysis tools guide compares specific products in detail.
Is sentiment analysis legal?
Sentiment analysis is legal in most settings when data protection rules are followed. That means notice, a lawful basis such as consent, data minimisation and limited retention. In the EU, Article 5(1)(f) of the AI Act bans emotion inference from biometric data at work and in education. Check EU deployments with legal counsel before launch.
What is another name for sentiment analysis?
Sentiment analysis is also called opinion mining. Some teams use the terms emotion AI or tone analysis, although those usually mean emotion detection, which is a narrower task. In customer experience work, the same idea often appears under voice of the customer analytics. All of these describe software that reads opinion in text at scale.
How is AI sentiment analysis different from traditional sentiment analysis?
Traditional sentiment analysis counts words from a fixed list and adds up their scores. AI sentiment analysis uses machine-learning models that read words in context. That lets it handle sarcasm, negation and mixed opinions far better. The trade-off is that AI models need labelled data or careful prompts, and their results are harder to explain.
What does brand sentiment in AI answers mean?
It means the tone AI assistants such as ChatGPT, Gemini or Perplexity use when they describe your brand. Marketing teams collect those answers for common questions and label each one as positive, negative or neutral. Tracked over time, the balance shows how AI search presents the brand, using the same classification idea as customer review sentiment.
What are the main types of sentiment analysis?
The main types are polarity, fine-grained, aspect-based, emotion detection and intent detection. Polarity returns positive, negative or neutral. Fine-grained uses a five-point scale. Aspect-based scores each feature separately, emotion detection names feelings such as anger or joy, and intent detection spots planned actions such as cancelling. Choose the type by the question you need answered.
Which AI model is best for sentiment analysis?
No single model is best for every job. A fine-tuned transformer from the BERT family suits high volumes of in-domain text. An LLM suits complex, low-volume or changing tasks without training data. A lexicon tool such as VADER suits quick social media baselines. Large programs often combine a small model with an LLM for hard cases.
Can ChatGPT do sentiment analysis?
Yes. ChatGPT and other large language models can label sentiment from a prompt with no training data, and a few examples often improve results. A 2023 study across 26 datasets found LLMs did well on simple tasks but lagged on complex, structured ones. Test any prompt on your own labelled data and watch the cost at volume.
How accurate is AI sentiment analysis?
Accuracy depends on how closely your text matches the training data. A DistilBERT model fine-tuned on the SST-2 movie review set reports 91.3% accuracy on its development set. Real tickets and reviews carry jargon, sarcasm and mixed opinions, so accuracy is usually lower. Measure it on a labelled sample of your own records before relying on it.
What role does NLP play in sentiment analysis?
Natural language processing supplies the steps that let a machine read text at all. It splits text into tokens, detects the language, handles negation and turns words into numbers a model can compare. Sentiment analysis is one task within NLP, alongside related tasks such as named entity recognition, translation and summarisation of documents.
What is aspect-based sentiment analysis?
Aspect-based sentiment analysis, or ABSA, finds the opinion attached to each feature or topic in a piece of text. A hotel review might be positive about the room and negative about check-in. The task was formalised in the SemEval-2014 Task 4 benchmark. ABSA tells product and service teams what to fix, not just the overall mood.
What is the difference between sentiment analysis and emotion detection?
Sentiment analysis asks whether a feeling is positive, negative or neutral. Emotion detection asks which feeling it is, such as anger, joy, fear or sadness. Two complaints can share a negative sentiment while one is mild disappointment and the other is fury. Teams use emotion labels to choose the right tone and urgency of reply.
How is a sentiment score calculated?
It depends on the method. Lexicon tools such as VADER add up word scores into a compound value, where 0.05 or above counts as positive and -0.05 or below as negative. Machine-learning models output a probability for each label. Google Cloud Natural Language returns a score from -1.0 to 1.0 plus a magnitude for strength.