TL;DR
Among generative AI models in November 2026, choose GPT-6.1 Sol for company-wide workflows and Claude Opus 5.5 for engineering and long knowledge work. For long-context work inside Google Cloud, Gemini 4 Argon costs $2 in and $10 out per million tokens until November 30, 2026. Qwen3.8-Max suits teams that need open weights at frontier scale and can accept a custom license. DeepSeek V4.1-Flash-1017 wins high-volume work, where 100 million input and 20 million output tokens cost $27 a month off-peak. That same month costs $800 on Opus 5.5, so send routine calls to a cheap tier and keep frontier models for judgment calls. Every price and date here was checked on November 2-3, 2026.
Key Takeaways
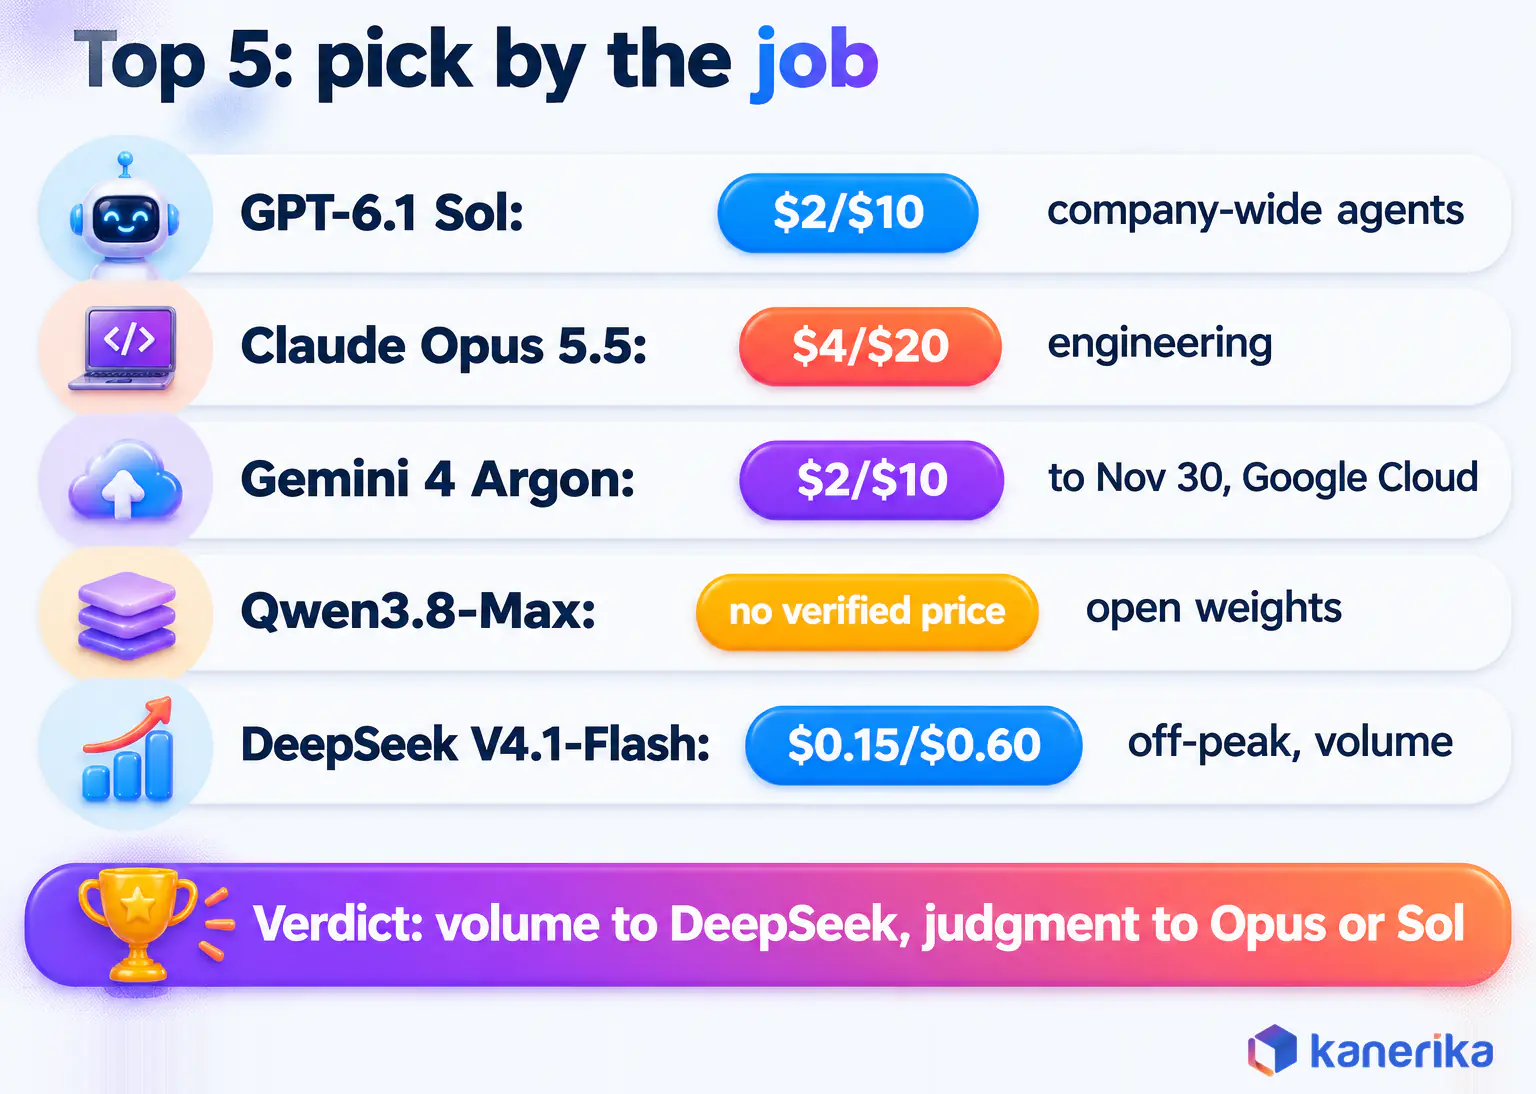
- The five picks map to five business outcomes: company-wide agents (GPT-6.1 Sol), engineering (Claude Opus 5.5), long context in Google Cloud (Gemini 4 Argon), open-weight control (Qwen3.8-Max) and high-volume work (DeepSeek V4.1-Flash-1017).
- For 100M input and 20M output tokens a month, Opus 5.5 costs about 30x the DeepSeek off-peak bill ($800 vs $27), and GPT-6.1 Sol costs about 15x ($400).
- Routing is the biggest cost lever: sending 80% of tokens to Claude Haiku 5.5 cuts the $800 Opus month to $176.
- Open weights give deployment control, but every license needs a legal read first.
- Dates to plan around: Gemini 4 Argon rises to $4/$20 on December 1, 2026, OpenAI retires gpt-5, o3 and o3-pro on December 11, 2026, and EU AI Act high-risk duties start on December 2, 2027.
- Pick by workload, data residency and license, then prove the choice on your own documents before you scale it.
Five Model Bills, One Budget Meeting
Picture an AI lead walking into a budget meeting with five quotes for the same job. The job is a contract-review assistant that reads 100 million input tokens and then writes 20 million output tokens a month.
The quotes run from $27 to $800, even though all five models can do the task. Every vendor page shows a strong benchmark. So the finance director asks one fair question: which bill buys the outcome we need?
That question also drives this guide. It ranks five generative AI models by business result, by the cost of a real workload and by the control you keep. Every price and date below was checked on November 2-3, 2026.
What Are Generative AI Models?
Generative AI models are systems that produce new content, such as text, code, images or audio, from a prompt. They learn patterns from large training sets and then create output that did not exist before.
That sets them apart from discriminative models, which only sort or score existing data. For example, a fraud model that flags a payment is discriminative. A model that drafts the email explaining the hold is generative, because it writes something new.
Most business tools sit on foundation models, which are large general-purpose models trained once and then adapted to many tasks. GPT-6.1 Sol and Claude Opus 5.5 are foundation models, and so is the open-weight Qwen3.8 family. For the wider picture of the field, start with Kanerika’s guide to generative AI.
How Generative AI Models Work
Three designs account for most of the models a business will meet. Each one shapes cost and speed differently, so the design matters at buying time.
- Transformers. The model reads a whole prompt at once and uses attention to weigh how each word relates to every other word. Text and code models are built this way, and this explainer on how LLM architecture works walks through the layers.
- Diffusion. The model starts from random noise and then removes it step by step until an image or audio clip appears. Most image generators use this approach, as the guide to diffusion models explains.
- Mixture-of-experts (MoE). The model holds many expert sub-networks but switches on only a few for each token. For instance, Qwen3.8-Max has 2.4 trillion parameters with 95 billion active, while Mistral Large 4 has 1 trillion with 52 billion active.
MoE is the reason a very large model can still answer at a sane price. Only the active share of parameters works on each token, so compute per request stays far below the headline size.
Types of Generative AI Models
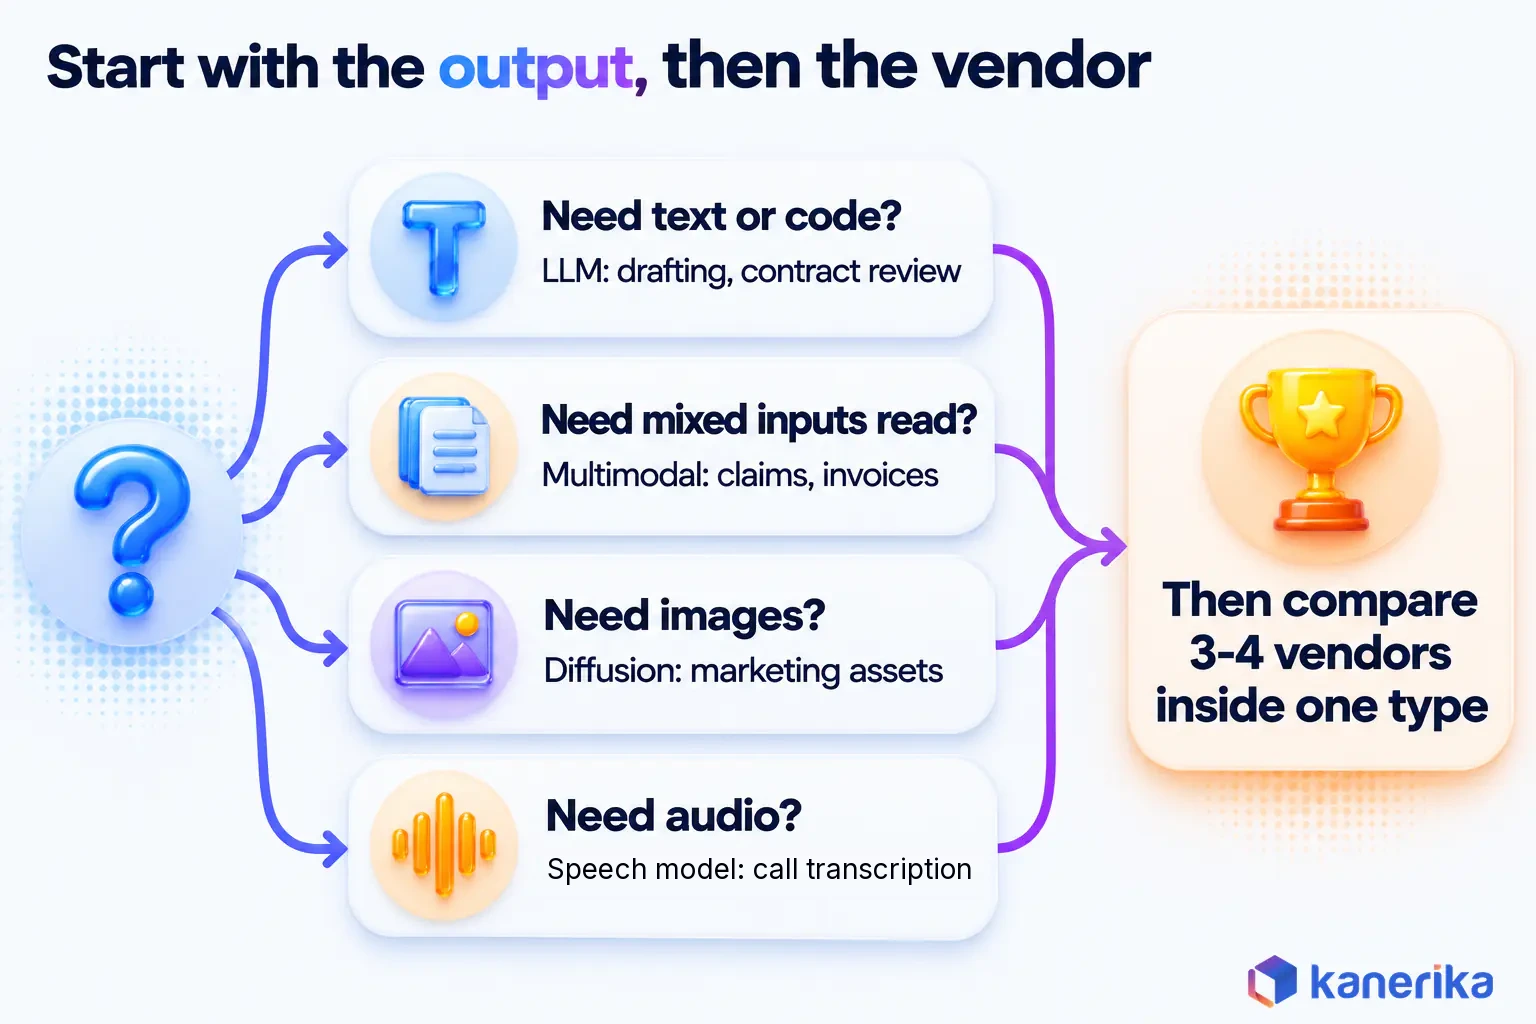
The most useful way to sort these models is by the output they produce, because output maps straight to a business function. A legal team needs text, while a claims team needs mixed inputs read correctly and a marketing team needs images.
| Type | Output | Business function | Example |
|---|---|---|---|
| Large language model (LLM) | Text and code | Drafting, contract review, support replies | GPT-6.1 Sol, Claude Opus 5.5 |
| Multimodal model | Text from mixed inputs (text, image, audio) | Claims intake, invoice reading, field reports | Phi-4-multimodal-instruct (open, MIT); hosted Qwen3.8-Max (image input) |
| Code model | Code, tests and reviews | Software delivery and migration work | Claude Opus 5.5 (66.4% on Terminal-Bench 4.0) |
| Image and video (diffusion) | Images and short clips | Marketing assets, product mock-ups | Diffusion-based generators (check each vendor’s page) |
| Speech model | Audio in or out | Transcription and call analysis | Phi-4-multimodal-instruct (audio input) |
Phi-4-multimodal-instruct shows how small a capable multimodal model can be. It has 5.6 billion parameters, takes text, image and audio input and returns text. It ships under an MIT license. Kanerika’s piece on multimodal models covers this class in more depth.
The type decides the shortlist before any vendor enters the room. Once you know the output you need, comparing three or four models inside one type is a short job.
Five Model Families by How They Generate
Many guides also sort models by how they generate output, and that view explains why some designs suit some jobs better. Five families cover nearly every model a buyer will meet:
- Generative adversarial networks (GANs). A generator makes samples while a discriminator tries to spot the fakes, so both improve through the contest. Businesses use GANs to create synthetic images and extra training data where real examples are scarce.
- Variational autoencoders (VAEs). An encoder compresses data into a compact code, and a decoder builds new samples from points in that code. A common business use is anomaly detection, since a faulty part on a production line rebuilds poorly and stands out.
- Autoregressive transformers. The model predicts the next token from every token before it, one step at a time. All five picks in this guide work this way, and they power drafting, contract review and code.
- Flow-based models. A chain of reversible steps maps simple noise to real data, so the model can score exactly how likely any sample is. That makes them useful for flagging an unusual transaction or sensor reading.
- Diffusion models. The model learns to remove noise step by step until an image appears. Marketing teams use them for campaign visuals and product mock-ups.
For most text and code budgets, the autoregressive family is the one being priced. That is why the rest of this guide compares transformer models.
How We Picked the Top 5
Leaderboards change every few weeks, so this list ranks models by what they do for a business instead. Each pick had to clear five tests, and every test was checked against vendor pages on November 2-3, 2026.
- A clear business outcome. The model must lead on one workload a company pays for, such as agents, engineering or high-volume processing.
- Published pricing. Per-token prices must appear on the vendor’s own page, so a monthly bill can be worked out. Qwen3.8-Max is the one exception, kept because of its open weights.
- A context window near 1 million tokens. All five accept about 1 million tokens, which is enough for a long contract set in one prompt.
- Deployment control. The list needed hosted vendor APIs as well as at least one model you can run yourself.
- A dated, checkable release. Each model has a release date or model card, so rumored models were left out.
These tests also leave out some strong models. Claude Fable 5.1, Mistral Large 4 and Grok 4.7 all came close, and the next section says where each one fits.
Top 5 Generative AI Models at a Glance
The quick answer fits in one table, so start here. Prices are list rates per million tokens, with input first and output second, as of November 3, 2026.
| Model | Vendor | Price in / out per 1M | Context | Deployment | Best business outcome |
|---|---|---|---|---|---|
| GPT-6.1 Sol | OpenAI | $2 / $10 | 1,050,000 | API and ChatGPT | Company-wide workflows and agents |
| Claude Opus 5.5 | Anthropic | $4 / $20 | 1M | API | Engineering and long knowledge work |
| Gemini 4 Argon | $2 / $10 to Nov 30; $4 / $20 from Dec 1, 2026 | Up to 1M | Gemini API | Long-context work in Google Cloud | |
| Qwen3.8-Max | Qwen | No verified price | 1M | Hosted, plus public text-base weights | Open-weight control at frontier scale |
| DeepSeek V4.1-Flash-1017 | DeepSeek | $0.15 / $0.60 off-peak; double at peak | 1M | API, plus MIT weights | High-volume, cost-sensitive work |
Three models just missed the list. Claude Fable 5.1 costs $10/$50, while Opus 5.5 matches or beats it on most listed benchmarks at less than half the price. Mistral Large 4 costs $0.7/$2.1 in public preview, so it makes a strong open-weight fallback. Grok 4.7 costs $2/$6 under 200,000 tokens but holds 500,000 tokens, half the window of the five picks.
For a ranking across every major model, also see the full LLM ranking. When the real question is which chat assistant to give staff, the comparison of ChatGPT, Gemini and Claude as assistants covers that choice.
1. GPT-6.1 Sol: Best for Company-Wide Workflows and Agents
GPT-6.1 Sol is the safest default when one model must serve many teams at once. It runs in the API and also in ChatGPT, so the same model can power staff chat, internal tools and agents.
OpenAI released Sol on September 29, 2026. Its API pricing page lists $2 per million input tokens and $10 for output, while cached input costs $0.10. The context window holds 1,050,000 tokens, with up to 128,000 output tokens per call.
For instance, consider a shared-services team that wants one assistant for HR policy answers, finance reconciliations and IT ticket triage. Sol covers all three because it handles chat, tools and agents in one model. Staff can also try the same model in ChatGPT Plus at $20 a month before IT wires it into workflows.
Sol has one cost trap and one easy saving. When a prompt runs over 272,000 tokens, it bills at twice the input rate and 1.5 times the output rate. Batch and Flex processing cut the price by 50%, so overnight jobs should never run at the standard rate.
Inside the same family, GPT-6.1 Terra costs $1/$5 and GPT-6 Luna costs $0.10/$0.50. That spread makes routing within one vendor simple, since all three sit on the same API. Sol is a strong fit for:
- Companies standardizing on ChatGPT for staff
- Teams building agents that call internal tools
- Buyers who want Batch pricing for overnight jobs
Teams weighing OpenAI’s own tools against Microsoft’s bundle should read Microsoft Copilot or ChatGPT. For how Sol relates to Terra and Luna, see OpenAI’s GPT model lineage.
Kanerika Service
Generative AI Development Services
Kanerika helps enterprises pick models by workload, build retrieval and guardrails around them, and run them in production with cost per task measured.
Explore Generative AI Services2. Claude Opus 5.5: Best for Engineering and Long Knowledge Work
Hard, long work that is costly to get wrong is where Claude Opus 5.5 earns its price. Software changes, migration plans and long research memos are the typical cases.
Anthropic released Opus 5.5 on September 22, 2026 at $4 per million input tokens and $20 for output, according to its models overview. Cached reads cost only $0.20, so repeated context gets far cheaper. The model also holds 1 million tokens of context with up to 128,000 output tokens.
Opus 5.5 scored 66.4% on Terminal-Bench 4.0, a test of agent work in a command line, while Claude Fable 5.1 scored 55.8% there. Since Opus 5.5 matches or beats Fable 5.1 on most listed benchmarks, the pricier model rarely makes sense as a default.
Take an engineering team migrating a library of legacy stored procedures. Because Opus 5.5 holds 1 million tokens, it can read a large share of that library at once. It can then propose rewrites and explain each change for review.
Price, however, is where it falls short. At list rates, the 100M-in, 20M-out workload costs $800 a month, twice Sol’s bill. Teams that want a cheaper Claude can instead drop to Claude Sonnet 5.5 at $2/$10 or Claude Haiku 5.5 at $0.10/$0.50. Opus 5.5 fits best on:
- Code migration, refactoring and review
- Long contract, policy and research analysis
- Multi-step agents that run commands
Pick Opus 5.5 when one wrong answer costs more than the tokens do. The head-to-head of Claude Opus versus Mistral shows how it compares with an open-weight rival on the same jobs.
3. Gemini 4 Argon: Best for Long-Context Work in Google Cloud
Gemini 4 Argon suits teams whose data and identity already live in Google Cloud. It reads up to 1 million tokens of combined context, so long reports, transcripts and document sets fit in a single call.
Google published the Argon model card on October 13, 2026, and the model is live in the Gemini API. The Gemini API pricing page lists $2 per million input tokens and $10 for output through November 30, 2026. From December 1, 2026 the price rises to $4 and $20.
For example, a media company checking a season of call transcripts for compliance phrases is a good fit. Because the team already buys from Google, Argon adds no new vendor contract.
Still, the price change is the catch. A budget built on November rates doubles in December, so finance teams should model the $4/$20 rate from the start. Gemini 4 Carbon has been announced, but no price, model id or availability date was published as of November 3, 2026.
Teams that want a cheaper Google tier can use Gemini 3.8 Flash at $0.75/$3.75 until December 31, 2026. After that date, the price rises to $1.50/$7.50. Argon is the right pick for:
- Teams already building on Google’s stack
- Long-document and transcript review
- Budgets that can absorb the December price rise
Pick Argon when long inputs and an existing Google relationship matter more than the lowest bill on the list.
4. Qwen3.8-Max: Best for Open-Weight Control at Frontier Scale
Qwen3.8-Max is the pick for teams that want frontier-scale ability with weights they can download. Teams with strict residency rules, such as banks and public bodies, are the natural audience.
Qwen released it on August 3, 2026. It is a mixture-of-experts model with 2.4 trillion parameters, 95 billion of them active per token, and a 1 million token context window. The hosted version also accepts images as input.
The public weights, published on Hugging Face as Qwen3.8-2.4T-A95B, are the text base model. So plan any image work on the hosted service, and keep self-hosted deployments to text.
Licensing is also a catch. The weights ship under a custom license named qwen3.8-max, so legal review should read it before any commercial use. No verified per-token price for the hosted model was found as of November 3, 2026.
Smaller jobs, though, have a simpler option. Qwen3.8-27B is a dense model under Apache 2.0 with 262,144 tokens of native context, extendable to 1 million. Qwen3.8-Max suits:
- Teams that must self-host
- Buyers who want to inspect or fine-tune the weights
- Workloads where data cannot leave your own cloud
Kanerika’s roundup of open-source LLMs compares the Qwen family with other open-weight releases.
5. DeepSeek V4.1-Flash-1017: Best for High-Volume, Cost-Sensitive Work
When volume, rather than judgment, drives the bill, DeepSeek V4.1-Flash-1017 is the cheapest verified option of the five. Classification, tagging, summaries and first-pass extraction run millions of calls, so the price per token sets the budget.
The model is dated October 17, 2026 and runs under the API id deepseek-flash with a 1 million token window. DeepSeek’s pricing page lists $0.15 per million input tokens on a cache miss and $0.60 for output off-peak. Peak hours bill at double, $0.30 and $1.20.
Peak runs 01:00-04:00 and 06:00-10:00 UTC, Monday to Friday, except on Chinese public holidays. A batch scheduled outside those UTC windows pays the off-peak rate. For US and European teams the windows fall overnight and early morning, so check the scheduler’s time zone.
The weights carry an MIT license on Hugging Face, so a team can self-host when the hosted API does not meet its data rules. DeepSeek V4-Pro-0813, generally available since August 13, 2026, costs $0.66/$1.98 off-peak for heavier reasoning. This guide to DeepSeek’s model family covers the hosting trade-offs.
Flash still has three limits worth planning for:
- Jobs that run inside the peak windows pay double, and in US and European time zones that includes overnight runs
- Hosted data handling must pass your own review before regulated data goes in
- Hard judgment calls still belong on a frontier tier
Pick DeepSeek for high-volume work on data that may leave your walls, and self-host the MIT weights for data that may not.
Talk to Kanerika
Shortlisting Models for a Real Workload?
Bring one workload and its monthly volume. Kanerika will map it to a first-pick model, a fallback and a cost per task in a short working session.
Schedule a Demo →How to Choose a Generative AI Model: Workload, Cost and Control
Choosing among generative AI models comes down to three questions asked in order. What is the workload, what will a month of tokens cost, and how much control does your data need?
Starting from benchmarks usually pushes buyers toward the priciest model for every call. Starting from the workload instead usually ends with two or three models behind one router, each doing the job it is cheapest at.
Match the Model to the Workload
Each workload gets a first pick and a fallback, so one outage or price change never stops the work. The table below pairs common business workloads with both.
| Workload | First pick | Fallback | Why |
|---|---|---|---|
| Company-wide assistant and agents | GPT-6.1 Sol | Claude Sonnet 5.5 | One model for chat and API; Sonnet matches Sol’s $2/$10 |
| Code migration and review | Claude Opus 5.5 | GPT-6.1 Sol | 66.4% on Terminal-Bench 4.0 |
| Long transcripts in Google Cloud | Gemini 4 Argon | Gemini 3.8 Flash | Up to 1M combined context; no new vendor |
| Regulated data, self-hosted | Qwen3.8-Max | DeepSeek V4.1-Flash-1017 (MIT weights) | Weights you control |
| High-volume tagging and summaries | DeepSeek V4.1-Flash-1017 | Claude Haiku 5.5 or GPT-6 Luna | $27 or $20 a month for the reference workload |
| Routing tier | Claude Haiku 5.5 | GPT-6 Luna | $0.10 / $0.50 per 1M tokens |
Not every workload needs a frontier model at all. The guide to small language models versus LLMs explains when a smaller model is the better first pick.
What a Month of Tokens Really Costs
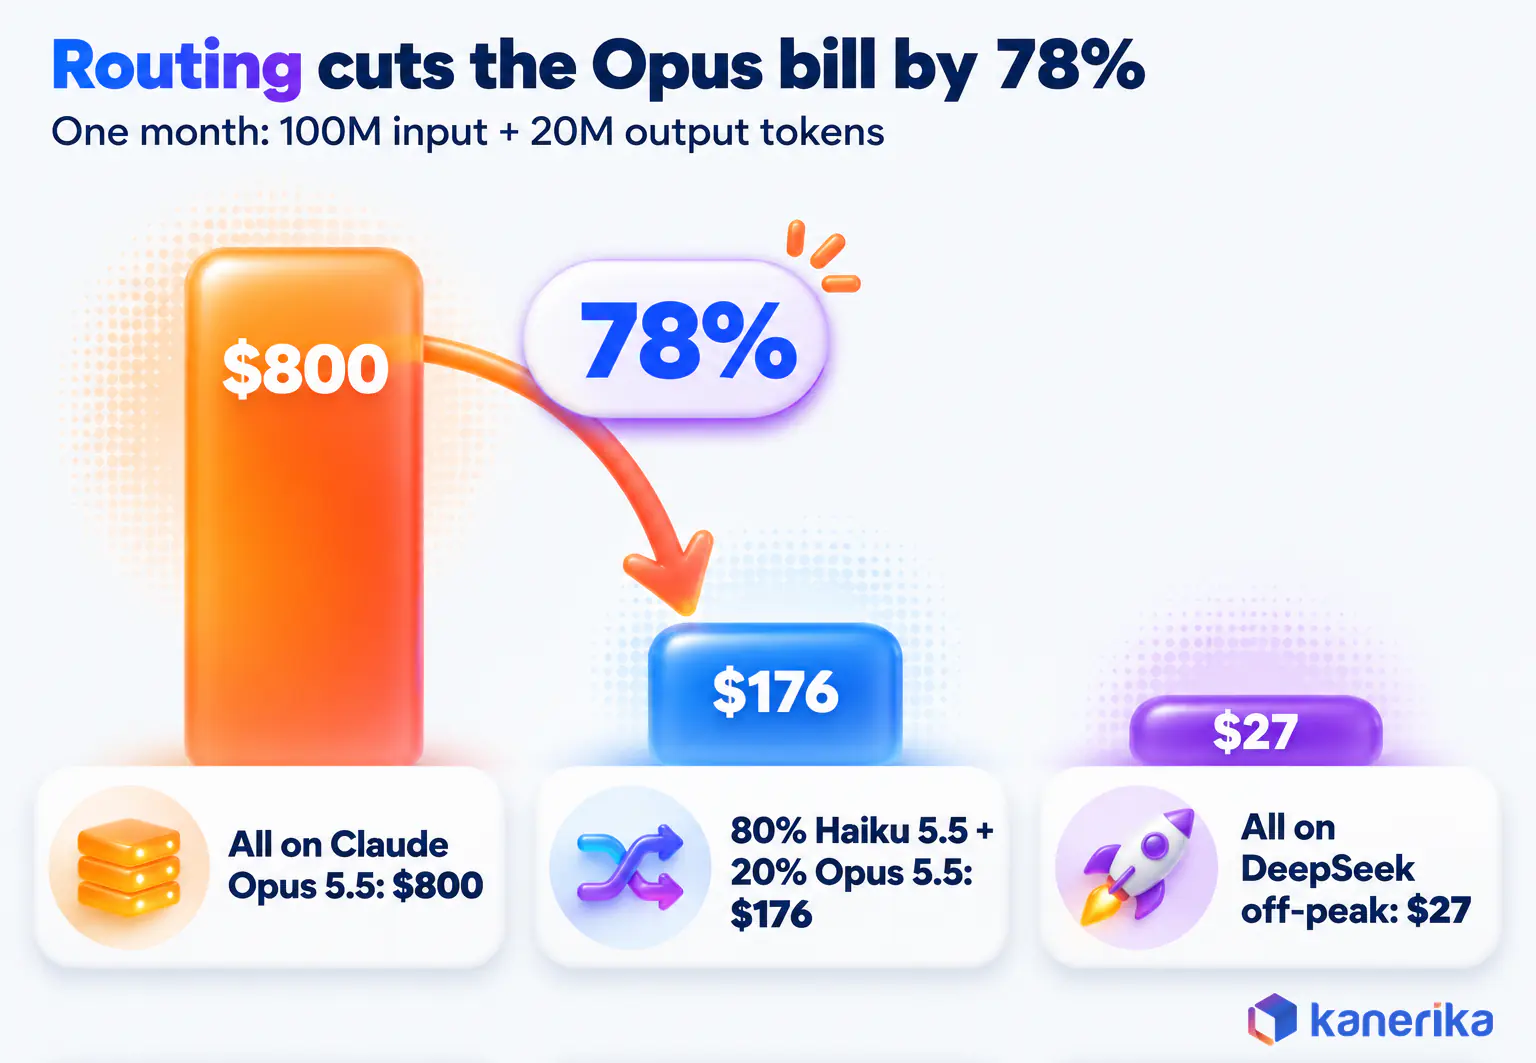
Token prices look tiny until a real month of traffic multiplies them. The worked example uses 100 million input tokens and 20 million output tokens, list prices, prompts under 272,000 tokens and no caching.
| Model | Price in / out per 1M | Monthly cost |
|---|---|---|
| Claude Opus 5.5 | $4 / $20 | $400 + $400 = $800 |
| GPT-6.1 Sol | $2 / $10 | $200 + $200 = $400 (Batch: about $200) |
| Gemini 4 Argon | $2 / $10 to Nov 30; $4 / $20 from Dec 1 | $400, rising to $800 from Dec 1, 2026 |
| Mistral Large 4 (preview) | $0.7 / $2.1 | $70 + $42 = $112 |
| DeepSeek V4.1-Flash-1017 | $0.15 / $0.60 off-peak; peak double | $15 + $12 = $27 off-peak; $54 all-peak |
| Router tier: Claude Haiku 5.5 or GPT-6 Luna | $0.10 / $0.50 | $10 + $10 = $20 |
Opus 5.5 costs about 30 times the DeepSeek off-peak bill, while Sol costs about 15 times. Qwen3.8-Max is left out because no verified price was published as of November 3, 2026.
Token bills are only part of the cost, though. Evaluation sets, integration work and guardrails such as PII redaction can take more of the first-year budget than the tokens do.
Three levers bring the bill down. Routing sends routine calls to a $0.10/$0.50 tier, and caching cuts repeated input by 95% on both Opus 5.5 and Sol. Batch or Flex processing then halves Sol’s price for jobs that can wait.
Here is the routing math for the same month, assuming Haiku prompts stay under 100,000 tokens. When 80% of tokens go to Claude Haiku 5.5 and 20% to Opus 5.5, the bill falls from $800 to $176, a 78% cut. Haiku handles $16 of that, while Opus accounts for $160.
A router like this usually sits in an LLM gateway, and small language models often serve as the cheap tier behind it.
Open-Weight or Proprietary?
Open-weight models run on your own hardware or cloud account, while proprietary models run only on the vendor’s service. The choice turns on control, residency and the license text.
A hospital that cannot send patient notes outside its own cloud needs open weights or a hosted service inside its region. A marketing team drafting blog posts, in contrast, can use any hosted API. The license then decides what you may do with the weights:
- DeepSeek V4.1-Flash-1017 and V4-Pro-0813: MIT license, the simplest terms on this list.
- Qwen3.8-27B: Apache 2.0, also a standard permissive license.
- Qwen3.8-Max: a custom license named qwen3.8-max that needs a legal read.
- Mistral Large 4: public Mistral Large 4 weights under a custom license listed as “other” on Hugging Face.
- GLM-5.3: 753 billion parameters, with weights at zai-org/GLM-5.3, also under a custom license.
The model cards also publish the serving setup. For Mistral Large 4, Mistral recommends the vLLM library for production inference, and the card’s start command is vllm serve "mistralai/Mistral-Large-4-1T-A52B". SGLang is also supported, and a quantized NVFP4 checkpoint with a smaller memory footprint targets Blackwell GPUs.
Self-hosting, however, moves security, evaluation and upgrade work onto your own team. Kanerika’s guide to private LLMs covers the hosting patterns that keep data inside your boundary.
What to Watch Next
Each of the dates below deserves a calendar entry for whoever owns the AI budget.
The next phase of generative AI development through 2027 turns on three dated events. Gemini 4 Argon’s price rises on December 1, 2026. OpenAI then retires gpt-5, o3 and o3-pro on December 11, 2026, and EU AI Act high-risk duties start on December 2, 2027.
Older OpenAI models, meanwhile, are already leaving. The ids gpt-4-turbo, o1, o3-mini and gpt-4o-2024-05-13 retired on October 23, 2026, and the GPT-4o and GPT-4.1 snapshots follow on January 14, 2027. So any workflow pinned to those ids needs a migration plan.
Two announcements still lack firm details. Gemini 4 Carbon has been announced with no price or availability. Kimi K3.1 Pro weights were announced as due by November 4, 2026, but had not shipped as of November 2.
Checklist
Generative AI Checklist
Work through the data, security, evaluation and ownership checks to settle before a model goes into production.
Get the Checklist →Which Generative AI Models Fit Which Industry
The same five models behave differently once industry rules apply. A bank, a hospital and a factory can run the same model but still need different controls around it.
| Industry | Typical workload | Model fit | Governance note |
|---|---|---|---|
| Financial services | Contract review, KYC document reading, reporting | Claude Opus 5.5 for analysis; DeepSeek or a Haiku tier for tagging | Keep audit trails; check output against source documents |
| Healthcare | Clinical note summaries, prior-authorization letters | Self-hosted Qwen3.8-Max or Qwen3.8-27B | Patient data stays in your cloud; redact PII before prompts |
| Manufacturing | Maintenance logs, work instructions, supplier documents | GPT-6.1 Sol agents; Gemini 4 Argon for long logs | Tie answers to approved manuals |
| Retail | Product descriptions, review analysis, service chat | DeepSeek V4.1-Flash-1017 for volume; Sol for chat | Human review for brand and pricing claims |
| Legal | Contract comparison, clause extraction | Claude Opus 5.5 | Privilege rules decide which hosted APIs are allowed |
Overall, a pattern runs through the table. High-stakes reading goes to a frontier model, while bulk text goes to a cheap tier, and regulated data pushes teams toward weights they host themselves.
Healthcare and factory teams can find worked use cases in the guides to generative AI for healthcare and generative AI in manufacturing. For a broader set across business functions, see these generative AI examples.
Matching the model to the industry is only half the job; the payoff is still uneven. McKinsey’s State of AI 2026 survey, as reported by FM Magazine, found that 37% of companies attribute some EBIT impact to AI. Only about 6% are AI high performers, who credit AI with at least 5% of EBIT and call the impact significant.
Risks and Governance to Plan For
Every one of these models can produce confident, wrong output, so error handling is the first thing to plan. Governance means deciding in advance which errors are tolerable, who checks the output and what data the model may see.
Two frameworks, in particular, give that work a structure. The NIST AI 600-1 Generative AI Profile was published on July 26, 2024. It lists the risks specific to generative systems as well as the actions that address them. It is voluntary, so it works well as a checklist for internal controls.
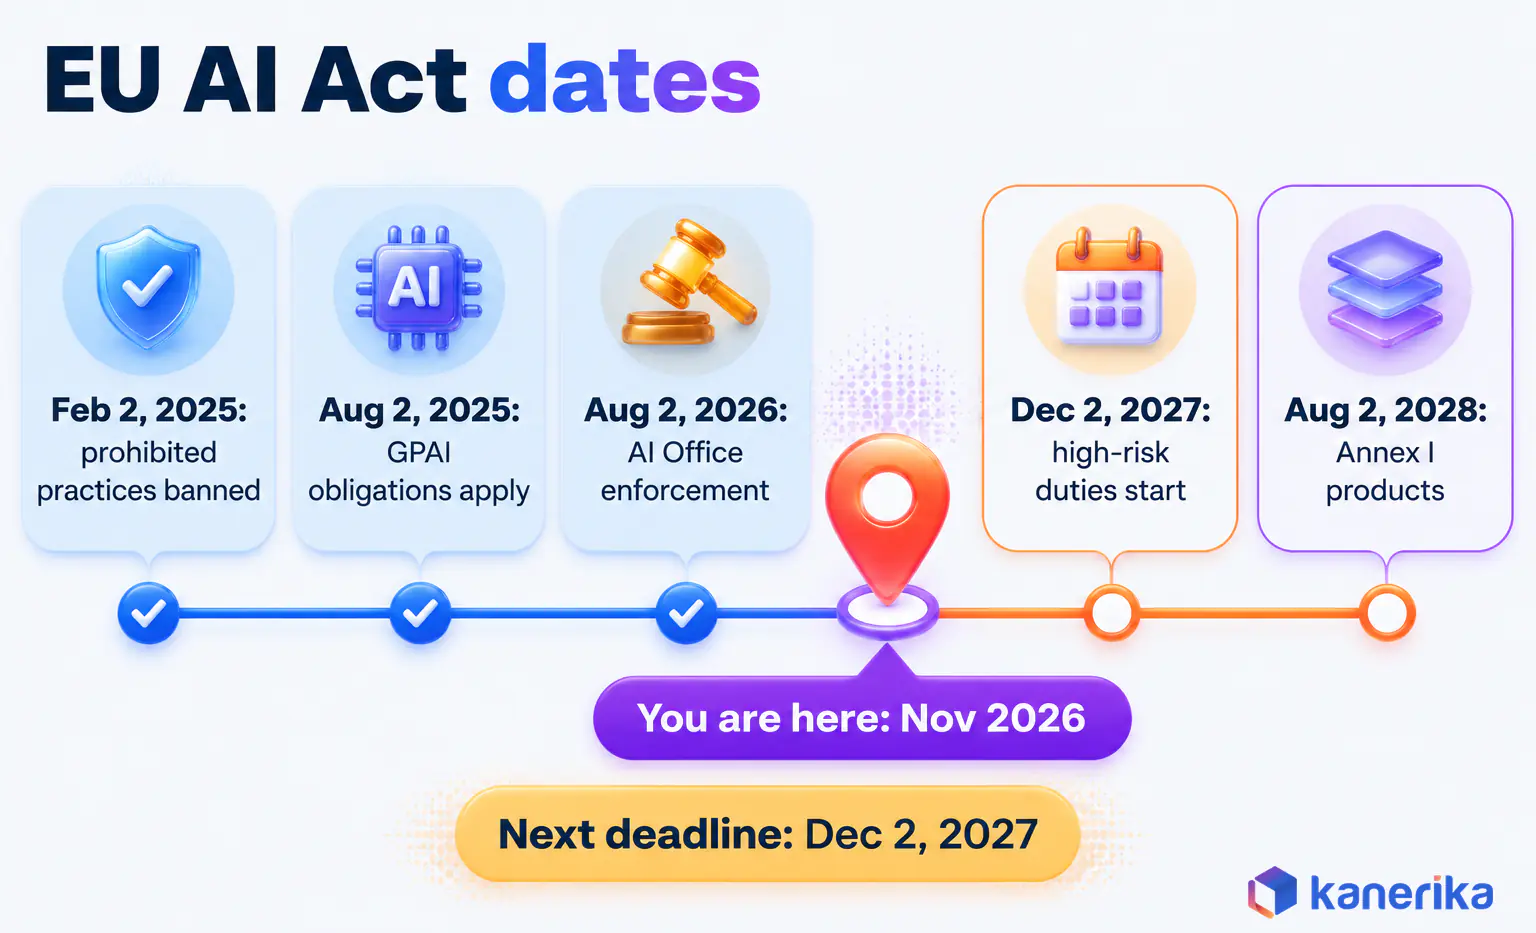
The EU AI Act, in contrast, is binding for anyone serving users in the EU. Prohibited practices applied from February 2, 2025 and general-purpose AI (GPAI) obligations from August 2, 2025. AI Office enforcement then began on August 2, 2026.
The next deadlines sit further out, so there is still time to prepare. High-risk duties for sensitive uses start on December 2, 2027, and Annex I products follow by August 2, 2028.
Six Risks That Need an Owner
With the frameworks in place, six risks need an owner before launch:
- Hallucination. Models invent facts, citations and numbers. So ground answers in retrieved documents, and see this guide to LLM hallucination for the methods.
- Data privacy. Prompts can carry personal or confidential data to a third party. Redact PII before the call, and confirm where each vendor stores prompts.
- Intellectual property. Generated text or code can echo licensed material. Keep a human review step before anything is published or shipped.
- Bias. Output can reflect skews in training data, so test every customer group.
- Vendor lock-in. Prices and models change fast. Gemini 4 Argon doubles from $2/$10 to $4/$20 on December 1, 2026, and OpenAI retires gpt-5, o3 and o3-pro ten days later. Keep prompts and evaluations portable so you can switch vendors.
- Regulation. Rules carry fixed dates and fines. EU AI Act high-risk duties start on December 2, 2027, so map each use case to its legal category now.
Security also deserves its own review, since prompt injection and data leakage are specific to these systems. Kanerika’s guides to generative AI security and an AI governance framework set out the controls.
How Kanerika Puts Generative AI to Work
Kanerika’s generative AI services help enterprises choose, build and run generative AI systems that hold up in production. The work starts from a business metric and the client’s own documents rather than from a model name.
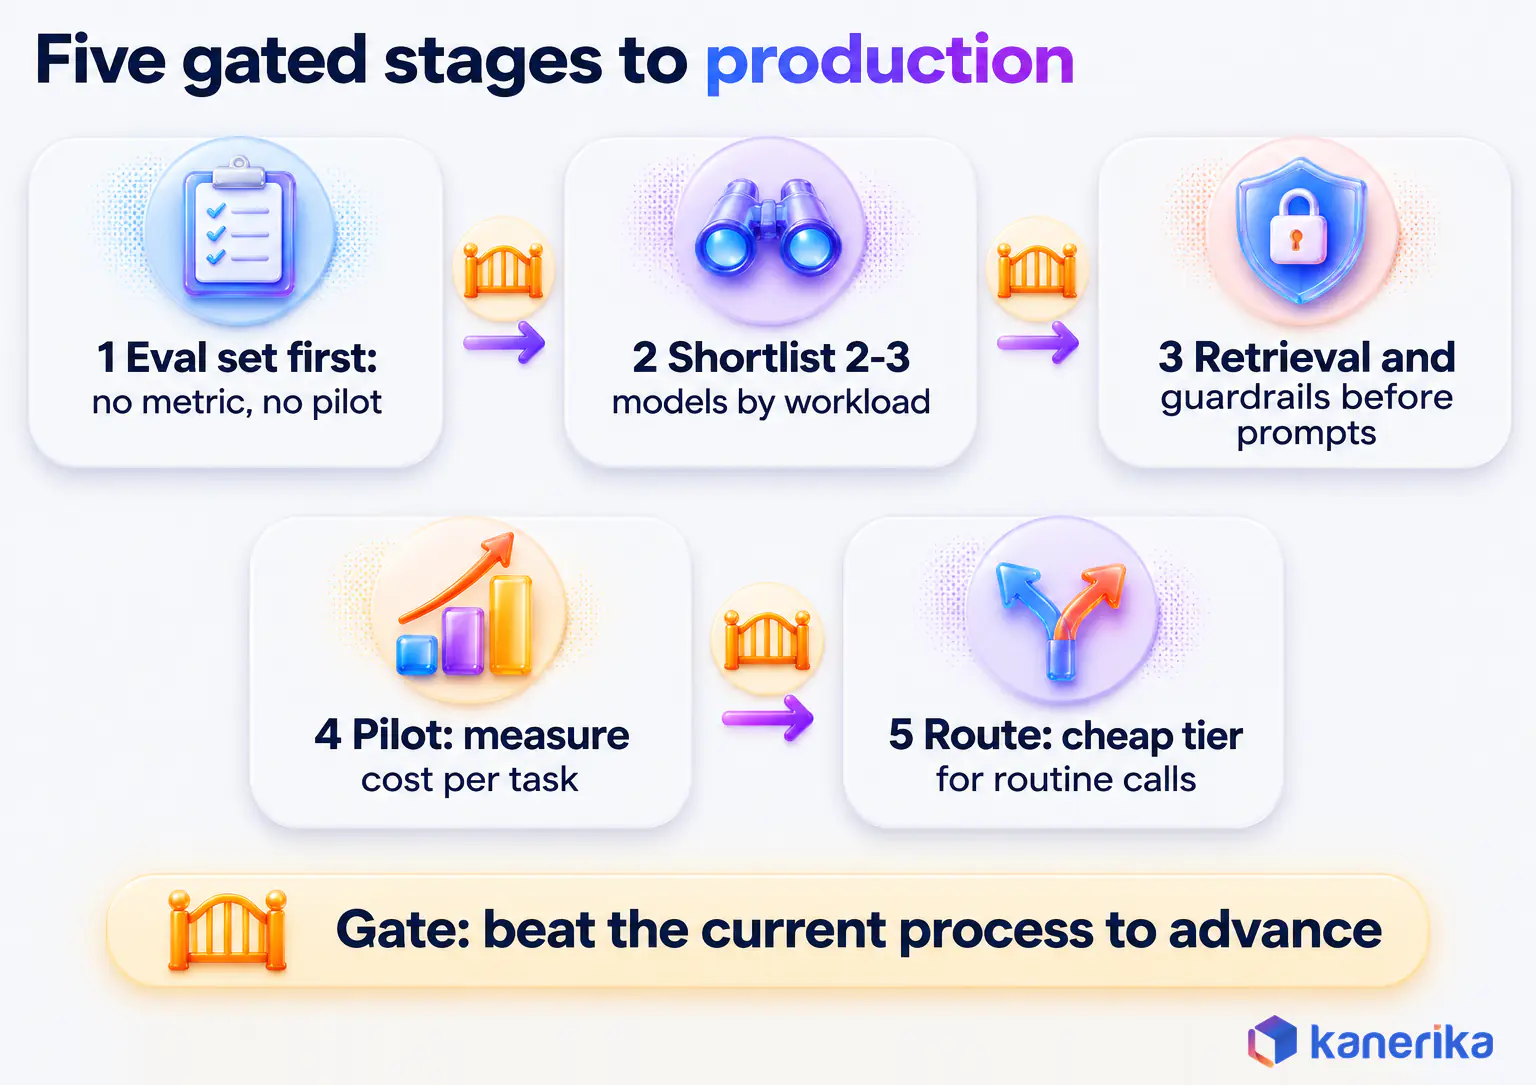
Every engagement follows the same five stages:
- Define the business metric and build a task-level evaluation set from real documents.
- Shortlist two or three models by workload, data residency and license.
- Build retrieval and guardrails before prompts, including PII redaction with Susan and access controls.
- Pilot against the incumbent process, then measure cost per task.
- Route and monitor in production, with a cheap tier for routine calls and a frontier tier for judgment.
The building blocks come from Kanerika’s own teams and products. The LLM development and RAG development teams build the model and retrieval layers. FLIP handles the data pipelines underneath, while KlarityIQ works as a document intelligence agent.
Kanerika is a Microsoft Solutions Partner for Data and AI. It also holds ISO 27001, ISO 27701 and SOC 2 Type II certifications, and it is appraised at CMMI Level 3. Those controls matter when a pilot touches contracts, patient data or financial records.
Proof From a Vendor-Agreement Pipeline
One engagement shows the method at work. A real estate developer backed by a Middle-Eastern public investment fund held its vendor agreements as unstructured PDFs in Oracle Content Management Cloud. Kanerika built an LLM extraction and question-answering pipeline, with a GCP readiness upgrade underneath. Teams could then query the terms of each agreement instead of reading every PDF by hand.
The delivery began with the data, not the model. Limited understanding of the data was delaying migration and analysis, so Kanerika analyzed the data environment in full, which is stage 1 of the method. Users then reached the agreements through a chat interface built with detailed prompt criteria for finding a vendor.
The results were measured against the old manual process. Manual processing time fell by 82%, cloud integration efficiency rose by 75%, and vendor selection saw a 90% boost. That is stage 4 in practice, where the pilot is judged against the way the work was done before.
Case Study
90% Faster Vendor Selection with LLM Agreement Processing
A real estate developer turned unstructured vendor agreements into question-ready data with an LLM pipeline, cutting manual processing time by 82%.
Read the Case Study →So which generative AI models deliver business value in 2026? Each of the five does when it is matched to the workload it leads and then measured on a real task.
Frequently Asked Questions
What is a generative AI model?
A generative AI model is a system that creates new content from a prompt. It can write text, produce code, make images or generate audio. It learns patterns from large training sets and uses them to predict new output. GPT-6.1 Sol, Claude Opus 5.5 and Gemini 4 Argon are well-known examples that businesses use in 2026.
How do generative AI models work?
Most text models use a transformer design. Attention lets the model weigh how every word in a prompt relates to the others, and the model then predicts the next token. Image models usually use diffusion and remove noise step by step. Very large models such as Qwen3.8-Max add mixture-of-experts, so only part of the model runs per token.
How much do generative AI models cost to run?
Cost depends on tokens, model and timing. For 100 million input and 20 million output tokens a month at list price, Claude Opus 5.5 costs $800 and GPT-6.1 Sol costs $400. DeepSeek V4.1-Flash-1017 costs $27 off-peak. A router tier such as Claude Haiku 5.5 or GPT-6 Luna costs $20. Prices were checked on November 3, 2026.
Can a business use more than one generative AI model at once?
Yes, and cost-conscious teams usually should. A router or LLM gateway sends routine calls to a cheap tier and hard calls to a frontier model. Sending 80% of tokens to Claude Haiku 5.5 and 20% to Opus 5.5 cuts an $800 monthly bill to $176. A second vendor also protects you from outages and price changes.
Should you fine-tune a generative AI model or use retrieval (RAG)?
Start with retrieval in most cases. RAG feeds the model your current documents at answer time, so facts stay fresh and each answer can cite a source. Fine-tuning changes the model’s behavior and suits fixed formats, tone or narrow tasks. Many teams combine both, with RAG for knowledge and light fine-tuning for style.
Are generative AI models the same as foundation models?
The two groups overlap heavily. A foundation model is a large general-purpose model trained once and adapted to many tasks. Most well-known generative AI models are foundation models, including GPT-6.1 Sol, Claude Opus 5.5 and Qwen3.8-Max. A small model trained for one narrow task can be generative without being a foundation model.
How do you measure ROI from generative AI models?
Measure cost per task and outcome per task against the current process. Track time saved, error rates and the full bill, including tokens, integration and review time. McKinsey’s State of AI 2026 survey, as reported by FM Magazine, found about 6% of companies get 5% or more of EBIT from AI. A baseline pilot shows which side you sit on.
Is ChatGPT a generative AI model?
ChatGPT is an application built on generative AI models from OpenAI. The model underneath does the generating, and ChatGPT adds the chat window, memory and tools. As of November 2026, ChatGPT Plus costs $20 a month and includes GPT-6.1 Sol and GPT-6 Luna. Pro plans start at $100 a month for heavier use.
What are the main types of generative AI models?
The main types are sorted by the output they produce. Large language models write text and code. Multimodal models read mixed inputs such as images, audio and text. Diffusion models create images and short video. Speech models handle audio in or out. Pick the type your workflow needs first, then compare vendors inside that type.
What is the difference between an LLM and GPT?
An LLM, or large language model, is any model trained on large amounts of text to understand and generate language. GPT is OpenAI’s own family of LLMs. GPT-6.1 Sol is the GPT model this guide picks for company-wide work as of November 2026. Every GPT model is an LLM. Claude, Gemini, Qwen and DeepSeek are LLMs from other vendors.
What are common examples of generative AI?
Common business examples include drafting emails and reports, summarizing contracts, answering policy questions and writing code. Teams also use it to read invoices and claims forms, write product descriptions and transcribe service calls. Each example maps to one model type. Text work uses an LLM, mixed documents use a multimodal model and images use diffusion.
What data are generative AI models trained on?
Vendors train them on large collections of public web text, licensed books and articles, and code repositories. Multimodal models also learn from images and audio. Many vendors add human feedback to tune the answers. Before you send sensitive prompts, check each vendor’s data terms to confirm whether your own inputs can be used for future training.
Are generative AI models always accurate?
No. Generative AI models can produce fluent answers that are wrong, including invented facts, citations and numbers. Accuracy improves when the model answers from retrieved company documents and when a person reviews high-stakes output. Test each model on a set of real tasks from your own business before you trust it with customers or regulators.
Which generative AI model is best for enterprise use in 2026?
No single model wins every job. GPT-6.1 Sol suits company-wide workflows and agents. Claude Opus 5.5 leads on engineering and long knowledge work. Gemini 4 Argon fits long-context work in Google Cloud. Qwen3.8-Max gives open-weight control. DeepSeek V4.1-Flash-1017 handles high-volume work at the lowest verified bill of the five picks.
Are open-weight generative AI models safe for enterprise deployment?
They can be safe when you run them inside your own controls. Self-hosting keeps data in your cloud. Your team then owns security, evaluation and upgrades. Read each license first. DeepSeek uses MIT and Qwen3.8-27B uses Apache 2.0. Qwen3.8-Max and Mistral Large 4 use custom licenses that need a legal review.