TL;DR
On SLMs vs LLMs, pick a small model for narrow, high-volume or private work and a frontier LLM for hard multi-step reasoning. No fixed parameter count separates the two, so judge a model by active parameters, memory footprint and price per token. As of November 3, 2026, Claude Haiku 5.5 and GPT-6 Luna list at $0.10 per million input tokens, while Claude Opus 5.5 lists at $4. At 50 million input and 10 million output tokens a month, that gap is $10 against $400. Open-weight models such as gpt-oss-20b also run within 16GB of memory, which keeps regulated data on your own hardware. Most teams get the best result from routing, which sends each request to a small model first and escalates only the hard ones.
Key Takeaways
- Choose an SLM when the task is narrow, repetitive, latency-bound or private, and a frontier LLM when it needs multi-step reasoning.
- Measure size by active parameters, since gpt-oss-20b holds 21B parameters but activates only 3.6B per token.
- Claude Haiku 5.5 charges $0.10 per million input tokens, a fortieth of Opus 5.5 at $4.
- Self-hosting an open-weight SLM keeps data inside your network but moves the cost to GPU hours and operations.
- Small models store less factual knowledge, so pair them with retrieval and test them on your own data first.
- Routing also pays, because sending 80% of tokens to Haiku 5.5 and 20% to Opus 5.5 cuts the worked example from $400 to $88 a month.
The Password Reset That Cost Frontier Prices
Picture an IT help desk that sends every ticket to a frontier model. Half the queue asks for a password reset, a VPN fix or a software license. Each answer comes back well written, but the invoice climbs with every ticket.
That work is narrow, though. For most tickets the model picks one of a few known answers and fills in a template, thousands of times a day. So the job needs speed, consistency and a low price per call far more than deep reasoning.
This mismatch sits at the center of the SLMs vs LLMs question. Below, we compare the two on cost, latency, privacy, accuracy and customization, using November 2026 prices, and then show how to route between them.
SLMs vs LLMs at a Glance
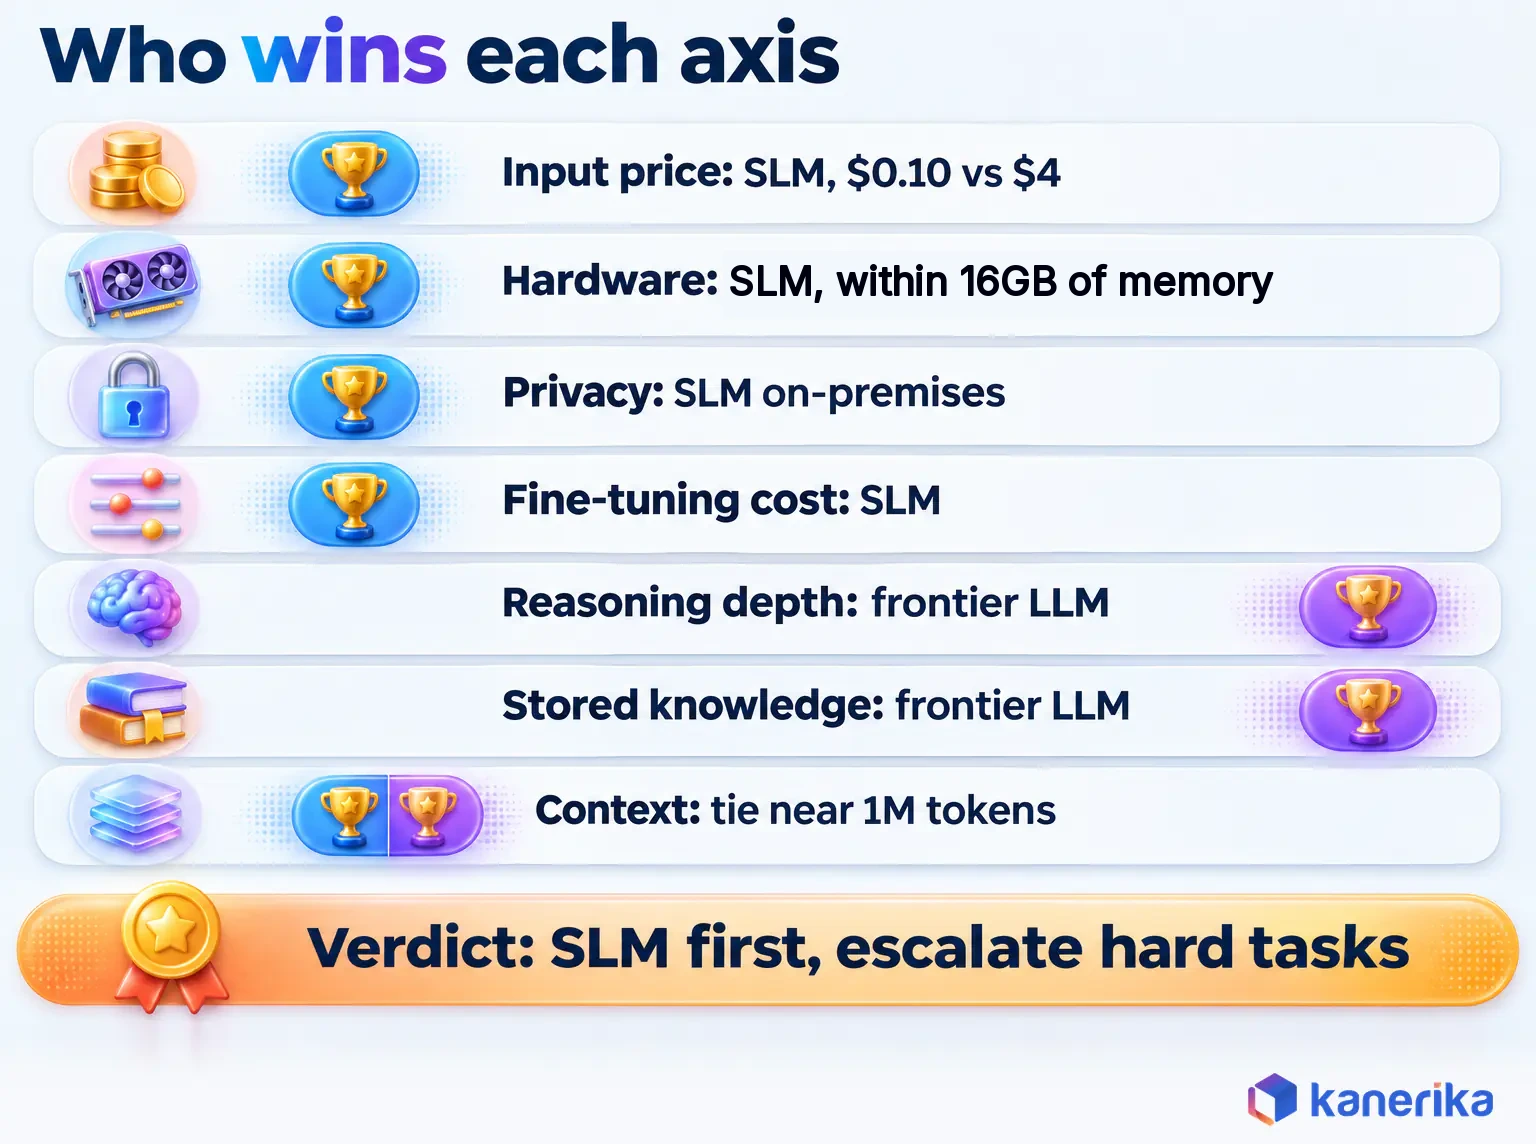
The quickest way to compare the two is axis by axis, because each side wins on different ground. Small models win on price, speed and where they can run, while frontier models win on reasoning depth and stored knowledge.
The table sets hosted small tiers and open-weight models against frontier models. All prices are list prices checked on November 3, 2026.
| Axis | Small language model (SLM) | Large frontier model (LLM) |
|---|---|---|
| Size | A few billion parameters, or a MoE such as gpt-oss-20b with 3.6B active | Hosted vendors rarely publish counts; open gpt-oss-120b holds 117B |
| Cost per 1M tokens | $0.10 input and $0.50 output on Claude Haiku 5.5 or GPT-6 Luna | $2 to $10 input and $10 to $50 output, GPT-6.1 Sol to Claude Fable 5.1 |
| Latency | Fewer calculations per token, so faster replies on modest hardware | Heavier serving, plus a network round trip per API call |
| Hardware | One GPU, a workstation or an edge device | Vendor cloud, or one 80GB GPU even for gpt-oss-120b |
| Privacy and deployment | Self-host on-premises, in a private VPC or at the edge | Mostly a vendor API, so prompts leave your network |
| Accuracy on narrow tasks | Often enough once grounded or fine-tuned | Strong with little setup |
| Reasoning depth | Limited on multi-step, open-ended problems | The main reason to pay frontier prices |
| Customization | Cheap to fine-tune and redeploy | Mostly prompts and retrieval |
Treat the table as a starting default, then test it. The sections below check each row against real prices, hardware limits and deployment options.
Where the Line Between Small and Large Sits in 2026
There is no official parameter count that makes a model small. Guides and vendors draw the line in different places, and mixture-of-experts designs blur it further.
A more useful test is therefore practical. Can the model run on one GPU, a workstation or an edge device, at a price that suits high-volume work? If you want the basics first, start with what small language models are, then come back to the trade-offs here.
Hosted models complicate the picture because vendors do not publish their parameter counts. In practice, a hosted small tier such as Claude Haiku 5.5 plays the small-model role, even though its size is unknown. Our overview of types of generative AI models also shows where these tiers sit among other model families.
Total Parameters vs Active Parameters
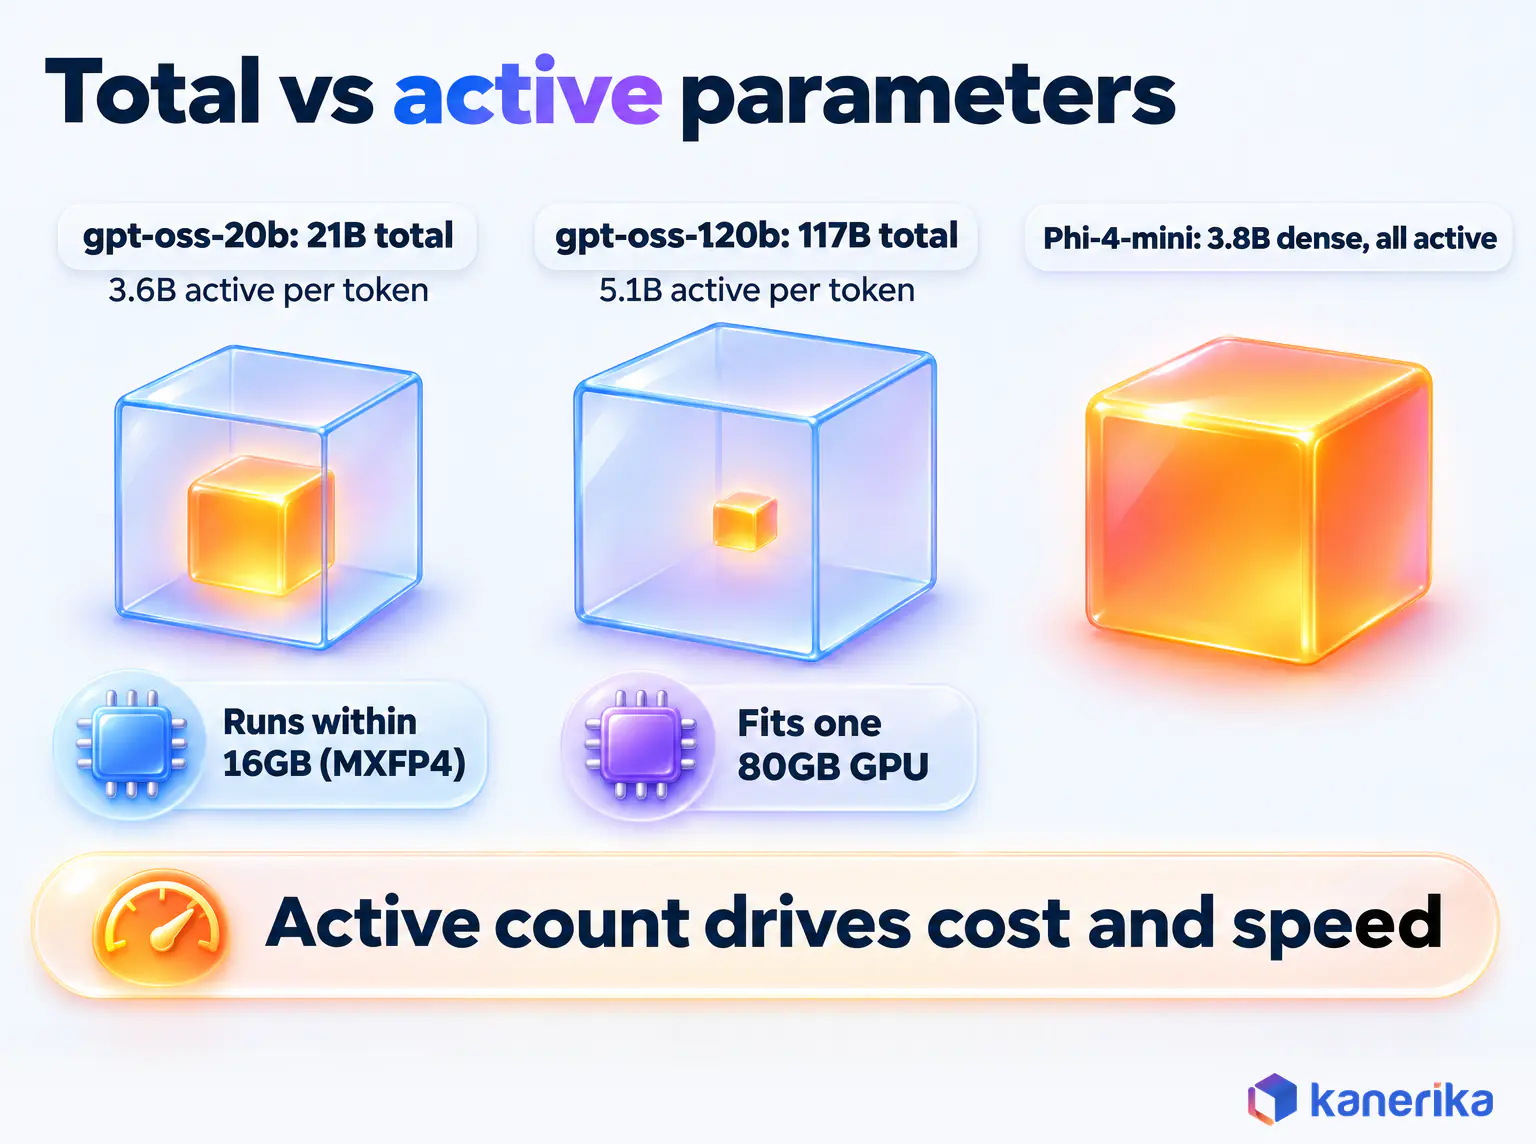
Mixture-of-experts (MoE) models split their weights into expert blocks and use only a few blocks for each token. As a result, the total count sets how much the model must load, while the active count drives the compute behind every token.
For example, the gpt-oss-20b model card lists 21B parameters with 3.6B active. The model runs within 16GB of memory using MXFP4 quantization of the MoE weights. Its larger sibling, gpt-oss-120b, holds 117B parameters with 5.1B active and can run on a single 80GB GPU such as an H100.
Those numbers show why the label gets slippery. A 21B model that computes like a 3.6B one behaves small on cost and speed, yet it stores far more than a dense 3.8B model. For the mechanics behind this, see how LLM architecture works.
How Small Models Are Made
Teams get a small model in three main ways, and many production models also combine them.
- Distillation. A large teacher model produces examples or soft labels, then a smaller student model learns to imitate it on target tasks.
- Quantization. Weights are stored at lower precision, such as the MXFP4 format, so memory drops at a small accuracy cost.
- Task fine-tuning. A compact base model trains further on domain examples, so it learns one job well instead of everything a little.
Each method gives something up. Distillation and fine-tuning narrow what the model knows, and aggressive quantization can cost accuracy, so measure the result on your own tasks.
The 2026 Field: Small Tier vs Frontier Models
The model field shifts every few weeks, so read this section as a snapshot taken on November 3, 2026. It pairs hosted small tiers and open-weight models with the frontier models they would escalate to.
| Model | Tier | Access | Price per 1M tokens (in / out) | Context | License |
|---|---|---|---|---|---|
| Phi-4-mini-instruct | Small, 3.8B dense | Open weights | No per-token fee | 128K | MIT |
| gpt-oss-20b | Small, MoE, 3.6B active | Open weights | No per-token fee | See model card | Apache 2.0 |
| Qwen3.8-27B | Small to mid, 27B dense | Open weights | No per-token fee | 262,144 native, up to 1M | Apache 2.0 |
| Claude Haiku 5.5 | Hosted small tier | API | $0.10 / $0.50 | 1M | Vendor terms |
| GPT-6 Luna | Hosted small tier | API | $0.10 / $0.50 | 1.05M | Vendor terms |
| Gemini 3.8 Flash | Hosted low-cost tier | API | $0.75 / $3.75 to Dec 31, 2026 | See Google docs | Vendor terms |
| GPT-6.1 Sol | Frontier | API | $2 / $10 | 1,050,000 | Vendor terms |
| Gemini 4 Argon | Frontier | API | $2 / $10 to Nov 30, 2026, then $4 / $20 | See Google docs | Vendor terms |
| Claude Opus 5.5 | Frontier | API | $4 / $20 | 1M, 128K output | Vendor terms |
| Claude Fable 5.1 | Frontier | API | $10 / $50 | 1M, 128K output | Vendor terms |
Two patterns stand out. First, hosted small tiers have reached context windows of about 1M tokens, so context length alone no longer pushes you to a frontier model. Second, Gemini 3.8 Flash sits between the tiers, priced above Haiku 5.5 but far below the frontier.
What the Frontier Tier Looks Like
At the top, Anthropic’s models overview recommends Opus 5.5 for most work. Opus 5.5 also matches or beats Fable 5.1 on most listed benchmarks, at 40% of Fable’s price. Gemini 4 Argon is also live, with a model card published on October 13, 2026, but Google’s pricing page does not label it generally available.
Release dates matter because each tier turns over within months, so a model chosen today needs a re-test plan. Haiku 5.5 (October 7, 2026), Opus 5.5 (September 22) and GPT-6.1 Sol (September 29) all arrived within three weeks of each other. Phi-4-mini-instruct dates from February 2025, so treat it as an older reference point.
For deeper head-to-heads, read our Claude Opus vs Mistral comparison and the look at how Jev compares with general LLMs.
Kanerika Service
LLM Development Services
Kanerika designs, adapts and deploys language models, small and large, with retrieval, routing and governance built in for enterprise workloads.
Explore LLM DevelopmentSLMs vs LLMs on Cost: Per-Token Prices and a Worked Month
Price is where the gap between the two is widest, and it compounds with volume. Per-token prices look tiny on their own, so the clearest comparison is a realistic month of traffic.
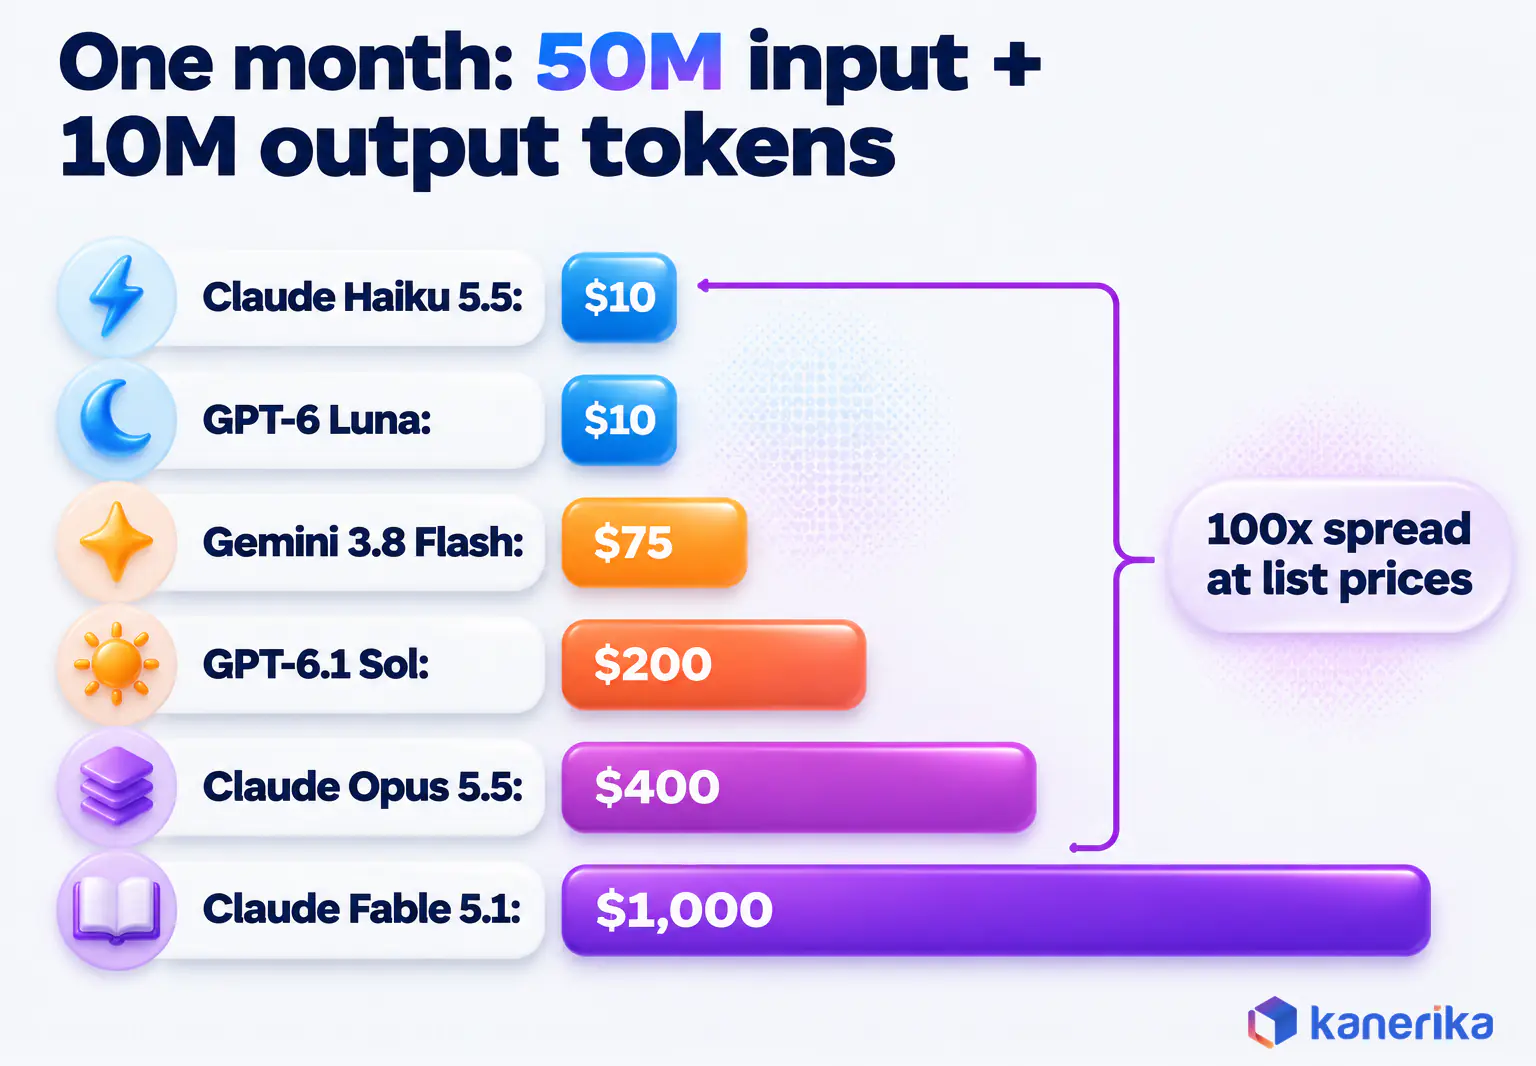
Take, for example, a workload of 50 million input tokens and 10 million output tokens a month. Also assume each prompt stays under 100,000 tokens and no caching or batch discounts apply. At list prices on November 3, 2026, the monthly bill looks like this.
| Model | Input / output per 1M tokens | Input cost | Output cost | Monthly total |
|---|---|---|---|---|
| Claude Haiku 5.5 | $0.10 / $0.50 | $5 | $5 | $10 |
| GPT-6 Luna | $0.10 / $0.50 | $5 | $5 | $10 |
| Gemini 3.8 Flash | $0.75 / $3.75 | $37.50 | $37.50 | $75 |
| GPT-6.1 Sol | $2 / $10 | $100 | $100 | $200 |
| Claude Opus 5.5 | $4 / $20 | $200 | $200 | $400 |
| Claude Fable 5.1 | $10 / $50 | $500 | $500 | $1,000 |
The spread is a factor of 100 between the cheapest and the most expensive option. Prices also move on fixed dates. After December 31, 2026, Gemini 3.8 Flash rises to $1.50 and $7.50, which doubles its line to $150. Gemini 4 Argon, meanwhile, moves from $2 and $10 to $4 and $20 on December 1.
Long prompts change the math as well. OpenAI’s pricing page bills GPT-6.1 Sol prompts over 272K tokens at 2x input and 1.5x output. Similarly, Anthropic’s pricing page charges $2.50 per million output tokens on Haiku 5.5 prompts above 100k. Google’s Gemini pricing lists the dated Flash and Argon changes.
What Self-Hosting Really Costs
Self-hosting changes the cost model rather than removing it. An open-weight model has no per-token fee, but you pay for GPU hours whether the card is busy or idle. The real unit cost therefore depends on utilization, so a self-hosted SLM is cheapest when traffic is steady and high.
Engineering time, monitoring and upgrades add to that bill. Our breakdown of AI development cost covers those line items, and the DeepSeek guide shows how open-weight pricing plays out for one model family.
Latency, Throughput and Hardware
Speed depends on how much work the hardware does for each token, and small models simply do less of it. Because fewer active parameters mean fewer calculations, replies start sooner and one GPU can serve more users at once.
Memory, however, is usually the binding limit. A model must fit in GPU memory with room left for the context cache, so precision matters as much as parameter count. With MXFP4 quantization of the MoE weights, for instance, gpt-oss-20b fits within 16GB of memory. Its sibling gpt-oss-120b can run on a single 80GB GPU such as an H100.
Frontier models sit at the other end. Hosted APIs hide the cluster behind them, but every call still crosses the network, which adds round-trip time that a local model avoids.
- Edge devices and laptops: compact models such as Phi-4-mini, at 3.8B parameters, suit offline work because they need little memory. Our edge AI guide also covers the patterns.
- One workstation GPU: gpt-oss-20b runs within 16GB of memory, so it suits internal assistants and batch jobs.
- One 80GB GPU: gpt-oss-120b can run on a single 80GB GPU such as an H100 when private workloads get heavier.
- Vendor API: frontier models with no hardware to manage, but billed per token.
Serving software is the last piece of the setup. Our comparison of vLLM vs Ollama covers two common ways to run open models.
Privacy, Data Residency and Deployment Options
Where a model runs decides who can see your prompts, and that often settles the choice before cost does. A frontier model reached by API means data leaves your network, while an open-weight SLM can run entirely inside it.
| Deployment option | Where the data goes | Best fit |
|---|---|---|
| Public vendor API | Prompts go to the vendor’s cloud under its terms | Non-sensitive data that needs frontier reasoning |
| Private VPC | An open-weight model runs in your own cloud account | Regulated data that still needs cloud scale |
| On-premises | Model and data stay in your data center | Strict residency or air-gapped rules |
| Edge device | Inference runs on the device itself | Offline work, low latency and local data |
Small models make the last three rows practical, because they fit modest hardware. So a regulated team can keep customer records on a self-hosted SLM and send only approved, de-identified data to a frontier API.
That split also simplifies audits, since the sensitive path never touches a third party. For deeper reading, see our guides to private LLMs, AI privacy and LLM security.
Licensing and Governance Checks
Open weights do not grant unlimited rights, so read the license before you build on a model. Qwen3.8-27B and gpt-oss-20b ship under Apache 2.0, and Phi-4-mini-instruct uses MIT, both permissive for commercial work. Other open models, however, carry custom licenses with usage limits, so our ranking of top LLMs and the guide to open-source LLMs are worth checking before you shortlist one.
Governance still applies at every size. The NIST AI Risk Management Framework, version 1.0, was released on January 26, 2023 as a shared structure for managing model risk. Its Generative AI Profile, NIST-AI-600-1, then followed on July 26, 2024.
Our AI governance framework guide and AI governance services apply that structure to enterprise rollouts.
Checklist
Generative AI Checklist
Work through data, security, model and governance questions before a generative AI rollout, including where each workload should run and who can see its prompts.
Get the Checklist →Accuracy, Reasoning and Context: Where Small Models Fall Short
Small models make different mistakes, and knowing which ones keeps a deployment honest. Their main gap is stored knowledge, because fewer parameters hold fewer facts.
Microsoft says so directly. The Phi-4-mini-instruct model card notes that the model lacks the capacity to store much factual knowledge. It also suggests pairing the model with search or retrieval, a trade-off worth testing in any compact model.
Reasoning is the second gap. Multi-step planning, ambiguous instructions and synthesis across many documents favor frontier models, which is why vendors price them higher. Still, a small model can handle one step inside that workflow, such as classifying or extracting, while a larger model plans.
Context length divides the tiers less than it used to. Claude Haiku 5.5 accepts 1M tokens and GPT-6 Luna 1.05M, while the Qwen3.8-27B model card lists 262,144 tokens natively and up to 1M. Window size and long-document reasoning are different skills, though, so test recall on your own files.
Even so, grounding closes much of the knowledge gap. A RAG pipeline feeds the model relevant passages at query time, and our guide to LLM hallucination covers the checks that catch confident errors.
Customization: Fine-Tune, RAG or Prompt?
Adapting a model to your business costs less on a small one, but the right lever depends on what is missing. Missing facts call for retrieval, a missing skill or format calls for fine-tuning, and a clear task may need only a good prompt.
| Lever | Use it when | Model size it suits |
|---|---|---|
| Prompting | The task is clear and a few examples fit in the prompt | Both sizes, and always the first thing to try |
| Retrieval (RAG) | Answers depend on company documents that change | Both sizes, and close to essential for small models |
| Fine-tuning | You need a fixed format, tone or narrow skill at high volume | Mostly small models, which are cheap to train and redeploy |
Small models reward fine-tuning because each training run is short and the result is yours to host. Parameter-efficient fine-tuning also trains small adapter layers instead of all the weights, which cuts the hardware bill further.
Kanerika Service
RAG Development Services
Kanerika builds retrieval pipelines that ground small and large models in your own documents, with access control at the retrieval layer.
Explore RAG DevelopmentFrontier models, by comparison, are usually adapted through prompts and retrieval, since closed frontier models cannot be self-hosted, and training any large model costs far more. Our guide to RAG vs fine-tuning compares the two approaches in detail.
When an SLM Is the Right Choice
A small model is the right default when the task is well defined and repeats at volume. Each rule below describes a situation where its strengths decide the outcome.
Think of an invoice-coding queue, a support triage step or a field technician’s offline assistant, for example. Each has a clear input, a clear output and enough traffic that price per call matters.
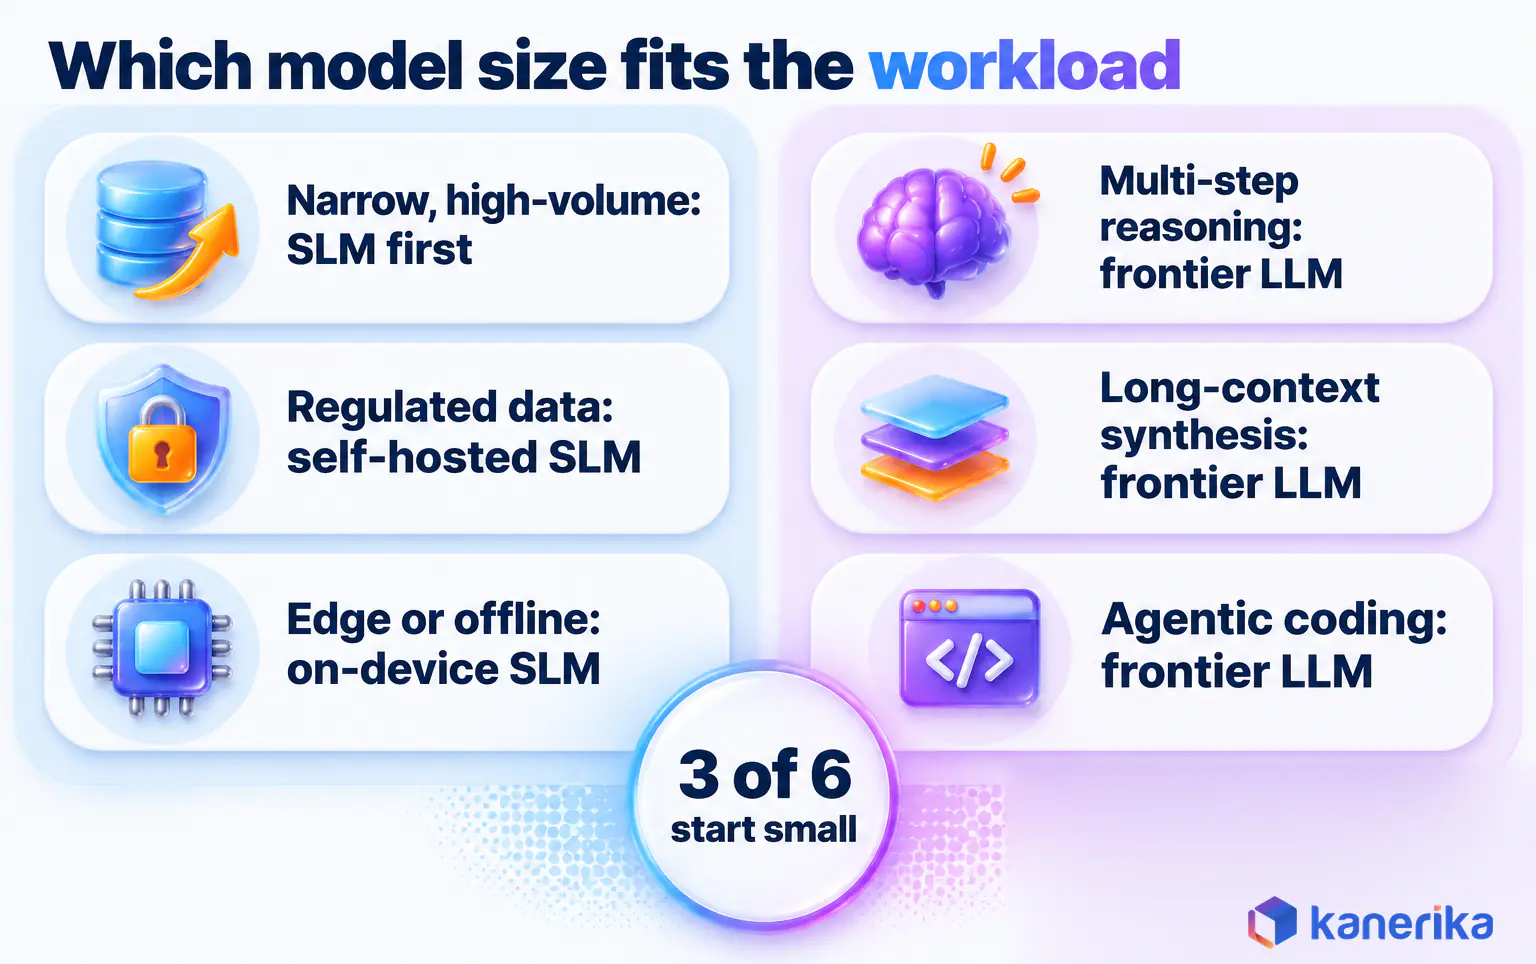
- Narrow, repetitive tasks. Classification, extraction, routing and templated replies need consistency more than deep reasoning.
- High volume. When calls reach millions a month, a 20x to 100x gap in input price decides the budget.
- Tight latency. Chat, autocomplete and in-app features feel slow when every token waits on a large model.
- Regulated or private data. A self-hosted open-weight model keeps records inside your network, so no vendor sees them.
- Edge or offline use. Field devices and plants with weak connectivity need a model that still runs when the network drops.
If two or more rules apply, start with a small model and prove that it fails before you pay for a larger one. In most cases, retrieval then covers its knowledge gaps.
When a Frontier LLM Is the Right Choice
A frontier model earns its price when the task is open-ended or a wrong answer is expensive. Picture a contract review that weighs clauses across forty documents, or an analyst asking why margins fell in one region.
Those requests chain several judgments together, so a small model tends to lose the thread partway. The cases below are where the premium pays for itself.
- Multi-step reasoning. Planning and analysis, because each decision depends on the steps before it.
- Long-context synthesis. Combining many documents into one judgment, since recall alone is not enough.
- Agentic coding and tool use. Agents that write code or call tools across long sessions, as our agentic AI guide also explains.
- Rare, ambiguous requests. Expert questions with low volume, so the price premium barely moves the bill.
- Fallback for weak small-model answers. The escalation target when the small model in a routing setup is unsure.
That is why many enterprise LLM programs end up using both. In short, the frontier model handles the hard tail, and a small model carries the volume.
Hybrid Routing: Start Small, Escalate to Large
Routing turns SLMs vs LLMs from a choice into a pipeline. Every request goes to a small model first, and only the requests it cannot handle confidently move up to a frontier model.
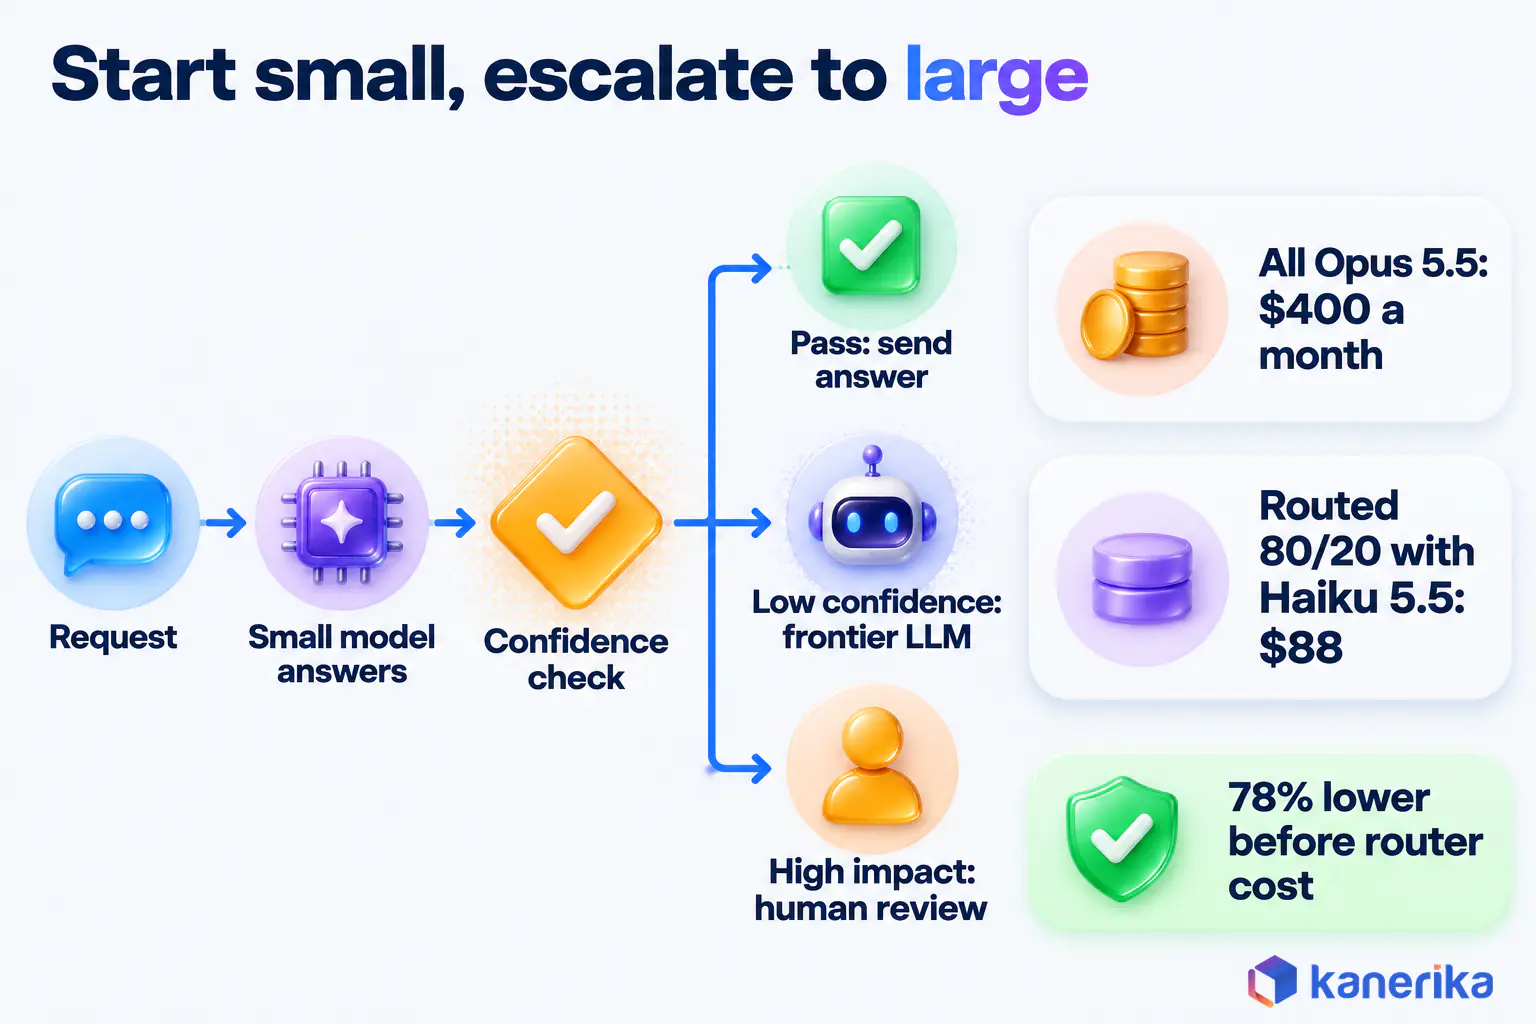
- Classify the request. A rule set or a small classifier first tags the task type and data sensitivity.
- Answer with the small model. Most routine requests then end here.
- Check confidence. A score, a validator or a format check decides whether the answer is good enough before it goes out.
- Escalate the rest. Low-confidence or complex requests go to the frontier model instead.
- Send risky cases to a person. High-impact answers get human review before they reach a customer.
The savings then follow from the split. In the worked month, routing 80% of tokens to Haiku 5.5 costs $8, and escalating the other 20% to Opus 5.5 costs $80. That makes $88 a month against $400 for all-Opus, a 78% cut before the router’s own cost.
Build or Buy the Router
Managed options exist if you would rather not build the router. For instance, the Microsoft Foundry model router sends each prompt to the most suitable model. Its default Balanced mode picks the cheapest model within about 1-2% of the best quality. Cost mode widens that band to about 5-6%, whereas Quality mode ignores cost.
A self-built router usually sits behind an LLM gateway, which also handles authentication, logging and rate limits. Track the escalation rate through LLMOps observability, because a rising rate means the traffic changed or the small model is drifting.
Tune the confidence threshold with care. Set it too low and weak answers slip through, but set it too high and most traffic escalates, which erases the savings. Start with a conservative setting, then review a sample of escalated and kept answers each week and adjust in small steps.
Testing SLMs vs LLMs: A Five-Step Evaluation on Your Own Data
Public benchmarks rank models on someone else’s tasks, so the reliable test is your own traffic. This five-step protocol compares one small and one large candidate on equal terms.
- Build a golden set. Collect a few hundred real requests with approved answers, and also include the hard and sensitive cases.
- Define pass criteria. Agree on accuracy, format, latency and cost-per-request thresholds before any test runs.
- Run both candidates. Test a small model and a frontier model on the same set, so prompts and retrieval stay identical.
- Compare cost per correct answer. Divide the monthly cost by passing answers rather than raw requests.
- Pilot the router. Send live traffic through the small model with escalation, then watch the escalation rate for a few weeks.
Our LLM evaluation framework guide covers scoring methods in more depth.
Cost per correct answer can reverse the price ranking on hard tasks, because a cheap model that fails often creates rework. On routine tasks, by contrast, SLMs usually win outright while LLMs keep the hard tail, and the pilot shows by how much. Keep the golden set after launch as well, since every new model release calls for a fresh run against it.
How Kanerika Helps Teams Pick and Run the Right Model Size
Kanerika treats model size as a decision for each workload rather than for the whole company. Through our LLM development services and AI model services, we run five stages. Each stage produces evidence for the next, so the final model mix rests on measured results from your own workloads.
- Workload inventory and tiering. We first list each AI task, then tag it as narrow and high-volume or reasoning-heavy.
- Golden-set evaluation. We test a small and a large candidate on the client’s own data, then compare cost per correct answer.
- Deployment by data class. Each class of data then gets a home, whether a vendor API, a private VPC or on-premises servers.
- Routing and guardrails. Confidence thresholds decide escalation, while human review covers high-impact answers.
- Monitoring. We track accuracy, latency and spend, then retune thresholds as traffic shifts.
Case Study
43% Faster Data Retrieval for a Global Investment Bank
43% faster information retrieval and 35% higher workforce efficiency for a global investment bank.
Read the Case Study →What One Investment Bank Project Shows
The same thinking shaped our work for a global investment bank. There, Kanerika paired DokGPT for unstructured RFI documents with Karl for structured databases, both behind one chat interface with role-based access control.
The bank recorded 43% faster information retrieval, 100% role-based compliance and 35% higher workforce efficiency. It ran two task-specific assistants instead of one general model, and sensitive data stayed under access control. The case study does not say which model sizes ran underneath.
Even so, the lesson for model choice is scope. Each assistant had one job and one class of data, which is the same shape that lets a smaller, cheaper model do the work. So when we scope a new project, we start from that shape and only reach for frontier capacity where the task demands it.
DokGPT and Karl are part of FLIP, Kanerika’s platform for data and AI work, so teams start from existing assistants instead of building from scratch.
So, SLMs or LLMs? Use an SLM for narrow, high-volume and private work, and a frontier LLM for hard reasoning. Then route between them, so each request lands on the cheapest model that answers it well.
Talk to Kanerika
Not Sure Which Model Size Fits Your Workload?
Talk to Kanerika about testing a small and a frontier model on your own data and designing the routing and guardrails between them.
Talk to an Expert →Frequently Asked Questions
What is the difference between SLMs and LLMs?
SLMs are compact language models that run on modest hardware, cost less per token and answer faster. LLMs, especially frontier models, store far more knowledge and handle multi-step reasoning better. The practical difference is fit, so an SLM suits narrow, high-volume or private tasks while a frontier LLM suits open-ended analysis, planning and synthesis.
What are SLMs in AI?
SLMs, or small language models, are language models sized to run on one GPU, a workstation or an edge device. They use the same transformer design as large models with fewer parameters, or with few active parameters in a mixture-of-experts design. Examples include Phi-4-mini-instruct at 3.8B parameters and gpt-oss-20b, which runs within 16GB of memory.
Are SLMs better for data privacy and compliance?
They often make compliance easier, because an open-weight SLM can run on-premises or in a private cloud, so sensitive prompts never reach a vendor. The model alone does not make a system compliant, though. Access control, logging, output checks and a risk framework such as the NIST AI RMF still apply, whatever the model size.
Can small language models handle complex reasoning?
Only to a limited degree. Small models handle single, well-defined steps such as classifying or extracting, but they tend to lose the thread on long multi-step plans and open-ended synthesis. Microsoft’s Phi-4-mini card also notes limited factual knowledge. For complex reasoning, use a frontier model or let the small model handle one step inside a larger workflow.
What are SLMs used for?
Common uses include ticket classification, document field extraction, intent routing, templated replies, answering questions over company data with retrieval, and offline assistants on field devices. These jobs share a clear input, a clear output and high volume. That profile rewards a model that is cheap per call, fast to respond and easy to host inside your own network.
Are SLMs cheaper to run than LLMs?
Usually, yes. In a worked month of 50 million input and 10 million output tokens, Claude Haiku 5.5 costs $10 at list price while Claude Opus 5.5 costs $400. Self-hosted SLMs drop per-token fees but add GPU hours, monitoring and staff time, so compare the full running cost at your real traffic level before you decide.
What are the advantages of SLMs?
Small language models cost less per request, respond faster and fit modest hardware, so they can run on-premises, in a private cloud or on edge devices. They are also cheap to fine-tune and redeploy for one task. The trade-off is less stored knowledge and weaker multi-step reasoning, which retrieval and routing to a frontier model can offset.
What parameter count qualifies as a small language model?
No official threshold exists, and guides draw the line in different places. A practical test is whether the model runs on one GPU or an edge device at a price that suits high-volume work. Mixture-of-experts models blur the count, since gpt-oss-20b holds 21B parameters but activates only 3.6B for each token it produces.
When should you use an LLM instead of an SLM?
Use a frontier LLM when the task needs multi-step reasoning, synthesis across many long documents, agentic coding or tool use, or expert answers to rare and ambiguous questions. These requests are usually lower in volume, so the higher price per token matters less. A frontier model also works well as the escalation target behind a small model.
Can small language models run on-premises or on edge devices?
Yes. Open-weight small models can run entirely on your own servers or devices, so prompts never leave your network. The gpt-oss-20b model runs within 16GB of memory with MXFP4 quantization of its MoE weights, and compact models such as Phi-4-mini at 3.8B parameters suit laptops and offline field work. Check each model’s license before commercial use.
Should you fine-tune an SLM or use RAG with an LLM?
It depends on what is missing. If answers depend on changing company documents, add retrieval, which helps models of any size. If you need a fixed format, tone or narrow skill at high volume, fine-tune a small model, since training runs are short and you host the result yourself. Many teams combine a tuned SLM with retrieval.
How does hybrid SLM and LLM routing work?
A router sends each request to a small model first, checks the answer with a confidence score or validator, and escalates weak or complex requests to a frontier model. Risky cases go to a person. In our worked example, routing 80% of tokens to Haiku 5.5 and 20% to Opus 5.5 costs $88 a month instead of $400.