TL;DR
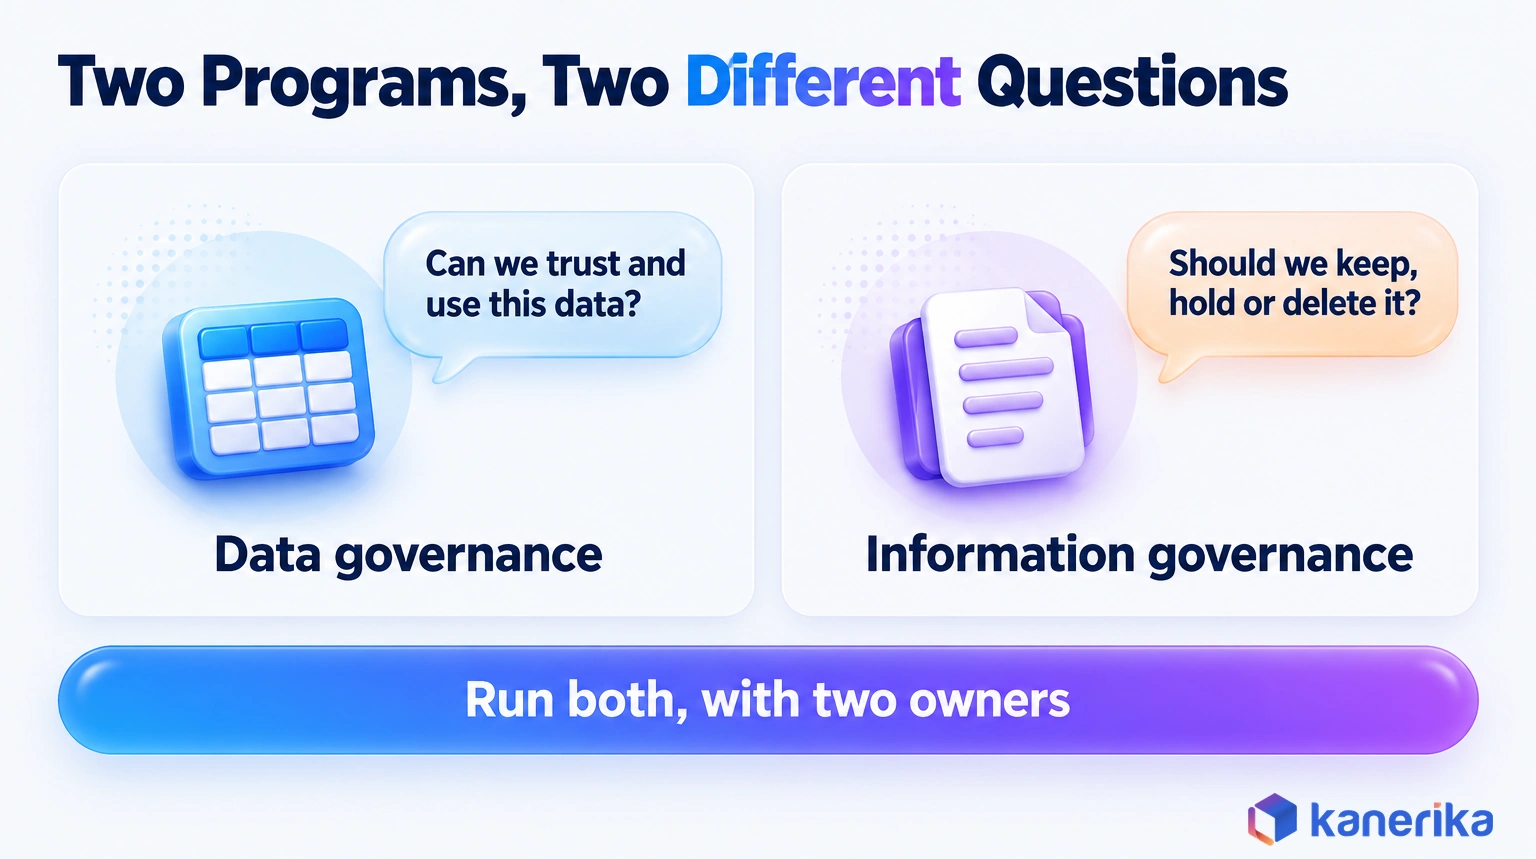
In data governance vs information governance, start with data governance when analytics or AI trust is the risk, and information governance when litigation or retention is. Data governance makes structured data accurate, owned and safe to use through quality rules, a catalog, lineage and access policies. Information governance, on the other hand, controls the lifecycle and risk of every information asset, from email and contracts to chat and paper records.
It decides what to keep, for how long, what goes on legal hold and what gets deleted. The two meet on privacy, security and classification, so they should share one inventory and one labeling scheme. Run them as one program with two owners, the data office on one side and legal, records and privacy on the other.
Key Takeaways
- Data governance covers structured data and asks one question, which is whether the data is accurate, understood and safe to use.
- Information governance covers every information asset, including email, documents, chat, recordings and paper, and asks whether it should be kept, held or deleted.
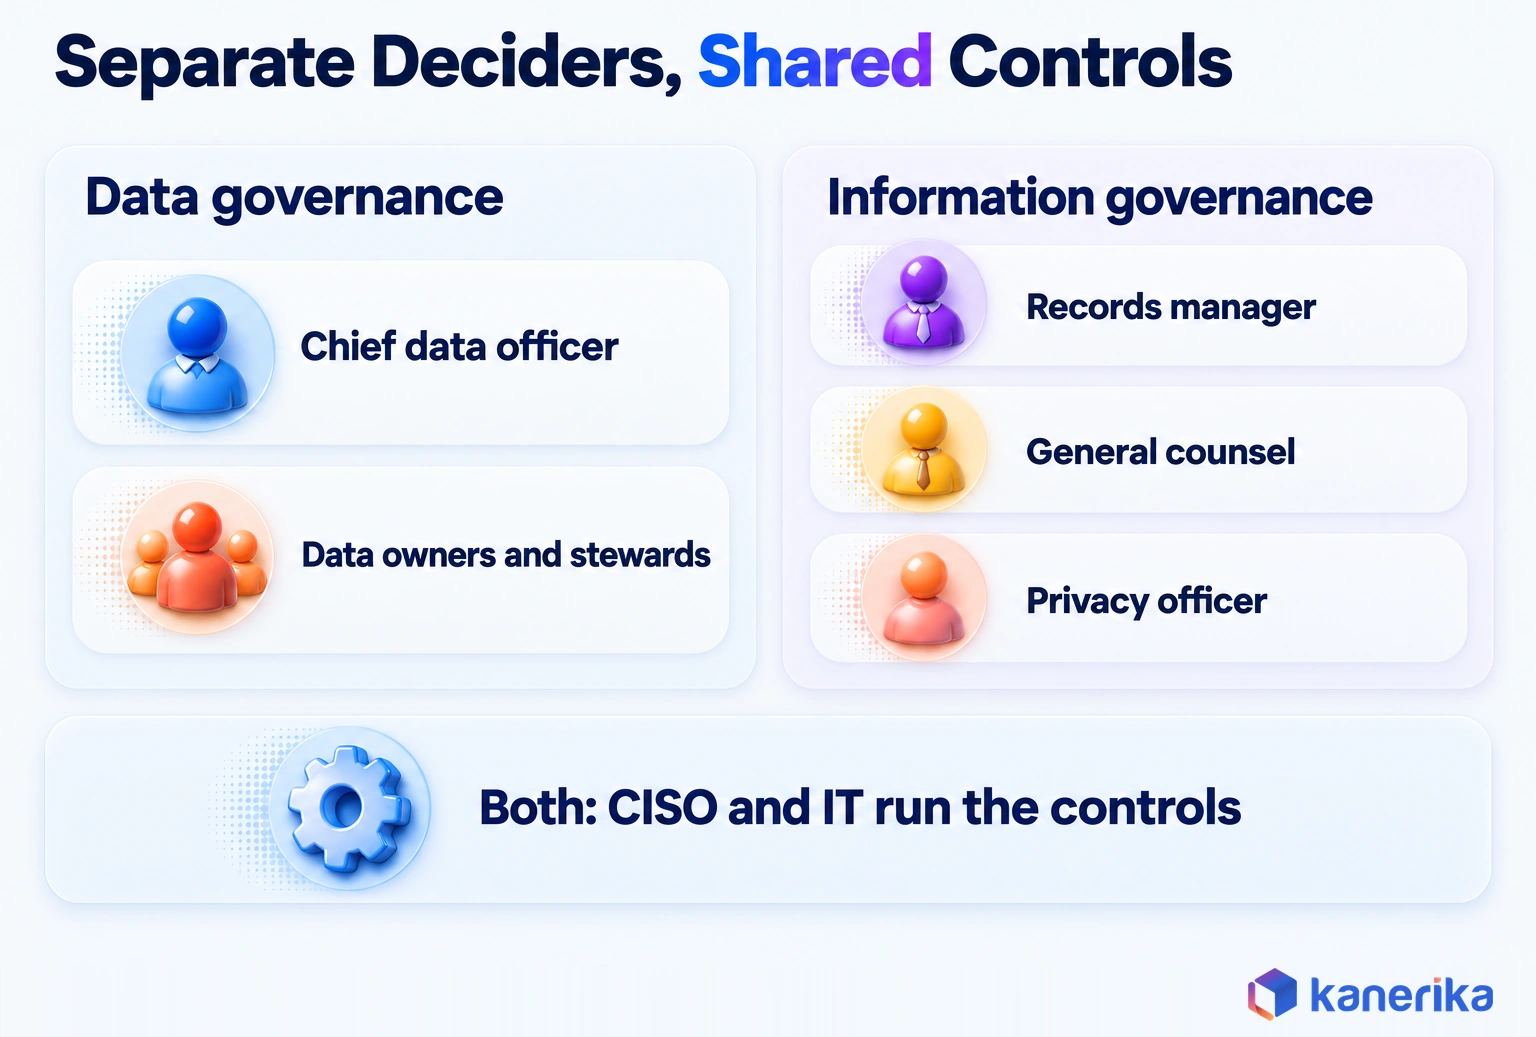
- Ownership differs, since a chief data officer and data stewards usually lead data governance while records management, legal and privacy lead information governance.
- Their controls differ too, with quality rules, catalogs, lineage and access policies on one side and retention schedules, legal holds and disposition on the other.
- You can treat data governance as one component of information governance or as a peer program, so pick the model that matches your reporting lines.
- Start with the program that addresses your biggest risk, then connect both through a shared inventory, one classification scheme and a joint decision-rights table.
When a Clean Customer Record Still Fails a Legal Review
A regional US lender spent two years cleaning up its customer master data. As a result, every customer record has an owner, a quality score and a lineage map in the catalog.
Then a borrower files a lawsuit, and the legal team sends a preservation request to IT.
Legal then needs three answers fast. Which emails and signed loan agreements mention this customer? Are any of them already under a legal hold? And which ones were past their retention date and should have been deleted long ago?
The data team cannot answer any of them. The catalog covers database tables rather than inboxes, shared drives or scanned contracts. Nobody owns the retention schedule for those files either.
That gap is the practical difference between the two disciplines. Data governance made the customer record trustworthy, while information governance would have made every document about that customer findable, held and disposed of on schedule. This guide sets out data governance vs information governance in plain terms. It also shows where each one stops, then helps you decide which to fund first.
What Is Data Governance?
Data governance is the set of decisions, roles and controls that keep an organization’s data accurate, understood and safe to use. It is easiest to define by what it actually runs each day, rather than by a mission statement.
Its scope is mostly structured and semi-structured data rather than documents. That means tables in a data warehouse, records in a CRM, files in a lakehouse and the reports built on top of them. The goal is simple to state: anyone who uses a number should be able to trust where it came from and what it means.
Many programs borrow their vocabulary from the DAMA Data Management Body of Knowledge, known as DAMA-DMBOK, because it is a common reference for the discipline. DAMA launched a DMBOK 2.0 revision in 2024 and started work on DMBOK 3.0 in 2025 (DAMA International).
In practice, a data governance program runs four kinds of control:
- Ownership: a named data owner and a data steward for each critical data element.
- Quality rules: measurable thresholds for completeness, validity and timeliness, checked automatically.
- Catalog and lineage: agreed business definitions, plus a data lineage map of where each field comes from and where it flows.
- Access: policies that decide who can read, change or share each data set, a practice known as data access governance.
A Worked Definition: The Active Customer
Take the definition of an active customer. Sales counts anyone who bought something in the past 24 months, while finance counts anyone with an open balance. Each team builds its own report, so the board sees two customer counts that never match.
Data governance settles it in one pass: the customer data owner approves one definition, and the data steward publishes it in the business glossary. A quality rule flags any record missing a last-purchase date. When the failure rate passes an agreed threshold, say 2%, the steward gets an alert.
That is the whole discipline in miniature: one owner, one definition and one measurable rule. Our guide to building a data governance framework also shows how those pieces scale into a full program.
Kanerika Service
Data Governance Services
Kanerika sets up ownership, quality rules, catalog, lineage and access policies, then connects them to your retention and privacy controls.
Explore Data Governance Services
What Is Information Governance?
Information governance is the policy-led control of all the information an organization creates or receives, across its full lifecycle. It also weighs the value of information against its risk and its legal obligations. Data governance asks whether data is fit to use, while information governance asks whether a piece of information should still exist, and for how long.
Its scope is wider and messier than a data platform. It covers email, contracts, office files, chat messages, meeting recordings, scanned forms and paper archives, as well as databases. Because of that breadth, the disciplines inside it include records management, retention schedules, legal hold, eDiscovery, privacy and defensible disposition.
Defensible disposition deserves a plain definition, because it is the part most teams skip. It means deleting information on a documented schedule, so you can later show a court or a regulator exactly why it is gone.
Consider signed customer contracts, for example. An information governance policy might classify every signed agreement as a contract record and keep it for seven years after the contract ends. After that, the file is deleted unless a legal hold applies.
The retention clock starts on an event, the contract end date, rather than on the day the file was saved. A records manager owns that schedule, and legal can suspend deletion whenever a dispute appears.
The Eight Recordkeeping Principles
Many records programs anchor on ARMA International’s Generally Accepted Recordkeeping Principles, which name the eight principles listed below (TechTarget).
One useful way to read them is in three groups. Accountability, transparency and compliance describe how the program is run, while integrity, protection and availability overlap with data governance. Retention and disposition form the lifecycle core, and those decisions sit outside data governance even when it carries out a deletion.
- Accountability: a senior leader oversees the program.
- Transparency: processes are documented and open to review.
- Integrity: records are authentic and reliable.
- Protection: sensitive information is secured.
- Compliance: the program meets laws and internal policy.
- Availability: records can be found when needed.
- Retention: information is kept for the right period.
- Disposition: information is disposed of securely when its time ends.
Notice how little of this list concerns data quality. Information governance cares that a record is authentic and retrievable rather than that a revenue figure inside it is correct. With so little overlap, one program cannot simply stand in for the other.
Talk to Kanerika
Need Both Programs Mapped to Owners?
Kanerika can map your data and records decisions to owners, find the gaps between data governance and information governance, and plan the first 90 days.
Schedule a Demo →
Data Governance vs Information Governance: Side-by-Side Comparison
The fastest way to see the difference is to ask the same ten questions of each program, then compare the answers. The answers diverge on almost every row, even though both programs carry the word governance and often report to the same executive committee.
| Dimension | Data governance | Information governance |
|---|
| Scope | Structured and semi-structured data used in operations, analytics and AI | All information the organization creates or receives, in any format |
| Asset types | Tables, data sets, data products, reports, metrics | Email, documents, contracts, chat, recordings, paper records, plus databases |
| Main question | Is this data accurate, understood and safe to use? | Should we keep this, hold it or delete it, and can we prove why? |
| Usual owner | Chief data officer, data owners and data stewards | Records manager, general counsel, privacy officer |
| Main drivers | Trusted reporting, analytics and AI readiness | Litigation risk, regulatory retention, privacy, storage cost |
| Core controls | Definitions, quality rules, lineage, access policies | Retention schedules, legal hold, records declaration, disposition |
| Tool categories | Data catalog, data quality, lineage, access policy | Records management, lifecycle and retention, eDiscovery, DLP |
| Success measures | Owner coverage, quality-rule pass rate, lineage coverage | Retention coverage, disposition backlog, time to preserve on hold |
| Typical failure | Two reports disagree, or an AI model learns from bad data | Evidence cannot be produced, or data is kept far past its limit |
| Time horizon | Fitness of data at the point of use and for its next use | The full life of a record, often many years |
What the Comparison Shows
Read the table by row and one pattern in data governance vs information governance stands out. Data governance is judged by trust in what the data says, so its failures show up as conflicting dashboards and stalled AI projects.
Information governance is judged by control over what information exists, so its failures show up in court, in audits and in storage bills. The two programs also run on different clocks. Data governance cares about the next use of the data, while information governance tracks a record until the day it is destroyed.
Is Data Governance Part of Information Governance?
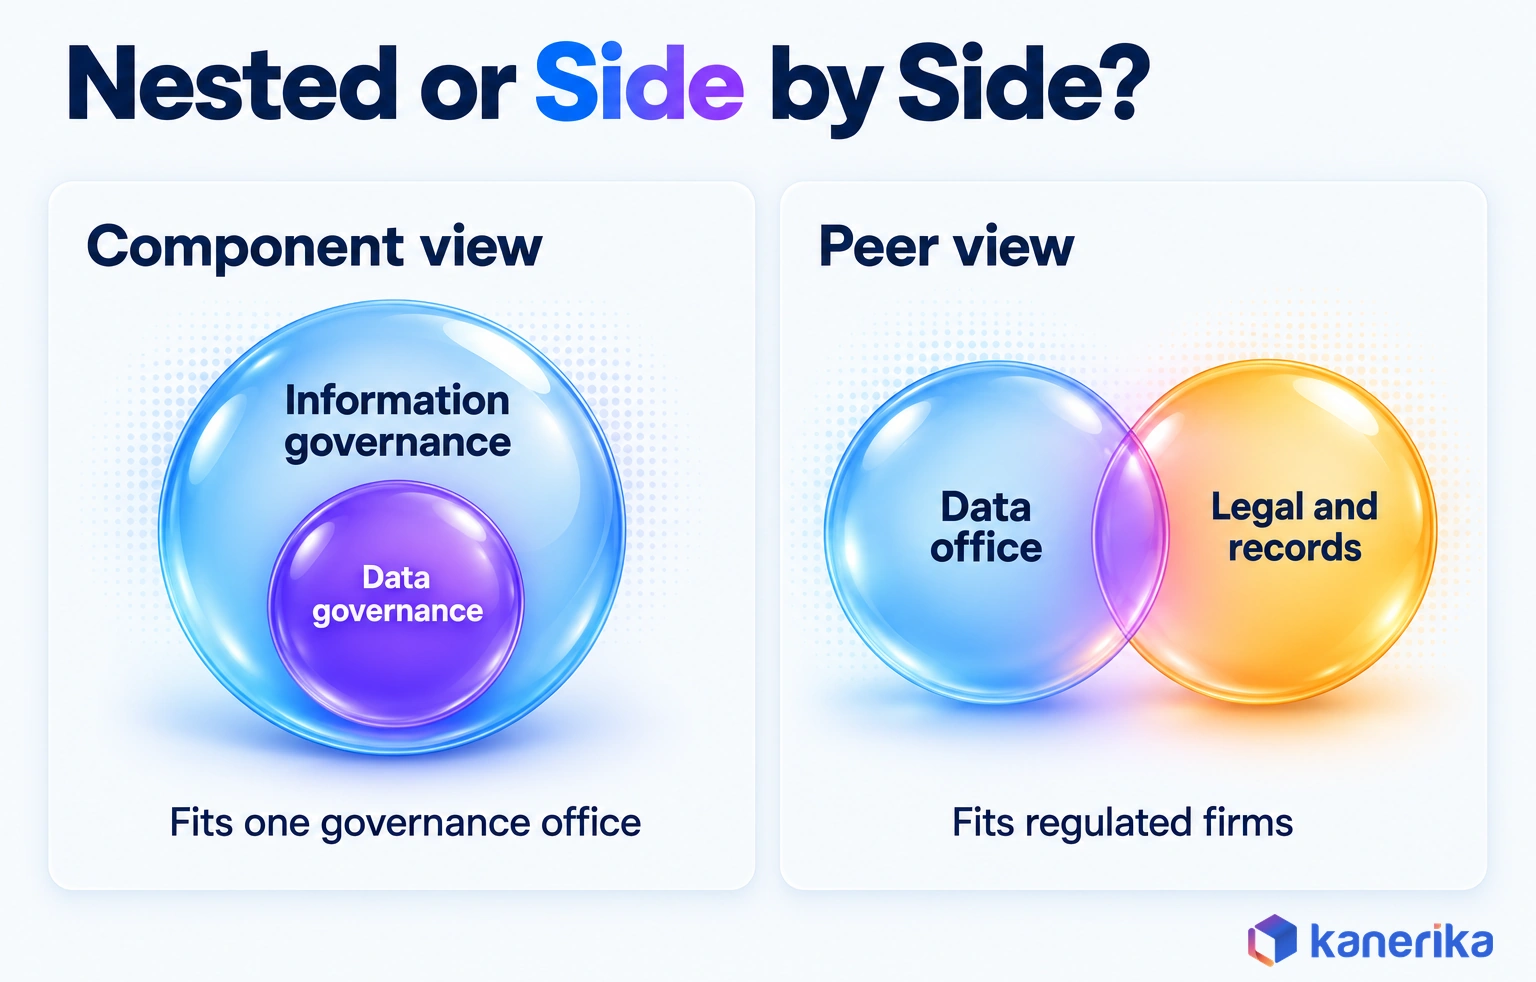
Whether data governance sits inside information governance or beside it is a matter of perspective, and both answers hold up. The right choice rests less on theory than on how your organization reports.
The component view treats information governance as the umbrella, since it spans every format. TechTarget describes data governance as a component of the broader information governance discipline, because data in databases is one kind of information among many (TechTarget). This model fits well when one governance office, often under the CIO, runs policy for every information type.
TechTarget also observes that DataOps practices are blurring the line between the two.
The peer view treats them as sibling programs. It is common in banks, insurers and health systems. For the banking case, see our guide to data governance in banking. There, the chief data officer often reports through technology or the business, while records, legal and compliance report elsewhere. Each program keeps its own owner, while a joint steering forum settles the overlaps on privacy, classification and deletion.
Data governance has other neighbors too, and the boundaries work the same way. Our comparisons of data governance vs data management and IT governance vs data governance show where it ends and the next discipline begins.
Whichever model you choose, the reporting line matters less than one rule: every asset type needs exactly one owner for each decision.
One Customer Record, Two Programs: A Worked Example
Following one customer record from creation to deletion shows exactly where one program hands off to the other. Picture a first-time mortgage customer at the same lender from the opening example.
- Create. The onboarding app creates the customer record. Data governance decides the field definitions, the mandatory fields and the validation rules at entry.
- Quality-check. Steward-owned rules check the address, the tax ID format and possible duplicates. Data governance owns the rule, and failures route to the steward’s queue.
- Catalog and lineage. The record lands in the warehouse. Data governance makes sure the catalog shows its owner, its definition and its lineage from the onboarding app to the risk reports.
- Share for analytics. Analysts get a masked view, with sensitive fields classified. Data governance sets the access policy that decides who sees what.
- Retain. The signed loan agreement, the identity documents and the email about the account get a retention label tied to an event, the loan payoff. Information governance owns that schedule.
- Legal hold. A dispute arises, so legal places a hold over the mailbox, the documents and the related database records. Information governance suspends deletion until legal releases it.
- Dispose. Once the hold is released and retention expires, the documents are deleted with a disposition record. Information governance decides when, while data governance deletes or anonymizes the database rows and updates lineage.
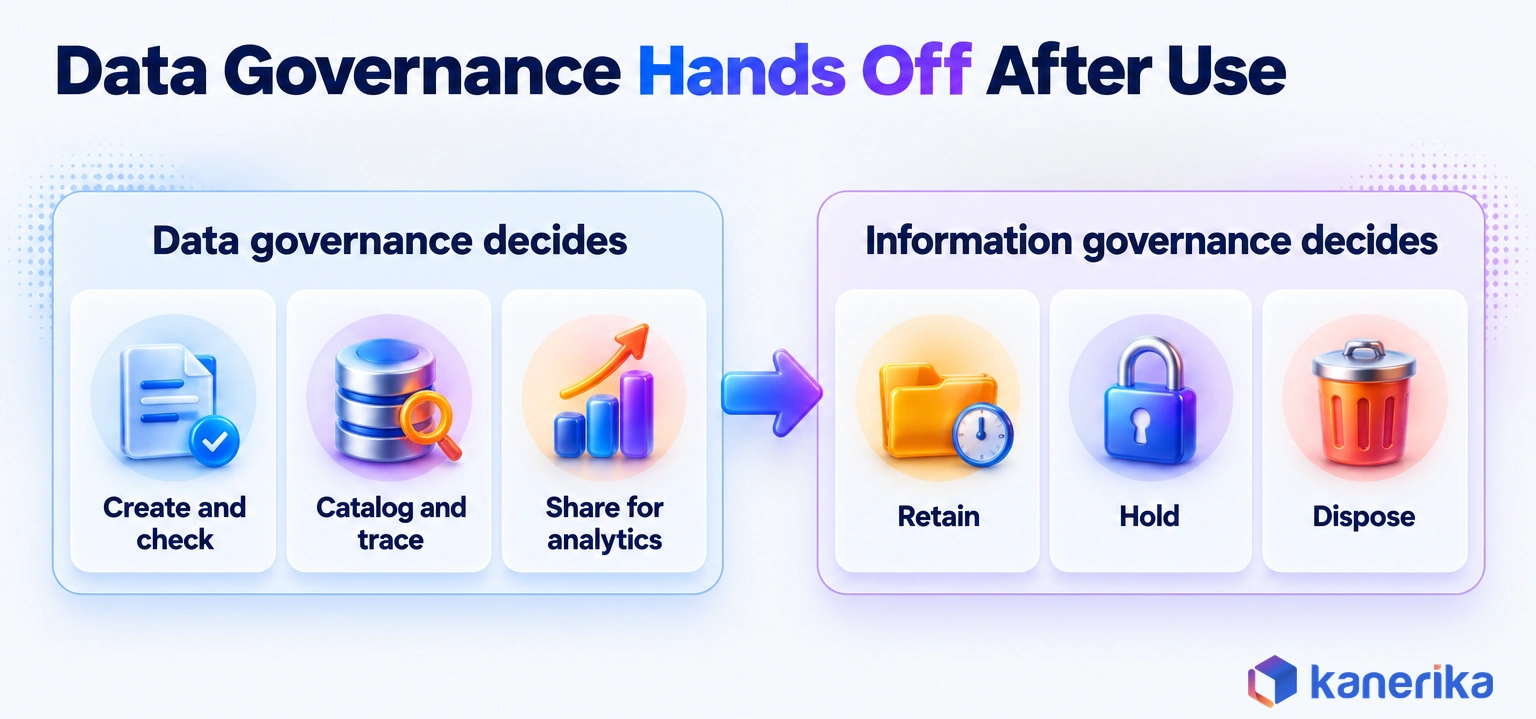
Look closely at step 7. Disposition is an information governance decision, but inside the database it becomes a data governance job. Deleting a customer row can break downstream tables and reports unless lineage is updated at the same moment.
That seam is also where the two programs most often fail to talk. The records team assumes IT will purge the data, while the data team assumes the records team told them what to purge.
What Changes When an AI Assistant Reads Both
AI assistants erase the old boundary between tables and documents, because they read both. A copilot or a retrieval-augmented generation app answers one question by pulling from a sales table, a contract PDF and an email thread at once.
That turns information governance controls into AI safety controls. According to Microsoft’s Purview documentation, the AI apps it supports never return tenant data to a user who lacks access to it. The model cannot use that data for that user either (Microsoft Learn). Sensitivity labels add a further layer, and an encrypting label requires extract and view rights before an AI app returns the content.
Permission sprawl therefore matters twice. An overshared folder of expired contracts becomes an answer source once an assistant can read it.
That overlap is one reason AI governance has to draw on both programs. Good retention shrinks what the AI can surface, while data governance keeps the numbers it quotes correct. If you run Microsoft 365, our guide to Microsoft Purview Information Protection explains how labels are set up and applied.
Watch on YouTube
Elevating Enterprise Productivity and Security with Copilot and Purview
A Kanerika session on using Microsoft Purview to keep Copilot productive and secure, so AI assistants respect permissions and sensitivity labels.
Who Owns What: Decision Rights in Each Program
Programs fail when two teams both think they own a decision, or when neither does. A decision-rights table removes that ambiguity before the first argument starts.
For example, consider a common clash. The privacy officer wants customer data deleted two years after an account closes. The analytics team wants to keep it longer to train a churn model.
In this case, the retention limit is an information governance call made by legal and privacy, so analytics can request an exception but cannot set the limit itself. Data governance then carries out the decision in every table that holds the data.
| Decision | Who decides | Who is consulted |
|---|
| Business definition of a critical data element | Data owner | Steward and CDO office |
| Quality thresholds for critical data | Data owner | Steward |
| Access to a data set | Data owner | CISO and privacy officer |
| Retention period for a record class | Records manager with legal | Privacy officer and business owner |
| Placing and releasing a legal hold | General counsel | Records manager and CISO |
| Privacy erasure requests (both programs) | Privacy officer | Data owner and records manager |
| Classification and sensitivity labels (both programs) | CISO with privacy officer | CDO office and records manager |
| Defensible disposition | Records manager | Legal and data owner |
Where the Two Programs Share Decisions
Two decisions, privacy erasure and classification, belong to both programs and need a joint forum. They touch every system, so the data office and the records team must agree on one scheme. Our guide to data classification best practices covers how to design it. When you design councils and stewardship at scale, our guide to the enterprise data governance operating model covers the full structure.
IT and the platform team are missing from the table on purpose. They run the controls for nearly every row, but they never make the decision. Instead, they carry out what the business, legal and privacy roles decide on.
How You Know Each Program Is Working
Each program needs its own scorecard, because the two succeed in different ways. Track coverage and outcomes rather than the number of policies written.
Our opening lender would have scored well on data governance measures like these, because its customer data already had owners and lineage:
- Share of critical data elements with a named owner and steward
- Pass rate of active data quality rules
- Share of critical reports with end-to-end lineage
- Access reviews completed on time
It would have failed on the information governance side, above all on the time from a hold notice to confirmed preservation:
- Share of repositories covered by a retention policy
- Size and age of the disposition backlog
- Time from a hold notice to confirmed preservation
- Open findings from internal and external audits
Set your own baselines in the first quarter, then report the trend. A falling disposition backlog says more about information governance than any policy count can.
Which Regulations Pull on Each Program
Regulations rarely use the words data governance or information governance, but each rule lands on one program’s controls. Mapping rules to owners therefore stops the familiar loop where legal and data each assume the other has it covered.
GDPR is a useful example, because one article pulls on both sides. Its accuracy principle requires personal data to be accurate and kept up to date, so it is a data quality duty. Its storage limitation principle requires that personal data be kept no longer than necessary, which is a retention duty (GDPR Article 5).
| Rule | What it requires | Program that owns the control |
|---|
| GDPR Art. 5(1)(d), accuracy | Personal data must be accurate and, where necessary, kept up to date | Data governance (quality rules on personal data) |
| GDPR Art. 5(1)(e), storage limitation | Personal data kept in identifiable form no longer than necessary | Information governance sets the limit; data governance deletes it in databases |
| HIPAA, 45 CFR 164.316(b)(2) | Keep required documentation for 6 years from creation or last effective date, whichever is later | Information governance (retention schedule) |
| FRCP Rule 37(e) | Sanctions are possible when relevant electronic information is lost because reasonable preservation steps were not taken, and it cannot be restored or replaced through additional discovery | Information governance (legal hold); data governance preserves structured data |
The HIPAA text comes from 45 CFR 164.316 (Cornell LII). The preservation duty comes from Rule 37(e) of the Federal Rules of Civil Procedure (Cornell LII).
This table is orientation, not legal advice, so your counsel should still map each rule for your industry and jurisdictions.
Retention and preservation rules land almost entirely on information governance, while accuracy rules land on data governance. Deletion is shared again, because a retention decision is only real once every copy in every database is gone.
Datasheet
Elevate Data Governance, Compliance and Security of Your Organization
A datasheet on how Kanerika approaches data governance, compliance and data security, from classification to access controls.
Get the Datasheet →
How to Implement Both Programs Together
Implementation goes faster when both programs share their first steps instead of running two separate rollouts.
- Inventory. Map where data and documents live, and name one owner per location.
- Classify. Agree one sensitivity scheme, so a single label drives access, retention and AI exposure.
- Assign. Get legal, records, privacy and the data office to sign the decision-rights table.
- Configure. Set quality rules and lineage on the data side, plus retention labels and legal hold on the information side.
- Report. Bring both scorecards to one steering forum every quarter.
Configuration is where the contract rule from earlier becomes real. In Microsoft Purview, it becomes an event-based retention label: you set a retention period and pick an event type, such as contract expiration, as its start. Each contract carries an asset ID, such as ComplianceAssetID:C-1042, so one event starts the clock only for that contract (Microsoft Learn).
At the end of the period, the label can start a disposition review instead of deleting outright. Purview allows up to five review stages with up to 10 reviewers or groups per stage, and approved items are permanently deleted within 15 days (Microsoft Learn).
The benefits land on both scorecards. Trusted data lets analytics and AI teams reuse numbers without rebuilding them. Scheduled disposition shrinks what eDiscovery, storage and AI assistants have to search, and one inventory answers erasure requests from a single register.
Data Governance vs Information Governance: Which Should You Prioritize First?
The right first program is the one that addresses the risk you are most exposed to. Few organizations can fund both at full scale in the first quarter, so sequencing matters.
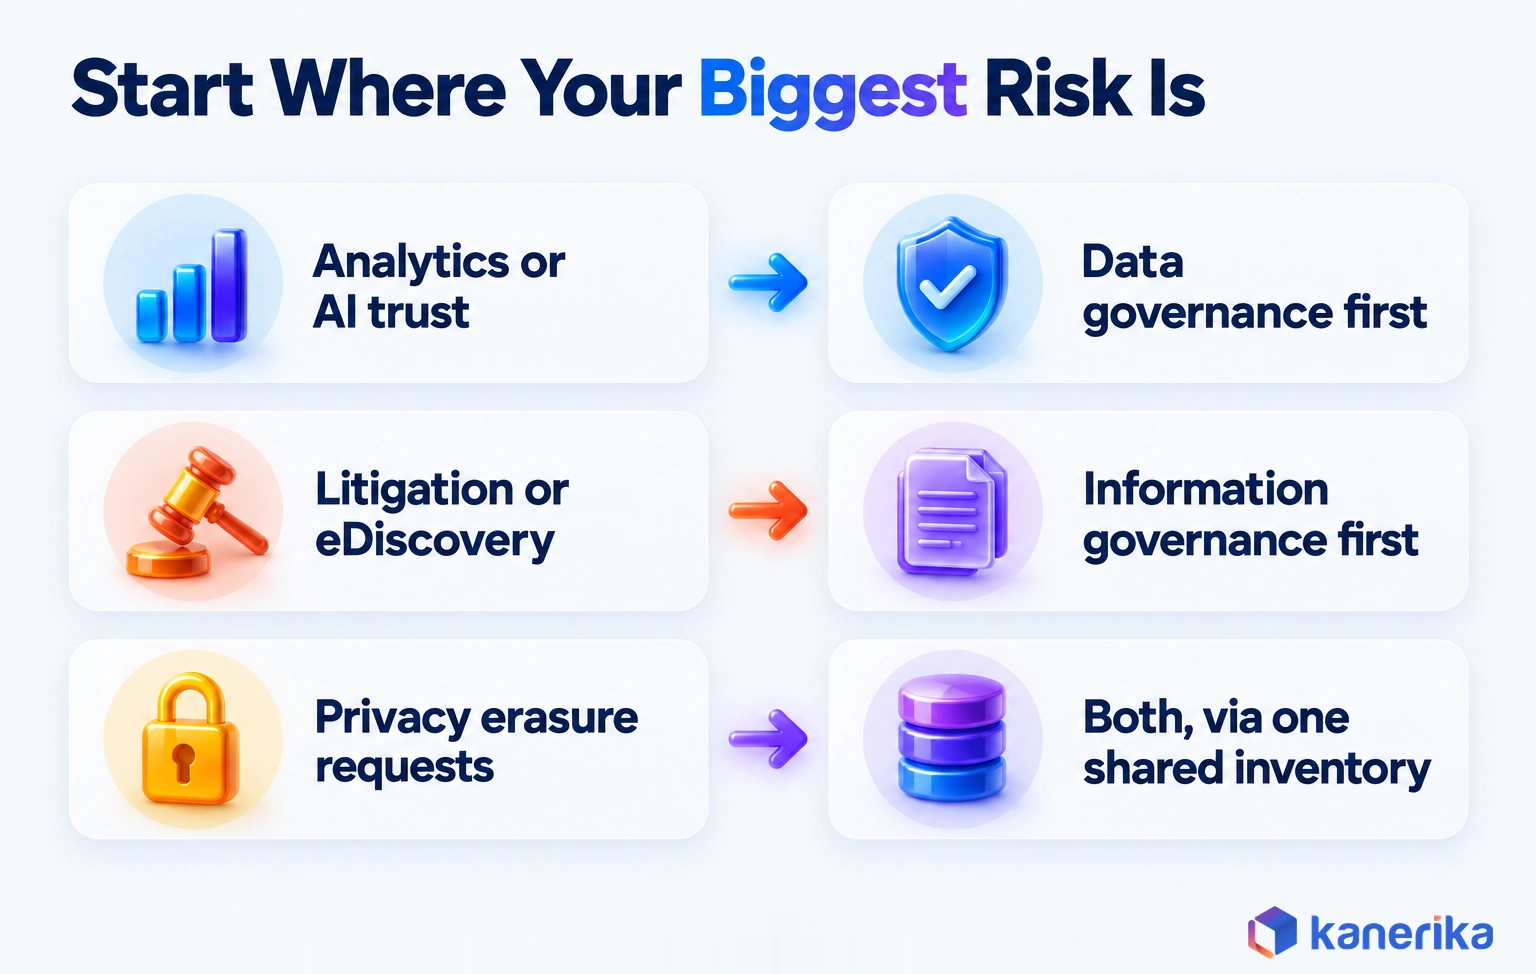
Start by naming the incident you most want to avoid, then work backward. A wrong number in a board pack, a classic sign of bad data quality, points one way, while a failed eDiscovery request points the other. The table below turns that choice into a starting control you can put in place within 90 days.
| If your main risk is | Start with | First 90-day control |
|---|
| Untrusted analytics or AI outputs | Data governance | Owners, definitions and quality rules for the top 20 critical data elements |
| Litigation and eDiscovery requests | Information governance | A legal hold process and a map of where email, chat and documents live |
| Privacy erasure requests | Both, through a shared inventory | One register of where personal data sits, in tables and in files |
| A cloud or Microsoft 365 migration | Information governance first | Retention labels and a cleanup of expired content before anything moves |
| A regulatory audit | The program the regulator tests | Evidence of controls for the specific rule, such as retention or data accuracy |
Whichever you start with, still plan for both from day one. A data program that ignores retention will keep personal data longer than the law allows. Likewise, a records program without data ownership cannot safely delete anything from a database. Before you commit budget, use a data governance maturity model to assess where each program stands.
The assessment will usually surface a few familiar blockers, such as unclear ownership and weak sponsorship. Our breakdown of common data governance challenges covers how to work through them.
Tool Categories for Each Discipline
Tools follow the same split as the programs, although a few suites cover both. Choose by category first, then by vendor.
| Tool category | Serves | Example capability |
|---|
| Data catalog and lineage | Data governance | Business glossary, owners, field-level lineage |
| Data quality | Data governance | Rule checks, scorecards, issue routing to stewards |
| Access policy | Data governance | Policy-based access to data sets and masking |
| Records management | Information governance | Declaring records, event-based retention, disposition review |
| Retention and lifecycle | Information governance | Keep-or-delete policies across email, files and chat |
| eDiscovery and legal hold | Information governance | Hold notices, preservation, search and export |
| DLP and sensitivity labels | Both | Classification that drives access, retention and AI exposure |
Microsoft Purview, for example, shows the split inside one suite. Its Unified Catalog serves data governance (Microsoft Learn). Data Lifecycle Management, formerly Microsoft Information Governance, retains the content you need and deletes what you don’t (Microsoft Learn).
Records Management handles regulatory, legal and business-critical records, including disposition (Microsoft Learn). For a vendor-by-vendor view, see our roundups of data governance tools and data catalog tools.
How Kanerika Helps Enterprises Run Both Programs
We help enterprises run data governance and information governance as one program with two clear owners, usually on Microsoft Purview. Every engagement starts with a decision-rights map like the one above, so the data office, legal, records and privacy each know which calls are theirs.
Watch on YouTube
Building an AI-Powered Compliance Platform That Scales Across Jurisdictions
How Kanerika built a centralized compliance platform with automated requirement mapping, controls monitoring and audit traceability for a regulatory compliance provider.
On the data side, we put the catalog, lineage, quality rules and access policies in place, so analytics and AI teams work from trusted data. On the information side, we also configure retention labels, records management and legal hold workflows. Then we connect both to one classification scheme, so a single sensitivity label drives access, retention and AI exposure together. Our guide to Microsoft Purview for data governance shows how those pieces fit in one suite.
That work runs on our KANGovern, KANGuard and KANComply solutions, built on Microsoft Purview, Databricks Unity Catalog and Concentric AI. KANGovern handles the unified catalog and business glossary, and KANGuard handles DLP and labeling across Microsoft 365. KANComply automates DSAR workflows, PII discovery and retention policy enforcement.
Where the Two Halves Met in a Compliance Platform
One compliance engagement shows how the two halves meet in practice. The client is an AI-powered regulatory compliance solutions provider serving financial institutions across multiple jurisdictions. Before the project, its compliance workflows were fragmented, controls mapping was manual, and audit readiness had gaps.
We built a centralized compliance platform with automated requirement mapping, controls monitoring and audit traceability. Underneath it sits a structured regulatory data architecture, which unified compliance data across teams and jurisdictions.
Results included 60% less manual compliance work, 40% faster regulatory response and 5X better audit traceability. The engagement centered on compliance evidence rather than retention, but it follows the same pattern: owned, structured data underneath and traceable records on top.
For your own estate, our data governance services cover the assessment and the Purview implementation, as well as the operating model for both programs. We usually begin with one high-risk domain, such as customer or patient data, and extend from there once the first owners and controls are working.
Case Study
60% Less Manual Compliance Work with AI
Kanerika built a centralized compliance platform for a regulatory compliance provider, with 40% faster regulatory response and 5X better audit traceability.
Read the Case Study →
The Bottom Line: Data Governance vs Information Governance
Go back to the lender from the opening. Its data governance work was real, and it is the reason the customer record could be trusted. What it lacked was the information governance half: a view of the emails, contracts and scanned files around that record.
One first move would have answered legal’s three questions: a shared inventory of where customer data and documents live. Each location in it needs an owner, a retention rule and a hold flag.
That inventory is where the two programs meet, whichever one you fund first. The difference between data and information governance comes down to two questions: can you trust the record, and should you still keep it?
Frequently Asked Questions
What is the main difference between data governance and information governance?
Data governance makes structured data accurate, understood and safe to use. It runs ownership, quality rules, catalogs, lineage and access policies. Information governance controls the full lifecycle and legal risk of every information asset, including email, documents, chat and paper. It runs retention schedules, legal holds and disposition. One builds trust in data, and the other decides what to keep.
Is data governance part of information governance?
It can be. Many experts treat data governance as one component of information governance, since databases are one kind of information. Regulated firms often run them as peer programs instead, because the data office and the legal or records team report separately. Either model works well if every asset type has one clear owner for each decision.
What is the most common data governance framework?
DAMA-DMBOK, the Data Management Body of Knowledge from DAMA International, is the common starting point for many data governance programs. DAMA lists the 2nd edition as current, with a revision published in 2024 and a 3.0 project started in 2025. Many organizations build their own framework from it and add the roles, policies and metrics that fit their business.
Will AI replace data governance?
No. AI can automate parts of governance, such as classifying sensitive data, suggesting definitions, detecting quality issues and drafting lineage. It cannot decide who owns data, what level of risk is acceptable or how long records must be kept. AI actually raises the need for governance, because assistants and agents surface any data and documents they are allowed to read.
What are the four main roles in data governance?
Four roles appear in most programs. The executive sponsor or chief data officer sets direction and funding. Data owners are accountable for a domain and approve definitions and access. Data stewards run daily quality, metadata and issue work. Data custodians, usually in IT, operate the platforms and controls. Some organizations add a governance council to settle cross-domain decisions.
What are the 5 pillars of data governance?
Frameworks name them differently, but five pillars come up often. They are ownership and accountability, data quality, metadata and lineage, security and privacy, and compliance. Some models list four pillars, five areas or six dimensions of data quality instead. The labels matter less than coverage, so check that each pillar has an owner, a policy and a measure.
What is an example of information governance?
A common example is a retention policy for signed contracts. Every signed agreement is classified as a contract record and kept for a set period after the contract ends, such as seven years. The file is then deleted unless legal has placed a hold. A records manager owns the schedule and can show why each file was deleted.
What is an example of data governance?
A simple example is agreeing what an active customer means. Sales and finance often count customers differently, so their reports never match. Under data governance, the customer data owner approves one definition and a steward publishes it in the glossary. A quality rule then flags records missing the needed fields, and the steward fixes them through a tracked process.
Who is responsible for information governance in an organization?
Responsibility is usually shared under one executive sponsor. A records manager owns retention schedules and disposition. General counsel owns legal holds and litigation readiness. A privacy officer owns personal data rules and erasure requests, and the CISO owns security and classification. IT runs the systems. Some organizations also name a chief information governance officer to coordinate these roles.
Can data governance and information governance use the same tools?
Partly. Some suites cover both, such as Microsoft Purview, which includes a Unified Catalog for data governance plus Data Lifecycle Management and Records Management for information governance. Sensitivity labels and data loss prevention serve both programs. Specialist needs, such as deep data quality checks or complex eDiscovery work, may still call for dedicated tools in each program.
How do you measure the success of information governance?
Measure coverage and outcomes. Useful metrics include the share of repositories covered by a retention policy, the size and age of the disposition backlog, and the time from a hold notice to confirmed preservation. Open audit findings and the volume of expired content still stored also show progress. Set baselines first, then report the trend each quarter.
How does information governance support regulatory compliance?
Many rules set retention, preservation or deletion duties. HIPAA requires certain documentation to be kept for six years. GDPR limits how long personal data can be stored in identifiable form. US court rules expect reasonable steps to preserve relevant electronic information in litigation. Information governance turns these duties into retention schedules, holds and disposition records that auditors can check.
How do data governance and information governance overlap?
They overlap on privacy, security, classification and deletion. Both need to know where personal and sensitive information lives. Both rely on one labeling scheme to drive access and retention. Deletion is shared too, because information governance decides when records must go and data governance removes them from databases and updates lineage. A joint forum should own these overlaps.
What is the difference between information governance and records management?
Records management is one discipline inside information governance. It deals with records, meaning information kept as evidence of business activity, and manages their retention and disposition. Information governance is broader. It also covers privacy, security, eDiscovery, storage cost and the value of information that is not a formal record, such as working drafts and chat messages.
What does information governance cover?
Information governance covers every kind of information an organization creates or receives. That includes email, contracts, office files, chat messages, meeting recordings, scanned forms, paper archives and databases. Its disciplines include records management, retention schedules, legal hold, eDiscovery, privacy and defensible disposition. The aim is to keep useful information available and remove what has no reason to stay.
Can you have data governance without information governance?
You can, and many companies start that way. A data program can fix definitions, quality and access for analytics without touching email or documents. The gap appears in litigation, audits and privacy requests, where unmanaged files become a risk. Most organizations eventually need both, so plan shared classification and deletion rules even if you fund one program first.
Which governance framework should a business prioritize?
Prioritize the program that addresses your biggest risk. If untrusted analytics or AI outputs worry you most, start with data governance. If litigation, eDiscovery or retention rules are the pressure, start with information governance. Privacy erasure requests need both through a shared inventory. Whichever comes first, design shared classification and deletion rules from the start so the programs connect later.
Which governance type applies to unstructured data?
Information governance is the main program for unstructured content such as email, documents, chat and recordings. It decides how long each item is kept, when it goes on hold and when it is deleted. Data governance increasingly reaches unstructured data too, because AI and search tools now read documents. Classification and access rules should then cover both kinds of content.
Is data governance an IT job?
Not mainly. IT runs the platforms and implements the controls, but the decisions belong to the business. Data owners decide definitions, quality thresholds and access for their domains, and data stewards run the daily work. A chief data officer usually leads the program. Treating governance as an IT project is a common reason programs lose business support over time.
What are the 5 main points of information governance?
Frameworks list different numbers of points. A common reference is ARMA International’s Generally Accepted Recordkeeping Principles, which name eight. They are accountability, transparency, integrity, protection, compliance, availability, retention and disposition. If you need five, group them into ownership, security, compliance, access and lifecycle. That covers who is responsible, how records stay safe and when they are disposed of.
Why is data governance important?
Data governance makes the numbers behind decisions trustworthy. It gives each critical data element an owner, a definition and quality rules, so reports agree and teams stop arguing about whose figure is right. It also controls who can access sensitive data. AI raises the stakes, because models and assistants act on whatever data they are able to reach.




