TL;DR
In data fabric vs data mesh, choose fabric when scattered systems are the bottleneck and mesh when an overloaded central team is. A data fabric is a design pattern that uses active metadata and automated integration to connect data where it already lives. A data mesh is an operating model where business domains own their data and publish it as products on a shared platform.
Fabric changes technology first and suits regulated firms with lean data teams, while mesh changes ownership and needs mature domains. Many large enterprises end up with both, so they run mesh-style domain ownership on top of a fabric-style integration and governance layer. If you have both bottlenecks, build the fabric layer first, then hand ownership to domains one at a time.
Key Takeaways
- Data fabric is a design pattern that connects data where it lives, using active metadata and automated integration.
- Data mesh is an operating model in which business domains own their data and publish it as products.
- Fabric fits when the bottleneck is disconnected systems, while mesh fits when a central team cannot keep up with domain demand.
- Mesh without a platform team and fabric bought as a single tool are the most common ways each approach fails.
- Microsoft Fabric domains, Purview governance domains and Databricks Unity Catalog can also support either pattern.
- An 18-point readiness scorecard and a four-stage pilot let you decide without a full redesign.
Is Your Data Problem Technical or Organizational?
Picture a manufacturer that grew through two acquisitions. It runs three ERP instances, each with its own customer codes and product hierarchy. A simple request, such as revenue by customer for last quarter, takes three extracts and a week of spreadsheet work.
That same company has one central data team. Its request queue is three months deep, so sales, finance and supply chain all wait in the same line.
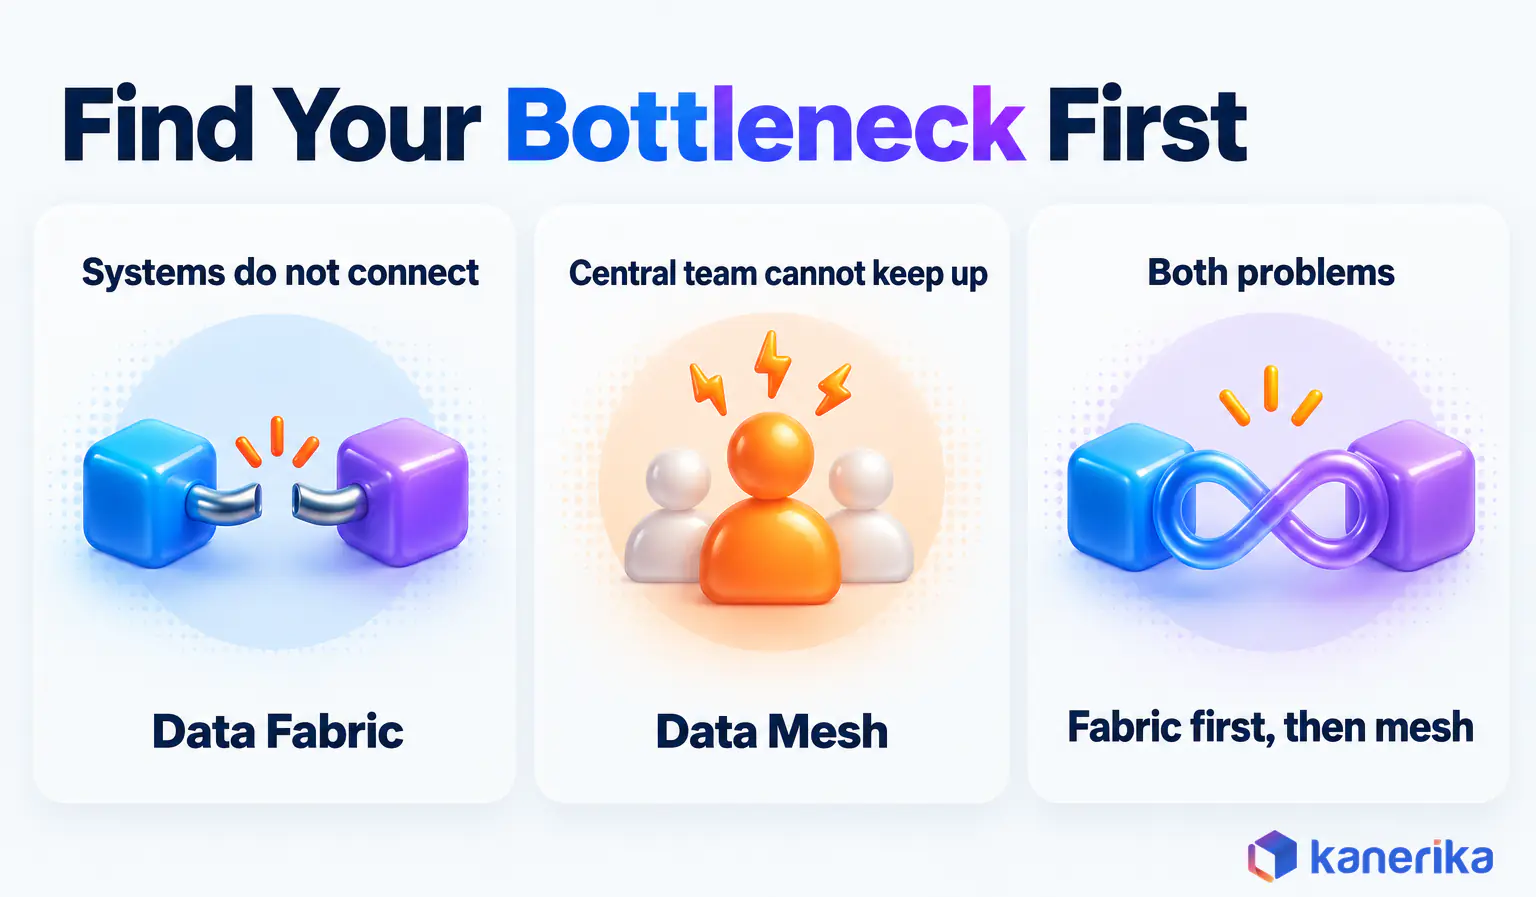
These are two different problems that look alike from the boardroom. One is technical, because the systems do not talk to each other. The other is organizational, because one team owns every pipeline and the whole company moves at its pace.
The technical version is common. In a 2025 IBM Institute for Business Value study, half of CEOs said their organization has disconnected technology because of the pace of recent investments.
Data fabric was designed for the first problem and data mesh for the second. So the data fabric vs data mesh choice starts with naming which problem you actually have, and the rest of this guide helps you do that.
Data Fabric vs Data Mesh in One Minute
Both ideas chase the same goal: trusted data that reaches the people who need it without a long wait. They take different routes, though, so a short definition of each is enough before the comparison. For the wider picture of how these patterns sit inside a full data architecture, see our primer.
What Is Data Fabric?
Gartner describes data fabric as “an emerging data management and data integration design concept”. It supports access to data “through flexible, reusable, augmented and sometimes automated data integration”. In practice, data can stay in the systems where it already lives. An analyst could then query customers in a CRM and orders in an ERP through one governed view, with neither system copied.
Active metadata is the engine underneath. A fabric collects technical and business metadata, learns how data is used, and then suggests or automates integration, quality checks and access rules. IBM puts it plainly: a fabric is “not a piece of software, but rather a design approach”.
That last point matters for buyers, because no single product is a fabric on its own. Our guide to data fabric architecture covers the layers in more depth.
What Is Data Mesh?
Data mesh comes from Zhamak Dehghani, then at Thoughtworks. She introduced it in a May 2019 article on moving beyond the monolithic data lake. Instead of one central team owning every pipeline, each business domain owns its data and serves it to others.
Her December 2020 follow-up set out the four data mesh principles: domain ownership, data as a product, a self-serve data platform and federated computational governance. Mesh is mainly a change in who owns data, with technology in a supporting role.
AWS describes the same shift as a move away from centralized warehouse and lake thinking, with each domain serving its own data. Our full data mesh guide then explains how teams adopt it step by step.
The Short Version
If you only have time for one table, use this one. It sums up how each approach behaves on the six questions leaders ask first.
| Question | Data Fabric | Data Mesh |
|---|
| What it is | A design pattern for connected, metadata-driven data access | An operating model for domain-owned data products |
| Who owns data | A central data or platform team | Each business domain |
| What changes first | Integration technology and metadata | Roles, ownership and team structure |
| Where governance sits | Central policies, applied by automation | Global rules, applied by each domain |
| Best for | Many disconnected systems and a lean data team | Many capable domains and a central bottleneck |
| Main risk | Buying tools without doing the metadata work | Decentralizing before a shared platform exists |
Neither approach is a storage design, because storage is a separate choice. If storage is your real question, read data fabric vs data lake, data mesh vs data lake or data fabric vs data warehouse before going further.
Kanerika Service
Data Architecture Consulting Services
Kanerika maps your sources, teams and governance needs, then designs a fabric, mesh or combined architecture that fits how your business actually runs.
Explore Data Architecture Services
Data Fabric vs Data Mesh: The Core Differences
These two approaches differ less in tools than in where they put responsibility. Fabric centralizes enterprise data integration and lets automation do the connecting. Mesh, by contrast, spreads ownership out and asks each domain to act like a supplier of data.
Beyond the basics in the short table above, five more points decide cost, staffing and risk in a real program.
| Dimension | Data Fabric | Data Mesh |
|---|
| Integration method | Virtualization, pipelines and automated mapping | Domains publish data products through standard interfaces |
| Data location | Stays in sources or a cloud data warehouse, reached through one access layer | Stays with each domain, though often on shared platform storage |
| Team skills | Integration, metadata and platform engineering | Domain engineers, product owners and also a platform team |
| Time to first value | Faster, since you can go one integration flow at a time | Slower, because roles and platform come first |
| Cost driver | Tooling, metadata platform and integration work | Domain headcount and a dedicated platform team |
Centralized Integration vs Domain Ownership
A fabric keeps one team in charge of how data connects. That team builds the integration layer, curates metadata and publishes shared views. Business users get faster access, but they still depend on the center for every added source or model.
A mesh moves that work out to the domains. Finance owns its general ledger data, documents it and publishes it as a product for sales and supply chain. The central team shrinks into a platform team that builds shared templates and data orchestration tools rather than individual pipelines.
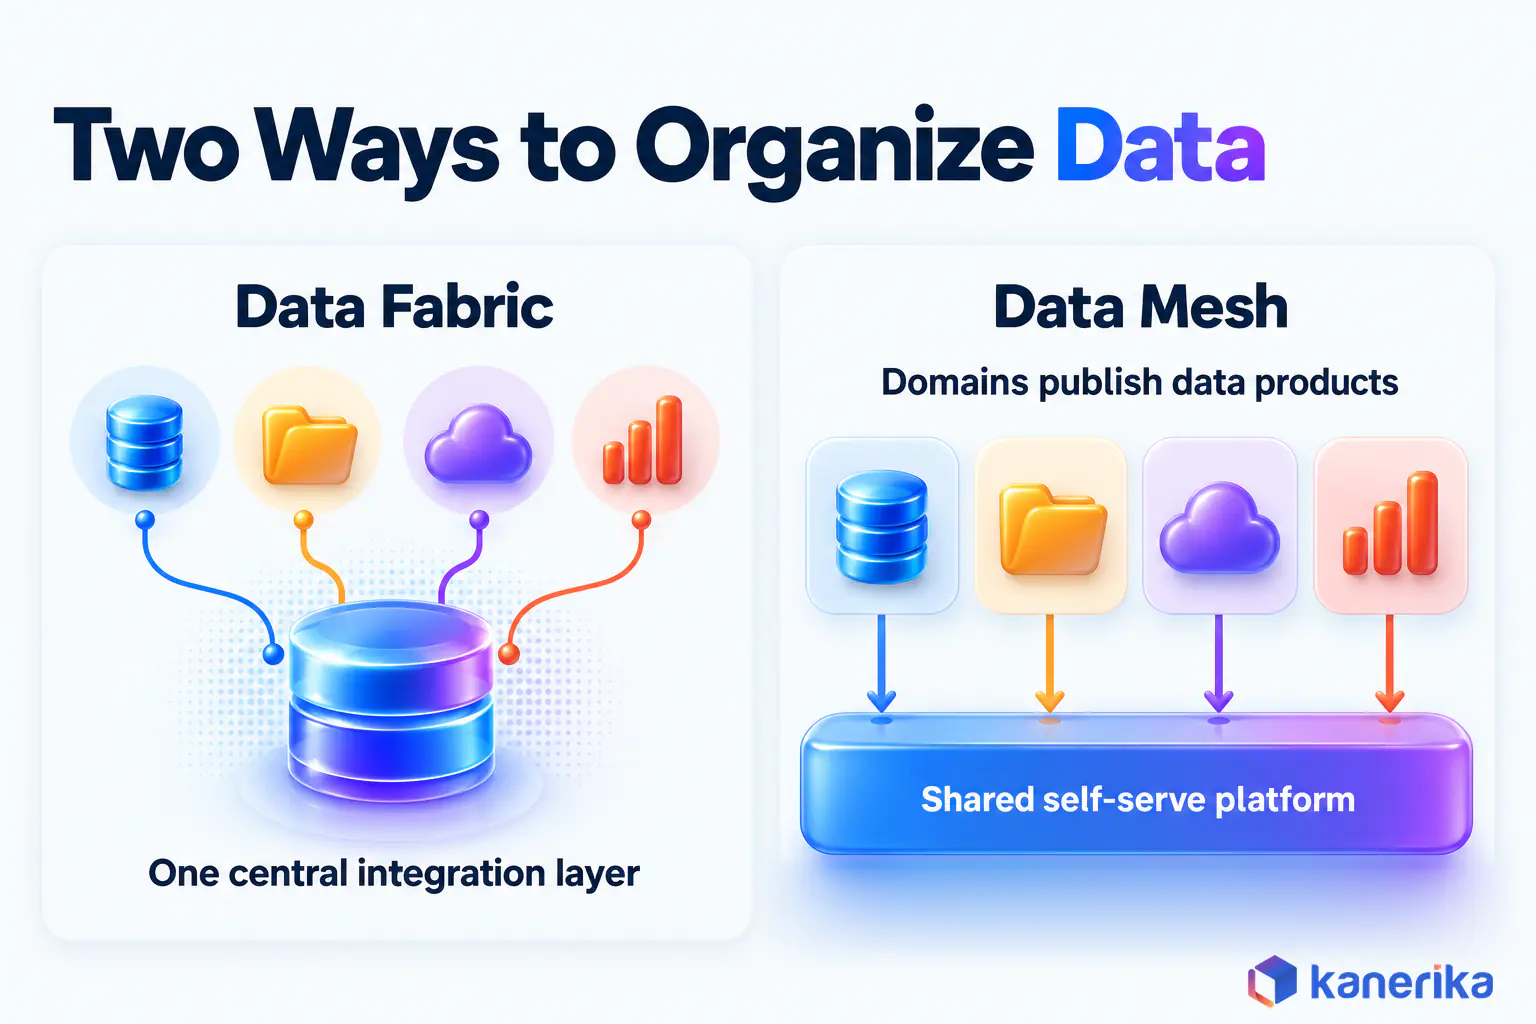
So the trade-off is speed against scale. Central integration is quicker to start and easier to control, which is why it wins early. Domain ownership scales better once dozens of teams need data at the same time, because no single queue sits in the way.
Both models also carry a built-in weakness. In a fabric, the central team can itself turn into the bottleneck once requests pile up. In a mesh, standards can drift from one domain to the next unless a federated group enforces them.
Push each model to its limit. A fabric with forty source systems still works, as long as the metadata keeps up. A mesh with forty domains also works, but only if each domain has someone who treats its data as a product with users.
Technology-Led Change vs Operating-Model Change
Gartner draws the line clearly. It treats data fabric as a data management design concept. In contrast, it calls data mesh “an architectural approach with the goal of building business-focused data products”.
That difference shows up in the budget. A fabric program mostly buys and configures technology, so IT can run it. A mesh program changes job descriptions, incentives and accountability, so it needs business leaders to sponsor it.
Its topic page, read in October 2026, adds that “data fabric is not a mature technology, and no single vendor currently delivers all data fabric components”. So treat any claim of a complete fabric in a box with care. Ask which parts you would still build yourself.
What Each Approach Gains You
Each pattern pays off in a different place. A fabric’s main gain is reuse. Once sources are mapped, every later report, model or AI tool starts from the same governed view, not a fresh extract.
A fabric also gives auditors one place to check access and lineage, which is worth a great deal in a regulated business.
A mesh gains you speed through parallel work and sharper accountability. Each data product has a named owner who understands the business meaning, so errors get fixed by the people closest to them.
How Each Works in Practice: One Customer Revenue View, Built Two Ways
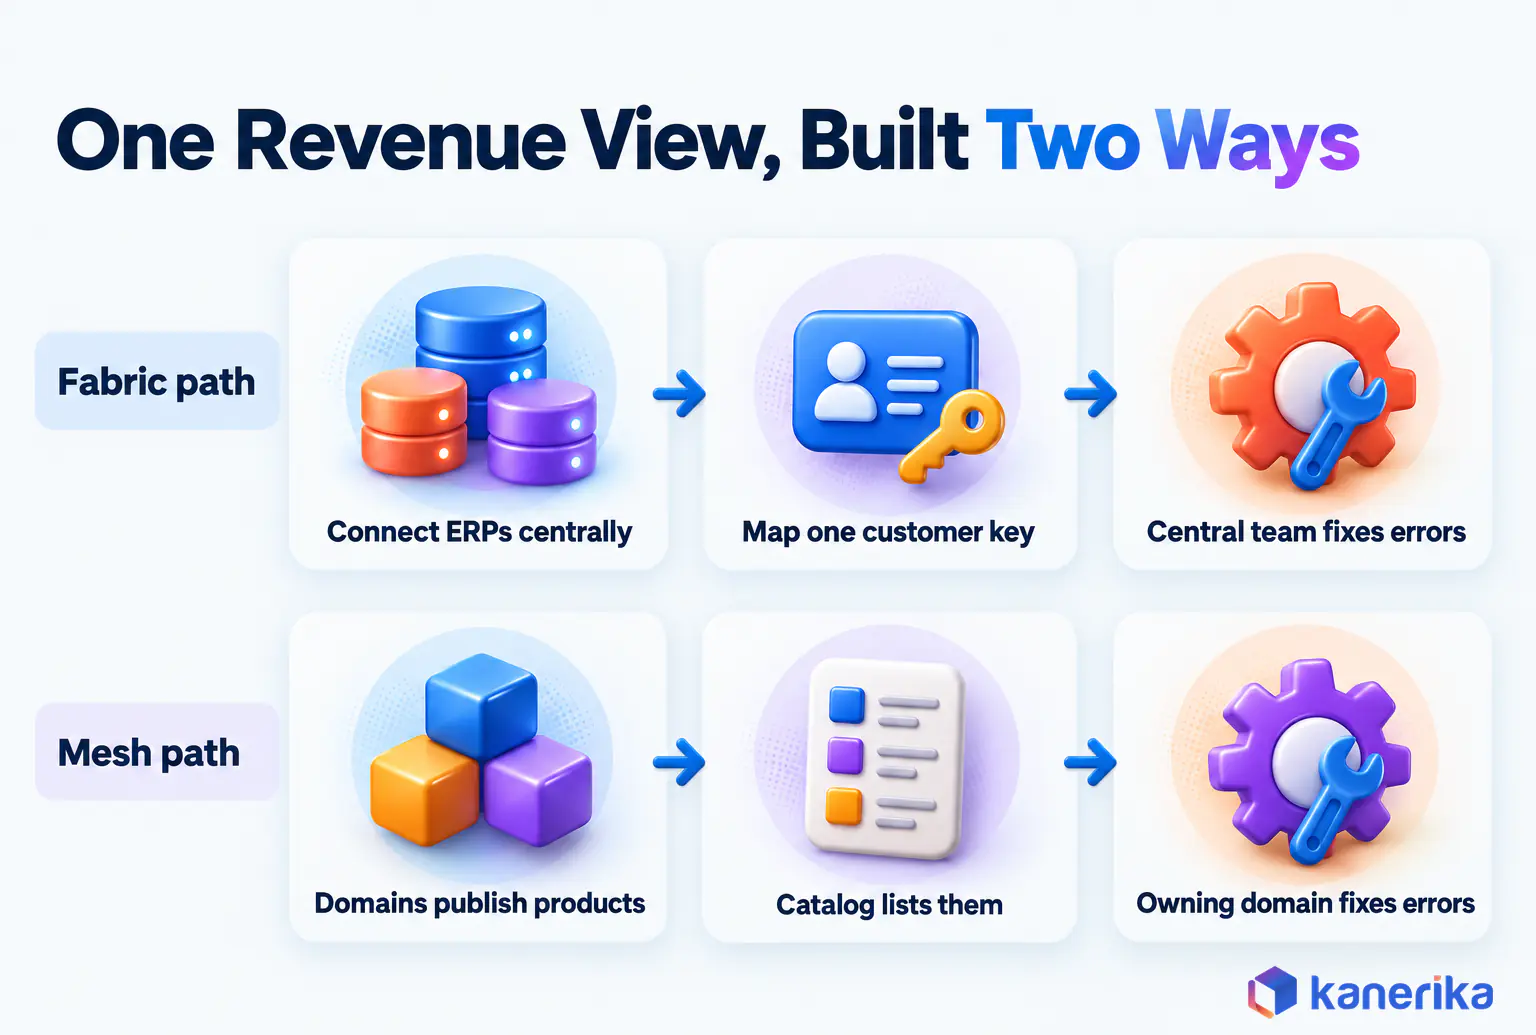
Definitions only go so far, so here is one request handled both ways. Our manufacturer from the opening wants a single view of revenue by customer across its three ERP instances.
Its goal is the same in both builds. What changes is who does the work, where the logic lives and who answers for a wrong number.
The Data Fabric Path
- First, the central team connects the three ERPs through data ingestion pipelines or virtual access, without forcing a full migration. On Microsoft Fabric, virtual access can mean OneLake shortcuts that point to data where it sits.
- Next, a metadata catalog maps the three customer codes to one customer entity.
- Then central access policies decide who sees which regions, and the fabric applies them to every query.
- Finally, when a record is wrong, the central team traces it through data lineage and fixes the mapping or the source feed.
Fabric speed comes from reuse. Once the customer mapping exists, the next request for margin by customer or orders by region builds on it instead of starting over.
Checklist
Data Integration Checklist
A downloadable checklist for planning source connections, mappings, quality rules and access controls before you build a shared integration layer.
Get the Checklist →
The Data Mesh Path
- First, the sales domain owns customer master data and publishes a certified customer data product with a clear contract.
- Next, each domain that runs an ERP publishes its own orders product, documented in a shared catalog.
- Then a federated governance group sets naming, privacy and quality rules that every product must meet, drawn from a shared data governance framework.
- Finally, when a record is wrong, the owning domain fixes it at the source and releases an updated product version.
Mesh speed comes from parallel work instead. Five domains can each improve their products at once, without queuing behind a central team.
You can see the difference most clearly in step four. In a fabric, a wrong customer record goes to the central team. In a mesh it goes to the domain that created it, which usually understands the error faster but needs the skills to fix it.
When to Choose Data Fabric and When to Choose Data Mesh
Let your bottleneck drive the choice. A small but heavily regulated firm can need a fabric, while a mid-sized digital business can be ready for a mesh. These signs help you tell which situation you are in.
Signs Data Fabric Fits
- You run many systems that do not share keys, such as several ERPs, clouds or acquired platforms.
- Your data team is small, so it cannot be split across business domains.
- Regulators expect one consistent point of control over access and lineage.
- Most demand is for shared reports and dashboards, not for domains publishing data to each other.
- You need visible results within one or two quarters.
Signs Data Mesh Fits
- Domains wait months for a central team that cannot keep up.
- Business units already have their own engineers, analysts and product owners.
- Many teams want to publish and reuse each other’s data, not only consume it.
- Leadership will fund a platform team and also accept changed ownership roles.
- Most data errors trace back to business context that only the domain holds.
Few organizations match only one list. So use the scenario table to find your closest match, then confirm it with the scorecard further down.
| Your situation | Pick | Why |
|---|
| Regulated firm with a small data team | Data fabric | Central control and automation do more with fewer people |
| 15 domains with strong product teams | Data mesh | Ownership already exists, so a central team only slows them down |
| M&A activity with many ERPs to reconcile | Data fabric | The core problem is connecting systems, not ownership |
| Central backlog over a quarter, capable domains | Data mesh | Moving ownership out removes the queue |
| Single cloud platform, few sources, one analytics team | Data fabric, kept light | A shared catalog and access layer is enough |
| Many disconnected systems and an overloaded central team | Data fabric first, then data mesh domains | Connect sources centrally, then hand ownership out |
| Global firm with regional data residency rules | Data fabric for policy, data mesh by region | Central rules, while regional owners handle local data |
Notice that company size never decides the row. The shape of the bottleneck does, which is why two firms of the same size can land on opposite answers.
If you sit between two rows, the scorecard below breaks the tie by weighting the questions that matter most.
Talk to Kanerika
Not Sure Which Row You Are?
Kanerika architects review your sources, teams and backlog with you and recommend data fabric, data mesh or a phased mix, with a first pilot scoped.
Book a Working Session →
Can Data Fabric and Data Mesh Work Together?
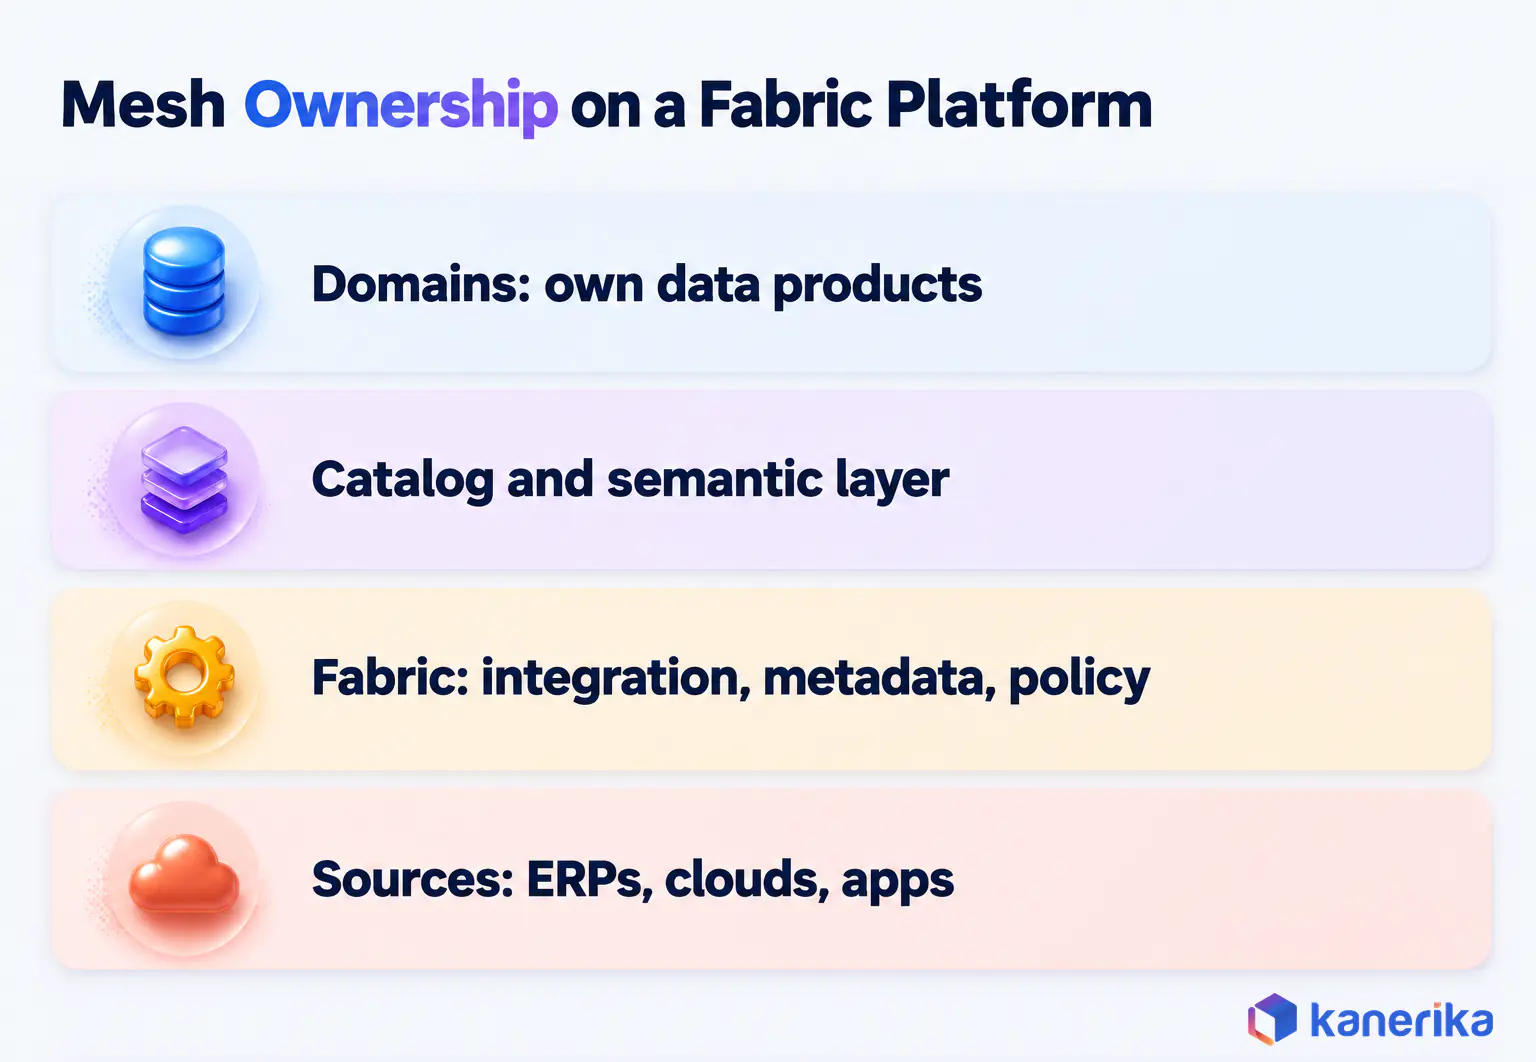
Yes, and in large enterprises that is often where both programs end up. Each idea works at a different level: mesh decides who owns data, while fabric decides how data is connected, described and governed.
A clean way to combine them is to treat the fabric as the self-serve platform that a mesh needs. IBM notes that a fabric can automate parts of a mesh, such as creating data products and enforcing global governance. Domains keep ownership, while the shared layer handles discovery, lineage and policy.
At the center of that layer sits the catalog. It records every data product with its owner, quality checks and lineage. Those fields are what let a domain in one region find and trust a product built in another. So picking among metadata management tools and data catalog tools is one of the first real design decisions in a combined program.
Above the catalog, a shared semantic layer keeps business terms like “active customer” consistent across domains. That is the territory of data intelligence, which turns metadata into answers that people and AI tools can rely on.
A combined model also lowers risk. You can start with the fabric layer, prove value on shared integration, and then hand ownership to domains as each one becomes ready.
A Data Fabric vs Data Mesh Readiness Scorecard
A scorecard turns a long debate into a structured conversation. Answer the eight questions below with your data, IT and business leads in the room. Then give each question’s weight to the column that describes you better.
| # | Question | Fabric answer | Mesh answer | Weight |
|---|
| 1 | How scattered are your sources? | Many disconnected systems | Sources are manageable | 3 |
| 2 | How mature are domain teams? | Domains rely on central IT | Domains have engineers and product owners | 3 |
| 3 | How long is the central backlog? | Manageable | Domains wait months | 3 |
| 4 | Where must governance decisions sit? | With one central team | With domains, inside global rules | 2 |
| 5 | Can you fund a platform team? | Not yet | Yes, with dedicated staff | 2 |
| 6 | How heavy is regulation? | Heavy, with a small data team | Moderate or domain-specific | 2 |
| 7 | What do users mainly need? | Shared reports and dashboards | To publish and reuse data products | 2 |
| 8 | What is your budget horizon? | Results within two quarters | A multi-year change program | 1 |
How to Read Your Score
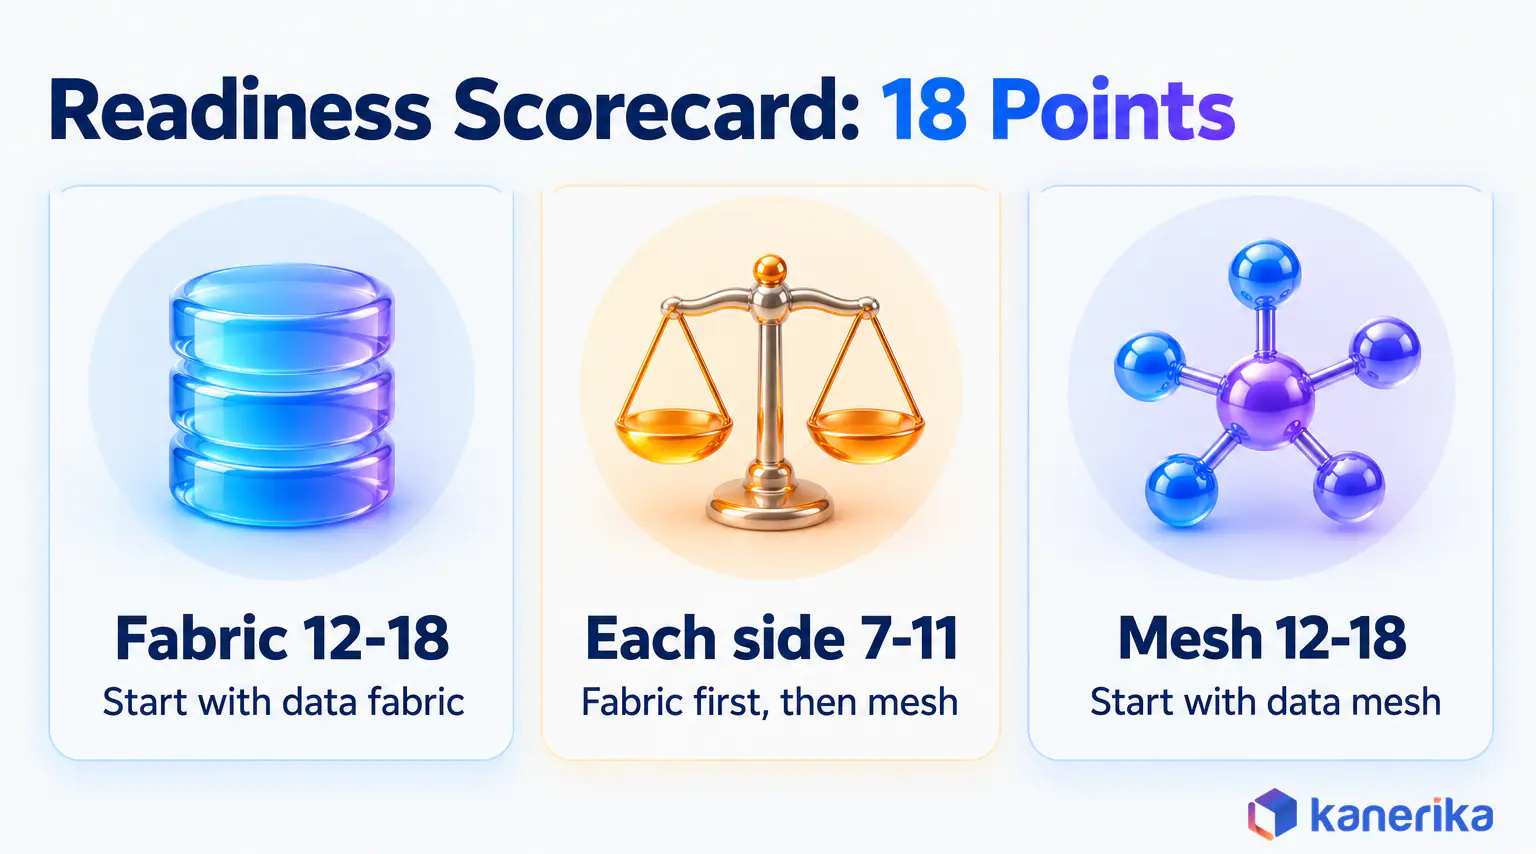
All eight weights add up to 18, so the fabric total and the mesh total always sum to 18. Read your result against three bands.
- Fabric scores 12 to 18: start with a data fabric, because connecting systems is your main bottleneck.
- Mesh scores 12 to 18: start with a data mesh, because ownership and the central queue are the constraint.
- Each side scores 7 to 11: build a fabric-style platform first, then move domains to mesh-style ownership one at a time.
Worked Example: The Manufacturer
Take the manufacturer from the opening through it. Its sources are scattered, so question 1 gives 3 points to fabric. Domains still rely on central IT, which adds 3 more to fabric.
Its backlog runs for months, so question 3 sends 3 points to mesh. Governance must stay central and there is no platform team yet, which adds 2 and 2 to fabric.
Regulation is moderate, so mesh gets 2. Users mostly want reports (2 to fabric), and leaders want results within two quarters (1 to fabric).
That makes fabric 13 and mesh 5, so the answer is a fabric first. Still, the mesh points from the backlog are a signal worth keeping. Once domains build skills, the company can revisit mesh-style ownership on top of the platform it has built.
Cost, Team and Timeline Implications
Budgets for these programs go to different places, which is why a straight price comparison misleads. Reliable public benchmarks for either pattern are also hard to find, so this section sticks to what drives cost rather than dollar figures.
A fabric’s cost sits mostly in technology. You pay for data integration tools, a metadata and catalog platform, and the engineering time to map sources. Its central team stays small, but it needs strong integration and metadata skills.
A mesh’s cost sits mostly in people. Each domain needs engineers and a data product owner, and the company also needs a platform team to build shared tooling. Licences matter less than headcount and the time it takes to change roles.
Who Does What in Each Model
Role design is where the two patterns diverge most visibly on an org chart. This table shows how each role changes.
| Role | In a data fabric | In a data mesh |
|---|
| Central data team | Builds and runs integration, models and access | Shrinks into a platform team instead |
| Platform team | Optional, since it is often the same central team | Required, because it builds self-serve tools for domains |
| Data product owner | Not needed | One per domain, accountable for quality |
| Domain data engineers | Not needed | Build and maintain domain products |
| Data stewards | Central, so they curate shared metadata | Per domain, plus a federated governance group |
| Governance lead | Sets and enforces central policy | Chairs the group that sets global rules |
Realistic Timelines
Timelines follow the same pattern, and the running example shows why. For the manufacturer, the first fabric use case is the revenue-by-customer flow across its three ERPs. In Kanerika’s delivery experience, a first fabric use case built on one integration flow usually reaches production within weeks to a few months.
A first mesh domain takes longer, often two quarters or more. Suppose the manufacturer later hands customer master data to its sales domain. That first product cannot ship until the platform, the data contracts with the ERP-owning domains and a named product owner in sales all exist.
Treat both as planning ranges, not promises, since source sprawl and data quality move them more than the pattern does.
How Major Platforms Map to Each Pattern in 2026
No platform is a fabric or a mesh by itself, yet as of October 2026 the Microsoft and Databricks documentation describes features for both. So the real question is which features you switch on and who controls them.
| Platform | Role in a data fabric | Role in a data mesh | Source |
|---|
| Microsoft Fabric | A shared analytics platform that can host the integration and storage layer | Domains group data by business area, while some tenant-level governance is delegated to them | Microsoft Learn: Fabric domains |
| Microsoft Purview Unified Catalog | A central catalog for discovery, classification and policy | Governance domains own data products, so people across the company can find them | Microsoft Learn: Purview data products |
| Databricks Unity Catalog | “The unified governance layer for data and AI built into Databricks” | Separate catalogs per domain, but under shared access rules | Databricks docs: Unity Catalog |
What the Vendor Documentation Says
Microsoft says directly that Fabric’s “data mesh architecture primarily supports organizing data into domains”. The same feature also enables federated governance, since it delegates some tenant-level settings to each domain.
A Fabric admin creates each domain and names its domain admins, ideally the business owners. Workspaces are then assigned by name, by workspace admin or by capacity, and every item in a workspace inherits the domain. Domain admins can override delegated settings, such as a default sensitivity label or who may certify items as trusted.
In Purview, a data product is a group of assets, such as tables, files and Power BI reports, with a defined use case. One governance domain manages each product, yet people across many domains can discover it. That maps closely to the data-as-a-product idea, and our guide to data governance with Microsoft Purview goes further.
On the Databricks Data Intelligence Platform, Unity Catalog gives each domain its own catalog, while one team keeps grants consistent across them. Reading a table takes SELECT on it plus USE CATALOG and USE SCHEMA on its parents. Here is a sales domain sharing customer data with finance:
-- The sales domain owns its own catalog
CREATE CATALOG sales;
ALTER CATALOG sales OWNER TO `sales-data-team`;

-- Finance analysts can read the published customer product
GRANT USE CATALOG ON CATALOG sales TO `finance-analysts`;
GRANT USE SCHEMA ON SCHEMA sales.customer TO `finance-analysts`;
GRANT SELECT ON TABLE sales.customer.customer_master TO `finance-analysts`;
The domain team controls what it publishes, while the shared metastore keeps audit and lineage in one place.
The fabric side of these platforms is metadata automation. Our guide to the AI-driven data fabric covers how machine learning on active metadata automates integration and governance.
Scale is where both patterns get tested on these platforms. In this Kanerika podcast episode, Microsoft MVP Amit Chandak discusses why Fabric deployments fail at scale. It is useful context before you plan domains on the platform.
Is Microsoft Fabric the Same as Data Fabric?
No. Microsoft Fabric is a product, while data fabric is a design pattern, and the shared word causes real confusion in vendor meetings.
Microsoft Fabric can serve as the platform for a data fabric, because it brings storage, integration and analytics into one governed estate. It can also host a data mesh, since its domains feature is built for domain ownership. Our overview of Microsoft Fabric architecture explains those layers, but the product does not decide your pattern. Your operating model does.
Common Mistakes With Either Approach
Both approaches fail in predictable ways, and most failures come from people and process rather than software. These six show up again and again, so check your plan against each one.
- Mesh without a platform team. Domains are told to own data but get no shared tooling, so each one rebuilds pipelines from scratch.
- Fabric as a tool purchase. A platform is bought, but nobody curates metadata, so the automation has nothing reliable to work with.
- Domains without product owners. Ownership is assigned on paper, yet no one is accountable when a data product breaks.
- A catalog with no stewards. Assets get registered once and never updated, and then users stop trusting search results.
- A big-bang rollout. Every source or every domain moves at once, which spreads skills thin and delays any visible win.
- No data contracts. Producers change schemas without notice, so downstream reports fail overnight.
Most of these trace back to governance that exists only as a document. The data governance best practices that work in a fabric also work in a mesh: named owners, enforced standards and quality checks that run automatically.
Datasheet
Elevate Data Governance, Compliance and Security of Your Organization
A Kanerika datasheet on putting governance, compliance and security controls in place for enterprise data, whichever ownership model you choose.
View the Datasheet →
One test helps here. Ask who gets paged when a shared dataset breaks at 6 a.m. If nobody can answer with one name, fix that before you buy anything, and add data observability tools so breaks surface before users find them.
A Phased Start That Avoids a Full Redesign
You do not need to redesign the whole estate to begin. Instead, a phased start lets you test the pattern on real data, measure it, and only then expand.
- Assess sources and ownership. List your main systems, who owns each one and where the backlog builds up. Then run the scorecard with business and IT leaders together.
- Pick one integration flow or one domain. A fabric pilot takes one cross-system question, like revenue by customer. A mesh pilot, by comparison, takes one capable domain and one data product.
- Pilot on shared governance services. Stand up the catalog, access policies and quality checks that any later source or domain will reuse.
- Expand on measured results. Track time to answer, data quality incidents and backlog length, then add the next flow or domain.
Each stage produces something useful even if you stop there. That keeps the program fundable, because leaders see working data instead of an architecture diagram.
How Kanerika Helps You Choose and Build the Right Architecture
Kanerika works with enterprises on both sides of this decision. Our data architecture services start with the diagnosis in this guide, so we map sources, ownership and backlog before any platform choice.
From there, we design the integration layer, the catalog and the access model. Pipeline work runs on FLIP, our workflow automation platform, whose DataOps module automates data pipelines. For ERP sources such as QAD, we connect the data to Microsoft Fabric through Open Mirroring.
For mesh programs, our data governance team also sets up the federated model, including global standards, domain stewards and data contracts.
One Kanerika engagement shows the fabric pattern at work. A global leader in thermal management and heat transfer had order data split across three SAP systems. We unified them on one Microsoft Fabric platform, connecting 35+ source tables across the order lifecycle and defining 50+ governed KPIs.
Access is scoped by region, Sales Organization, Sales Office and Sales Group through four levels of row-level security. As a result, time spent per reporting cycle fell by 60%. That domain-scoped access is also how a fabric can later host mesh-style ownership without rebuilding the foundation.
Case Study
60% Less Reporting Effort Across 3 SAP Systems on Fabric
A global thermal management manufacturer unified three SAP systems on Microsoft Fabric, connected 35+ source tables and 50+ governed KPIs, and cut time spent per reporting cycle by 60%.
Read the Case Study →
The Verdict: Which One Fits Your Architecture?
Start with the bottleneck. If your data is trapped in systems that do not connect, a data fabric fits, because it fixes integration and governance from the center.
If your systems connect but one central team cannot serve every domain, a data mesh fits. That holds as long as you fund a platform team and real product owners. With both problems, build the fabric layer first and then move domains onto mesh-style ownership as each one is ready.
Your next step is a short one. Run the 18-point scorecard with your data, IT and business leads in the same room. Then pick one integration flow for a fabric pilot, or one domain for a mesh pilot. Its results answer the data fabric vs data mesh question with your own data, showing which of the two fits your architecture.
Frequently Asked Questions
What is the difference between a data mesh and a data fabric?
A data fabric is a design pattern that connects data across systems through active metadata and automated integration, usually run by a central team. A data mesh is an operating model where business domains own their data and publish it as products. Fabric changes technology first, while mesh changes who is accountable for the data itself.
Can data mesh and data fabric be used together?
Yes. Many large enterprises run mesh-style domain ownership on top of a fabric-style platform. The fabric layer handles integration, the catalog, lineage and policy enforcement, while domains own and publish their data products. IBM notes that a fabric can automate parts of a mesh, such as creating data products and applying global governance rules.
How do data fabric and data mesh handle data governance?
A data fabric centralizes governance: one team defines policies and the platform applies them automatically through metadata. A data mesh federates it: a cross-domain group sets global rules for privacy, naming and quality, and each domain applies them to its own products. Both rely on a strong catalog, named owners and enforced standards.
Between data fabric and data mesh, which is easier to implement?
A data fabric is usually easier to start, because one central team can deliver a first integration flow without restructuring the company. In Kanerika’s experience that takes weeks to a few months. A data mesh takes longer, often two quarters or more, because platform tooling, data contracts and ownership roles must exist before domains publish products.
What are the cost implications for both data fabric and data mesh?
Fabric costs sit mostly in technology: integration and virtualization tools, a metadata and catalog platform, and engineering time to map sources. Mesh costs sit mostly in people: engineers and product owners in each domain plus a dedicated platform team. Reliable public cost benchmarks for either are scarce, so estimate from your own sources and team structure.
Is data mesh suitable for real-time analytics?
It can be, as long as domains publish streaming data products with clear contracts and the shared platform supports streaming. The mesh model itself is neutral on latency. Real-time use cases do raise the bar on platform engineering and monitoring, so many teams start real-time work on a central fabric layer before handing it to domains.
What is data mesh vs data fabric vs data vault?
Data mesh is an operating model for domain-owned data, and data fabric is a design pattern for connecting data through metadata and integration. Data vault is a modeling method for auditable warehouse layers built from hubs, links and satellites. They solve different problems, so a company can use a data vault inside either a fabric or a mesh.
What is data mesh vs data lake vs data warehouse?
A data lake and a data warehouse are storage designs: the lake holds raw data in many formats, while the warehouse holds structured, modeled data for reporting. Data mesh is an operating model that decides who owns data, and a domain can publish products from either store. The choice of storage and the choice of ownership model are separate decisions.
What is the difference between data fabric and data lakehouse?
A data lakehouse is a storage and processing architecture that combines lake-style storage with warehouse-style tables and queries. A data fabric is a design pattern that connects many stores, including a lakehouse, through metadata and integration. A lakehouse can be one source inside a fabric, so the two often work together rather than compete.
Between data fabric and data mesh, which is better for large, complex organizations?
Large organizations often need both. A fabric layer connects the many systems that come with size and acquisitions, while mesh-style ownership stops one central team from becoming the bottleneck. Start with the problem that hurts most: disconnected systems point to fabric first, and a months-long central backlog with capable domains points to mesh.
Does data mesh require decentralized data storage?
No. Data mesh decentralizes ownership, not necessarily storage. Domains can publish their data products on shared platform storage, such as one cloud data platform, as long as each domain controls its own products, contracts and quality. Many mesh programs run on a single platform, with domains and catalogs providing the separation of responsibility.
Can Databricks support a data mesh?
Yes. Databricks Unity Catalog is the unified governance layer for data and AI built into Databricks. Its catalog, schema and table hierarchy lets teams give each domain its own catalog under shared access rules. Domains can then own and publish data products, while central policies, lineage and auditing stay consistent across the whole platform.
What are the 4 pillars of data mesh?
Zhamak Dehghani defined four principles in 2020: domain-oriented ownership of data, data as a product, a self-serve data infrastructure platform, and federated computational governance. Together they move data responsibility from a central team to the business domains that create the data, while shared standards and a common platform keep those domains interoperable and secure.
Is data mesh obsolete?
No. Major platforms are still building support for it. Microsoft Fabric’s domains feature is designed for data mesh architecture, Purview manages data products through governance domains, and AWS still documents mesh as a current pattern. What has faded is the idea that mesh suits every company, since it needs mature domains and a funded platform team.
Is mesh better than fabric?
Neither is better in general. Mesh is better when a central data team cannot keep up with many capable business domains. Fabric is better when the main problem is disconnected systems, heavy regulation or a small data team. The right answer depends on your bottleneck, which a weighted scorecard can help you identify before you commit.
Who needs a data mesh?
Organizations with many business domains, long central backlogs and domain teams that already have engineers and product owners. They also need leadership willing to fund a platform team and change ownership roles. The biggest risk is decentralizing too early, before domains have the skills, standards and shared tooling to run data products well.
What problems does data mesh solve?
Data mesh addresses the bottleneck of a single central data team serving the whole company. It cuts long request queues, puts data ownership with the people who understand the data, and lets domains improve their products in parallel. It also makes quality accountable, because each data product has a named owner and published standards.
Why is it called data fabric?
The name describes a woven layer that connects data across many systems, the way threads form a fabric. Rather than moving everything into one store, the fabric links sources through metadata, integration and shared access rules. Gartner describes it as a data management and data integration design concept, not a single product or tool.
What is data fabric used for?
Data fabric gives people consistent, governed access to data spread across many systems, such as several ERPs, clouds or acquired platforms. Typical uses include unified customer or revenue views, central access policy enforcement, lineage tracing and automated data integration. It suits organizations whose main problem is connecting systems rather than deciding who owns data.
Is Microsoft Fabric a data mesh?
Microsoft Fabric is a product, not a data mesh by itself, but it supports one. Its domains feature organizes data by business area and enables federated governance by delegating some tenant-level settings to domains. It can also serve as the platform for a data fabric. Your operating model, not the product, decides the pattern.














