TL;DR
Enterprise data security fails when teams protect systems but lose track of the sensitive data and its copies. Seven mistakes cause most of the damage. Each one has a simple fix with a named owner. Start by finding the data, then limit access, protect it, watch it and test your restores. A breach cost USD 4.99 million on average in 2026, according to IBM. Prove the fixes on one high-risk domain in 90 days before scaling them.
Key Takeaways
- Enterprise data security means knowing where sensitive data and its copies live, who may use them for what, and enforcing that every day.
- The costliest mistakes are organizational, such as classifying once, reviewing access yearly and buying tools before anyone owns the data.
- Five layers do the work: discover and classify, control access, protect the data itself, monitor use, and recover with tested restores.
- DLP, DSPM, CASB and encryption solve different problems, so pick controls by the question you need answered, not by the vendor category.
- Copilots and AI tools read whatever their users can read, which turns old oversharing into a new exposure.
- A 90-day plan on one high-risk domain, measured with five metrics, proves more to a board than a long policy document.
The Dashboard Was Locked. The Export Was Not.
Picture a retail bank’s analytics team on a Monday morning. The customer dashboard sits behind single sign-on, row-level security and a quarterly access review. Every control on that report also passed its last audit.
Then someone searches the shared drive for a churn file. They find a CSV export of the same customer table, made six months earlier for a one-off model. It holds names, account numbers and balances, and its sharing setting reads “anyone with the link.”
Nobody broke a rule to create that file. The export button worked, but no policy followed the rows once they left the warehouse.
Closing that gap between a secured system and its unsecured copy is what enterprise data security is for. This guide covers the seven mistakes behind most exposures, the fix for each, a 90-day plan and the metrics that prove it works.
What Is Enterprise Data Security?
Enterprise data security is the practice of protecting an organization’s sensitive data wherever it lives, moves or gets copied. In other words, you need to know where the data is, who may use it and for what purpose. Then you enforce those answers with controls you can prove.
The definition therefore puts the data at the center, with servers and networks in a supporting role. A firewall protects a perimeter, but a customer record travels through warehouses, spreadsheets, SaaS apps, test environments and AI prompts. Each copy carries the same risk as the original.
The classic model behind it is the CIA triad of confidentiality, integrity and availability. Confidentiality keeps data away from people who should not see it, while integrity keeps it accurate and unaltered. Availability means the right people can still reach it when they need it, even after an attack.
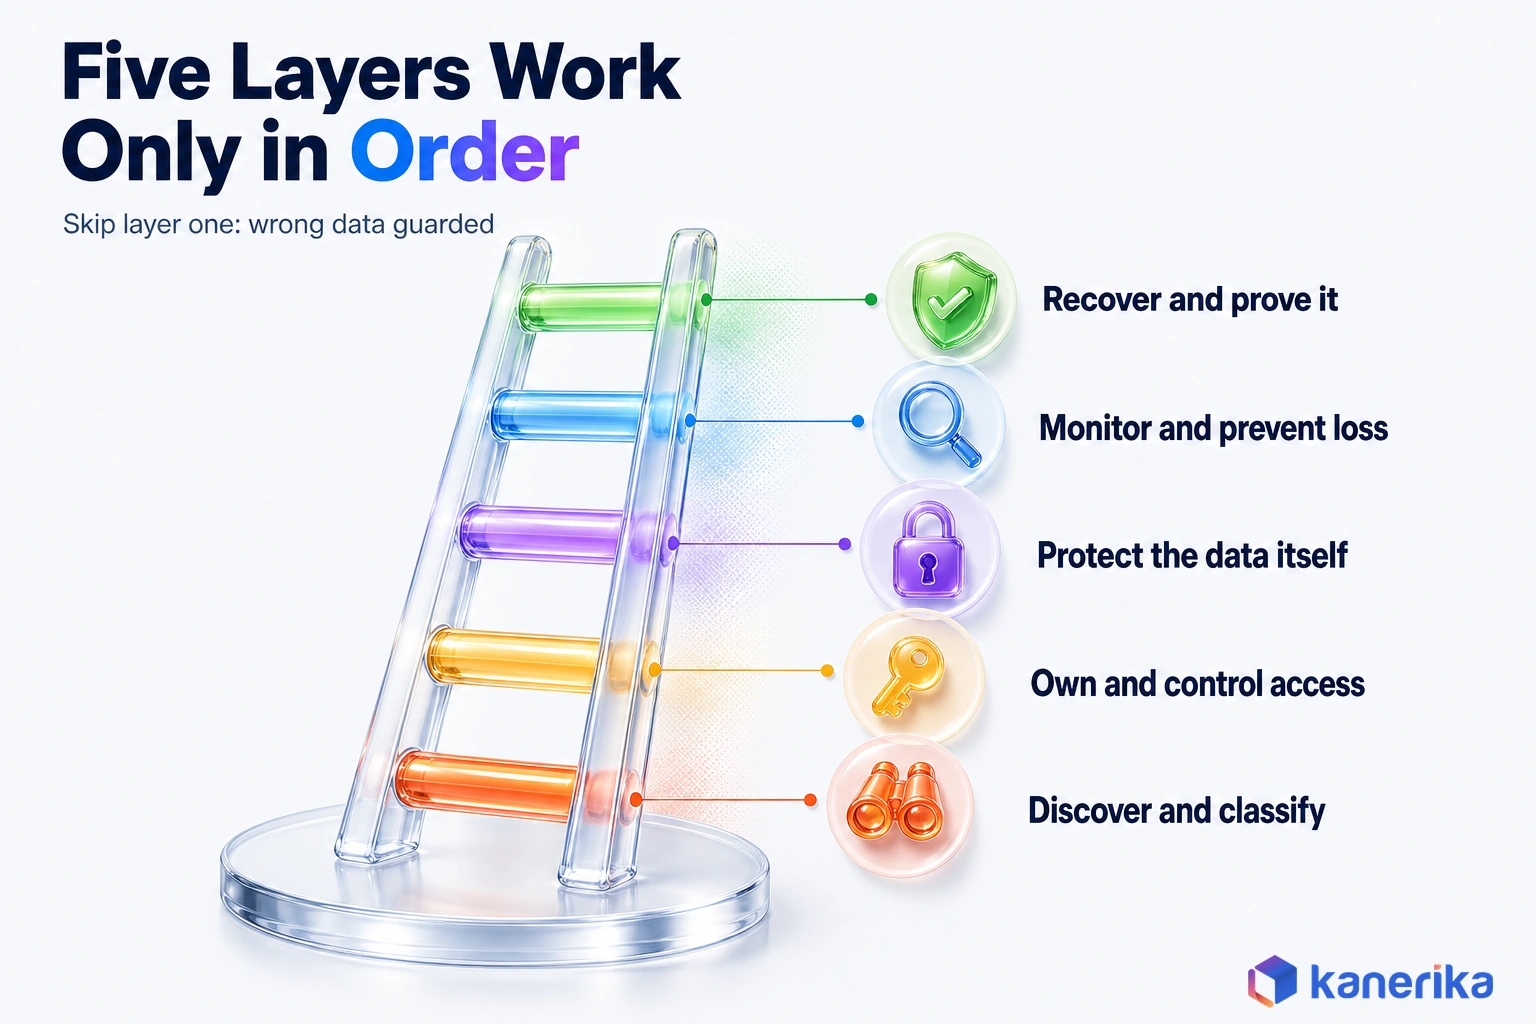
In practice, five activities turn that model into an operating program. Teams first discover and classify sensitive data, and then they control who can access it. After that, they protect the data itself, monitor how it is used and recover it when something fails.
Talk to Kanerika
Not Sure Where Your Sensitive Data Sits?
Kanerika maps sensitive data, its copies and who can reach it, including the copilots and AI tools in your estate, then ranks the gaps by risk.
Schedule a Demo →Data Security vs Cybersecurity, Data Privacy and Data Governance
These four terms overlap, and that overlap also explains why no team owns the problem. Cybersecurity protects systems and networks, while data privacy decides what you may lawfully do with personal data. Data governance assigns owners and rules, and data security then enforces those rules on the data itself.
| Discipline | Question it answers | Typical owner | Example control |
|---|---|---|---|
| Data security | Is this data protected wherever it lives and moves? | CISO with data owners | Encryption, masking, data loss prevention |
| Cybersecurity | Are our systems, networks and endpoints defended? | CISO and security operations | Firewalls, endpoint detection, patching |
| Data privacy | May we collect and use this personal data, and for what? | Privacy officer or legal | Consent records, retention limits |
| Data governance | Who owns this data and what rules apply to it? | Chief data officer and data stewards | Catalog, classification policy, ownership |
A useful test, for example, is to ask who would answer if a regulator called about one specific dataset. When the honest answer is “probably security,” governance and security have not met yet.
Why Enterprise Data Security Matters in 2026
The short answer is cost, and the cost keeps rising. A breach now hits budgets, regulators and customer trust at the same time. The attack routes have also shifted toward places many programs do not watch closely.
The figures below come from the two reports most security leaders cite, IBM’s annual study and Verizon’s breach investigations report. Both put the 2026 numbers on the record:
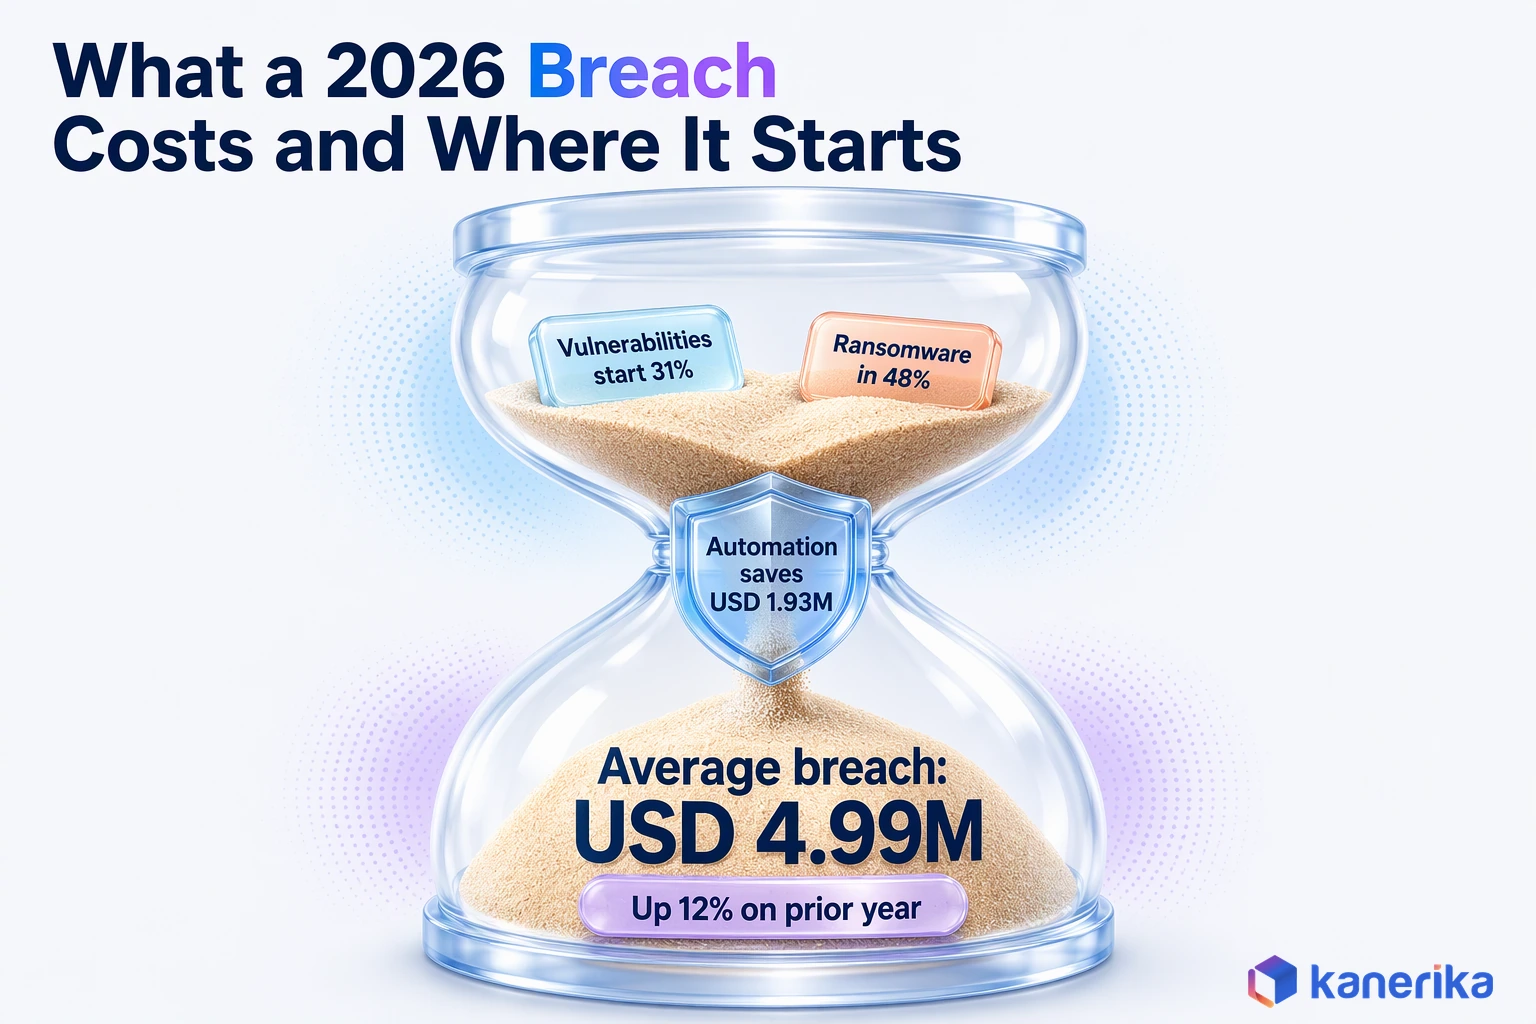
- The global average cost of a data breach reached USD 4.99 million, up 12% on the prior year and a record high, according to the IBM Cost of a Data Breach Report 2026.
- Organizations that used security AI and automation extensively saved USD 1.93 million per breach compared with those that used none (IBM).
- Software vulnerabilities started 31% of breaches and moved ahead of stolen credentials, according to the Verizon 2026 Data Breach Investigations Report.
- Ransomware appeared in 48% of breaches, even as ransom payouts shrank (Verizon).
Read together, the numbers say the bill depends less on the attack itself. It depends on how much reachable data sits behind it and how fast a team can find, contain and restore it.
Where Breaches Start Now
For years, the standard advice was to guard passwords above all else. Stolen credentials still matter, but the Verizon data shows unpatched software has overtaken them as the most common way in. For example, an attacker who exploits a vulnerable file-transfer server never needs a password at all.
Ransomware has also changed shape. Attackers increasingly steal data before they encrypt it, so a good backup no longer ends the incident. The stolen copy becomes the bargaining chip for extortion, which is why encryption and keeping less data matter as much as recovery.
AI, meanwhile, has entered the picture on both sides. IBM reports a 56% increase in AI-driven attacks, led by deepfake impersonation and AI-enabled malware. Still, the same report shows that defenders who automate detection save real money.
More Copies, More Identities, More AI Consumers
Three trends multiply the data a team has to protect. The first is copies, because every export, extract, test refresh and BI dataset creates another place where sensitive rows live.
After that come identities. Service accounts, API keys, pipelines and bots are identities too, yet they rarely appear in an access review. So a pipeline account with read access to every schema is a standing invitation.
Finally, there are AI consumers. A copilot answers questions using whatever its user can already open, so it inherits every old permission. If a finance folder was overshared years ago, the copilot will find it in seconds and quote it back.
What Enterprise Teams Get Wrong About Data Security
The mistakes that cause the most damage are rarely exotic. They are ordinary habits from a time when data lived in a few systems. Those habits stop working once data spreads across clouds, SaaS apps and AI tools.
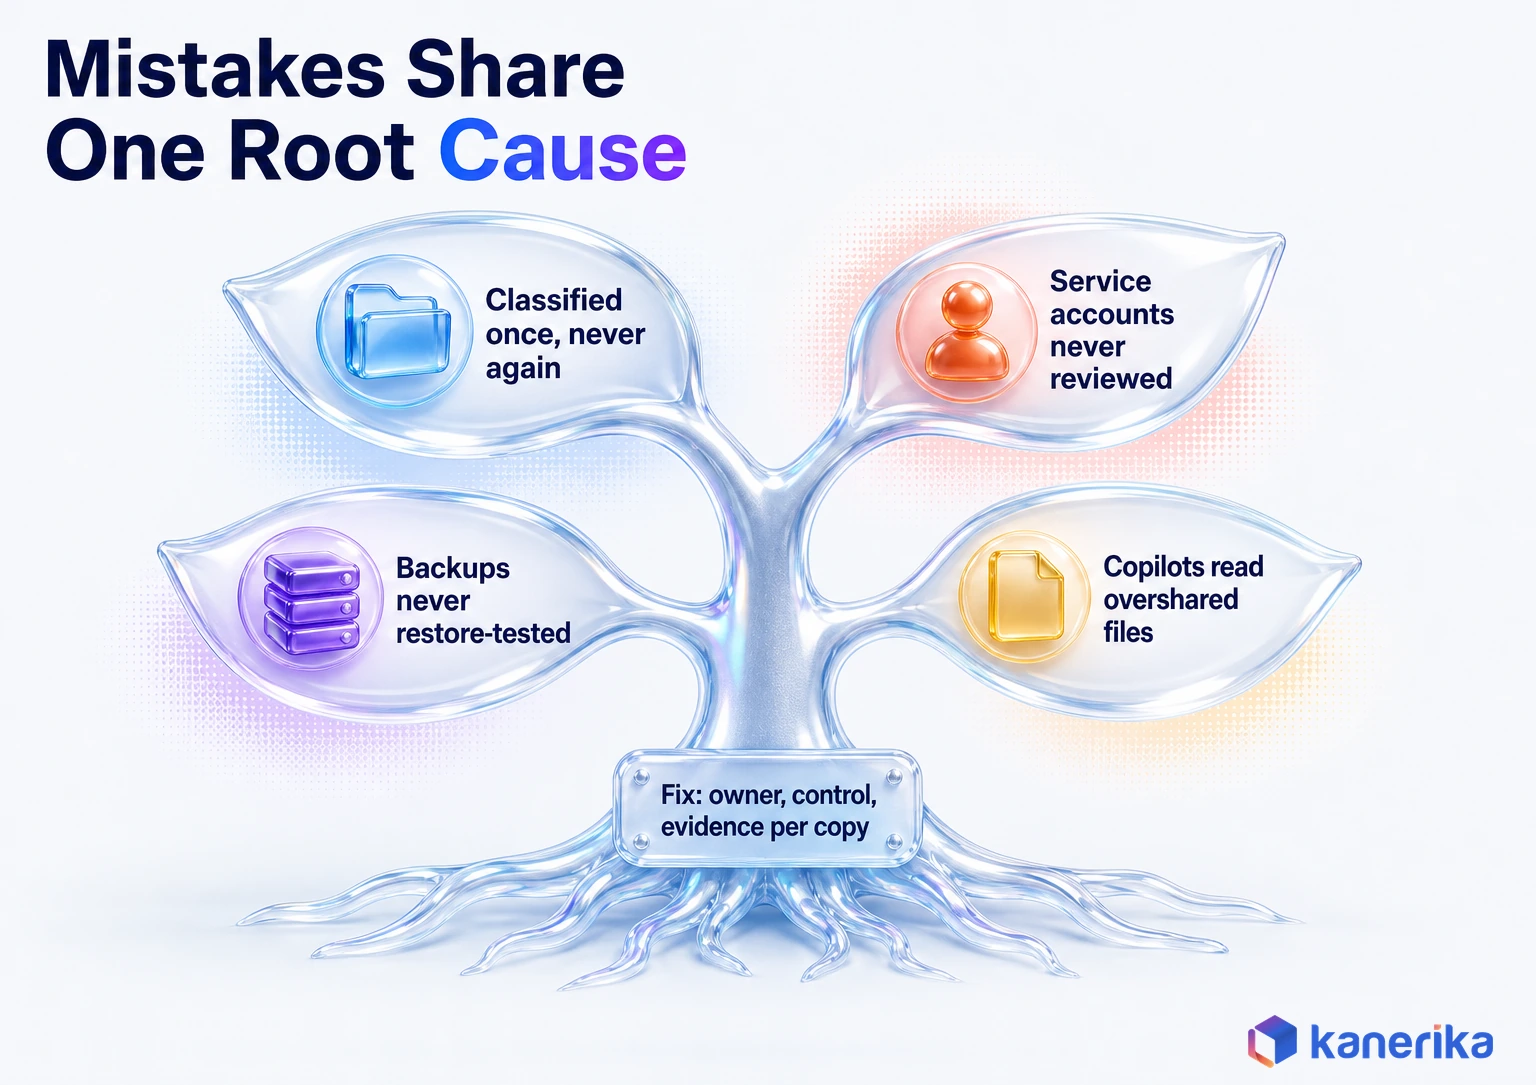
Each mistake below also has the same root. The team protected a system, a project or a moment in time, while the data kept moving. So the fix in every case is to tie a control to the data itself, give it an owner and keep evidence that it works.
Seven Mistakes, Why They Happen and the Fix
| Mistake | Why it happens | The fix | Owner |
|---|---|---|---|
| 1. Securing systems instead of the data and its copies | Budgets and audits are organized by platform | Inventory sensitive datasets and every known copy, then apply controls that travel with the data | CISO with the chief data officer |
| 2. Classifying data once and never again | Classification is run as a project with an end date | Automate scanning on new stores and re-scan on a schedule | Data governance lead |
| 3. Reviewing access yearly while service accounts go unreviewed | Reviews cover people, not pipelines and bots | Add non-human identities to quarterly reviews and remove standing admin rights | Identity and access team |
| 4. Buying a tool before defining ownership and permitted use | A vendor demo feels like progress | Name an owner and write permitted uses for each sensitive domain first | Data owners, with procurement |
| 5. Encrypting without managing keys or masking non-production data | Encryption at rest is switched on by default and then forgotten | Centralize key management and mask or tokenize data in dev and test | Security architecture |
| 6. Keeping backups that are never restore-tested | Backup jobs report success, so nobody checks the restore | Run scheduled restore tests and keep at least one immutable copy | Infrastructure and operations |
| 7. Ignoring what AI tools and copilots can read | Copilots inherit existing permissions, and old oversharing was invisible | Fix oversharing, label sensitive content and limit what AI can index | CISO with AI governance |
Two pressures make rows 1, 3 and 7 worse. When approved tools are slow, people adopt shadow AI tools, and a stretched security team cannot review what it cannot see.
None of these fixes needs a new platform on day one. Most need a decision, an owner and a schedule. For detail on each row, see our guide to data security best practices.
How Enterprise Data Security Works: Five Layers
A working program can be described as five layers that each answer one question. Where is the sensitive data? Who may use it? Is the data itself protected? Is anyone misusing it? Can we get it back?
The layers also depend on each other in order. You cannot restrict access to data you have not found, and you cannot spot misuse before you know normal use. As a result, a team that skips layer one usually ends up with strong controls around the wrong datasets.
1. Discover and Classify Sensitive Data
Discovery means scanning every store, especially the ones nobody planned. That covers warehouses and lakehouses, file shares, SaaS apps, email, backups and the shadow copies people create along the way. Classification then tags each item by sensitivity, such as public, internal, confidential or restricted.
The goal, in other words, is a living map that updates as new data lands. Because new data lands every day, scanning has to run on a schedule and on every new store. A label also needs to drive something, such as an access rule or a DLP policy, or it is decoration.
2. Assign Owners and Control Access
First, every sensitive domain needs a business owner who decides who may use it and why. Security then enforces that decision with least privilege, multi-factor authentication and role-based or attribute-based access.
Non-human identities also deserve the same treatment as people. Pipelines, service accounts and API keys should have narrow scopes, expiry dates and a place in the access review. In the bank scenario above, for instance, a scoped export role with an expiry would have stopped the CSV from outliving its purpose.
Access reviews work best when they are short and frequent. A quarterly review of high-risk data, signed by its owner, beats an annual review of everything that nobody reads.
3. Protect the Data Itself
This layer assumes that some other control will fail sooner or later. Data encryption at rest and in transit makes a stolen copy unreadable, as long as the keys are managed separately and rotated. Customer-managed keys also let you cut off access to data held by a provider.
Data masking and tokenization protect data that people need to use but not to see in full. Developers can test with realistic but fake values, while analysts join on a token instead of a real account number. Masking non-production copies therefore removes one of the largest and least watched exposures.
4. Monitor Use and Prevent Loss
Monitoring watches how data is used and then stops the risky moves. Data loss prevention (DLP) inspects content leaving through email, endpoints, browsers and cloud apps. It can block a file with card numbers or warn a user before they share it.
Posture signals, by comparison, add a second view. Data security posture management tools flag stores that are overexposed, unencrypted or holding data they should not. Those alerts then flow into a SIEM together with identity and endpoint events, so analysts can connect them. Insider-risk rules also look for patterns, such as a departing employee downloading a whole customer list.
Checklist
Data Governance Checklist
Kanerika’s data governance checklist covers ownership, classification, access policies and audit evidence, the groundwork every data security layer depends on.
Get the Checklist →Network and Endpoint Controls Around the Data
Network and endpoint controls do not protect data on their own, but they shrink the paths an attacker can use to reach it. They work best when tuned to where the sensitive data sits:
- Network segmentation: Separate the zones that hold restricted data so a compromised laptop cannot reach the warehouse directly.
- Cloud access security broker (CASB) or security service edge (SSE): Inspect traffic to SaaS apps and stop uploads of sensitive content to unsanctioned tools.
- Patch management: Close known vulnerabilities on internet-facing systems first, since exploited software now starts more breaches than stolen passwords.
- Intrusion detection and prevention (IDS/IPS): Watch traffic into the zones that hold restricted data and block known attack patterns automatically. Teams tuning that visibility often start by comparing ISP and residential proxies, since each changes how traceable inbound and outbound traffic is.
- Endpoint detection and response (EDR): Spot and isolate a compromised laptop before it reaches a data store; endpoint security adds the detection and response that prevention alone misses.
Zero trust ties these controls together because it verifies every user, device and request instead of trusting the network location. Our guide to zero trust data security covers how that model applies to data stores.
5. Recover and Prove It
Recovery is the layer that decides whether a breach is a bad week or a bad year. The 3-2-1 rule is a sound baseline: three copies of the data, on two types of media, with one copy offsite. Many teams also add an immutable or offline copy that ransomware cannot encrypt.
A backup only counts once a restore has worked. So schedule restore tests for critical datasets, time them and keep the results as evidence. Retention and deletion belong here too, since data you no longer hold cannot leak. For tooling options, see our review of data recovery tools.
Datasheet
Elevate Data Governance, Compliance and Security of Your Organization
A Kanerika datasheet on running governance, compliance and security as one program, so each sensitive dataset has an owner, a control and the evidence to prove it.
View the Datasheet →DLP vs DSPM vs CASB vs Encryption: Which Control Solves Which Problem
Security buyers often compare these tools as if they were rivals, but each one answers a different question about the data. The table maps each control to the problem it actually solves and to the gap it leaves behind.
| Control | Problem it solves | Where it acts | What it cannot do | Typical first owner |
|---|---|---|---|---|
| Data loss prevention (DLP) | Sensitive content leaving through email, endpoints or uploads | At the point of use and transfer | Find data at rest in stores nobody scanned | Security operations |
| Data security posture management (DSPM) | Not knowing where sensitive data lives or how exposed it is | Across cloud and SaaS data stores | Block a file transfer in real time | Cloud security or data security lead |
| Cloud access security broker (CASB) | Uncontrolled use of SaaS apps and shadow IT | Between users and cloud services | Protect data inside your own databases | Network or cloud security |
| Encryption and key management | A stolen or misplaced copy being readable | On the data itself, at rest and in transit | Stop an authorized user from misusing data | Security architecture |
For depth on two of these, read our guides to data security posture management and Microsoft Purview DLP. In short, DSPM finds the problem, DLP stops data leaving, and encryption limits the damage when both miss.
Five Questions to Answer Before You Buy
A clear brief saves months of tool evaluation. Answer these five questions in writing before any demo, and most vendor shortlists shrink on their own:
- What data? Name the sensitive data types and the domains that hold them.
- Where does it move? Map the stores, apps, exports and AI tools it passes through.
- Who uses it? List the human roles and the service accounts with access.
- Which obligation applies? Note the regulations and contracts that set the bar.
- What evidence do you need? Decide which reports an auditor or the board will ask for.
Buy, Extend Your Platform, or Hybrid
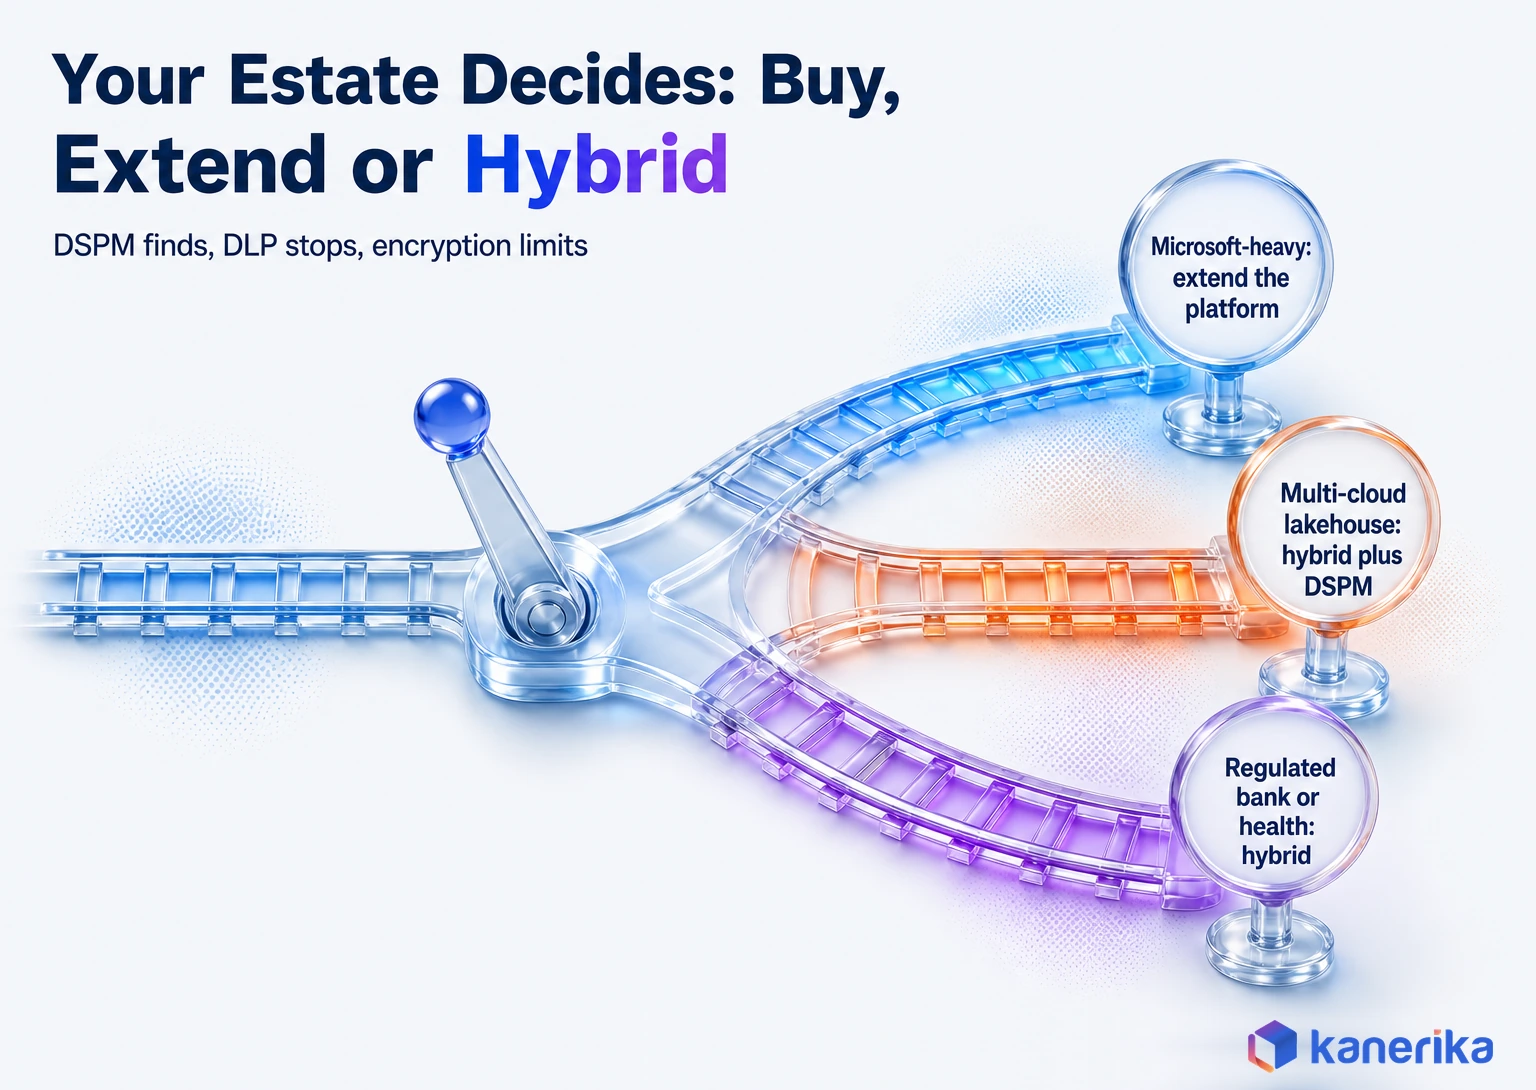
Once those answers exist, the build choice depends mostly on your estate. A Microsoft-heavy organization running Microsoft 365, Azure and Fabric should extend its platform first. Sensitivity labels, DLP and identity controls in that stack follow the data across its services, so a separate tool would duplicate much of the work. Our guide to data warehouse security in Microsoft Fabric shows those native controls at work.
A multi-cloud lakehouse, on the other hand, is different. When data spreads across AWS, Azure, Databricks or Snowflake and many SaaS apps, no single platform sees all of it. A hybrid fits better there, with native controls in each platform and a DSPM tool for one cross-cloud inventory. Our guides to Databricks security and Snowflake security cover the native side of that split.
Regulated banks and health systems usually land on a hybrid as well, but for a different reason. They need platform controls for daily enforcement and specialist tools where an auditor expects separate evidence. In every case, the five answers above decide the scope, not the vendor’s feature list.
Securing Enterprise Data Across Cloud, SaaS and AI
Cloud providers secure their infrastructure, while you secure what you put on it. That shared responsibility model is simple to state but easy to forget. The provider patches the hypervisor, but your team still owns access settings, encryption keys and every misconfigured storage bucket. Clear cloud governance rules give each of those settings a named owner.
SaaS also adds a vendor-management layer. Each app holds a slice of your sensitive data under its own security model. Contracts, security reviews and offboarding steps therefore matter as much as technical controls, and someone must confirm deletion when a vendor relationship ends. An AI vendor risk assessment applies the same review to suppliers whose models touch your data.
AI then raises the stakes on all of it. Copilots surface overshared files, prompt injection can trick an assistant into leaking what it can read, and sensitive data can slip into training sets. IBM also put the average cost of an AI model inversion attack at USD 6 million.
The practical response is to treat AI tools as new data consumers with their own access scope. Fix oversharing before rollout, label sensitive content so AI tools respect it, and log prompts against sensitive data. Our guide to securing the data AI systems read covers those controls in detail. An AI governance framework then decides which AI uses are allowed at all.
Regulations and Frameworks to Map Your Controls To
Regulations rarely tell you which product to buy. Instead, they set an outcome to reach and the proof to keep, so mapping each control to an obligation pays off at audit time. One control, such as quarterly access reviews, can often satisfy several frameworks at once. Compliance automation can then collect that proof on a schedule instead of the week before an audit.
| Obligation | Applies to | What it asks of data security | Evidence to keep |
|---|---|---|---|
| GDPR | Personal data of people in the EU | Security appropriate to the risk; fines up to EUR 20 million or 4% of worldwide annual turnover under Article 83 | Records of processing, risk assessments, breach logs |
| US state privacy laws | Personal data of residents in states with privacy statutes | Reasonable security and limits on how data is used and kept | Data inventories, retention schedules, vendor contracts |
| HIPAA Security Rule | Electronic protected health information | Administrative, physical and technical safeguards | Risk analysis, access logs, policies |
| PCI DSS v4.0.1 | Cardholder data | Protect stored card data and restrict access by need to know | Scans, segmentation tests, access reviews |
| SEC cyber disclosure (Form 8-K Item 1.05) | US public companies | Disclose material incidents, generally within four business days of the materiality decision | Incident timelines, materiality decisions |
| NIST CSF 2.0 | Any organization (voluntary) | Govern, identify, protect, detect, respond and recover | Current and target profiles |
| ISO/IEC 27001 | Organizations seeking certification | A managed information security system with risk-based controls | Statement of applicability, audit reports |
| SOC 2 | Service providers handling client data | Controls against the trust services criteria | Independent auditor’s report |
The Dates Behind the Table
Three dates shape how you read the table, and each one changes what a team needs ready. Under the SEC’s cybersecurity disclosure rules, Item 1.05 incident disclosures became mandatory for most registrants on December 18, 2023. With only four business days after the materiality decision, incident timelines must be evidence-ready before an incident, not pieced together after it.
NIST CSF 2.0 added the Govern function to the framework’s core functions. Govern puts roles, accountability and policy ahead of tools, which is the same owner-first argument this guide makes for every sensitive dataset.
The PCI Security Standards Council published PCI DSS v4.0.1 as a limited revision on June 11, 2024. It is still the version assessors test against, so map card-data controls to its requirements.
On-Demand Webinar
Transform Your Data Strategy with Microsoft Purview: Governance, Security & Growth
An on-demand session on using Microsoft Purview to classify data, apply protection policies and keep audit evidence across a governed estate.
Watch the Webinar →AI rules are adding to this list as well. Our guide to AI compliance obligations covers them, while our post on ISO 27701 certification explains how privacy management extends ISO 27001.
A 90-Day Enterprise Data Security Plan
A strategy document does not show progress, but a bounded plan with owners does. The plan below covers one high-risk domain in 90 days, so the team learns the method before scaling it across the estate.
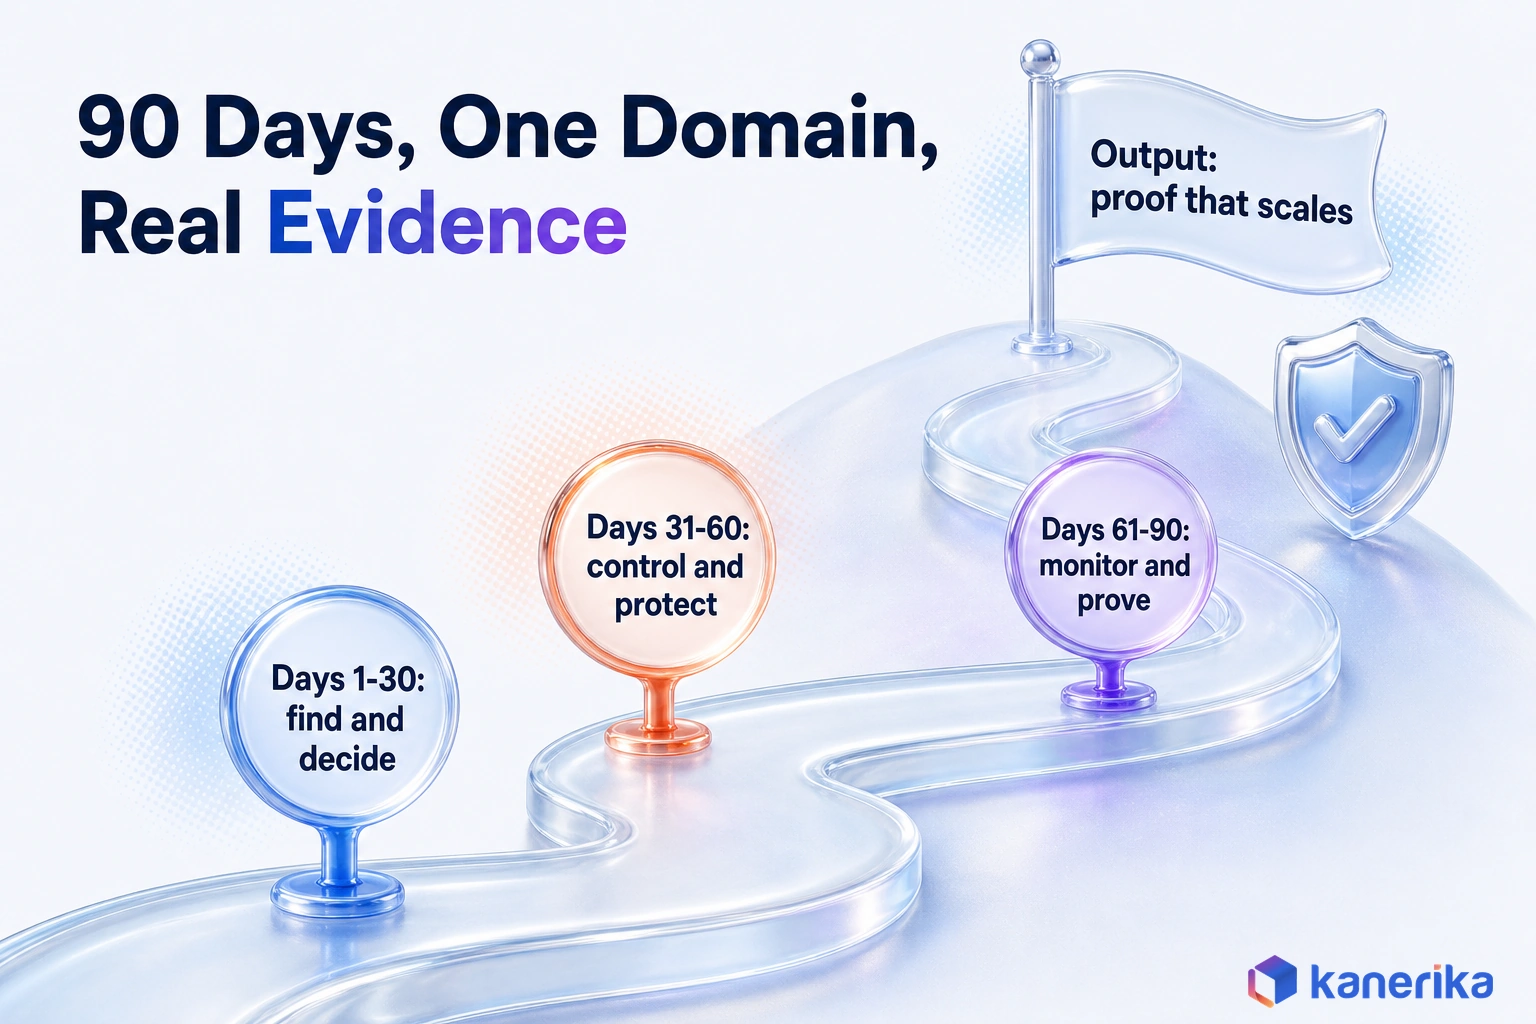
- Days 1 to 30, find and decide. Pick one domain, such as customer data. Scan its stores and copies, classify what you find and name a business owner. The CISO and the chief data officer sponsor this phase together.
- Days 31 to 60, control and protect. Remove excess access, including service accounts. Mask non-production copies, confirm key management and switch on DLP rules for the domain’s sensitive types. Identity, security architecture and data engineering share the work.
- Days 61 to 90, monitor and prove. Route alerts to the SIEM, run a restore test and hold the first access review. Then report the five metrics in the next section to leadership. Security operations and the domain owner close the phase.
As a result, the output after 90 days is evidence that an auditor can check. You hold a classified inventory, a shorter access list, a passed restore test and a first set of metrics. That package also makes the case for the next domain.
Worked Example: Protecting Customer Data Used by Analytics and AI
Take the customer table from the opening scenario and walk it through the five layers. Discovery finds the warehouse table, three BI datasets, the forgotten CSV and a copy in a test environment. Classification then marks names, account numbers and balances as restricted.
Next, the owner in retail banking decides that analysts need balances and segments but not names. Access then shrinks to two roles and one scoped pipeline account with an expiry date. The test copy is masked, and the CSV is deleted once the owner confirms nobody needs it.
On a SQL Server or Azure SQL table, that access decision takes a few lines of T-SQL. Dynamic data masking hides names and most of each account number from analysts. Only a role the owner approves sees real values:
-- Analysts can query the table but see masked values
CREATE ROLE analyst_ro;
GRANT SELECT ON dbo.Customers TO analyst_ro;

ALTER TABLE dbo.Customers
  ALTER COLUMN FullName ADD MASKED WITH (FUNCTION = 'default()');
ALTER TABLE dbo.Customers
  ALTER COLUMN AccountNumber ADD MASKED WITH (FUNCTION = 'partial(0,"XXXX-XXXX-",4)');

-- Only the role the data owner approves sees real values
CREATE ROLE fraud_review;
GRANT UNMASK TO fraud_review;
Masking is not encryption, though. A user with free-form query rights can sometimes infer masked values. So keep the analyst role narrow and pair masking with encryption.
DLP rules now warn anyone who tries to export restricted columns or share them outside the company. The copilot the analytics team uses, meanwhile, can only reach the masked view. A restore test of the warehouse table passes in under an hour, and the result goes into the audit file.
In the end, the dashboard looks the same to its users. The difference is that every copy of the data now has an owner, a control and a record that the control works.
Data Security Metrics That Show the Program Is Working
Boards and auditors want to see a trend they can follow quarter by quarter. Five metrics cover most of what matters, and each one comes from systems you probably already run.
| Metric | What good looks like | Source system | Audience |
|---|---|---|---|
| Share of sensitive data classified | Rising each quarter toward full coverage of known stores | Catalog or DSPM tool | Board and data owners |
| Over-permissioned accounts, human and non-human | Falling, with no standing admin rights on restricted data | Identity platform | CISO and audit |
| Mean time to detect and contain | Falling over time, measured per incident | SIEM and incident tickets | Board and security operations |
| Restore-test pass rate | Every critical dataset tested on schedule, with passes logged | Backup platform | CIO and audit |
| Policy exceptions open past due | Close to zero, each with a named owner | Governance or GRC tool | Risk committee |
Keep the list short and stable so the trend means something. When a board sees the same five numbers every quarter, it will notice when one moves.
How Kanerika Delivers Enterprise Data Security in Stages
Kanerika treats data security as a governance problem first and a tooling problem second. Our data governance services build the ownership, classification and access model, while our Microsoft Purview practice enforces it across the estate. Work runs in four stages:
- Assess. Map the estate, find sensitive data and rank the risk by domain.
- Design. Set the controls and the operating model, including owners and how exceptions get approved.
- Pilot. Prove the design on one high-risk domain and collect the evidence.
- Scale. Roll out to the remaining domains and hand over to the client’s team.
Three Kanerika solutions support that work across governance, compliance and protection: kanGovern, kanComply and kanGuard, all delivered on Microsoft Purview. Kanerika also holds ISO 27001, ISO 27701 and SOC 2 certifications, so we run the same controls on our own operations.
Kanerika Service
Data Governance and Security Services
Kanerika builds ownership, classification, access and protection policies on Microsoft Purview, then proves each control on a high-risk domain before scaling it.
Explore Data Governance ServicesOne change to plan for: on November 12, 2026, Microsoft announced the retirement of Purview Data Governance, with support ending November 12, 2027. That covers Unified Catalog and Data Map, while the Purview data security controls this guide covers, such as sensitivity labels and DLP, continue.
The pilot stage matters most, because it turns a design into evidence. For instance, a bounded domain shows which controls work in daily use, which exceptions appear and how much effort each owner carries. Scaling then repeats a tested pattern instead of a theory.
Case Study: Zero Breaches at a Global Bank
A prominent global bank with nearly 9,000 branches and 22,000 ATMs shows the approach in practice. First, Kanerika used the Purview Data Map to discover and classify data across SAP, Dynamics 365, CRM, Oracle, Netezza and a central lakehouse. Purview policies then covered PII, PCI and PHI data, with automated lineage and sharing rules set by data type and sensitivity.
The results on the bank’s case study page are specific. Data classification accuracy improved by 72%, the bank recorded 0% data breaches, and it reached 100% adherence to compliance regulations.
That is the same five-layer pattern applied at bank scale. Discovery came first, ownership and policies followed, and the evidence came from the platform rather than from a spreadsheet.
The Bottom Line
Enterprise data security rarely fails for lack of tools. It fails because teams secure the system and lose track of the data, as the bank team in the opening did. They locked the dashboard, but the CSV export of the same customer table stayed open to anyone with the link. Each of the seven mistakes is a version of that one gap.
The fix follows a set order. Find every copy of the sensitive data and give each one an owner and a control. Then prove those controls on one high-risk domain within 90 days. That is how enterprise teams fix what they get wrong: they secure the data and its copies first, then show the evidence.
Frequently Asked Questions
What is enterprise data security?
Enterprise data security is the practice of protecting an organization’s sensitive data wherever it lives, moves or gets copied. It means knowing where the data and its copies sit, who may use them and for what purpose. Teams enforce those answers through discovery, access control, encryption and masking, monitoring and tested recovery, and they keep evidence that each control works.
What do you mean by data security?
Data security means protecting digital information from unauthorized access, corruption and theft across its whole life. It covers the data itself, the systems that store it and the people and accounts that use it. Some teams call it information security or data protection. In an enterprise, it also means proving to auditors that the controls really work.
What is the 3-2-1 rule for data protection?
The 3-2-1 rule means keeping three copies of your data on two different types of storage, with one copy offsite. Many teams now add an immutable or offline copy that ransomware cannot encrypt or delete. The rule only works when restores are tested on a schedule, because a backup that has never been restored is unproven.
What do enterprise teams most often get wrong about data security?
They protect systems instead of the data and its copies. Common mistakes include classifying data once, skipping service accounts in access reviews and buying tools before anyone owns the data. Others are encrypting without key management, never testing restores and ignoring what copilots can read. Each mistake has a fix with an owner and evidence.
What is the difference between DLP and DSPM?
Data security posture management finds where sensitive data lives across cloud and SaaS stores and flags how exposed it is. Data loss prevention watches data in motion and blocks or warns when sensitive content leaves through email, endpoints or uploads. DSPM tells you where the risk is, and DLP stops data from walking out the door.
How much does a data breach cost in 2026?
IBM’s Cost of a Data Breach Report 2026 puts the global average cost at USD 4.99 million. That figure is 12% higher than the prior year and a record high. The same report found that organizations using security AI and automation extensively saved USD 1.93 million per breach compared with those that used none.
How do you secure enterprise data used by AI tools and copilots?
Treat each AI tool as a new data consumer with its own access scope. Fix oversharing before rollout, because copilots can read whatever their users can open. Label sensitive content so AI tools respect it, and limit what they can index. Then log prompts against sensitive data and test assistants for prompt injection before wide release.
How long does it take to build an enterprise data security program?
A focused first phase on one high-risk domain can show results in about 90 days. That covers discovery, access cleanup, masking, monitoring and a tested restore. Extending the same method across a large estate usually takes several quarters, depending on the number of data stores, the regulations in scope and how clear data ownership already is.
Which regulations and frameworks apply to enterprise data security?
It depends on your data and markets. GDPR covers personal data of people in the EU, and US state privacy laws cover residents of those states. HIPAA covers health data and PCI DSS covers card data. Public companies follow SEC disclosure rules. NIST CSF 2.0, ISO 27001 and SOC 2 then structure and prove the controls.
What metrics should a CISO report to the board on data security?
Five metrics cover most of what a board needs. Report the share of sensitive data classified and the number of over-permissioned accounts, human and non-human. Add mean time to detect and contain incidents, the restore-test pass rate and policy exceptions open past due. Report the same five every quarter so the trends stay comparable.
What is the difference between data security and cybersecurity?
Cybersecurity defends systems, networks and devices from attack. Data security protects the data itself wherever it goes, including exports, SaaS apps, test copies and AI prompts. A company can have strong network defenses and still leak data through an overshared file or an unmasked test database. Mature programs run the two together under one owner model.
Is encryption enough to protect enterprise data?
No. Encryption makes stolen copies unreadable, but only if keys are managed separately, rotated and restricted. It does nothing to stop an authorized user, a compromised account or a copilot from reading decrypted data. Enterprises pair encryption with least-privilege access, masking of non-production data, monitoring and tested backups to cover the gaps it leaves open.
What is the difference between data protection and data security?
Data security keeps data safe from unauthorized access, change or loss through controls such as encryption, access rules and monitoring. Data protection is the broader goal. It adds backup, recovery and privacy, meaning what you may lawfully do with personal data and how long you keep it. Security is one part of protection, and both need named owners.
Why do enterprises need data security?
A breach now costs an average of USD 4.99 million, according to IBM’s 2026 report. Beyond that cost, weak data security brings regulatory fines, lost customers and halted operations during ransomware recovery. Strong controls also make audits faster and let teams share data with analytics and AI tools safely. Security is what makes wider data use possible.
What are 5 ways to secure data?
Five practical ways are to discover and classify sensitive data, restrict access by least privilege with multi-factor authentication, encrypt data at rest and in transit, monitor use with data loss prevention, and keep tested backups. Each measure should have a named owner. Each one should also produce evidence, such as a review record or a restore test result.
What are the pillars of data security?
The pillars are often described as five layers. Teams discover and classify data, control who can access it and protect the data itself with encryption and masking. They then monitor how the data is used and recover it when something fails. Some frameworks use four or five elements instead, but they cover the same ground in different groupings.
What are the 3 principles of data security?
The three principles form the CIA triad of confidentiality, integrity and availability. Confidentiality keeps data away from people who should not see it. Integrity keeps data accurate and stops unauthorized changes. Availability means authorized users can reach the data when they need it, including after an outage or attack. Every control should support at least one principle.
What are the 3 types of data security?
A common grouping is physical, technical and administrative security. Physical security protects data centers and devices. Technical security covers encryption, access controls, monitoring and backups. Administrative security covers the policies, training, ownership and audits that make the technical controls work. Regulations such as the HIPAA Security Rule use this same three-way split for their safeguards.
Who is responsible for data security?
Responsibility is shared, but it must be specific. The CISO usually owns the security program and its controls. Business data owners decide who may use each sensitive domain and why. IT and engineering teams run the controls day to day. Every employee handles data safely. Cloud providers secure their infrastructure, while you secure your data on it.
Which is the most secure way to protect data?
No single method is enough, so the most secure approach layers several defenses. Encryption makes intercepted data unreadable, but it needs zero trust network access, multi-factor authentication, network segmentation and continuous monitoring around it. Keys should sit in hardware security modules or a managed key service. Regular penetration tests then confirm that the layers hold if one of them fails.