TL;DR
Data transformation reshapes raw source data into trusted, analysis-ready data, and for most batch analytics the right choice is ELT inside your warehouse. Pick streaming only when a decision needs data that is minutes old, and pick low-code tools when analysts own the business rules. The work covers four types of change: constructive, destructive, structural and formatting. It then runs in six steps, from profiling sources to monitoring the pipeline in production. Each rule needs a named business owner and an automated test, because untested rules are what make two dashboards disagree. For AI workloads, the same discipline also covers feature pipelines, text cleanup and governed training data.
Key Takeaways
- Data transformation changes the format, structure, values or grain of data so that a report, application or model can use it.
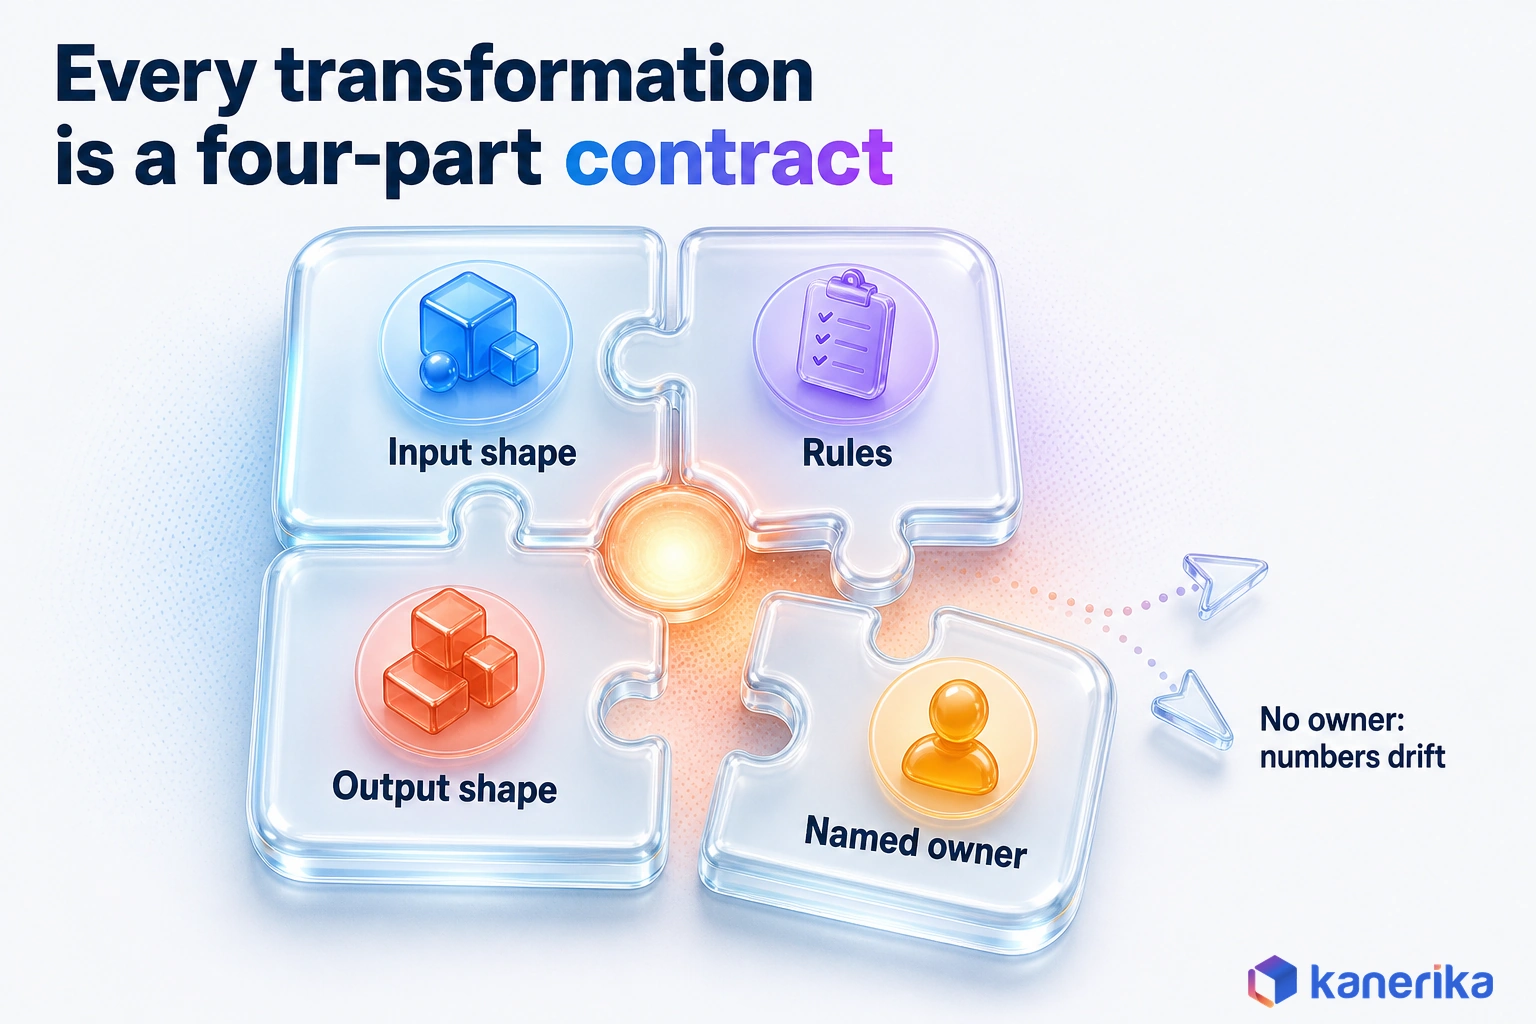
- Treat every transformation as a contract with four parts: input shape, rules, output shape and a named owner.
- Rules that change meaning, such as currency conversion, need business sign-off before anyone writes code.
- ELT inside the warehouse suits most batch analytics, while streaming earns its cost only for minute-level decisions.
- Row counts, sum checks, uniqueness and freshness tests should run on every build, not once at launch.
- AI workloads add features, text chunking and embeddings, so they also raise the bar for training-data lineage.
Two Dashboards, One Revenue Number, Two Answers
Picture the Monday business review. Finance shows one figure for net revenue, while the sales dashboard shows a noticeably higher one. The meeting then stalls on which number is right.
Both teams pulled from the same invoice table. Finance converted every currency to dollars and netted out credit notes. Sales summed the raw amounts and counted each invoice on the local date it was raised, so late-evening deals landed on the wrong day.
Nobody made an arithmetic mistake. The two teams ran different transformations on the same data, and neither had written its rules down.
This guide closes that gap: what data transformation is, its four types and six steps, the invoice example worked end to end, and a framework for choosing where your transformations should run.
What Is Data Transformation?
Data transformation is the process of changing data from the shape a source system produces into the shape a report, application or model needs. It can change formats, structures, values or the level of detail.
A useful way to think about it is as a contract between a source and a target. The contract has four parts: the input shape, the rules applied, the output shape and the person who owns those rules. When any of the four is missing, the output drifts over time.
Take a customer table from a CRM as an example. Its input has free-text country names, duplicate records and phone numbers in several formats. Rules then standardize country codes, merge duplicates and format phone numbers one way. As a result, the output is one clean row per customer, and the sales operations lead owns the merge rule.
Transformation is also the T in ETL and ELT. It sits between extraction from sources and loading into the place where people and systems read the data.
Data Transformation vs Data Cleansing, Integration and Migration
The four terms overlap, so teams often use them loosely. The real difference lies in what changes and what you get at the end.
| Term | What changes | Output | Example |
|---|---|---|---|
| Data transformation | Format, structure, values or grain | Data shaped for a specific use | Invoice lines rolled up to daily net revenue in USD |
| Data cleansing | Errors, gaps and duplicates | Correct, complete records | Fixing invalid postcodes before merging duplicate customers |
| Data integration | How sources combine | A unified view across systems | Joining CRM, ERP and support data on one customer key |
| Data migration | The system that holds the data | The same data on a new platform | Moving an on-premises warehouse to a cloud lakehouse |
Cleansing is usually one step inside a transformation, and integration usually depends on both. Migration often includes transformation too, since a new platform rarely accepts the old structure as is. Kanerika’s guide to data integration also covers the combining step in more depth.
Kanerika Service
Data Integration Services
Kanerika connects ERP, CRM, cloud and file sources and builds governed transformation pipelines with one shared layer of business rules.
Explore Data IntegrationWhy Data Transformation Matters for Analytics and AI in 2026
Every number a business acts on has passed through some transformation, whether anyone designed it or not. The real question is whether those rules are explicit, tested and shared.
Three things depend on that answer. The first is trust, because when two teams apply the same rule, their reports agree. Speed comes next, since well-modeled data lets an analyst answer a new question without rebuilding the logic. Spend is the last one: a job that reprocesses full tables every hour burns more compute than an incremental one.
AI raises the stakes further. A dashboard with a wrong number at least gets questioned in a meeting. A model trained on that number, however, repeats the error in every prediction, and an assistant built on it states the error with confidence.
Where Transformed Data Gets Used
Each use below needs something slightly different from the pipeline, as the table shows.
| Use case | What transformation provides | Example |
|---|---|---|
| Business intelligence | Consistent metrics and dimensions | One definition of net revenue for finance and sales |
| Data warehousing | Modeled, query-ready tables | A star schema with order facts and customer dimensions |
| Machine learning | Clean, stable features | Customer tenure computed the same way in training and scoring |
| Regulatory reporting | Traceable, repeatable figures | Tax reports that reconcile back to source ledgers |
| Operational systems | Data in the format each system expects | Partner orders translated into an internal message schema |
The BI row is generally where readers feel the pain first. Charts are only as good as the tables behind them, a point Kanerika’s guide to data visualization makes from the reporting side.
Dirty data is usually the first thing a transformation program has to confront. Duplicates, inconsistent codes and missing values are cheap to fix at the source but expensive to fix in a board report.
Types of Data Transformation
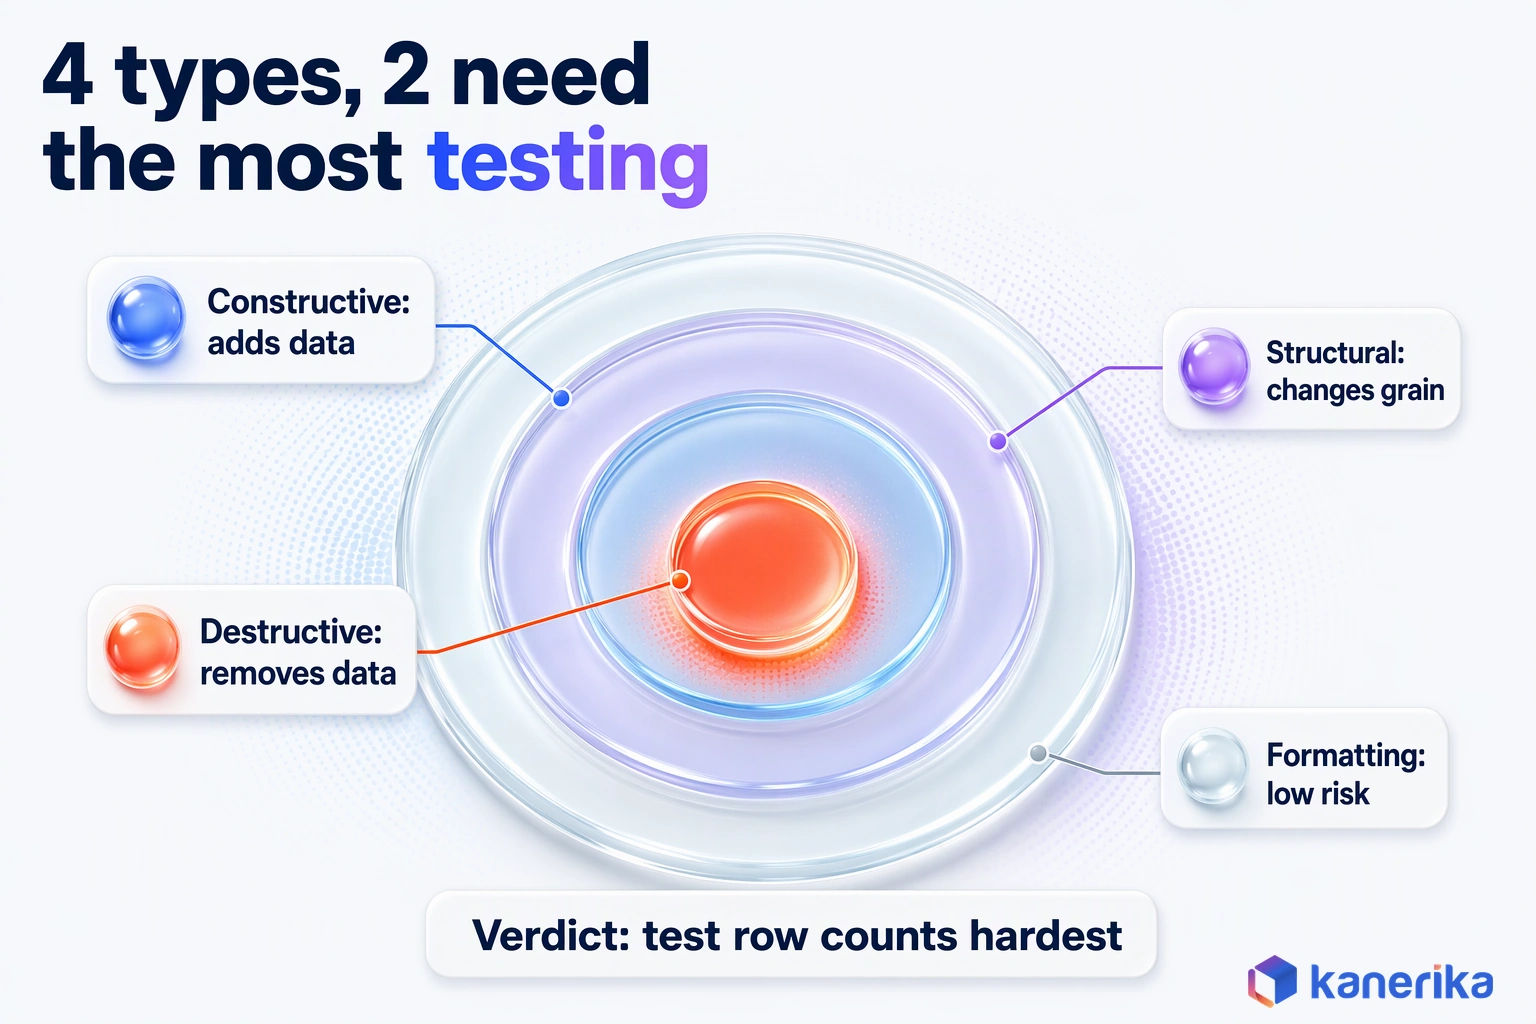
Transformations fall into four broad types, based on what they do to the data. Naming the type helps you predict the risk, because some types add information while others remove it.
Constructive changes add something, such as a derived column. Destructive changes instead remove records or attributes you do not need. Structural changes reshape the data, while formatting changes alter how values look without changing what they mean.
| Type | What it does | Example | Main risk |
|---|---|---|---|
| Constructive | Adds or derives data | Computing order margin from price and cost | A wrong formula spreads quietly because nothing fails |
| Destructive | Removes rows or columns | Dropping test accounts and unused fields | Deleting data that a later use case needs |
| Structural | Changes shape or grain | Pivoting monthly columns into rows, or joining tables | Totals double or vanish when keys are not unique |
| Formatting | Changes appearance, not meaning | Dates to ISO 8601, names to title case | Low, unless it hides a value change |
Destructive and structural changes deserve the most testing, because they change row counts. A join on a key that is not unique can multiply rows, while a filter written too broadly can remove a whole region from revenue.
Common Data Transformation Techniques
Techniques are the specific operations inside those types. Most pipelines combine several of them in a single model, so it helps to know what each one can break.
| Technique | What it does, with an example | Watch for |
|---|---|---|
| Normalization | Scales numbers to a common range, such as income from 0 to 1 | Outliers squeeze the range unless you cap them |
| Standardization | Converts values to one convention, such as ISO country codes | Unmapped values that fall into “other” |
| Aggregation | Summarizes detail to a higher grain, such as daily revenue | Losing detail that auditors need later |
| Discretization | Turns continuous values into bands, such as age groups | Band edges that shift results |
| Generalization | Replaces detail with a broader category, such as city to region | Hiding patterns at the lower level |
| Smoothing | Reduces noise, for example with a seven-day moving average | Masking real spikes |
| Attribute construction | Builds new fields, such as customer tenure in months | Formula drift when teams compute it separately |
| Deduplication | Removes repeated records, so each invoice line appears once | Merging records that are distinct |
| Joining | Combines tables on a key, such as orders to customers | Duplicate keys multiplying rows |
| Pivoting | Turns rows into columns or back, such as one column per month | Breaking schemas that reports depend on |
Attribute construction is called feature engineering when the output feeds a model. Kanerika’s glossary entry on feature engineering covers that use in more detail. Kanerika also has a separate guide to data standardization.
Transformations That Change Meaning Need Business Sign-Off
Some rules are purely technical, like trimming spaces. Others encode a business decision, so those need an owner outside the data team.
Currency conversion, for example, is one such rule. Should a euro invoice use the rate on the invoice date, the payment date or the month-end close? Each answer is defensible, yet each one gives a different revenue figure.
Revenue recognition and customer merge rules work in the same way. When two records share an email but not a name, someone in the business must decide whether they are one customer.
Write these rules in plain English first, get them approved and only then code them. The approval record then becomes part of the contract.
How Data Transformation Works: Six Steps
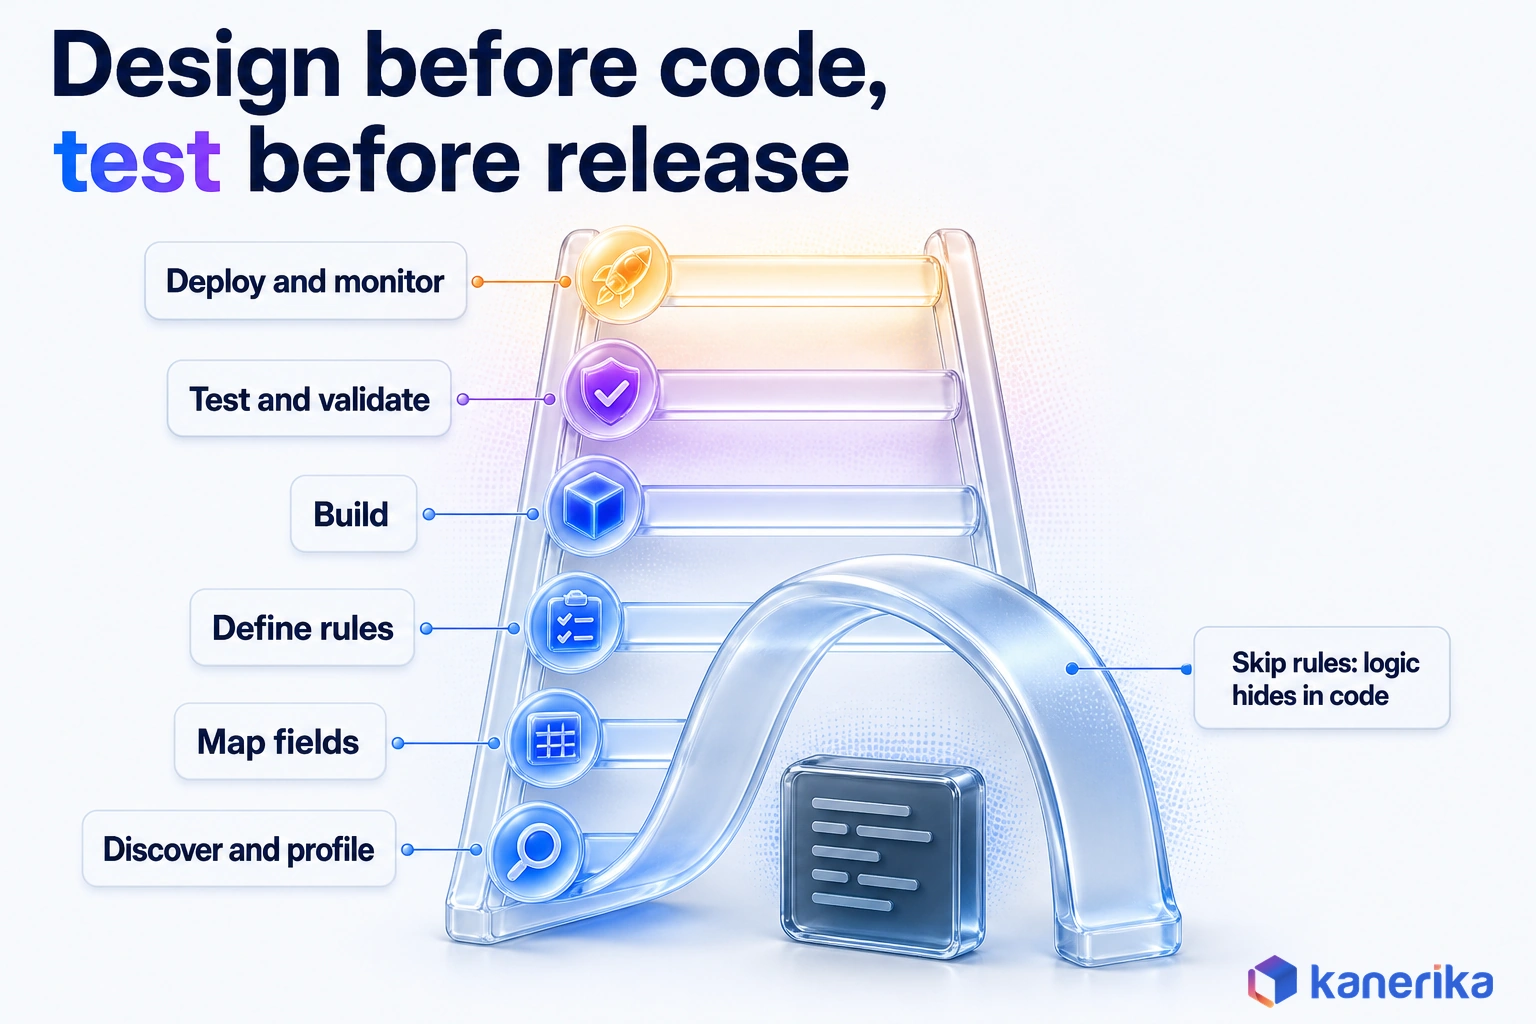
A reliable transformation follows the same six steps, whether it runs in a warehouse, a lakehouse or a streaming engine. This order keeps design ahead of code, and it also keeps testing ahead of release.
- Discover and profile. Inspect each source for row counts, null rates, value ranges and duplicate keys. Data profiling shows the real shape of the data before you write a rule.
- Map. Match each source field to a target field, then note any gaps or conflicts.
- Define rules. Write each business rule in plain language with an owner, and agree on the edge cases.
- Build. Code the rules as versioned models or pipelines, so each step is small enough to test alone.
- Test and validate. Reconcile outputs against sources, and run automated checks on every build.
- Deploy and monitor. Schedule or trigger the pipeline, then watch freshness, volumes and test results in production.
The tempting shortcut is to jump from step 1 straight to step 4. It feels faster, but the rules then live only in code, so nobody outside the data team can review them. Steps 2 and 3 are where a reviewer catches the euro rate question before it reaches a board report.
Worked Example: Invoice Lines to Daily Net Revenue
Return once more to the two dashboards from the opening. Here is a small extract of the invoice table both teams used, with four raw rows.
| Row | Document | Amount | Currency | Created (New York time) |
|---|---|---|---|---|
| 1 | INV-1001 | 1,000.00 | EUR | Mar 31, 2026, 9:00 PM |
| 2 (same line loaded twice) | INV-1001 | 1,000.00 | EUR | Mar 31, 2026, 9:00 PM |
| 3 | INV-1002 | 500.00 | USD | Apr 1, 2026, 10:00 AM |
| 4 (credit note on INV-1002) | CN-0042 | -200.00 | USD | Apr 1, 2026, 3:00 PM |
The agreed rules are short. Remove duplicate lines, convert to US dollars at the rate for each line’s UTC date, keep credit notes as negative amounts and assign each line to that UTC date. For this example, assume the April 1 rate is 1.10 dollars per euro.
| Rule applied | Effect on the rows |
|---|---|
| Deduplicate | Row 2 is removed because it repeats row 1 |
| Convert currency | Row 1 becomes 1,100.00 USD (1,000 x 1.10) |
| Net credit notes | Row 4 stays at -200.00 USD, so it reduces the total |
| Assign UTC date | Row 1 moves to Apr 1, since 9:00 PM EDT is 1:00 AM UTC |
| Output row | Apr 1, 2026 net revenue: 1,400.00 USD |
The sales dashboard summed the raw amount column and got 2,300. That figure mixes euros with dollars, counts one line twice and also puts row 1 in March. Finance, by contrast, applied the rules and got 1,400.00 USD for April 1.
Same data, two sets of rules, two answers.
Writing the Rules as Code
In a SQL-based tool, the agreed rules fit in one model, so both teams can share a single definition. The sketch below uses dbt-style references, and the table and column names are illustrative.
-- daily_net_revenue.sql
with lines as (
  select distinct invoice_id, line_no, amount, currency, created_at_utc
  from {{ ref('stg_invoice_lines') }}       -- credit notes arrive as negative amounts
),
usd as (
  select l.*, l.amount * fx.usd_rate as amount_usd
  from lines l
  join {{ ref('fx_daily') }} fx
    on fx.currency = l.currency
   and fx.rate_date = cast(l.created_at_utc as date)
)
select cast(created_at_utc as date) as revenue_date_utc,
       sum(amount_usd)              as net_revenue_usd
from usd
group by 1
Each rule is then visible, versioned and open to review. When finance changes its rate policy, the change shows up as a code diff with an approver attached.
Tests That Prove a Transformation Is Correct
A transformation is only correct when you can show it. The checks below catch most errors before anyone opens a report.
- Row-count reconciliation: rows in versus rows out, so every difference is explained by a rule.
- Sum checks: output totals match source totals after known adjustments.
- Uniqueness: the key of each output table appears only once.
- Not-null: required fields are never empty.
- Accepted values: codes such as currency or status come from an approved list.
- Referential integrity: every foreign key matches a row in its parent table.
- Freshness: the newest record is no older than the agreed lag.
Run these on every build rather than once at launch. A failed test should also stop the pipeline, so bad data never reaches a dashboard.
Checklist
Data Engineering Checklist
Plan sources, transformation rules, testing and ownership before the build starts with Kanerika’s data engineering checklist.
Get the Checklist →ETL vs ELT vs Streaming: Where Data Transformation Runs
Where a transformation runs shapes its cost, its speed and who can maintain it. There are three main patterns, as well as a virtual option for light work.
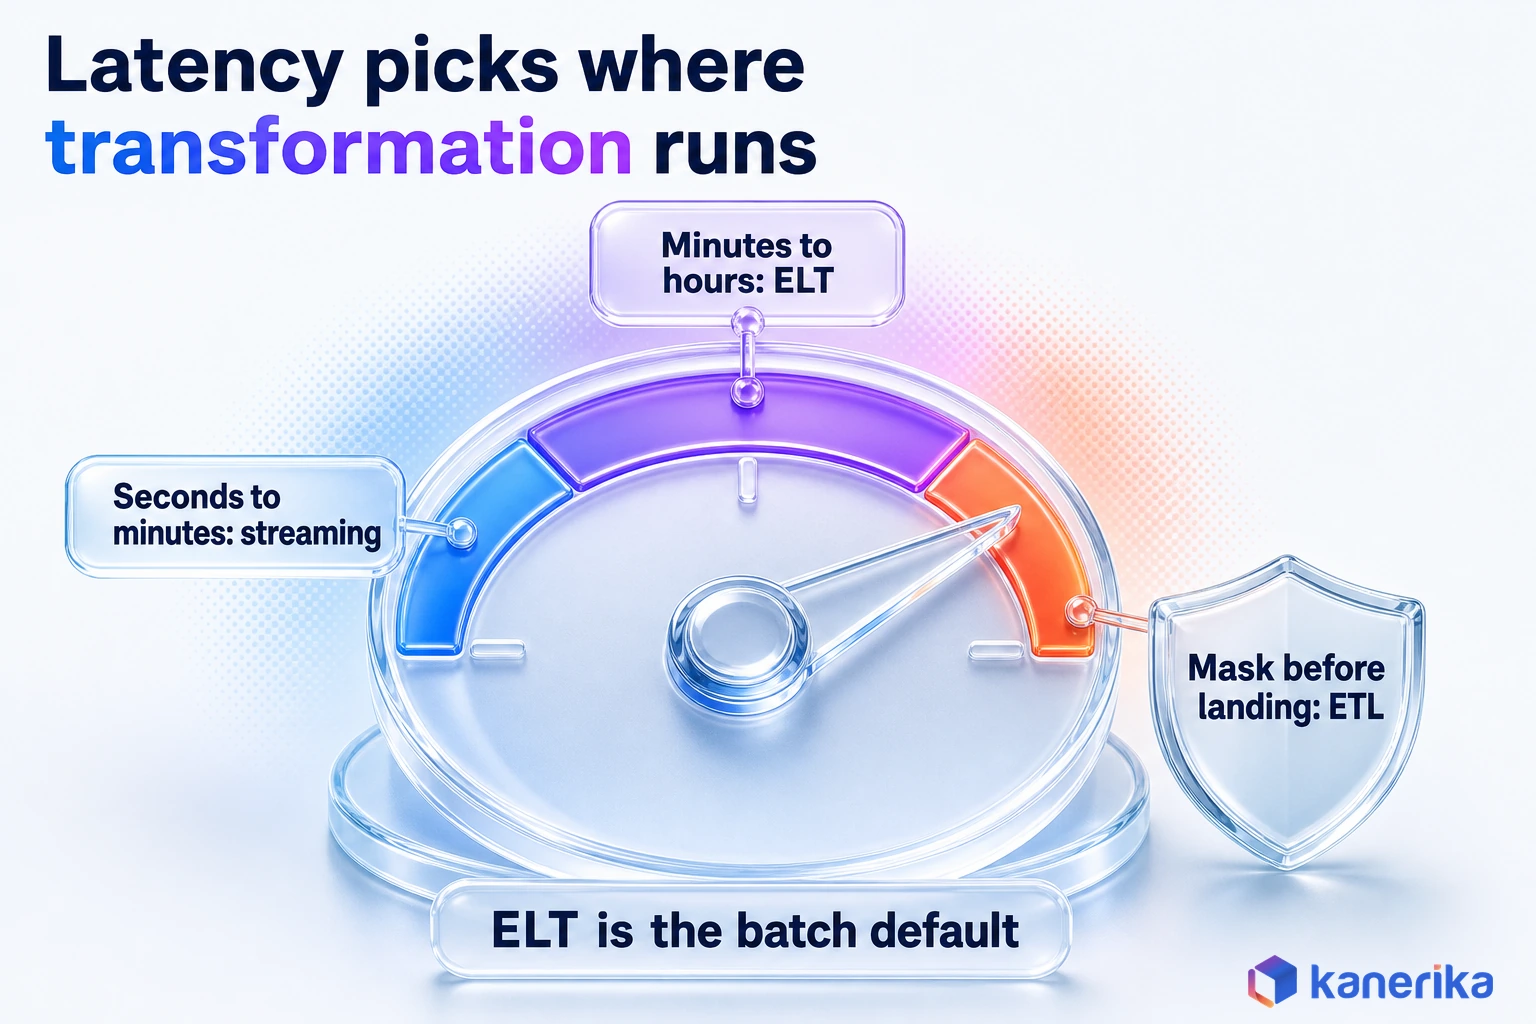
ETL transforms data on a separate engine before loading it into the target. ELT loads raw data first and then transforms it inside the warehouse or lakehouse with SQL or Spark. Streaming, by comparison, transforms events continuously as they arrive. All three depend on reliable data ingestion upstream.
| Pattern | Where transformation runs | Typical latency | Best fit | Watch-outs |
|---|---|---|---|---|
| ETL | A separate engine, before loading | Hours, on a schedule | Strict schemas, or masking before data lands | Logic hidden in the engine, so changes are slower |
| ELT | Inside the warehouse or lakehouse | Minutes to hours | Most cloud analytics, especially for SQL-skilled teams | Raw data lands first, so access control matters |
| Streaming | A stream processor, as events arrive | Seconds to minutes | Fraud checks, IoT telemetry and live operations | Late events and a higher running cost |
For most batch analytics, ELT is the sensible default, because the platform already scales and the team already writes SQL. Streaming earns its cost only when a decision changes with data that is minutes old. Kanerika’s full comparison of ETL vs ELT goes deeper on the trade-offs.
A fourth option skips the copy entirely. A virtual layer can apply light transformations at query time, as the guide to data fabric vs data virtualization explains. It suits light reshaping rather than heavy joins over large history.
Data Transformation Tools by Platform
Tool choice generally follows platform choice. Most enterprises pick the transformation layer that fits the warehouse or lakehouse they already run.
Each option below takes a different approach. Some ask you to write SQL, while others let you declare the end state you want or offer a visual editor.
| Tool | How it transforms | Fits when |
|---|---|---|
| dbt | You write SQL select statements, and dbt adds version control, modularity, CI/CD and documentation | Your team is SQL-first and wants a software workflow on a cloud warehouse |
| Spark Declarative Pipelines on Lakeflow (Databricks) | A declarative framework for building batch and streaming pipelines | You run Databricks and want batch and streaming in one framework |
| Snowflake Dynamic Tables | Materializes a SELECT query and keeps it current against a target lag you set | You run Snowflake and want the platform to manage refresh |
| Microsoft Fabric Dataflow Gen2 | Power Query transformations with multiple output destinations, used with pipelines | Analysts and engineers share the work in Microsoft Fabric |
| Kanerika FLIP | Low-code configuration that translates data and messages into target formats | Rules change often, or when each partner needs its own format |
The descriptions come from each vendor’s documentation. Snowflake, for instance, says a dynamic table “materializes the results of a SELECT query and keeps them up to date.” Similarly, the dbt docs say dbt “transforms raw warehouse data into trusted data products.” Kanerika has deeper guides on dbt and Snowflake Dynamic Tables if either is on your shortlist.
Whatever you pick, keep business logic in one layer. Rules split between a pipeline tool and a BI tool are the most common cause of the two-dashboard problem.
Kanerika Service
Data Engineering Services
Kanerika designs, builds and runs transformation pipelines on Microsoft Fabric, Databricks and Snowflake, with tests, lineage and monitoring built in from the first release.
Explore Data EngineeringTransforming Data for AI Workloads
AI workloads use the same transformation discipline, but with new kinds of input and a higher bar for traceability.
A classic machine learning model needs features, which are fields computed the same way in training and in production. A retrieval system for a large language model, on the other hand, needs text that has been cleaned, split into chunks and converted into embeddings. Each of these steps is a transformation with rules, tests and an owner.
- Feature pipelines: compute features once and reuse them for training and scoring, so the model sees the same logic in both.
- Unstructured text cleanup: strip boilerplate, headers and duplicate pages before indexing documents.
- Chunking and embeddings: split documents at sensible boundaries, then store each embedding with a link back to its source.
- Label and training-set lineage: record which data version and which rules produced each training set.
Regulation points the same way. Article 10 of the EU AI Act (Regulation 2024/1689) covers data and data governance for high-risk AI systems. When such systems are trained on data, their training, validation and testing sets must meet quality criteria. Versioned, tested transformations are therefore a practical way to show that.
AI analytics tools rest on the same groundwork. An assistant that answers questions over company data, the idea behind agentic BI, can only be as accurate as the transformed tables it reads.
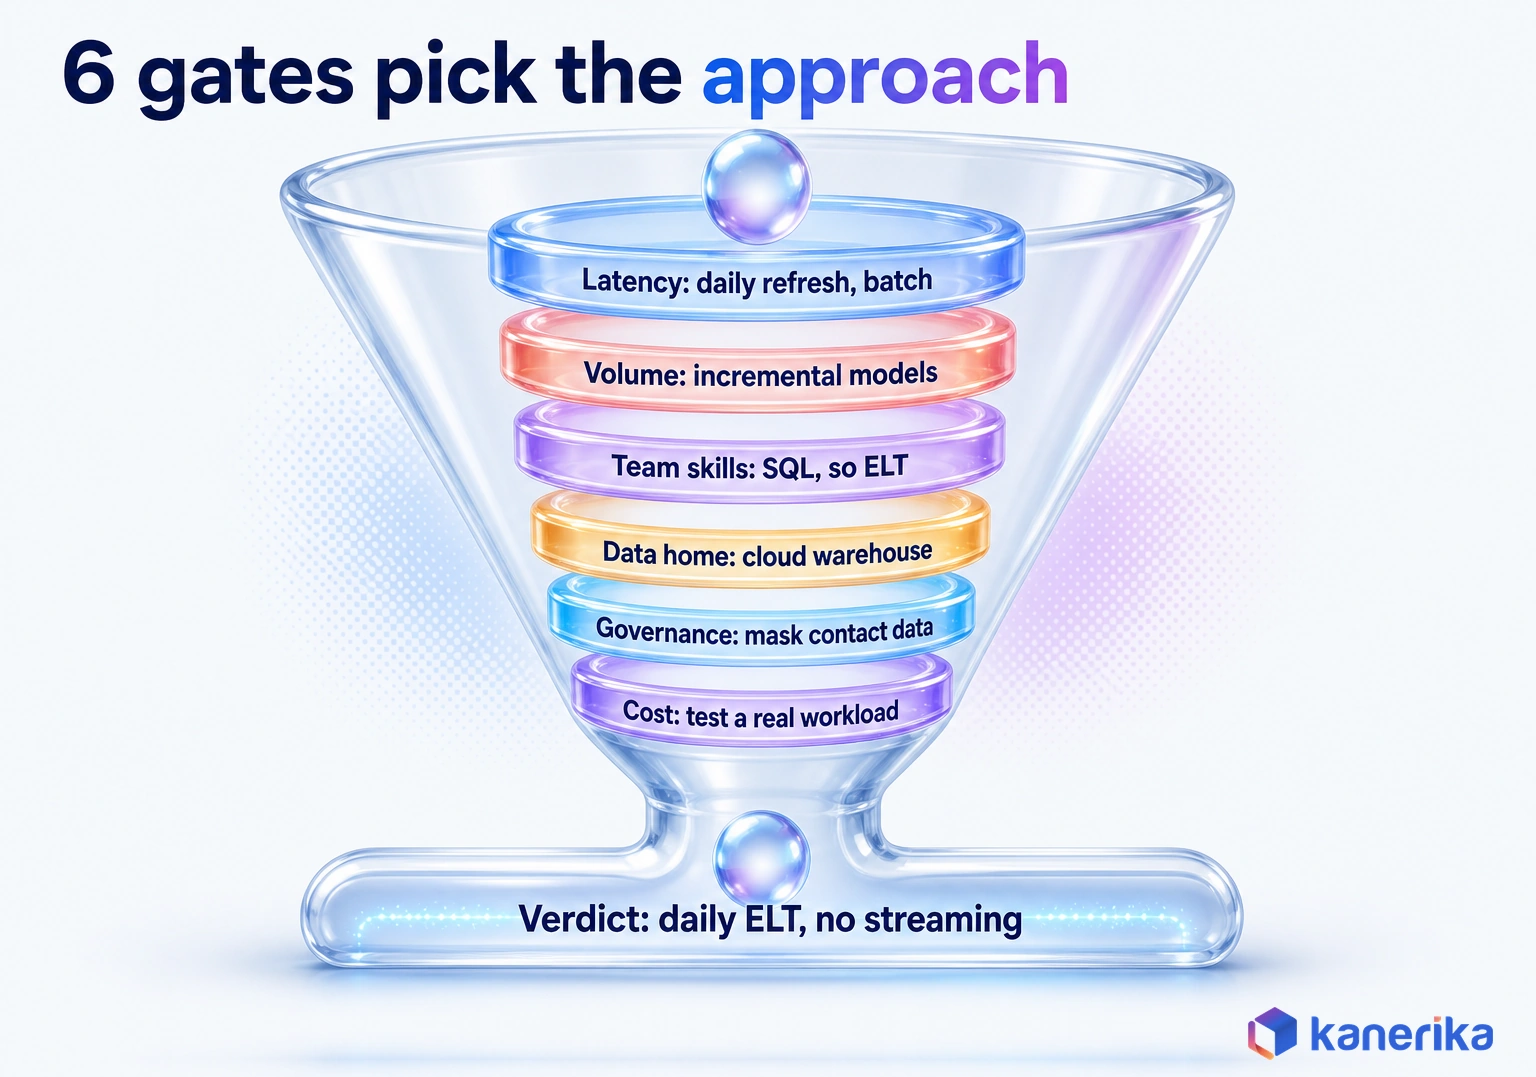
Decision Framework: How to Choose a Data Transformation Approach
Choosing an approach is easier when you work through the same six gates in order. Each gate narrows the options before you reach the next one.
- Latency: if decisions change with data that is minutes old, consider streaming. Otherwise, start with batch.
- Volume and change rate: large tables that change a little each day call for incremental processing rather than full reloads.
- Team skills: SQL-first teams fit dbt or warehouse-native tools, while Spark teams fit lakehouse pipelines and analyst-led teams fit low-code dataflows.
- Where data already lives: transform on the platform that holds the data, so you avoid extra copies and egress.
- Governance and PII: if raw personal data may not land in the analytics platform, mask or pseudonymize it before loading.
- Cost model: compare compute billed per query, per cluster or per capacity, then test with your real workload.
In practice, most organizations end up with a mix. ELT handles the bulk of reporting, a small streaming path serves the few real-time cases, and masking happens before data lands. The graphic below runs all six gates for the revenue-forecast example worked through in the next section.
Worked Decision: CRM and ERP Data for a Revenue Forecast
Consider a forecasting team that needs CRM pipeline data and ERP bookings in one model. Since the forecast refreshes daily, gate 1 points to batch. Both sources already land in a cloud warehouse and the team writes SQL, so gates 3 and 4 point to ELT with a SQL framework.
Gate 5 then adds one twist. The CRM holds contact emails and phone numbers that the forecast does not need, so those fields are dropped or pseudonymized in the staging step.
What comes out is a daily ELT pipeline with incremental models and a masking step at the edge. Streaming is ruled out, because nothing in a daily forecast changes with minute-old data. For gate 6, the team then prices the design by running a real day of CRM and ERP loads before it commits.
Cost and Effort: What Sizes a Data Transformation Program
The size of a transformation program depends less on the tool than on the data and the rules. A handful of drivers explain most of the effort.
| Driver | Why it adds effort | How to keep it in check |
|---|---|---|
| Number of sources | Each source has its own quirks, keys and refresh pattern | Onboard sources in priority order rather than all at once |
| Rule count and complexity | Every rule needs a definition, an owner and a test | Write rules once in a shared layer, then reuse them |
| Data volume | Large tables raise compute and test time | Process increments instead of full tables |
| Latency target | Lower latency means more infrastructure and on-call work | Set the slowest latency the business can accept |
| Test coverage | Tests take time to write but save rework later | Start with keys, sums and freshness on every model |
| Compute model | Pricing differs by query, cluster or capacity | Model cost on a real pilot workload before you scale |
| Team skills | Unfamiliar tools slow delivery | Match the tool to the skills you have |
Three performance levers cut both cost and run time. Incremental processing updates only new or changed rows. Partition pruning lets the engine skip files that cannot match a filter, such as dates outside the reporting window.
The third lever is discipline about full refreshes, since each one reprocesses everything. Run them only when a rule changes, and daily runs stay short.
Avoid estimating a whole program from a vendor sheet. Instead, build one representative pipeline end to end and measure its effort and run cost, then scale the estimate by source and rule count.
Talk to Kanerika
Sizing a Data Transformation Program?
Bring one metric your teams argue about. Kanerika will map its sources and rules, then scope a pilot pipeline with tests and a run-cost estimate.
Schedule a Demo →Governance, Risks and Common Mistakes
Governance is what keeps transformations trustworthy after the first release. Without it, rules drift, people leave and soon nobody can explain a number.
Lineage comes first. It records which sources and rules produced each output, so an analyst can trace a figure back to the source rows. Kanerika’s guide to data lineage covers the tooling, while the wider data governance guide covers ownership.
Sensitive data needs its own treatment. GDPR Article 4(5) defines pseudonymisation as processing personal data in a specific way. Afterward, the data “can no longer be attributed to a specific data subject without the use of additional information,” which is kept separately. Masking and pseudonymization therefore belong early in the pipeline, before data spreads to many tables. Kanerika’s guide to data anonymization techniques compares the main methods.
The common mistakes are predictable, so they are easy to test for.
- Schema drift: a source adds, renames or retypes a column, and then the pipeline breaks or silently drops data.
- Silent type casts: text-to-number conversions turn bad values into nulls or zeros without an error.
- Undocumented business rules: logic lives only in one engineer’s code or memory.
- Transforming in BI tools: each report rebuilds its own logic, so the same metric differs by dashboard.
- No data contracts: source teams change fields without warning, because nothing defines what downstream users rely on.
A data contract fixes the last problem. It is a written agreement on schema, meaning and freshness between a source team and its consumers, checked automatically on every load. When you pair it with the checks in Kanerika’s data quality guide, most drift is caught at the door.
Data Transformation Best Practices
Each of the five practices below prevents a failure described earlier in this guide.
- Agree on the business rule before writing code. A rule written in plain English and approved by its owner avoids the euro-rate argument later.
- Treat transformation logic as versioned software. Keep it in source control, review every change and release through CI/CD.
- Automate validation. Run reconciliation, uniqueness and freshness checks on every build, and stop the pipeline when one fails.
- Test the edge cases on purpose. Cover late-arriving records, time zones, negative amounts, nulls and duplicate keys.
- Build observability in from day one. Track run times, row volumes and test results, then alert the owner when they move. Kanerika’s guide to data observability explains what to watch.
Automation then ties these practices together. Scheduling, retries and alerting are covered in Kanerika’s guide to data pipeline automation, and they matter more as the number of pipelines grows. Pipeline design itself is covered in the guide to data pipeline architecture.
Choosing who builds and runs this work is a decision of its own. The podcast below discusses how to pick the right data engineering partner.
How Kanerika Delivers Data Transformation
Kanerika builds transformation programs on Microsoft Fabric, Databricks and Snowflake, using the contract-first approach described above. The work runs in five stages.
- Discover and baseline: profile sources, list current rules and measure run times and error rates.
- Design the contract and approach: agree on rules, owners and tests, then choose the pattern with the six gates.
- Pilot one data product: build one pipeline end to end and prove that it reconciles to source.
- Productionize: add CI/CD, monitoring, lineage and access controls before onboarding the next sources.
- Measure: compare run time, error rate and effort against the baseline.
Kanerika’s certifications include ISO 27001, ISO 27701, ISO 9001, SOC 2 Type II and CMMI Level 3, as listed on its data engineering services page. For message and format translation, the team also uses its low-code FLIP platform, alongside its data integration services.
One engagement, for example, shows the approach at work. A connected-vehicle telemetry platform provider converted datalogger binary data into its own message format, but its end customers needed messages in their own structures. Custom transformation code was slow to change, and each change cost about $80. It was a textbook transformation problem, with one input format, many required outputs and rules that differed by customer.
Kanerika implemented FLIP to translate JSON, Excel and Kafka messages into each customer’s format through low-code configuration. The provider cut data integration time by 24% and improved operational efficiency by 27%. Resource utilization also rose by 20%, and customer satisfaction increased by 16%. The full case study describes the setup.
Case Study
24% Less Data Integration Time with Low-Code Message Transformation
A connected-vehicle telemetry platform provider used Kanerika FLIP to translate JSON, Excel and Kafka messages into customer formats, cutting integration time by 24% and lifting operational efficiency by 27%.
Read the Case Study →Choosing Your Next Step
The two dashboards from the opening did not need a new tool. Instead, they needed one written rule for currency, credit notes and dates, an owner who approved it and a nightly test.
Start small. Pick one metric that people argue about, write its transformation contract and build it with tests. Once that metric reconciles, the same pattern scales to the next source, the next team and the AI use cases that depend on clean data.
Use streaming only when a decision changes with minute-old data, and use low-code tools when analysts own the rules. Data transformation is the rulebook that turns raw data into trusted data. For most batch analytics, ELT on your current platform is the best place to start.
Frequently Asked Questions
What is data transformation?
Data transformation is the process of changing data from the shape a source system produces into the shape a report, application or model needs. It can change formats, structures, values or the level of detail. Each transformation works best as a contract that defines the input, the rules, the output and the person who owns those rules.
Why is data transformation important?
Data transformation decides whether the numbers people act on can be trusted. When teams share tested rules, their reports agree and analysts answer new questions faster. It also controls compute spend through incremental processing. For AI, it matters even more, because a model trained on badly transformed data repeats the same error in every prediction it makes.
When should you use batch versus streaming transformation?
Use batch when decisions run on hourly or daily data, which covers most reporting and forecasting. Use streaming when a decision changes with data that is seconds or minutes old, such as fraud checks, IoT telemetry or live operations. Streaming costs more to run and must handle late events, so reserve it for those cases.
How do you test data transformation rules?
Test every build automatically. Reconcile row counts between source and output, and check that totals match after known adjustments. Assert that keys are unique, required fields are not null and codes come from approved lists. Add referential integrity and freshness checks. Then write edge-case tests for time zones, negative amounts, late records and duplicate keys.
How do you handle schema changes in data transformation?
Agree on a data contract with each source team that defines schema, meaning and freshness, and check it automatically on every load. Fail loudly when a column is added, renamed or retyped, instead of letting the pipeline drop data silently. Keep transformation code in version control, so each schema fix is reviewed and released with tests.
How do you transform sensitive data safely?
Mask or pseudonymize sensitive fields as early as possible, ideally before data lands in the analytics platform. Under GDPR Article 4(5), pseudonymized data cannot be attributed to a person without additional information that is kept separately. Drop fields a use case does not need, restrict access to raw layers and record lineage for every sensitive output.
What are the common types of data transformation?
There are four broad types. Constructive transformations add or derive data, such as an order margin column. Destructive ones remove rows or fields you do not need. Structural transformations change shape or grain through joins, pivots and aggregation. Formatting changes alter how values look, such as dates in ISO 8601, without changing what the values mean.
How is data transformation different from data cleansing and data integration?
Data cleansing fixes errors, gaps and duplicates so records are correct. Data integration combines sources into one unified view, such as CRM and ERP data on a shared customer key. Data transformation is broader and reshapes data for a specific use. In practice, cleansing is usually one step inside a transformation, and integration depends on both of them.
How does data transformation improve data quality?
Transformation applies the same rules to every record, so duplicates are removed, codes are standardized and formats match. Quality improves further when each rule carries automated tests, such as row-count reconciliation, uniqueness, not-null and freshness checks. A failed test should stop the pipeline, which keeps bad records out of dashboards, models and reports that decision makers rely on.
What tools are commonly used for data transformation?
Common choices follow the platform you run. dbt suits SQL-first teams on a cloud warehouse. Databricks offers Spark Declarative Pipelines on Lakeflow for batch and streaming. Snowflake Dynamic Tables refresh query results against a target lag. Microsoft Fabric Dataflow Gen2 builds on Power Query. Low-code tools such as Kanerika FLIP suit frequently changing format rules.
What challenges are associated with data transformation?
The most common challenges are schema drift, silent type casts, undocumented business rules and logic rebuilt separately inside BI tools. Each one makes reports disagree or quietly drops data. Rules that change meaning, such as currency conversion, also cause conflict when nobody owns them. Data contracts, lineage, version control and automated tests address most of these problems.
How is data transformation used in business intelligence?
Business intelligence depends on modeled tables with consistent metrics and dimensions. Transformation turns raw transactions into facts and dimensions, applies shared definitions such as net revenue and keeps those definitions in one layer. When the logic lives in the pipeline instead of each report, every dashboard shows the same number for the same question across teams.
What is an example of data transformation?
Take raw invoice lines in several currencies. A transformation removes a duplicate line, converts euros to dollars at the rate for each line’s UTC date, keeps credit notes as negative amounts and assigns each line to that date. Four raw rows that naively sum to 2,300 in mixed currencies become one output row of 1,400 dollars for April 1.
What is the difference between ETL and ELT transformation?
In ETL, data is transformed on a separate engine before it is loaded into the target. In ELT, raw data is loaded first and transformed inside the warehouse or lakehouse with SQL or Spark. ELT suits most cloud analytics, while ETL fits cases where sensitive data must be masked before it lands anywhere.