TL;DR
The machine learning operations best practices for 2026 are versioning, data tests, release gates and clear model owners. MLOps is the set of habits and tools that keeps a model accurate after launch. Save every version of your code, data, model and settings, so any old model can be rebuilt. Check new data before the model sees it, and retrain through a tested pipeline. Watch data quality, prediction quality and system health as three separate signals. Small teams should automate one pipeline first, while regulated firms should add approval gates early.
Key Takeaways
- A 2024 Gartner survey found only 48% of AI projects reach production, so the hard part of machine learning starts after the prototype.
- Version code, data, model and environment together, and validate data before it reaches training or serving.
- Run CI, CD and continuous training as separate loops, each with its own trigger and release gate.
- Monitor data health, model quality and service health separately, because a green uptime dashboard says nothing about prediction quality.
- Measure MLOps with deployment frequency, lead time, time to restore and change fail percentage, plus a business KPI for each model.
- Give every production model a business metric, a business owner and a technical owner, then review it until it is retired.
Why Models That Work in Testing Fail in Production
A model that scores well in a notebook has passed one test, on one frozen dataset, on one day. Production asks it to keep passing that test every hour, on data that keeps changing, inside systems that other teams keep editing.
When a Fraud Model Goes Quiet
Picture a card issuer’s fraud model on an ordinary Tuesday. Then an upstream payments team renames a field in its transaction feed. The model’s pipeline does not crash. Instead, it fills the missing column with a default value and keeps scoring.
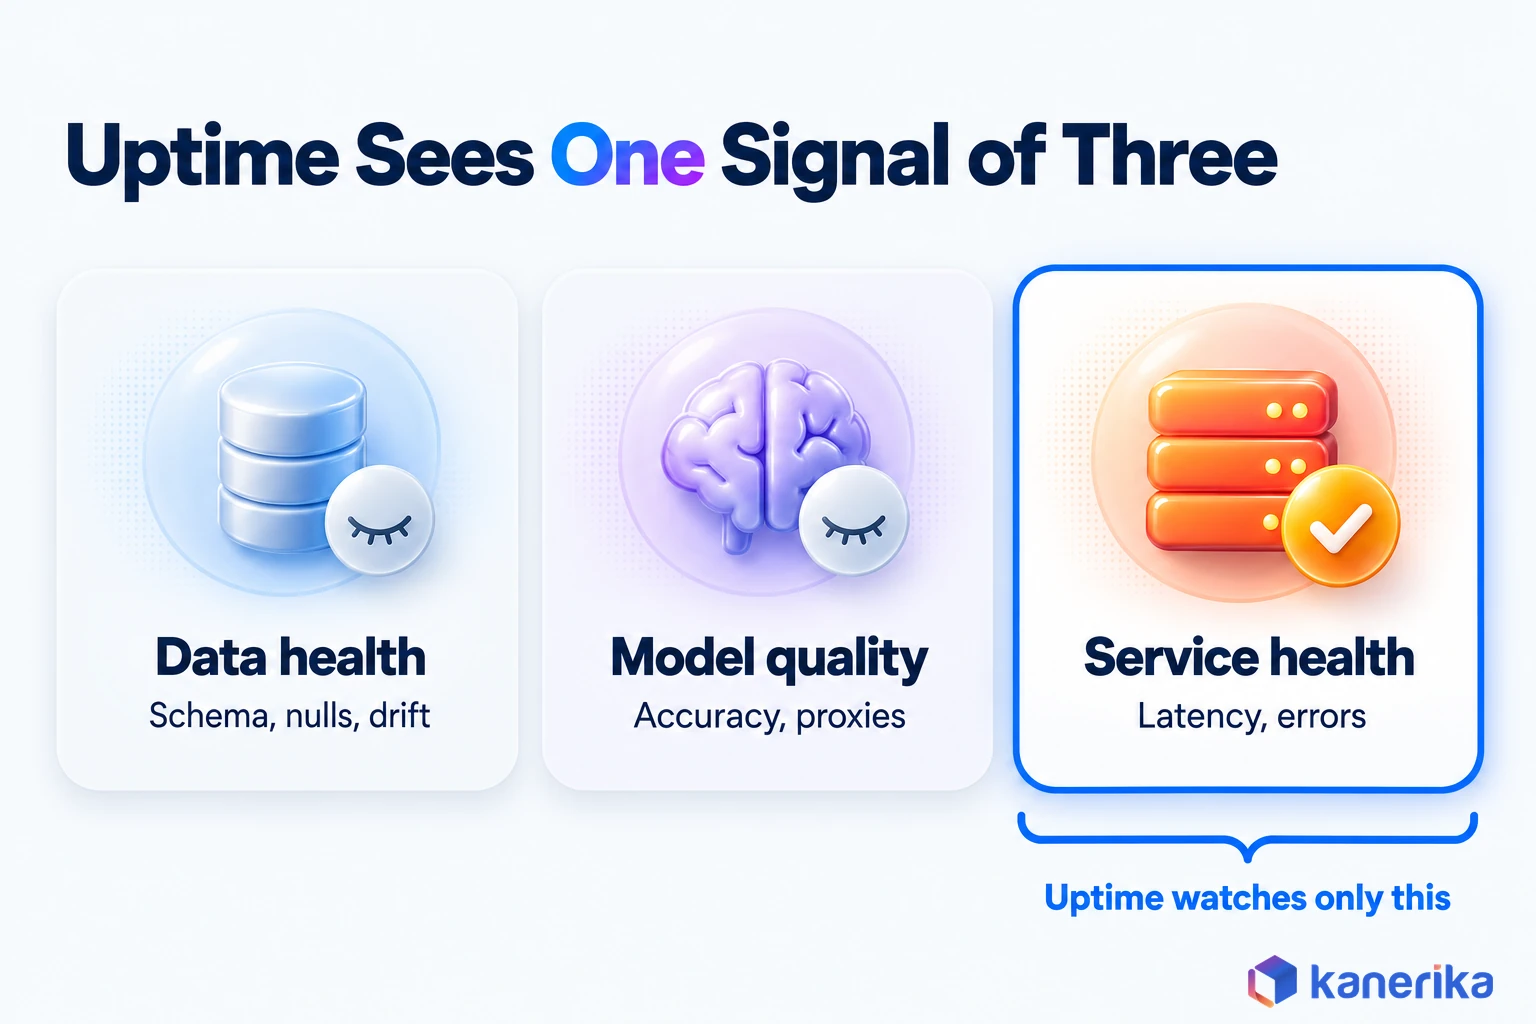
From that moment, almost every transaction gets the same middling risk score. Fraud alerts drop, and at first the drop looks like good news. The serving endpoint still answers every request in milliseconds, so the platform dashboard stays green for three weeks.
The problem surfaces only when chargebacks climb and an analyst asks why the alert queue went quiet. Nobody had a check on the incoming data before scoring. The model’s business result had no owner either, so nobody was watching it. This scenario is illustrative, but each missing control in it maps to a practice in this guide.
Survey data tells the same story. A 2024 Gartner survey found that, on average, only 48% of AI projects make it into production. The same survey put the trip from prototype to production at eight months.
Adoption keeps climbing while that gap stays open. The 2025 AI Index from Stanford HAI reports that 78% of organizations used AI in 2024, up from 55% the year before. More models in more teams means more of them stuck between pilot and production.
Reaching production is only the halfway mark, though. In a NeurIPS 2015 paper, Sculley and colleagues warned that it is common to incur massive ongoing maintenance costs in real-world ML systems. They traced that cost to hidden data dependencies, entangled features and feedback loops that nobody designed on purpose.
Machine learning operations exists to close both gaps. It gets a model into production on a repeatable path, and then it keeps the model honest once it is there.
What Is Machine Learning Operations (MLOps)?
Machine learning operations, or MLOps, is the set of people, processes and automation that moves models from experiment to production and keeps them accurate afterward. It borrows the habits of DevOps, such as version control, automated testing and repeatable releases, and then extends them to data and models.
That extension matters because a model is not ordinary software. A web service behaves the same way until someone changes its code. A model can change its behavior with no code change at all, since the world that produces its input data keeps moving. For readers newer to the terms, our guide to machine learning vs AI explains where ML sits inside the wider AI field.
So MLOps treats the model, the data and the pipeline as one system. A release is only safe when all three have been checked together.
What MLOps Covers Beyond Model Training
Training code gets most of the attention in a machine learning project. Yet a production system needs far more around it, and each surrounding piece can break a model on its own. MLOps puts every one of those pieces under version control and automated checks.
- Data: raw sources, labels, features and the schemas that describe them.
- Code: feature logic, training scripts, evaluation and serving code.
- Model: the trained artifact, its parameters and its evaluation results.
- Environment: library versions, container images and hardware settings.
- Pipeline: the automated steps that connect the other four and run them in order.
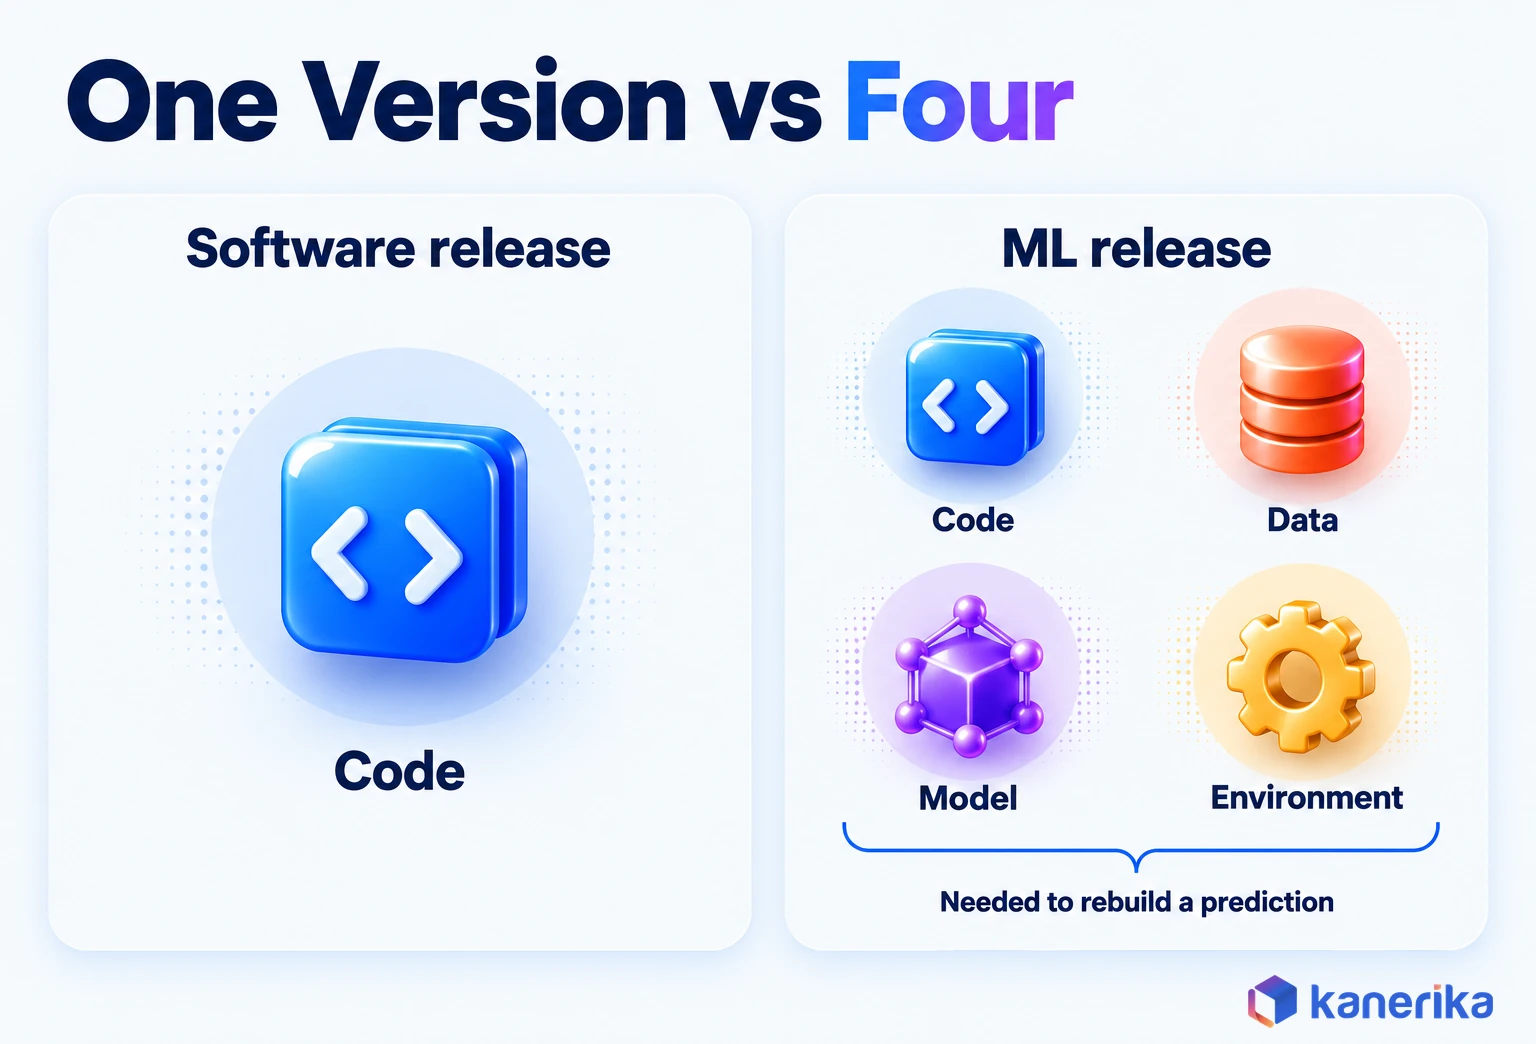
A change in any one of these can also change predictions. That is why a team that versions only its code cannot answer a simple question from an auditor or an unhappy stakeholder. Which data and which settings produced the prediction we made last March?
Compare that with a typical software release, where the commit hash alone tells you what is running. An ML release needs four identifiers before anyone can say the same thing with confidence.
MLOps vs DevOps vs LLMOps
The three disciplines share a toolkit but guard against different failures. DevOps protects software releases, while MLOps adds the risk that data drifts away from what the model learned. LLMOps then adds the risks of prompts, retrieval and per-call cost. The table compares them on the five questions that shape daily work.
| Question | DevOps | MLOps | LLMOps |
|---|---|---|---|
| What is versioned? | Application code and infrastructure configuration | Code as well as data, model and environment | Everything in MLOps, as well as prompts, base-model versions and retrieval indexes |
| What is tested? | Code behavior, such as unit and integration tests | Code as well as data quality, model accuracy and fairness | Answer quality on evaluation sets, together with safety and groundedness |
| What triggers a release? | A code change, once tests pass | Code changes as well as new data or a quality drop | Prompt, model, index or guardrail changes, since each alters answers |
| What is monitored? | Uptime, latency and errors | Service health as well as data drift and model quality | Service health as well as answer quality, safety flags and cost per call |
| Who owns it? | Developers and operations | Data scientists, ML engineers and platform teams | ML engineers, application teams and risk reviewers |
LLMOps is best read as MLOps with extra assets, and the generative AI section below covers what each extra asset needs.
The MLOps Lifecycle and Pipeline Architecture
The MLOps lifecycle is easiest to understand by following one model around the loop. Take a churn model for a subscription business, a classic case of machine learning in predictive analytics. It starts as raw usage and billing data and then becomes a set of features. After training, the model ends up scoring every customer each night.
Then the loop restarts, because next month’s customers will not behave exactly like last month’s. Each stage hands a versioned output to the next one. When a stage fails, the pipeline stops there instead of passing a bad artifact along. That single property separates an MLOps pipeline from a folder of scripts someone runs by hand.
The Eight Pipeline Stages
- Ingest and validate data. Pull from source systems and check schema, volume and value ranges before anything else runs. Our primer on data pipelines covers the ingestion side in more depth.
- Build features. Turn raw fields into model inputs, using the same code for training and serving.
- Train and track. Run training and log parameters, metrics and artifacts for every run.
- Evaluate and validate. Compare the candidate with the current production model on held-out data and on important business segments.
- Register. Store the approved model and its lineage in a model registry.
- Deploy and serve. Release the model behind an API or a batch job through a controlled rollout.
- Monitor. Watch data health, model quality and service health in production.
- Retrain. Start a new training run on a schedule, when fresh data lands or when a monitored signal crosses its threshold.
Not every team needs all eight stages automated on day one. Still, every stage needs an owner and a written definition of done, even while a person runs it by hand.
Core Components of an MLOps Platform
Behind the stages sit a handful of platform components. Each does a specific job, and each leaves a recognizable hole when it is missing. The table maps them, with examples drawn from the tools covered later in this guide.
| Component | Job | What breaks without it | Examples |
|---|---|---|---|
| Data versioning | Snapshots datasets and links them to code commits | Old models cannot be rebuilt once data changes | DVC |
| Feature store | Serves the same feature definitions to training and serving | Training-serving skew, due to duplicated feature code | Feature tables in your ML platform |
| Experiment tracking and metadata | Records parameters, metrics and artifacts for each run | Results cannot be compared or reproduced later | MLflow |
| Model registry | Stores approved versions with lineage and status | Nobody knows which version is live when something fails | MLflow, Models in Unity Catalog, Azure Machine Learning |
| Orchestrator | Runs pipeline steps in order and retries failures | Steps run by hand, so they run out of order | Kubeflow Pipelines, Apache Airflow, SageMaker Pipelines |
| Serving | Exposes the model as an API or batch job | Models stay in notebooks rather than in products | Managed endpoints on your cloud platform |
| Monitoring | Tracks drift, quality and service health | Silent failures, such as the fraud example | Azure Machine Learning drift detection as well as custom checks |
Teams rarely need all seven on day one, and our guide to data orchestration tools compares the scheduling options in more depth. The registry and the orchestrator usually come first, because together they turn one-off work into a repeatable path to production.
Kanerika Service
MLOps Consulting Services
Kanerika builds production ML pipelines with versioning, tests, release gates and monitoring on the Azure, Databricks or Fabric platform you already run.
Explore MLOps ServicesMLOps Maturity Levels: 0, 1 and 2
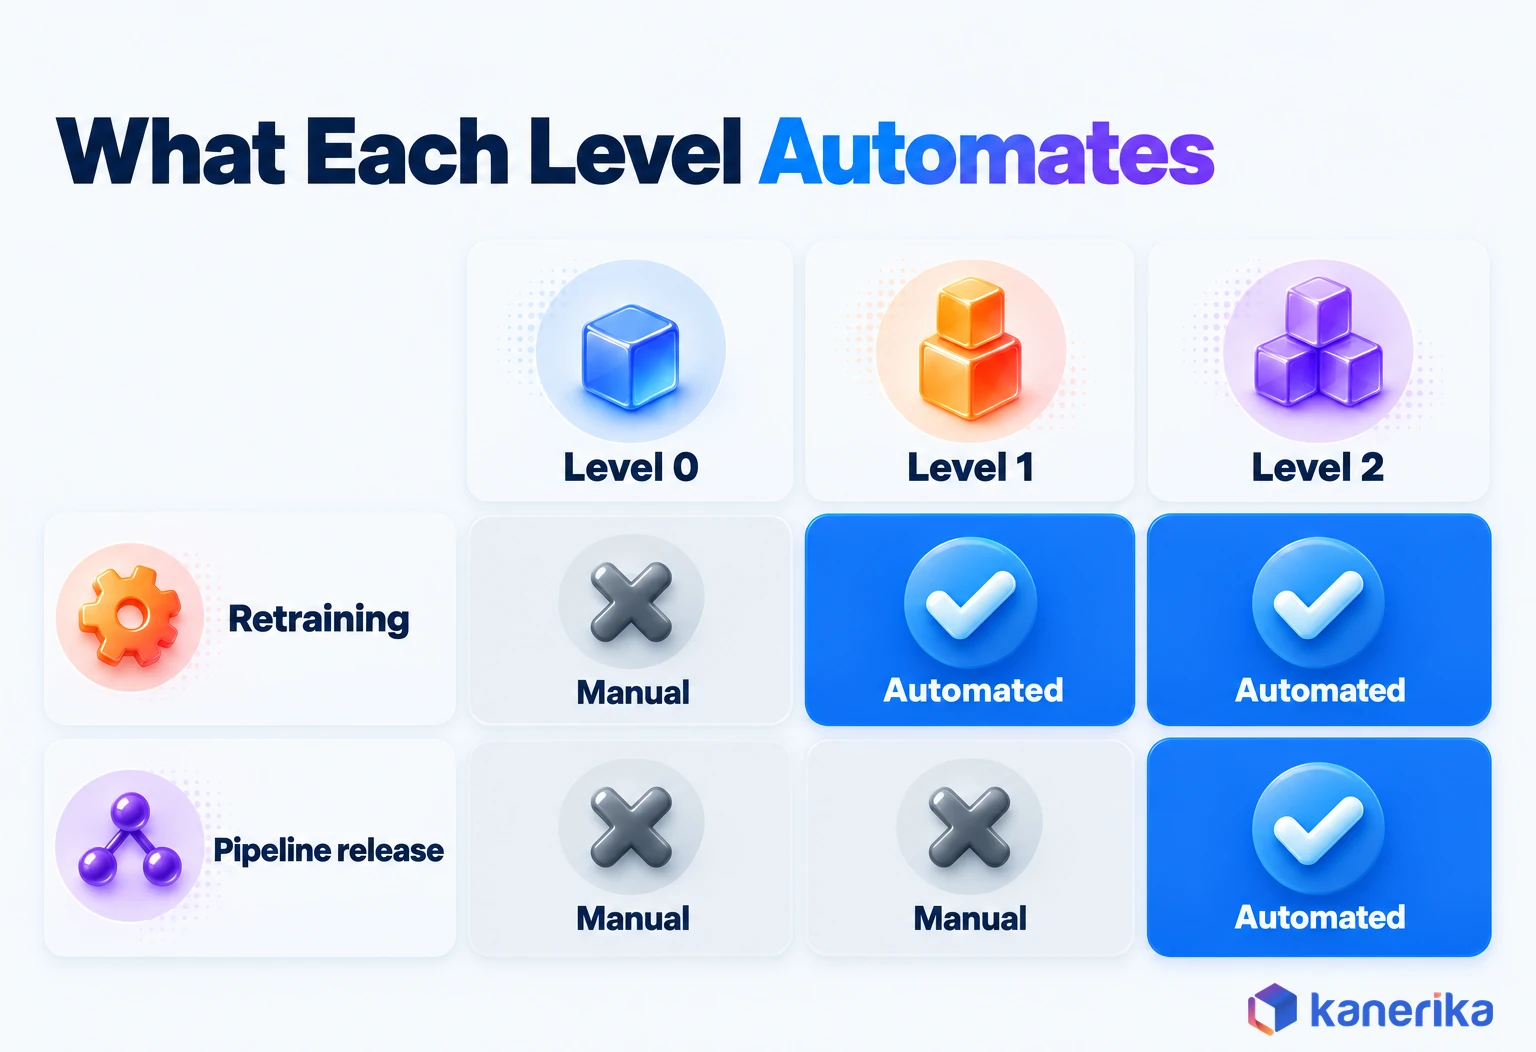
Maturity in MLOps is mostly a question of how much of the path to production runs without a person pushing it. Google Cloud’s MLOps architecture guide describes three levels of pipeline automation. The map is useful even if you never run on Google’s platform. Each level keeps everything from the one below it and automates one more handoff. So the useful question at every level is the same: which step still waits for a person?
At level 0, everything is manual. A data scientist trains a model in a notebook and then hands a file to engineers, who deploy it. At level 1, the training pipeline itself is automated, so the model retrains on fresh data without anyone rerunning cells, which Google calls continuous training. At level 2, the pipeline is also built, tested and deployed through CI/CD, so teams can change the pipeline quickly and safely.
What the Levels Do and Do Not Measure
The levels measure pipeline automation, not safety. Like a data governance maturity model, they describe how work gets done rather than whether results are good. A level 0 team with strong data checks can run a safer model than a level 2 team with no monitoring. Google also notes that its guide applies mainly to predictive AI, so generative systems need the extra assets covered later in this article.
| Level | How models ship | How retraining happens | Who it suits |
|---|---|---|---|
| Level 0: manual process | A file handed from data science to engineering | By hand, when someone finds time | Teams with one or two models that change rarely |
| Level 1: ML pipeline automation | An automated pipeline produces each new model | Continuous training whenever new data or a trigger arrives | Teams with several models or fast-moving data |
| Level 2: CI/CD pipeline automation | Pipeline code passes CI/CD before it runs | Continuous training as well as tested pipeline updates | Platform teams serving many models and many data scientists |
Six-Question Self-Check
Answer each question with a plain yes or no. Every “no” points to a practice later in this guide.
- Can you rebuild last quarter’s production model from versioned data, code and settings?
- Does an automated pipeline produce each new model version?
- Do incoming data batches get checked before training and before scoring?
- Does every production model have a named business owner and a business metric?
- Would you know within a day if a model’s prediction quality dropped?
- Can you roll back to the previous model version in minutes?
Mostly “no” means you are at level 0, and the first goal is one automated pipeline for your highest-value model. Yes on the first three but not the rest means level 1 automation without the monitoring and ownership that make it safe. Finally, a team that answers yes to all six is ready to scale out to many models.
AI Assessment
Where Does Your ML Practice Stand?
Take Kanerika’s AI Maturity Assessment to see how your data, models and governance compare before you plan the next MLOps level.
Start Your AI Assessment →10 MLOps Best Practices for 2026
The ten practices below are the core answer to what good machine learning operations looks like in 2026. Each one starts with a plain rule, then explains why it matters, gives an example and names what breaks without it. They follow roughly the order in which teams adopt them.
1. Tie Every Model to a Business Metric and a Service Target
Before a model ships, write down two numbers. One is the business result it should move, while the other is the service level it must meet. For example, a churn model might target a lower cancellation rate among contacted customers, plus a nightly batch that finishes by 6 a.m.
Accuracy alone is a weak release criterion, because a more accurate model can still lose money. A fraud model that catches more fraud but doubles false alarms may cost more in blocked customers than it saves. Without a business metric, nobody can say whether a model is worth keeping, so every review turns into a debate about opinions. Our guide to machine learning for business analytics shows more models framed around a business result.
2. Version Code, Data, Model and Environment Together
Every production model should trace back to an exact code commit, data snapshot, parameter set and environment. Tools such as DVC extend Git so that data and models get the same version history as code. An experiment tracker then links each trained model to the run that produced it.
Reproducibility is the payoff. When a regulator, a customer or your own team asks why a model behaved a certain way, you can rebuild it and test it again. Without full versioning, the team ends up guessing which dataset was used, so a rollback means redeploying a file nobody can recreate.
3. Validate Data Before It Reaches Training or Serving
Treat incoming data as untrusted until it passes checks. At minimum, test the schema, null rates, value ranges and row counts of every batch, and compare feature distributions with the training data. Many teams also formalize this as a data contract with the team that owns each upstream source. The same checks belong in the validation step of any ETL framework that feeds a model.
This is the control that would have saved the fraud model in the opening example. A schema check would have failed the moment the field was renamed, so the pipeline would have stopped instead of scoring on defaults. The same checks need to run at serving time, because training-serving skew appears when production features are computed differently from training ones.
4. Track Every Experiment
Log every training run, including the ones that lose. Record parameters, metrics, artifacts, the data version and a snapshot of the code. MLflow, whose 3.17.0 release shipped on October 6, 2026, is a widely used open-source tracker, and a few lines of code are enough to start.
import mlflow

with mlflow.start_run(run_name="churn-model-candidate"):
    # Record what went in: settings and the data version
    mlflow.log_params({"max_depth": 6, "learning_rate": 0.05, "data_version": "v42"})

    model, auc = train_and_evaluate()  # your own training code

    # Record what came out, so runs can be compared later
    mlflow.log_metric("auc", auc)
Tracking turns tuning from memory into evidence. When a new candidate beats production, the team can see exactly what changed and why. Without it, the best model of the quarter can turn out to be impossible to reproduce.
5. Test Data, Model and Infrastructure, Not Just Code
Unit tests on code are necessary, but they cover only one way an ML system fails. Breck and colleagues published the ML Test Score rubric in 2017, and the MLOps principles on ml-ops.org summarize it. The rubric scores a system on tests that go well beyond code. The table lists the tests that catch the most common production failures.
| Test | What it catches | When it runs |
|---|---|---|
| Schema and data quality tests | Problems such as renamed fields, nulls and out-of-range values | Every data batch, before training and scoring |
| Feature tests | Skew when serving features differ from training ones | Every pipeline run |
| Model quality tests | A candidate that does worse than the production model | Before a candidate is registered |
| Fairness checks | Uneven error rates across customer groups | Before release and at each review |
| Infrastructure tests | Broken containers, missing dependencies and slow inference | Whenever code or the environment changes |
| Rollback tests | A release that cannot be undone quickly | Before major releases |
Start with the first and third rows. Data tests and a champion-versus-challenger comparison are cheap to add, and they would also have caught the failure in the opening example.
6. Run CI, CD and Continuous Training as Separate Loops
MLOps has three release loops, and each one needs its own trigger. Continuous integration tests pipeline code whenever someone changes it. Continuous delivery then deploys the tested pipeline or model service. Finally, continuous training reruns the pipeline when new data arrives or a monitored signal crosses a threshold.
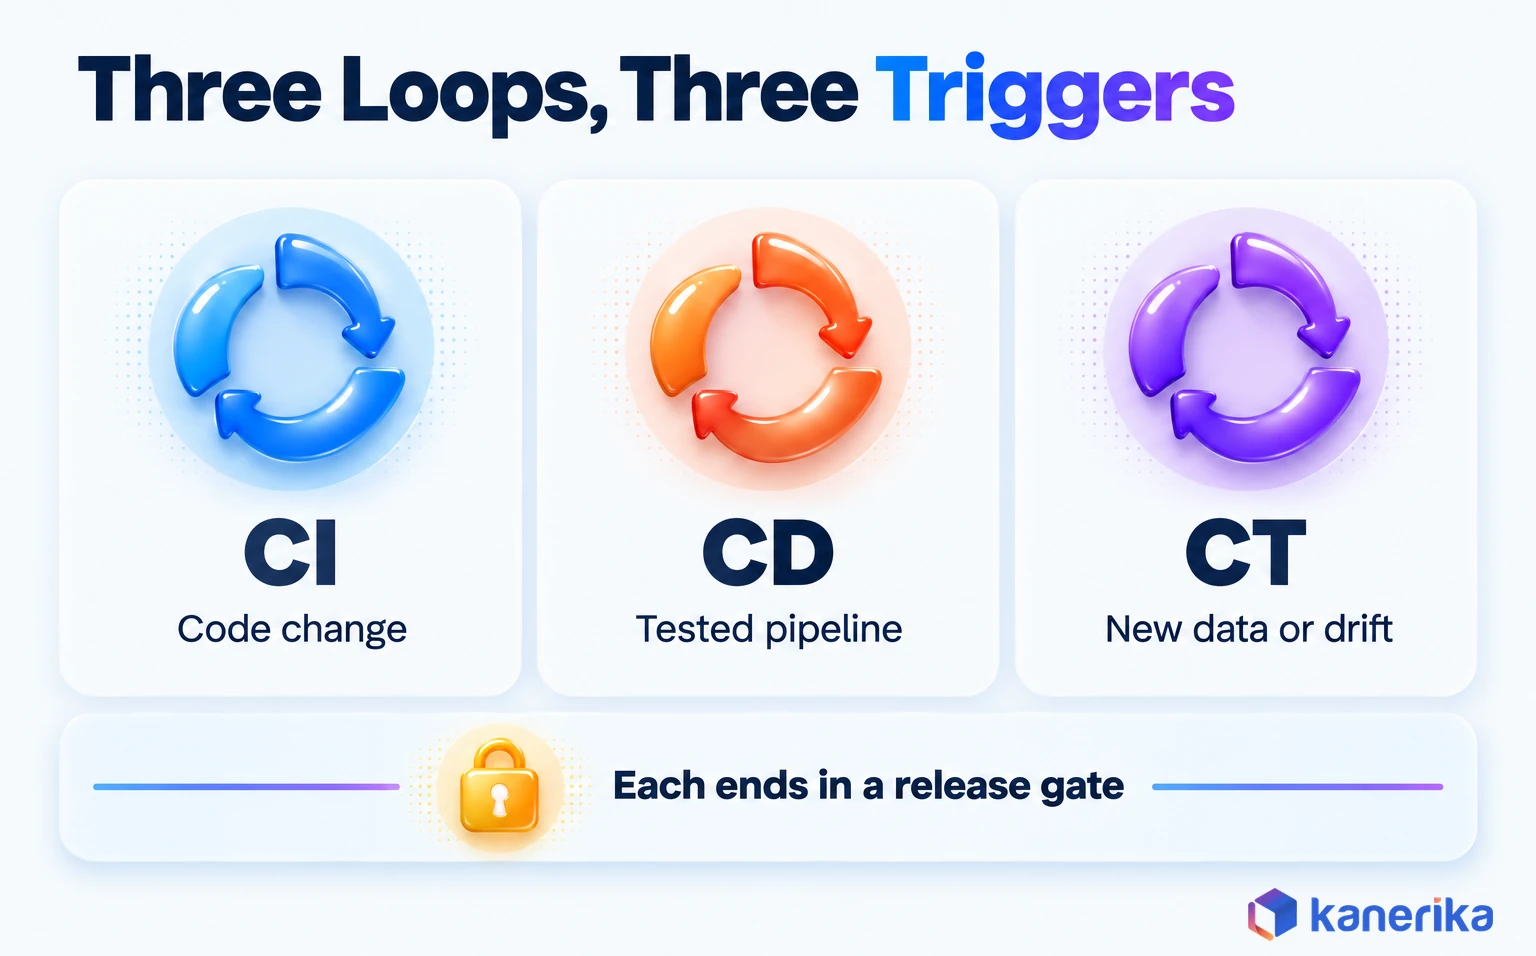
Keeping the loops apart makes failures easy to trace. In its MLOps workflow guidance, Databricks recommends that teams “deploy code, not models” in most situations. The training code moves through development, staging and production, so the production model comes from tested code running on production data.
Every loop ends in a release gate. A typical gate checks that the candidate beats the current model on agreed metrics, passes data and fairness tests, and has a named approver. Rollouts then expose the new model gradually, for example through a shadow or canary release. For the full set of deployment patterns and rollback rules, see our guide to machine learning model management.
On Databricks, the promotion step itself can be a single API call. Models in Unity Catalog supports aliases, mutable names that point at one model version. A batch job loads models:/prod.ml_team.churn_model@Champion, so promoting a candidate means moving the Champion alias with set_registered_model_alias. The job code never changes, and rolling back means pointing the alias at the previous version. In MLflow 3, the default registry URI on Databricks is already databricks-uc.
7. Monitor Data Health, Model Quality and Service Health Separately
Production monitoring needs separate views, because each signal fails in a different way. Service health shows whether the model answers at all. Data health shows whether the inputs still look like the training data, while model quality shows whether the answers are still right.
| Signal | Example metric | Action when it moves |
|---|---|---|
| Data health | Schema breaks, null rates and feature drift | Stop the pipeline, then alert the data owner |
| Model quality | Accuracy, precision or a proxy such as approval rate | Investigate, then retrain or roll back |
| Service health | Latency, error rate and throughput | Scale or fix the serving system before users notice |
| Business result | The metric agreed before launch in practice 1 | Review the model with its business owner |
Ground truth often arrives late. A loan default may take months to show up, so accuracy cannot be measured in real time. Use proxy metrics until the labels arrive, such as the share of applications approved or the spread of risk scores.
Upstream signals also help. Many model problems begin as data problems, so tooling for data observability often raises the alarm before any model metric moves.
8. Secure and Govern the Pipeline
A pipeline that can change production models is a high-value target, so secure it like any other production system. Keep secrets in a vault and limit who can register or promote models. Also record the provenance of every artifact, and keep an audit trail of each approval. Our AI security framework guide covers the controls around the pipeline in more detail.
Governance frameworks give this work a structure. The NIST AI Risk Management Framework, released in January 2023 and extended with a generative AI profile in July 2024, is a common reference point. In US banking, the Federal Reserve, OCC and FDIC replaced SR 11-7 with SR 26-2, their revised model risk guidance, in April 2026.
Some data cannot leave its source at all. In those cases, federated learning lets teams train models without moving the data, which changes how the pipeline is secured. The policies, risk tiers and review roles behind all of this belong in a wider machine learning governance program.
Checklist
AI Governance Checklist
Use Kanerika’s AI Governance Checklist to review the access controls, approvals and audit evidence your ML pipelines need before a model risk review.
Get the Checklist →9. Control Training, Serving and Monitoring Costs
ML costs grow quietly, one idle endpoint at a time. So give each model a cost owner, and then review its spend alongside its business metric.
Take the churn model from earlier, which scores every customer once a night. On an always-on real-time endpoint, the business pays for serving capacity around the clock to answer one nightly batch of requests.
Moving that model to a scheduled batch job removes the idle capacity. The trade-off is latency the business never needed, because retention teams act on the scores the next morning anyway. Similar savings come from a short list of habits, and our guide to Databricks performance optimization adds platform-specific tuning.
- Scale down endpoints that serve little traffic, or move them to batch scoring.
- Retrain on a trigger or a measured schedule rather than by habit, since daily retraining on slow-changing data wastes compute.
- Choose batch scoring when decisions can wait a few hours, because online serving keeps capacity ready around the clock.
- Sample monitoring data for high-volume models instead of logging every request in full.
- Tag every training job and endpoint with its model and owner, so spend shows up per model.
The aim is a cost per model that the business owner agrees is worth paying.
10. Review and Retire Models That No Longer Pay Off
Every production model needs a review date. At each review, the business owner and the technical owner decide together whether to keep, retrain, replace or retire it. Retiring a model is a sign of a healthy practice, since every live model carries monitoring work, cost and risk. The model management guide linked under practice 6 also sets out the retirement rules in detail.
Consider a quarterly review of a pricing model. Its business KPI has been flat for two quarters, yet its monitoring and compute still cost money every month. The owners retire it and route pricing decisions to the rules-based fallback.
Retiring means more than switching the model off. The team stops serving it and archives its registry version with its data and code lineage. It then removes the model’s alerts, so nobody gets paged for a model that no longer runs.
Who Owns What in Machine Learning Operations
MLOps problems tend to appear at the handoffs between teams rather than inside any one of them. A clear split of responsibilities keeps a model from becoming everyone’s interest and nobody’s job. The table gives a RACI-style split, showing what each role does and what it answers for.
| Role | Responsible for | Accountable for |
|---|---|---|
| Data scientist | Training and evaluation, such as feature choice and model selection | Model quality before release |
| ML engineer | Pipelines, CI/CD, serving and monitoring | Keeping production models running once they ship |
| Data engineer | Source pipelines and quality checks | Data that arrives on time and in the agreed schema |
| Platform or DevOps team | Infrastructure, security and cost tagging | Uptime and spend, so models have a stable home |
| Business owner | The business metric and release approval | Whether the model still creates value |
| Risk and compliance | Model risk reviews and audit evidence | Policy and regulatory fit before high-stakes releases |
Small teams can combine roles, and one person often covers both data and ML engineering. Still, the split worth keeping is accountability for the business result. The person who built a model should not be the only person who decides that it still works.
MLOps Tools and Platforms in 2026
Choosing MLOps tools starts with the platform you already run. Most choices fall into three groups: open-source components you assemble, managed platforms from the major clouds and data vendors, or a hybrid of the two.
Each option trades control against the work of running it. Open-source tools give you portability and control, but your team operates the platform. Managed platforms cut that work and plug into their cloud’s security and data services, though they tie you more closely to one vendor. A hybrid, such as open-source tracking on managed compute, suits enterprises that run more than one cloud. Teams choosing between two managed data platforms can start with our Microsoft Fabric vs Databricks comparison.
Open Source, Managed and Hybrid Compared
The table sticks to what each vendor’s own documentation says the tool does, so you can compare them on the same terms.
| Tool | Type | What it does |
|---|---|---|
| MLflow | Open source | Tracks experiments and manages models, on the MLflow 3 release line |
| Kubeflow Pipelines | Open source | Builds and deploys portable, scalable ML workflows using containers on Kubernetes |
| Apache Airflow | Open source | Authors, schedules and monitors workflows defined in Python |
| DVC | Open source | Versions data and models the way Git versions code |
| Amazon SageMaker Pipelines | Managed (AWS) | Purpose-built workflow orchestration that automates ML development |
| Azure Machine Learning | Managed (Microsoft) | A registry that stores and versions models, as well as deployment, monitoring and data drift detection |
| Databricks with MLflow and Models in Unity Catalog | Managed (data platform) | MLflow tracks development, while Unity Catalog manages model versions, governance and deployment status |
| Gemini Enterprise Agent Platform Pipelines | Managed (Google Cloud) | Google’s ML pipeline service, renamed from Vertex AI Pipelines in April 2026 |
Which Approach Fits Your Scenario
The right starting point depends on your current platform, your regulatory exposure and how many teams ship models. The table maps five common situations to an approach and to the best practice each one should put in place first.
| Scenario | Starting approach | First best practice to adopt |
|---|---|---|
| You already run one cloud for data | That cloud’s managed ML platform, since access is in place | Version code, data and models in its registry (practice 2) |
| Regulated bank or insurer | Managed platform as well as a registry with approval records | Release gates with named approvers and an audit trail (practices 6 and 8) |
| Startup with three models | MLflow and a simple scheduler, then level 1 automation | Data checks before experiment tracking (practices 3 and 4) |
| Kubernetes-first engineering team | Kubeflow Pipelines together with MLflow tracking | Separate CI, CD and continuous training loops (practice 6) |
| Many teams sharing a data lakehouse | Databricks with MLflow and Models in Unity Catalog | Named owners and three-signal monitoring for every model (practices 1 and 7) |
Whatever you pick, the practices stay the same. A tool makes versioning, testing and monitoring easier, but it never decides what to version, test or monitor.
MLOps for Generative AI and AI Agents
Generative AI keeps the MLOps foundation and adds more to manage on top of it, which is why enterprise artificial intelligence programs extend the same pipelines rather than start over. A team building a support assistant may never train a model at all. Even so, it ships changes that alter behavior every week, in prompts, retrieval data and model versions.
LLMOps adds six concerns to the standard practice:
- Prompt and configuration versioning, so every prompt edit has a history and a rollback.
- Evaluation sets of real questions with reviewed answers, run before every release.
- Retrieval index refresh, because stale documents produce confident but outdated answers.
- Guardrails that check inputs and outputs for unsafe or off-policy content.
- Cost per call, tracked per feature, since token spend rises with usage.
- Tracing of every step in a multi-step chain or agent run.
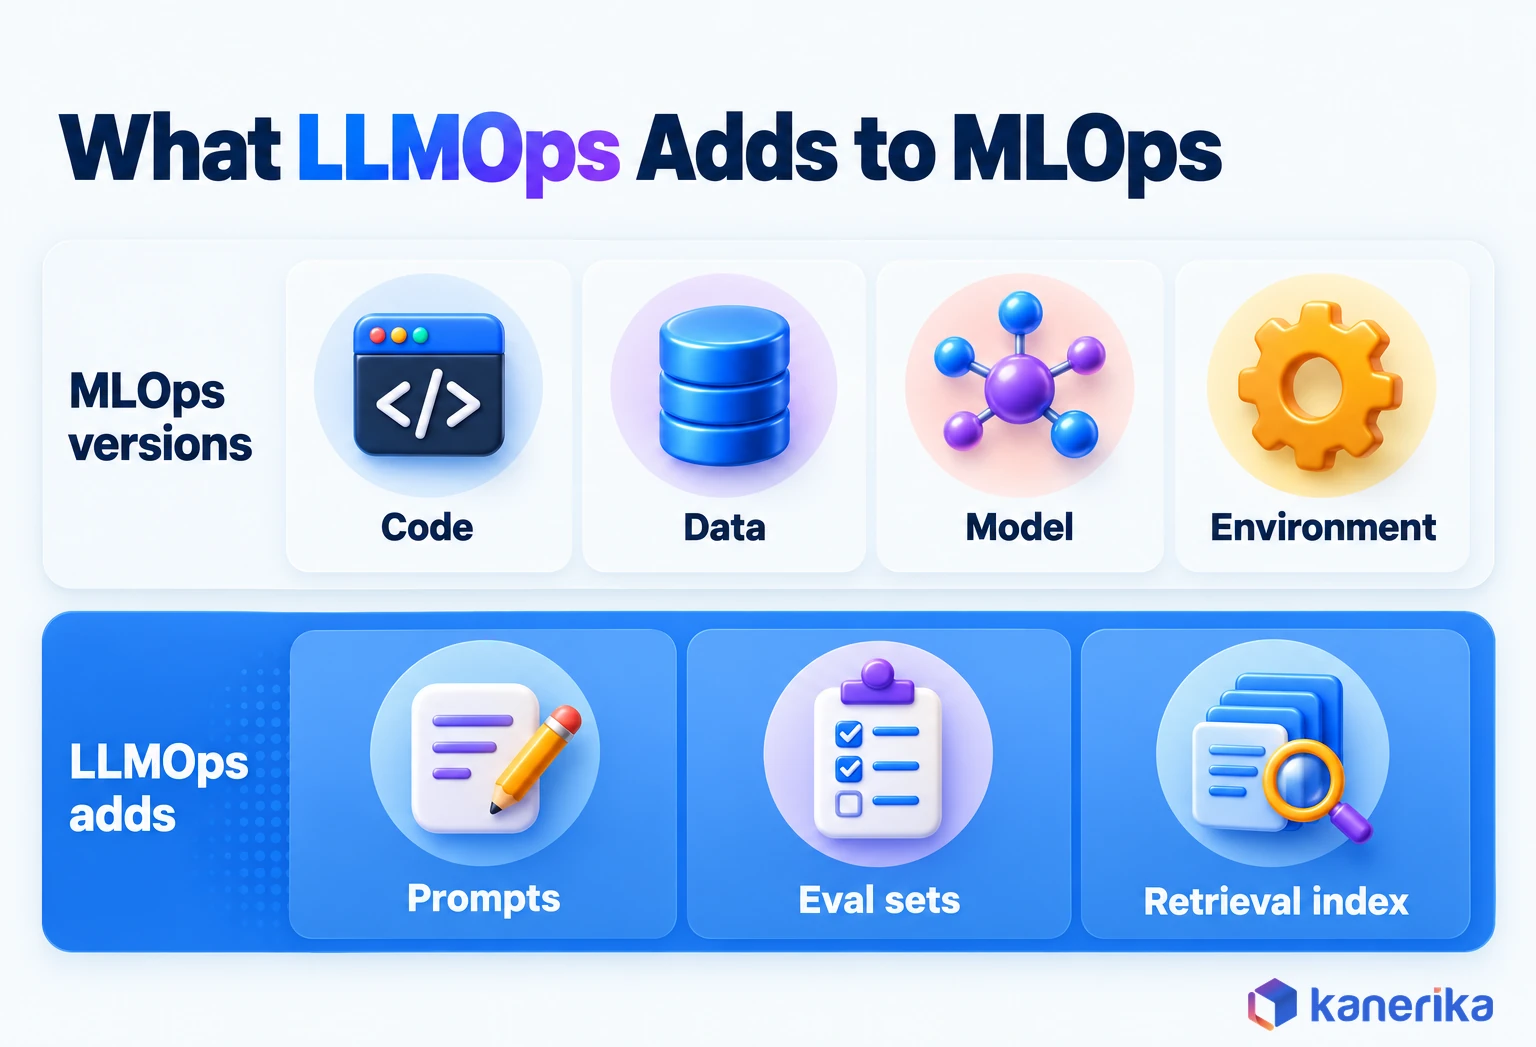
Treat each of these like a model asset, including the agent steps that an AI agent orchestration layer coordinates. A prompt change should pass the evaluation set before release, just as a retrained model must beat the current one.
Agents raise the stakes, because they take actions instead of only producing text. A tool call that updates a customer record needs the same release gates and audit trail as a model that approves a loan. Our guide to autonomous AI agents covers how agents behave in production. For tracing and evaluation in more depth, see our piece on LLMOps observability.
How to Measure Whether MLOps Is Working
MLOps is an investment, so it needs its own scorecard. The practical approach borrows the four delivery metrics from DevOps, as the ml-ops.org principles do. It then adds two measures that only make sense for models.
| KPI | What it shows | Good direction |
|---|---|---|
| Deployment frequency | How often model or pipeline changes reach production | Up |
| Lead time for changes | Time from a committed change until it reaches production | Down |
| Mean time to restore | How fast you recover when a model or service fails | Down |
| Change fail percentage | Share of releases that need a rollback or a fix | Down |
| Share of production models monitored | Coverage of data, quality and service checks | Up, toward every model |
| Business KPI per model | Whether each model still earns its place | Up, against the target set before launch |
Read the metrics together rather than one at a time. For example, fast deployments with a rising change fail percentage mean the release gates are too loose. Similarly, a high share of monitored models with flat business KPIs suggests some models are ready for retirement.
Review the scorecard every quarter with the business owners in the room. When the numbers improve, the case for expanding MLOps to more models makes itself.
Talk to Kanerika
Want Your Models Running Reliably in Production?
Kanerika can review your current models and pipelines, then show which MLOps practices would close the biggest gaps first.
Schedule a Demo →Common MLOps Challenges and How to Fix Them
A familiar set of problems shows up in MLOps programs across industries. The table pairs each challenge with its symptom and with the practice above that fixes it.
| Challenge | Symptom | Fix |
|---|---|---|
| Models stuck after the prototype | Months between a good notebook and a live model | Automate one pipeline end to end (practices 2 and 6) |
| Silent data breaks | Predictions drift while uptime looks perfect | Data validation and data health monitoring (practices 3 and 7) |
| Unreproducible models | Nobody can rebuild last year’s model | Version everything and track experiments (practices 2 and 4) |
| Late ground truth | Accuracy is known only months later | Proxy metrics until labels arrive (practices 1 and 7) |
| Unclear ownership | Alerts fire, but nobody acts | Named owners and a RACI (practice 1 and the ownership section) |
| Rising cloud bills | Idle endpoints and needless retraining | Cost owners and trigger-based retraining (practice 9) |
| Model sprawl | Dozens of models, but few of them reviewed | Review dates and retirement rules (practice 10) |
Pick the one or two rows that hurt most; fixing those usually builds the habits that make the rest easier.
How Kanerika Implements MLOps
Kanerika helps enterprises move models from pilots into production through its MLOps consulting services. The work builds on the data platform a client already uses, such as Azure, Databricks or Microsoft Fabric. It also runs in stages, so each step delivers something usable.
- Assess. Inventory current models, data sources and risks, and rank each model by business value.
- Design. Set a target architecture on the existing platform and decide which components to adopt first.
- Build the first pipeline. Take one high-value model to production with versioning, tests and release gates.
- Monitor and control cost. Add data, quality and service monitoring, plus cost tagging for each model.
- Expand. Reuse the proven pattern across further models and teams.
Data checks at the front of the pipeline often decide whether a model stays healthy. For that layer, Kanerika’s FLIP DataOps platform is a low-code, AI-powered tool that automates data transformation pipelines through pre-built connectors. Pairing it with an MLOps pipeline gives the model an automated, repeatable feed instead of hand-run extracts.
Fraud detection shows why this staged approach matters. Fraud patterns shift as fraudsters adapt, so a fraud model loses value fastest when nobody watches its data and results.
In one fraud detection engagement, Kanerika built fraud and risk models for a mid-sized US insurer rated A+ by AM Best. The models used Isolation Forest and Autoencoder techniques on data held in Azure Data Lake. The fraud-modeling project delivered a 33% decrease in financial losses, a 25% reduction in overall risk exposure and a 37% increase in the customer base.
Case Study
33% Fewer Financial Fraud Losses with AI Modeling & Forecasting
Kanerika built fraud detection and risk models for a mid-sized US insurer rated A+ by AM Best, helping cut financial losses by 33% and overall risk exposure by 25%.
Read the Case Study →Kanerika works as a partner of Microsoft, Databricks and Snowflake. Its wider AI services cover the models and agents that run on these pipelines once they are in place.
MLOps Best Practices for 2026: The Short Answer
Machine learning operations best practices for 2026 come down to three priorities, applied in order. Each one builds on the one before it, so skipping ahead tends to create the failures described in this guide.
- Control first. Version everything, validate data, and give every production model a named owner and a business metric.
- Repeatability next. Automate one pipeline end to end with tests, release gates and continuous training.
- Expand on evidence. Add models, teams and generative AI workloads only when monitoring and the KPI scorecard show the current ones are healthy.
A small team can reach the first two priorities within a few releases on the platform it already runs. Start with the model that would hurt most if it went quiet, and give it versioning, a data check and an owner this quarter.
Frequently Asked Questions
What is machine learning operations (MLOps)?
Machine learning operations, or MLOps, is the set of people, processes and automation that moves models from experiment to production and keeps them accurate afterward. It applies DevOps habits such as version control, testing and repeatable releases to data and models too. The goal is a model that stays correct while its data and environment keep changing.
Is MLOps just DevOps?
No. MLOps borrows DevOps practices but covers more moving parts. DevOps versions and tests code, while MLOps also versions data, models and environments. A model can degrade with no code change at all, because its input data shifts. So MLOps adds data validation, continuous training and model quality monitoring that a standard DevOps pipeline does not include.
How do you monitor machine learning models in production?
Monitor three signal families separately. Data health covers schema breaks, null rates and feature drift. Model quality covers accuracy or proxy metrics, such as approval rates, while true labels are still pending. Service health covers latency and errors. Add the business metric agreed before launch, and give every signal a threshold, an owner and an action.
When should a machine learning model be retrained?
Retrain when a monitored signal shows the model no longer fits its data, or when the business metric slips past an agreed tolerance. A fixed schedule also works for data that changes predictably. Drift alone is a reason to investigate first. Every retrained model should beat the current version and pass its release gate before going live.
How do you implement MLOps in an enterprise?
Start small and build on the platform you already run. Assess current models and risks, then pick one high-value model. Take it to production with versioning, data tests and a release gate, and add monitoring and cost tagging. Once that pipeline works, reuse the pattern across other models and teams instead of building a custom platform.
Who is responsible for MLOps in an organization?
MLOps is shared work. Data scientists own training and evaluation, ML engineers own pipelines, serving and monitoring, and data engineers own data quality. Platform teams run the infrastructure. A business owner stays accountable for each model’s results, and risk teams review high-stakes models. The builder should never be the only person judging the model.
How much does MLOps cost, and how do you measure its ROI?
Cost depends on model count, data volume and platform choice, so estimate it per model. Include platform fees, training and serving compute, monitoring and staff time. Measure return with delivery metrics, such as deployment frequency and time to restore, plus the business KPI each model was built to move. Retire models whose value no longer covers cost.
What are the main stages of the MLOps lifecycle?
A typical MLOps lifecycle has eight stages. Teams ingest and validate data, build features, train and track runs, and evaluate candidates against the current model. They then register the approved model, deploy and serve it, and monitor it in production. Retraining closes the loop, triggered by a schedule, fresh data or a monitored signal crossing its threshold.
What are the main components of an MLOps pipeline?
An MLOps pipeline usually rests on seven components. Data versioning and a feature store keep inputs consistent. Experiment tracking records every run, and a model registry stores approved versions with lineage. An orchestrator runs the steps in order, serving exposes the model, and monitoring tracks drift, quality and service health once the model is live in production.
What are the levels of MLOps maturity?
Google Cloud describes three levels of pipeline automation. Level 0 is manual, with models trained in notebooks and handed to engineers. Level 1 automates the training pipeline, so models retrain on fresh data through continuous training. Level 2 adds CI/CD for the pipeline itself, so teams can test and release pipeline changes quickly and safely at scale.
What are the biggest challenges in MLOps?
The most common challenges are models stuck after the prototype, silent data breaks, unreproducible models and late ground-truth labels. Unclear ownership, rising cloud bills and model sprawl follow close behind. Most of them trace back to missing basics, such as versioning, data validation, named owners and monitoring that watches data, model quality and service health separately.
What is the difference between MLOps and LLMOps?
LLMOps is MLOps extended for large language models and agents. It keeps the same pipelines, registries and release gates. It also adds prompt and configuration versioning, evaluation sets, retrieval index refresh, guardrails, cost per call and tracing. Many LLM applications never train a model, yet prompt edits and model upgrades still change their behavior every week.
What tools are used for MLOps?
Common open-source MLOps tools include MLflow for tracking and model management, Kubeflow Pipelines and Apache Airflow for orchestration, and DVC for data versioning. Managed options include Amazon SageMaker AI Pipelines, Azure Machine Learning, Databricks with Models in Unity Catalog, and Google’s Gemini Enterprise Agent Platform Pipelines. Most teams start with the platform they already run.
How does CI/CD work in MLOps?
In MLOps, continuous integration tests pipeline code whenever it changes, and continuous delivery deploys the tested pipeline or model service. Each loop ends in a release gate that checks metrics, data tests and approvals. Databricks recommends deploying code rather than models in most situations, so production models come from tested code running on production data.
What is continuous training in MLOps?
Continuous training means the pipeline retrains a model automatically instead of waiting for someone to rerun a notebook. It can start on a schedule, when fresh data arrives or when monitoring shows quality dropping. Each new model still passes validation and a release gate before it replaces the current one, so automation never skips the checks.