TL;DR
Machine learning governance starts with a model inventory and risk tiers, then adds drift and bias triggers that send each breach to a named owner. Watch data drift with PSI or KS tests, performance against a labeled baseline, and fairness with the four-fifths rule. Tie each alert to a retrain, rollback or re-approval path set by tier. Map the same controls to SR 26-2, the EU AI Act, NIST AI RMF and ISO/IEC 42001 so one set of evidence serves every regulator. Most enterprises should run all of this as a hybrid program. A regulated lender with a few high-impact models should centralize approval, while a product company with many low-risk models can federate it.
Key Takeaways
- Machine learning governance turns model decisions into a repeatable, auditable process, so approvals, changes and retirements leave evidence behind.
- A model inventory with risk tiers comes first, because approval depth, monitoring frequency and documentation all scale with a model’s tier.
- Drift and bias checks need thresholds tied to an owner and an action, such as a retrain, a rollback or a re-approval.
- SR 26-2 replaced SR 11-7 in April 2026, and the AI Omnibus moved EU high-risk duties for credit scoring and hiring models to December 2027.
- A hybrid operating model, with central policy and domain-run monitoring, fits most enterprises better than a fully centralized or federated one.
- Fairness needs the same cadence as drift: re-check the four-fifths screen every time drift is checked, not once at launch.
The Credit Model That Drifted for a Quarter
Picture a consumer lender whose approval model looks healthy on every dashboard. Its accuracy report is green, the monthly committee signs off, and so nobody touches the code.
Underneath, though, the mix of applicants has shifted. A new partner channel is sending younger applicants with thinner credit files, and the model saw few people like them during training. Approval rates for one age band then slide for a full quarter before a complaint reaches compliance.
Nothing in that story is a data science failure, since the model did exactly what it was built to do. The system around it failed. No one owned the input checks, no threshold triggered a review, and no record showed who approved the last version.
A governed program would have caught the shift early. For example, a drift test on applicant mix would have fired within weeks and routed the alert to a named owner. Then a scheduled fairness check would have flagged the slipping approval rate before a regulator or a customer did.
The rest of this guide shows how to build that system, one control at a time.
What Is Machine Learning Governance?
Machine learning governance is the set of policies, roles, controls and evidence that decide which ML models reach production. It also sets how those models are watched once live and when they are changed or retired. The result is a repeatable process that an auditor can follow, rather than a series of judgment calls.
Think of it as the rules of the road for models. Data science teams still build and tune them. Governance decides what evidence a model needs before launch, who signs off and what happens when a metric breaks.
Consider a model that blocks card payments in AI fraud detection next to a model that ranks articles on a website. Both may run on the same platform, yet they deserve very different scrutiny. A wrong answer from the first one costs real money and customer trust.
That proportionality is the core idea. When governance treats every model as high risk, teams slow to a crawl. When it treats every model as low risk, the program fails its first audit. So good programs spend effort where a wrong prediction hurts a customer, a balance sheet or a regulator’s trust.
ML governance also sits inside a wider data and AI control stack. It depends on clean, traced training data from your enterprise data governance program. It also feeds the board-level policies of an AI governance framework.
ML Governance vs MLOps vs Model Risk Management vs AI Governance
These four terms overlap, so teams often use them interchangeably. The cleanest way to separate them is by the question each one answers and by who owns the answer.
| Discipline | Scope | Typical owner | Main question |
|---|---|---|---|
| MLOps | Building, deploying and running model pipelines | ML platform team | Can we ship and run this model reliably? |
| ML governance | Policies and controls for ML models, such as tiers and approvals | Governance lead, together with risk and data teams | Should this model run, and under what conditions? |
| Model risk management | Independent validation of model risk | Second-line risk or validation team | Is this model sound for its intended use? |
| AI governance | Enterprise policy for all AI, including GenAI and agents | Executive committee or chief AI officer | Is our use of AI lawful, safe and aligned? |
MLOps supplies the plumbing that makes governance cheap to run, as our guide to MLOps orchestration explains. Model risk management is the validation discipline inside governance. The AI model risk management playbook walks through it step by step.
AI governance is the widest of the four, since it covers chat assistants, agents and vendor tools as well as trained models. ML governance is therefore best seen as one well-defined part of it.
Kanerika Service
AI Governance Services
Kanerika sets up the policies, risk tiers, approval paths and oversight that let enterprises put machine learning and generative AI models into production with audit-ready evidence.
Explore AI GovernanceWhy Machine Learning Governance Matters in 2026
The case for governance used to rest on good practice alone. In 2026, however, it rests on dated rules from bank supervisors, the European Union and standards bodies.
The biggest change for US banks came on April 17, 2026, when the Federal Reserve issued SR 26-2. This revised model risk guidance replaces SR 11-7 from April 2011 as well as SR 21-8. On the same day, the OCC issued it as Bulletin 2026-13 and rescinded its own model risk booklet. The OCC also said the guidance is most relevant to banks over $30 billion.
Europe moved too. The EU AI Act entered into force on August 1, 2024 and became applicable on August 2, 2026, with exceptions. The AI Omnibus, in force since July 27, 2026, pushed the Annex III high-risk duties to December 2, 2027. Those duties cover uses such as credit scoring, employment and biometrics.
What Changed for ML Teams
US bank model risk guidance has changed for the first time in fifteen years. The first job is to re-read any policy written for SR 11-7 against SR 26-2. EU high-risk models also need risk management, logging, human oversight and post-market monitoring. In practice, high-tier models should get logging and a post-market monitoring plan in their release checklist.
Supplier reviews are shifting as well. ISO/IEC 42001, published in December 2023, gives buyers a certifiable AI management standard. Expect it to appear in vendor questionnaires on both sides of a contract. Chat assistants and agents now sit next to classic scoring models, so they belong in the same inventory from their first pilot.
Governance also pays back outside compliance. It gives teams a consistent way to judge models, and it leaves audit evidence as a by-product of normal work. It even speeds approvals, because reviewers know exactly what to expect.
That last point surprises engineers most. A clear checklist is faster to pass than an open-ended review, so a known approval path lets teams plan release dates with confidence.
AI Assessment
How Ready Is Your AI Program for Governance?
Score your data foundations, model practices and oversight with Kanerika’s AI maturity assessment, and see which governance gaps to close first.
Take the Assessment →The Core Components of an ML Governance Program
Every mature machine learning governance program rests on the same seven controls, whatever its size. Because each one answers a question an auditor will eventually ask, it helps to build them in roughly this order.
- Model inventory and registry. This is one list of every model in production or development, with its owner, purpose, version and status. No other control works without it, since nobody can govern an unknown model.
- Risk tiering. A short rubric places each model in a high, medium or low tier by impact, autonomy and regulatory exposure. The tier sets how deep validation goes and how often monitoring runs.
- Training data lineage and quality. This records which datasets, labels and engineered features trained each version, traced back with data lineage. Teams choosing data annotation tools should also check that those tools export audit trails.
- Validation and documentation. Independent tests of accuracy, stability and limits run before launch. The results go into a model card that states intended use and known weaknesses.
- Explainability. Methods such as feature attribution show why a model produced a given output. For a declined loan, for instance, a lender needs reasons a customer can read.
- Bias and drift monitoring. Scheduled checks cover inputs, output quality and outcomes across groups, each with a threshold and an owner. Without a trigger, though, monitoring is only a dashboard.
- Access control and audit evidence. Rules set who can train, approve, deploy and change a model, while every action is logged. That log is what turns good behavior into proof.
How the Seven Controls Depend on Each Other
These controls lean on each other. Tiering is only as good as the inventory beneath it. Likewise, monitoring is only useful when lineage lets you trace a drift alert back to a source change.
Teams that already run data observability on their pipelines have a head start on the last two controls. Their freshness and schema checks become the first layer of model monitoring, so no new tooling is needed at first.
Checklist
AI Governance Checklist
Work through inventory, risk, oversight and evidence requirements for your AI and ML models with Kanerika’s AI governance checklist.
Get the Checklist →How ML Governance Works Across the Model Lifecycle
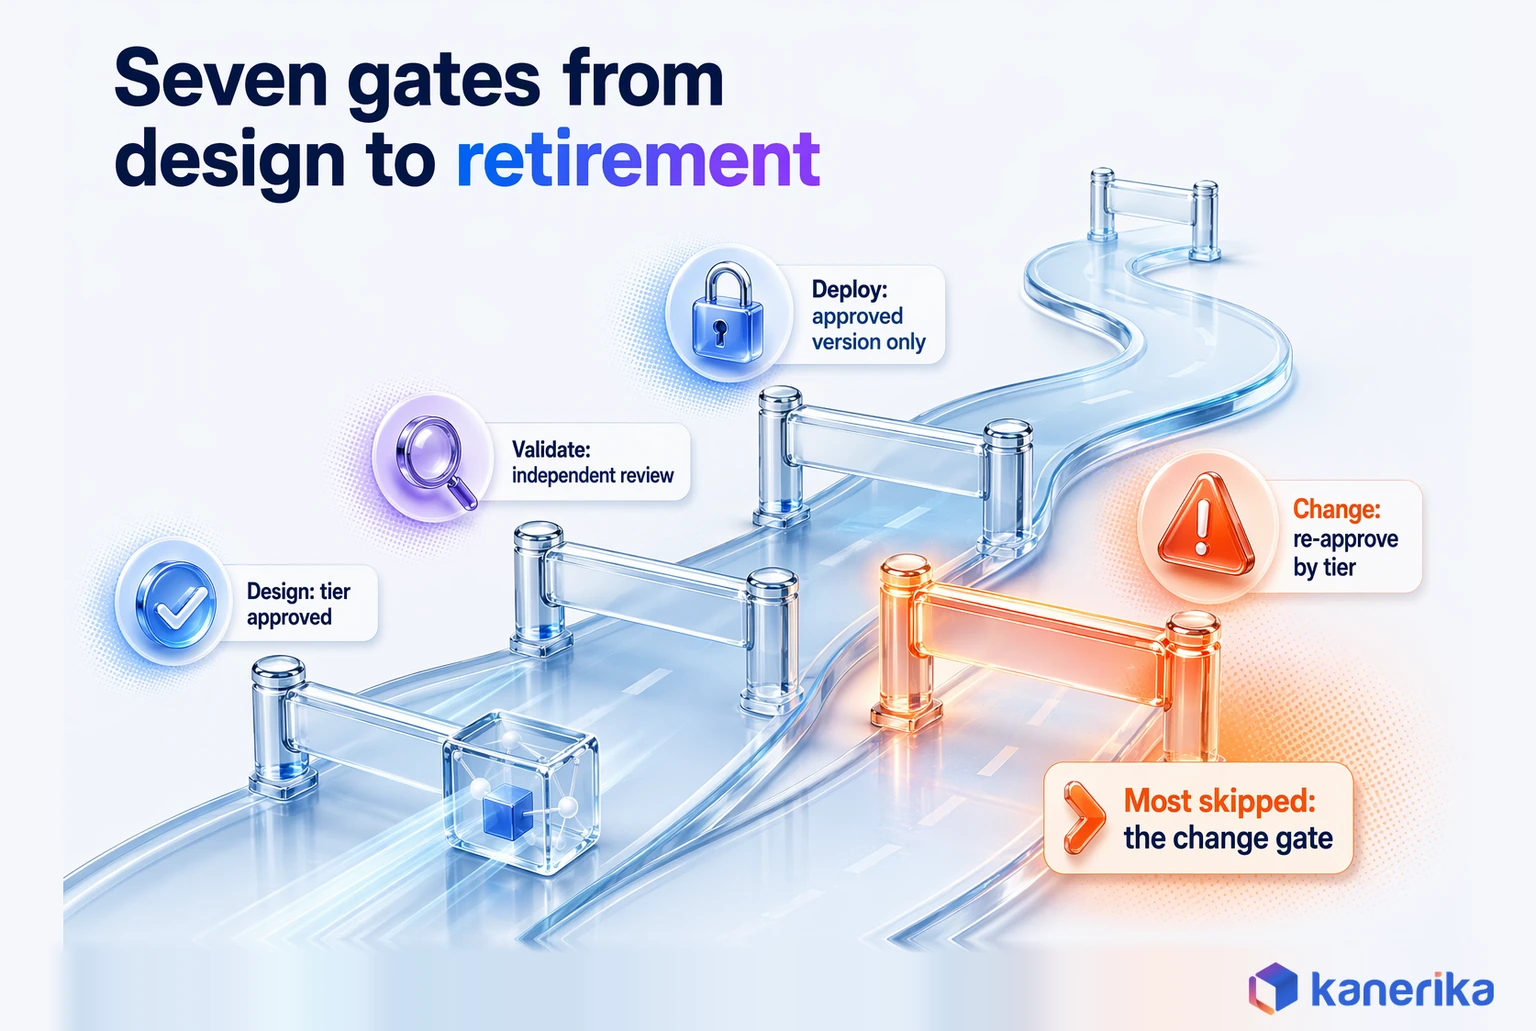
Machine learning governance is easiest to run when it shows up as a gate at each stage of a model’s life, rather than as one review at the end. Each gate asks for specific evidence and has a named owner, so teams know what “done” means before they start.
Consider a customer churn model moving from idea to retirement. At design, the business owner states the decision it will drive, and then the tier is set. During validation, an independent reviewer reruns the main tests. Finally, at deployment, the platform team confirms that the approved version is the one serving traffic.
| Stage | Gate | Evidence | Owner |
|---|---|---|---|
| Design | Use case and tier approved before work starts | Problem statement, tier rating, data sources | Business owner and governance lead |
| Develop | Data and features fit for purpose | Lineage record, data quality report, experiment log | Data science team |
| Validate | Independent review passed before launch | Validation report, model card, fairness results | Validator or second-line risk |
| Deploy | Approved version matches production | Registry version, alias, deployment record | ML platform team |
| Monitor | Metrics stay inside thresholds | Drift, performance and fairness reports | Model owner |
| Change | Material change re-approved before release | Change log, comparison with the prior version | Model owner and validator |
| Retire | Model removed once a successor is live | Decommission record, archived artifacts | Model owner |
The change gate is the one teams skip most often. A retrain on fresh data can shift behavior as much as a new algorithm. So the program needs a clear definition of a material change for each tier.
The deploy gate deserves equal care, because it is where a governed model meets the release pipeline. Our note on ML model deployment explains how those pipelines usually work.
Monitoring Drift and Bias: Metrics That Trigger Action
A model starts going stale on the day it ships, because the world it learned from keeps moving. Monitoring exists to notice that change early and route it to someone who can act.
Three kinds of change matter. Data drift means the inputs look different from the training data, such as a new mix of applicant incomes. Concept drift means the link between inputs and outcomes has changed. Fairness drift means outcomes for one group are slipping relative to others.
Each kind has standard tests. The Population Stability Index (PSI) and the Kolmogorov-Smirnov (KS) test compare a feature’s current distribution with its training baseline. Performance decay is measured on labeled samples with the usual model evaluation metrics.
Labels often arrive weeks late, which makes concept drift the hardest kind to catch. When labels are scarce, some teams use semi-supervised learning to stretch the few they have.
| Drift type | What it means | Common methods | What to watch |
|---|---|---|---|
| Data drift | Inputs no longer resemble training data | PSI and KS test per feature | Shifts in major inputs such as income or region |
| Concept or performance drift | The same inputs now lead to different outcomes | Metric decay against a labeled baseline | Accuracy, AUC or error rate once new labels arrive |
| Fairness drift | Outcomes differ across groups | Four-fifths rule and equal opportunity gaps | Approval and error rates by group |
Drift Thresholds and Monitor Setup
A test only triggers action once it has a number attached. Databricks publishes a common rule of thumb for PSI in its data profiling metric tables. Below 0.1 means no significant population change, and 0.1 to 0.2 is moderate. A PSI of 0.2 or more signals significant change. Treat these bands as a starting point that the validator adjusts by tier, since they are a convention and not a regulatory limit.
The monitor around those numbers matters just as much, and Azure Machine Learning model monitoring shows what a complete setup covers. It compares model inputs with training data to detect data drift, and model outputs with validation data to detect prediction drift. Each signal offers metrics such as PSI, Jensen-Shannon distance and the two-sample KS test, each with its own threshold. Microsoft suggests a daily schedule for high-traffic models and a weekly or monthly one where data builds up slowly. When a threshold is crossed, the run sends an alert, and Azure Event Grid can route that event to a ticket or a retraining job.
Fairness Checks and the Four-Fifths Rule
On fairness, US teams usually start with the four-fifths rule from the federal employee selection guidelines. Under 29 CFR 1607.4(D), a group’s selection rate below four-fifths (80%) of the top group’s rate is generally evidence of adverse impact.
It is a screen rather than a verdict, so it pairs well with error-rate gaps such as equal opportunity and equalized odds. Thresholds still belong to the validator, though. A PSI level that alarms a high-tier credit model may be noise for a low-tier recommender, so set limits per tier.
What Happens When a Metric Breaches Its Limit
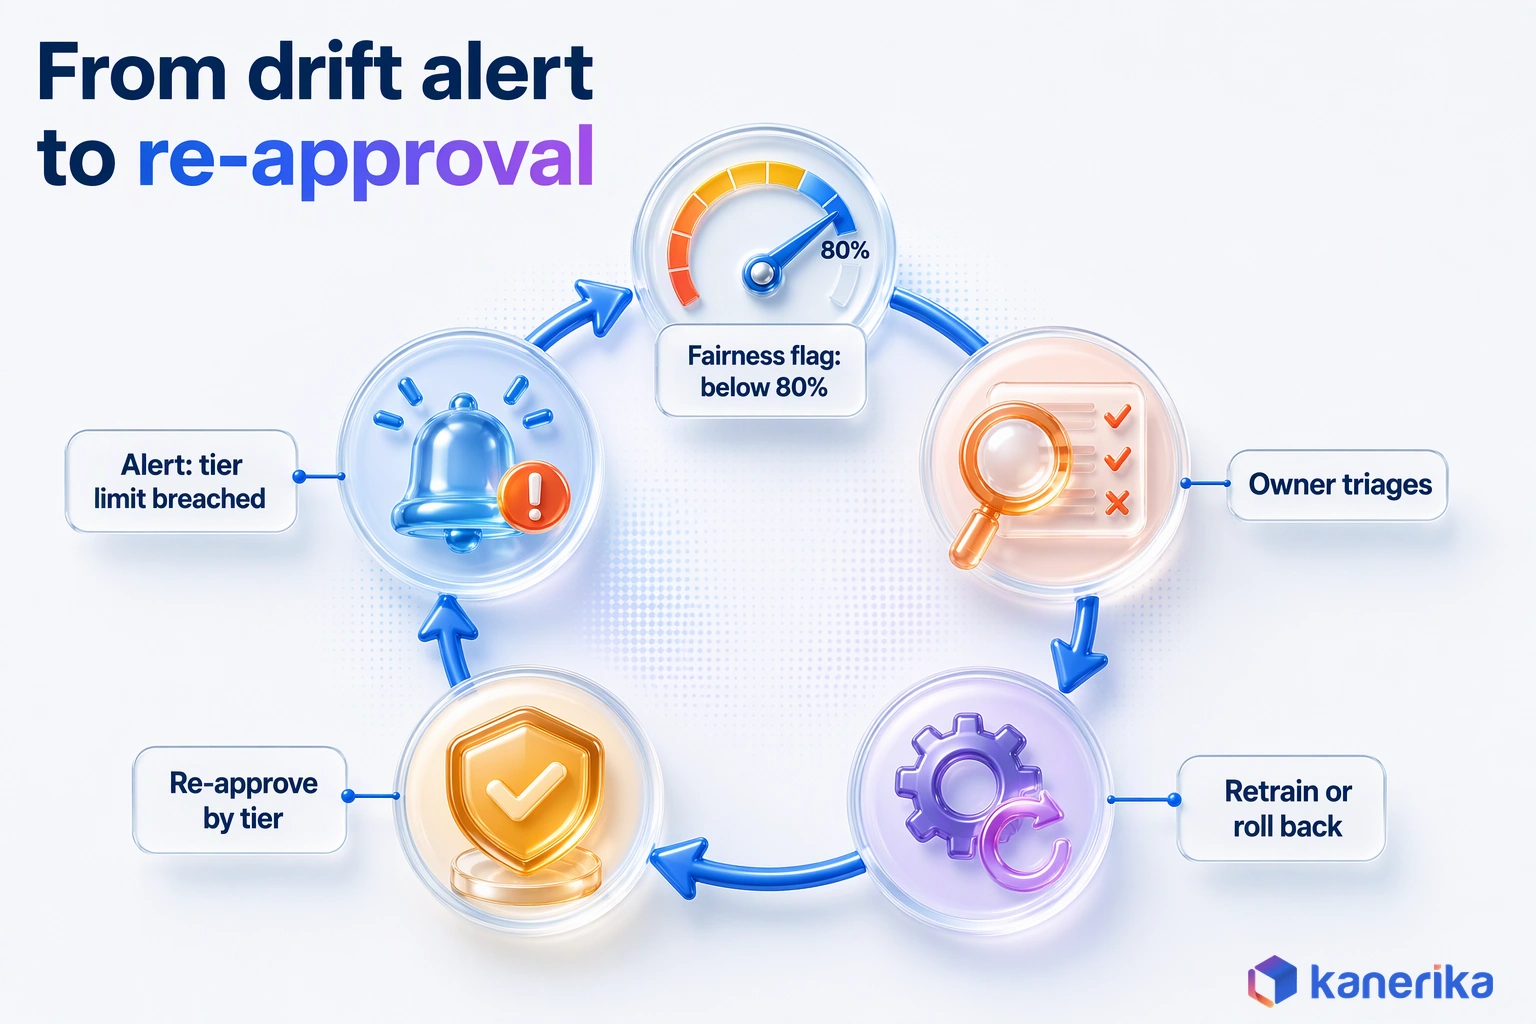
When a metric breaches its limit, the response should follow a fixed path:
- First, the monitoring job raises an alert with the metric, the threshold and the affected segment.
- Next, the named model owner triages it within an agreed window and decides whether the breach is real.
- Then the owner picks a response, such as a retrain on recent data, a rollback or a temporary override.
- Finally, the change goes back through approval at its tier’s depth, and the record closes with evidence.
Written down this way, the path removes the most common failure in monitoring, which is an alert that everyone sees and nobody owns.
Choosing an Operating Model: Centralized, Federated or Hybrid
Someone has to set the rules, and someone has to apply them to each model. How you split those two jobs is the operating model, and it shapes speed and control more than any tool choice does.
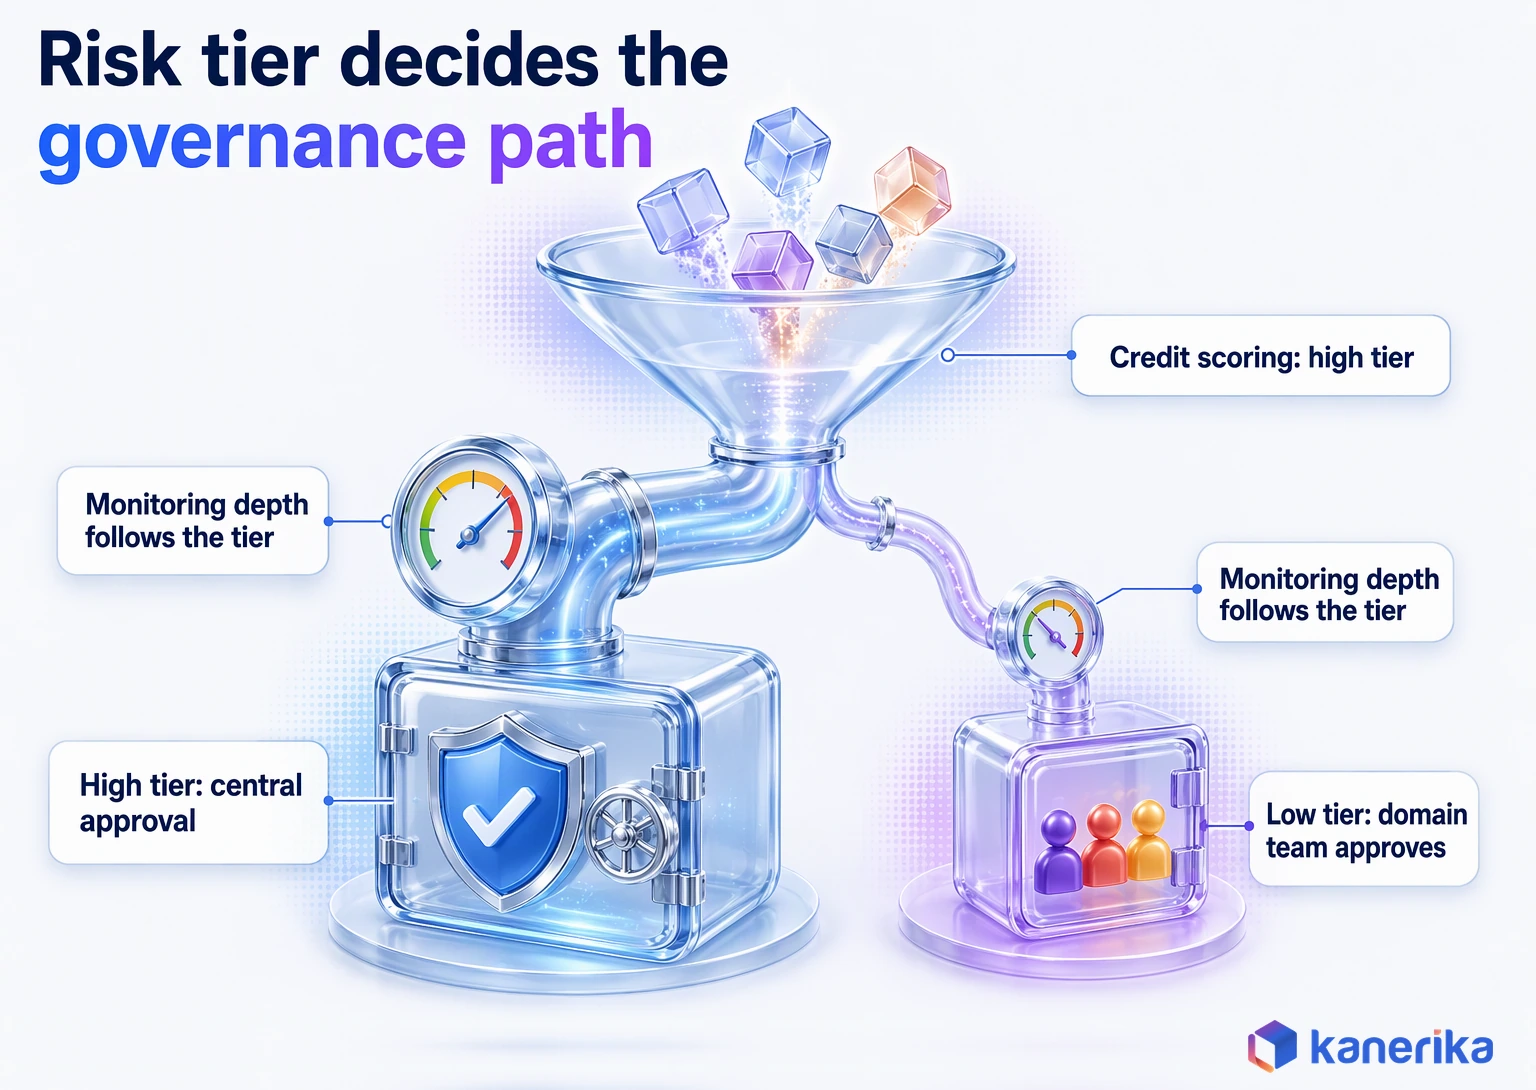
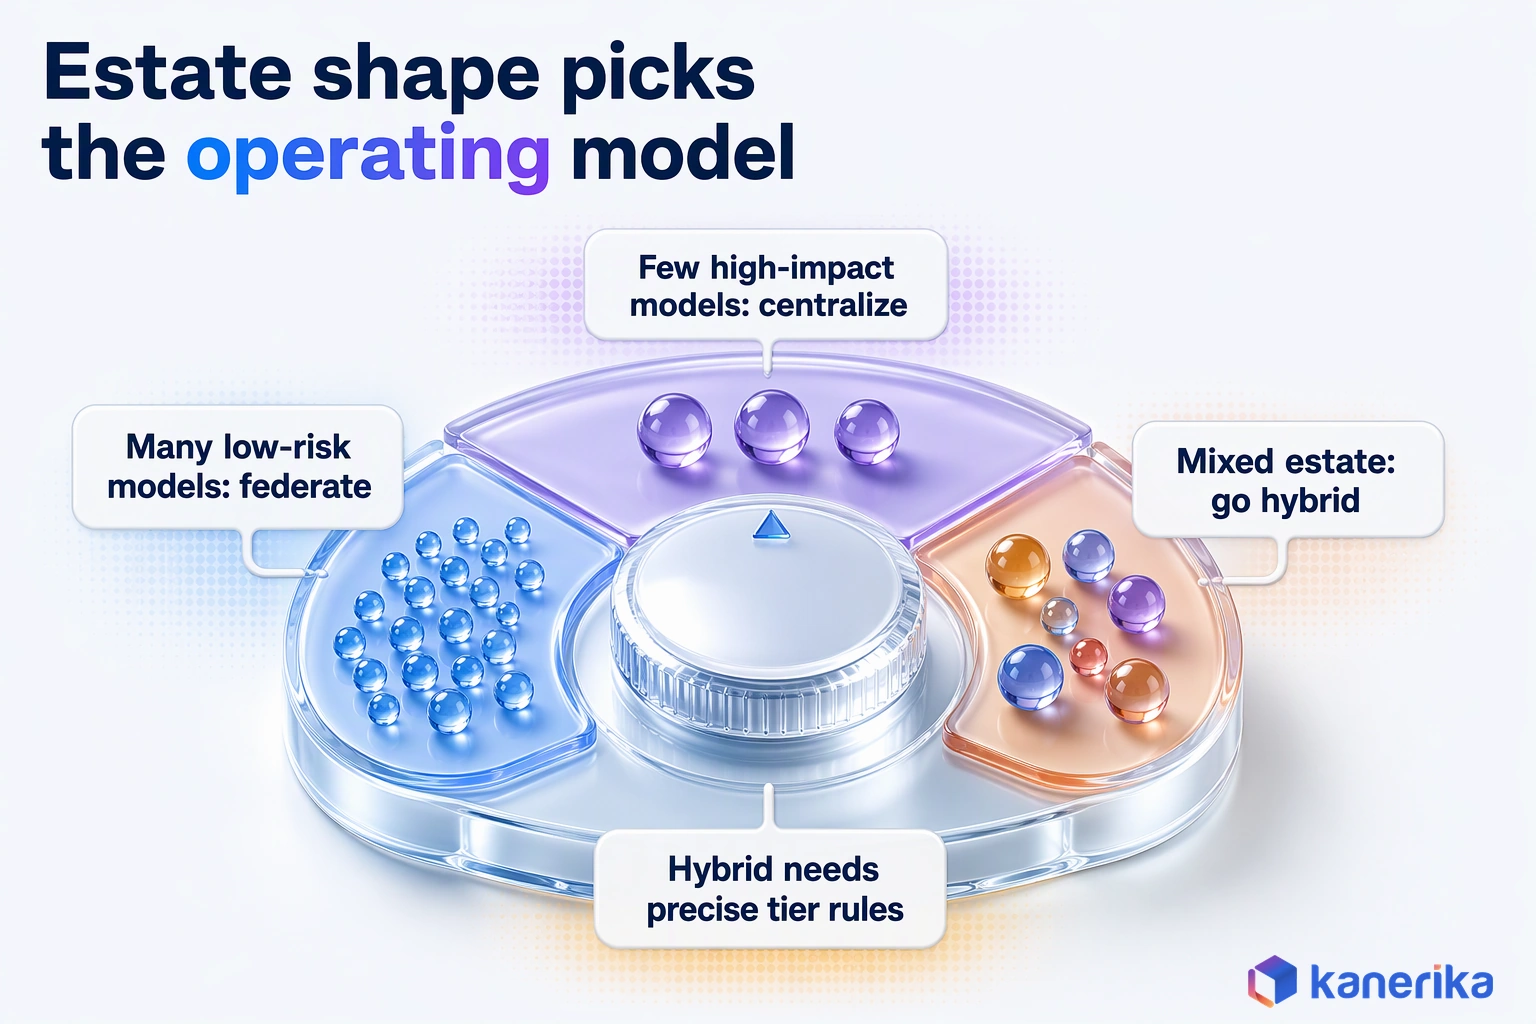
In a centralized model, one team writes policy and approves every model. A federated model lets each business unit govern its own models against a light common standard. A hybrid keeps policy and high-tier approvals central, while domain teams run daily monitoring and approve low-tier models themselves.
| Operating model | Who approves | Fits when | Main risk |
|---|---|---|---|
| Centralized | Central team, for every model | Few models, high impact and heavy regulation | A bottleneck once model count grows |
| Federated | Each business unit, under a light shared standard | Many low-risk models and strong local teams | Inconsistent evidence across units |
| Hybrid | Central team for high tier, domains for low tier | Mixed estates, which describes most enterprises | Fails unless tier rules are precise |
Decision Framework: Which Operating Model to Pick
Pick by the shape of your model estate rather than by org chart preference. Three common situations point to three different answers.
- Regulated lender with a few high-impact models: centralize. Every model touches credit or capital, so a single expert approval path is worth the slower pace.
- Product-led company with many low-risk models: federate. Ranking models change weekly, and so a central queue would stall them for little reduction in risk.
- Most enterprises, with a mix of both: go hybrid. Central policy keeps high-risk models tight, while domain teams run monitoring and ship low-tier changes on their own.
The hybrid only works when tier rules are precise. If teams can argue a model down a tier to skip review, the central team loses control without noticing.
A quarterly sample of low-tier approvals, checked by the central team, keeps everyone honest. It costs a few hours and also catches tier creep before it becomes a pattern.
Mapping ML Controls to Regulations and Standards
Regulations rarely name ML controls directly, but they all ask for the same underlying evidence. Mapping each rule to the seven components therefore lets one body of evidence answer several regulators at once.
| Framework | What it asks for | Components that cover it |
|---|---|---|
| EU AI Act, high-risk systems | Risk management, logging for traceability, human oversight, post-market monitoring | Tiering, audit evidence, explainability, monitoring |
| SR 26-2 and OCC Bulletin 2026-13 | Sound development, validation and governance of bank models | Inventory, validation, documentation, change gate |
| NIST AI RMF 1.0 and NIST AI 600-1 | Voluntary risk practices, together with a profile for generative AI | All seven, used as a reference structure |
| ISO/IEC 42001:2023 | A certifiable AI management system | Policy, roles, inventory, audit evidence |
| Four-fifths rule, 29 CFR 1607.4(D) | A screen for adverse impact in selection decisions | Bias monitoring |
The NIST AI Risk Management Framework, released on January 26, 2023, is voluntary, but many US firms use its structure as a policy skeleton. Its Generative AI Profile, NIST AI 600-1 from July 26, 2024, also extends the approach to large language models. ISO/IEC 42001 then adds what NIST lacks, which is a management system that an external auditor can certify.
Which Controls Matter Most by Industry
The same seven controls apply everywhere, but a bank and a hospital will lean on different ones first, as the table below shows.
| Industry | Typical high-tier models | Controls to emphasize |
|---|---|---|
| Banking | Credit scoring, fraud and capital models | Validation depth, change gate, SR 26-2 documentation |
| Insurance | Pricing and claims triage | Explainability and fairness checks across groups |
| Healthcare | Patient triage and risk scoring | Training data lineage, human oversight, privacy controls |
| HR and hiring | Candidate screening and ranking | Four-fifths screen, EU Annex III high-risk duties |
| Security and public safety | Biometric identification | Human oversight and logging, especially under EU rules |
Biometric systems deserve a special mention, since the EU lists biometrics among its high-risk areas. Our guide to AI surveillance covers how those systems are built and checked.
Worked Example: Governing a Credit Risk Model End to End
A single model shows how the pieces fit together. Take a credit scoring model at a US bank that also lends to customers in the EU, and follow it from tiering to retirement.
- Tiering. The model decides who gets credit, so it is high tier. Credit scoring is an Annex III high-risk use, and the model also falls under SR 26-2.
- Documentation. The team writes a model card with intended use, data sources and known limits. Lineage then links each feature to its source table.
- Validation. An independent validator reruns performance tests and checks stability over time. Any group approved below 80% of the top group’s rate goes back for review before launch.
- Deployment. The approved version is registered and given a production alias, so the record shows which version serves traffic.
- Monitoring. A weekly PSI job tracks the applicant income mix, while a monthly job checks approval rates by group.
- Drift alert. When a new partner channel changes the income mix, the PSI job breaches its tier limit. The owner confirms the shift and opens a change ticket.
- Retrain and re-approval. The team retrains on recent applications, and then the validator compares the old and new versions before sign-off.
- Retirement. Finally, the old version loses its production alias, its artifacts are archived, and a decommission record closes the loop.
What the Example Shows
No step here is exotic. The value comes from doing all eight in order, with evidence saved at each one, so the next audit is a file pull rather than a scramble.
This is exactly the program that would have caught the drifting lender in the opening story. The drift job would have fired, and the owner would have acted. The fairness check would also have shown the slipping approval rate long before a complaint arrived.
Talk to Kanerika
Want This Lifecycle Running on Your Models?
Kanerika can walk one of your high-tier models through tiering, validation, monitoring and re-approval, and show where your current evidence falls short.
Schedule a Demo →Tools That Support ML Governance, by Control
No single product covers every machine learning governance control, so most teams assemble a stack from tools they already own. The useful question is which control each tool covers, rather than which tool is best.
| Control | Example tools | What to check |
|---|---|---|
| Inventory and registry | MLflow Model Registry, Models in Unity Catalog, and cloud registries such as Azure Machine Learning and Amazon SageMaker | Versioning, aliases, tags and discovery across workspaces |
| Lineage | Unity Catalog lineage, Microsoft Fabric OneLake catalog (Purview Data Governance retires Nov 2027) | Coverage from source tables through features to models |
| Access and audit | Unity Catalog permissions, cloud IAM, Microsoft Purview | Who can approve and deploy, and whether each action is logged |
| Monitoring | Databricks data profiling, Azure Machine Learning model monitoring, Amazon SageMaker Model Monitor (no longer open to new customers) | Drift tests per feature, fairness metrics and alert routing |
| Documentation | Model cards stored with the registry version | The card stays tied to the exact version in production |
The MLflow Model Registry records lineage and versions. It also lets teams attach aliases such as @champion, tags and annotations. Models in Unity Catalog hosts that registry with centralized access control, auditing, lineage and discovery across workspaces, and Databricks recommends it.
For a side-by-side view of registry options, see our comparison of MLflow Model Registry, Hugging Face Hub and Azure ML. Tags also make approval state visible in the registry itself, as this short MLflow example shows.
from mlflow import MlflowClient

client = MlflowClient()

# record the governance decision on the exact version
client.set_model_version_tag("credit_risk", "7", "risk_tier", "high")
client.set_model_version_tag("credit_risk", "7", "validation_status", "approved")

# point production at the approved version only
client.set_registered_model_alias("credit_risk", "champion", "7")
Should you build or buy? Teams with a strong platform group can cover most controls with the registry, lineage and job tooling they already run. A dedicated governance product makes more sense when model counts are high, several platforms are in play, or regulators expect one system of record.
Kanerika Service
MLOps Consulting
Kanerika builds the registries, monitoring, alerting and pipeline gates that make model governance part of how models ship, on the platforms your teams already run.
Explore MLOps ConsultingEffort and Measuring Whether Governance Works
Governance effort depends far more on your starting point than on any vendor price list. Three factors drive it, namely how many models you run, how many sit in the high tier, and whether a registry already exists.
A team with a working registry and lineage mostly adds policy, tiering and an approval workflow. A team whose models sit scattered across notebooks spends its first phase just finding them. That discovery step is often the largest single cost, although it also pays off fastest.
An illustrative example shows the gap. The phase lengths here are planning assumptions, not benchmarks. Picture an estate of 20 models, four of them in the high tier. With a registry in place, inventory takes about two weeks and tiering and policy about three. Wiring approvals and monitors adds about four more, so the program runs roughly nine weeks.
Without a registry, the same estate starts with about six weeks of discovery across notebooks and jobs. Building the registry adds another four weeks before tiering (three) and approvals and monitors (four) can begin. That puts the same program near 17 weeks, almost double, which is why a registry is usually the first purchase or build.
Measuring Whether Governance Works
Measure the program like any other operation. In practice, that means picking a few numbers, reporting them monthly and watching the trend.
| KPI | What it shows | Healthy direction |
|---|---|---|
| Share of production models in the inventory | Coverage of the program | Toward 100% |
| Median days to approve, by tier | Whether governance slows delivery | Down for low tier, stable for high tier |
| Drift alerts closed within SLA | Whether monitoring leads to action | Up |
| Models with current documentation | Quality of evidence | Up |
| Open audit findings on models | Overall control health | Down |
The approval-time KPI matters most for adoption. If low-tier approvals take as long as high-tier ones, teams will route around the process. Shadow models will appear outside the registry.
Report these numbers to the same committee that owns model risk. A short monthly page keeps governance visible to leaders, so it never turns into a reporting project of its own.
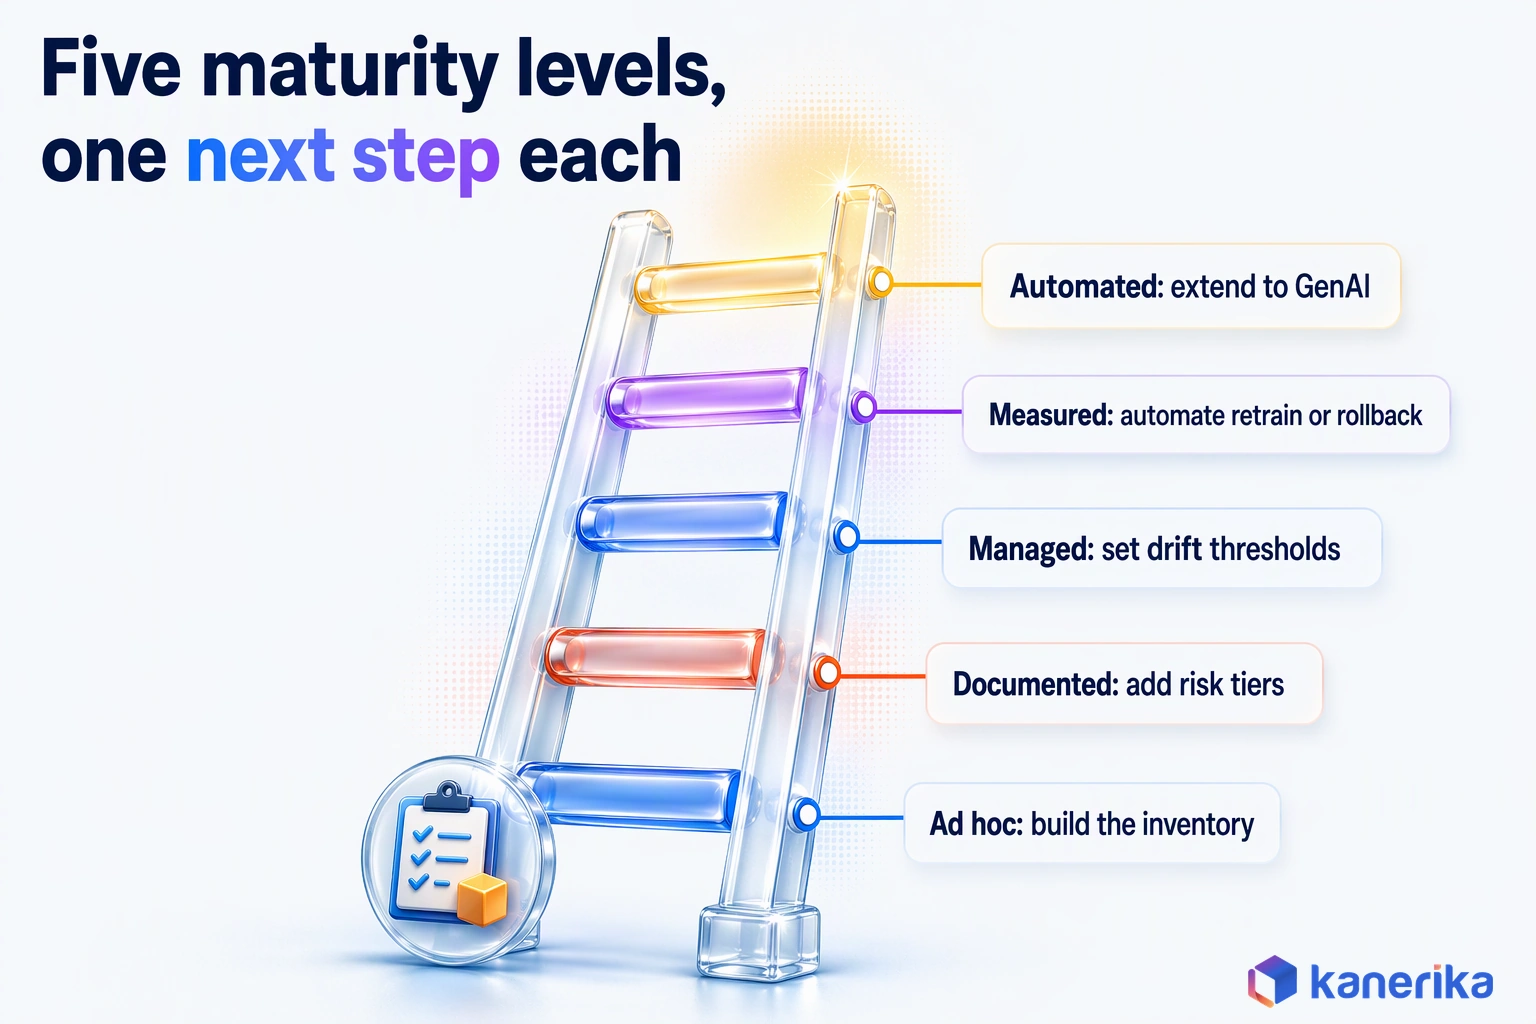
ML Governance Maturity Model
A machine learning governance maturity model helps you see where you are and pick the next step, rather than grade yourself. Since most organizations sit at different levels for different controls, score each component on its own.
| Level | Signs | Next step |
|---|---|---|
| 1. Ad hoc | Models live in notebooks, so nobody can list what runs in production | Build the inventory |
| 2. Documented | An inventory and model cards exist, but approvals are informal | Add risk tiers and a sign-off path |
| 3. Managed | Tiered approvals and a registry exist, while monitoring is partial | Add drift and fairness thresholds with owners |
| 4. Measured | KPIs are reported, and alerts route to owners | Tie alerts to retrain or rollback workflows |
| 5. Automated | Gates, evidence and monitoring run inside the pipeline | Extend the program to GenAI and agents |
Where to start depends on your lowest level:
- When you cannot list your production models, spend the first weeks on the inventory and nothing else.
- Once the inventory exists, write a one-page tiering rubric and apply it to every model.
- After tiers exist, pick your three highest-tier models and give each a drift threshold, a fairness check and an owner.
For a wider view of AI capability beyond governance, the AI maturity model also covers data, talent and strategy. Data readiness has its own scale in our data governance maturity model, which pairs well with this one.
Governing Generative AI Models in the Same Program
Large language models and agents now share the estate with classic models, so they need a place in the same program. The tools differ, but the questions of inventory, tiering, evidence and ownership stay the same.
Banks should note a gap here. The OCC says generative AI and agentic models are not within the scope of the new guidance, so firms have to set their own controls for them. NIST AI 600-1 is the natural reference for doing so.
In practice, GenAI governance adds three controls to the seven above. Evaluation sets replace a single accuracy number, because answers need testing for accuracy, safety and refusal behavior. Prompt and output logging then gives the audit trail that a scoring model gets from its registry.
Third-party model review is the third addition. It checks a vendor’s terms, data handling and update cadence, since a hosted model can change underneath you.
The same tiering logic applies to assistants and agents. An internal summarizer is low tier, while an agent that can approve refunds or change records is high tier. Teams adopting AI automation tools should therefore add each one to the inventory before it reaches production.
Release rules for LLMs and agents are covered in the model risk management guide, while attack testing sits in our LLM security guide.
Common Machine Learning Governance Mistakes
Programs rarely fail for lack of policy. Instead, they fail on a handful of predictable mistakes, and each one has a simple fix.
- Paperwork before inventory. Teams write a long policy before they know which models exist. Start with the list, because policy is easier to write once you can see the estate.
- One approval path for every tier. A recommender then waits in the same queue as a credit model. Tiered paths keep scrutiny where the risk is real.
- No owner per model. Alerts land in a shared inbox, so nobody acts. Every model needs one named, accountable person.
- Monitoring without action triggers. Dashboards show drift, but nothing happens next. Each metric needs a threshold and a predefined response.
- Shadow models outside the registry. A team deploys from a notebook to meet a deadline. Make the registry the only path to production, even for small models.
- Fairness checked once at launch. Group outcomes shift as the population shifts. Schedule fairness checks on the same cadence as drift checks.
Most of these mistakes share one root cause, which is governance designed on paper and never tested on a real model. Running one high-tier model through the full lifecycle early exposes the gaps fast.
Datasheet
Elevate Data Governance, Compliance and Security
A Kanerika datasheet on the governance, compliance and security capabilities that keep the data behind your models trusted and audit-ready.
View the Datasheet →How Kanerika Delivers ML Governance in Stages
Kanerika builds machine learning governance as a sequence of working stages, so each one leaves something usable behind. The aim is a program your teams run themselves, rather than a binder of policies.
- Assess and inventory. We find every model in production and development, record its owner and purpose, and score maturity by component.
- Tiering and policy. We agree a tiering rubric, approval paths and evidence rules, mapped to the regulations your exposure requires.
- Registry, lineage and monitoring build. We implement the controls on platforms you already run, such as Microsoft Purview, the Microsoft Fabric OneLake catalog, Unity Catalog and MLflow.
- Run and transfer. We operate the program alongside your team for the first cycles, and hand over runbooks and KPIs.
The work draws on our AI governance services for policy and oversight, as well as MLOps consulting for monitoring and pipeline gates. On the data side, our data governance practice runs KANGovern, KANGuard and KANComply on Purview and Unity Catalog. KANComply alone covers more than 360 regulations and frameworks.
For the model layer itself, Kanerika builds and runs an AI governance agent on the client’s own cloud. It keeps a live inventory in which every model and agent has an owner and a risk tier. Internal policy maps to frameworks such as NIST AI RMF and ISO/IEC 42001. A material change to a model triggers re-assessment automatically, so an old approval does not cover a new version. Every control status also links to the artifact behind it, such as a test result, an access review or an approval.
Case Study: One Governed Definition Layer for AI
Governed definitions are the foundation that AI depends on, and one project shows why. A global pharmaceutical enterprise kept KPI definitions inside separate Power BI dashboards. The same metric returned different numbers depending on who ran the report.
Kanerika built a governed business ontology on Microsoft Fabric, connected to governed data in OneLake and extended to Fabric AI and Copilot. The client cut manual investigation and reconciliation time by 70% and standardized more than 85 KPIs across Power BI.
The project governed definitions rather than models. Even so, it solved the problem ML governance starts with, because every report and AI query now draws on the same trusted definitions.
Case Study
70% Less Investigation Time with One Governed Ontology on Fabric
A global pharmaceutical enterprise moved KPI definitions out of individual dashboards into a governed ontology on Microsoft Fabric, standardizing 85+ KPIs and cutting investigation and reconciliation time by 70%.
Read the Case Study →Making Machine Learning Governance Routine
Machine learning governance works when it is part of how models ship, rather than a review bolted on at the end. Start with an inventory and risk tiers, and then attach drift and fairness triggers to named owners. Map the evidence once to SR 26-2, the EU AI Act, NIST and ISO/IEC 42001. Choose a hybrid operating model unless your estate is clearly all high risk or all low risk. Do that, and risk, drift and bias become routine controls rather than surprises found by a regulator.
Frequently Asked Questions
What is machine learning governance?
Machine learning governance is the set of policies, roles, controls and evidence that decide which ML models reach production, how they are monitored once live, and when they are changed or retired. It scales scrutiny to risk, so a credit scoring model gets deep validation while a low-impact recommender moves through a lighter, faster approval path.
How is ML governance different from MLOps?
MLOps is the engineering practice of building, deploying and running model pipelines reliably. ML governance decides whether a model should run at all and under what conditions, through inventory, risk tiers, approvals and evidence. MLOps supplies the plumbing, such as registries and monitoring jobs, that makes governance cheap to run, so the two work best together.
How do you govern generative AI and LLM models?
Put every assistant, agent and hosted model in the same inventory and tier it by what it can do. Add evaluation sets for accuracy, safety and refusals, log prompts and outputs, and review third-party models for terms and update cadence. US bank guidance excludes generative and agentic models, so NIST AI 600-1 is the usual reference.
What tools are used for ML model governance?
Most teams combine tools they already run. MLflow Model Registry or Models in Unity Catalog handle versions, aliases and tags, while Unity Catalog and Microsoft Purview cover lineage and access auditing. Monitoring jobs run drift and fairness tests, and model cards sit beside each registered version. Dedicated governance products suit large, multi-platform model estates.
How long does it take to set up an ML governance program?
Timing depends on scope rather than a fixed schedule. The biggest variables are how many models you run, how many are high tier, and whether a registry and lineage already exist. Teams with those foundations mostly add policy, tiering and approvals, while teams with scattered notebook models must first spend time building the inventory.
What regulations apply to machine learning models in 2026?
US banks follow SR 26-2 and OCC Bulletin 2026-13, issued on April 17, 2026, which replaced SR 11-7. The EU AI Act became applicable on August 2, 2026, with exceptions, and Annex III high-risk duties start on December 2, 2027. Hiring models also face the four-fifths adverse impact screen, and many firms adopt NIST AI RMF or ISO/IEC 42001.
What is model drift and why does it matter for governance?
Model drift is the gradual mismatch between the world a model learned from and the world it now serves. Data drift changes the inputs, concept drift changes how inputs relate to outcomes, and fairness drift shifts results between groups. Governance matters because drift is silent, so only thresholds with named owners turn it into timely action.
What are the core components of an ML governance program?
A complete program has seven components: a model inventory and registry, risk tiering, training data lineage and quality, validation and documentation through model cards, explainability, bias and drift monitoring, and access control with audit evidence. Build them roughly in that order, because tiering, monitoring and audits all depend on first knowing which models exist.
How do you implement ML governance without slowing down development teams?
Tier every model so low-risk work follows a light path while high-risk models get full review. Publish the evidence each gate needs before teams start, automate checks inside the pipeline, and let domain teams approve low-tier changes. Track median approval days by tier, and fix the process quickly if low-tier approvals start dragging behind.
What does the EU AI Act mean for machine learning models?
The EU AI Act sorts AI systems by risk. Models used for credit scoring, employment or biometrics fall under Annex III high-risk rules, which apply from December 2, 2027 after the AI Omnibus. They need risk management, logging for traceability, human oversight and post-market monitoring, which map directly to tiering, audit evidence and monitoring controls.
What is a model registry and why is it essential for governance?
A model registry is the system of record for trained models, holding each version with its lineage, tags, aliases and status. It is essential because governance controls attach to specific versions. Approvals, model cards and monitoring results only mean something when everyone can confirm which exact version is serving production traffic at any moment.
How do you detect model drift in production?
Compare live inputs with the training baseline using the Population Stability Index or the Kolmogorov-Smirnov test for each important feature. Track accuracy or error on labeled samples to catch performance decay, and compare approval or error rates across groups for fairness. Set thresholds per risk tier, and route every breach to a named model owner.
Who owns machine learning governance in an organization?
Ownership is shared but clearly split. A central governance lead, often within risk or the data office, sets policy and the tiering rubric. Independent validators review high-tier models, and each model has one named business or technical owner who answers alerts. In a hybrid setup, domain teams also approve their own low-tier models.