TL;DR
The best predictive analytics tools for enterprise teams follow your cloud: Azure Machine Learning, Gemini Enterprise Agent Platform or Amazon SageMaker AI. Lakehouse teams should start with Databricks. Mixed teams of analysts and data scientists fit Dataiku or DataRobot. Analyst-led teams fit Alteryx One or KNIME, and tight budgets can start free with KNIME or H2O-3. Regulated teams should rank governance first and test SAS Viya or DataRobot. Whatever the list, drop tools that fail a hard gate, then pilot the rest on your own data.
Key Takeaways
- Your cloud picks the first shortlist: Azure Machine Learning, Gemini Enterprise Agent Platform (formerly Vertex AI) or Amazon SageMaker AI.
- Databricks suits lakehouse teams, Dataiku and DataRobot suit mixed-skill teams, and Alteryx One and KNIME suit analyst-led teams.
- Free tools such as KNIME and H2O-3 remove the license fee, but hosting, security, monitoring and people still cost money.
- Choose with hard gates, a weighted scorecard and a pilot on your own data, never with a vendor demo.
- Count the full cost to run, because compute, storage, monitoring and people can outweigh the license or subscription.
- A model without a drift owner and a retrain trigger loses accuracy quietly, so plan monitoring before you buy.
A Forecast Nobody Acts On
On a Monday morning, a demand planner at a packaging plant opens her dashboard and finds a new quarterly forecast. It looks sharp, with confidence bands and a clean trend line. The number never reaches the order system, though, so she copies it into a spreadsheet, adjusts it on instinct and places orders the old way.
Six weeks later, nobody can say whether the model helped. The forecast lived in a chart, so no one compared it with what actually shipped.
That gap is where predictive analytics tools differ most. Almost any of them can train a decent model on clean history. The harder test is whether a tool puts predictions into the systems where decisions happen. It also has to keep them accurate as data shifts, and your own team has to be able to run it.
What Predictive Analytics Tools Do (and Where BI Stops)
Predictive analytics tools are software platforms that use machine learning and statistics to learn patterns from historical data, then use them to estimate what happens next. For example, typical questions are which customer will churn, how many units will sell next month or which invoice will be paid late. If you want the ideas and use cases behind this, our guide to predictive AI covers them; this post stays on choosing the software.
Three kinds of product get sold under the same label, so buyers often mix them up. Business intelligence tools show what happened, and diagnostic analytics explains why it happened. Most BI suites also include a forecast option that extends a trend line on a chart. That is useful for a quick look, but it is rarely enough for a decision that runs every day.
A predictive modeling platform, by comparison, goes further. It handles many input drivers at once and tests several algorithms against each other. Then it publishes the winning model as a service and watches it after launch. AI assistants are the third group. They answer questions about data in plain language, yet they do not train or govern a forecasting model on their own.
Forecast Features in BI Suites and AI Copilots
If your team already lives in a BI suite, it is worth knowing what the built-in features can do before you buy a platform. In Power BI, the Analytics pane adds a Forecast option to line charts, where you set the forecast length and confidence interval. Tableau’s forecast uses exponential smoothing, and its forecasting guide says it needs at least five data points to estimate a trend.
Qlik goes a step further. Qlik Predict is a no-code machine learning product for classification, value prediction and time series forecasting, with SHAP-based explanations of results. So Qlik shops can test it before adding a separate tool.
Generative AI copilots work on a different layer. Copilot in Power BI summarizes reports, answers questions about a semantic model and writes DAX queries. It needs paid Fabric capacity (F2 or higher) or Power BI Premium (P1 or higher). A copilot explains the data you have, while a predictive platform trains, deploys and monitors the model that scores what comes next.
The Five-Step Loop Behind Every Platform
Every serious platform in this guide supports the same five-step loop, although the steps after the model are where projects usually stall:
- Data: collect clean, dated history for the outcome you want to predict.
- Features: turn raw fields into model inputs through feature engineering, such as order frequency or days since last purchase.
- Model: train and compare candidate models against a simple baseline, using the methods covered in our guide to machine learning in predictive analytics.
- Deploy: publish the model so an application, report or workflow can call it.
- Monitor and retrain: track accuracy and input drift, then retrain when performance slips.
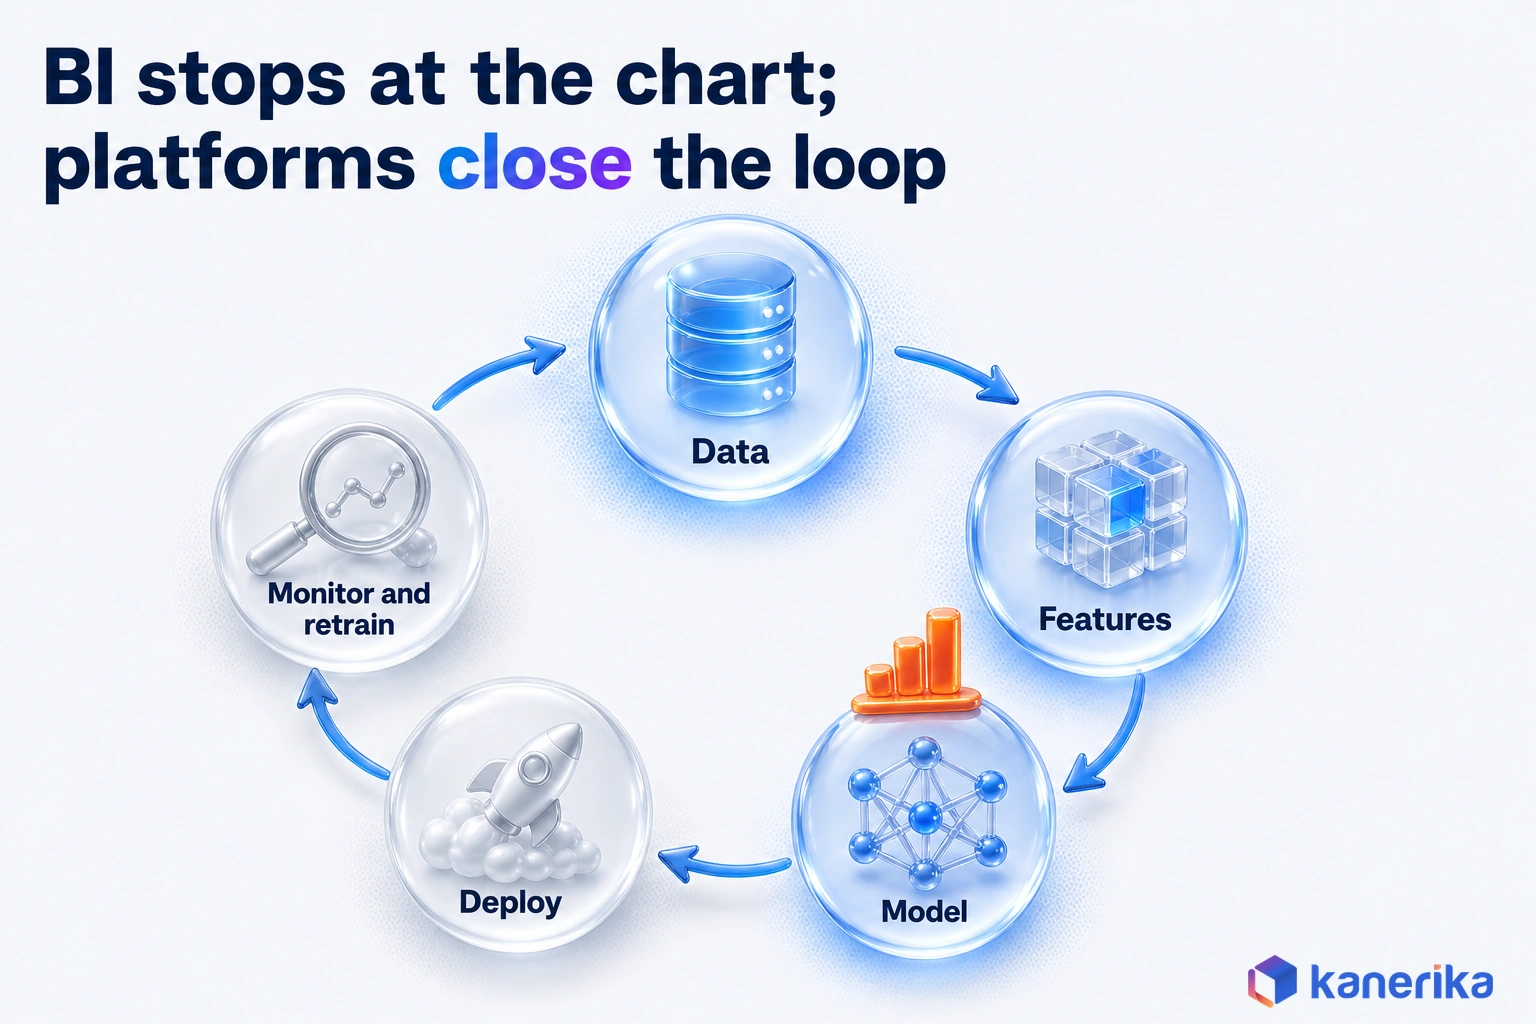
When that loop runs well, three benefits follow. Decisions move earlier because the forecast arrives before the problem does. Planners also stop rebuilding the same spreadsheet each week, and every region gets scored by the same rules instead of by local habit.
How We Evaluated These Tools
We judged each platform on the work an enterprise team has to do after the purchase, rather than on the length of its feature list. Vendor facts in this guide come from each vendor’s own product pages and documentation, checked on November 10, 2026. We did not run benchmark tests, so treat the verdicts as a starting shortlist, not a ranking.
Six criteria shaped every entry:
- Data-stack fit: does the tool sit close to where your data already lives, or does every training run start with a copy job?
- AutoML and modeling depth: can analysts get a baseline model quickly, and can data scientists still write custom code when they need to?
- Deployment and MLOps: can a model move from notebook to a scheduled or real-time service without a rebuild?
- Governance and explainability: are there a model registry, lineage, access control and per-prediction explanations for regulated decisions?
- Skills required: who on your team can use it on day one, and who has to be hired or trained?
- Pricing model: is it a subscription, a consumption bill for compute or a free license with self-hosting costs?
Two examples show how the criteria shaped the entries. On AutoML and modeling depth, Databricks is listed as code-first because its documentation states that AutoML is not built into Runtime 18.0 ML and above. On pricing, Azure Machine Learning reads as “no service fee” in the table, since Microsoft bills only for compute and supporting services.
The weight of each criterion changes with your situation, so the framework later in this guide turns them into a scorecard. A bank will weight governance far more heavily than a retailer testing its first demand model.
Best Predictive Analytics Tools at a Glance
Where a tool runs and how it is priced usually settle the shortlist before features do. Read those two columns first.
| Tool | Best for | Modeling style | Where it runs | Pricing model | Watch-out |
|---|---|---|---|---|---|
| Azure Machine Learning | Teams on Azure | Code-first, with AutoML | Azure | No service fee; pay for compute and Azure services | Idle compute still bills |
| Gemini Enterprise Agent Platform (formerly Vertex AI) | Google Cloud teams | AutoML and custom training | Google Cloud | Usage-based | Docs and links still mix both names |
| Amazon SageMaker AI and SageMaker Canvas | AWS teams; analysts via Canvas | Code (SageMaker AI) or no-code (Canvas) | AWS | Usage-based | Two products for two skill levels |
| Databricks | Lakehouse teams | Code-first notebooks | Your cloud account | Consumption-based | AutoML not built into Runtime 18.0 ML and above |
| Dataiku | Mixed analyst and data science teams | Visual, low-code and code | Managed or self-run | Subscription, free trial | Cost scales with users |
| DataRobot | Governed AutoML at scale | AutoML-led | Managed or self-run | Enterprise subscription | Broad platform, so check fit for one use case |
| SAS Viya | Regulated, statistics-heavy teams | Visual and code | Managed or self-run | Subscription | Needs SAS skills as well as budget |
| H2O-3 | Data scientists on a budget | Code, with AutoML | Self-hosted | Free (Apache License 2.0) | You run hosting and monitoring |
| Alteryx One | Analyst-led teams | Low-code workflows | Managed or self-run | Subscription | Check MLOps depth before you sign |
| KNIME Analytics Platform | Budget-limited mixed teams | Visual workflows | Desktop or self-hosted | Free and open source | Team scale needs extra setup, so plan it |
| Also consider: IBM SPSS Modeler | SPSS-trained statisticians | Visual, drag-and-drop | Check edition | Commercial | Narrower than full ML platforms |
| Also consider: RapidMiner AI Studio | Visual workflow teams | Visual workflows | Check edition | Commercial | Name and owner changed, so check support |
“Managed or self-run” options vary by edition, so confirm them in your quote, because they differ by contract.
Kanerika Service
Predictive Analytics Services
Kanerika helps enterprise teams shortlist, pilot and deploy predictive analytics tools on their own data, from readiness checks to monitored models in production.
Explore Predictive AnalyticsThe 10 Best Predictive Analytics Tools in 2026
Each entry below follows the same pattern, so you can compare like with like. It covers what the tool is, who it suits, where it is strong, what to watch and how it charges. The order starts with the three cloud platforms, because for most enterprises the cloud you already pay for narrows the field before any feature does.
1. Microsoft Azure Machine Learning
Azure Machine Learning is Microsoft’s managed service for building, training and deploying models on Azure. It suits teams whose data, identity and security controls already live in Azure, since models can be trained and served inside the same tenant.
Its main strength is location. The platform sits next to the rest of the Azure estate, so data does not have to leave the cloud to be scored. Data scientists can work in code, while AutoML gives analysts a fast baseline to beat.
The pricing is the part buyers misread most. According to Microsoft’s Azure Machine Learning pricing page, there is no additional charge for the service itself. You pay for the compute you use plus other Azure services such as Blob Storage, Key Vault, Container Registry and Application Insights. The watch-out follows directly, because a forgotten compute cluster or an oversized endpoint keeps billing whether anyone uses it or not.
A first AutoML job needs only a few settings. Per Microsoft’s AutoML setup guide, you point training_data at an MLTable asset, name the target_column_name and choose a primary_metric. For demand forecasting, the guide suggests normalized_root_mean_squared_error. Set timeout_minutes and max_trials as well, because without them a job can run for six days and try up to 1,000 trials.
2. Google Gemini Enterprise Agent Platform (formerly Vertex AI)
Google renamed Vertex AI in 2026. The Google Cloud release notes state that Vertex AI is now part of Gemini Enterprise Agent Platform. As a result, shortlists and procurement documents should use the new name.
For predictive work, the relevant part is still the tabular machine learning stack. Google’s tabular data documentation covers both AutoML and custom training for tabular data, which is the shape of most churn, demand and risk problems. For teams already running analytics in Google Cloud, it is the natural first pick.
The rename creates a practical risk rather than a technical one. Tutorials, internal wikis and partner material still say “Vertex AI,” so check that any guide your team follows matches the current console and docs.
3. Amazon SageMaker AI and SageMaker Canvas
AWS sells its machine learning platform as Amazon SageMaker AI, with a separate no-code product for business users. SageMaker Canvas lets people build models through a visual interface with no code required.
That split is the reason to shortlist it. Data scientists get a full code platform, while analysts can try a forecast in Canvas without waiting for a data science ticket. For an AWS-first company, both also sit next to the data the team already stores there.
Setting up a Canvas forecast is a form, not a script. According to the Canvas build guide, you pick the target, item ID and timestamp columns, enter a forecast length and can switch on a holiday schedule. A quick build trains one tree-based model, while a standard build combines several algorithms into an ensemble.
Two products also mean two skill paths. So decide early who owns a model that starts in Canvas and later needs production monitoring. Otherwise it falls between the analyst who built it and the engineer who has to run it.
4. Databricks
Databricks is a lakehouse platform where data engineering, analytics and machine learning share one copy of the data. It fits teams that already run Spark pipelines and want models trained where the features are built, which removes a whole class of copy jobs. Our post on the Databricks AI runtime also goes deeper on the compute side.
Its strength is the short path from feature table to model to production job. Teams that already think in notebooks and pipelines therefore move quickly here.
One documented change matters for buyers who expect point-and-click modeling. The Databricks AutoML documentation notes that in Databricks Runtime 18.0 ML or above, AutoML is not included as a built-in library. So treat Databricks as a code-first platform, and staff it with people who write Python or SQL.
5. Dataiku
Dataiku is a collaborative data science platform built for teams where analysts and data scientists work on the same project. Analysts can prepare data and build models visually, while data scientists add code in the same flow. Because of that, a forecast does not have to be rebuilt when it changes hands.
That shared workspace is its main strength, because it removes the handoff problem from the opening story. The person who understands the business and the person who tunes the model see the same pipeline.
Dataiku provides a free trial in a fully managed workspace, which makes a pilot on your own data cheap to start. Cost at scale is the part to test early. Ask how the quote scales as more users join, and model the bill for the whole team, not the pilot group.
6. DataRobot
DataRobot started as an AutoML specialist, and its scope has since widened well beyond AutoML. As of November 2026, its platform page describes coverage of predictive AI, generative AI, agentic AI, AI governance and AI observability.
For predictive teams, the draw is automation with controls around it. It can test many candidate models quickly, and the governance and observability parts give risk teams something concrete to review before a model goes live.
Take a lender whose risk team must approve a new default model before go-live. Instead of a slide deck, the reviewers can inspect the ranked candidate models and their monitoring in the same platform the data scientists used.
Breadth has a cost, though. A company with a single forecasting use case may pay for far more platform than it needs. Price only the modules you will actually use in the first year.
7. SAS Viya
SAS Viya is SAS’s AI and analytics platform. It is worth a close look for regulated teams in banking, insurance or pharma. In those teams, statistical rigor, documentation and audit trails matter as much as accuracy.
Its strength is depth in classical statistics. Teams with existing SAS code and SAS-trained staff can extend what they already have rather than start again.
Consider a bank whose credit-risk scorecard must be signed off by an independent validator. A team with years of SAS code can rebuild that model in Viya. The validator then gets a documented, traceable model in the form the review expects.
Skills and cost cut the other way. Hiring for SAS is narrower than hiring for Python, and the subscription is a real budget line. So compare it against a cloud platform plus governance tooling before you renew by default.
AI Assessment
Is Your Team Ready for a Predictive Pilot?
Score your data, governance and skills in a few minutes and see where your organization stands before you shortlist a platform.
Start Your AI Assessment →8. H2O.ai (H2O-3)
H2O-3 is an open source, in-memory, distributed machine learning platform released under the Apache License 2.0. It includes AutoML along with standard algorithms such as generalized linear models, random forests and deep learning.
It suits data scientists who want strong tabular modeling without a license fee. In practice, that means people comfortable in Python or R. AutoML gives a fast leaderboard of candidate models, and the distributed engine handles larger datasets than a single laptop library.
The setup is short. The H2O AutoML documentation requires only the response column (y), a training_frame and a stopping rule. If you set neither max_models nor max_runtime_secs, the run stops after one hour. The docs also advise always setting max_models so results can be reproduced.
No license fee also means no vendor behind the model. You host it, secure it, monitor it and support it yourself, so the real cost sits in engineering time rather than on an invoice.
9. Alteryx One
Alteryx sells its platform as Alteryx One, and its 2026 releases lean on governed analytics. Its home ground is analysts who build data preparation and analysis workflows without writing code.
The strength is speed for that audience. For instance, a finance or operations analyst can blend sources, add a predictive step and schedule the workflow in one tool. That is often the fastest route from spreadsheet to repeatable forecast.
Depth at the far end of the loop is where analyst tools get tested. Before you commit, test how models are versioned, monitored and retrained, because analyst-built forecasts still need an owner once they feed live decisions.
10. KNIME Analytics Platform
The KNIME Analytics Platform is free and open source, with more than 300 connectors to data sources. Users build visual workflows by linking nodes, so a model can be built and explained without writing code.
It suits budget-limited teams that mix analysts and technical users. It also works well as a first tool for testing predictive work before a platform purchase. For example, a single analyst can build a churn or demand model on a desktop and share the workflow with colleagues.
Growing past one desktop is where the free tool stops being free. Running workflows on a schedule, sharing them across a large team and governing who changed what take extra setup beyond the free desktop tool.
Also Worth Considering: IBM SPSS Modeler and RapidMiner AI Studio
IBM SPSS Modeler is a visual, drag-and-drop data science and machine learning tool. It remains a sensible choice for statisticians and survey researchers who already work in SPSS, though it is narrower than the full platforms above.
RapidMiner is back under its own name. As of November 10, 2026, the product page lists it as RapidMiner AI Studio from Siemens, after a period as Altair AI Studio. The same page places it within Intelligence Center X. With the product folded into a wider suite, teams already using it should check the roadmap and support terms before renewing.
Talk to Kanerika
Comparing Two or Three of These Tools?
Bring your shortlist and one forecasting decision. Kanerika will help you set the hard gates, weight the scorecard and plan a pilot on your own data.
Schedule a Demo →Best Predictive Analytics Tools by Team Type
The fastest way to narrow the list is to start from your team rather than from the tools. Two companies can pick different winners from the same 10 platforms and both be right, because their data, people and rules differ.
Use the table as a first shortlist of two or three names, then run the framework in the next section to pick one.
| Team profile | First shortlist | Why |
|---|---|---|
| Azure shop | Azure Machine Learning; Databricks | Models train and run next to Azure data and identity |
| Google Cloud shop | Gemini Enterprise Agent Platform | Tabular AutoML and custom training on Google Cloud |
| AWS shop | Amazon SageMaker AI; SageMaker Canvas | Code platform as well as a no-code option on AWS |
| Lakehouse team | Databricks | Features and models share one copy of the data |
| Mixed-skill team | Dataiku; DataRobot | Analysts work alongside data scientists in one project |
| Analyst-led team | Alteryx One; KNIME; SageMaker Canvas | Visual workflows, little or no code |
| Regulated industry | SAS Viya; DataRobot; your cloud platform | Governance, documentation and explainability first |
| Tight budget | KNIME; H2O-3 | No license fee, but you pay in hosting and people |
| BI-led team (Power BI, Tableau, Qlik) | Built-in forecast first, then your cloud platform | Chart forecasts cover quick looks; daily decisions need a governed model |
Can non-technical teams use these tools? Yes, within limits. Visual tools such as SageMaker Canvas, Alteryx One, KNIME and Dataiku let analysts build a first model without code. In fact, that is often how good use cases get found.
The limit appears once a model heads to production. Someone still has to check the model for data leakage, schedule it, monitor it and decide when to retrain it. Retailers testing demand or promotion models will find worked examples in our guide to predictive analytics in retail.
Checklist
Data Analytics Checklist
Check data quality, ownership and platform readiness before you pilot a free or paid predictive analytics tool.
Get the Checklist →Free and Open-Source Predictive Analytics Tools
Free predictive analytics tools are good enough for real enterprise models, and many production systems run on them. The license is free, while everything needed to run a model safely for years still costs money.
Three options cover most needs. KNIME gives a visual, free desktop platform. H2O-3 gives distributed modeling and AutoML under Apache 2.0. Finally, a Python open-source stack, built around libraries such as scikit-learn, gives the most control and the most engineering work.
| Option | What is free | What you still pay for |
|---|---|---|
| KNIME Analytics Platform | Desktop platform, 300+ connectors, visual workflows | Scheduling, sharing and governance at team scale; support |
| H2O-3 | Distributed engine, AutoML, core algorithms | Cluster hosting, security, monitoring, support |
| Python open-source stack | Modeling libraries and notebooks | Everything around the model: serving, registry, monitoring, people |
The honest comparison is total cost over several years. A free tool run by two engineers can cost more than a subscription that one analyst runs. On the other hand, a free tool on infrastructure you already operate can be the cheapest route by far.
Open source also changes who carries the risk. When a security patch or library upgrade breaks a scoring job, your team fixes it. So budget for that support time before you call the tool free.
How to Choose a Predictive Analytics Tool: A 5-Step Framework
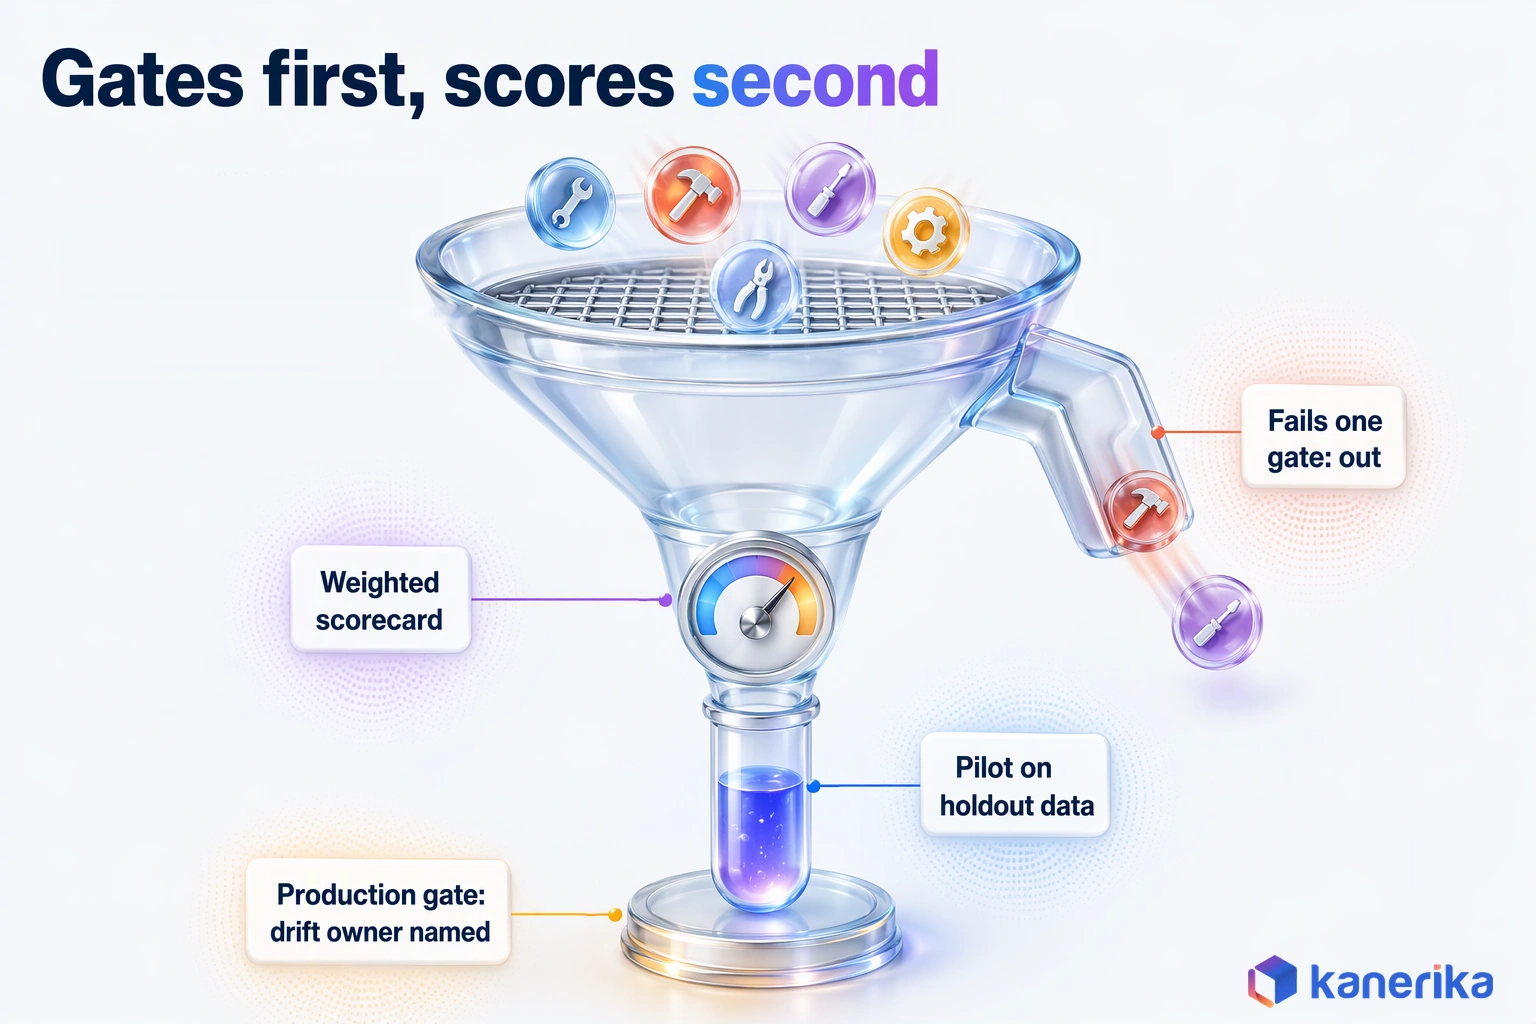
Choosing a predictive analytics tool works best as a sequence of filters, from the business decision down to a pilot on your own data. Each step removes options, so by the time you watch a demo you are comparing two or three tools that could all work.
- Define the decision and the action it triggers. Write down what the model predicts, who acts on it, how often and through which system. “Forecast weekly demand by item so the buyer can set purchase orders in the ERP” is a usable brief; “use AI for forecasting” is not.
- Apply hard gates. Gates are pass-or-fail tests: the cloud you run on, data residency rules, latency (batch scores overnight or real-time scores in milliseconds), identity and access integration, and the skills you have today. A tool that fails one gate is out, however good its demo looks.
- Score the survivors with a weighted scorecard. Agree the weights before anyone sees a vendor, so the scoring cannot be bent toward a favorite.
- Pilot on your own data with a holdout. Train on older history, then test on a recent period the model has never seen. Compare the result with a simple baseline, such as last year’s same week or a moving average.
- Pass a production gate. Before launch, name the person who owns monitoring, set the accuracy level that triggers a retrain and confirm where the predictions will land.
Latency deserves a special note, since it quietly decides many shortlists. A nightly demand forecast can run on almost any platform. Fraud scoring at checkout, by contrast, needs a real-time endpoint and a feature pipeline fast enough to feed it.
Set the Weights Before You Score
The weights below are an example, not a standard. A regulated lender might raise governance to 30, while a startup with one analyst might raise skills.
| Criterion | Example weight | What a 5 looks like |
|---|---|---|
| Data-stack fit | 25 | Trains and scores where the data already lives |
| Deployment and MLOps | 20 | Batch and real-time serving, versioning, rollback |
| Governance and explainability | 20 | Registry, lineage, access control, per-prediction explanations |
| Skills fit | 15 | Your current team can run it before any new hires |
| Cost to run | 20 | Predictable total cost at full team scale |
Score each tool from 1 to 5 on every criterion and multiply by the weight. Then add the results and divide by 5 to get a score out of 100. Teams forecasting demand across many products and sites can pair this with our guide to supply chain analytics to define the decision in step 1.
Worked Example: Choosing a Tool for a Sales Forecast
Picture a mid-size manufacturer that runs on Azure and keeps three years of order history in its ERP. Its sales team forecasts by hand in spreadsheets, while the analytics group has one data scientist and three analysts. The goal, in short, is a monthly sales forecast by product family for production planning.
The hard gates remove most of the field quickly. Data must stay in the company’s Azure tenant, so the Google and AWS platforms drop out. A monthly forecast needs only batch scoring, so latency is not a gate. Three candidates remain: Azure Machine Learning, Databricks and Dataiku.
The scores below are illustrative judgments for this one company, not ratings of the vendors.
| Criterion (weight) | Azure ML | Databricks | Dataiku |
|---|---|---|---|
| Data-stack fit (25) | 5 | 4 | 4 |
| Deployment and MLOps (20) | 4 | 4 | 3 |
| Governance and explainability (20) | 4 | 5 | 4 |
| Skills fit (15) | 3 | 2 | 5 |
| Cost to run (20) | 4 | 3 | 2 |
| Weighted score (out of 100) | 82 | 74 | 71 |
Azure ML scores 82 because it sits inside the existing tenant and bills only for the compute the team uses. Databricks scores 74; it would win if the company already ran a lakehouse, but with one data scientist the code-first approach strains the team. Dataiku scores 71 because it has the best skills fit for three analysts but also the highest subscription cost.
Pilot the Top Two on a Holdout
The gap of eight points is not large enough to decide on paper. Instead, the team pilots the top two on the same holdout, the last six months of orders. On Azure ML, that means passing those months as validation_data instead of relying on the default, which holds out 10% of rows once data passes 20,000 rows. It keeps the one that beats the spreadsheet forecast by the wider margin. If inventory is the next use case, our roundup of AI inventory management tools covers what changes when the forecast drives stock levels.
Case Study
85% Accurate Sales Forecasts for a Packaging Manufacturer
ABX, a US flexible-packaging manufacturer, replaced intuition-led forecasts with a time series and regression model, reaching 85% forecast accuracy and a 50% increase in identifying customer churn risk.
Read the Case Study →What Predictive Analytics Tools Cost to Run
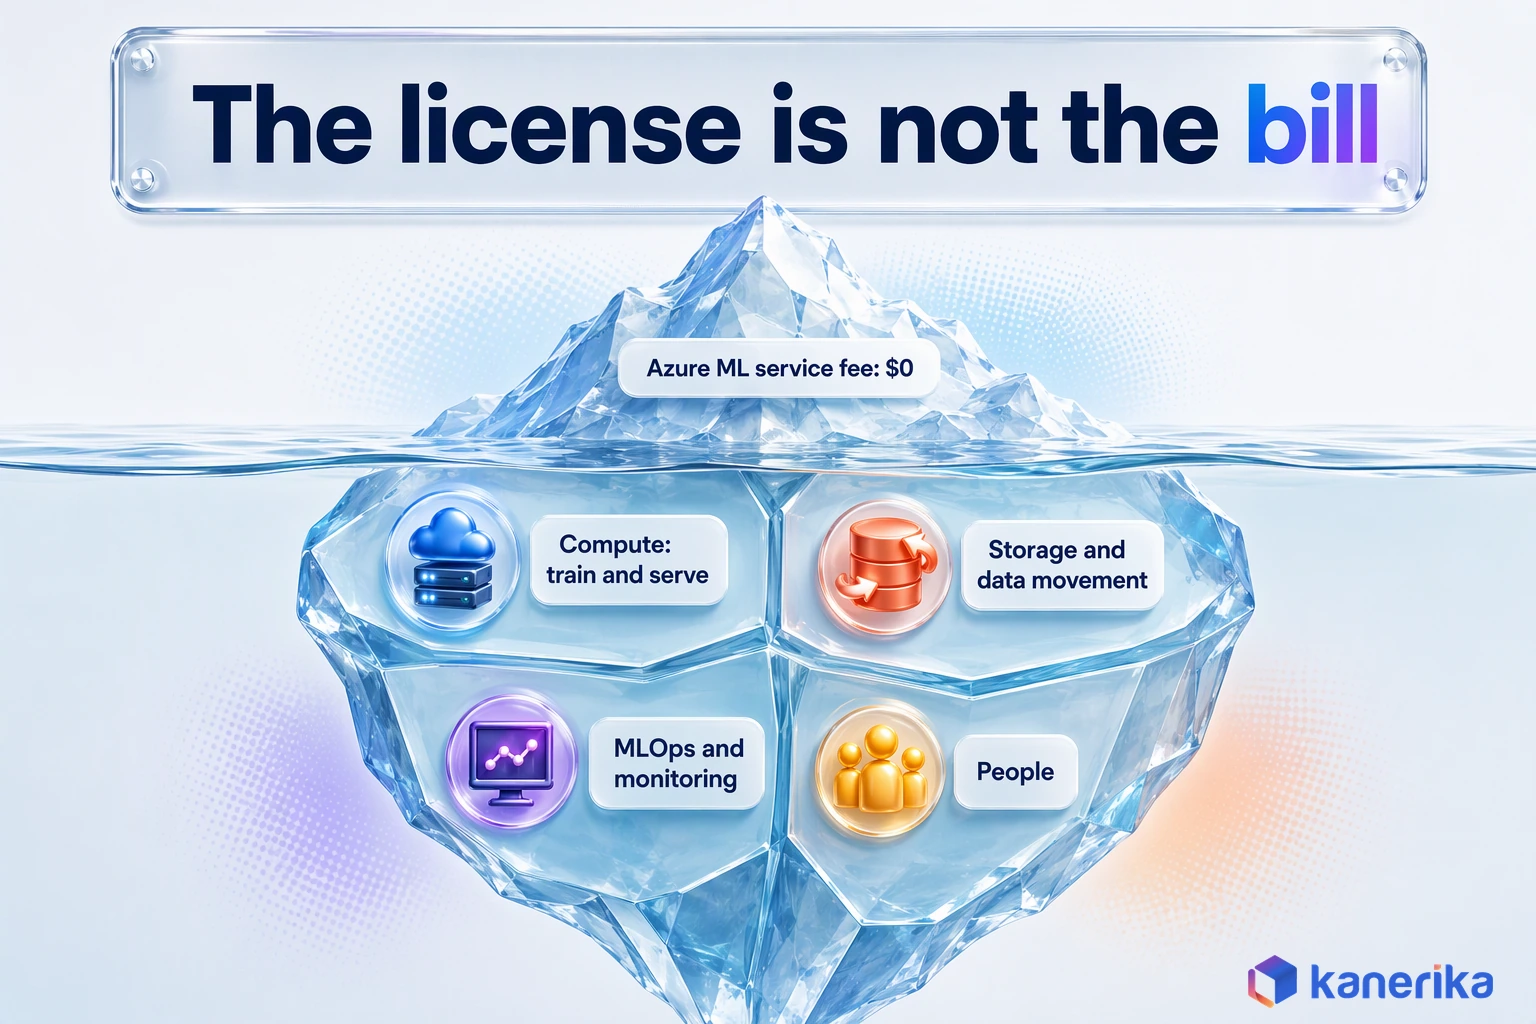
The license or subscription is only one line in the cost of a predictive analytics tool, and on consumption platforms it can be zero. A realistic budget adds up five components, and the people line is the one most often left out.
Which line dominates depends on the pricing model. On a subscription tool such as Dataiku, the contract is the big number. On Azure Machine Learning or Databricks, compute drives the bill, rising with every retrain and running endpoint. With free KNIME or H2O-3, engineering time becomes the main cost.
| Cost component | What drives it | How to control it |
|---|---|---|
| License or subscription | Users, modules, edition | Price the first year’s real users rather than the full catalog |
| Compute for training and serving | Model size, retrain frequency, always-on endpoints | Auto-shutdown, and batch scoring when real time is not needed |
| Storage and data movement | Copies of training data, cross-region transfer | Train where the data lives |
| MLOps and monitoring | Registry, logging, drift alerts | Monitor the models that drive decisions first |
| People | Data scientists, engineers, platform admins | Match the tool to the skills you already have |
Keep Retraining and Idle Compute in Check
Retraining frequency is the line that surprises teams. A demand forecasting model retrained every week on three years of history uses far more compute than one retrained each quarter. Set the schedule from how fast your data actually changes, and check whether a retrain improves accuracy before you pay for the next one.
Idle training compute is the easiest line to fix, and on Azure ML it takes one setting. Microsoft’s compute cluster guide says to set minimum nodes to 0, because any higher value keeps nodes running even when unused. The cluster below shrinks to zero after 120 idle seconds:
$schema: https://azuremlschemas.azureedge.net/latest/amlCompute.schema.json
name: forecast-training
type: amlcompute
size: STANDARD_DS3_v2
min_instances: 0
max_instances: 2
idle_time_before_scale_down: 120
Two habits keep the bill honest. Estimate costs for the steady state a year after launch, when several models are retraining on schedule, rather than for the pilot. Also tag every workspace and endpoint to a business owner, so idle resources have someone who answers for them.
Governance, Model Drift and Explainability
Governance is the set of controls that lets you trust a model’s predictions after launch. It also lets you explain them to an auditor, a customer or a regulator. It matters more over time, not less, because the data a model learned from keeps changing.
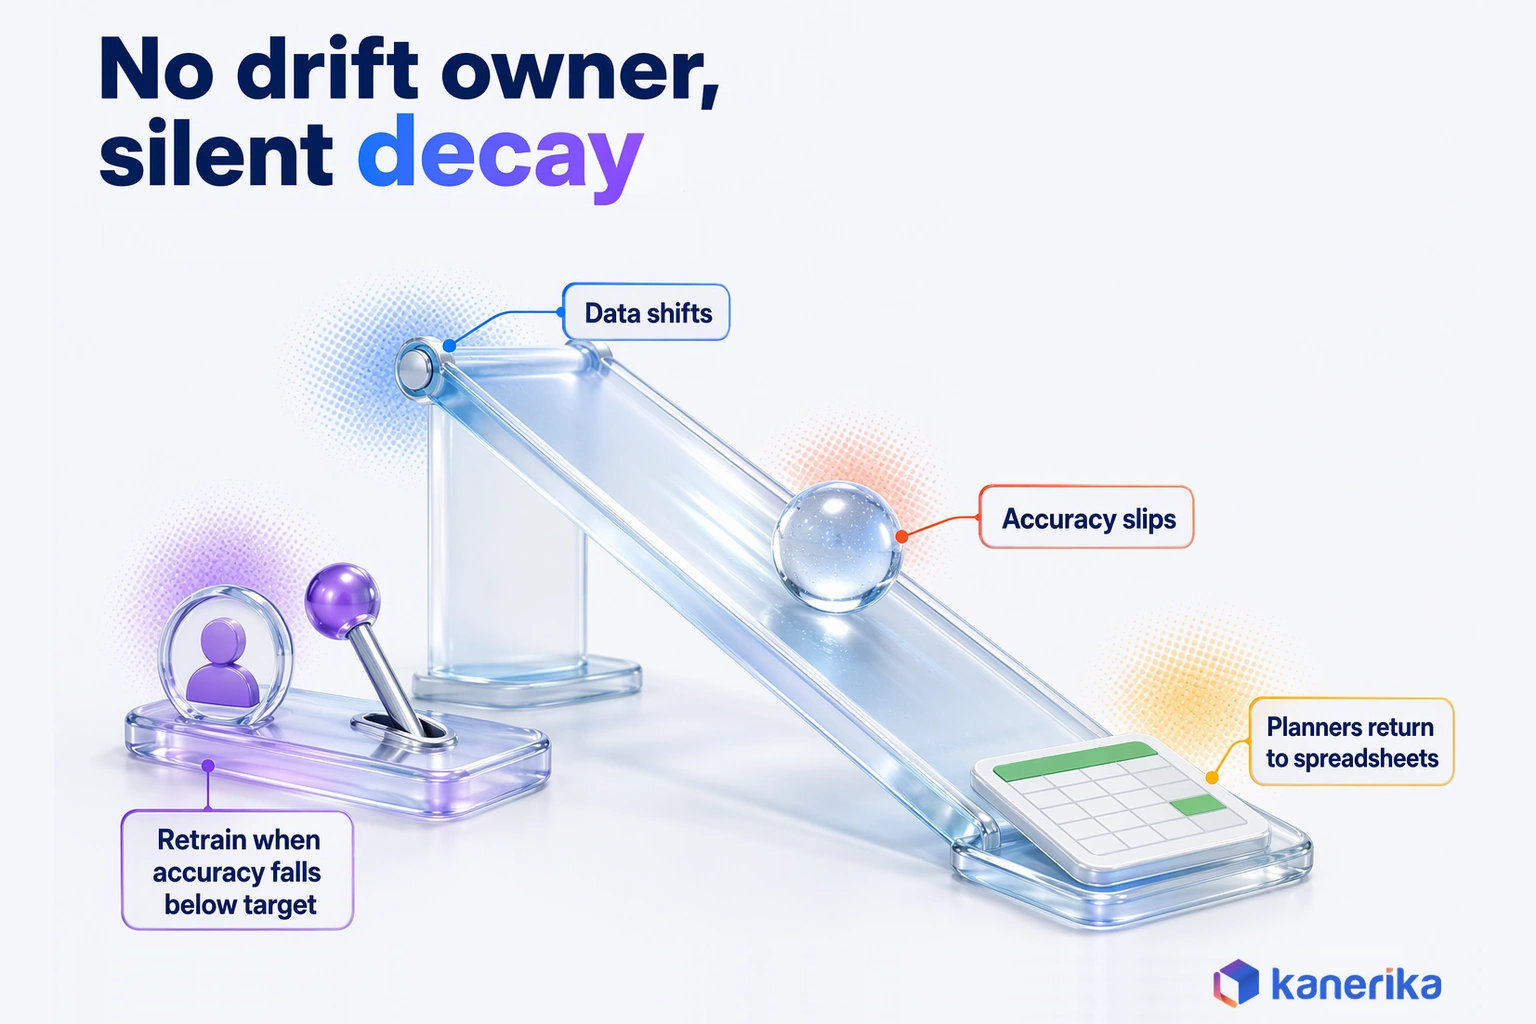
That change is called drift. Customer behavior shifts, a new product line changes the mix or a supplier changes lead times. As a result, a model trained on old patterns starts to miss. Drift rarely announces itself. Instead, accuracy slips a little each month, and the first sign is often a planner who quietly goes back to the spreadsheet.
Before you buy, check that the tool, or the stack around it, covers these controls, which our AI governance checklist also lists:
- Model registry: every model version stored with its training data reference, code and metrics. Our comparison of MLflow, Hugging Face Hub and Azure ML registries walks through the options.
- Lineage: a traceable path from source data to features to prediction, as described in our guide to data lineage.
- Access control: who can train, approve, deploy and read predictions, tied to your existing identity system.
- Explainability: per-prediction reasons for regulated decisions such as credit, pricing or claims.
- Drift monitoring and retrain triggers: alerts on input drift and accuracy decay, with a named owner and an agreed threshold.
For a shared reference point, many teams map these controls to the NIST AI Risk Management Framework. NIST published AI RMF 1.0 and is revising it under the White House AI Action Plan. For that reason, treat the current text as a guide that will be updated.
Security belongs in the same review. Because training data often holds customer and pricing details, our guide to data security in AI covers the controls to ask vendors about.
Common Mistakes When Buying Predictive Analytics Software
Tool purchases usually go wrong for reasons that have little to do with algorithms. The six mistakes below come up again and again, but each one has a cheap fix if you catch it before the contract.
Data readiness sits under several of them. In a July 2024 Gartner survey of 1,203 data management leaders, 63% lacked the right data practices for AI or were unsure. Gartner also predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. A pilot on your own messy history therefore matters more than any feature list.
- Buying on demo data. Vendor demos use tidy datasets. Instead, insist on a pilot with your own messy history and a holdout period.
- Ignoring deployment. A model that cannot reach the ERP, CRM or planning tool is only a report. Ask to see the path to production in the pilot.
- Leaving drift without an owner. If nobody is named to watch accuracy, nobody will. Assign the owner before launch.
- Picking a tool outside the cloud you run. Every cross-cloud copy adds cost, delay and a security review. Start from your own cloud unless a gate rules it out.
- Counting the license and not the people. A cheap or free tool that needs two new engineers is not cheap. Put salaries in the comparison.
- Having no baseline to beat. Without a simple benchmark, such as last year’s figures or a moving average, you cannot tell whether the model adds anything.
Beat a Baseline Before You Buy
Mistake six is the easiest to picture. ABX, the packaging manufacturer in the case study below, forecast sales by hand and largely on intuition. That manual forecast was the baseline its new model had to beat, and the model went on to deliver sales forecasts that were 85% accurate.
A small, scoped AI pilot catches most of these before money is committed. It also gives you real numbers for the cost and accuracy rows of your scorecard.
How Kanerika Helps Teams Choose and Deploy Predictive Analytics Tools
Kanerika helps enterprises pick a predictive analytics tool that fits their data and team, then puts the first models into production on it. Our predictive analytics services follow four stages:
- Decision and readiness: define the decision, the action and the data behind it, and check whether the history is good enough to learn from.
- Shortlist and pilot on client data: apply the hard gates, score the survivors and pilot the top two against a baseline on a holdout period.
- Integrate and govern: connect predictions to the systems where people act, and set up the registry, lineage and access controls. Data preparation can also run on FLIP, Kanerika’s data operations platform.
- Monitor and expand: set drift alerts and retrain triggers through our MLOps consulting practice, then add the next use case on the same platform.
Kanerika Service
MLOps Consulting
Kanerika sets up model registries, drift monitoring and retrain triggers so predictive models stay accurate long after launch.
Explore MLOps ServicesCase Study: Sales Forecasting for a US Packaging Manufacturer
ABX, a US flexible-packaging manufacturer headquartered in Charlotte, North Carolina, forecast sales manually and largely on intuition. Forecasts varied by person, while churn risk among customers surfaced late.
Kanerika built a time series and regression model on ABX’s sales history, so planners started from a model forecast instead of a blank spreadsheet. According to the ABX sales forecasting case study, the work delivered:
- Sales forecasts that were 85% accurate.
- A 50% increase in identifying customer churn risk.
For tool selection, the lesson is the same one as in the worked example. The model type, time series forecasting plus regression, is available on almost every platform in this guide. The result came from defining the decision first and then fitting the model into how the sales team already works.
Choosing the Right Predictive Analytics Tool
Start from your cloud and your team rather than from a feature list. Azure, Google Cloud and AWS shops should shortlist their own platform first. Lakehouse teams should look at Databricks, and mixed teams at Dataiku or DataRobot. Analyst-led teams fit Alteryx One or KNIME, while tight budgets fit KNIME or H2O-3. Then filter with hard gates, score with agreed weights and pilot on your own data against a baseline. So the best predictive analytics tool for your enterprise team is the one that passes your gates and beats your baseline on your own data.
Frequently Asked Questions
What is predictive analytics?
Predictive analytics uses historical data, statistics and machine learning to estimate what is likely to happen next. Typical outputs are a churn probability, a demand forecast or a fraud score. Descriptive analytics explains what already happened, while predictive analytics looks ahead. Its accuracy depends on the quality and completeness of the data the model learns from.
What are the main types of predictive analytics?
The main types are classification, regression and time series forecasting. Classification predicts a category, such as whether a customer will churn. Regression predicts a number, such as next quarter’s order value. Time series forecasting predicts values over time, such as weekly demand. Many tools also add anomaly detection to flag unusual events like fraud.
How much do predictive analytics tools cost?
Cost depends on the pricing model more than the list price. Cloud platforms such as Azure Machine Learning bill for compute and related services, commercial suites charge subscriptions that often scale with users, and open source tools have no license fee. Add storage, monitoring and staff time to compare tools on total cost.
Do you need data scientists to use predictive analytics tools?
Not to start. No-code tools such as SageMaker Canvas, KNIME, Alteryx One and Dataiku let analysts build a first model visually. A data scientist or ML engineer is still needed before production, to check for data leakage, validate accuracy against a baseline, set up monitoring and decide when the model should be retrained.
What is the difference between predictive analytics tools and BI tools?
BI tools report and visualize what has already happened, and some add a simple trend forecast. Predictive analytics tools train models on many drivers at once, test them against a baseline, deploy them as services and monitor accuracy over time. Most enterprises use both, with BI dashboards displaying the predictions the models produce.
How do predictive analytics tools handle model drift?
Good platforms track model inputs and accuracy after launch and alert when either moves outside an agreed range. The team then retrains the model on recent data and redeploys it after testing. Tools differ in how much of this is built in, so confirm drift alerts, retrain triggers and a named owner during the pilot.
Should we buy a predictive analytics platform or build an open-source stack?
Buy when you need governance, support and fast results from a team of analysts and a few data scientists. Build on open source when you have strong engineers, existing infrastructure and a need for full control. Compare the two on total cost over three years, including the people who will run each option.
Which predictive analytics tools should enterprises use?
Start with the platform in the cloud you already run. Azure shops should look at Azure Machine Learning, Google Cloud shops at Gemini Enterprise Agent Platform and AWS shops at SageMaker AI. Lakehouse teams fit Databricks, mixed teams fit Dataiku or DataRobot, regulated teams should test SAS Viya, and tight budgets can start with KNIME.
What is the difference between AI and predictive analytics?
AI is the broad field of software that performs tasks needing human-like judgment, including language, vision and planning. Predictive analytics is one practical use of it, focused on forecasting outcomes from historical data. Many predictive models use machine learning, a branch of AI, but simple statistical models such as regression also count as predictive analytics.
What is real-time predictive analytics and when does it matter?
Real-time predictive analytics scores each new event within milliseconds or seconds, instead of in an overnight batch. It matters when the decision has to happen in the moment, such as blocking a fraudulent payment or pricing a ride. For monthly sales or weekly demand forecasts, batch scoring is cheaper and usually good enough.
Can predictive analytics handle unstructured data?
Yes, but unstructured data such as emails, reviews, call notes and images first has to be turned into model inputs. Text can become sentiment scores, topics or embeddings, and images can become labels or measurements. Those features then sit beside structured fields such as order history, so the model can learn from both.
Why is explainable AI important in predictive analytics?
Explainable AI shows which inputs drove a prediction, so people can check it before acting. That matters most in regulated decisions such as credit, insurance pricing and claims, where a customer or regulator may ask for reasons. It also helps teams catch bad models early, because a strange explanation often reveals leakage or biased data.
What are the most common reasons predictive analytics projects fail?
Projects usually fail outside the model. Common causes are a vague business decision, poor or missing history, no path from the model into the systems people use, and no owner watching accuracy after launch. Buying a tool on demo data instead of piloting it on real data is another frequent and avoidable mistake.
Which predictive analytics tool is best for a company on Microsoft Azure?
Azure Machine Learning is the natural first choice, because it trains and serves models inside your Azure tenant. Microsoft charges nothing extra for the service and bills for compute plus the Azure services it uses. Databricks is the main alternative if your team already runs a lakehouse and writes Python or SQL.
Are there free predictive analytics tools good enough for enterprise use?
Yes. KNIME Analytics Platform is free and open source with more than 300 connectors, and H2O-3 is an open source machine learning platform under the Apache License 2.0. Both can support real enterprise models. You still pay for hosting, security, monitoring and the people who run them, so compare total cost.