TL;DR
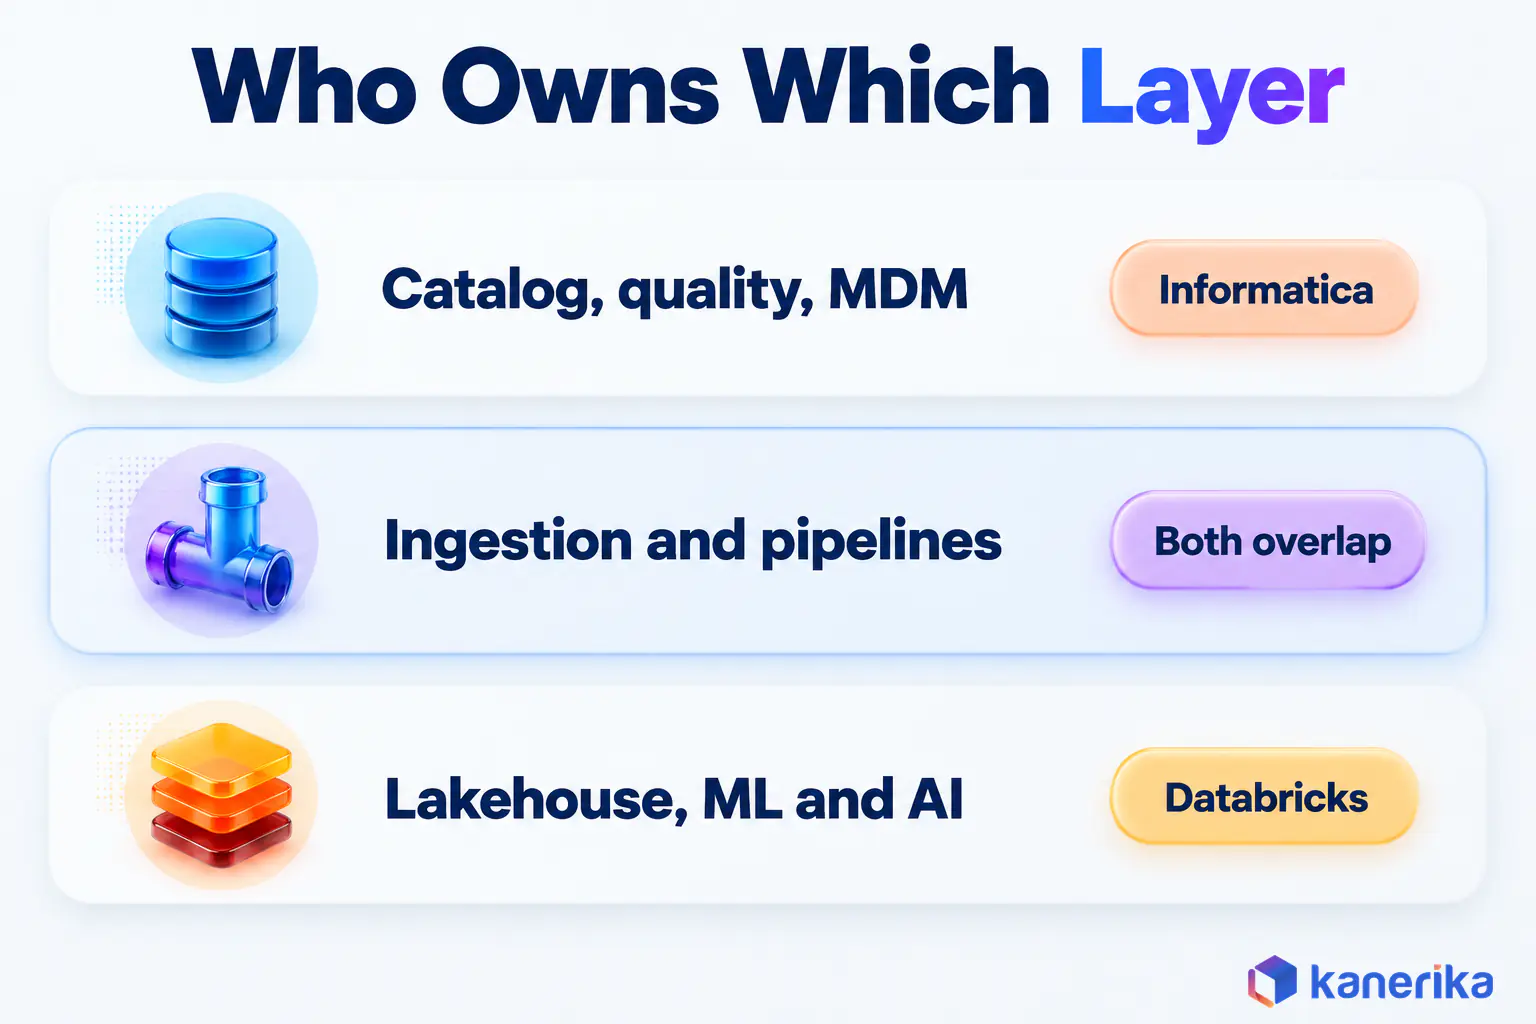
In the Informatica vs Databricks choice, pick Informatica for governed integration, data quality and MDM across many systems, and pick Databricks for lakehouse engineering and AI. The old split of governance tool versus analytics platform no longer holds, because Databricks now ships its own ingestion, pipelines and governance. Informatica, part of Salesforce since November 2025, is best read as a data management control plane rather than a pipeline engine. Teams that run both usually keep Informatica for catalog, quality and golden records, and let Databricks process, store and serve the data. Both platforms bill by consumption, IPUs for Informatica and DBUs for Databricks, so compare cost per workload rather than per unit. If you own a PowerCenter estate, plan its future first, because support dates often set the timeline.
Key Takeaways
- The overlap grew because Databricks Lakeflow now covers ingestion and pipelines that once needed a separate ETL tool.
- Informatica still keeps the edge on cross-platform data quality, master data management and a catalog that spans many systems.
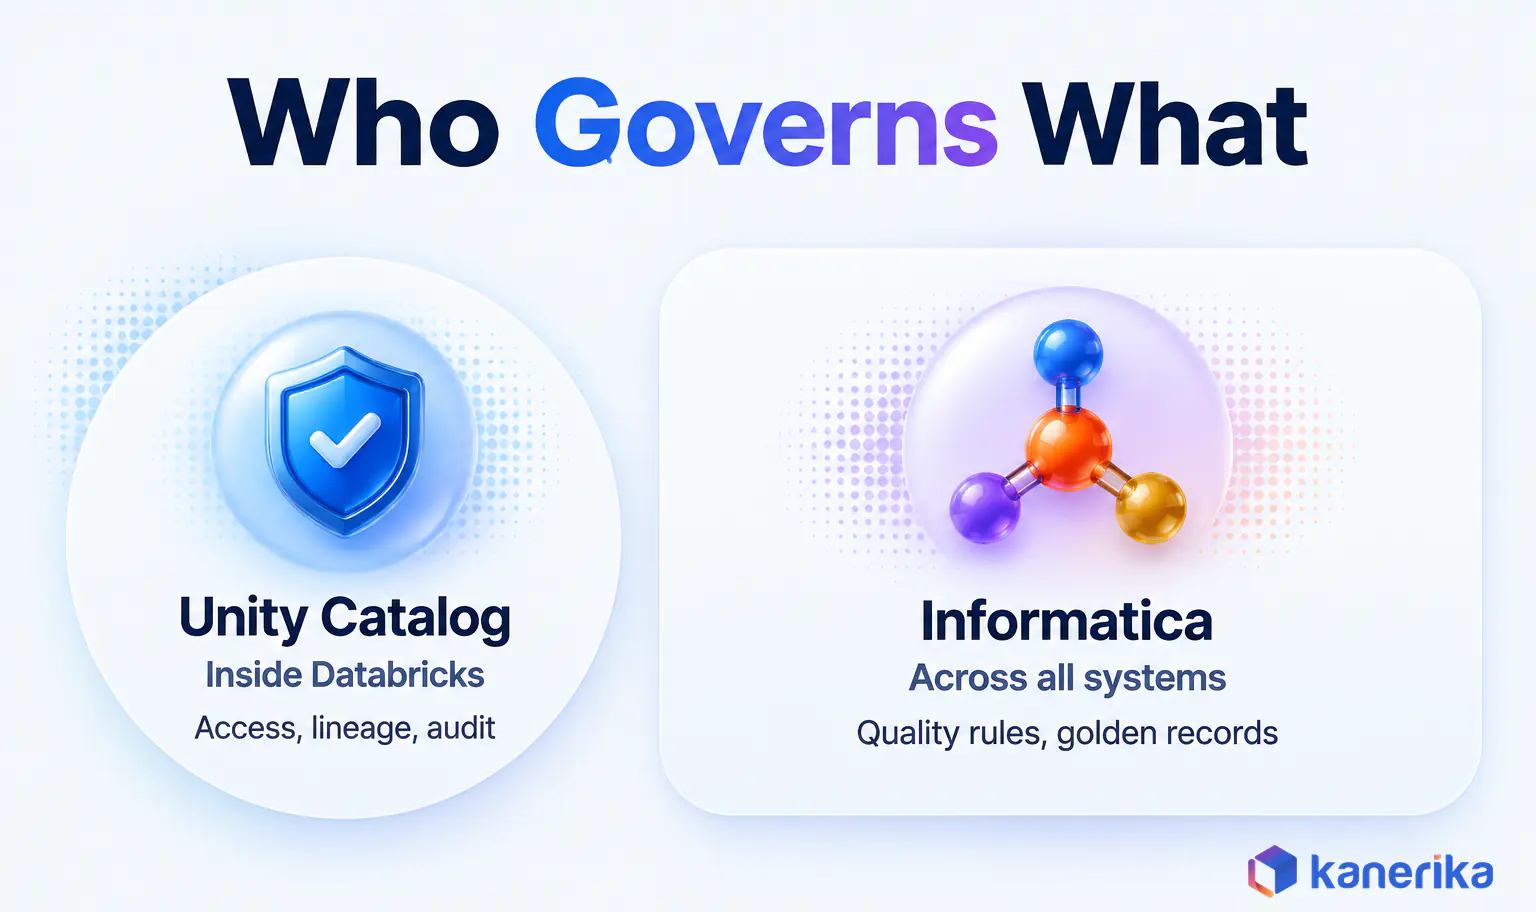
- Unity Catalog is native to Databricks, so it governs access, lineage and audit for everything inside the lakehouse.
- Pick by layer, not by brand: decide who owns ingestion, transformation, governance and AI, then map each tool to a layer.
- PowerCenter 10.4 moved to paid Extended Support in March 2024, so a PowerCenter estate needs a dated plan whichever way you go.
- Both bill by consumption, so compare cost per workload over three years rather than IPU and DBU prices per unit.
2,000 Mappings and a Lakehouse Next Door
Picture a data team whose 2,000 PowerCenter mappings feed finance, claims and supply chain reports before each business day starts. Two floors up, the analytics group runs a Databricks lakehouse for forecasting models and streaming dashboards.
Both teams move data, clean it and govern it, and both pay for compute. Then the Informatica renewal arrives. So the CFO asks a fair question: why pay for two platforms that seem to do the same job?
The honest answer is that the two products overlap more than they did, yet they still own different layers. This guide to Informatica vs Databricks walks through each layer first, then the pricing models and the coexistence pattern. Finally, it ends with a decision framework you can apply to your own estate.
Why the Informatica vs Databricks Decision Changed in 2026
Three changes between late 2025 and 2026 reshaped this comparison, since each one moves a different piece of the decision.
The first is ownership. Salesforce completed its acquisition of Informatica on November 18, 2025. Salesforce said the deal brings catalog, integration, governance, quality, privacy and MDM capabilities into its platform. For buyers, Informatica’s roadmap therefore sits inside a larger company with its own data and AI agenda.
The second is scope. Databricks no longer needs a partner tool to land data. Lakeflow Connect, Lakeflow Spark Declarative Pipelines and Lakeflow Designer cover ingestion, transformation and visual prep, while Unity Catalog governs the results. That closes much of the gap that once made Informatica the default front door to a lakehouse.
The third is support pressure on PowerCenter. Version 10.4 moved to paid Extended Support on March 31, 2024. In 2026, teams still on PowerCenter weigh the cost of staying against the cost of moving, so the platform question and the migration question arrive together.
Informatica vs Databricks at a Glance
The quickest way to see the difference is to line up what each platform is built to do before comparing features. Informatica starts from data management and then reaches into processing. Databricks, by comparison, starts from processing and reaches into management.
| Dimension | Informatica | Databricks |
|---|---|---|
| Category | Data management platform (IDMC) | Data and AI platform built on a lakehouse |
| Core job | Integrate, clean, master and catalog data across systems | Store and process data, then build analytics and AI on it |
| Integration | Cloud connectors, mappings, CDC and mass ingestion | Lakeflow Connect managed connectors and Lakeflow pipelines |
| Transformation engine | Informatica mappings and runtime | Apache Spark, with SQL and Python |
| Governance | Catalog and governance across many platforms | Unity Catalog, native to the platform |
| Data quality and MDM | Dedicated data quality rules and MDM golden records | Quality checks inside pipelines; golden records usually come from an MDM partner such as Informatica |
| AI | CLAIRE engine for data management work | Agent Bricks, MLflow and model serving for models and agents |
| Pricing unit | IPUs (Informatica Processing Units) | DBUs (Databricks Units), billed per second |
| Skills | Visual mapping developers and data stewards | SQL and Python engineers, plus visual prep in Lakeflow Designer |
| Deployment | Cloud service (IDMC); PowerCenter on premises | Managed service on AWS, Azure and Google Cloud |
Read the table as two overlapping circles rather than two rival boxes. The overlap sits in the middle rows, ingestion and transformation, so that is where most budget arguments start. The outer rows show where each platform still has ground the other does not cover.
What Each Platform Actually Does in 2026
Both vendors have renamed and expanded their products several times, so it helps to define each one on current facts before comparing them.
Analysts also file the two in different markets, which supports reading Informatica vs Databricks as a question of layers. Gartner named Informatica a Leader in its 2025 Magic Quadrant for Data Integration Tools, published December 8, 2025, for the 20th consecutive year. Databricks was named a Leader in the 2025 Magic Quadrant for Cloud Database Management Systems for the fifth year running, according to the company.
Informatica IDMC and PowerCenter, Now Part of Salesforce
Informatica Intelligent Data Management Cloud (IDMC) is the company’s platform for cloud data integration and data management. It groups integration, data quality and master data management into one service, together with a data catalog and governance. Informatica counts more than 250 intelligent data services, and says more than 80 of the Fortune 100 use its products.
PowerCenter is the older on-premises ETL product that many enterprises still run. It is mapping-based, mature and deeply embedded in nightly batch jobs, so moving off it takes planning.
IDMC runs on CLAIRE, Informatica’s AI engine, which automates data management work and also helps optimize costs. Salesforce has said the deal brings Informatica’s catalog, governance, quality and MDM into its own platform. So buyers outside the Salesforce ecosystem should ask how roadmap priorities will balance the two kinds of customer.
Databricks Data + AI Platform and Lakeflow
Databricks, founded in 2013, comes from the creators of Apache Spark, Delta Lake, MLflow and Unity Catalog. More than 20,000 organizations use it, including 70% of the Fortune 500, according to the company.
Its Data + AI Platform, previously marketed as the Data Intelligence Platform, is a lakehouse. It keeps data in open table formats such as Delta Lake, a Linux Foundation project, on cloud object storage. It then runs SQL analytics, data engineering, streaming and machine learning against that same copy. That single copy is the main architectural difference compared to stacks that move data between separate systems.
Lakeflow is the data engineering layer on top, and it has three parts. Lakeflow Connect handles ingestion, Lakeflow Spark Declarative Pipelines handle transformation, and Lakeflow Designer handles visual prep. The next section compares each part with its Informatica counterpart.
Checklist
Databricks Checklist
A Kanerika checklist for judging whether your data, pipelines and team are ready before you move workloads onto Databricks.
Get the Checklist →Data Integration and ETL: Informatica Mappings vs Lakeflow Pipelines
Integration is where the two platforms overlap most, because both can build the same ETL pipeline from source to curated table. The difference is where the work runs and who builds it.
In Informatica, a developer designs a mapping in a visual tool and the Informatica runtime executes it. The output lands in a warehouse or lake, which may well be Databricks. In Databricks, however, the pipeline is code or a declarative definition that runs on the same Spark compute that serves analytics. No separate engine sits in the middle.
That one difference drives the cost and skills debates later in this guide. For the wider market view, see our roundup of data integration tools and our explainer on data integration vs ETL. Our guide to enterprise data integration covers the architecture questions that sit above either tool.
| Integration need | Informatica | Databricks |
|---|---|---|
| Managed source connectors | Cloud connectors inside IDMC | Lakeflow Connect for databases, SaaS apps, files and streams |
| Batch ETL | Visual mappings run by the Informatica runtime | Lakeflow pipelines in SQL or Python |
| Streaming | CDC and mass ingestion services | Kafka, Kinesis, Pub/Sub, Event Hubs and Pulsar sources |
| Visual development | Mapping designer | Lakeflow Designer canvas and natural language |
| Where it runs | Informatica runtime | Databricks compute, governed by Unity Catalog |
Connectors and Ingestion
Connectors decide how much custom code you write before data reaches the platform. Informatica built its business on breadth here, with cloud connectors for databases, applications and file systems inside IDMC.
Lakeflow Connect gives Databricks managed connectors for databases, files, streams and SaaS applications such as Salesforce, HubSpot, Jira and Workday. Each ingested table is also governed by Unity Catalog from the moment it lands. For a team already on Databricks, that is automated data integration without a second vendor.
The practical test is your own source list. Check each source against both connector catalogs, then mark the ones that need custom work. Niche and on-premises sources deserve the closest look, because that is where connector gaps usually show up. Our note on data ingestion vs data integration explains why landing data and reconciling it are separate jobs.
Batch, CDC and Streaming
Batch jobs still carry most enterprise reporting, but a growing share of pipelines must deliver fresh data within minutes. Both platforms handle batch well, so the deciding factor is usually streaming and change data capture (CDC).
Lakeflow Spark Declarative Pipelines are built on Apache Spark Declarative Pipelines. They run batch and streaming in the same SQL or Python definition, and they also read from Kafka, Kinesis, Pub/Sub, Event Hubs and Pulsar. Engineers declare the tables they want, and the framework works out the order in which steps run.
Informatica covers CDC and bulk loading through IDMC ingestion services, often feeding a warehouse where data warehouse automation handles the downstream models. It is a strong fit when changes must be captured from many operational databases under one central team. When the same team also runs analytics on streaming data, Databricks keeps the whole flow on one engine.
Talk to Kanerika
Map Your Pipelines to the Right Platform
Talk to Kanerika about which of your Informatica pipelines should move to Lakeflow, which should stay and what each path costs.
Schedule a Demo →Low-Code vs Code-First Development
Skills shape this choice as much as product scope does, especially in large teams. Informatica’s visual mapping designer lets ETL developers build complex flows without writing Spark code, and many enterprises have years of mapping knowledge on staff.
Databricks used to be the code-first option, but Lakeflow Designer changes that. It is a visual, no-code, AI-native data prep tool with a drag-and-drop canvas and natural language prompts. Engineers can still drop into notebooks, SQL and Python when a flow needs custom logic, as our guide to Databricks Lakeflow shows.
Here is what the code-first side of Informatica vs Databricks looks like in practice. The two statements below land raw claim files, then drop rows that fail a quality rule. In an Informatica mapping, the same work takes a source, a filter and a data quality step.
-- Bronze: land raw claim files from a Unity Catalog volume
CREATE OR REFRESH STREAMING TABLE claims_bronze
AS SELECT * FROM STREAM read_files(
  '/Volumes/main/raw/claims/',
  format => 'json'
);

-- Silver: drop rows that break a quality rule
CREATE OR REFRESH STREAMING TABLE claims_silver (
  CONSTRAINT valid_claim_id EXPECT (claim_id IS NOT NULL) ON VIOLATION DROP ROW
)
AS SELECT claim_id, member_id, CAST(amount AS DECIMAL(12, 2)) AS amount
FROM STREAM(claims_bronze);
The expectation in the second statement is the native Databricks answer to a simple data quality rule. Rules that must hold across many systems, or that feed MDM matching, still sit more naturally in Informatica’s data quality service. For more patterns, see our walkthrough of ETL on Databricks.
- Informatica fits teams with mapping developers, strict change control and many sources managed centrally.
- Databricks fits teams with SQL and Python engineers, a lakehouse in place and analysts who want visual prep on the same data.
Whichever style you lean toward, test it on one real pipeline before you commit. Vendor demos rarely include your messiest source.
Governance, Data Quality and MDM: Informatica vs Unity Catalog
Data governance is the area where old comparisons are most out of date. Many still describe Unity Catalog as an add-on, but it is native to Databricks and sits beneath every data and AI interaction on the platform.
Unity Catalog enforces access control, tracks lineage and logs audit events for the data and AI assets in Databricks. Its open-source edition, Unity Catalog OSS, is an LF AI & Data sandbox project. For a company whose data mostly lives in the lakehouse, it can be the main governance layer, as our Databricks Unity Catalog guide explains.
Where Informatica Governance Reaches Further
Informatica’s catalog scans many platforms rather than just one, so a warehouse, a SaaS app and the lakehouse can sit in one governed view. Its data quality rules and MDM also build trusted golden records for customers, products and suppliers. Those records are what reports and AI agents should read. In most mixed stacks, these are the pieces Informatica still owns.
The two catalogs also connect. Informatica’s Cloud Data Governance and Catalog (CDGC) extracts Unity Catalog tags, a capability that shipped in its April 2026 release. That lets one enterprise catalog show Databricks assets together with the tags their owners already applied.
Those tags and grants are plain SQL on the Databricks side. A steward could mark a sensitive column and limit who reads the table like this:
-- Tag a sensitive column so catalogs and policies can find it
ALTER TABLE main.claims.members
ALTER COLUMN ssn
SET TAGS ('pii' = 'ssn');

-- Let analysts read the curated table, nothing more
GRANT USE CATALOG ON CATALOG main TO `claims_analysts`;
GRANT USE SCHEMA ON SCHEMA main.claims TO `claims_analysts`;
GRANT SELECT ON TABLE main.claims.members TO `claims_analysts`;
Informatica’s catalog can then pick up those Unity Catalog tags through the CDGC extraction, so stewards do not tag the same column twice.
If lineage is your main gap, start with our guide to data lineage. If ownership is the gap, the list of common data governance challenges is the better first read.
| Governance need | Unity Catalog | Informatica |
|---|---|---|
| Access control on lakehouse data | Native | Relies on each platform’s own controls |
| Lineage | Tracked natively inside Databricks | Traced across many platforms through the catalog |
| Audit | Logs Databricks data and AI activity | Covers Informatica jobs and catalog activity |
| Catalog scope | Databricks assets, with an open-source catalog | Many platforms, including Unity Catalog tags |
| Data quality rules | Checks inside pipelines | Dedicated data quality service |
| Master data (golden records) | Not its focus | MDM service; publishing to the lakehouse scheduled for October 2026 |
AI and Machine Learning: CLAIRE vs Agent Bricks and MLflow
Both vendors talk about AI, but they point it at different jobs. Informatica uses AI to manage data, while Databricks uses AI to build models and agents on top of data.
CLAIRE is the AI engine that powers IDMC, and Informatica positions it as automation for data management work, including cost optimization. The value therefore shows up as less manual effort for data stewards and developers. It is not, however, a toolkit for the models your business ships to customers.
Databricks puts model building at the center. Agent Bricks is its agent developer platform for building AI agents on governed data, and MLflow tracks experiments and the model lifecycle. That makes it the natural home for data science teams, as our guides to MLOps and generative AI on Databricks describe.
The two meet in agent work. In May 2026, Informatica announced headless IDMC MCP servers inside Agent Bricks, in private preview, with general availability targeted for Informatica’s summer 2026 release. An agent built on Databricks could then call Informatica services for trusted master data or quality checks. Treat it as a roadmap item until you confirm availability for your own contract.
Informatica vs Databricks Pricing: IPUs vs DBUs
Both vendors charge by consumption rather than per seat, but each one meters different work, so a direct price comparison can mislead.
Informatica prices IDMC in Informatica Processing Units (IPUs). You buy IPUs and spend them across eligible IDMC services such as integration, data quality and catalog. MDM is priced separately, by domain and record volume. That shared model suits estates that use several Informatica services, since one IPU commitment covers most of them.
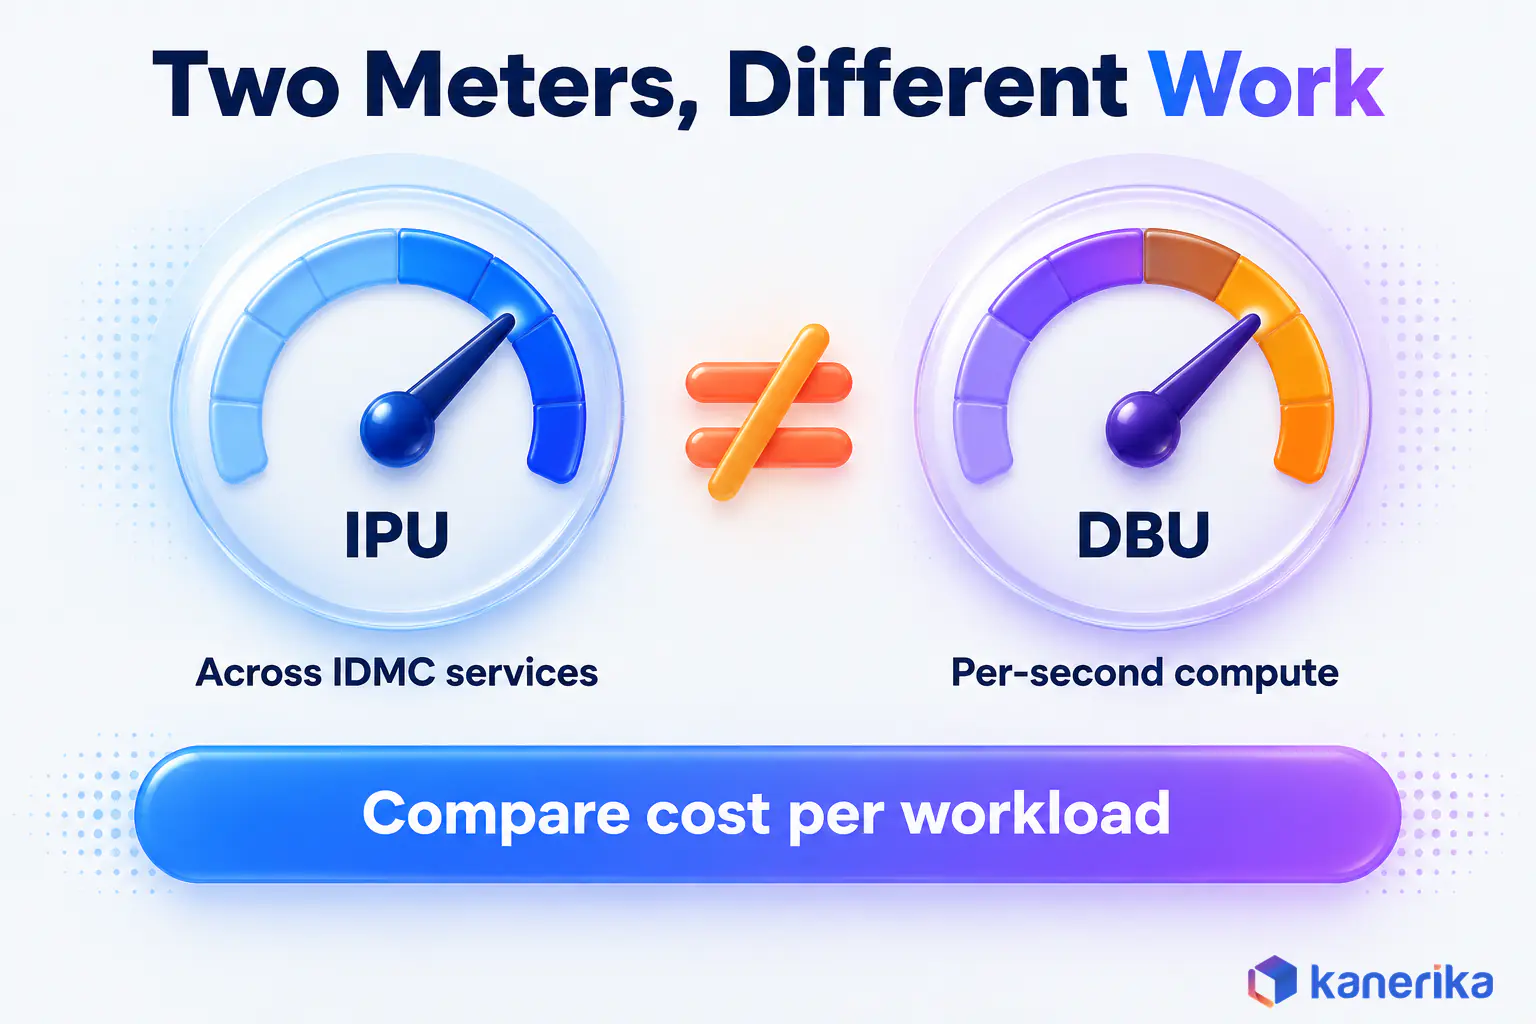
Databricks pricing is pay as you go, with no up-front cost. Usage is billed in Databricks Units (DBUs) at per-second granularity, and committed-use contracts also bring discounts. Unless you use serverless compute, you also pay your cloud provider for the infrastructure underneath, so read DBU rates and cloud costs together.
The trap is comparing one IPU price with one DBU price. They do not measure the same thing. The only fair unit is cost per workload, meaning the yearly cost of one pipeline at its real volume on each platform.
| Pricing question | Informatica | Databricks |
|---|---|---|
| Unit | IPU | DBU |
| What it meters | Use of eligible IDMC services | Compute used, per second |
| Commitment | Pooled IPU purchase | Pay as you go, or committed use for discounts |
| Costs to add | Extended Support fees if still on PowerCenter 10.4 | Cloud infrastructure, unless serverless |
| Main cost lever | Size the IPU pool to real use | Right-size compute and commit for discounts |
On the Databricks side, most savings come from compute sizing and scheduling, which our guide to Databricks cost optimization covers in detail.
What a Three-Year TCO Comparison Must Include
A three-year view catches costs that a first-year quote hides, especially the months when both platforms run at once. Count these six items for each option:
- Licenses or IPUs. The Informatica commitment you keep, shrink or end.
- DBU compute and cloud infrastructure. Databricks usage plus the cloud resources beneath it, at real volumes.
- Dual-run period. Months when both platforms run the same pipelines during parallel testing.
- Migration labor. Conversion, testing and validation effort, which grows with mapping count and complexity.
- Extended Support premium. Fees for keeping an older PowerCenter version supported while you move.
- Skills. Training or hiring for the platform you are moving toward.
A Databricks move is not automatically cheaper. It can lower run costs once Informatica is retired, but the dual-run months and migration labor come first. Model both sides before you promise savings.
Migration ROI Calculator
Estimate Your Informatica Migration ROI
Put your mapping count, run costs and timeline into Kanerika’s migration ROI calculator before you compare a three-year Informatica and Databricks TCO.
Calculate Migration ROI →Using Informatica and Databricks Together
Plenty of enterprises run both platforms and give each one the layer it does best.
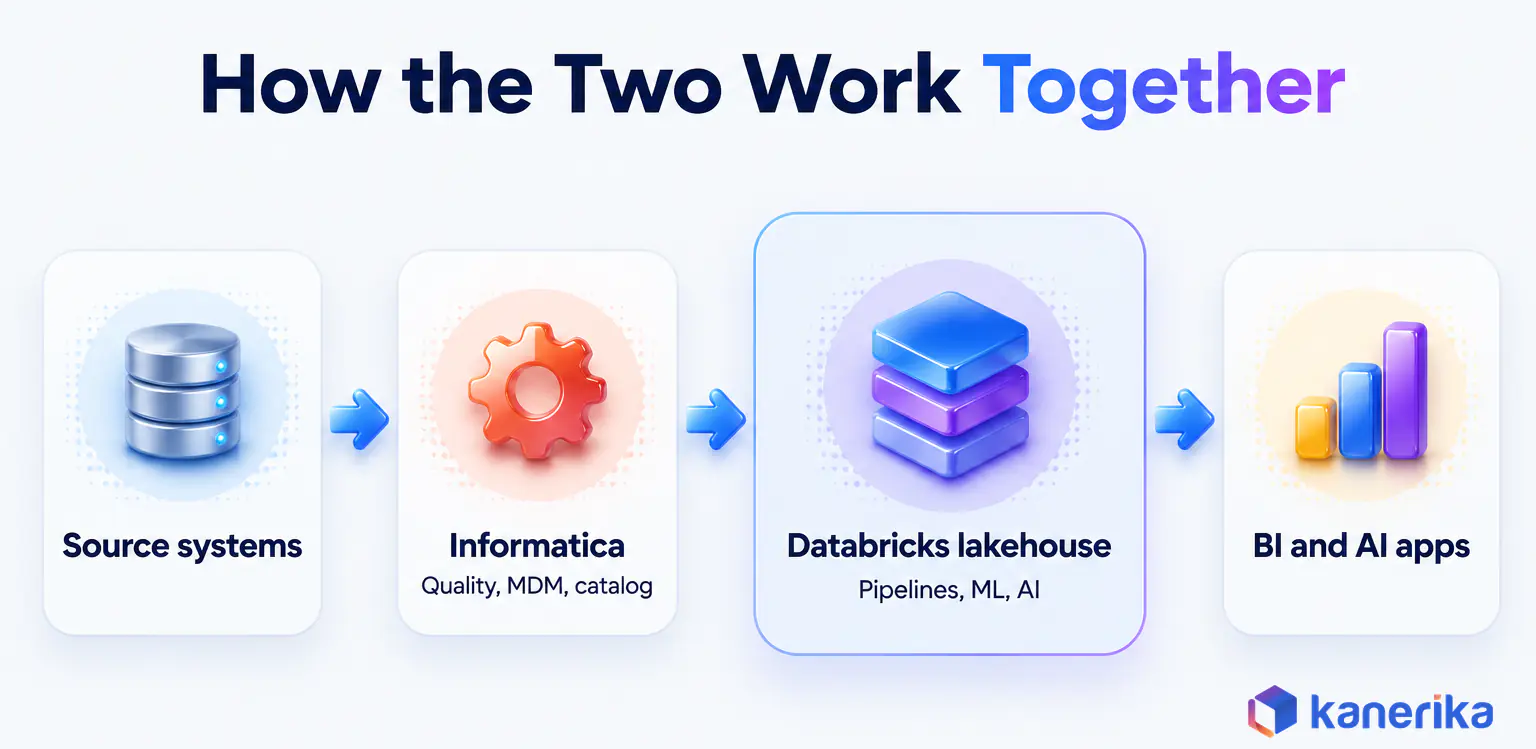
A common split looks like this. Informatica handles ingestion from legacy and operational systems, applies data quality rules and maintains golden records in MDM. Databricks then stores the data in the lakehouse, runs transformations and serves BI dashboards and the AI data pipelines behind models and agents. Unity Catalog governs what lives in Databricks, while Informatica’s catalog gives the enterprise-wide view.
The May 2026 Informatica and Databricks announcement made this pattern easier to run. It listed four items, each at a different stage:
- CDGC extraction of Unity Catalog tags, available since the April 2026 release.
- Headless IDMC MCP servers in Agent Bricks, announced in private preview with general availability targeted for summer 2026.
- A named Lakebase connector, scheduled for Informatica’s October 2026 release.
- MDM golden-record publishing to the lakehouse, through the MDM Extension for Databricks, also scheduled for October 2026.
Check Informatica’s release notes for which of these has shipped before you design around it.
Running both is not free, because you pay two vendors and keep two skill sets. It works best when each tool has a clear, written job, so that no team builds the same pipeline twice.
Which Should You Choose? A Workload-Based Decision Framework
The right answer to Informatica vs Databricks depends on which workloads you run and who runs them, not on which vendor wins a feature checklist. Use the table below to score your own estate one workload at a time.
| Workload or situation | Better fit | Why |
|---|---|---|
| Nightly batch ETL from many legacy sources | Informatica | Mature connectors and mapping skills already in place |
| Streaming and near-real-time pipelines | Databricks | Batch and streaming in one pipeline engine |
| Data quality and master data across systems | Informatica | Dedicated data quality and MDM services |
| Governance for lakehouse data | Databricks | Unity Catalog is native |
| One catalog across many platforms | Informatica | Its catalog scans many systems, including Unity Catalog tags |
| Machine learning, generative AI and agents | Databricks | Agent Bricks, MLflow and model serving on governed data |
| Team of SQL and Python engineers | Databricks | Code-first, with visual prep in Lakeflow Designer |
| Team of mapping developers and data stewards | Informatica | Visual mappings and stewardship tools |
| PowerCenter estate under support pressure | Informatica or Databricks, by workload | Move to IDMC, migrate to Databricks or split the estate |
Count the rows that match your estate. If most lean one way, that platform should own your core stack. If they split, run both with clear layer ownership, as the previous section describes.
Two rows can overrule the count. If golden records are a hard requirement and no other MDM tool is in place, keep Informatica for that layer whatever the tally says. If streaming or agents are on your 12-month roadmap, give the processing layer to Databricks even when batch rows lean the other way.
Team skills deserve extra weight in that count. A platform your people cannot run well will cost more than its price list suggests. Databricks work, in particular, calls for Spark, SQL and Python depth.
When Informatica Is the Better Fit
- Your data comes from many operational and legacy systems, and you need one integration layer across all of them.
- Data quality and master data are core requirements, for example customer or product golden records that feed several systems.
- You need one catalog and governance view across many platforms rather than only the lakehouse.
- Your team is built around visual mapping skills and strict change control.
If Informatica is your likely pick but other ETL tools are still on the table, see how Talend compares with Informatica PowerCenter. Our comparison of Informatica, Azure Data Factory and Talend also covers the cloud ETL options.
When Databricks Is the Better Fit
- Your analytics, data science and AI work already runs on a lakehouse, or soon will.
- Streaming and near-real-time pipelines matter as much as nightly batch.
- Your engineers work in SQL and Python, while analysts want visual prep on the same data.
- You want one platform and one governance layer, Unity Catalog, for data and AI assets.
For the transformation layer alone, our breakdown of dbt, Informatica and Azure Data Factory may help. If Databricks is the front-runner, also weigh Databricks vs Snowflake and Microsoft Fabric vs Databricks before you sign.
What to Do With a PowerCenter Estate
A PowerCenter estate turns the platform choice into a deadline. PowerCenter 10.4 moved to paid Extended Support on March 31, 2024. Informatica’s own notice listed three options: move to IDMC, buy Extended Support or upgrade to 10.5.
Migration vendors report that standard support for 10.5 ended in March 2026, so confirm your contract dates with Informatica before you plan. From there, three paths are open:
- Stay with Informatica. Modernize to IDMC, either by converting mappings to cloud-native ones or through PowerCenter Cloud Edition. This keeps skills and governance in place.
- Move to Databricks. Convert mappings and workflows to Lakeflow pipelines or Spark code, ideally with an accelerator. This puts engineering and AI on one platform.
- Split by workload. Move analytics-bound pipelines to Databricks and keep quality, MDM and catalog in Informatica.
Case Study
71% Higher Reporting Accuracy After an Informatica to Databricks Migration
A healthcare provider moved batch-heavy Informatica pipelines to Azure Databricks with Kanerika’s migration accelerator and a central rule framework, and cut data handling costs by 38%.
Read the Case Study →A simple rule picks the path. Choose the first when most mappings feed systems outside the lakehouse, and the second when most already feed Databricks. Choose the third when the estate splits roughly evenly. The how-to detail for the second path, from mapping conversion to data type handling, lives in our Informatica to Databricks migration guide.
Four Mistakes Teams Make When Comparing Them
The same four errors come up in most evaluations, and each one is cheap to catch before the contract is signed.
- Treating it as like-for-like. One tool manages data across systems and the other runs a lakehouse, so a feature-by-feature scorecard misses the point.
- Assuming Databricks is always cheaper. Dual-run months, migration labor and skills can outweigh first-year savings.
- Ignoring data quality and MDM. Retiring Informatica without a plan for golden records moves the problem into every downstream report.
- Skipping a parallel run. Without side-by-side output checks, small logic differences surface after cutover, when they cost the most.
Moving Informatica Workloads to Databricks: A Four-Stage Plan
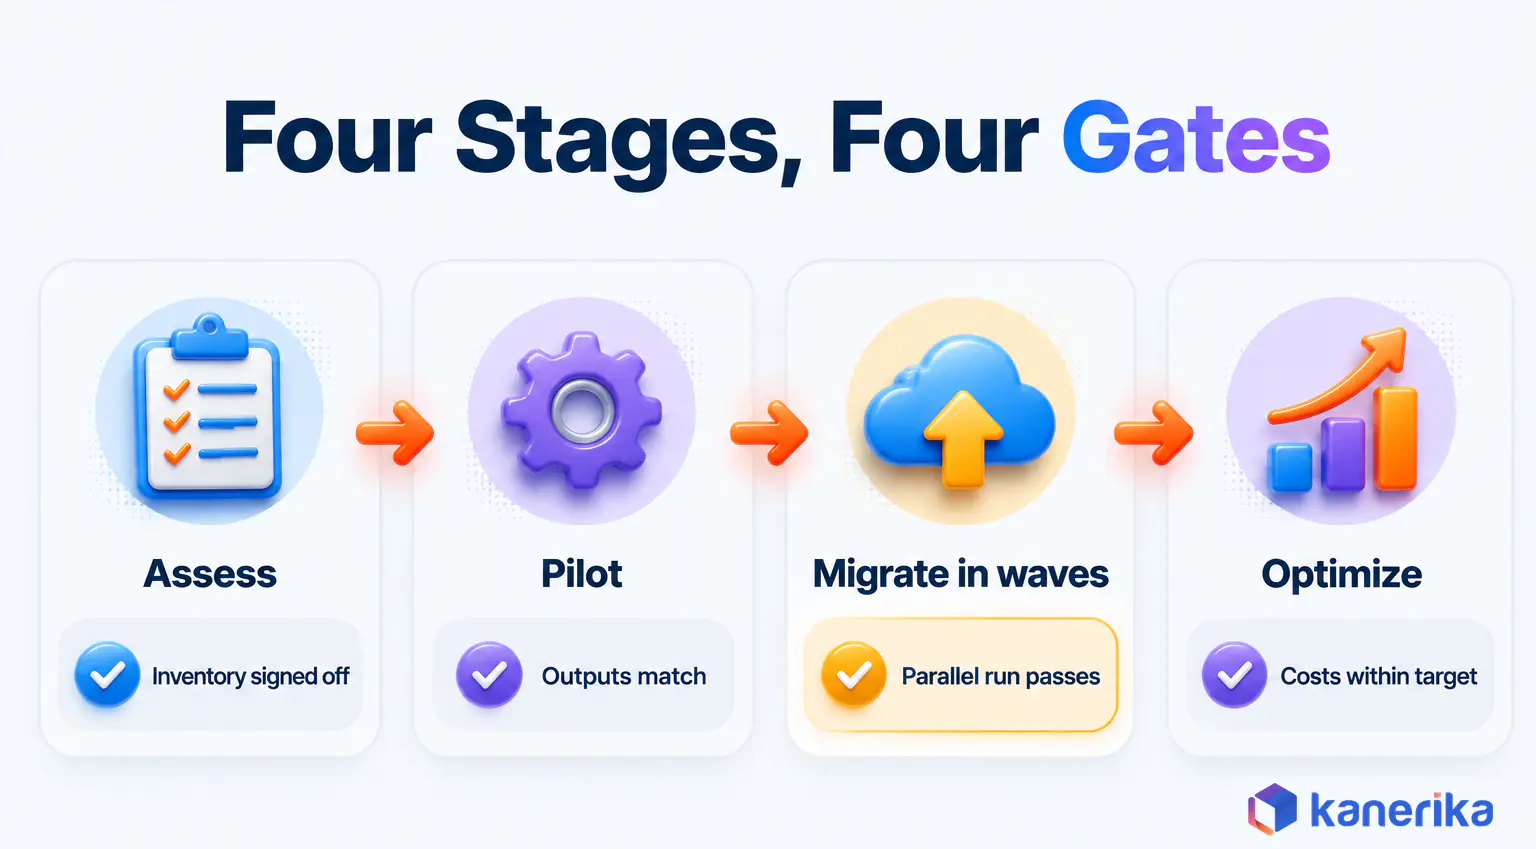
If your decision lands on Databricks for some or all workloads, the move itself follows a predictable shape. Each stage below ends with a gate, and you only move on when the gate is met.
The gates matter more than the stage names. A team that skips the pilot gate usually finds its logic gaps during the first wave, when fixing them costs far more.
- Assess. Inventory every mapping, workflow, source and target, then rank them by complexity and business value. Gate: a signed-off inventory and a target architecture.
- Pilot. Convert a small, representative set of pipelines and run them on Databricks. Gate: outputs match the Informatica results on real data.
- Migrate in waves. Move pipelines in groups, running each wave in parallel with Informatica until results reconcile. Gate: the parallel run passes and data owners sign off.
- Optimize. Tune compute, schedules and storage, then retire the Informatica jobs you replaced. Gate: run costs fall within the target set in your TCO model.
Tooling can shorten the first and last stages. Databricks Lakebridge is a free tool for assessing legacy code, converting it and validating the results. Check which source technologies it supports for your estate, then read our Lakebridge guide for how it works.
Partner accelerators handle conversion of Informatica mappings specifically. The wider planning work, however, is the same as any enterprise data migration, with clear owners, frozen scope per wave and a rollback plan.
How Kanerika Helps You Choose and Migrate
Kanerika works on both sides of this decision as a certified Databricks partner with a dedicated Informatica to Databricks migration practice. We start with the layer map in this guide, then decide which workloads move and which stay.
For the workloads that move, our FLIP Migration Accelerator converts PowerCenter mappings and workflows into Databricks-native pipelines. FLIP is listed on Azure Marketplace and is MACC-eligible, so Azure customers can count it toward their Microsoft commitment.
One example is a leading healthcare provider that struggled with batch-heavy Informatica pipelines as well as inconsistent coding rules across clinical, claims and billing data. Kanerika migrated its workflows to Azure Databricks with the accelerator, re-architected the pipelines and built a central rule framework. The result was 71% higher reporting accuracy, 38% lower data handling costs and 64% faster decision-making, as the full case study shows.
Teams that want to keep Informatica for quality and MDM get the same layer-by-layer plan, while Databricks takes the processing and AI work. Our Databricks services cover the lakehouse side end to end.
Kanerika Service
Informatica to Databricks Migration Services
Kanerika assesses your Informatica estate, decides which workloads move and converts PowerCenter mappings and workflows into Databricks-native pipelines with FLIP.
Explore the Migration ServiceThe Bottom Line on Informatica vs Databricks
Informatica and Databricks overlap more than they used to, but they still own different layers. Informatica is the stronger choice for integration, quality, MDM and a catalog across many systems. Databricks is the stronger choice for lakehouse engineering, streaming and AI on one platform.
Many enterprises will run both, with written rules about which tool owns which layer. A PowerCenter estate adds a deadline, so price all three paths over three years before you renew.
So which should you choose? Pick Informatica to manage data across many systems, pick Databricks to process it and build AI, and run both when you need both layers.
Frequently Asked Questions
What is the main difference between Informatica and Databricks?
Informatica is a data management platform that integrates, cleans, masters and catalogs data across many systems. Databricks is a lakehouse platform that stores and processes data and builds AI on it. They overlap in ingestion and pipelines, so the real difference is which layer each one owns. Many enterprises run both with clear ownership rules.
Does Databricks have its own ETL tool?
Yes. Databricks Lakeflow covers the full ETL flow. Lakeflow Connect ingests data from databases, SaaS apps, files and streams, Lakeflow Spark Declarative Pipelines transform it in SQL or Python, and Lakeflow Designer gives analysts a visual, no-code canvas. Unity Catalog governs every table these tools create, so a separate ETL product is optional rather than required.
Who competes with Informatica?
Informatica competes with cloud integration services such as Azure Data Factory and AWS Glue, and with tools like Talend and Fivetran. Lakehouse platforms such as Databricks now compete too, because they ship their own ingestion and pipelines. In data quality, catalog and MDM it faces specialist vendors, so the overlap depends on which service you use.
Can Informatica and Databricks be used together?
Yes, and many enterprises run them side by side. A common pattern uses Informatica for ingestion, data quality, MDM and an enterprise catalog, and Databricks for storage, processing and AI. The two vendors announced deeper integration in May 2026, including Unity Catalog tag extraction in Informatica’s catalog and MDM golden-record publishing to the lakehouse.
Which platform is better for real-time data processing and CDC?
Databricks is the stronger fit when streaming and analytics run on the same platform, because Lakeflow pipelines handle batch and streaming together and read from Kafka, Kinesis, Event Hubs and similar sources. Informatica is strong for change data capture from many operational systems under central control. Some teams combine the two, using Informatica CDC to feed Databricks.
Can Databricks replace Informatica PowerCenter?
For many workloads, yes. PowerCenter mappings and workflows can be converted to Lakeflow pipelines or Spark code, often with an accelerator that automates much of the conversion. Data quality rules and MDM need a separate plan, since those are Informatica strengths. Run a pilot and a parallel run on real data before you retire any PowerCenter job.
Which is better for data governance, Informatica or Databricks?
It depends on scope. Unity Catalog is native to Databricks and governs access, lineage and audit for everything on the lakehouse. Informatica governs across many platforms with an enterprise catalog, data quality rules and MDM. If most of your data lives in Databricks, Unity Catalog may be enough. If it spans many systems, Informatica adds coverage.
How long does an Informatica to Databricks migration take?
There is no standard timeline, because duration depends on the number and complexity of mappings, the sources involved and how long the parallel run lasts. A small estate with simple batch jobs moves far faster than thousands of mappings with complex logic. Start with an assessment and a pilot, then estimate the waves from measured pilot results.
What are the risks of migrating Informatica to Databricks?
The main risks are logic differences that change results, gaps in data quality and MDM coverage, underestimated dual-run costs and a skills gap on the Databricks side. Each one is manageable. Inventory every mapping, pilot on real data, run each wave in parallel until results reconcile and plan training before cutover, not after it.
Which platform is better for AI and machine learning?
Databricks is the better platform for building AI and machine learning. Agent Bricks, MLflow and model serving support model building, lifecycle tracking and AI agents on governed lakehouse data. Informatica’s CLAIRE engine applies AI to data management tasks instead. The two can work together, with Informatica supplying trusted master data that Databricks models and agents use.
Is Databricks a database or an ETL tool?
Databricks is neither in the traditional sense. It is a data and AI platform built on a lakehouse, which stores data in open formats on cloud storage. On top of that it runs SQL analytics, ETL pipelines, streaming and machine learning. Teams use it heavily for ETL, but ETL is one workload among several on the platform.
Which is the best ETL tool in 2026?
No single ETL tool is best for every team. Informatica suits enterprises with many legacy sources and strict data quality needs. Databricks Lakeflow suits teams building on a lakehouse with SQL and Python skills. Azure Data Factory, Talend and dbt fit other patterns. Test your own sources and workloads on a pilot before choosing any of them.
How do costs compare between Informatica and Databricks?
Both charge by consumption, but the units differ. Informatica sells Informatica Processing Units, or IPUs, spent across IDMC services, while Databricks bills Databricks Units, or DBUs, per second of compute, usually plus cloud infrastructure. Because the units measure different work, compare cost per workload over three years, including migration labor, dual-run months and support fees.
Which is easier for non-technical users?
Informatica has long been the easier choice for non-coders because of its visual mapping designer. Databricks narrowed that gap with Lakeflow Designer, a visual, no-code data prep tool with a drag-and-drop canvas and natural language prompts. For business analysts, test both on a real data set, since ease of use depends on your sources and existing skills.
What is a major weakness of Databricks?
Databricks asks more of your team than a packaged ETL tool does. Getting full value takes engineers who know Spark, SQL and Python, plus discipline around compute sizing and cost control. Without cost guardrails, consumption billing can surprise teams that are new to the platform. Data quality and MDM also need their own plan.
What is replacing Informatica PowerCenter?
Informatica’s own successor is IDMC, its cloud platform, which PowerCenter customers can reach by converting mappings or through PowerCenter Cloud Edition. Many enterprises instead move PowerCenter workloads to a lakehouse such as Databricks, often with a conversion accelerator. Others split the estate, moving analytics pipelines to Databricks and keeping data quality and MDM in Informatica.
Is Informatica end of life?
No. Informatica is an active business and has been part of Salesforce since November 18, 2025. What is ending is support for older PowerCenter versions. Version 10.4 moved to paid Extended Support in March 2024, and migration vendors report that standard support for 10.5 ended in March 2026. Confirm your own contract dates with Informatica.
Who is the biggest competitor of Databricks?
Snowflake is usually named as the biggest competitor of Databricks, since both sell cloud data platforms for analytics and AI. Microsoft Fabric, Google BigQuery and the AWS data services compete for the same budgets. The right comparison depends on your cloud provider, your workloads and whether your team works mainly in SQL or in Python.