TL;DR
Microsoft Fabric Copilot needs a paid Fabric capacity of size F2 or larger, and it does not work on a free trial. There is no extra license to buy, and a typical prompt costs about two cents of capacity. If you already pay for Fabric in the US or EU, Copilot is on by default, so decide who should use it first. Teams with only Power BI Pro licenses need a Fabric Copilot capacity before they can use it. Test it with one small team for 30 days, using questions whose answers you already know. Good answers depend on a clean data model with clear names and descriptions.
Key Takeaways
- Fabric Copilot needs a paid F2+ or P1+ capacity in a supported region. Trial capacities and sovereign clouds are excluded.
- The old “F64 or higher” rule is out of date. Smaller SKUs work, and a Fabric Copilot capacity covers Pro, PPU and Power BI Desktop users.
- Each request bills capacity units per 1,000 tokens as a background job smoothed over 24 hours, and output tokens cost four times as much as input.
- Copilot only sees data the signed-in user can already see, and Microsoft does not use your prompts or data to train models.
- A well-described semantic model and a 30-day pilot scorecard decide answer accuracy far more than any prompt trick.
- Fabric data agents differ from Copilot because your team builds, configures and shares them, while Copilot comes preconfigured in each tool.
Watch on YouTube
AI That Talks to Your Data: Fabric Data Agents | Amit Chandak, Microsoft MVP
Amit Chandak, Microsoft MVP and the author of this guide, walks through Fabric data agents, the configurable assistants that sit beside Copilot and answer repeat business questions from your data.
The Margin Number That Did Not Match the Board Deck
Picture a CFO typing a simple question into Copilot in Power BI. What was Q3 gross margin by region? The answer arrives in seconds, neatly charted, and it is two points off the figure in the board deck.
Copilot itself worked exactly as designed. The trouble sat in the semantic model, which held two margin measures with similar names, one before freight and one after. Copilot picked the one a person would also have guessed, and it guessed wrong.
That small scene captures how Copilot behaves inside Fabric. The model is capable, but it can only work with the names, relationships and definitions you give it. Licensing, capacity and cost decisions also matter, because they decide whether a rollout gets off the ground.
This guide explains what Microsoft Fabric Copilot does in each workload and what you need before turning it on. After that, it shows how to enable it, budget for it and prove it works in a 30-day pilot.
What Is Microsoft Fabric Copilot and How Does It Work?
Microsoft Fabric Copilot is a set of generative AI assistants built into the Fabric workloads, from Power BI reports to notebooks and SQL editors. You describe what you want in plain English, and Copilot then drafts a report page, a query, a transformation or a summary. It runs on Azure OpenAI models that Microsoft controls, not the public OpenAI service, unless an admin opts in to OpenAI as a subprocessor.
Fabric itself is Microsoft’s unified analytics platform, with OneLake storage under data engineering, warehousing, real-time analytics and Power BI. If you need the platform basics first, start with our overview of what Microsoft Fabric is. Our breakdown of Microsoft Fabric architecture shows how those layers share one copy of the data. The rest of this guide assumes you know the workloads and want Copilot working inside them.
Every Copilot request follows the same path, which Microsoft describes in its Copilot privacy and security documentation. In short, there are four steps.
- You write a prompt. For example, “show net sales by region as a bar chart” or “explain why this cell failed”.
- Copilot grounds the prompt. It adds context such as table and column names, the item you have open and the recent conversation.
- Azure OpenAI drafts a response. Copilot then post-processes it, which can include responsible AI checks and content filtering.
- You review the output. You keep, edit or discard it before it goes anywhere near a report or pipeline.
Why Your Metadata Decides Answer Quality
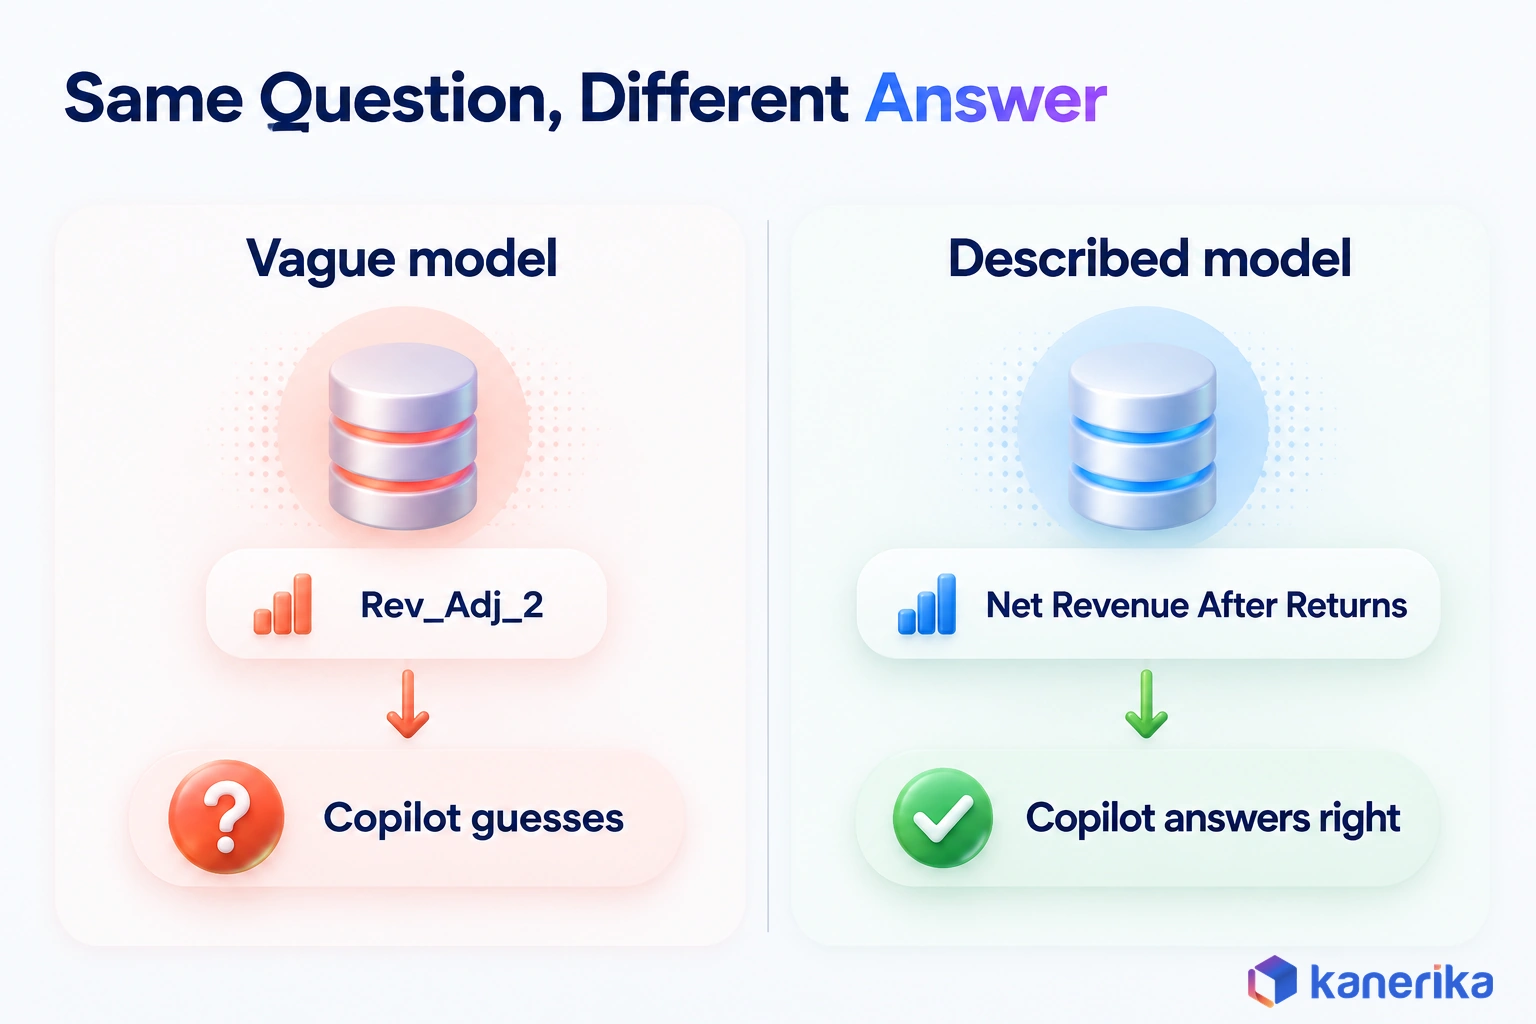
Step two explains the CFO’s problem. Copilot never reads the business glossary that lives in someone’s head. It reads your metadata, so vague names produce vague answers, while clear names and descriptions produce answers you can check.
That is also why two teams on the same capacity can have very different experiences. For example, the team with a tidy, documented model gets useful drafts on the first try. The team with cryptic column names, by contrast, spends its time correcting Copilot.
Case Study
95% Fewer Reporting Man-Hours on a Governed Fabric Lakehouse
A leading pharma manufacturer consolidated Model N, SQL Server, SAP and SAP Vistex data into a Fabric lakehouse with Power BI reporting. It is the kind of governed foundation Copilot answers depend on.
Read the Case Study →
What Copilot Can Do in Each Fabric Workload
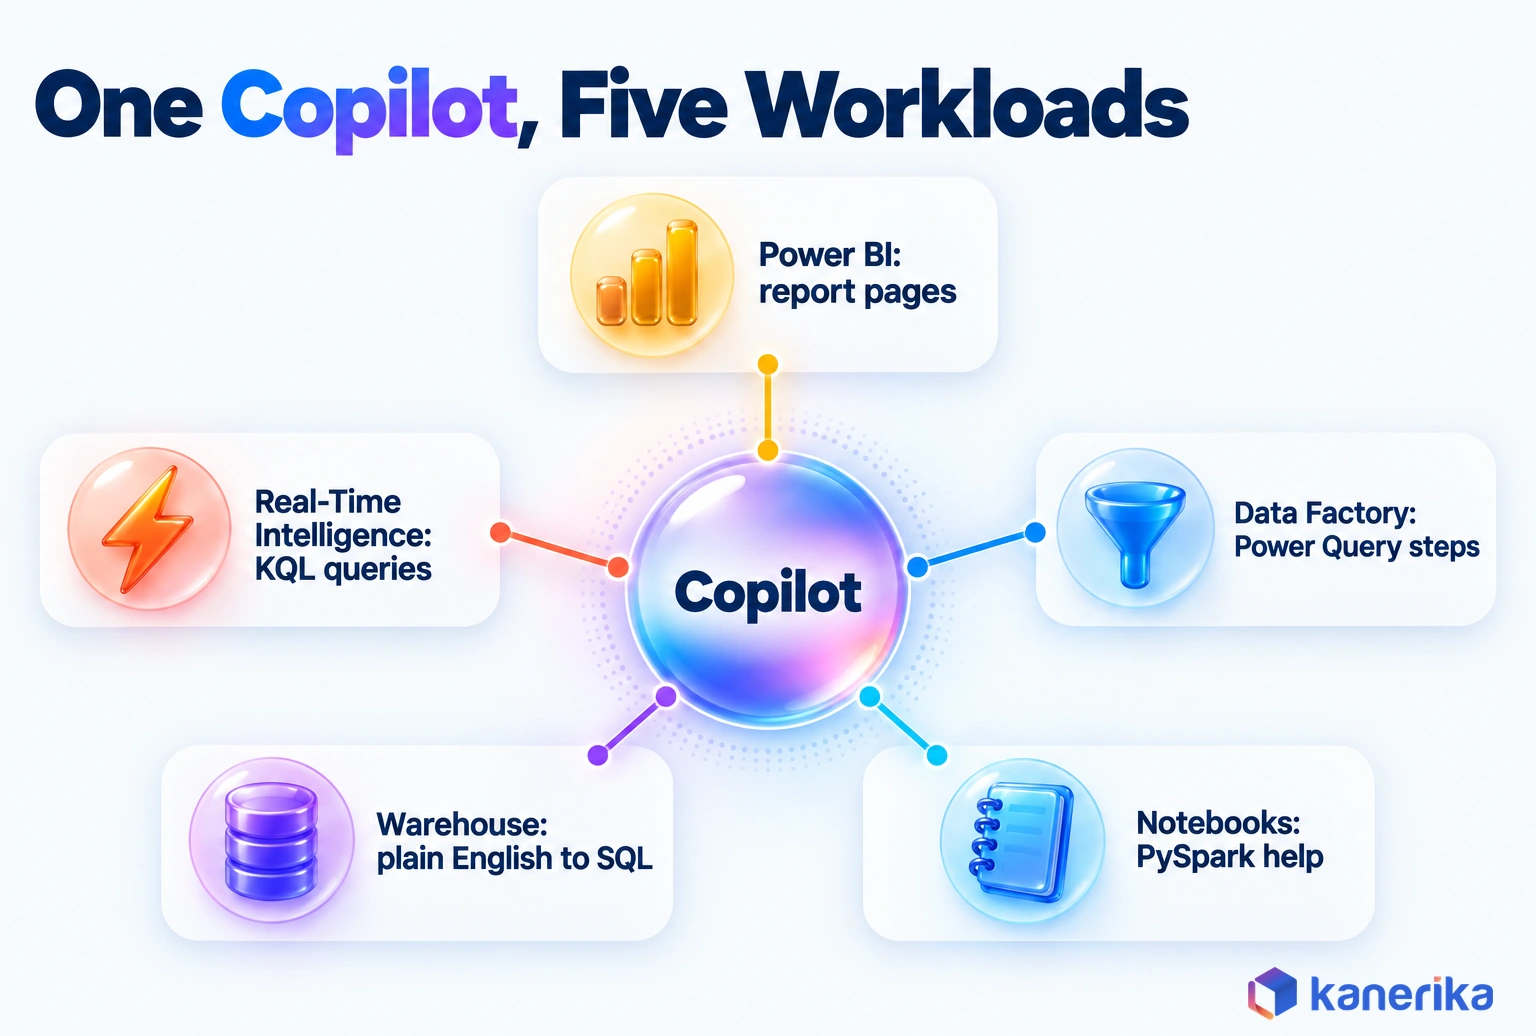
Each Fabric workload gets its own Copilot, tuned to the job done there. The same rules on capacity, permissions and billing apply to all of them, yet what they produce differs a lot.
The Copilot in Fabric overview lists each experience and its release status. Status varies by feature, and several were still in preview in October 2026, so check the page before you promise a capability to users.
Copilot for Power BI
Power BI is where most people meet Copilot first. Report authors can ask it to draft a report page from a semantic model. Business users, for their part, ask it to summarize a page or answer a question about the numbers on it.
It can also suggest synonyms for Q&A, which helps when people call the same field revenue, sales and turnover. Copilot works in Power BI Desktop too, as long as you connect to a workspace on a Copilot-enabled capacity. App-scoped Copilot, which answers only from the content of a published Power BI app, was still in preview in October 2026.
Copilot for Data Factory and Dataflow Gen2
In Dataflow Gen2, Copilot turns a plain-English request into Power Query steps. Type “remove rows where the order date is blank” or “group sales by month and region”, and it adds the steps for you to inspect.
It can also explain an existing query step by step, which helps when you inherit a dataflow someone else built. A filter that looks right can still drop rows you needed, so compare row counts before you publish. For pipelines, connectors and scheduling beyond dataflows, see our guide to Data Factory in Microsoft Fabric.
Copilot in Notebooks for Data Engineering and Data Science
Notebook Copilot is context-aware from the moment you open a notebook, with no need to start a Spark session first. It knows the attached lakehouse tables and files, the notebook’s structure and the runtime state, so it writes PySpark that uses your real column names.
When a cell or Spark job fails, Fix with Copilot (in preview) summarizes the error, suggests a root cause and proposes a fix. It shows the change as an approval diff, so you decide what gets committed. To move results between a notebook and a warehouse, see our guide to PySpark notebooks in a Fabric warehouse.
Copilot for Data Warehouse and SQL Database
For SQL work, Copilot turns a question into T-SQL, completes code as you type and offers quick actions such as explaining or fixing a query. When you connect to a Fabric SQL database, SSMS 22 gives you the same Copilot help. The MSSQL extension for VS Code, by contrast, brings GitHub Copilot grounded on that database.
Read the joins and filters before you run generated SQL against production tables. A missing join condition, for instance, can return a confident total that is simply wrong.
Copilot for Real-Time Intelligence
In Real-Time Intelligence, Copilot translates questions into Kusto Query Language (KQL). It works in the KQL queryset editor and inside dashboard tile editing. For example, an operations analyst can ask for failed logins per hour over the last day and then refine the query from there.
That lowers the bar for teams who know their data but not KQL syntax. Our walkthrough of event streaming with KQL in Microsoft Fabric also shows those queries in context. For the wider picture of eventstreams, Eventhouse and alerts, see our guide to Real-Time Intelligence in Microsoft Fabric.
Prompt Examples to Try First
Good prompts name the table, the measure and the shape of the answer you expect. Use the examples below as templates, then swap in your own table and measure names.
| Prompt | Workload | What to check before you trust it |
|---|
| Create a report page showing net revenue by region and month from the Sales model | Power BI | That it used the approved revenue measure, not a lookalike |
| Summarize this page for an executive in five bullets | Power BI | That every number in the summary appears on the page |
| Remove rows where OrderDate is blank, then group by month | Dataflow Gen2 | Row counts before and after the new steps |
| Load the customers table and show null counts per column | Notebook | That it read the right lakehouse table |
| Write a query for the top 10 products by margin last quarter | Warehouse | Join keys, the date filter and the margin definition |
| Show error events per hour for the last 24 hours | Real-Time Intelligence | Time zone and the event filter |
The last column matters most. Each check takes only a minute, yet it is what separates a useful draft from a number that ends up in the wrong meeting.
What Do You Need Before You Turn On Fabric Copilot?
Before anyone sees the Copilot button, four things must line up. You need the right capacity, a supported region, the right tenant settings and a workspace on that capacity. Older guides, including the first version of this one, said you needed F64 or higher. Microsoft has since lowered that bar a long way.
Microsoft’s guide to enabling Copilot in Fabric lists a paid Fabric F2 or higher, or Power BI Premium P1 or higher. If you only want Copilot for Power BI, a P SKU can run it without switching on other Fabric workloads. Our comparison of Microsoft Fabric vs Power BI explains where those licenses split. The table below also adds the traps that catch teams on each requirement.
| Requirement | Detail | Common trap |
|---|
| Capacity | Paid Fabric F2 or higher, or Power BI Premium P1 or higher | Assuming F64 is required and over-buying |
| Not a trial | Azure OpenAI, including Copilot, is not available on trial SKUs | Testing Copilot during a Fabric trial and concluding it is broken |
| Region | Copilot’s Azure OpenAI runs in the US and the EU Data Boundary; other Fabric regions need cross-geo processing | Capacity outside the US or EU Data Boundary with cross-geo processing off |
| Cross-geo settings | Tenant settings that let data be processed or stored outside the capacity’s geography | Leaving the decision to default and hearing about it from users |
| Pro and PPU workspaces | Need a Fabric Copilot capacity to carry the usage | Expecting Pro licenses alone to light up Copilot |
| Power BI Desktop | Must connect to a workspace on a Copilot-enabled capacity | Opening Desktop without choosing an active workspace |
| Cloud | Sovereign clouds are not yet supported, due to GPU availability | Planning a government-cloud rollout around Copilot |
How to Enable Copilot in Microsoft Fabric
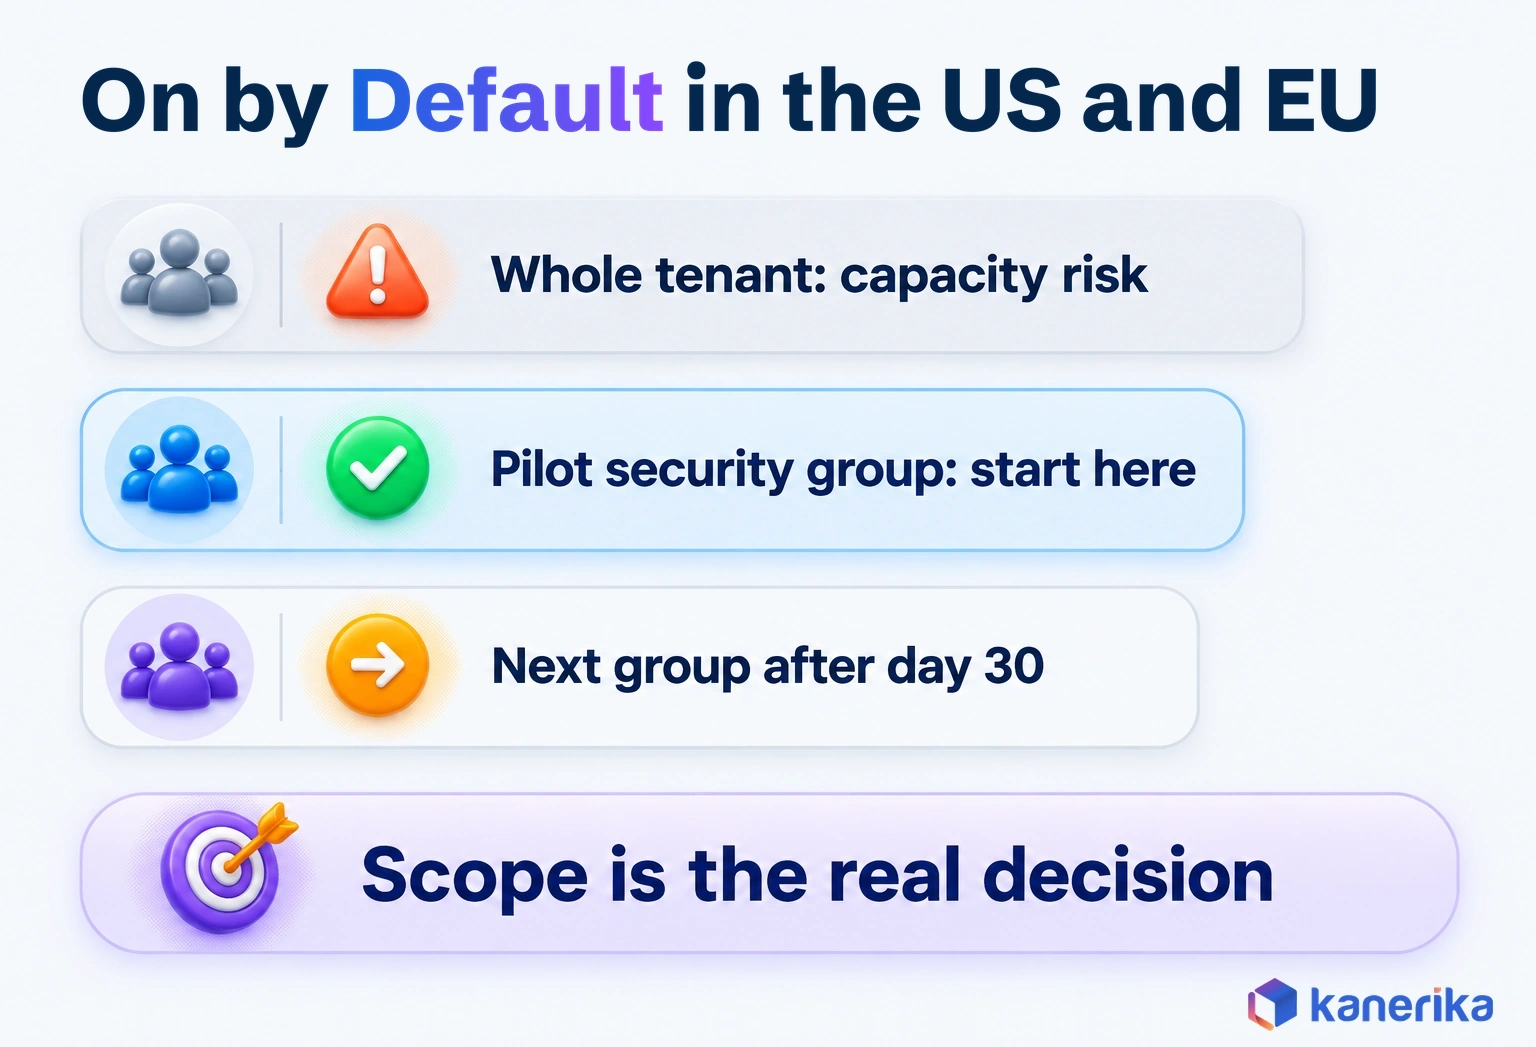
Enabling Copilot is mostly a scoping exercise, because the main switch is often already on. In the US and the EU Data Boundary, Copilot is on by default with paid F2 or larger capacity. Your tenant may therefore already have it live for everyone, planned or not. The steps below follow Microsoft’s order, and the real decision sits in step two, which is who gets Copilot first.
- Check the tenant setting. Sign in to the Fabric admin portal, open Tenant settings and confirm “Users can use Copilot and other features powered by Azure OpenAI” is on.
- Scope it to a security group. Apply the setting to one or more security groups instead of the whole organization. Start with a pilot group that has finished basic training.
- Decide on cross-geo and OpenAI settings. If your capacity sits outside the US or the EU Data Boundary, Copilot stays off until you allow data to be processed outside its geography. Also decide on “Users can use Copilot, AI Agents, and other AI experiences powered by OpenAI as a Microsoft subprocessor”.
- Enable delegated settings. If tenant settings are delegated to capacity admins, each capacity admin must enable the same settings for their capacity.
- Assign the workspace. Put the pilot workspace on a Copilot-enabled capacity and give pilot users the right workspace roles.
- Connect Power BI Desktop. In Desktop, select a workspace on that capacity as the active workspace. Desktop usage then counts against that capacity.
Microsoft itself warns that enabling Copilot for the entire tenant without planning can drive up capacity use. Scoping by security group keeps that risk inside a test you can measure. Widening access later takes one settings change.
Audit Copilot Settings With the Fabric Admin API
Although the admin portal is fine for a one-off check, a script is faster when you need proof of who has Copilot. It also gives you a weekly check that nobody widened access.
The List Tenant Settings API returns every tenant setting with its state, security groups and delegation flags. Because it is an admin API, the caller must be a Fabric administrator or a service principal with Tenant.Read.All. The snippet below keeps only the Copilot and Azure OpenAI settings.
# Sign in as a Fabric administrator, then get a token for the Fabric API
TOKEN=$(az account get-access-token \
  --resource https://api.fabric.microsoft.com \
  --query accessToken -o tsv)

# List tenant settings and keep the Copilot and Azure OpenAI ones
curl -s -H "Authorization: Bearer $TOKEN" \
  "https://api.fabric.microsoft.com/v1/admin/tenantsettings" |
  jq '.value[]
      | select(.title | test("copilot|openai"; "i"))
      | {settingName, title, enabled,
         groups: [.enabledSecurityGroups[]?.name],
         delegateToCapacity}'
Each result shows whether the setting is on, which groups it covers and whether capacity admins can override it. Save the output at pilot start and compare it each week. If the response carries a continuationToken, call the API again with it to fetch the next page.
Why Is Copilot Not Showing in Microsoft Fabric?
When users report a missing Copilot button, the cause is usually a setting rather than a bug. Work down this table from the top, since each row takes only a minute to rule out.
| Symptom | Likely cause | Fix |
|---|
| No Copilot anywhere in a workspace | The workspace sits on a trial capacity | Move it to a paid F2+ or P1+ capacity |
| Copilot missing in a Pro workspace | No Fabric Copilot capacity assigned to the user | Ask a capacity admin to add the user to a Fabric Copilot capacity |
| Colleagues see it and you do not | The tenant setting is scoped to a group you are not in | Ask the Fabric admin to add you to that security group |
| Copilot unavailable for one capacity | Capacity outside the US or EU Data Boundary with cross-geo processing off | Allow cross-geo processing in tenant settings |
| Tenant setting is on, still nothing | The capacity-level setting is off under delegation | The capacity admin enables it in capacity settings |
| Copilot stopped working after a trial ended | The workspace relied on a trial capacity that expired | Reassign the workspace to a paid capacity |
If every row checks out and Copilot still does not appear, wait a while after any settings change. Then have users sign out and back in, and check the Fabric service status before you open a support ticket.
How Much Does Microsoft Fabric Copilot Cost?
Microsoft Fabric Copilot is billed through the capacity you already pay for, by the token. Each request uses capacity units (CUs) from the capacity that holds your content, measured by the tokens you send and receive. That makes Copilot a capacity-planning question as much as a licensing one.
The rates come from Microsoft’s Copilot consumption page, and they apply across Power BI, Data Factory and the other Copilot experiences. Input prompts cost 100 CU seconds per 1,000 tokens, cached input costs 10, and output completions cost 400. As a rule of thumb, 1,000 tokens equal roughly 750 words.
Output tokens cost four times as much as input, so long generated answers drive the bill. Cached input, meanwhile, runs at a tenth of the normal input rate, which rewards repeated prompts against the same context.
Worked Example: What One Copilot Request Costs
Microsoft’s own example request makes the math concrete, so it is worth walking through. It assumes 2,000 input tokens and 500 output tokens. Every figure below follows from the published rates.
| Item | Calculation | Result |
|---|
| Input | 2,000 tokens x 100 CU seconds per 1,000 | 200 CU seconds |
| Output | 500 tokens x 400 CU seconds per 1,000 | 200 CU seconds |
| Total per request | 200 + 200 | 400 CU seconds (6.67 CU minutes, 0.111 CU hours) |
| Cost per request | 0.111 CU hours x $0.18 per CU hour | About $0.02 |
| 1,000 requests | 1,000 x $0.02 | About $20 |
The $0.18 figure is the pay-as-you-go East US list price on the Azure retail price list. It was checked on October 30, 2026, under the Copilot and AI Capacity Usage meter. Prices vary by region and by reservation, so rerun the sum with your own rate.
Copilot runs as a background job, so Fabric smooths its CU use over 24 hours rather than charging it all at once. On an F64, which has 1,536 CU hours a day, Microsoft calculates room for more than 13,824 of these requests daily. In effect, each request’s cost is spread thinly across the day.
The risk sits with small capacities. An F2 holds 48 CU hours a day, enough for about 432 such requests. At the same $0.18 rate, that F2 costs about $263 a month if it runs all 730 hours (2 CUs x 730 x $0.18). Its budget is also shared with every refresh, query and pipeline. Heavy Copilot use on a small, busy capacity can push it into throttling, which slows everything else on it.
For SKU prices and reservation discounts, see our breakdown of Microsoft Fabric pricing and F-SKU costs.
Estimate Copilot Capacity for Your Own SKU
The same arithmetic scales to any SKU, so it is worth scripting once. This Python sketch uses Microsoft’s published rates and the East US price, with each assumption in a comment.
# Copilot rates in CU seconds per 1,000 tokens (Microsoft Learn)
INPUT_RATE, CACHED_RATE, OUTPUT_RATE = 100, 10, 400
PRICE_PER_CU_HOUR = 0.18  # East US pay-as-you-go, October 2026

def request_cost(input_tokens, output_tokens, cached_tokens=0):
    cu_seconds = (input_tokens * INPUT_RATE
                  + cached_tokens * CACHED_RATE
                  + output_tokens * OUTPUT_RATE) / 1000
    dollars = cu_seconds / 3600 * PRICE_PER_CU_HOUR
    return cu_seconds, dollars

def daily_requests(sku_cus, cu_seconds_per_request, copilot_share=1.0):
    # An F-SKU's number is its CU count, so an F8 has 8 CUs
    return int(sku_cus * 86400 * copilot_share // cu_seconds_per_request)

cu_s, usd = request_cost(2000, 500)
print(cu_s, round(usd, 3))              # 400.0 0.02
print(daily_requests(2, cu_s))          # 432 on a whole F2
print(daily_requests(8, cu_s, 0.25))    # 432 on an F8 at a 25% share
print(daily_requests(64, cu_s, 0.25))   # 3456 on an F64 at a 25% share
Planning happens in the copilot_share argument. A 25% share is an assumption for illustration, not a Microsoft figure, but it leaves room for refreshes and queries. At that share, an F2 carries about 108 typical requests a day, an F8 about 432 and an F64 about 3,456.
For example, take a pilot of 20 users who each send 15 prompts a day. That is 300 requests, which fits an F8 at a quarter share but would take about 70% of an F2. If your pilot needs more than its share, give it a separate capacity designated as a Fabric Copilot capacity, so refreshes keep theirs.
Fabric Copilot Capacity: One Bill for Copilot Usage
By default, Copilot usage bills to whichever capacity holds the content a user is working in. A Fabric Copilot capacity changes that by billing every Copilot and data agent request from its assigned users to one designated capacity.
Setting one up takes two admins. The Fabric admin enables Copilot and lets capacity admins designate a Copilot capacity. The capacity admin then assigns a group of users, who need no extra steps.
It also covers cases that otherwise fail. Examples include Copilot in Power BI Desktop, Pro or PPU workspaces, and Copilot or data agents on SKUs smaller than F64. Choose one for Pro or PPU workspaces and Power BI Desktop, or when Copilot traffic would pass a quarter of a shared capacity. For finance, it turns Copilot spend into one line to watch instead of a cost spread across every departmental capacity.
Talk to Kanerika
Planning Capacity and Copilot Costs?
Kanerika’s Fabric team sizes your capacity, models Copilot token spend and helps you decide whether a Fabric Copilot capacity makes sense, then scopes a pilot group.
Talk to a Fabric Expert →
Is Your Data Ready for Copilot?
Copilot answers are only as good as the semantic model and tables underneath them. In a February 2025 forecast, Gartner predicted that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data. This is also where the CFO’s margin problem from the opening gets fixed, and your BI team can start the work before anyone gets access.
Power BI’s Prep data for AI features (preview, October 2026) let model owners add an AI data schema, verified answers and AI instructions. Together they tell Copilot which fields matter, which answers are approved and which business rules to follow. Use this checklist before a pilot starts.
- Rename tables and columns in business language. “Rev_Adj_2” tells Copilot nothing, while “Net Revenue After Returns” tells it exactly what the column holds.
- Add descriptions. Describe tables, columns and measures, especially where two measures sound alike, as in the CFO’s margin case.
- Check relationships. Remove ambiguous paths between fact tables so there is one sensible way to join them. A star schema makes that easiest.
- Mark the approved measures. Name the approved measures in their descriptions, hide helper columns, then mark the model Approved for Copilot in its settings.
- Set the AI data schema and verified answers. Limit Copilot to the fields that matter, and save approved answers for the most common questions.
- Write a test question set. List 20 to 30 real business questions with known correct answers, signed off by the data owner.
Start With the Test Question Set
In our readiness assessments we write the question set first, because it is what makes a pilot measurable. Without known answers, nobody can tell whether Copilot is right or simply fluent.
The rest of the list is classic modeling discipline, and it also pays off for human report users. Our guide to Power BI data modeling best practices covers star schemas, naming and measure design in more depth.
Fabric Copilot vs Fabric Data Agents: Which Do You Need?
Copilot and data agents both answer questions in plain English, but they suit different jobs. Copilot comes preconfigured inside each workload, while a data agent is something your team builds, configures and shares.
A Fabric data agent is generally available and, like Copilot, needs F2 or higher or P1 or higher. You point it at up to five sources, such as lakehouses, warehouses, semantic models and KQL databases. Then you add instructions and example queries so it answers the way your business expects. Our guide to Microsoft Fabric data agents also walks through that setup step by step.
| Dimension | Copilot in Fabric | Fabric data agent |
|---|
| Setup | Preconfigured, on by default with paid capacity | Built and configured by a data team |
| Scope | Tasks inside the item you have open, such as notebook code or warehouse queries | Questions across up to five chosen data sources |
| Customization | Your prompts, plus Prep data for AI on semantic models | Instructions and example queries per agent |
| Sharing | Available to anyone with access and the tenant setting | Published and shared with colleagues, like a report |
| Governance | User permissions and tenant settings | User permissions, plus Purview controls (preview) |
| Reach outside Fabric | Stays inside the Fabric and Power BI experiences | Can connect to Copilot Studio, Microsoft Foundry (formerly Azure AI Foundry), Teams and Microsoft 365 Copilot |
Which One Fits Your Team?
In practice, the choice usually follows the user, so pick the row that matches who will ask the questions.
| Choose this when | Pick |
|---|
| You build reports, queries or code and want help inside the tool | Copilot in Fabric |
| A business team needs consistent answers from a curated set of sources | Fabric data agent |
| You want that same agent inside Teams, Microsoft 365 Copilot or a custom app | Fabric data agent, extended through Copilot Studio or Microsoft Foundry |
You can run both side by side, with Copilot for builders and a few data agents for repeat business questions. To publish an agent into Teams, our guide to Copilot Studio covers the low-code route. For the latest announcements on both, see our roundup of agents and Copilot updates in Fabric.
Case Study
90% Fewer Data Query Errors with Microsoft Copilot in Teams
A California dairy paired Microsoft Copilot with Power Automate and Azure SQL so its sales team could ask data questions in Teams and an intranet chatbot. Decisions came 30% faster.
Read the Case Study →
Security, Privacy and Governance Controls for Fabric Copilot
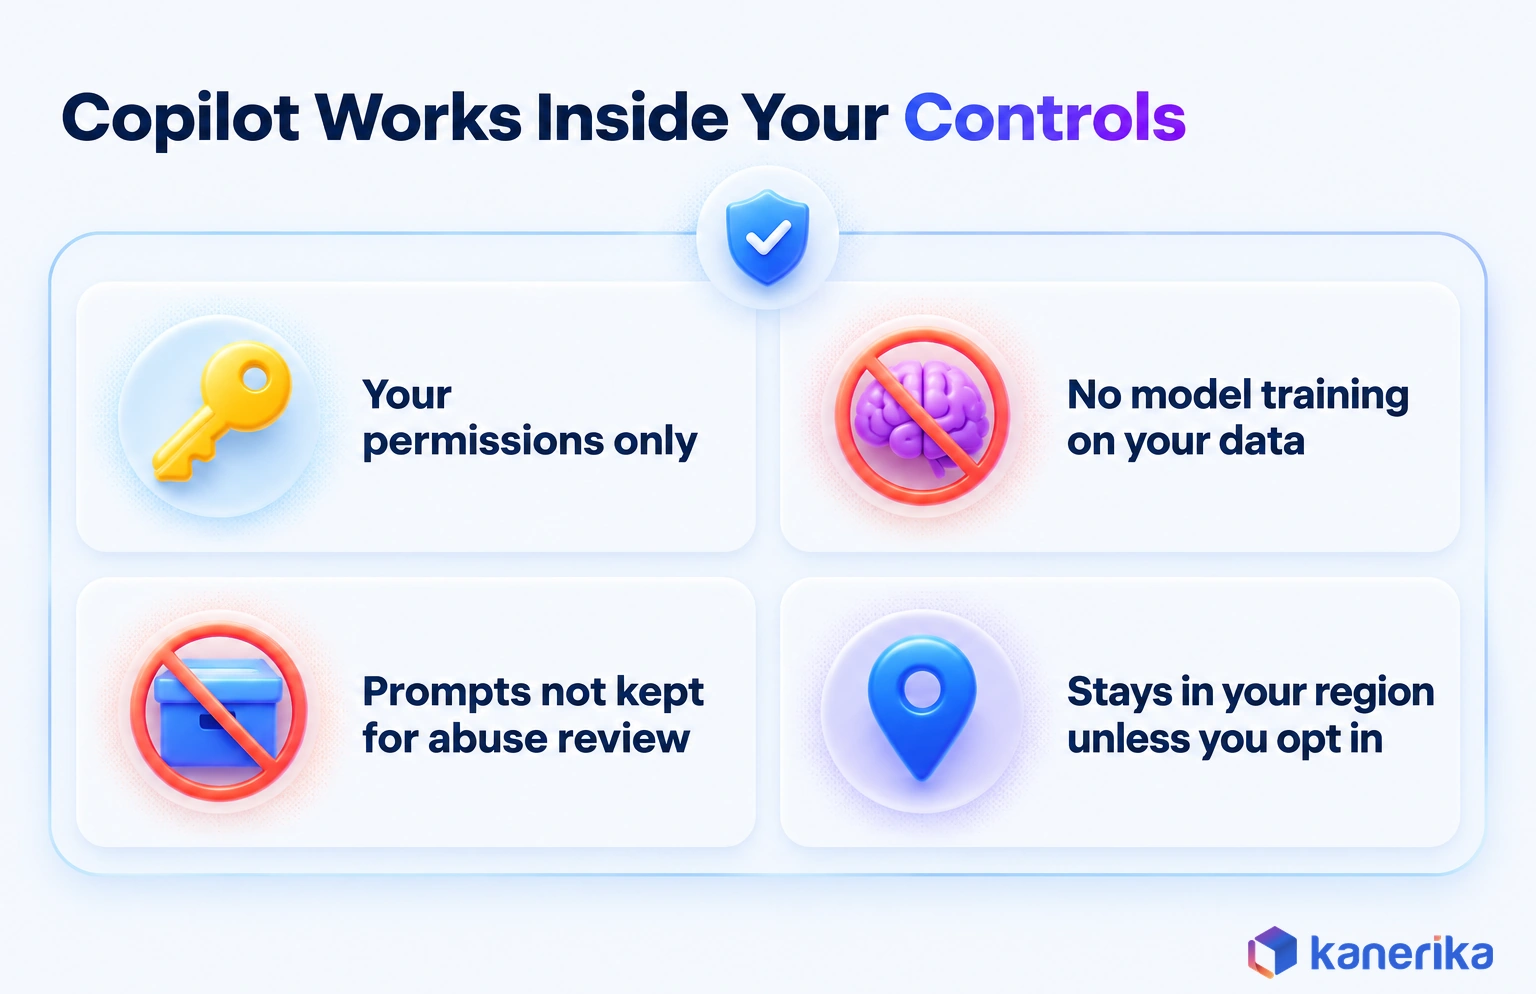
Copilot works inside the permissions, regions and settings you already control. That lets governance teams review it against the rules they have today, with no new access model to learn.
Microsoft’s privacy and security page and the Copilot overview set out the main guarantees and limits.
- Copilot only accesses data the signed-in user can already access.
- Your data is not used to train models.
- Prompt data is no longer stored for abuse monitoring, after Microsoft dropped its earlier 30-day retention.
- Processing stays in your capacity’s geographic region unless an admin allows cross-geo processing.
- Copilot in notebooks and data agents keep conversation history for 28 days unless the user clears the chat.
- Microsoft Purview controls for data agents, such as risk discovery and auditing, are in preview.
Still, none of this makes an output correct. The one rule that covers every workload is review before use. Treat every answer as a draft that someone with domain knowledge checks, especially code and numbers that feed decisions.
NIST’s Generative AI Profile (NIST AI 600-1, July 2024) names this risk confabulation. In other words, it means confidently stated but erroneous or false content. Teams that already follow the NIST AI Risk Management Framework can also file the pilot scorecard as evidence for its Measure function.
Row-level security also deserves a test of its own. Ask the same question as two users with different roles, and confirm that each gets a different, correct answer. Our guide to data warehouse security in Microsoft Fabric covers the row-level and object-level controls behind that test. For the scripted version, see our T-SQL playbook for Fabric warehouse security.
Copilot also fits inside a wider control plan for your tenant. Our guide to Microsoft Fabric governance covers the domains, sensitivity labels and OneLake catalog controls that sit around it.
Common Microsoft Fabric Copilot Mistakes
The mistakes that sink Copilot rollouts are planning gaps. They tend to surface a few weeks in, when users lose trust or the capacity slows down.
- Enabling it tenant-wide on day one. Start with a security group, and widen access only after the pilot passes.
- Skipping the semantic model work. Unclear names and missing descriptions produce confident, wrong answers.
- Sharing a small capacity with production refreshes. Copilot load and nightly refreshes compete for the same CUs, so isolate the pilot or use a Fabric Copilot capacity.
- Shipping generated SQL or PySpark unreviewed. Route generated code through the same code review and deployment pipelines as anything a person wrote.
- Running without a test question set. Without known answers, you cannot tell accuracy from fluency.
- Ignoring the cross-geo decision. If your capacity sits outside the US or EU Data Boundary, users find out by seeing nothing, so settle it early with your compliance team.
Each of these is cheap to avoid before launch and expensive to undo after it. That is why the pilot below is built to catch all six.
How to Run and Measure a 30-Day Copilot Pilot
A pilot turns a vague sense that Copilot seems useful into a decision you can defend. Keep it to 30 days, one or two personas and a fixed question set, so the results are comparable from week to week. Anything bigger turns into a rollout before you know whether Copilot works.
First, pick a group whose work sits on a well-modeled semantic model, such as finance analysts or sales operations. Record a baseline in week one, before they use Copilot, then measure the same tasks again in week four.
| Metric | Baseline | Target | How to measure |
|---|
| Answer accuracy | Analyst answers to the test set | Agreed with the data owner before day one, for example 18 of 20 test questions correct | Run the fixed question set weekly and mark each answer |
| CU consumption | Capacity load in the week before the pilot | No throttling, spend within budget | Microsoft Fabric Capacity Metrics app |
| Adoption by persona | Zero | A share agreed upfront, for example half the pilot group active weekly | Workspace usage data and a weekly check-in |
| Time saved per task | Minutes for three common tasks without Copilot | A reduction agreed upfront for each of the three tasks | Time the same three tasks before and after |
Expand, Fix or Stop at Day 30
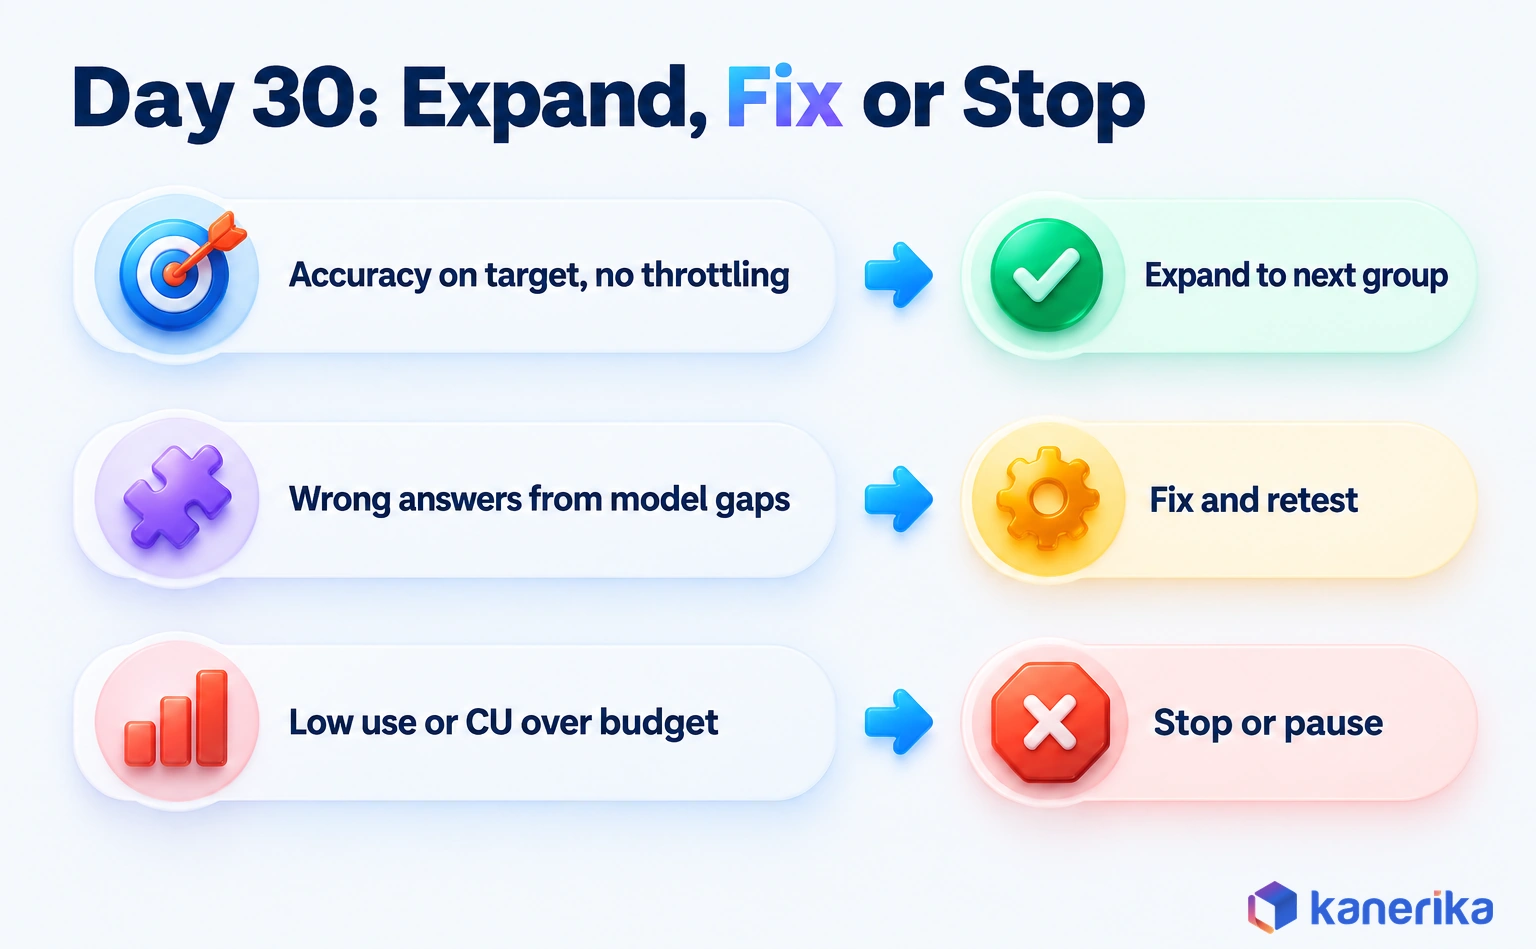
At day 30, the scorecard should point to one of three outcomes. Agree these rules and write them into the pilot plan before day one.
- Expand when accuracy meets the agreed target and the capacity shows no throttling.
- Fix and retest when wrong answers trace back to model names, descriptions or measures.
- Stop or pause when adoption stays low or CU use outgrows the budget.
Expanding means adding the next security group, not the whole tenant. Each new group brings its own semantic models, so repeat the readiness checklist for them before access widens. That keeps each step small enough to measure.
Our guide to Microsoft Fabric adoption covers how to stage that rollout across teams. Scaling from one pilot group to many teams is also the subject of the podcast episode below, from the author of this guide.
How Kanerika Helps Enterprises Get Fabric Copilot Production-Ready
Kanerika is a Microsoft Fabric Featured Partner and a Microsoft Solutions Partner for Data and AI. Our Copilot work starts with the data and the rollout plan, not the switch, and it follows four stages.
- Readiness assessment. We review capacity, region, tenant settings and the semantic models a pilot group would use, then write the test question set with the data owner.
- Semantic model and governance prep. We fix names, descriptions, relationships and approved measures, set up Prep data for AI where it fits, and align access with your governance rules.
- Pilot with a scorecard. We run the 30-day pilot, track accuracy, CU use and adoption, and bring an expand, fix or stop recommendation.
- Scale and monitor. We widen access group by group, set up a Fabric Copilot capacity if billing needs one, and watch the Capacity Metrics app for throttling.
Proof From Our Fabric and Copilot Projects
In the end, the data foundation decides how far Copilot can go. For a leading pharma manufacturer, we consolidated Model N, SQL Server, SAP and SAP Vistex data into a Fabric lakehouse with Power BI reporting. The sales and financial KPI project delivered a 95% decrease in man-hours spent on reporting. It also brought a 40% increase in operational efficiency and a 35% reduction in operational costs.
That project was not a Copilot rollout, but it built the kind of governed, well-described model that Copilot answers depend on.
Our Microsoft Copilot work outside Fabric points the same way. For a California-based dairy, we used Microsoft Copilot with Power Automate and Azure SQL, delivered through Microsoft Teams and an intranet chatbot. The sales team assistant cut data query errors by 90% and made decision-making 30% faster. That was Microsoft Copilot rather than Fabric Copilot, so read it as a related result, not a Fabric benchmark.
Our Microsoft Fabric consulting services cover the full path from capacity planning to Copilot pilots. For reporting and model work outside Fabric, our data analytics services team applies the same method.
Kanerika Service
Microsoft Fabric Consulting Services
Kanerika, a Microsoft Fabric Featured Partner, plans capacity, prepares semantic models and runs measured Copilot pilots, then scales access group by group.
Explore Fabric Services
Bottom Line: What Fabric Copilot Takes to Run Well
Microsoft Fabric Copilot is within reach of far more teams than the old F64 rule suggested. Any paid F2 or P1 capacity can run it, with cross-geo processing allowed outside the US and EU. A typical request also costs only about two cents at the East US list price.
If you already pay for Fabric capacity, start a scoped 30-day pilot now. If you are on a trial or Pro only, budget for a paid capacity or a Fabric Copilot capacity first. Either way, requirements and costs are the easy part, and the rollout succeeds only when the model is ready and the pilot proves accuracy.
Frequently Asked Questions
How do I enable Copilot in Microsoft Fabric?
A Fabric admin opens Tenant settings and confirms that Users can use Copilot and other features powered by Azure OpenAI is on. Scope that setting to a security group, enable delegated capacity settings if used, and assign the workspace to a paid F2 or larger capacity. Copilot is on by default for paid tenants in the US and EU.
What is the main benefit of Copilot in Microsoft Fabric?
The main benefit is speed on routine work. Copilot drafts report pages, Power Query steps, PySpark, T-SQL and KQL from plain-English prompts, so builders start from a draft instead of a blank editor. Business users get summaries and answers from Power BI reports. The benefit holds only when the semantic model has clear names and descriptions.
How do I connect Copilot Studio to Microsoft Fabric?
Create and publish a Fabric data agent over the lakehouse, warehouse, semantic model or KQL database you want to expose. Then consume that data agent from Copilot Studio, which Microsoft lists as a supported service outside Fabric. Review the related admin setting first, because answers from the data agent then appear outside the Fabric experience.
Is Copilot in Fabric generally available?
It depends on the experience. Several Copilot features in Fabric are generally available, while others, such as Fix with Copilot in notebooks, app-scoped Copilot in Power BI and Prep data for AI, are labeled preview. Check the Copilot in Fabric overview on Microsoft Learn for the status of each feature before you promise it to users.
Can Copilot be enabled for specific workspaces or groups?
Yes. Fabric admins can apply the Copilot tenant settings to specific security groups instead of the whole organization, and capacity admins control the same settings for their capacity when delegation is on. Copilot then works only in workspaces assigned to a Copilot-enabled capacity, which lets you limit a pilot to chosen users and workspaces.
Do I need F64 capacity to use Copilot in Microsoft Fabric?
No. The F64 requirement is out of date. Microsoft now lists any paid Fabric F2 or larger capacity, or Power BI Premium P1 or larger, as enough to run Copilot. Smaller capacities have less headroom, so heavy use can throttle them, and a Fabric Copilot capacity also covers Copilot on SKUs smaller than F64.
How much does Copilot in Microsoft Fabric cost?
Copilot bills capacity units per 1,000 tokens, at 100 CU seconds for input, 10 for cached input and 400 for output. Microsoft’s example request of 2,000 input and 500 output tokens uses 400 CU seconds, about $0.02 at the $0.18 East US pay-as-you-go rate. A thousand such requests cost about $20 in total.
Why is Copilot not showing in Microsoft Fabric?
The usual causes are a trial capacity, a Pro workspace without a Fabric Copilot capacity, a tenant setting scoped to a group you are not in, a capacity outside the US or EU Data Boundary with cross-geo off, or a capacity-level setting left off under delegation. Check each one in that order before you open a support ticket.
Can Copilot in Fabric write SQL and KQL queries?
Yes. In Data Warehouse and SQL database, Copilot turns plain-English questions into T-SQL, completes code and offers quick actions, including in SSMS 22. VS Code’s MSSQL extension uses GitHub Copilot instead. In Real-Time Intelligence it translates questions into KQL in querysets and dashboard tiles. Always review joins, filters and time ranges before running generated queries on production data.
What is the difference between Fabric Copilot and a Fabric data agent?
Copilot is preconfigured inside each Fabric workload and helps with the task in front of you, such as writing notebook code or a warehouse query. A data agent is built and configured by your team, with instructions and example queries over up to five sources, then shared with a business audience that asks repeat questions.
Does Copilot in Fabric use my data to train models?
No. Microsoft states that your data is not used to train models. Copilot uses Azure OpenAI by default, and prompt data is no longer stored for abuse monitoring after Microsoft removed its earlier 30-day retention. Notebook Copilot and data agents do keep conversation history for 28 days unless the user clears the chat.
Can I use Copilot in Power BI with a Pro license?
Not with a Pro license alone. A Pro or Premium Per User workspace needs a Fabric Copilot capacity before Copilot works there. Once a capacity admin assigns you to that capacity, Copilot in Power BI works in your Pro workspace and in Power BI Desktop, and all of the usage bills to the Copilot capacity.
How do I connect a Copilot agent to Fabric?
Build a Fabric data agent over up to five sources, such as a lakehouse, warehouse, semantic model or KQL database, and add instructions and example queries. Once it is published, the data agent can be consumed from Copilot Studio, Microsoft Foundry (formerly Azure AI Foundry), Teams or Microsoft 365 Copilot, while governance policies on the underlying data still apply.
Does Microsoft Fabric use AI?
Yes. Fabric includes Copilot assistants in Power BI, Data Factory, notebooks, Data Warehouse, SQL database and Real-Time Intelligence, all running on Azure OpenAI models by default. It also offers Fabric data agents that teams configure with their own instructions for business questions, and Prep data for AI features that shape how Copilot reads a semantic model.
What are the limitations of Copilot in Fabric?
Copilot needs a paid F2 or P1 capacity and does not run on trial SKUs or sovereign clouds. Several experiences are still in preview, output quality depends on your semantic model, and heavy use can throttle a small capacity. Generated code and answers can be wrong, so a person with domain knowledge should review them before anyone relies on them.
When you use Copilot, who can access what data?
Copilot only accesses data that the signed-in user already has permission to see, so workspace roles, item permissions and row-level security still apply. It does not widen anyone’s access. Test this directly by asking the same question as two users with different roles, and confirm that each gets a different, correct answer before a wider rollout.
Is Copilot included in Microsoft Fabric?
Copilot has no separate license in Fabric. It comes with paid F2 or larger capacities and Power BI Premium P1 or larger, and it is on by default for those tenants. Each request consumes capacity units based on the tokens sent and received, so usage shows up on your capacity bill rather than as a per-user fee.
What are the AI capabilities in Microsoft Fabric?
Fabric’s AI capabilities include Copilot for Power BI report pages and summaries, Copilot for Dataflow Gen2 transformations, notebook Copilot for PySpark with Fix with Copilot, plain English to SQL in warehouses and SQL databases, and plain English to KQL in Real-Time Intelligence. Fabric data agents add configurable question answering across chosen data sources.
What is Fabric Copilot capacity?
A Fabric Copilot capacity is a designated capacity that bills all Copilot and data agent usage from its assigned users in one place. It also enables Copilot in Power BI Desktop, in Pro and Premium Per User workspaces, and on SKUs smaller than F64. A Fabric admin authorizes it, and a capacity admin then assigns the users.
Is Copilot available in a Fabric trial?
No. Microsoft states that Azure OpenAI Service, including Copilot, is not available on trial SKUs. To test Copilot you need a paid Fabric F2 or larger capacity, a Power BI Premium P1 or larger capacity, or a Fabric Copilot capacity assigned to your user. If you evaluate Fabric on a trial, plan a paid capacity for the Copilot part.














