TL;DR
The Databricks Data Intelligence Platform beats its competitors for engineering-heavy, multi-cloud and AI-agent work on open formats. Competitors such as Snowflake, Microsoft Fabric and BigQuery win when a team is SQL-first, Microsoft-centric or Google Cloud-native. It is a lakehouse that runs storage, governance, engineering, SQL, AI agents and apps on one governed copy of your data.
As of October 2026, Databricks markets it as the Databricks Data + AI Platform, but the layers underneath are the same. The right pick depends less on features than on who will build and run the platform. Pricing is pay as you go in DBUs, billed per second, and committed use earns discounts.
Key Takeaways
- The Databricks Data Intelligence Platform is a lakehouse that stores data once in open formats and runs engineering, BI, AI agents and apps on that copy.
- On its product page, checked October 23, 2026, Databricks sells it as the Data + AI Platform, but the architecture has not changed.
- Unity Catalog is the center of the platform because it handles permissions, lineage and auditing for both data and AI assets.
- Against Snowflake, Microsoft Fabric and Google BigQuery, Databricks wins on open formats, multi-cloud reach and agent building but loses on simplicity for SQL-only or Microsoft-first teams.
- Pricing is usage-based, so the bill tracks DBUs for processing and DSUs for storage, billed per second.
- A fair evaluation tests every vendor on the same dataset, the same governance rules and the same cost model.
Watch on YouTube
How Do Agent Bricks, LakeBase, and Unity Catalog Work Together in Databricks?
A Kanerika walkthrough of how governance, agents and the operational database connect on one platform, the core idea behind the six layers in this guide.
Three Vendors, One Phrase: Data Intelligence
Picture a data leader with three vendor decks open side by side. Each one promises “data intelligence.” They show storage at the bottom and AI at the top, and each claims to end data silos.
The slides look alike because the label has become a category name. Yet the products underneath are not alike at all. They differ in where the data lives, who governs it, which engines can read it, and how much engineering your team must own.
That is why this guide explains the Databricks Data Intelligence Platform one layer at a time. You will see what each layer does, then how the layers work together on a real flow. After that, you will see how Databricks stacks up, layer by layer, against Snowflake, Microsoft Fabric and Google BigQuery. The goal is a decision you can defend in front of your finance and security teams.
What Is the Databricks Data Intelligence Platform?
In plain terms, it is one platform where your data is stored once and every team works on that same copy. Engineers build pipelines on it while analysts query it with SQL. Data scientists train models on it, and AI agents read it under the same permissions.
Underneath sits the lakehouse idea. Data lives in your cloud object storage in open table formats, so it is not locked inside a proprietary database. On top of that storage, Databricks then adds governance, compute engines and AI tooling, all managed from one control plane. The platform runs on AWS, Azure and Google Cloud.
The name needs one note. Databricks’ product page, checked October 23, 2026, calls it the “Databricks Data + AI Platform,” and the old data intelligence platform URL redirects there. People still search for the Databricks Data Intelligence Platform, so this guide uses that name throughout.
From Lakehouse Platform to Data Intelligence Platform to Data + AI Platform
The name matters to a buyer because, when checked on October 23, 2026, Databricks’ product page and Azure Databricks docs used the newest one. Searches, RFPs and vendor questionnaires should therefore use both names. The table traces the three names and what each one put in front.
| Name | What it stressed | Source |
|---|
| Lakehouse Platform | One open storage layer that serves both data warehouse and data lake workloads | TechTarget launch coverage |
| Data Intelligence Platform | AI built into the platform itself, through the DatabricksIQ engine and MosaicML technology | TechTarget, November 17, 2023 |
| Data + AI Platform | Data, governance, agents and apps sold as one product | Databricks product page, checked October 23, 2026 |
Ali Ghodsi and other Databricks founders announced the middle name in a blog post, according to TechTarget’s report on the launch. It built on technology from MosaicML, which Databricks acquired in June 2023. We found no announced date for the Data + AI rename, so treat the two names as the same product.
Kanerika Service
Databricks Consulting and Implementation Services
Kanerika plans, builds and governs Databricks platforms, from Unity Catalog setup to pipelines, analytics and AI agents.
Explore Databricks Services
What “Data Intelligence” Means in Practice
Data intelligence, in Databricks’ sense, means the platform learns the context of your business. A table called fct_rev_v2 means nothing to a language model, because the name carries no business meaning. A platform that knows it holds recognized revenue, who uses it and how finance defines a quarter can then answer in your terms.
Databricks delivers this through Genie Ontology. The Databricks platform page says it combines semantics your team models by hand, such as KPI definitions, with knowledge inferred from real usage. Ask Genie for “net revenue by region last quarter,” and it uses your definition of net revenue rather than guessing at a column name.
The vendor feature, though, is only one implementation of a wider practice. If you want the vendor-neutral view before going further, our guide to data intelligence as a discipline covers definitions, lineage and ownership across any platform.
The Six Layers of the Databricks Data Intelligence Platform
The easiest way to understand the platform is as a stack. Each layer has one job, while every layer above the storage reads the same governed data. Here is what each one does and why it matters to a buyer.
Think of the stack the way a hospital thinks about patient records. There is one record, many departments read it, and a single policy decides who sees what. The six layers below follow that same pattern for enterprise data.
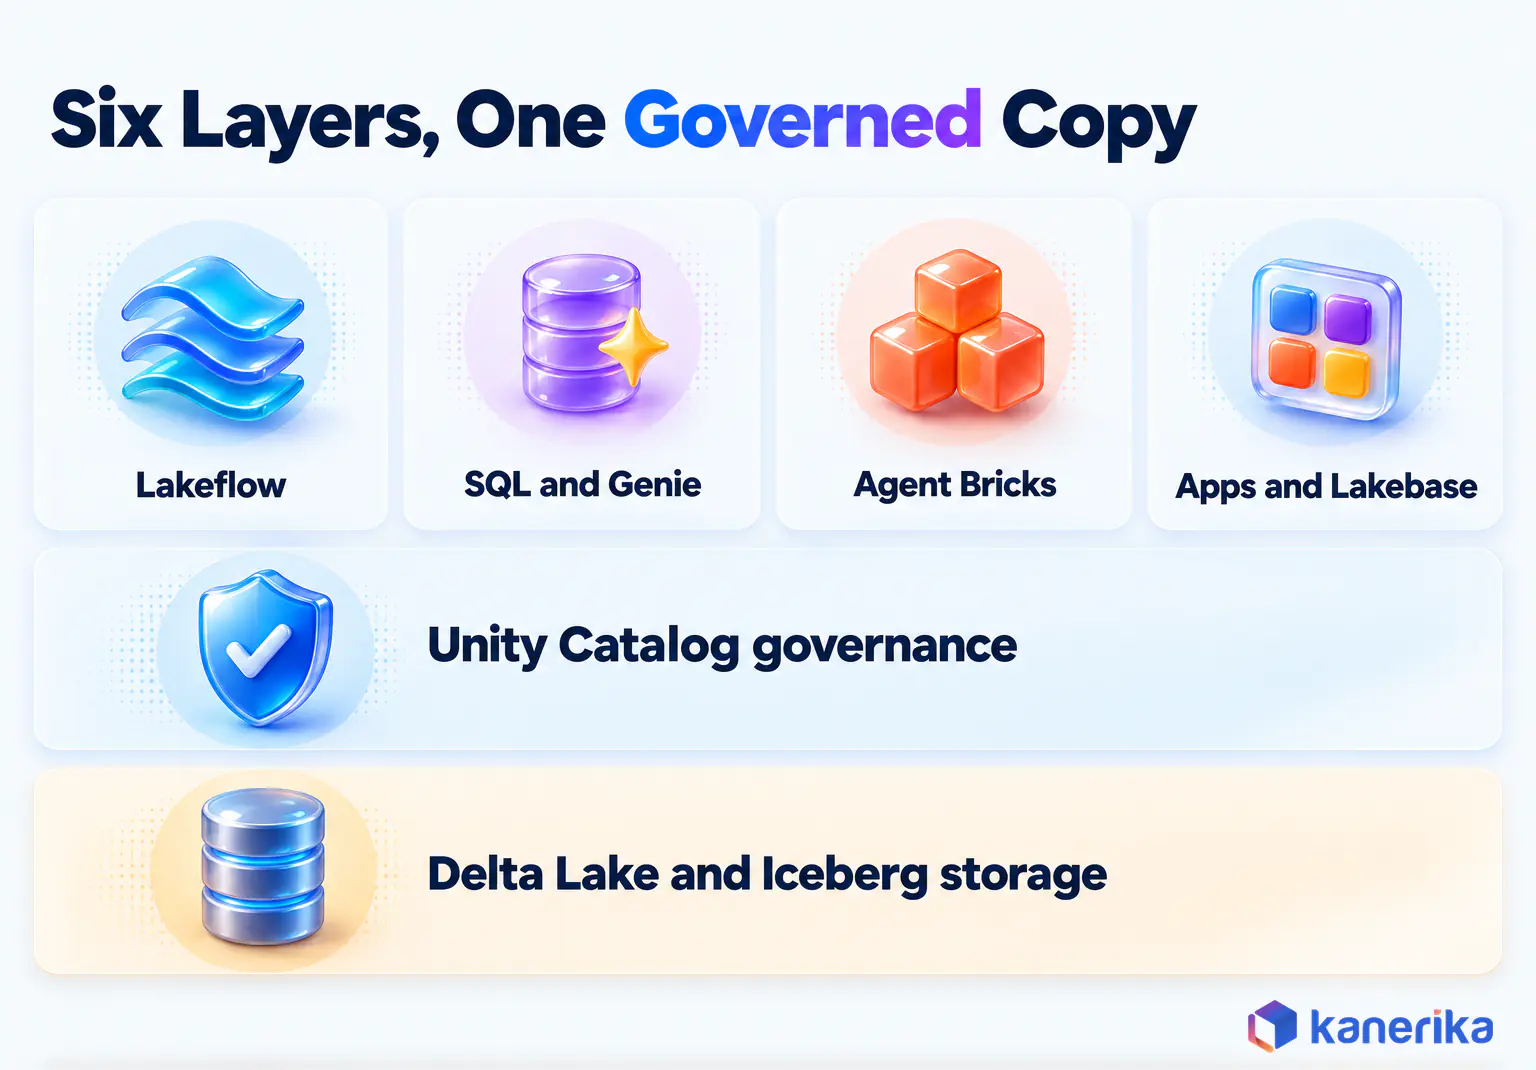
Open Storage: Delta Lake and Apache Iceberg
Everything starts with files in your own cloud storage. Databricks writes them as Delta Lake tables, and it also supports Apache Iceberg. Delta adds ACID transactions, so a failed write never leaves a half-updated table. It also adds time travel, so you can query a table as it stood before last night’s load.
Open formats are a big reason teams pick Databricks. Other engines can read the same files without an export, which lowers the cost of changing tools later. Our Databricks lakehouse architecture guide covers the design patterns, such as the bronze, silver and gold layering many teams use.
Governance: Unity Catalog and Unity Gateway
Unity Catalog is the layer that holds the platform together. It manages data and AI assets with consistent permissions, lineage and auditing. A table, a model and a dashboard therefore follow one set of rules. When an auditor asks who read a patient table last month, the answer comes from one place. Our guide to Databricks data lineage shows how that trail is captured.
Unity Gateway then extends that control to AI usage. It governs access, spend and observability across agents, tools, models and MCP servers. That matters once dozens of teams start calling large language models with company data.
Access control also goes below the table level. Unity Catalog row filters and column masks are SQL functions that run at query time, so one table can serve several audiences. You attach a filter with ALTER TABLE denials SET ROW FILTER region_filter ON (region). A mask can, for example, show an analyst only the last four digits of a member ID while auditors see the full value.
Unity Catalog is also open source under the Apache 2.0 license, with Iceberg REST Catalog APIs that other engines can call. For the policy side of this work, see our data governance best practices, and for setup detail, our Unity Catalog guide.
Datasheet
Build a Modern Data and AI Foundation with Databricks
A Kanerika datasheet on planning and building a governed data and AI foundation on Databricks, from storage and catalog to AI workloads.
View the Datasheet →
Data Engineering: Lakeflow
Lakeflow is how data gets into the platform and stays fresh. It unifies ingestion with orchestration, a job that standalone data orchestration tools do on other stacks. It also handles batch and streaming pipelines. For example, a nightly ERP extract and a live stream of device events can run under one scheduler with one set of alerts.
Before you design pipelines, settle on your data ingestion patterns, because they drive cost and latency more than the tool does. Our Lakeflow guide then walks through the components, and our data pipeline architecture guide covers the patterns behind them.
Warehousing and BI: Databricks SQL and Genie
Databricks SQL gives analysts a serverless SQL warehouse on the same lakehouse tables. They write standard SQL and connect their BI tools, so nobody copies data into a separate warehouse first.
Genie sits on top for people who rarely write SQL, such as sales and operations managers. One of them types a question in plain English and gets an answer grounded in the governed tables and the Genie Ontology definitions. Our Genie guide shows how teams set up Genie Agents (formerly Genie spaces) and test their answers before rollout.
AI and Agents: Agent Bricks
Agent Bricks is where teams build AI agents. The platform page calls it multi-harness agent development. In practice, you can use any model, framework or agent and still evaluate and deploy on one governed foundation.
The governed part, however, is the selling point. An agent that drafts a customer reply reads only the tables its user may see, while Unity Gateway tracks what it costs. For a build walkthrough, read our Agent Bricks guide. For designs where several agents cooperate, see our multi-agent AI systems guide.
Kanerika Service
Agentic AI Services
Kanerika designs, builds and governs AI agents that work on enterprise data, with evaluation and access controls in place before go-live.
Explore Agentic AI Services
Apps and Operational Data: Databricks Apps and Lakebase
The top layer turns analytics into working software, the core idea behind operational analytics. Databricks Apps run data and AI applications on serverless compute under the same governance. An internal tool can reuse that hosting and governance instead of standing up its own.
Lakebase adds the transactional database many of those apps need. It is a fully managed, serverless Postgres built on the open source engine rather than a fork, designed for AI and real-time OLTP workloads. It autoscales and supports branching, so a developer can test against a copy of production data. Our Lakebase guide goes deeper.
When you put them together, the six layers look like this.
| Layer | Component | What it does |
|---|
| Open storage | Delta Lake, Apache Iceberg | Stores data once in open formats, with ACID writes and time travel |
| Governance | Unity Catalog, Unity Gateway | Permissions, lineage and auditing for data and AI, plus AI access and spend control |
| Data engineering | Lakeflow | Ingests and orchestrates batch and streaming pipelines |
| Warehousing and BI | Databricks SQL, Genie | Serverless SQL and natural-language answers in business terms |
| AI and agents | Agent Bricks | Builds and evaluates agents before deploying them on governed data |
| Apps and operational data | Databricks Apps, Lakebase | Serverless apps and managed Postgres for transactions |
How the Layers Work Together: A Worked Example
A layer list only shows the parts, so here is one flow from end to end. The example is illustrative, so picture a regional health system that wants to cut the time its appeals team spends on denied insurance claims.
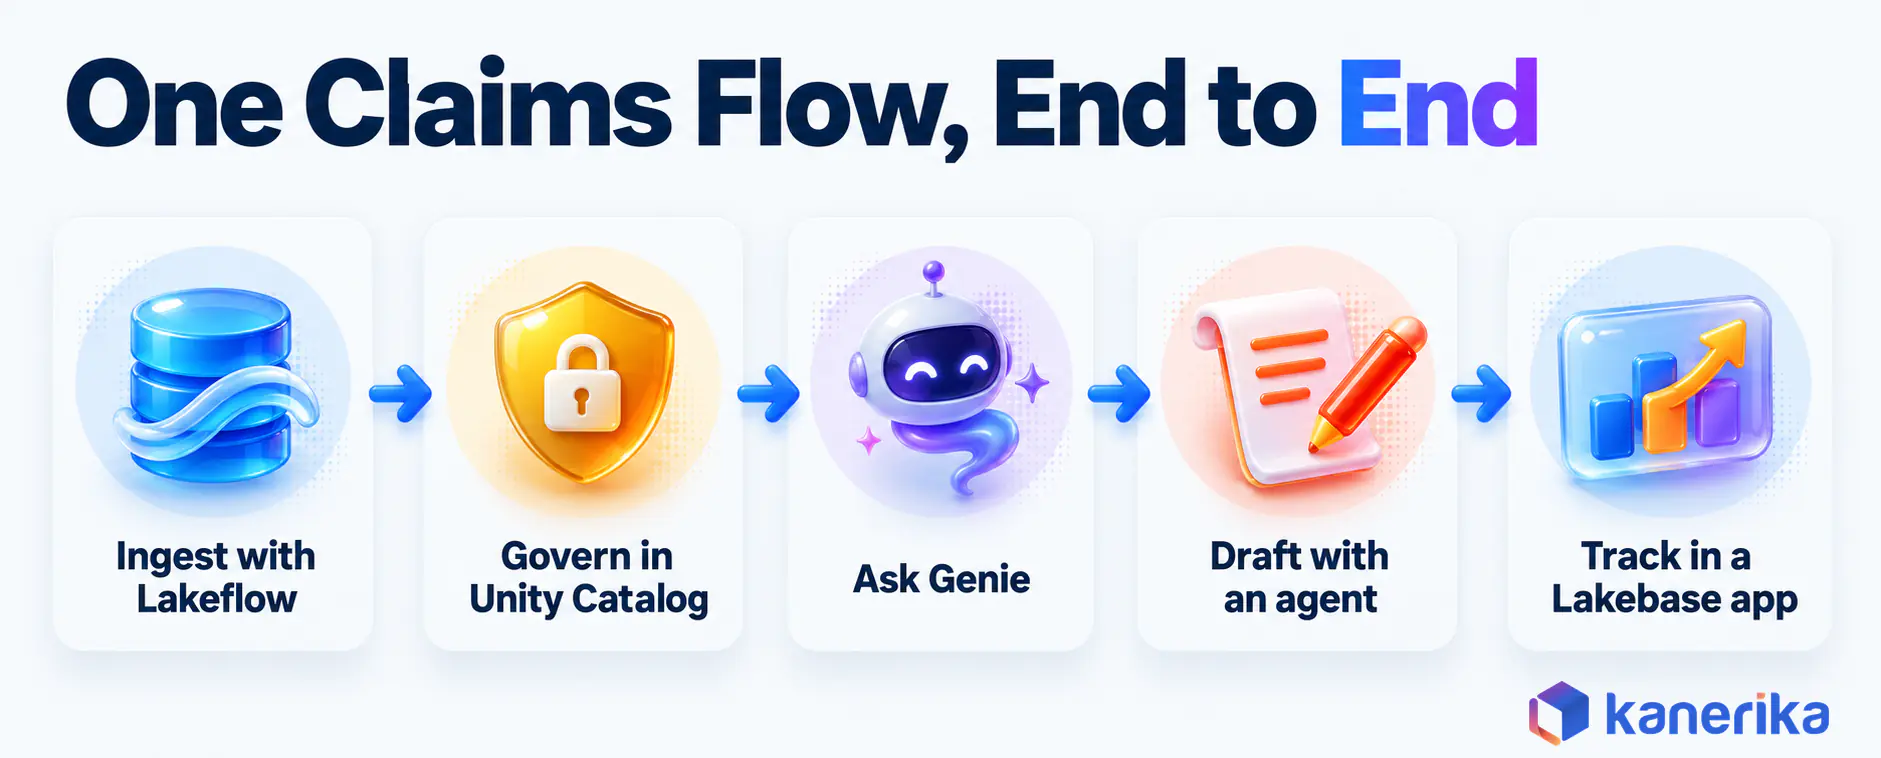
- Ingest with Lakeflow: a nightly batch pipeline loads claim files from the billing system, while a streaming pipeline adds payer remittance events as they arrive.
- Store in Delta tables: raw files land in a bronze table, then cleaned claims move to silver and a curated
denials table to gold.
- Govern with Unity Catalog: the data team grants read access on the gold table to the claims analysts group only. Lineage also shows which pipeline built each column.
- Ask with Databricks SQL and Genie: an appeals manager asks Genie which payers had the highest denial rate last quarter, then gets a ranked answer.
- Act with Agent Bricks: an agent then drafts a denial summary for each high-value claim, using only the tables its user may read.
- Track in an app on Lakebase: a Databricks App lets the appeals team log each appeal, while Lakebase stores those updates as transactions.
The SQL Behind Step Three
Step three is where most of the safety comes from, but it takes only a few lines of SQL. The grants below give analysts read access to the gold table. The query then checks what that table held at an earlier version, using Delta time travel.
-- Unity Catalog: let claims analysts read the curated table
GRANT USE CATALOG ON CATALOG claims_prod TO `claims_analysts`;
GRANT USE SCHEMA ON SCHEMA claims_prod.gold TO `claims_analysts`;
GRANT SELECT ON TABLE claims_prod.gold.denials TO `claims_analysts`;

-- Delta time travel: compare with the table before the last load
SELECT payer_id, COUNT(*) AS denied_claims
FROM claims_prod.gold.denials VERSION AS OF 42
GROUP BY payer_id;
Notice what never happened in this flow. Nobody exported a CSV, nobody copied claims into a second warehouse, and the agent never saw a table the analyst could not see. That single governed copy is the practical meaning of “data intelligence” on Databricks, so test it in any proof of concept.
The rivals can run parts of this illustrative flow too, each in its own way. On Snowflake, SQL grants and Cortex AI Functions such as AI_COMPLETE can cover the access, query and summary steps. On Fabric, Data Factory, OneLake and Copilot carry a Power BI team through the first four steps. BigQuery, for its part, answers the step four questions with serverless SQL and Gemini features.
Step six is the one to test hardest on each rival, because it needs a transactional store beside the analytics. Keep one limit in mind as well. A team without engineers will find the Databricks pipeline steps hard to own on any of these platforms.
What Changed in 2026 That Shifts the Comparison
Platform pages change faster than most buying cycles, so verify the 2026 additions before you sign. Every capability in the six layers above appeared on Databricks’ product pages as checked on October 23, 2026. Ask your account team how mature each one is in your region and cloud.
Two of these change the comparison with rivals. Unity Gateway puts AI cost and access under the same catalog as your data. Rivals handle that split differently. Snowflake governs data through Horizon Catalog, and Fabric draws Copilot use from Fabric capacity. BigQuery leans on IAM with row and column access controls. Lakebase, for its part, means a Databricks app no longer needs a separate database outside the platform.
Checklist
Databricks Readiness Checklist
A downloadable Kanerika checklist to work through before you commit to a Databricks rollout or a platform evaluation.
Get the Checklist →
Databricks Data Intelligence Platform vs Competitors, Layer by Layer
As of October 2026, every serious rival offers storage, governance, SQL and AI, so a yes-or-no feature list tells you little. The useful question is how each vendor builds each layer, as well as which design suits your team.
The table compares Databricks with Snowflake, Microsoft Fabric and Google BigQuery on the layers that drive most decisions. Each cell comes from the vendor’s own documentation, so you can check it at the source.
| Layer | Databricks | Snowflake | Microsoft Fabric | Google BigQuery |
|---|
| Storage | Delta Lake and Apache Iceberg in your cloud storage | Iceberg tables that any engine can read and write | OneLake on ADLS, in Delta Parquet or Iceberg | BigLake tables over Amazon S3, Azure and Google Cloud Storage |
| Catalog and governance | Unity Catalog for data and AI, open source under Apache 2.0 | Horizon Catalog, an “agentic catalog” for data inside or outside Snowflake | OneLake security roles that scope access down to rows and columns, enforced across Fabric engines | Knowledge Catalog, IAM, row and column access controls, lineage |
| AI in the platform | Agent Bricks for building and deploying agents | Cortex AI Functions such as AI_COMPLETE run LLM tasks in SQL | Copilot in each workload, plus Fabric data agents | Gemini assistive features and vector search |
| Operating model | Runs on AWS, Azure and Google Cloud | Fully managed service on AWS, Azure and Google Cloud (Snowflake runs the infrastructure) | OneLake included in every Fabric tenant | Fully managed and serverless on Google Cloud |
| Strongest fit | Engineering-heavy, multi-cloud, AI-agent work | SQL-first analytics teams | Microsoft-centric BI estates | Google Cloud-native analytics |
Reading the Comparison Row by Row
Read the table by row rather than by column. On storage, the four vendors have converged on open formats, with Iceberg as the common thread. For example, Snowflake documents Iceberg read and write from any engine through Horizon Catalog. Microsoft, similarly, builds Fabric on OneLake, one copy for many engines.
The real gaps, though, open higher in the stack. Snowflake brings AI into SQL with Cortex AI Functions, so it suits analysts who live in queries. Fabric spreads Copilot across its workloads, from Data Factory to Power BI, but that Copilot use also draws on Fabric capacity. BigQuery pairs serverless SQL with Gemini features, while its governance tools cover row and column security.
Agent Bricks, Databricks Apps and Lakebase sit under one Unity Catalog, so an agent, its app and its transactional store share one permission model. That is why, in our view, Databricks goes furthest toward building full agents and apps on the same governed data.
Datasheet
Snowflake vs Databricks vs Microsoft Fabric
A Kanerika datasheet that sets the three platforms side by side for teams building a shortlist.
View the Datasheet →
For the full field of twelve vendors, see our Databricks competitors guide. This section instead stays with three common rivals.
Where Databricks Fits Best
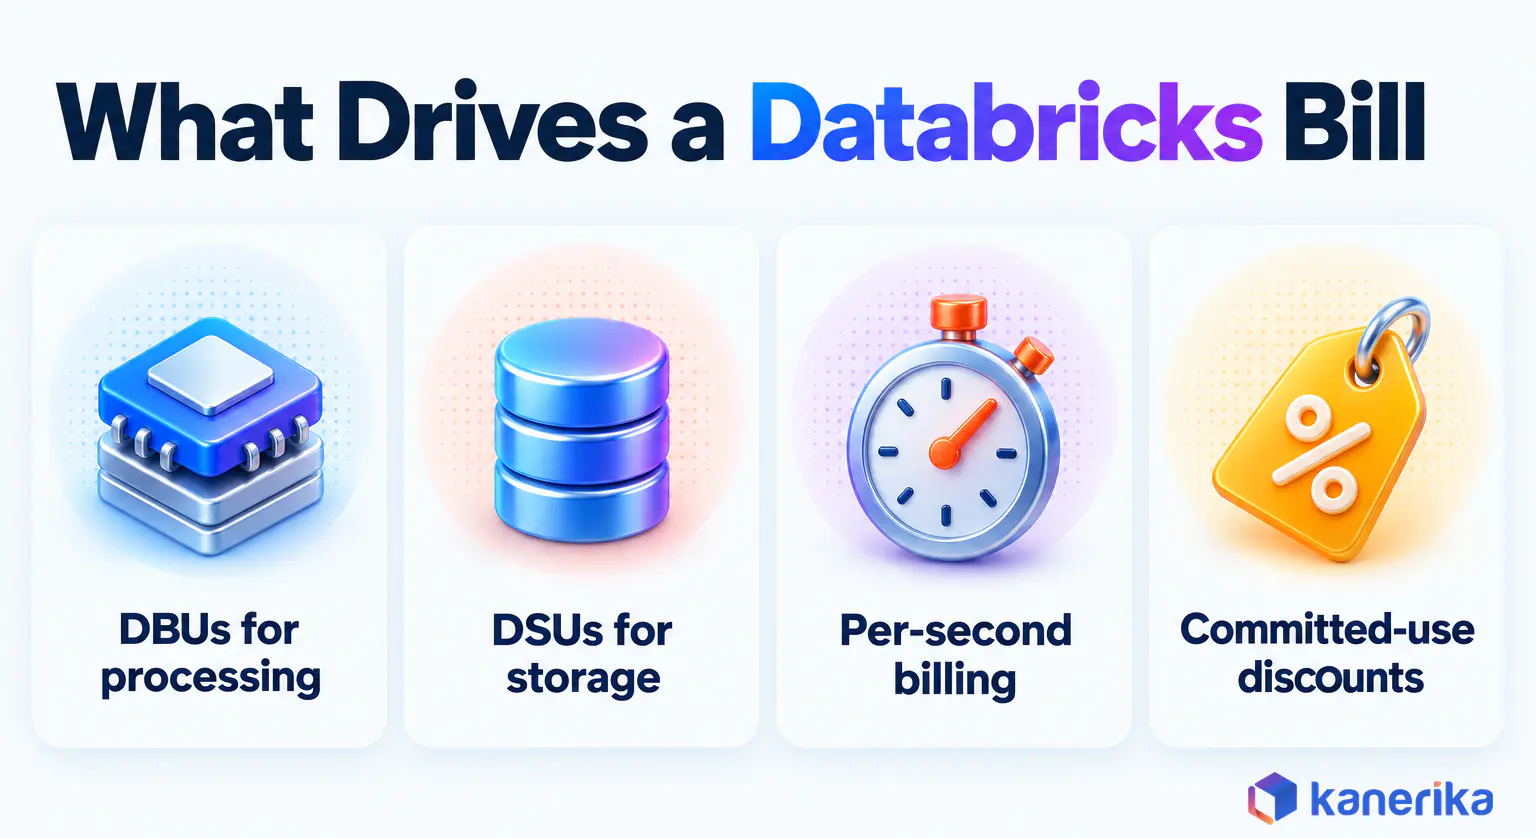
Databricks pays off when you value engineering control and open formats over managed simplicity. A 30-engineer platform team running pipelines across two clouds, for instance, gets the most from that trade.
- Teams with real data engineering skills who want full control when they build pipelines in Python, SQL or Scala.
- Multi-cloud estates, since the same platform runs on AWS, Azure and Google Cloud.
- AI and agent roadmaps that need models, agents and apps on governed enterprise data.
- Organizations that want open formats so other engines can read the data later.
Where a Competitor Fits Better
A rival wins when managed simplicity matters more than engineering control. A four-person BI team that lives in Power BI, for instance, will get value faster from a tool that needs no pipeline code.
- Snowflake suits SQL-first teams that want a managed platform rather than heavy engineering. Our Databricks vs Snowflake comparison covers the trade-offs.
- Microsoft Fabric suits estates built on Power BI and Microsoft 365. Read our Microsoft Fabric vs Databricks guide before you choose.
- Google BigQuery suits teams already standardized on Google Cloud who prefer serverless SQL rather than cluster tuning.
Many enterprises also end up running two of these side by side. Our three-way decision framework helps you split workloads between them, so each tool does what it does best. Our guide to cloud data warehouse architecture and cost explains the warehouse side of that choice.
How Databricks Pricing Works
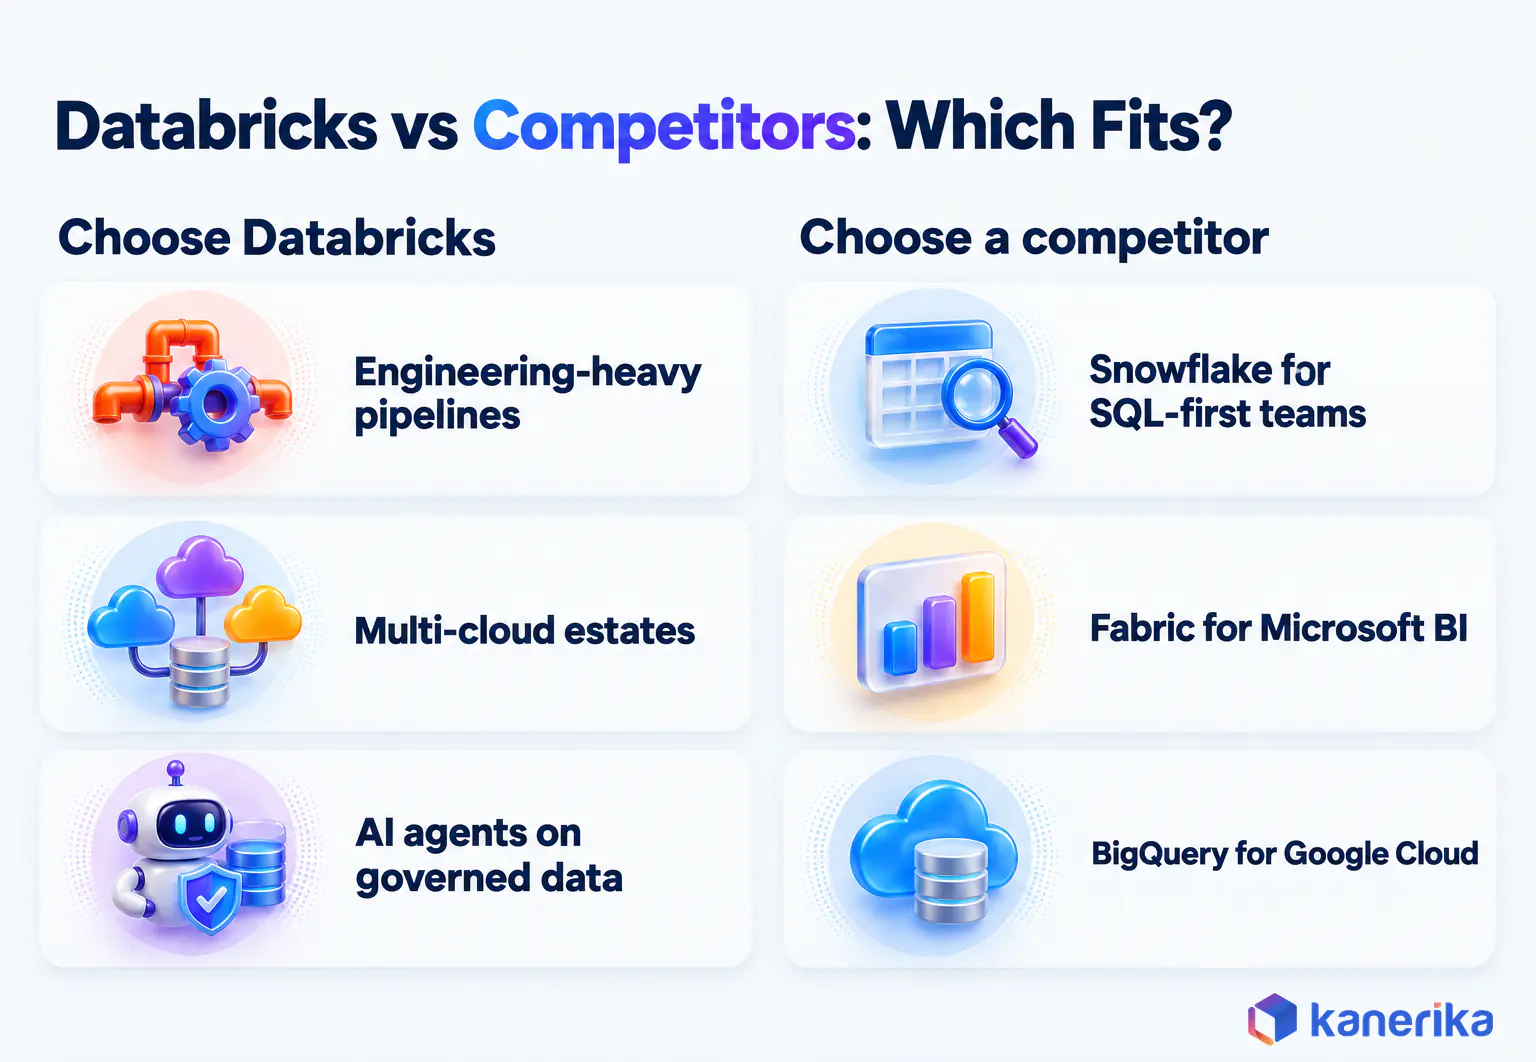
Databricks pricing follows usage rather than a license fee, so your bill tracks what your teams actually run. According to the Databricks pricing page, you pay as you go with no up-front costs, billed at per-second granularity.
Two units sit behind the bill. A DBU, or Databricks Unit, is a normalized unit of processing, driven by the compute you use and the data you process. A DSU, or Databricks Storage Unit, similarly measures storage usage. Once you can commit to a level of usage, committed use contracts give you a discount.
| Pricing element | What it measures | What to model in your TCO |
|---|
| DBU | Processing, driven by compute and data processed | Hours per workload type and idle time |
| DSU | Storage usage | Data volume today, then its growth rate |
| Pay as you go | Per-second billing, no up-front costs | Peak months compared to quiet months |
| Committed use | A discount for committing to usage | The usage level you can commit to safely |
A simple way to build the model is to list each workload, such as nightly pipelines, analyst queries and agent calls. Estimate the hours each one runs per month, and note which ones can stop when idle. On Databricks, the auto termination window for idle compute can be set anywhere from 10 to 10,000 minutes. Then compare pay-as-you-go against a committed level that covers only your steady baseline, and leave the peaks on demand.
The units are simple, but the bill depends on habits. Clusters left running, oversized warehouses and unbounded agent calls all show up as DBUs, so cost habits matter early. Our Databricks explainer covers DBUs in more depth, while our Databricks cost optimization guide lists the guardrails worth setting on day one.
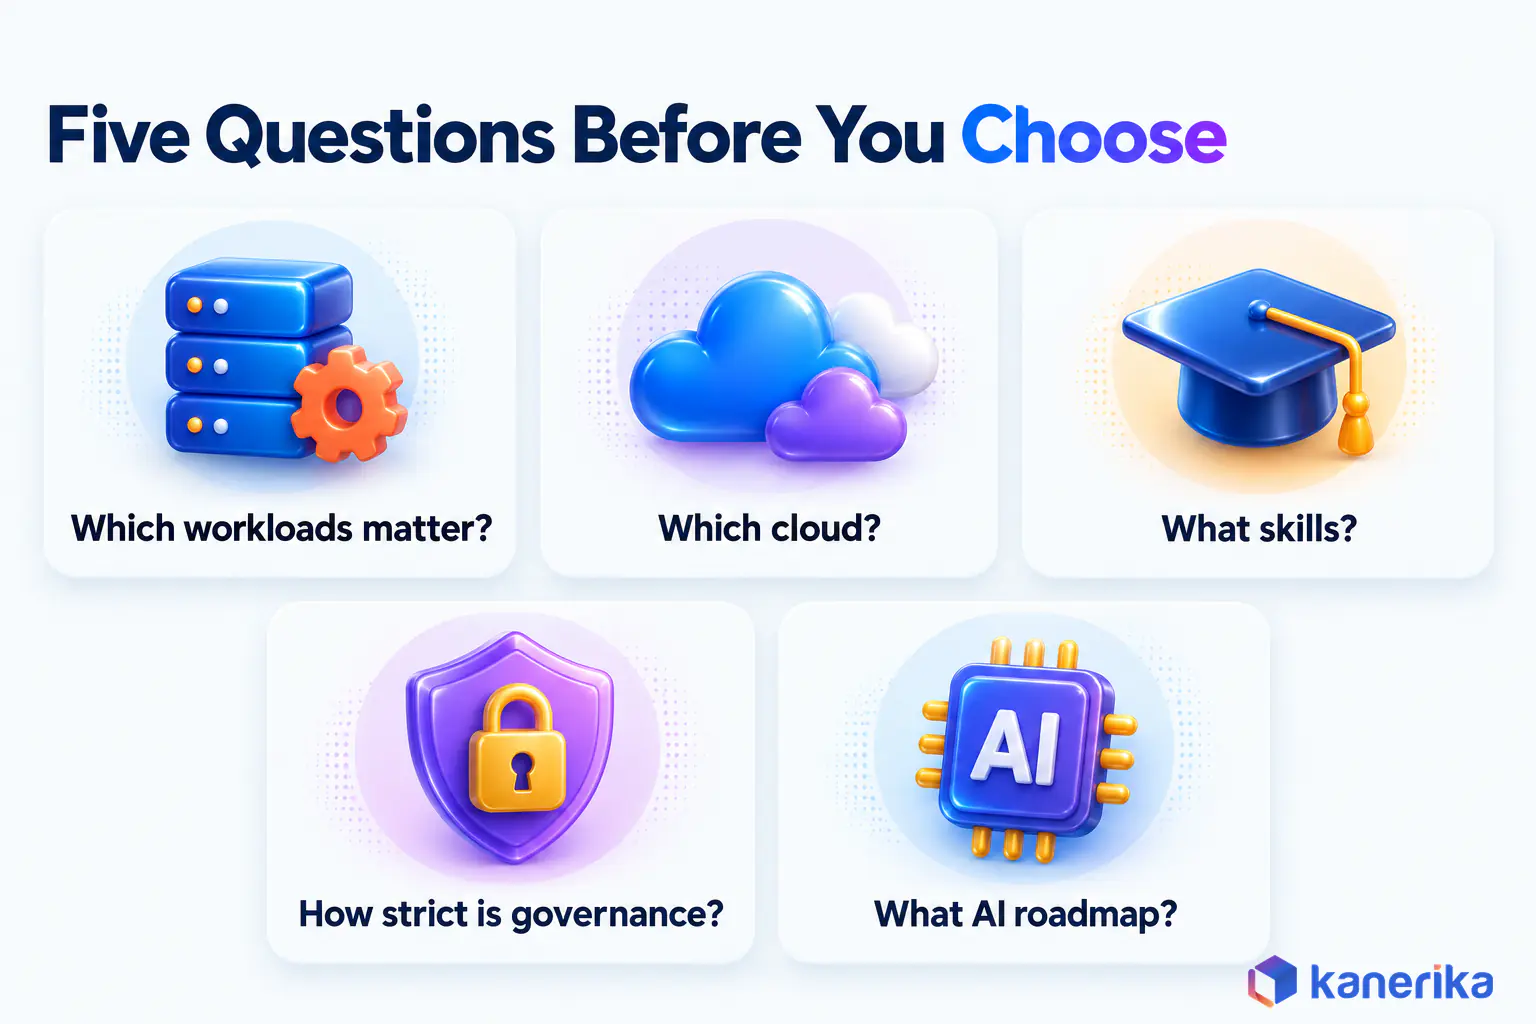
How to Evaluate the Platform: Five Questions and a Fair Proof of Concept
A good evaluation starts with your workloads rather than the vendor’s demo. Once you answer five questions, the shortlist often picks itself.
- Which workloads matter most? Heavy pipelines and machine learning point toward Databricks, while dashboards on clean data point toward a SQL-first tool.
- Which cloud are you on? A single-cloud Microsoft or Google estate changes the math compared to a multi-cloud one.
- What can your team build and run? Databricks rewards engineers who code, but it asks more of teams that do not.
- How strict is your governance? List the access, lineage and audit rules you must prove, then test each vendor against them.
- What is on your AI roadmap? When agents act on enterprise data, they need governed access, cost tracking and evaluation from day one.
Running a Fair Proof of Concept
Run a proof of concept that is fair to every vendor. Pick one real dataset, such as a year of claims or orders, and load it into each platform. Apply the same three access rules and run the same ten business questions, then build one small agent or app. Track setup time, query speed and cost for each.
Score the results with weights you agree on before the test starts, so the loudest demo does not win by default. For example, a team planning agents might weight governance and AI at 30% each, with cost, speed and ease of use sharing the remaining 40%. A BI-first team would flip those weights toward ease of use and SQL speed.
A fair test takes about the same effort for every vendor, but it exposes the gaps a demo hides. Write down who on your team would own each platform after go-live, because that person will live with the choice longest.
Implementation Mistakes and When Databricks Is Not the Right Choice
When a Databricks program stalls, the cause usually sits in how the work was planned and run. Four mistakes come up often, but each one has a clear fix.
| Mistake | Symptom | Fix |
|---|
| Governance added late | Hundreds of tables with unclear owners and broad access | Set up Unity Catalog, groups and grants before the first pipeline |
| No cost guardrails | Surprise DBU bills from idle clusters and oversized warehouses | Use auto-termination, compute policies that limit cluster settings, budgets and workload tags from week one |
| Lift and shift of legacy ETL | Old mappings copied as is, so jobs run slower and cost more | Redesign key pipelines for the lakehouse instead of porting them line by line |
| BI-only use case | An engineering platform bought for dashboards alone | Match the tool to the workload, or add the engineering and AI work that justifies it |
Databricks is also not always the answer. It is usually the wrong pick in three cases, even if the demo impresses.
- When a small team only needs dashboards on a Microsoft estate, it will often move faster on Fabric.
- Analysts who work only in SQL, with no engineering support, will usually find Snowflake simpler than a lakehouse built for engineers.
- A company fully committed to Google Cloud may prefer BigQuery’s serverless model, since it fits that estate natively.
If you are weighing a move away from the platform, our guide to Databricks alternatives covers when switching makes sense.
Skills, above all, sit behind every row of that table. A platform built for engineers needs people who can design pipelines, write grants and tune clusters. Hiring for those skills also takes time. The episode below covers what enterprises should look for in Databricks developers.
How Kanerika Delivers Databricks Programs
Kanerika is a registered Databricks Consulting Partner, and our approach puts governance and proof before speed. We hold ISO 27001, ISO 27701 and SOC 2 Type II certifications, which matters when the data includes patient or financial records.
Every program starts with an assessment of what you already run. For an Informatica estate, that means cataloging mappings, workflows and dependencies, then deciding which pipelines to redesign and which to convert. Our Informatica to Databricks migration service uses FLIP, our migration accelerator, to automate discovery, conversion and validation. The framework converts Informatica transformations to PySpark and handles about 95% of the conversion work while keeping business rules intact.
Unity Catalog comes next, before any data moves. We set up catalogs, groups, grants and lineage first, so every table lands governed.
Legacy Hive metastores get folded into that one catalog without stopping live pipelines. Cutover then happens in phases, with old and new pipelines running in parallel until the outputs match. That parallel run is where data observability tools earn their place, because they flag drift between the two.
On Databricks, the build follows the six layers in this guide. A standard enterprise deployment takes four to eight weeks, covering workspace setup, cluster configuration, governance and links to existing data sources. Unity Catalog groups are mapped to the roles people already hold, so access reviews stay familiar to the business owners who sign them off.
Once the governed foundation is live, the same catalog supports Genie Agents for business questions and custom agents built with Agent Bricks. AI work then starts from tables the business already trusts, instead of a separate copy that nobody owns.
Case Study: Informatica to Databricks for a Healthcare Provider
That approach worked for a leading healthcare provider with clinical, diagnostic and billing data spread across multiple facilities. It moved from Informatica to Azure Databricks. Once the move was complete, results included 71% higher reporting accuracy, a 38% reduction in data handling costs and 64% faster decision-making.
In our experience, the order of the work matters as much as the platform, so we keep governance first. Governed tables give reports one trusted copy, while parallel runs keep reporting live during a cutover. Learn more about our Databricks consulting and implementation work.
Case Study
71% Higher Reporting Accuracy with Informatica to Databricks
A leading healthcare provider moved from Informatica to Azure Databricks and gained 71% higher reporting accuracy, a 38% reduction in data handling costs and 64% faster decision-making.
Read the Case Study →
Final Verdict: Is the Databricks Data Intelligence Platform Right for You in 2026?
The platform is strongest where the work is hardest. Think of teams that build pipelines, train models and plan AI agents across more than one cloud. For them, open storage, Unity Catalog and Agent Bricks give one governed place to do all of it. Gartner also named Databricks a Leader in its 2025 Magic Quadrant for Data Science and Machine Learning Platforms. That was the fourth time in a row, per Databricks’ June 2, 2025 announcement.
The rivals, by comparison, are strongest where the work is simpler. Snowflake fits SQL-first analytics, Fabric fits Microsoft-centric BI, while BigQuery fits Google Cloud-native teams. Per vendor docs checked in October 2026, each one offers open formats, a catalog and AI features. The choice therefore turns on your team and workloads rather than on features.
So, is the Databricks Data Intelligence Platform better than its competitors? Choose it for engineering-led, multi-cloud and agent-heavy work, and choose a competitor when SQL analytics or a single-vendor BI estate leads your stack.
Frequently Asked Questions
What is the Databricks Data Intelligence Platform?
It is a lakehouse that stores data once in open formats such as Delta Lake and Apache Iceberg. On that single copy it runs data engineering, SQL analytics, machine learning, AI agents and apps, governed by Unity Catalog. It runs on AWS, Azure and Google Cloud, and as of October 2026 Databricks markets it as the Data + AI Platform.
Why does Databricks call it the Data + AI Platform?
Databricks’ product page, checked October 23, 2026, uses the name Databricks Data + AI Platform, and the old data intelligence platform page redirects there. The new name puts data, governance, agents and apps forward as one product. The architecture is the same, so guides and searches that use the older name still describe the platform you would buy in 2026.
What is the difference between Databricks and Snowflake, and which is better?
Databricks is an engineering-first lakehouse built for pipelines, machine learning and agents on open formats. Snowflake is a fully managed, SQL-first platform that brings AI into queries through Cortex AI Functions. Neither is better in general. Databricks suits engineering-heavy and AI-agent work, while Snowflake suits analytics teams that mostly write SQL and want less to manage.
Is Databricks just Apache Spark?
No. Spark is the processing engine at the core, and Databricks was founded by Spark’s creators, but the platform adds much more. It includes Delta Lake storage, Unity Catalog governance, Lakeflow pipelines, serverless SQL, Genie, Agent Bricks, Apps and Lakebase. Running plain Spark yourself means building and securing all of those pieces on your own.
Does Databricks run on Azure, AWS or Google Cloud?
Databricks runs on all three, AWS, Microsoft Azure and Google Cloud. On Azure it is sold as Azure Databricks, a first-party Azure service. The core layers are the same on each cloud, which makes Databricks a common choice for companies that run workloads across several providers or expect to change clouds later.
Is Databricks better than Microsoft Fabric?
It depends on your estate. Databricks is stronger for engineering-heavy pipelines, multi-cloud work and building AI agents on open formats. Microsoft Fabric is often simpler for teams built on Power BI and Microsoft 365, since every tenant includes OneLake and Copilot appears across its workloads. Many enterprises use both, with Databricks for engineering and Fabric for BI.
How does Databricks compare with Google BigQuery?
BigQuery is a fully managed, serverless warehouse on Google Cloud with Gemini features and vector search. Databricks runs on three clouds and gives engineers more control over pipelines, machine learning and agents. BigQuery is usually simpler for Google Cloud-native analytics, while Databricks fits multi-cloud estates and teams that need deep data engineering.
Can Databricks and Snowflake work together?
Yes. Both support Apache Iceberg, so one copy of data can be read by both platforms instead of being duplicated. Unity Catalog exposes Iceberg REST Catalog APIs that other engines can call, and Snowflake’s Horizon Catalog supports Iceberg reads and writes from any engine. Many companies run Databricks for engineering and Snowflake for SQL analytics.
What is Unity Catalog in Databricks?
Unity Catalog is the governance layer of the Databricks platform. It manages data and AI assets, such as tables, files, models and dashboards, with one set of permissions, lineage and audit logs. It is also open source under the Apache 2.0 license and offers Iceberg REST Catalog APIs, so other engines can use the same catalog.
Is Databricks suitable for enterprise AI agents?
Yes, it is one of its main strengths. Agent Bricks lets teams build, evaluate and deploy agents with any model or framework on governed data. Unity Catalog limits what each agent can read, and Unity Gateway tracks access and spend across models, tools and MCP servers. That control matters once agents touch customer or patient data.
What are the disadvantages of Databricks?
Databricks asks more of your team than SQL-first tools do. Pipelines and machine learning need engineers who write Python or SQL. Costs can climb if clusters sit idle or warehouses are oversized, so guardrails matter from day one. For a small team that only needs dashboards, a BI-first or SQL-first platform is often simpler and cheaper to run.
Does Databricks support real-time data processing?
Yes. Lakeflow handles streaming pipelines as well as batch, so events such as payments, sensor readings or claim updates can flow into Delta tables as they arrive. Lakebase adds a serverless Postgres for real-time transactional work in apps and agents. Teams often combine streaming tables for analytics with Lakebase for low-latency application reads.
What is Databricks used for?
Teams use Databricks to build data pipelines, run SQL analytics and dashboards, train machine learning models and deploy AI agents and apps. Its main purpose is to give every one of those jobs the same governed copy of data. Common uses include customer analytics, fraud detection, claims processing, demand forecasting and real-time monitoring of devices or transactions.
What is Databricks Lakebase?
Lakebase is a fully managed, serverless Postgres database inside the Databricks platform. It uses the open source Postgres engine rather than a fork and is built for AI and real-time transactional workloads. It autoscales and supports branching, so developers can test changes against a copy of production data without building a separate database outside the platform.
Is Databricks an ETL tool?
Databricks is more than an ETL tool, although ETL is one of its most common jobs. Lakeflow handles ingestion and orchestration for batch and streaming pipelines, and Spark does the heavy transformation work. The same platform then serves SQL analytics, machine learning and AI agents, so the transformed data never has to move to another system.
Is Databricks just a database?
No. Databricks is a data platform built on open files in your cloud storage, with engines for SQL, Python, streaming and machine learning on top. It does include a transactional database called Lakebase, a managed serverless Postgres for apps and agents. That database is one part of the platform rather than the whole of it.
Is Databricks a SaaS or PaaS?
Databricks sits between the two. It is a managed platform you use through a web workspace, which feels like SaaS, while your data stays in your own cloud storage. Serverless options remove most infrastructure work, and classic compute still lets engineers choose cluster sizes, which is closer to a platform-as-a-service model.
Does Databricks use SQL or Python?
It uses both, along with Scala and R. Analysts write standard SQL in Databricks SQL, while engineers and data scientists often work in Python notebooks. Both languages read the same Delta tables under the same Unity Catalog permissions. Databricks SQL uses familiar standard SQL syntax, so most analysts can start without learning a new dialect.
Does Databricks require coding?
Many tasks still need code, especially pipelines and machine learning, where Python and SQL are the norm. Business users can work without code through Genie, which answers plain-English questions on governed tables, and through dashboards and Databricks Apps. Teams with no engineers at all usually find a SQL-first or BI-first platform easier to run.
Which ETL and ingestion tools work with Databricks?
Lakeflow, built into the platform, covers ingestion and orchestration for batch and streaming data. Many teams also connect third-party ingestion and ETL tools that write into Delta tables, as well as orchestrators that trigger Databricks jobs. The right mix depends on your sources, latency needs and the skills your team already has.
How much does Databricks cost?
Databricks charges pay as you go with no up-front costs, billed per second. Processing is measured in DBUs, which depend on the compute used and the data processed, and storage in DSUs. Committed use contracts give discounts. Your real cost depends on workload hours, idle time and data volume, so model those before comparing vendors.














