TL;DR
In data fabric vs data virtualization, pick virtualization for quick access and a fabric for consistent numbers across many sources. Data virtualization queries data where it lives, without copying it. A data fabric finds, governs and delivers data across the whole company. Many fabrics use virtualization inside them, so the two often work together. Virtualization slows down when busy sources get too many queries. So start with your problem: virtualize when people cannot reach data, and build a fabric when their numbers disagree.
Key Takeaways
- Data virtualization is an access technique, so it queries data in place and returns one combined result without copying it by default.
- A data fabric is an architecture: active metadata, governance and a semantic layer decide how data is found, secured and then delivered.
- Virtualization often runs inside a fabric as one delivery mode, together with replication and batch pipelines.
- Virtualization fits fast access to a few sources, while a fabric fits shared KPIs, lineage and policy across many owners.
- Materialize data when sources cannot take query load, or when you need history, heavy transformation or ML features.
- Name the bottleneck first, then prove one outcome with exit criteria before you buy a platform.
The Quarter-End Report That Touched Three SAP Systems
Picture a sales operations lead at quarter end. Quotes live in one SAP system, approvals in a second and deliveries in a third. Each team exports its own numbers, so the totals never match by Friday.
The data team has two options on the table. It can query all three systems in place and then stitch the answer together at read time. Or it can build a governed layer that copies, cleans and defines the data once, so every report uses the same numbers.
That fork is the real data fabric vs data virtualization question. One answer buys speed of access, while the other buys consistency.
The stakes are higher in 2026, because AI assistants read the same data as dashboards. An assistant that pulls an ungoverned number will repeat it with confidence, to far more people than a report ever reached.
Data Fabric vs Data Virtualization: The Short Answer
The two terms sit at different levels of the stack. Data virtualization is a technique for reaching data. A data fabric is an architecture for managing it, and that architecture can also use virtualization inside it.
Think of virtualization as a universal adapter. A user writes one query, the virtual layer sends parts of it to each source, and then the results come back as one table. Nothing is copied unless the layer decides to cache it, so it is quick to stand up and data stays where its owners want it.
A fabric, by comparison, works one level up. It keeps a live map of what data exists, who owns it, what it means and who may see it. It then picks a delivery mode for each use, such as virtual access for some data and replication or batch pipelines for the rest.
For a quick decision, the choice comes down to two picks:
- Pick data virtualization when the problem is fast, governed access to two to five sources and the data can stay where it is.
- Pick a data fabric when the problem is consistent definitions, lineage and policy across many sources and owners. A fabric can still use virtualization for the sources that do not need to move.
What Is Data Virtualization?
Data virtualization lets people query data from many systems as if it sat in one place. IBM describes it as a virtual layer between data sources and the people who use them, giving access without replication or movement. The consumer sees one logical model, while the sources stay where they are.
For example, take a finance analyst who needs revenue by region. Orders sit in an ERP database, regions in a CRM and currency rates in a cloud file. With a virtual layer, she queries one view called revenue by region, so she never needs to know where each column came from. Behind that view, the layer handles connections, SQL dialects and security checks.
People often confuse the term with data visualization, which is about charts and dashboards. The two meet at one point only, since a dashboard is often the consumer that sends queries to the virtual layer.
How a Federated Query Runs: Pushdown, Caching and Source Load
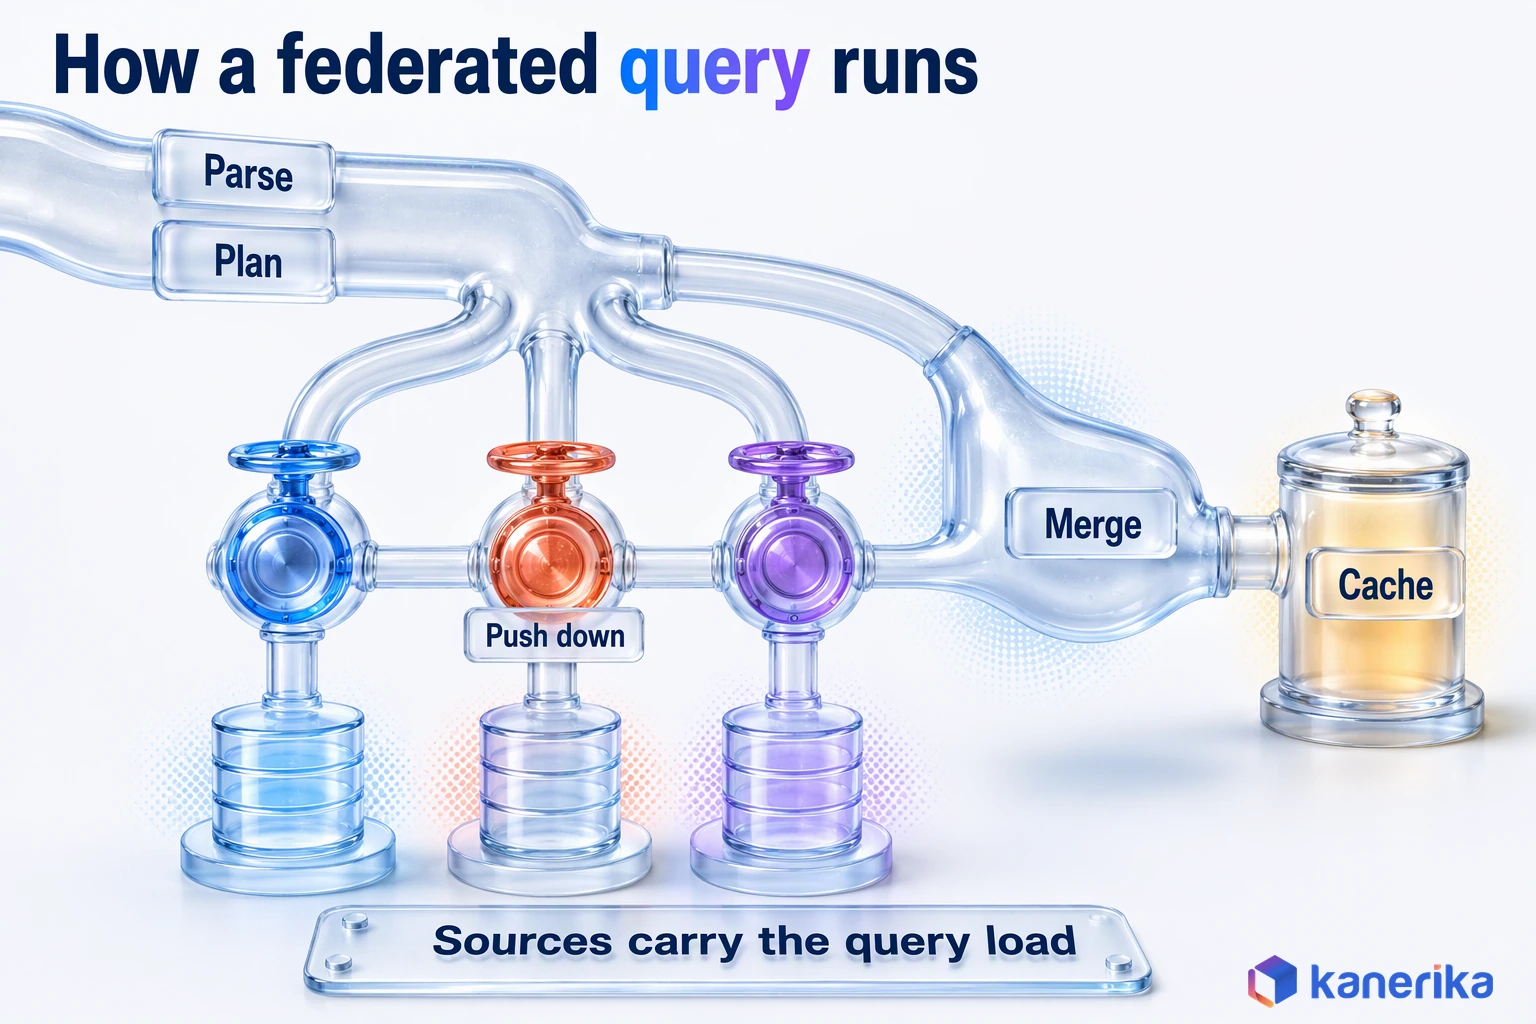
Under the hood, a virtual layer is a query planner that hands work to other systems. Each request runs through the same five steps:
- Parse: the layer reads the query against its logical model, then maps each view to its physical sources.
- Plan: it estimates cost and decides which source handles which part of the work.
- Push down: filters, joins and aggregations go to the sources, so only reduced rows travel back.
- Merge: the layer combines the partial results, then runs any remaining joins and enforces access rules.
- Cache: frequent results can be stored for reuse, so repeat load on the sources drops.
Pushdown is what lets the model scale. Databricks, for example, documents query federation with automatic query pushdown over JDBC connections, governed through Unity Catalog. When a filter runs inside the source database, the network carries thousands of rows instead of millions.
Pushdown has limits, and they differ by connector. For PostgreSQL, the Databricks connector documentation lists filters, projections, limits, offsets and aggregates as pushed down. Date, string and math functions go down only inside filter expressions, and anything outside the list runs in the federation engine after the rows arrive. The setup takes two statements, shown here with illustrative names:
-- Illustrative names; syntax from the Databricks PostgreSQL federation docs
CREATE CONNECTION erp_pg TYPE postgresql
OPTIONS (host '<hostname>', port '5432', user '<user>', password '<password>');

CREATE FOREIGN CATALOG IF NOT EXISTS erp
USING CONNECTION erp_pg
OPTIONS (database 'orders');

-- The WHERE filter and the SUM aggregate are candidates for pushdown
SELECT region, SUM(amount) AS revenue
FROM erp.public.orders
WHERE order_date >= '2026-10-01'
GROUP BY region;
When Source Load and Caching Become the Limit
The catch is that the source systems still do the work. A month-end reporting peak therefore lands on the same ERP that processes orders. If that database is already busy, every virtual query slows it down further for the people running the business.
Caching helps with repeated questions, though it adds a freshness rule you have to manage. In OneLake, for example, you set a cache retention period of 1 to 28 days. Each read resets that clock, and single files over 1 GB are never cached. When queries keep hitting the same large tables, the better fix is usually to materialize that data into a store built for analytics. That is where pure virtualization stops and a data pipeline architecture begins, as the guide to data integration vs ETL explains.
Kanerika Service
Data Integration Services
Kanerika connects ERP, CRM, cloud and file sources through virtual access, replication or governed pipelines, choosing the delivery mode each workload needs.
Explore Data IntegrationWhat Is a Data Fabric?
A data fabric is an architecture that manages data across every platform a company runs. IBM defines it as a modern data architecture that delivers integrated, end-to-end data management, supported by machine learning, active metadata and APIs. In other words, the word fabric points to the woven layer that connects sources, rules and users.
Active metadata is the engine. A fabric records what each dataset holds, where it came from, who owns it and how people use it. It then acts on that record to recommend data, apply policy and choose how data moves, which is the step beyond a plain catalog. Automated data lineage is the piece that lets a team trace any KPI back to its source.
Picture a new analyst who searches for customer churn. The fabric shows the certified dataset, its owner and its lineage, and it also masks personal fields based on her role. As a result, she can use the data without filing an access request. For the full architecture, see the Kanerika guide to data fabric.
The Layers: Connectors, Active Metadata, Governance, Semantic Layer, Delivery
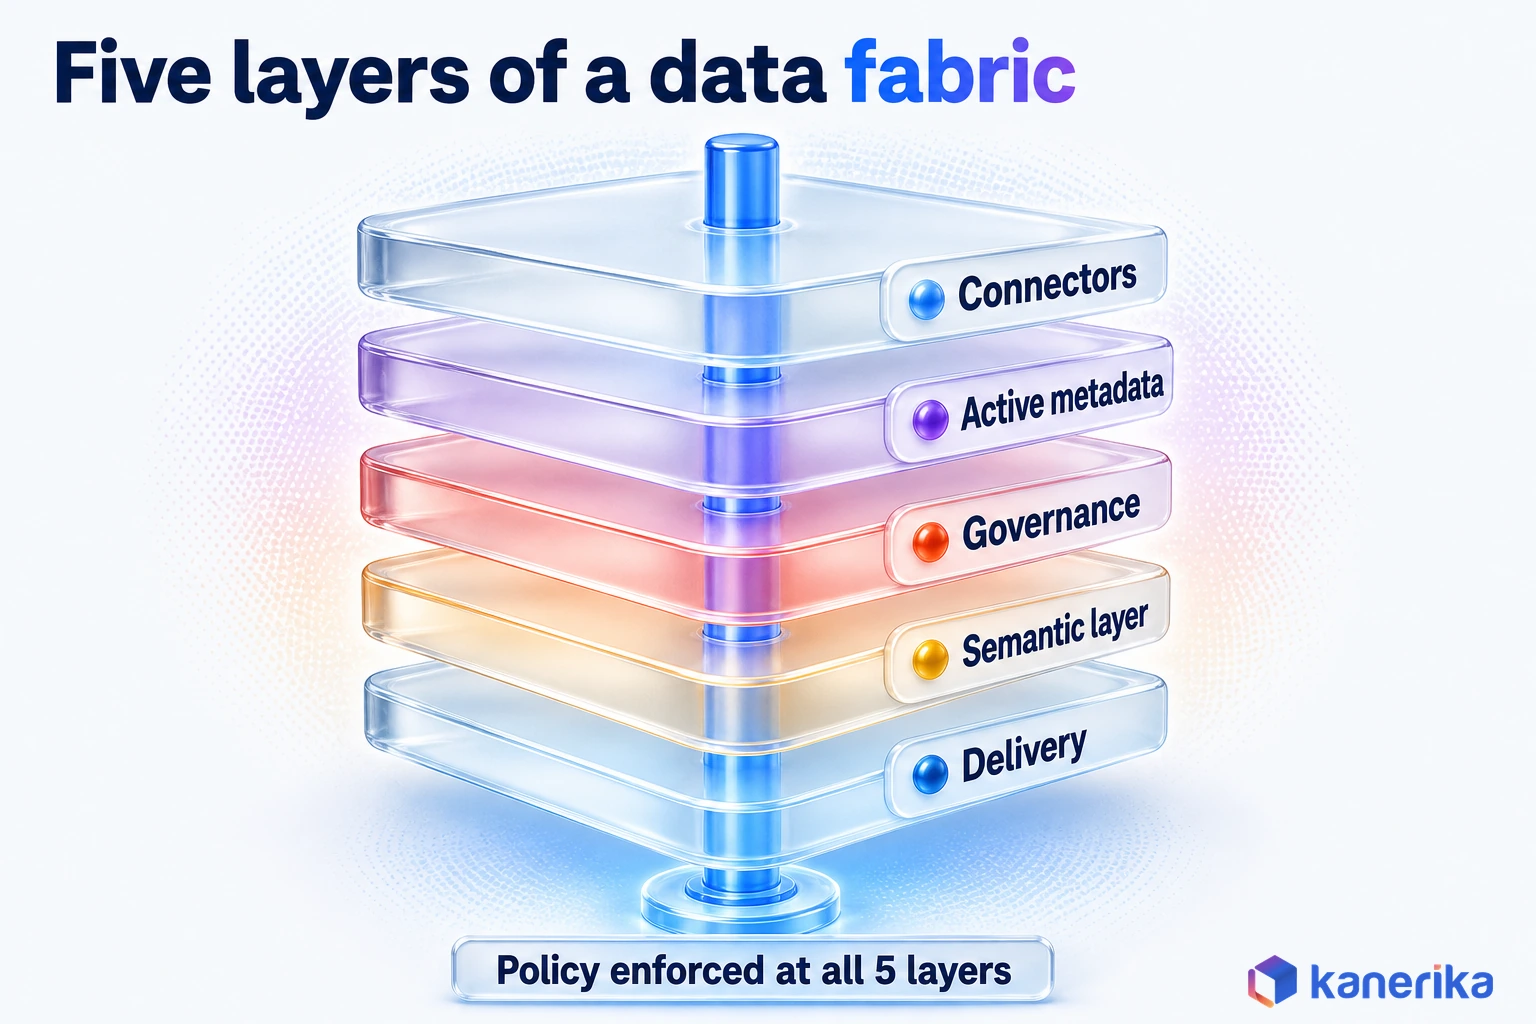
Most fabric designs share five layers, each with a clear job. The table also shows where policy is enforced in each layer, because that detail decides how safe the design is. For the catalog layer specifically, the review of metadata management tools compares the options.
| Layer | What it does | Where policy is enforced |
|---|---|---|
| Connectors | Read from sources such as databases, files, SaaS apps, streams and APIs | Source credentials, before any data moves |
| Active metadata | Catalogs datasets, tracks lineage, then profiles quality and usage | Classification tags, which later rules use |
| Governance | Applies access, masking, retention and residency rules | A central policy engine, then pushed to every engine |
| Semantic layer | Defines business terms, KPIs and how they relate | Certified definitions and row-level security |
| Delivery | Serves data by virtual query, replication, batch or streaming | At query time, then again in the target store |
Storage, however, is a separate decision. A fabric can sit over lakes, warehouses and operational systems at once. The comparison of data fabric vs data lake explains where the storage layer fits.
Data Fabric vs Data Virtualization: Side-by-Side Comparison
Virtualization answers how you reach this data, while a fabric answers how all of your data is found, trusted and delivered. When you read the rows, notice how often the fabric column includes virtualization as one option.
| Dimension | Data virtualization | Data fabric |
|---|---|---|
| Scope | An access layer over selected sources | An architecture across the whole data estate |
| Data movement | None by default, although caching is optional | Mixed, such as virtual access, replication, batch and streaming |
| Metadata | Mostly technical, for mapping queries | Active metadata on meaning, lineage, quality and usage |
| Governance enforcement point | In the virtual layer, when the query runs | Central policies, then pushed to every engine and store |
| Performance profile | Bound by the slowest source and the network | Tuned per workload, while hot data is materialized |
| Source-system load | High, since every query reaches the source | Lower, since heavy reads hit copies or caches |
| Historical data | Only what the sources still keep | Stored history and snapshots, even after sources purge them |
| Transformation depth | Light, such as joins, renames and simple calculations | Heavy data transformation in governed pipelines |
| AI readiness | Wide reach, although little shared meaning | Semantic layer and lineage give AI governed context |
| Time to first value | Fast, since a first view needs only connections and a model | Staged, so value arrives domain by domain |
| Team and ownership | A small platform team | Data owners, stewards and a platform team |
| Typical cost drivers | Licenses, source compute and egress | Metadata work, storage, pipelines and skills |
The historical-data row is where many teams pause. When the main need is centralized history, a warehouse may also belong in the answer. The guide to data fabric vs data warehouse explains how the two relate.
How Data Virtualization Works Inside a Data Fabric
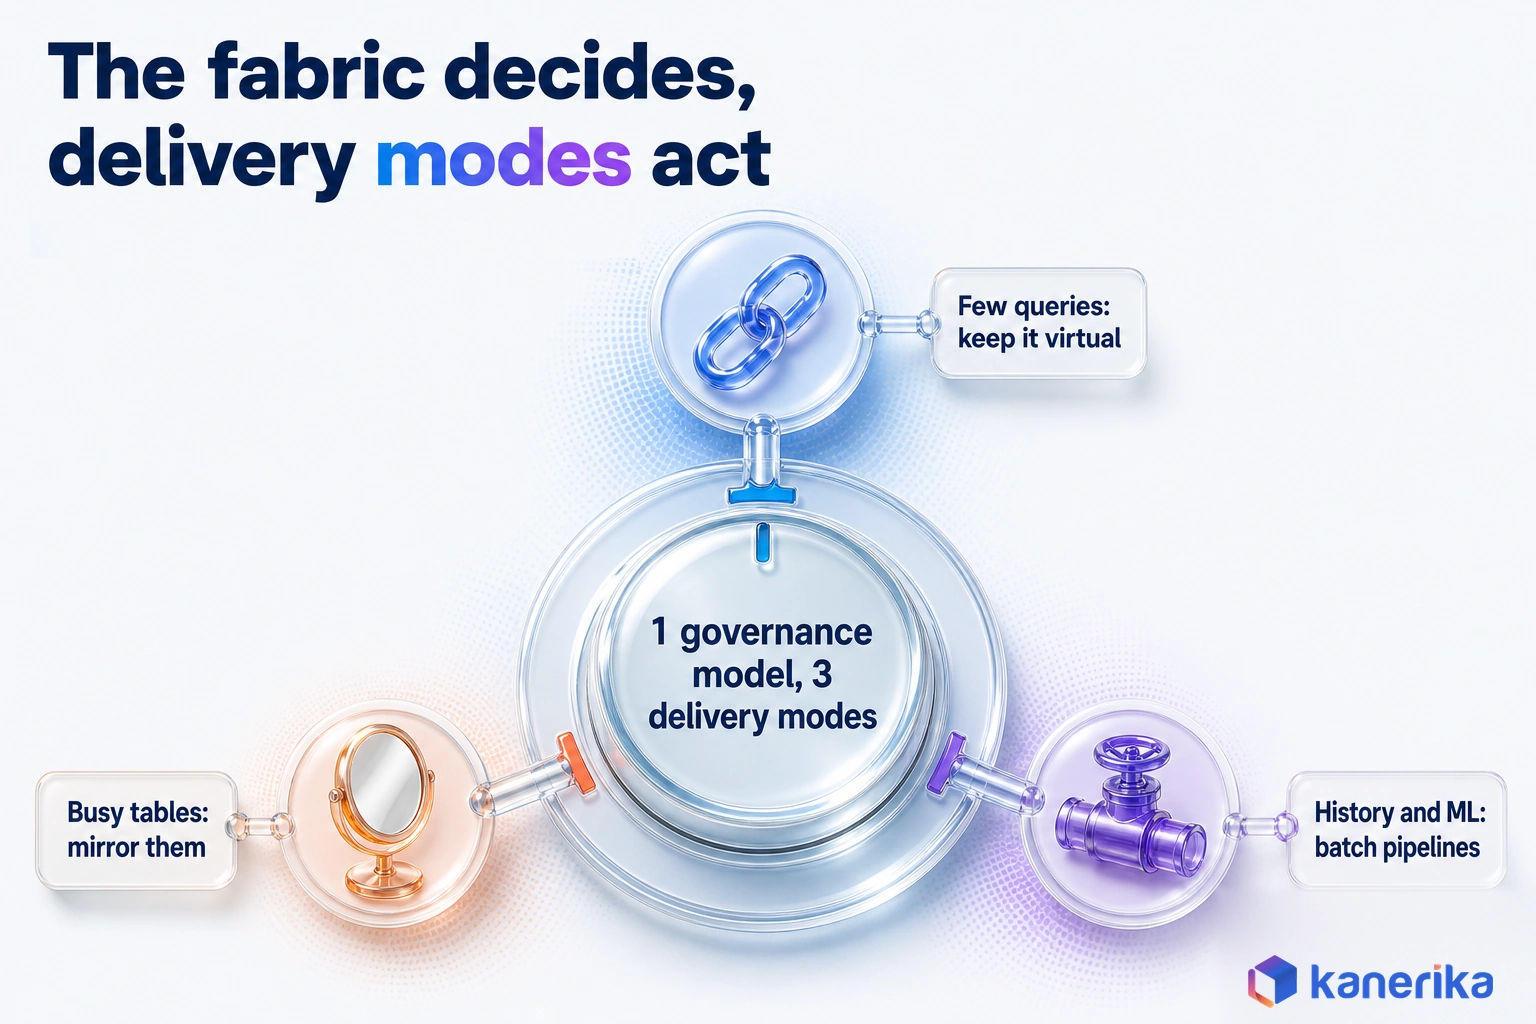
Inside a fabric, virtualization becomes one of several ways to deliver data. The fabric decides what each use case needs, and then a delivery mode carries it out: virtual access, replication or a batch pipeline.
Microsoft Fabric, a product and one of several ways to build a data fabric rather than the architecture itself, shows the pattern clearly with two features side by side. OneLake shortcuts behave like symbolic links, so data in Amazon S3 or Google Cloud Storage appears inside OneLake without a copy. Microsoft calls the result a single virtual data lake, and the Kanerika walk-through of Microsoft Fabric OneLake shortcuts shows the setup step by step.
Mirroring takes the opposite route. It continuously replicates databases or tables into OneLake as a fully managed service, and it also converts the data to Parquet. Analytics run against the copy instead, which keeps load off the operational database. A QAD to Fabric mirroring project is one example of this route for an ERP.
Shortcuts vs Mirroring: The Parameters That Decide
The choice between the two comes down to a handful of documented settings. The values below come from Microsoft Learn pages updated in 2026. Check them again before a design review, since the platform changes often.
| Parameter | OneLake shortcut (virtual) | Mirroring (replicated) |
|---|---|---|
| Data copied | No, it points to the source | Yes, into OneLake as Delta and Parquet |
| Freshness | Reads the source, or a cache that is refreshed when the source has a newer file | Near real time, with changes published as often as every 15 seconds |
| Cache or retention setting | Cache retention of 1 to 28 days; files over 1 GB are not cached | Delta history kept 1 day by default for databases created after mid-June 2025 |
| Scale limit | Up to 100 unique data source connections per Fabric item | Free mirroring storage of 1 TB per capacity unit |
| Who carries query load | Source store, unless the file is cached | OneLake replica, charged as normal query compute |
The fabric’s job is to choose between the two for each source. For example, a product catalog that changes daily and gets few queries can stay virtual. An order table that dashboards hit every minute suits mirroring better than shortcuts. Historical trends and ML training data go through batch pipelines instead, since they need stored history. One governance model covers all three, so users see the same names, owners and access rules whichever mode serves the data.
Where Each Approach Fits: Workloads and Scenarios
The right choice depends on the job in front of you, so it helps to test both options against real workloads. Each row names a scenario and the usual pick, as well as the case where that pick flips.
| Scenario | Pick | Why | Exception |
|---|---|---|---|
| Federated reporting over two to five sources | Data virtualization | Quick to stand up, since no new copies need maintaining | When sources are too busy at peak hours |
| Regulated data that cannot leave its region | Data virtualization | Data stays put, while only query results travel | When the results themselves fall under residency rules |
| Interim integration after a merger | Data virtualization | One view of both companies while systems stay separate | When the interim period drags on and history matters |
| Real-time operational dashboards | Data virtualization, or replication inside a fabric | Fresh data without nightly batch delays | When a fragile source gets high query volume |
| Historical trends and ML training | Data fabric | Needs stored history and heavy transformation | A one-off analysis on current data only |
| Enterprise-wide KPI consistency | Data fabric | One certified definition per metric | A single team working from a single source |
| AI assistants needing governed context | Data fabric | A semantic layer and lineage give agents trusted meaning | A narrow pilot over one clean source |
| Hybrid multicloud estate | Data fabric with virtual access | Central policy, even though data stays in each cloud | Once the estate is one cloud with a handful of sources |
The pattern across the rows is simple. Virtualization wins when the need is narrow, fresh and close to the source. A fabric wins when many teams must agree on what a number means and prove where it came from.
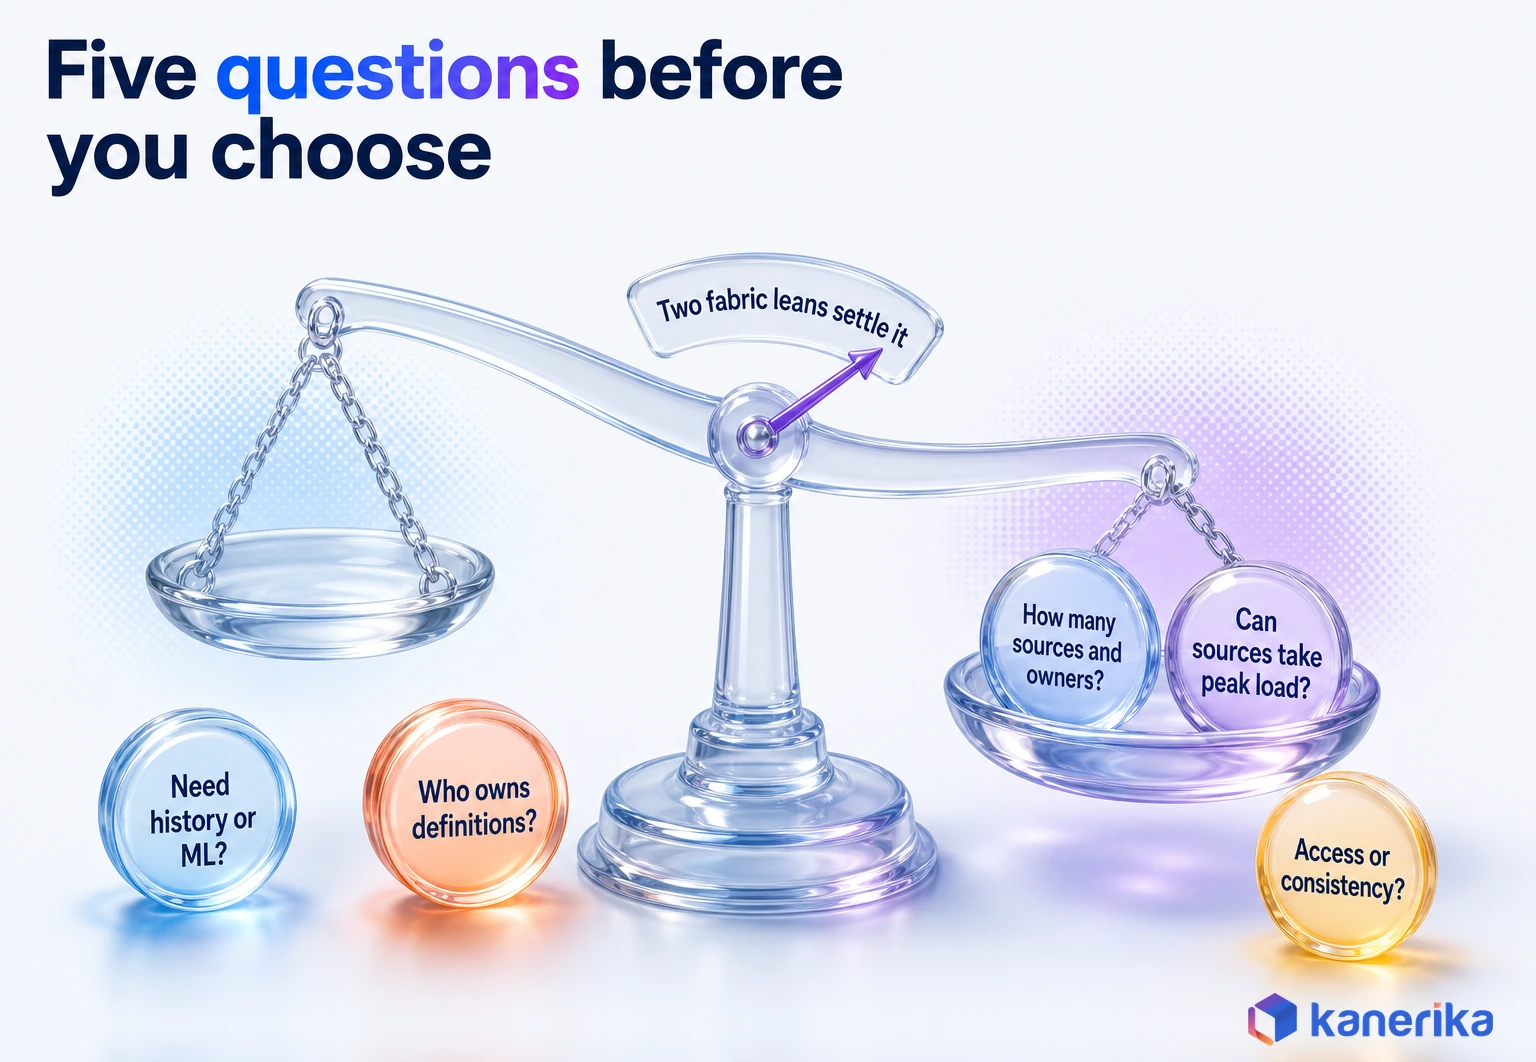
Decision Framework: Five Questions Before You Choose
Five short questions keep the decision grounded in your own constraints instead of a vendor’s category label. Answer each one honestly, then note which way it leans.
- What is the bottleneck: access or consistency? When people cannot reach data, lean toward virtualization. When they reach it and still disagree on the numbers, lean toward a fabric.
- How many sources and owners are involved? A few sources under one owner suit a virtual layer. Dozens of sources under many owners, however, need the metadata and stewardship of a fabric.
- Can the sources take query load at peak? When the ERP already slows down at month end, avoid sending more live queries to it, and replicate or materialize instead.
- Do you need history, heavy transformation or ML features? A yes points to persisted, modeled data inside a fabric, because sources rarely keep full history.
- Who owns policy, lineage and definitions? When nobody does, a fabric product will not fix it. Assign owners first, whichever pattern you choose.
Two or more answers that lean toward a fabric usually settle it. A single fabric lean, such as one busy source, can often be solved by materializing that source while the rest stay virtual.
Worked Example: Lead-to-Delivery Reporting Across Three SAP Systems
This walk-through is illustrative and builds on the scenario from the opening. It follows the same reasoning as a real Kanerika engagement described later in this guide.
Start with the bottleneck. The sales team could reach each system, yet the numbers still did not match, which points to consistency. The second answer pushes the same way, since the order journey crossed SAP Cloud for Customer, CPQ and S/4HANA, each with its own owners.
Source load was the third check. A virtual pilot over the three systems would have served a few analysts and also given leaders an early joined view. Rolled out to every sales office, though, it would have sent a steady stream of queries to transactional systems.
Finally, history settled it. Leaders wanted trends across quarters and 50+ standard KPIs, so the data had to be stored and modeled. Access rules also had to follow the sales hierarchy at four levels, from region down to sales group.
The answer was the data fabric side of the choice: a persisted, governed layer, built here as a Medallion architecture on the Microsoft Fabric platform, with one set of definitions and row-level security. A virtual layer would still have been a sensible pilot tool for proving the joins before the pipelines were built.
Cost, Effort and Time to Value
Each approach spends money at a different point, so compare the cost drivers before you compare any quote. Virtualization is light to start, then pays as you query. A fabric asks for more work up front in metadata, ownership and pipelines, then spreads that cost across every later use case.
The table lists the drivers to price for your own estate. It gives no list prices, since licensing models vary by vendor and contract.
| Cost driver | Data virtualization | Data fabric |
|---|---|---|
| Licensing model | One platform license, priced on the vendor’s own metric | One platform or several tools, each with its own pricing |
| Source-system compute | High, since every query runs at the source | Lower, since heavy reads hit replicas or cached copies |
| Egress | Charged when queries pull data across clouds | Charged during replication, although caching can reduce it |
| Caching storage | Small, since it holds hot results only | Larger, since it holds replicas, history and models |
| Metadata and catalog work | Light, for the views you publish | Heavy, especially for classification, lineage and certification |
| Skills | SQL and data modeling | Data engineering as well as governance and stewardship |
| Change management | Low, since users keep their tools | Higher, because owners, definitions and ways of working change |
Egress deserves a closer look, especially in multicloud estates. Microsoft notes that OneLake shortcut caching can reduce egress costs when data is read from other clouds. It is also a good example of a fabric mixing virtual access with caching to control spend.
Kanerika Service
Data Strategy Consulting
Kanerika maps your sources, owners, peak load and cost drivers, then turns the virtualize-or-fabric choice into a staged plan with exit criteria.
Explore Data StrategyA Worked Cost Example: Mirroring a 3 TB ERP Database
Published vendor terms make the trade-off concrete. Under the Fabric mirroring cost rules, the background compute that replicates data is free, and each capacity unit includes 1 TB of free mirroring storage. An F64 capacity therefore carries 64 TB of replica storage at no extra charge.
Take an illustrative case. A team mirrors a 3 TB ERP database on an F8 capacity, which includes 8 TB of free mirroring storage. The replica sits well inside that allowance. Its spend shows up in query compute for SQL, Power BI or Spark, which Microsoft charges at regular rates. The same reports run through a virtual layer would instead spend source compute on every refresh. For capacity sizing, see the guide to Microsoft Fabric pricing.
Tooling in 2026: How Platforms Map to Each Pattern
Tools rarely fit neatly into one box, so map each one to the pattern it implements. The table quotes capabilities as each vendor states them in its own documentation, so the order implies no ranking.
| Platform | Pattern it implements | Capability as the vendor states it | Source |
|---|---|---|---|
| Denodo Platform | Data virtualization as well as logical data management | A “logical data management solution” that sits above all data sources, with real-time access, security and governance | Denodo |
| Microsoft Fabric OneLake shortcuts | Virtual access inside a fabric | Shortcuts to stores such as S3, S3-compatible storage, ADLS Gen2, Azure Blob, Dataverse, Google Cloud Storage, Iceberg and OneDrive or SharePoint | Microsoft Learn |
| Microsoft Fabric Mirroring | Replication inside a fabric | Fully managed, continuous replication of databases or tables into OneLake, then converted to Parquet | Microsoft Learn |
| Databricks Lakehouse Federation | Query federation together with central governance | JDBC query federation with pushdown and Unity Catalog governance, plus catalog federation for sources such as Hive Metastore, AWS Glue and Snowflake | Databricks docs |
One naming point causes real confusion. Microsoft Fabric is an analytics platform for end-to-end data workflows on a SaaS foundation. The generic data fabric is an architecture pattern, so Microsoft Fabric is one of several ways to build it.
Databricks also adds a useful note on trade-offs, covered in more depth in the Kanerika guide to Databricks Lakehouse Federation. Its documentation describes catalog federation as more cost-effective and performance-optimized than query federation over JDBC. That matches the rule of thumb in this guide, since live queries are convenient while governed access to stored data is cheaper at scale.
Which Is Better for AI and RAG?
AI assistants and retrieval-augmented generation (RAG) raise the bar for both patterns, because a model repeats whatever data a RAG pipeline hands it. Reach matters, since an agent cannot use data it cannot find. Meaning matters more, since an agent that mixes up two definitions of revenue will answer wrongly with confidence.
Virtualization supplies reach. It can expose many sources to an agent through one query interface, so it suits a narrow pilot. A fabric, on the other hand, supplies meaning. Certified definitions, lineage and access rules travel with the data, often captured in a semantic layer or ontology. The comparison of ontology vs semantic layer explains which one an agent needs.
The difference shows up once systems reach production. In one pharmaceutical case, one governed ontology on Microsoft Fabric defined 85+ KPIs, and investigation and reconciliation time fell by 70%. The same need for governed context drives agentic BI, where agents act on business data and therefore must act safely.
For AI, then, the stronger base is a data fabric that uses virtual access where it helps. Virtualization widens reach quickly, while the fabric’s semantic layer decides what an agent may treat as true.
Risks, Governance and Common Mistakes
Both patterns fail in predictable ways, and the failures are usually about governance more than technology. The table lists seven common ones, the sign that each is happening and the fix.
| Risk | Sign | Mitigation |
|---|---|---|
| The virtual layer becomes a bottleneck | Query times climb while user numbers grow | Cache hot views, then materialize heavy ones and scale the layer |
| A source outage breaks reports | Dashboards fail when one system is down | Replicate critical sources and set clear service levels |
| Masking is applied in BI only | Raw values leak once users switch tools | Enforce masking in the virtual or governance layer instead |
| Lineage gaps | Nobody can trace a KPI back to its source | Capture lineage automatically through active metadata |
| A “fabric” product is bought without metadata ownership | The catalog goes stale soon after launch | Name data owners and stewards before buying |
| Virtualizing what should be materialized | The same heavy tables are hit again and again | Move those tables into a modeled store |
| No exit criteria in the proof of value | The pilot runs on until someone stops it | Agree success and stop conditions before the pilot starts |
Governance across a virtual layer needs one extra check. Policies must apply at the layer itself, so a user who skips the dashboard and queries directly still sees masked data.
Where Virtual-Layer Governance Breaks
Identity handling shows how easily this slips. Microsoft documents a case with OneLake shortcuts read through Power BI in Direct Lake over SQL, or through T-SQL in delegated identity mode. There, the item owner’s identity reaches the target instead of the user’s. A report built that way can show a regional manager rows her own account could never read. The documented fix is Direct Lake over OneLake, or T-SQL in user identity mode.
Standards bodies treat these as one discipline. The DAMA-DMBOK, which DAMA International calls the globally recognized framework for data management, covers data governance alongside data integration and interoperability. A written data governance framework gives both patterns the same owners and rules. For teams also weighing domain ownership, the comparison of data fabric vs data mesh covers how domains share that responsibility.
Run a Three-Step Proof of Value
A proof of value keeps these risks small and visible, so run one before any large purchase. It takes three steps:
- Baseline: measure today’s report cycle time, query latency and number of conflicting figures before anything changes.
- Test: run real queries at peak load, then add a negative-permission test. A user barred from a field must fail to see it in every tool.
- Exit criteria: agree before you start which result moves you to production and which result stops the pilot.
Talk to Kanerika
Not Sure Whether to Virtualize or Build a Fabric?
Bring one reporting problem to a working session. Kanerika will map the bottleneck, the sources involved and a proof of value you can run with clear exit criteria.
Schedule a Demo →How Kanerika Helps You Choose and Build the Right Data Layer
Kanerika helps enterprise data teams pick the pattern that fits their bottleneck, then build it with ownership and controls in place. The work starts from evidence about sources, load and policy, so product labels never drive the decision. Our data integration services and data strategy consulting follow four stages:
- Assess: map sources, owners, peak load and policy needs, then name the real bottleneck.
- Prove one outcome: build one virtual or persisted use case with agreed exit criteria before scaling anything.
- Productionize: add ownership, row-level security and lineage as well as monitoring.
- Expand: extend the pattern to new domains only when the evidence supports it.
A global leader in thermal management and heat transfer solutions is the real engagement behind the worked example above. Kanerika built one governed pipeline on Microsoft Fabric that moved about 35 source tables into a Medallion architecture with development, test and production stages.
A bridge linked Opportunities, Quotes and Orders, while a self-updating Power BI report tracks 50+ standardized KPIs. Row-level security works at four levels: region, Sales Organization, Sales Office and Sales Group. As a result, the client cut the time spent per reporting cycle by 60%.
Case Study
60% Less Reporting Effort Across 3 SAP Systems on Fabric
A global leader in thermal management and heat transfer solutions joined SAP Cloud for Customer, CPQ and S/4HANA data in one governed Fabric pipeline with 50+ KPIs and four-level row-level security.
Read the Case Study →Teams planning a wider program can also start from the Kanerika guide to enterprise data integration, which covers the architecture choices around this decision.
The Verdict: Start With the Bottleneck, Not the Label
In the data fabric vs data virtualization decision, choose data virtualization for fast, governed access to a few sources. On the other hand, choose a data fabric when you need consistent definitions, lineage and policy across many sources and owners.
Plenty of teams end up running both, because a fabric often uses virtualization as one of its delivery modes. When people cannot reach the data, virtualize it. When they reach it but still argue about the numbers, build the fabric and let virtualization serve the sources that do not need to move.
So which fits your stack? It depends on that one answer: access problems call for data virtualization, and consistency problems call for a data fabric.
Frequently Asked Questions
What is the difference between data fabric and data virtualization?
Data virtualization is a technique that queries data where it lives and returns one combined result without copying it. A data fabric is an architecture that uses active metadata, governance and a semantic layer to manage data across the whole estate. A fabric often includes virtualization as one delivery mode, next to replication and batch pipelines.
How does a data fabric work?
A data fabric connects to every source and records active metadata about each dataset. That metadata covers meaning, owner, lineage, quality and usage. The fabric uses it to recommend data, apply access and masking policies, and choose a delivery mode. Users then find governed data through one catalog, whether the data is queried virtually or copied.
When should a company use data virtualization instead of ETL or replication?
Use data virtualization when you need fresh data from a few sources, the sources can handle the query load and history is not required. ETL or replication is the better fit for heavy transformation, long history, ML features or busy operational systems. Many teams virtualize first to prove value, then materialize the heaviest tables.
Is data virtualization part of a data fabric?
It often is. A data fabric decides how each dataset should be delivered, and virtualization is one of the delivery modes it can use. Replication and batch pipelines are the others. The fabric adds the metadata, governance and semantic layer around those modes, so users see the same definitions and rules whichever mode serves them.
Can data fabric and data virtualization work together?
Yes, and they usually do. The fabric supplies the catalog, lineage, policies and business definitions. Virtualization supplies quick access to sources that do not need to move. In Microsoft Fabric, for example, OneLake shortcuts give virtual access while Mirroring replicates busy databases, and one governance model covers both delivery modes.
Is Microsoft Fabric a data fabric?
Microsoft Fabric is a SaaS analytics platform for end-to-end data workflows. A data fabric is a generic architecture pattern. You can build a data fabric with Microsoft Fabric, because it offers virtual access through OneLake shortcuts, replication through Mirroring and central governance. It is also more than an ETL tool, since it covers storage, engineering and BI.
Is data fabric better for AI than data virtualization?
For production AI, a data fabric is usually the stronger base. Agents and RAG systems need governed meaning, such as certified definitions, lineage and access rules, and a fabric supplies those. Virtualization adds reach to many sources quickly, which helps a pilot. The best setup is often a fabric that uses virtual access where it fits.
When should you materialize data instead of virtualizing it?
Materialize data when the same large tables are queried again and again, or when the source system slows down at peak. Also materialize when you need history, heavy transformation or ML features, since sources rarely keep those. Virtualize when data changes often, gets few queries and must stay in its home system.
Which costs more, data fabric or data virtualization?
The two spend money at different points. Virtualization is cheaper to start but adds source compute and egress with every query. A data fabric costs more up front in metadata work, storage, pipelines and skills, then spreads that cost across later use cases. Compare the drivers for your own estate before comparing quotes.
How do you govern data across a virtualization layer?
Apply access and masking rules in the virtual layer itself, so users who skip the dashboard still see protected data. Tie the rules to roles and data classifications, and capture lineage for every published view. Test with a user who should be denied a field. That user must fail to see it in every tool.
Does data fabric replace a data warehouse?
No. A data fabric is an architecture that sits across many stores, and a warehouse is often one of them. The warehouse holds modeled, historical data for reporting. The fabric adds catalog, lineage, policy and delivery across the warehouse, the lake and operational systems. Most fabric designs keep a warehouse or lakehouse for heavy analytics.
What is data virtualization?
Data virtualization is a logical layer between data sources and the people or tools that use them. It lets users query many systems as if the data sat in one place. The layer pushes work down to each source, merges the results and applies security rules. By default, it does not copy or move the data.
How does data virtualization support modern data integration?
Data virtualization gives teams a fast way to combine sources without building a pipeline first. It suits new sources, interim views after a merger and data that must stay in its region. Integration teams often use it to prove joins and demand early. They then move heavy, frequently queried tables into governed pipelines.
What are the different types of data virtualization?
Common forms include federated query engines, logical data warehouses and virtual access features built into platforms. Federated engines send each query to the sources and merge the results. Logical warehouses add a business model and caching on top. Platform features, such as OneLake shortcuts in Microsoft Fabric, expose external storage inside one lake without copying it.
Why is it called data fabric?
The name compares the architecture to woven cloth. Many threads, meaning sources, platforms and teams, are joined into one connected layer. Metadata, governance and delivery services run across every thread, so data can be found and used the same way everywhere. The term describes a design pattern, and no single product owns it.
What is a data fabric example?
A Kanerika client in thermal management had its order journey split across SAP Cloud for Customer, CPQ and S/4HANA. Kanerika built one governed pipeline on Microsoft Fabric with about 35 source tables, a Medallion architecture, 50+ standard KPIs and four-level row-level security. The time spent per reporting cycle fell by 60%.
Is data virtualization still relevant?
Yes. Data virtualization remains useful for fast access, data residency limits and interim integration after a merger. It also lives on inside modern platforms, such as OneLake shortcuts in Microsoft Fabric and query federation in Databricks. Its limits are unchanged, so heavy, repeated or historical workloads still belong in stored, modeled data.
What are the benefits of using data virtualization?
Data virtualization delivers a first combined view quickly, because it needs connections and a logical model instead of new pipelines. It avoids extra copies, keeps data in its home system and centralizes access rules at the query layer. It also reduces egress when filters are pushed down, since only reduced results travel.
What is the difference between data virtualization and data mesh?
Data virtualization is a technical method for querying data in place. Data mesh is an operating model that gives business domains ownership of their data as products. The two can work together, since a mesh domain might publish its product through a virtual layer. One answers how data is accessed, and the other answers who owns it.