TL;DR
A unified data platform is one system for all of a company’s data. It stores, prepares, analyzes and secures that data in one place. Reports, dashboards and AI models all use the same copy. This ends conflicting numbers and duplicate work across separate tools. Microsoft Fabric, Databricks, Snowflake, Google BigQuery and Amazon SageMaker Unified Studio are common examples. Pick one based on your cloud, your team’s skills and your main workloads, then move to it in phases.
Key Takeaways
- A unified data platform keeps one governed copy of data that every engine, report and AI agent uses.
- Most platforms share six layers, from ingestion and storage through processing, semantics, governance and AI.
- Microsoft Fabric, Databricks and Snowflake are the most common choices, with BigQuery and SageMaker Unified Studio leading on their own clouds.
- Choose by workloads, existing cloud and team skills, since every major platform now covers the core layers.
- Gartner expects 60% of AI projects without AI-ready data to be abandoned through 2026, which makes governed data an AI prerequisite.
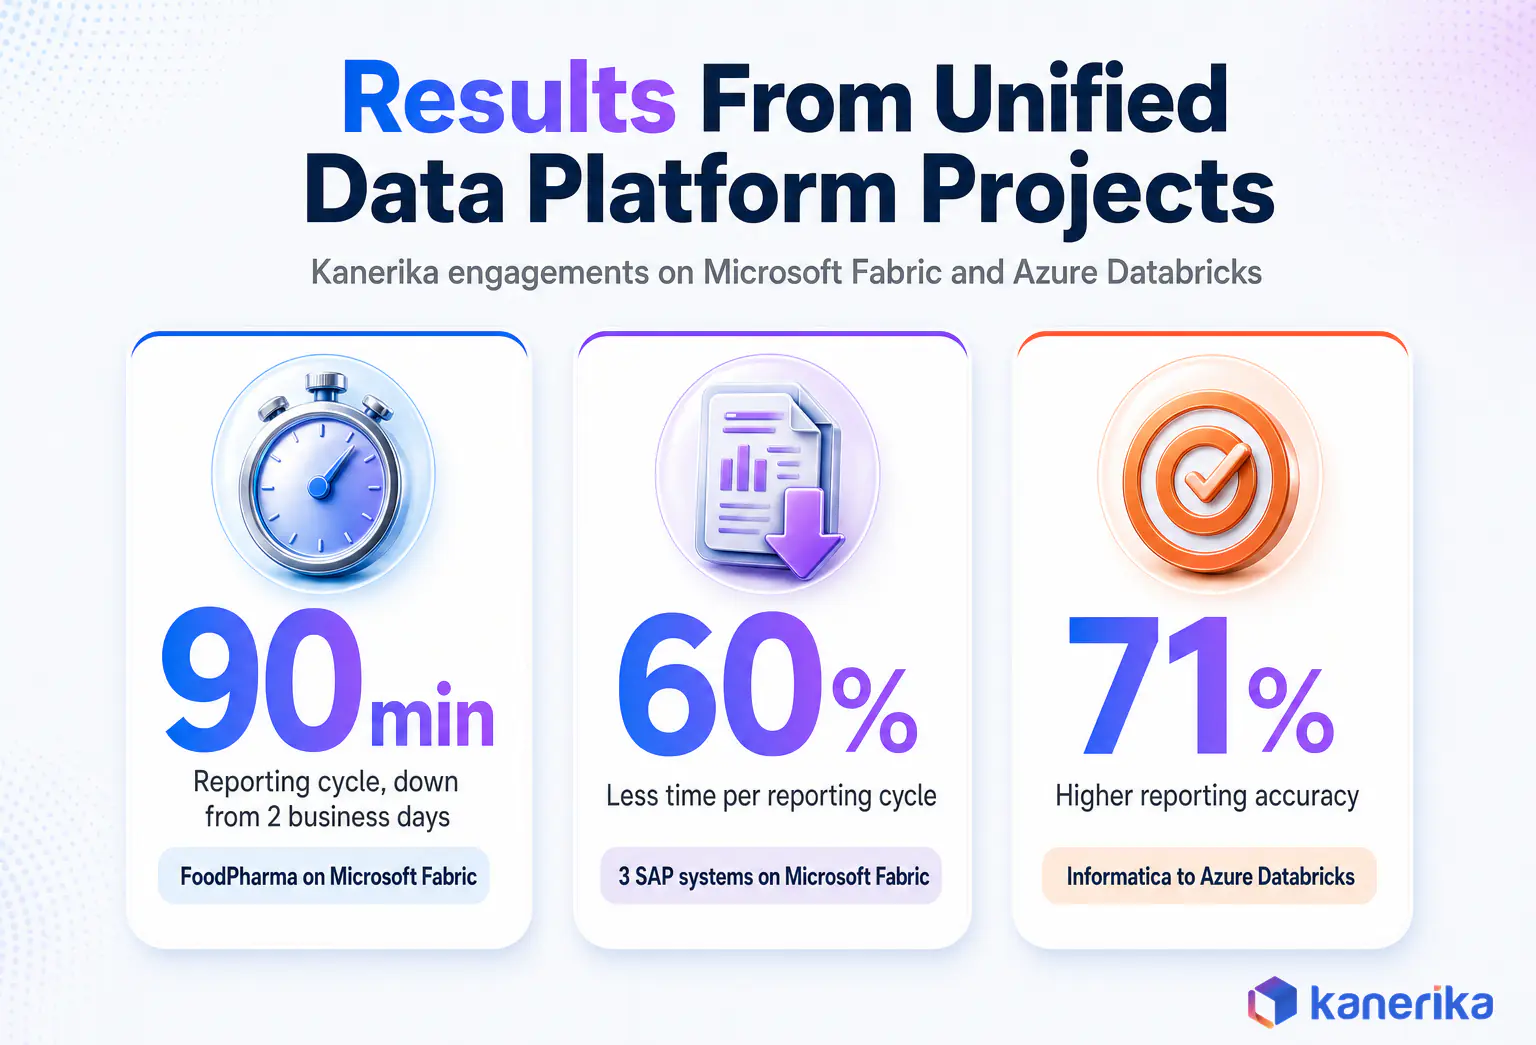
- FoodPharma cut a two-day reporting cycle to about 90 minutes after unifying six systems on Microsoft Fabric with Kanerika.
Two Business Days for One Report
At FoodPharma, a US maker of functional foods, one cross-functional report took two business days of manual extraction. Plant managers, finance and analysts each worked in a different system, and leadership often got answers after the decision was already made. After FoodPharma and Kanerika unified six systems on Microsoft Fabric, the same report takes about 90 minutes, according to Microsoft’s customer story.
The data existed the whole time. However, getting it into one trusted view was the bottleneck, and that is exactly the problem a unified data platform exists to solve.
The same foundation also decides whether AI projects succeed. Models and agents inherit every inconsistency in the data beneath them. As a result, a fragmented estate caps what AI can do before a single model is trained.
What Is a Unified Data Platform?
A unified data platform is a single, governed environment where an organization ingests, stores, transforms and serves its data for reporting and AI. Every engine on it, such as SQL, Spark, BI or ML, uses the same copy of data. One catalog and one set of security rules cover them all.
That shared foundation is exactly what separates a platform from a collection of connected tools.
In practice, a unified data platform replaces a chain of separate systems with one. For example, many enterprises run an ETL tool, a data lake, one or two warehouses, a BI server and a separate data science environment. Each one then keeps its own copy of the data, its own users and its own definition of revenue or on-time delivery.
What “Unified” Actually Covers
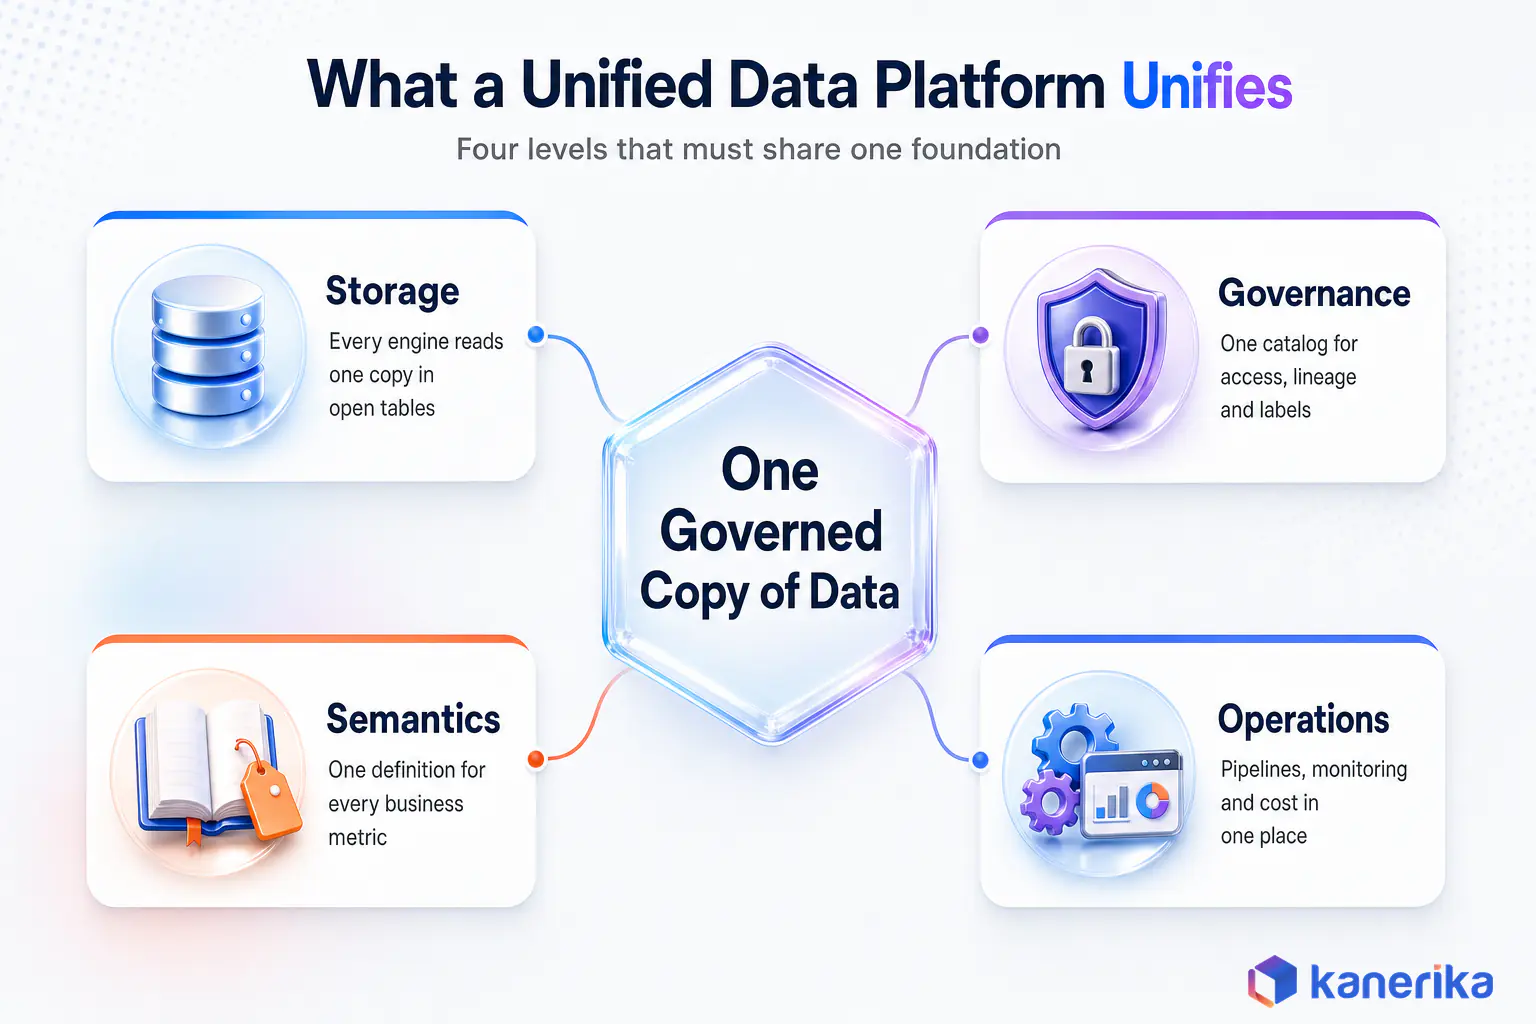
Put simply, unification happens at four levels, and a platform needs all four to deserve the name. Storage is unified when every workload reads one copy of the data, usually in an open table format. Governance is unified when one catalog controls permissions, lineage and classification for every engine.
Semantics are unified when a metric such as gross margin has one definition that every report and every AI agent uses. Operations are unified when pipelines, monitoring and cost management run from one place. A unified platform does not require one vendor for everything, and most enterprises still connect specialist tools at the edges.
Three Ways the Term Gets Used
Vendors, however, use “unified data platform” for three different products, which is why search results can feel contradictory. Analytics platforms such as Microsoft Fabric, Databricks and Snowflake unify enterprise data for reporting, engineering and AI. Customer data vendors, meanwhile, use the term for unifying customer profiles for marketing activation.
A third group, data fabric and virtualization tools, unifies access to data that stays in place across many systems. This guide focuses on the first meaning, the enterprise analytics and AI platform. The data fabric and customer data platform approaches are compared with it later in the article.
Why Enterprises Consolidate Onto a Unified Data Platform
Fragmentation carries a real price, and most of it hides inside manual work. For instance, every copy of a dataset needs its own pipeline, its own quality checks and its own access rules. When those copies drift apart, teams spend reporting cycles reconciling numbers instead of acting on them.
The Cost of a Fragmented Estate
To start with, poor data quality costs organizations at least $12.9 million a year on average, according to Gartner research from 2020. A fragmented estate makes quality problems harder to fix because the same error has to be found and corrected in several places. It also hides lineage, so nobody can say with confidence where a number on an executive dashboard came from.
Duplicate tooling also adds licence and infrastructure cost on top. Separate warehouses, ETL servers and BI platforms each still need patching, monitoring and specialist staff. Kanerika’s data consolidation guide covers the strategies for pulling these systems together in more depth.
Why AI Raises the Stakes
In fact, Gartner predicts that through 2026, organizations will abandon 60% of AI projects unsupported by AI-ready data, per its February 2025 announcement. AI-ready data means data that is governed, well described and consistent enough for a model to use without a human cleaning it first.
A unified platform is therefore the most direct route to that state. Models, retrieval pipelines and AI agents then all read the same governed tables the finance team reports from. When an agent answers a question about margin, it uses the same definition the CFO sees on the dashboard.
What Changes After Consolidation
The first change people notice is speed. For instance, reporting that required exports and spreadsheets becomes a scheduled refresh, and questions from leadership get answered in the meeting where they come up.
The second change is trust. One global thermal management manufacturer connected three SAP systems on Microsoft Fabric and standardized more than 50 governed KPIs. Its time per reporting cycle fell by 60%, because every team now reads the same numbers.
Unified Data Platform Architecture: The Six Layers
Most unified data platforms share the same six-layer architecture, whichever vendor builds them. Each layer describes a job the platform must do, while on a mature platform all six share storage, security and metadata. The diagram below then shows how data moves through all six.
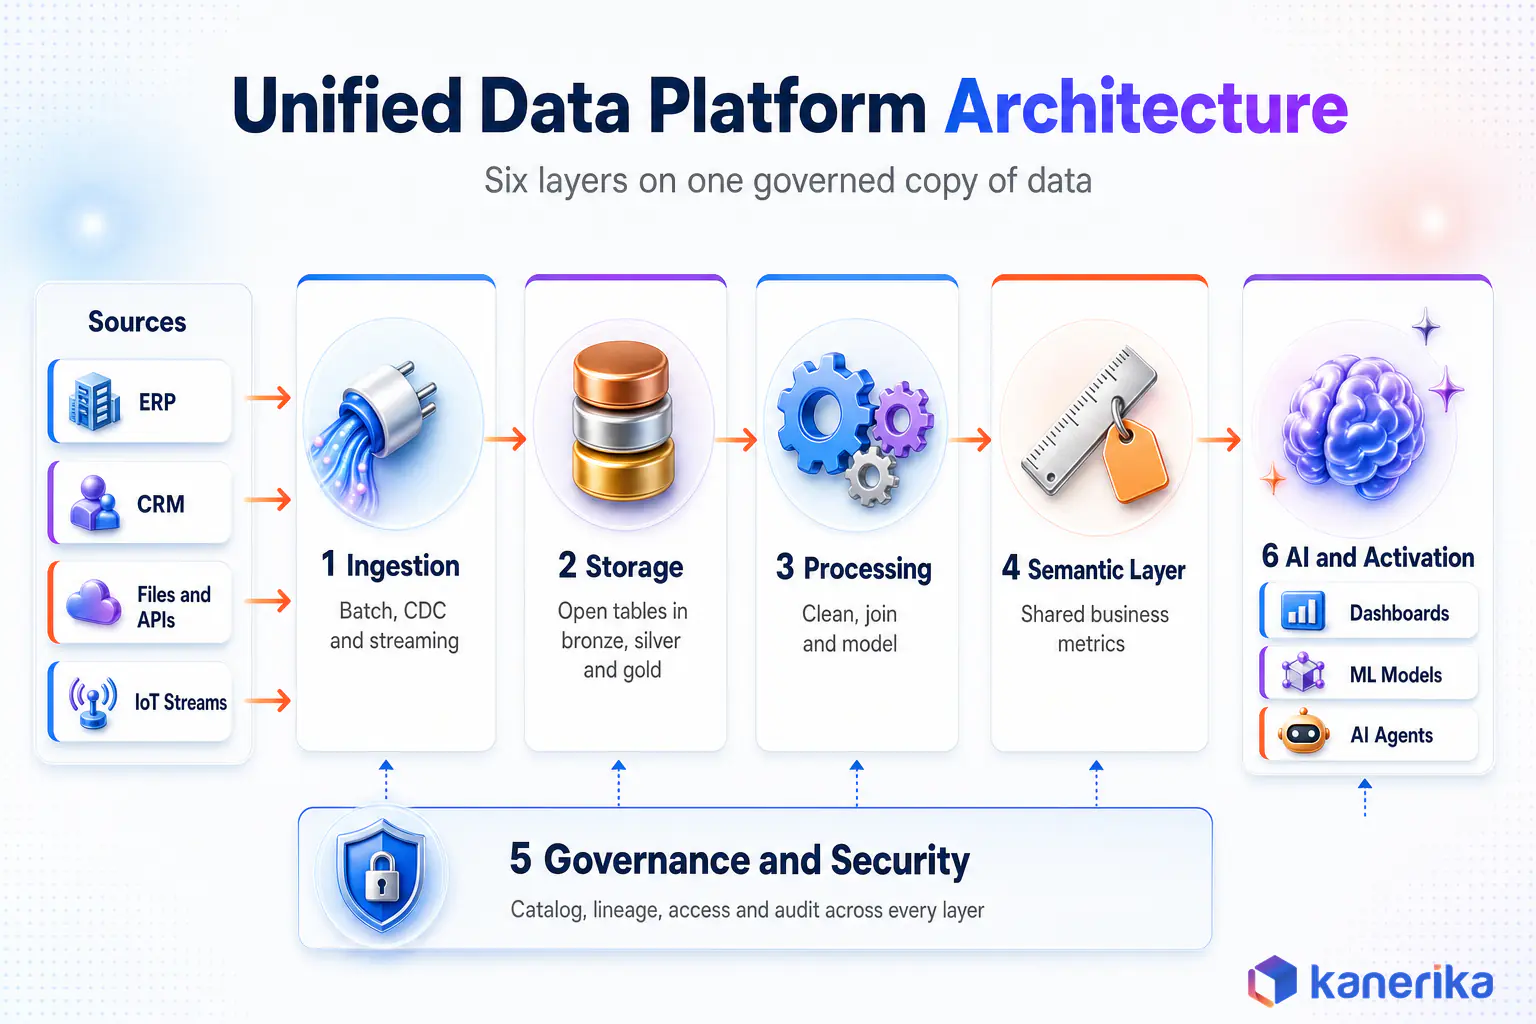
1. Ingestion
First, the ingestion layer brings data in from ERP and CRM applications, databases, files, APIs and event streams. It also supports batch loads, change data capture for databases, and streaming for real-time sources.
Newer platforms also offer zero-copy options, such as OneLake shortcuts in Microsoft Fabric, that reference external data without moving it. Our data ingestion guide explains each pattern in more detail.
2. Storage on Open Table Formats
Storage then holds one copy of the data in cloud object storage, organized as tables. Open table formats such as Delta Lake and Apache Iceberg add transactions, schema enforcement and time travel on top of plain files. Because the format is open, several engines can read the same table without copying it.
3. Processing and Transformation
Next, the processing layer cleans, joins and models raw data using Spark, SQL or low-code dataflows. Most platforms also follow a medallion architecture. First, raw data lands in a bronze layer, validated and conformed data sits in silver, and business-ready tables live in gold.
4. Semantic and Serving Layer
The semantic layer, in turn, converts tables into business terms, including measures, hierarchies and relationships that reports share. For example, Power BI semantic models, Snowflake’s semantic views and Databricks metric views all do this job. Serving also covers APIs and data products that other applications consume, and Direct Lake semantic models show how Fabric serves reports straight from lake tables.
5. Governance and Security
Governance, meanwhile, spans the catalog, lineage, classification, access policies and audit logs across every layer. On a unified platform, however, one set of permissions follows the data into every engine. Row-level and column-level security then decide what each user and each AI agent can see.
6. AI and Activation
The top layer is where data finally gets used. It covers dashboards and machine learning models, as well as retrieval-augmented generation, data agents and reverse ETL back into operational apps. Because this layer reads governed gold tables, its outputs inherit the platform’s quality and security.
The table below then maps each layer to the services that fill it on the three most common platforms.
Table 1: The six layers of a unified data platform and the services that fill them
| Layer | Job | Microsoft Fabric | Databricks | Snowflake |
|---|---|---|---|---|
| Ingestion | Bring data in by batch, CDC and streaming | Data Factory pipelines, Dataflow Gen2, mirroring, OneLake shortcuts | Lakeflow Connect, Auto Loader | Snowpipe, partner connectors |
| Storage | Keep one copy in open tables | OneLake (Delta Lake format) | Delta Lake on cloud object storage | Snowflake tables, Apache Iceberg tables |
| Processing | Clean, join and model data | Spark notebooks, Fabric Data Warehouse (T-SQL) | Apache Spark, Databricks SQL, Lakeflow jobs | SQL, Snowpark, dynamic tables |
| Semantic and serving | Define shared business metrics | Power BI semantic models with Direct Lake | Metric views, AI/BI dashboards | Semantic views |
| Governance | Catalog, lineage, access, audit | Microsoft Purview, OneLake security | Unity Catalog | Snowflake Horizon |
| AI and activation | Serve models, agents and apps | Fabric data agents, Copilot, Azure AI Foundry | Mosaic AI model serving and agent tools | Snowflake Cortex AI |
How Data Flows From Source Systems to AI
A worked example makes the layers concrete. So picture a manufacturer that wants one view of order-to-cash across its ERP, CRM and plant sensors. It also wants an AI assistant that can answer questions about late orders.
- First, pipelines copy ERP and CRM tables nightly and stream sensor readings every few seconds into the bronze layer.
- Then transformation jobs remove duplicates, align customer and product keys, and apply business rules to produce silver tables.
- Next, gold tables combine orders, shipments and machine downtime into a lead-time fact table with certified definitions.
- A semantic model exposes measures such as quote turnaround and on-time delivery, secured by region.
- Finally, dashboards read the semantic model, and an AI agent answers questions using the same measures and the same security rules.
Every step also leaves lineage in the catalog. So when a plant director questions a number, the data team can trace it from the dashboard back to the source record in minutes.
Case Study
60% Less Reporting Effort Across 3 SAP Systems on Fabric
Kanerika unified SAP Cloud for Customer, CPQ and S/4HANA on Microsoft Fabric, connecting 35+ source tables to 50+ governed KPIs with row-level security.
Read the Case Study →Unified Data Platform vs Data Warehouse, Data Lake, Lakehouse, Data Fabric, and CDP
These terms overlap, and vendors blur them on purpose. Therefore, the clearest way to separate them is by what each one unifies and who it serves.
A data warehouse, for instance, stores structured, modeled data for SQL reporting. A data lake, by contrast, stores raw files of any type cheaply but offers weak governance on its own.
Lakehouses, a newer design, instead add warehouse-style tables and transactions to lake storage. The data lakehouse is now the storage foundation of most modern unified platforms.
Table 2: Unified data platform vs data warehouse, data lake, lakehouse, data fabric and CDP
| Approach | What it unifies | Data types | Main users | AI support | Best fit |
|---|---|---|---|---|---|
| Data warehouse | Modeled data for reporting | Structured | BI analysts | Limited, usually exports data out | Stable SQL reporting on known sources |
| Data lake | Raw storage in one place | Any, as files | Data engineers, data scientists | Good for training data, weak governance | Cheap retention of large raw volumes |
| Data lakehouse | Storage plus warehouse-style tables | Structured and unstructured | Engineers, analysts, data scientists | Strong, same tables for BI and ML | The storage foundation of a modern platform |
| Data fabric | Access and metadata across systems | Any, left in place | Data stewards, integration teams | Depends on underlying systems | Data that cannot move for legal or technical reasons |
| Customer data platform | Customer identities and events | Customer and behavioral data | Marketing teams | Segmentation and personalization | Audience building and campaign activation |
| Unified data platform | Storage, processing, governance, semantics and AI | All enterprise data | Every data and business team | Native, on governed data | Enterprise-wide reporting and AI on one foundation |
Where Data Fabric and Data Mesh Fit
A data fabric is an architectural approach. It uses metadata and virtualization to connect data while it stays where it lives. It can sit on top of a unified platform or stand in for one when data cannot move.
Our data lake vs lakehouse comparison also goes deeper on the storage side. The data mesh article covers domain-owned operating models that often run on a unified platform.
Where a Customer Data Platform Fits
A customer data platform (CDP) resolves identities across web, app and CRM events into one profile per customer, then sends audiences to marketing tools. It is narrower by design, so it focuses on customer data and activation. Many enterprises therefore feed their CDP from the unified data platform, so finance, supply chain and marketing all count customers the same way.
Unified Data Platform Examples: 8 Platforms Compared
The platforms below are the ones enterprise buyers compare most often. Each unifies storage, processing and governance. However, they start from different places, and that starting point shapes where each one fits best.
1. Microsoft Fabric
Microsoft Fabric is a software-as-a-service analytics platform. It puts data integration, engineering, warehousing, real-time intelligence, data science and Power BI on one storage layer called OneLake.
As a result, OneLake keeps one copy of data for all Fabric engines, with Microsoft Purview providing governance. Microsoft reported more than 40,000 paid Fabric customers on its fiscal 2026 fourth quarter earnings call.
Fabric fits organizations already invested in Microsoft 365, Azure and Power BI, because identity, security and licensing carry over. Its capacity pricing also covers every workload from one pool of compute. Kanerika’s Microsoft Fabric practice also works on this platform daily.
2. Databricks Data + AI Platform
Databricks describes itself as a unified platform for data, analytics and AI, and it is built on the lakehouse and open Delta Lake tables. Unity Catalog then manages permissions, lineage and auditing for data and AI assets across workspaces. Databricks is especially strong where data engineering and machine learning are the center of gravity, and it runs on AWS, Azure and Google Cloud.
Our comparison of the Databricks Data Intelligence Platform and its competitors goes deeper on where it wins and where it does not.
3. Snowflake AI Data Cloud
Snowflake started as a cloud data warehouse but now positions itself as the AI Data Cloud. It is SQL-first, runs across the three major clouds and is known for secure data sharing between organizations. Snowflake Horizon supplies governance, while support for Apache Iceberg tables opens its storage to other engines.
4. Google BigQuery
BigQuery is Google Cloud’s serverless AI data platform. It separates storage and compute, so it runs SQL and machine learning in place, and connects to Vertex AI and Gemini models. It is the natural choice when most workloads already run on Google Cloud.
Our Microsoft Fabric vs Google BigQuery comparison covers the trade-offs in detail.
5. Amazon SageMaker Unified Studio
AWS brings its analytics and AI services together in Amazon SageMaker Unified Studio, which AWS calls a single data and AI development environment. In practice, it sits over S3 lakehouse storage, Redshift, Glue, EMR and Amazon Bedrock, with a shared catalog. AWS-centric enterprises therefore use it to unify services they already run without adopting a new vendor.
6. Palantir Foundry
Palantir Foundry takes an operational approach. Specifically, its ontology models real-world objects such as plants, orders and assets, so applications and AI act on business entities directly. Foundry especially suits organizations that want decision workflows built into the platform, and it usually carries a higher price and a heavier commitment.
7. Teradata VantageCloud and Cloudera
Teradata VantageCloud and Cloudera serve large regulated enterprises with hybrid or on-premises estates. Both also offer governed analytics across cloud and data center, which matters where data residency rules keep some workloads in house. Our Cloudera vs Databricks comparison explains when each fits.
8. Dremio and Starburst
Dremio and Starburst unify access through a federated query engine as well as an open lakehouse, often on Apache Iceberg. This way, analysts can query data across many systems without moving it first. They work well as a query layer in a multi-platform estate, though they rely on other tools for BI and data science.
Table 3: Unified data platform examples compared
| Platform | Architecture style | Strongest fit | Governance | Pricing model |
|---|---|---|---|---|
| Microsoft Fabric | SaaS, OneLake with Delta tables | Microsoft 365, Azure and Power BI organizations | Microsoft Purview | Shared capacity (F SKUs) |
| Databricks | Lakehouse on Delta Lake, multi-cloud | Data engineering and machine learning | Unity Catalog | Consumption (DBUs) |
| Snowflake | Managed SQL platform, Iceberg support, multi-cloud | SQL analytics and cross-company data sharing | Snowflake Horizon | Consumption (credits) |
| Google BigQuery | Serverless, storage and compute separated | Google Cloud workloads | Dataplex and IAM | On-demand or capacity editions |
| Amazon SageMaker Unified Studio | Unified studio over S3, Redshift and Glue | AWS-centric estates | SageMaker Catalog and Lake Formation | Per-service consumption |
| Palantir Foundry | Ontology-based operational platform | Operational decisions on business objects | Built-in, object level | Enterprise contract |
| Teradata VantageCloud and Cloudera | Hybrid cloud and on-premises | Regulated estates with residency needs | Built-in catalogs and policies | Subscription or consumption |
| Dremio and Starburst | Federated query on an open lakehouse | Querying data across many systems | Engine-level access controls | Consumption or subscription |
This comparison names no single winner, because the right platform depends on workloads, cloud and skills. The Databricks vs Snowflake vs Microsoft Fabric decision framework goes further on the three most common finalists.
Datasheet
Snowflake vs Databricks vs Microsoft Fabric Datasheet
A side-by-side view of architecture, workloads, governance and pricing across the three platforms enterprises shortlist most often.
View the Datasheet →Core Capabilities Every Unified Data Platform Should Have
Feature lists from vendors run long, so it helps to test for the capabilities that decide whether consolidation actually works. Together, these eight separate a real platform from a bundle of products sold under one name.
- Broad, governed ingestion. Native connectors for ERP, CRM and databases, change data capture, and streaming, all logged in the catalog.
- One copy of data in an open format. Delta Lake or Iceberg tables that every engine reads without duplication.
- Engines for every workload. SQL, Spark, real-time and machine learning compute on the same storage.
- A shared semantic layer. One definition of each business metric, used by reports and AI alike.
- A single catalog with lineage. Discovery, classification and end-to-end lineage across all assets.
- Fine-grained security. Row-level, column-level and attribute-based access that follows the data into every engine.
- Built-in quality and observability. Automated checks, freshness alerts and pipeline monitoring. See our data observability guide.
- Cost visibility. Workload-level usage reporting so teams can see which jobs and users drive spend.
Otherwise, a platform that misses several of these still leaves integration work for your team. That hidden work then usually shows up later as custom glue code and another round of copies.
How to Choose a Unified Data Platform
Platform selection goes wrong when it starts from features. Every major platform now covers the six layers. So a better starting point is your workloads, your existing cloud and the skills your team already has.
Signs You Have Outgrown Your Current Setup
Some symptoms show up in almost every estate that needs consolidation. In general, the more of these that sound familiar, the stronger the case for a unified platform.
- Two dashboards report different values for the same metric, and reconciling them is a recurring meeting.
- Analysts spend more time extracting and joining data than analyzing it.
- AI pilots stall because training data has to be exported and cleaned by hand.
- Nobody can quickly answer who has access to sensitive customer or employee data.
- Licence and infrastructure costs keep rising while the number of tools grows.
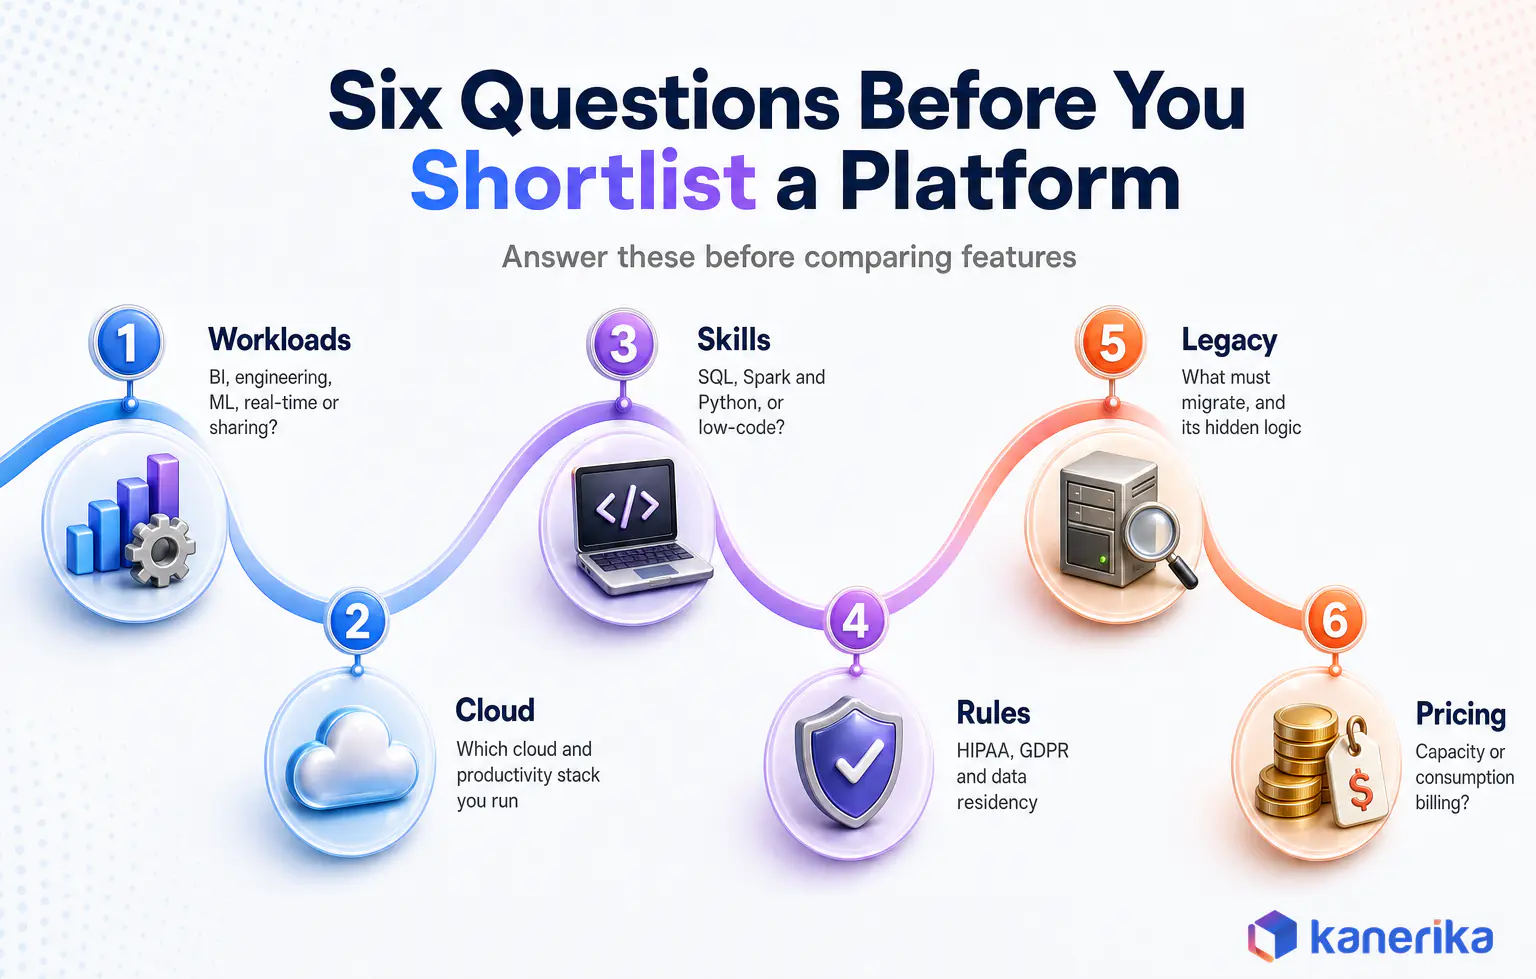
Six Questions to Answer Before a Shortlist
- Which workloads matter most, such as BI, data engineering, machine learning, real-time or data sharing?
- Which cloud and productivity stack does the business already run on?
- What skills does the team have today, SQL, Spark and Python, or low-code?
- What governance and residency rules apply, including HIPAA, GDPR or industry regulators?
- Which legacy systems must be migrated, and how much business logic is buried in them?
- Does the business prefer capacity-based or consumption-based pricing?
The table below then turns common starting points into a first recommendation. Treat it as a way to narrow the shortlist before a proof of concept, and let real workloads make the final call.
Table 4: Decision framework, which platform to evaluate first
| Your starting point | Evaluate first | Why |
|---|---|---|
| Microsoft 365, Azure and Power BI across the business | Microsoft Fabric | Identity, security, Office integration and Power BI carry over, and one capacity covers every workload |
| Engineering-heavy team running Spark and machine learning | Databricks | Deepest engineering and ML tooling on open Delta tables, on any major cloud |
| SQL-first analytics team that shares data with partners | Snowflake | Simple SQL operations and mature secure data sharing across clouds |
| Most workloads already on Google Cloud | Google BigQuery | Serverless scaling and native links to Vertex AI and Gemini |
| Most workloads already on AWS | Amazon SageMaker Unified Studio | Unifies S3, Redshift, Glue and Bedrock without a new vendor |
| Data that must stay in several systems or countries | Dremio, Starburst or a data fabric layer | Unifies access and governance without moving the data |
| Operational decision workflows across plants or assets | Palantir Foundry | Ontology models business objects that applications and AI act on |
When One Platform Is the Wrong Answer
A single platform is the right default, but forcing every workload onto it can backfire.
Take a company running heavy Databricks machine learning alongside Power BI reporting. It may then do better with Databricks for engineering and Fabric for BI, linked through shared Delta tables. Still, the goal is one catalog, one security model and one set of metric definitions, even with two engines underneath.
In contrast, smaller organizations with a handful of sources may not need a full platform at all. A managed warehouse plus a BI tool can be simpler and cheaper until data volumes, users or AI ambitions grow.
Kanerika Service
Data Architecture Services
Kanerika designs target architectures for unified data platforms on Microsoft Fabric, Databricks and Snowflake, including medallion layout, semantic models and security.
Explore Data ArchitectureUnified Data Platform Cost and TCO
Total cost of ownership depends as much on the pricing model and workload pattern as on list prices. As a result, comparing platforms on a single price per unit rarely predicts the real bill.
Capacity vs Consumption Pricing
Microsoft Fabric sells capacity, whereas Databricks, Snowflake and BigQuery mostly sell consumption. Per the Fabric pricing page, one pool of capacity units powers every workload, in sizes from F2 upward. Capacity then runs pay-as-you-go or on one or three year reservations that save about 41%.
By contrast, Databricks bills in Databricks Units by compute type, Snowflake bills in credits, and BigQuery offers on-demand pricing per data scanned or capacity-based editions.
Table 5: TCO factors to evaluate before choosing a unified data platform
| Cost driver | What it covers | How to control it |
|---|---|---|
| Compute | Queries, pipelines, notebooks and model training | Right-size capacity, auto-pause idle compute, schedule heavy jobs |
| Storage | Tables, history and snapshots | Retention rules on time travel and bronze data |
| Data movement | Egress between clouds and regions | Keep engines near the data, use shortcuts or shared tables |
| Licensing | Platform, BI and per-user licences | Retire duplicate tools as each migration wave lands |
| Migration | Converting pipelines, reports and business logic | Automated conversion accelerators and wave planning |
| People and operations | Training, support and platform administration | One operating model and shared templates across teams |
Hidden Costs to Budget For
Migration effort is usually the largest one-time cost, especially where years of business logic sit inside old ETL jobs and reports. Training, parallel running of old and new systems, and data egress between clouds also add more. On the savings side, however, retiring duplicate tools, servers and pipelines often offsets a large share of the new platform’s cost.
Cost governance therefore matters from day one. For example, workload tagging, auto-pause, right-sized capacity and alerts on runaway queries keep spend predictable. Our guides to Microsoft Fabric pricing and Databricks cost optimization cover the platform-specific levers.
Governance and Security in a Unified Data Platform
Consolidation concentrates risk as well as data, so governance has to arrive with the platform instead of after it. The upside is real, since one catalog and one policy engine are far easier to audit than a dozen separate systems.
Checklist
Data Governance Checklist
Check catalog, classification, access control and lineage readiness before you consolidate data onto one platform.
Get the Checklist →Fortunately, each major platform has a native governance layer. For instance, Microsoft Fabric uses Microsoft Purview for cataloging, sensitivity labels and data loss prevention, Databricks uses Unity Catalog, and Snowflake uses Horizon. Kanerika was one of the earliest Microsoft Purview implementors, and our Purview data catalog guide shows how cataloging works in practice.
In particular, four controls deserve attention in every design.
- Classification. Label personal, financial and health data at ingestion so policies apply automatically.
- Least-privilege access. Use groups, row-level security and masking instead of per-user grants.
- Lineage. Capture data lineage from source to report so audits and impact analysis take minutes.
- AI access rules. Make agents and copilots query data as the signed-in user, so they never see more than that user could.
Finally, a data governance framework ties these controls to owners and processes. Otherwise, without named owners, even a well-configured catalog decays within a year.
Building an AI-Ready Unified Data Platform
AI-ready means more than having data in one place. Models and agents also need context, so they understand what a table means, which figures are certified and what a user is allowed to see.
The semantic layer, therefore, carries most of that context. For example, business definitions, relationships and synonyms let a data agent turn a plain-language question into the right query.
Microsoft Fabric’s data agents and Fabric IQ build on semantic models and ontologies for this reason. Snowflake and Databricks also offer their own agent tooling on governed data.
Unstructured data also belongs on the platform.
Contracts, manuals and support tickets, for instance, feed retrieval-augmented generation. Keeping them under the same catalog means AI answers respect the same permissions as reports. Our enterprise AI platform guide covers the layer that sits above the data platform.
Finally, three checks tell you whether a platform is ready for AI.
First, gold tables have owners and documented definitions. Second, sensitive columns carry labels that agents honor. Third, lineage shows where every training and retrieval dataset came from.
Migrating to a Unified Data Platform: A Phased Roadmap
Most consolidation projects that stall run into scope problems first. A phased roadmap that moves workloads in waves keeps the business running and proves value early.
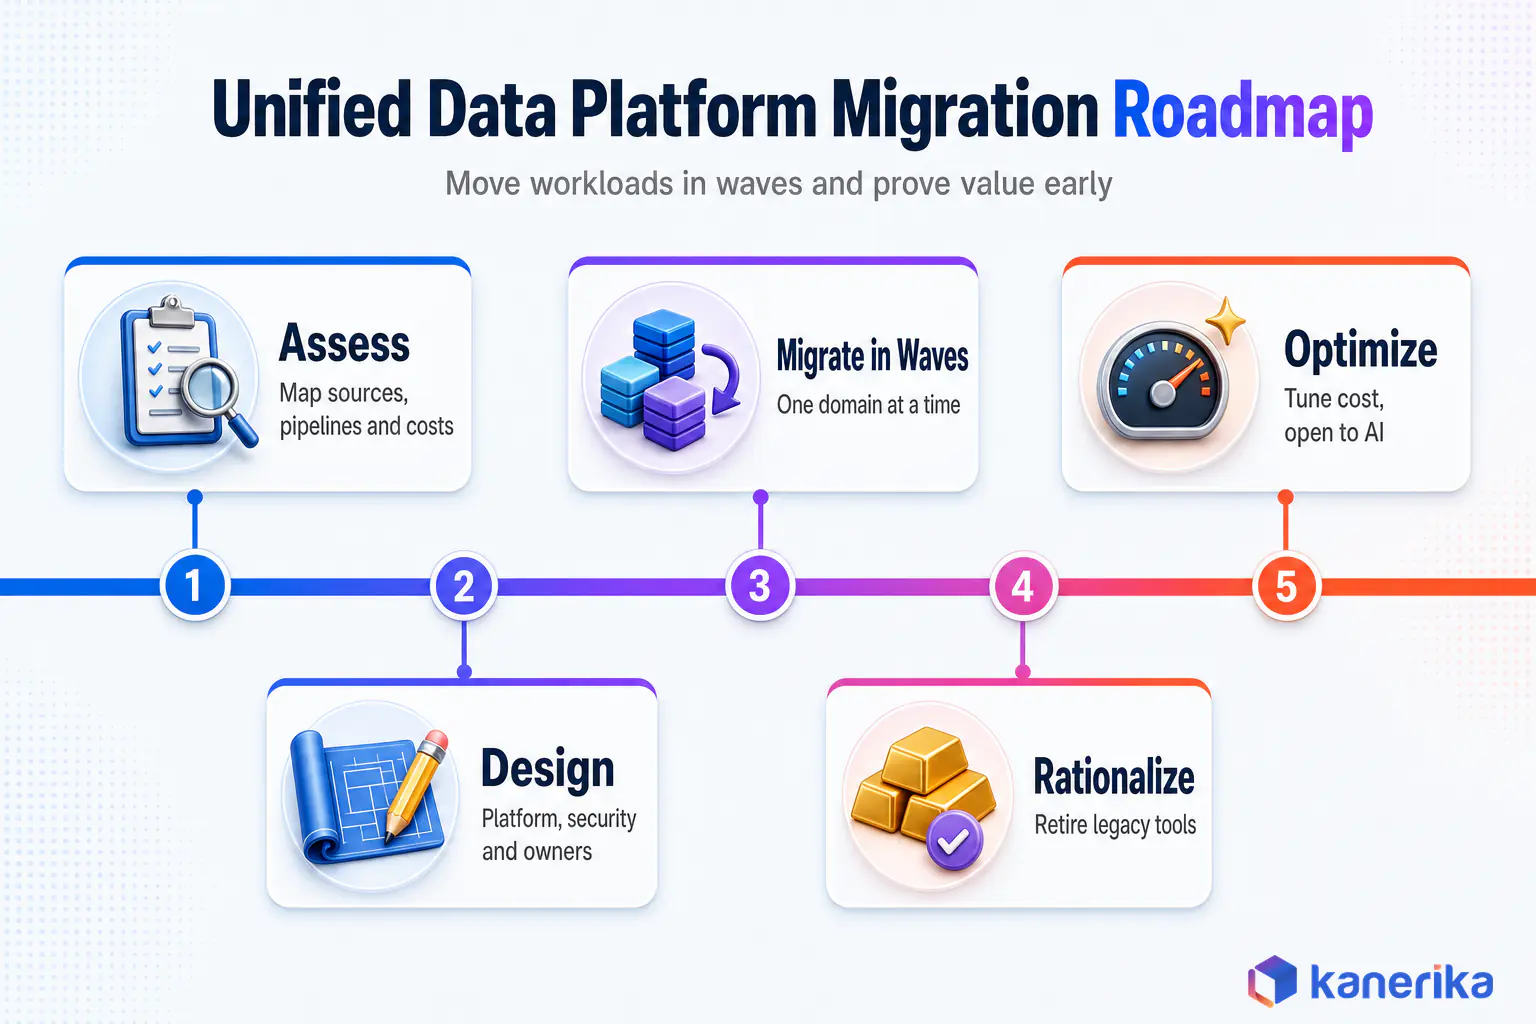
- Assess the current estate. Inventory sources, pipelines, reports, users and costs, then find the business logic hidden inside old ETL and BI tools.
- Design the target. Choose the platform, the medallion layout, the security model and the operating model, then agree on metric owners.
- Migrate in waves. Move one domain or workload at a time, run old and new in parallel, and validate numbers against existing reports before cutover.
- Rationalize and retire. Build shared gold tables and semantic models, then switch off the legacy systems each wave replaces.
- Optimize and enable. Tune cost and performance, train users and finally open the platform to AI and self-service use cases.
Automated conversion shortens the migrate phase the most. For example, conversion tools translate existing pipelines, stored procedures and reports into the target platform’s format. Manual rebuilding of each job, however, is slower and tends to lose business rules along the way.
For the full migration playbook, including validation and cutover planning, see our data platform migration guide and the migration decision framework.
Common Unified Data Platform Mistakes
The same failure patterns show up across industries and platforms. Still, each one is avoidable when it is planned for from the start.
- Lifting and shifting old ETL. Copying legacy pipelines unchanged also carries old workarounds and duplicate logic into the new platform.
- Leaving governance for later. Retrofitting access rules and lineage after go-live costs more and exposes data in the meantime.
- Recreating copy sprawl. Teams that build private copies inside the new platform rebuild the silos they set out to remove.
- Attempting a big-bang cutover. Moving everything at once makes validation impossible and puts every report at risk on the same day.
- Skipping the semantic layer. Without shared metric definitions, reports disagree again within months.
- Choosing by feature list. A platform that does not fit the team’s skills or cloud leads to slow adoption, because people keep working in the old tools.
Most of these mistakes trace back to treating consolidation as an infrastructure project. Teams that name data owners, agree on metric definitions and plan migration waves before the build tend to avoid all six. Each of those steps costs days during planning and saves months after go-live.
The first and fifth mistakes tend to cost the most. Both look like time savers during the project, yet both turn into rework after go-live.
Where Unified Data Platforms Pay Off: Industry Use Cases
The value of a unified platform shows up differently by industry, but the pattern is consistent. Data that used to live in separate operational systems then becomes one governed view that reporting and AI can both use.
Table 6: Industry use cases for a unified data platform
| Industry | Data brought together | What it enables |
|---|---|---|
| Retail | Point of sale, e-commerce, inventory and loyalty data | Demand forecasting, stock planning and personalized offers |
| Banking and financial services | Core banking, cards, CRM and risk data | Fraud detection, regulatory reporting and a single customer view |
| Healthcare | Clinical records, claims and billing | Accurate reporting, claims analytics and compliance audits |
| Manufacturing | ERP, MES, quality and IoT sensor data | Predictive maintenance, quality analytics and order lead-time tracking |
| Logistics | Transport, warehouse and telematics data | Route optimization, delivery estimates and capacity planning |
Industry-specific designs also follow the same six layers with different sources and rules. Our guides to the lakehouse for manufacturing and the lakehouse for financial services show two of these in detail.
How Kanerika Builds Unified Data Platforms
Kanerika designs, migrates and operates unified data platforms on Microsoft Fabric, Databricks and Snowflake. It is also a Microsoft Solutions Partner for Data and AI, a Databricks consulting partner and a Snowflake Select Tier partner. Because we deliver on all three, the platform recommendation follows the client’s workloads and existing investments.
Our Delivery Approach
- Assess. A current-state review of sources, pipelines, reports, costs and governance gaps, with a prioritized list of workloads to move first.
- Design. A target architecture with the medallion layout, semantic models, security model and cost controls agreed before any build starts.
- Migrate. Wave-based migration using FLIP accelerators to convert pipelines and reports from SSIS, Informatica, Azure Data Factory and Tableau, with automated validation against the old outputs.
- Govern. Catalog, classification, lineage and row-level security set up in Microsoft Purview or Unity Catalog as part of the build.
- Enable. Power BI reporting, data agents and AI use cases on the governed gold layer, plus training for the teams who will run it.
In addition, per Kanerika’s FabCon 2026 announcement, organizations using the FLIP-powered Azure to Fabric Migration Accelerator reported 80% faster migration timelines. They also reported 50% lower migration costs and 65% fewer resources.
Results From Real Engagements
FoodPharma on Microsoft Fabric. First, Kanerika consolidated more than 50 tables and about 1 TB of history from six systems into Fabric, with automated daily loads. Sources included NetSuite, RedZone and Paychex, as well as three other systems.
As a result, cross-functional reporting dropped from two business days to about 90 minutes. The BI team recovered roughly 15 hours a week, and the implementation took seven weeks, according to Microsoft’s customer story.
Three SAP systems, one Fabric platform. Second, for a global thermal management manufacturer, Kanerika connected SAP Cloud for Customer, CPQ and S/4HANA through one governed medallion pipeline.
Today, about 35 source tables feed 50+ governed KPIs with four-level row-level security. Time spent per reporting cycle fell by 60%, as documented in the three SAP systems on Fabric case study.
Informatica to Azure Databricks in healthcare. Third, a healthcare provider moved clinical, claims and billing pipelines from Informatica to Azure Databricks with Kanerika’s accelerator, with one rule framework for coding standards. As a result, the provider saw 71% higher reporting accuracy, 38% lower data handling costs and 64% faster decision-making.
What Our Teams Watch For
Undocumented business logic is the risk our architects check first. Old stored procedures and report formulas often hold rules nobody remembers, so we extract and document them before conversion starts.
Metric ownership comes next. We name an owner for each certified KPI during design, because a semantic model without owners drifts back into competing definitions.
Finally, Kanerika holds ISO 27001, ISO 27701 and ISO 9001 certifications, is SOC 2 Type II compliant and is CMMI Level 3 appraised. Security reviews therefore run alongside the build.
Talk to Kanerika
Plan Your Unified Data Platform
Talk to Kanerika’s data architects about your sources, workloads and target platform, and get a phased consolidation plan.
Book a Meeting →Wrapping Up
A unified data platform gives an organization one governed copy of its data and one set of metric definitions. The same security model then covers every report, model and agent.
Meanwhile, the six-layer architecture is now common across Microsoft Fabric, Databricks, Snowflake, BigQuery and AWS. So the choice comes down to workloads, existing cloud and team skills.
Start with an honest assessment, migrate in waves, and put governance and the semantic layer in place from the first wave. That order, above all, is what turns consolidation into faster reporting and AI that people trust.
Frequently Asked Questions
What is a unified data platform?
A unified data platform is one governed environment that handles data ingestion, storage, transformation, analytics and AI on a shared copy of data. Every engine reads from the same storage and follows the same catalog, security and metric definitions. Teams stop reconciling numbers between separate tools. Microsoft Fabric, Databricks and Snowflake are common examples.
What is an example of a unified data platform?
Microsoft Fabric is a clear example, since data engineering, warehousing, real-time analytics and Power BI all run on one storage layer called OneLake. Databricks does the same on a lakehouse governed by Unity Catalog. Snowflake, Google BigQuery, Amazon SageMaker Unified Studio and Palantir Foundry are other platforms enterprises use in this role.
Why do companies need a unified data platform?
Companies adopt one when separate warehouses, lakes and BI tools produce conflicting numbers and slow reporting. A shared platform gives every team one definition of each metric and one access model. It also removes duplicate pipelines and copies. AI projects benefit most, because models and agents need consistent, governed data to give reliable answers.
How does a unified data platform improve data quality?
It applies validation, cleansing and business rules once, at a central point, instead of repeating them in every tool. Layered designs such as bronze, silver and gold tables catch bad records before they reach reports. Lineage shows where each number came from. Quality checks run automatically on every load, so issues surface before users see them.
Is a unified data platform secure?
A unified platform can be more secure than a scattered estate, since there are fewer copies and fewer access points to protect. Security depends on configuration, though. Look for role-based and row-level access, encryption, audit logs and sensitivity labels. Catalogs such as Microsoft Purview, Unity Catalog and Snowflake Horizon apply these policies across every engine.
What are common challenges when adopting a unified data platform?
The hardest parts are usually undocumented business logic in old ETL jobs, inconsistent metric definitions across teams, and the skills gap on a new platform. Cost forecasting is also tricky before real workloads run. Migrating in waves, validating results against the old reports, and setting up governance before go-live reduce most of this risk.
Is Databricks a unified data platform?
Yes. Databricks runs data engineering, SQL analytics, machine learning and AI on a single lakehouse, with storage in open Delta Lake tables. Unity Catalog governs permissions, lineage and auditing across data and AI assets. It suits engineering-heavy teams and advanced machine learning, and it often sits alongside Power BI or other tools for reporting.
What are the layers of a unified data platform?
A typical unified data platform has six layers. Ingestion collects data from applications, databases, files and streams. Storage holds one copy in open table formats. Processing cleans and models the data for use. The semantic layer defines shared business metrics. Governance manages access and lineage, and the AI layer serves reports, models and agents.
What is the most popular data platform?
Microsoft Fabric, Databricks and Snowflake appear on most enterprise shortlists. Adoption figures are rarely published in the same way, so direct rankings are hard. Microsoft did report more than 40,000 paid Fabric customers in its fiscal 2026 fourth quarter. For most buyers, the better question is which platform fits their cloud, skills and workloads.
Who is the biggest competitor of Databricks?
Snowflake is usually named as the biggest competitor of Databricks, since both sell cloud platforms for analytics and AI. Microsoft Fabric has become the third major option, especially for companies already using Azure and Power BI. Google BigQuery and Amazon SageMaker compete inside their own clouds. The right choice depends on workloads and existing skills.
What is the difference between a unified data platform and a customer data platform?
A customer data platform, or CDP, unifies customer records for marketing, building profiles and sending audiences to ad and email tools. A unified data platform covers all enterprise data, including finance, operations, supply chain and HR. It supports reporting, engineering and AI. Many companies run a CDP on top of their unified data platform.
Is Microsoft Fabric a unified data platform?
Yes. Microsoft Fabric is a software-as-a-service analytics platform. It puts data integration, engineering, warehousing, real-time analytics, data science and Power BI on one storage layer called OneLake. Every workload uses the same copy of data. Governance comes through Microsoft Purview. Pricing is capacity based, so one capacity is shared across all workloads.
Should an enterprise choose one data platform or use several?
Most enterprises should standardize on one primary platform for shared data, metrics and governance. A second platform can still make sense for a specific workload, such as heavy machine learning or partner data sharing. The goal is one catalog, one security model and one set of metric definitions, even when two engines run underneath.
How long does it take to migrate to a unified data platform?
A focused first phase often takes six to twelve weeks. FoodPharma moved six systems onto Microsoft Fabric with Kanerika in about seven weeks, per Microsoft’s customer story. Large estates with hundreds of pipelines take several months and move in waves. Automated conversion of existing ETL and reports shortens the timeline considerably.
Can a unified data platform support machine learning and business reporting together?
Yes, and that is one of the main reasons to build one. Data engineers, analysts and data scientists work from the same governed tables. Reports read curated gold tables through a semantic model. Machine learning and AI workloads use the same data with full lineage. Nobody exports copies to a separate tool to train a model.
How does a unified data platform help with AI agents?
AI agents need accurate data plus business context to answer questions reliably. A unified platform gives them one governed source, shared metric definitions and access rules that follow the user. Features such as Fabric data agents and Databricks AI tools query this data directly. Fewer copies mean fewer conflicting answers and less exposure risk.
How much does a unified data platform cost?
Cost depends on the pricing model and the workload. Microsoft Fabric charges for a reserved or pay-as-you-go capacity shared by all workloads. Databricks, Snowflake and BigQuery mostly charge for compute used, plus storage. Migration effort, training and idle capacity add to the total. Retiring duplicate tools and pipelines often offsets much of it.