TL;DR
Data fabric vs data warehouse comes down to your bottleneck: choose the warehouse for trusted reports, and a fabric when scattered sources slow every answer. A data warehouse copies curated data into one governed store built for BI and history. A data fabric is an architecture that connects, catalogs and governs data where it already lives.
The two work together, since a fabric usually wraps the warehouse instead of replacing it. Keep the warehouse for finance, audit and heavy repeated reporting, and use fabric capabilities for fresh, cross-system and AI data access. For most stacks the answer is both: a warehouse core with a fabric layer added once source sprawl becomes the bottleneck.
Key Takeaways
- A data warehouse copies curated data into one governed store, so it fits your stack when trusted reports, history and fast repeated queries matter most.
- A data fabric connects, catalogs and governs data where it already lives, so it fits when scattered sources and slow access are the real bottleneck.
- Cloud warehouses such as Snowflake, BigQuery and Microsoft Fabric can already query external storage, which blurs the old line between the two.
- Copy data into the warehouse for heavy repeated joins, history and audit, and query it in place for fresh, low-volume, cross-system questions.
- Fabric capabilities help AI agents find and safely reach data, while models still train on curated warehouse or lakehouse data.
- For most enterprises the right stack is both: keep the warehouse at the core and add a fabric layer, starting with a catalog.
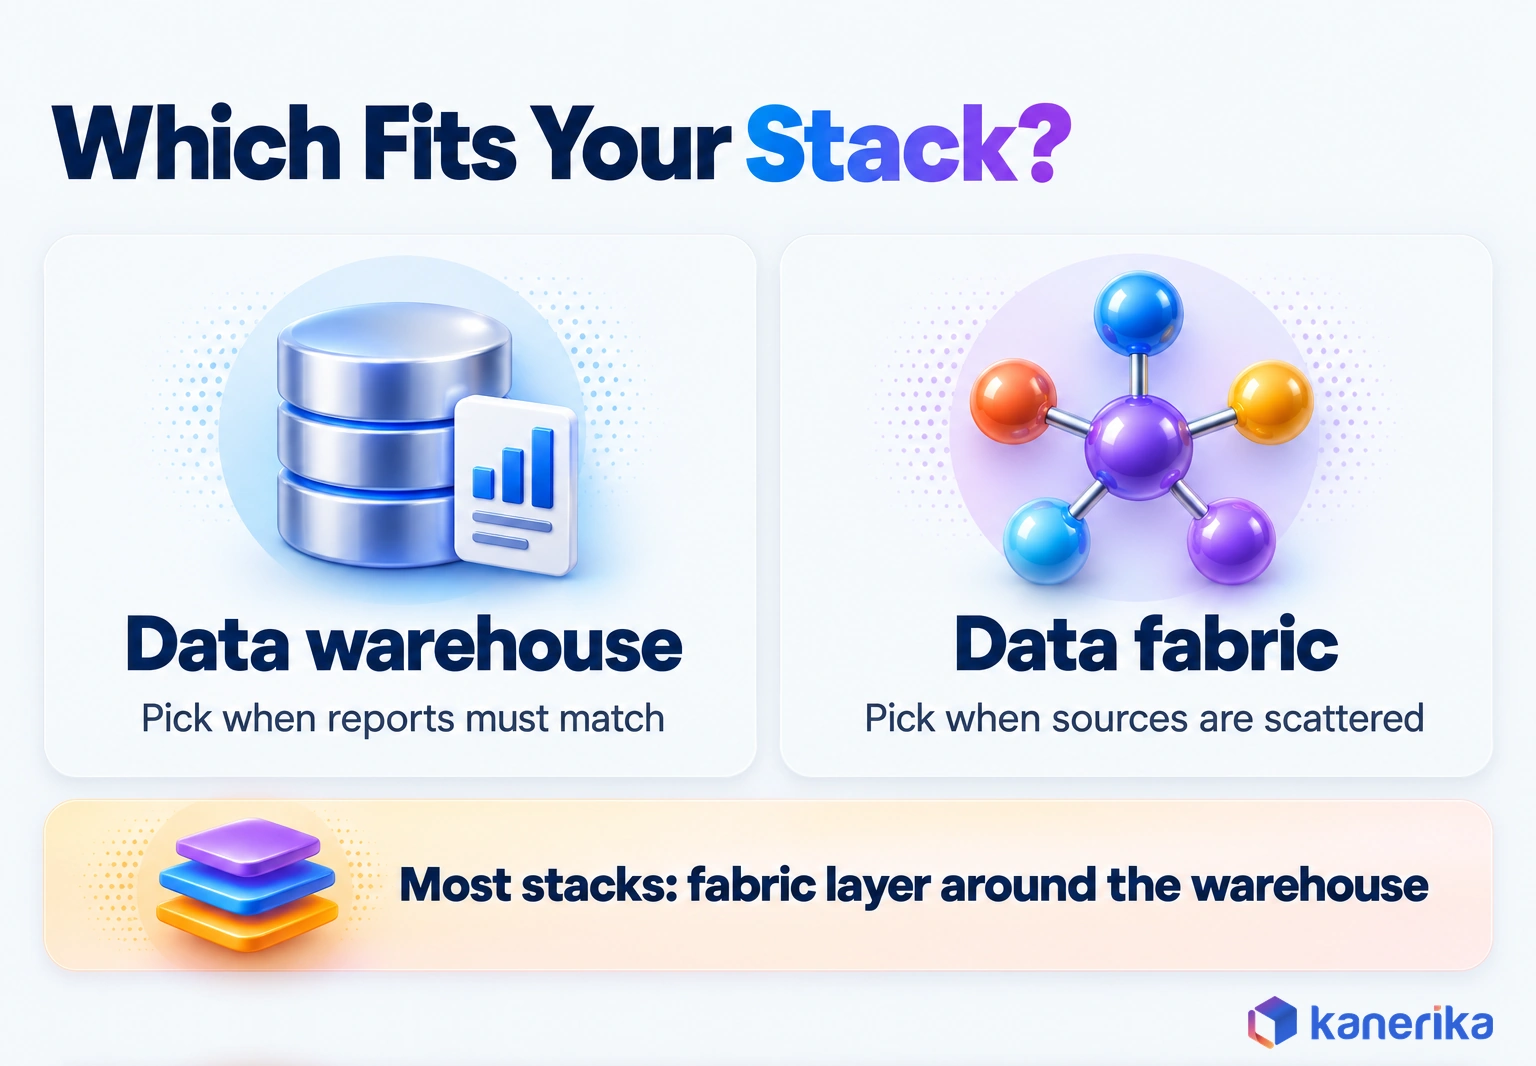
Where the Data Fabric vs Data Warehouse Question Starts
Picture a finance team that closes the month without drama. The revenue pack refreshes from the data warehouse every morning, the numbers match the ledger, and so nobody argues about definitions.
Then the COO asks a simple supply question: which customers will feel the shortage of one component next quarter? The answer needs open orders from SAP, account owners from Salesforce and supplier files that land in Amazon S3. None of that sits in the warehouse, so a week later the team is still mapping fields and chasing access requests.
That gap is where the data fabric vs data warehouse debate usually starts. The warehouse did its job, since it was built for curated reporting. The supply question stalled because its data sat in three systems, so finding and governing it took longer than answering it.
What Is a Data Warehouse?
Put simply, a data warehouse is a central database that holds a cleaned, integrated copy of business data for reporting and analysis. It is organized by subject, such as sales, finance or inventory. It also keeps history, so you can compare any quarter with the ones before it.
The key word is copy. Data leaves the source systems, gets checked and reshaped, and then lands in tables that analysts and BI tools trust. Because the structure is fixed before data arrives, reports run fast and two dashboards show the same revenue figure. For the layer-by-layer design, our guide to data warehouse architecture layers goes deeper.
How a Warehouse Works: ETL, Schema-on-Write and Star Schemas
A warehouse runs on a simple promise: do the hard work once, at load time, so every query after that is cheap. This is called schema-on-write, the opposite of the schema-on-read approach in our data lake vs data warehouse comparison. Engineers decide the tables, keys and data types first, and every load must fit them.
The load path usually follows four steps, and our comparison of data integration vs ETL covers the trade-offs:
- Extract: pull records from ERP, CRM, finance and other source systems on a schedule.
- Transform: clean, deduplicate and standardize the data, for example by mapping three customer ID formats to one key.
- Load: write the result into fact and dimension tables inside the warehouse.
- Serve: expose modeled data marts to BI tools, finance reports and analysts.
Most warehouses model those marts as star and snowflake schemas. Each one has a central fact table of transactions, surrounded by dimensions such as customer, product and date, so the result is predictable. A finance analyst can slice revenue by region and month in seconds, and an auditor can trace the same figure back to a governed load.
The cost is rigidity, though. Every new source or column means changing the data pipelines and the model first, so the warehouse team carries a backlog of waiting sources.
Kanerika Service
Data Architecture Services
Get a data platform design that matches how your teams use data, whether that is a governed warehouse, a fabric layer or both working together.
Explore Data Architecture
Modern Cloud Warehouses Already Reach Outside Their Walls
The textbook warehouse keeps everything inside its own storage. Cloud warehouses have moved past that, and the change matters here, because several of them can read data they do not own.
Microsoft’s Fabric Data Warehouse is built mainly around T-SQL and supports full multi-table ACID transactions. Its data, however, sits in Delta tables, which are Parquet files with a transaction log. Snowflake’s Iceberg tables, similarly, use an external volume, an account-level object that connects Snowflake to your own cloud storage. Google’s BigLake tables also let BigQuery query structured data in Cloud Storage, Amazon S3 and Azure Blob Storage with access delegation.
| Platform | How it reaches outside | What it means for the choice |
|---|
| Microsoft Fabric Data Warehouse | Stores its tables as Delta Parquet files in OneLake | Other Fabric workloads share the same storage layer |
| Snowflake | Iceberg tables on an external volume in your cloud storage | Table data can stay in your own bucket |
| Google BigQuery | BigLake tables over Cloud Storage, Amazon S3 and Azure Blob Storage | One SQL engine queries files across three clouds |
In Snowflake, the Iceberg setup takes two statements, adapted from the CREATE EXTERNAL VOLUME and CREATE ICEBERG TABLE examples in Snowflake’s documentation. The first registers your own S3 bucket through an IAM role. The second creates a table whose files are written to that bucket instead of Snowflake-managed storage.
CREATE OR REPLACE EXTERNAL VOLUME exvol
  STORAGE_LOCATIONS =
    (
      (
        NAME = 'my-s3-us-west-2'
        STORAGE_PROVIDER = 'S3'
        STORAGE_BASE_URL = 's3://my-example-bucket/'
        STORAGE_AWS_ROLE_ARN = 'arn:aws:iam::123456789012:role/myrole'
      )
    )
  ALLOW_WRITES = TRUE;

CREATE ICEBERG TABLE my_iceberg_table (amount int)
  CATALOG = 'SNOWFLAKE'
  EXTERNAL_VOLUME = 'exvol'
  BASE_LOCATION = 'my_iceberg_table';
So the line between a warehouse and a fabric is blurring. A warehouse that reads external files still behaves like a warehouse, though. It still wants modeled tables, runs one engine and governs only what it can see. If you want to see how one of these platforms splits storage from compute, Snowflake’s architecture is a good example. A fabric, instead, starts from the other end, with every source in the estate.
On-Demand Webinar
Snowflake + Fabric: Expert Strategies for Interoperability, Data Sharing & Migration
See how Snowflake and Microsoft Fabric work together through native interoperability and shared data, and how to choose the right move for your data platform.
Watch the Webinar →
What Is a Data Fabric?
A data fabric is an architecture, a way of designing how data is found, connected and governed across many systems, not a product you install. IBM’s definition calls it “a modern data architecture designed to democratize data access across an organization.” IBM also says a fabric “uses intelligent and automated systems to break down silos.”
The practical difference from a warehouse is where the data sits. A fabric leaves most data in its source systems and then adds a layer above them.
That layer knows what data exists, what it means, who may see it and how to reach it. When someone asks a question, the fabric either queries the sources in place or moves only the data that question needs. That self-service reach is the same goal that data democratization tools pursue.
Go back to the supply question. With a fabric, the analyst first searches one catalog for open orders and sees that the table lives in SAP. Then she confirms that her role may read it and joins it with Salesforce accounts, without waiting for a new pipeline. The warehouse still holds the finance pack, and the fabric simply makes the rest of the estate reachable.
Watch on YouTube
Why IBM Spent Billions on Confluent Acquisition | AI-Driven Data Fabric
A Kanerika video on the AI-driven data fabric idea and why connected, governed access to live data across systems matters to enterprise data platforms.
The Building Blocks of a Data Fabric
A fabric is easier to judge when you break it into parts. Each part solves one piece of the find, trust and reach problem, and many teams already own some of them.
- Active metadata and a catalog: an inventory of every dataset, its owner, its meaning and its usage, kept current by automation instead of by hand.
- Integration plus virtualization: enterprise data integration pipelines for data that must move, and virtual queries for data that can stay where it is.
- A semantic layer or knowledge graph: shared business definitions, so “active customer” means the same thing in every tool.
- Policy-based governance and lineage: access rules defined once and applied everywhere, with data lineage that shows where each figure came from.
- Automation: recommendations, quality checks backed by data observability, and access workflows that cut manual tickets as the estate grows.
The catalog is the foundation, because without accurate metadata, virtualization only makes it faster to query data nobody understands. A sensible fabric program starts by cataloging and classifying sources and adds virtual access later.
Data Fabric vs Microsoft Fabric: Not the Same Thing
The names cause real confusion in buying meetings, especially when both come up in one deck. Data fabric is the general design pattern, while Microsoft Fabric is a specific product. Microsoft delivers Microsoft Fabric as a software-as-a-service platform, with OneLake as one centralized, logical data lake for all its workloads.
Inside Microsoft Fabric you will find both sides of this comparison. The Fabric Data Warehouse is a warehouse in the classic sense. Next to it, however, two features behave like fabric capabilities. OneLake shortcuts reference data in Amazon S3, S3-compatible storage, ADLS Gen2, Azure Blob Storage and other sources without copying it. Fabric mirroring continuously replicates an existing data estate into OneLake, from sources that include Snowflake, SQL Server, Oracle and SAP Datasphere.
Buying Microsoft Fabric does not give you a data fabric by itself, and you can build a data fabric without it. Still, the platform does give you a warehouse and several fabric-style tools in one place. That is why it often comes up in this decision, and our guide to Microsoft Fabric adoption covers the rollout side.
Data Fabric vs Data Warehouse: Side-by-Side Comparison
The quickest way to compare the two is to look at what each one does with data. A warehouse moves and reshapes data before anyone queries it. A fabric, by contrast, connects to data first and then decides whether anything should move. Every row below follows from that one difference.
| Dimension | Data warehouse | Data fabric |
|---|
| Purpose | Trusted reporting and history on curated data | Find, connect and govern data across the whole estate |
| Data movement | Copies data in through ETL or ELT | Queries in place and moves only what it must |
| Schema | Schema-on-write, fixed before load | Source schemas plus a shared semantic layer |
| Latency | As fresh as the last batch load | Close to the source for in-place queries |
| Data types | Mostly structured, modeled tables | Structured, semi-structured and files across systems |
| Governance model | Central, inside one store | Policies applied across many stores through metadata |
| AI readiness | Clean, versioned training sets | Discovery, lineage and governed access for models and agents |
| Skills | SQL, dimensional modeling, ETL | Metadata, integration, virtualization, stewardship |
| Time to value | Slower per new source, since each needs a pipeline and a model | Faster first access to new sources, slower to mature as a whole |
| Cost drivers | Storage, compute and copy pipelines | Metadata tooling, integration software and skills |
| Typical failure mode | A backlog of sources waiting for pipelines | A catalog nobody maintains and slow virtual joins |
| Typical owner | Central BI or data warehouse team | Data platform team with domain data stewards |
Read each row as a trade-off between two real strengths. The warehouse wins on predictability, while the fabric wins on reach.
Strengths and Limits of Each
Both architectures have honest weak spots, and each weak spot tends to be where the other one is strong. The view below keeps the strengths and limits next to each other.
| Data warehouse | Data fabric |
|---|
| Strength | Fast, consistent queries on modeled data | Reaches new sources without building a pipeline for each |
| Strength | Long history for trends, audit and model training | One catalog and policy layer over many systems |
| Strength | Mature tools and widely available skills | Fresher answers to cross-system questions |
| Limit | Every new source needs a pipeline and a model | Depends on metadata quality and steady upkeep |
| Limit | Batch loads add latency | Heavy joins across live systems can run slowly |
| Limit | Schema changes are slow and costly | Needs new skills and data steward roles |
Without good metadata, a fabric is just a slower way to reach messy data. A warehouse with a six-month source backlog, on the other hand, is a fast way to answer yesterday’s questions.
Talk to Kanerika
Not Sure Which Fits Your Stack?
Kanerika maps your sources, freshness needs, regulations and skills against the decision guide and shows whether a warehouse, a fabric layer or both fits your estate.
Schedule a Demo →
How Data Moves: Copy and Centralize vs Connect in Place
Under the labels, the real choice is mechanical. You either copy data to where the questions are, or you send the questions to where the data is. Each path has a cost, so the right answer can change from one dataset to the next.
Copying works much like a central library. Data is extracted, cleaned and stored once, so every reader gets the same edition quickly. The trade-offs of that loading step are covered in our data ingestion vs data integration guide. The price is lag and duplication, because the copy is only as fresh as the last load. Every new source also adds another pipeline to run.
Connecting in place works more like an interlibrary loan. The fabric sends a query to SAP, Salesforce or S3 and combines the results. Nothing is duplicated, so the answer reflects the source at that moment. The price is speed and extra load on the source systems, especially when the same large join runs hundreds of times a day.
A practical rule of thumb follows from that:
- Move it into the warehouse when the same heavy joins run again and again, when you need years of history or when auditors need a governed, reproducible copy.
- Query it in place when the data must be fresh, the volume per query is small or the question is a one-off lookup across systems.
- Replicate it when you need a fresh copy without building a pipeline, which is what Fabric mirroring does for its supported sources.
In practice, most estates end up using all three paths at once. The skill, then, lies in moving each dataset to the right path as its usage changes over time.
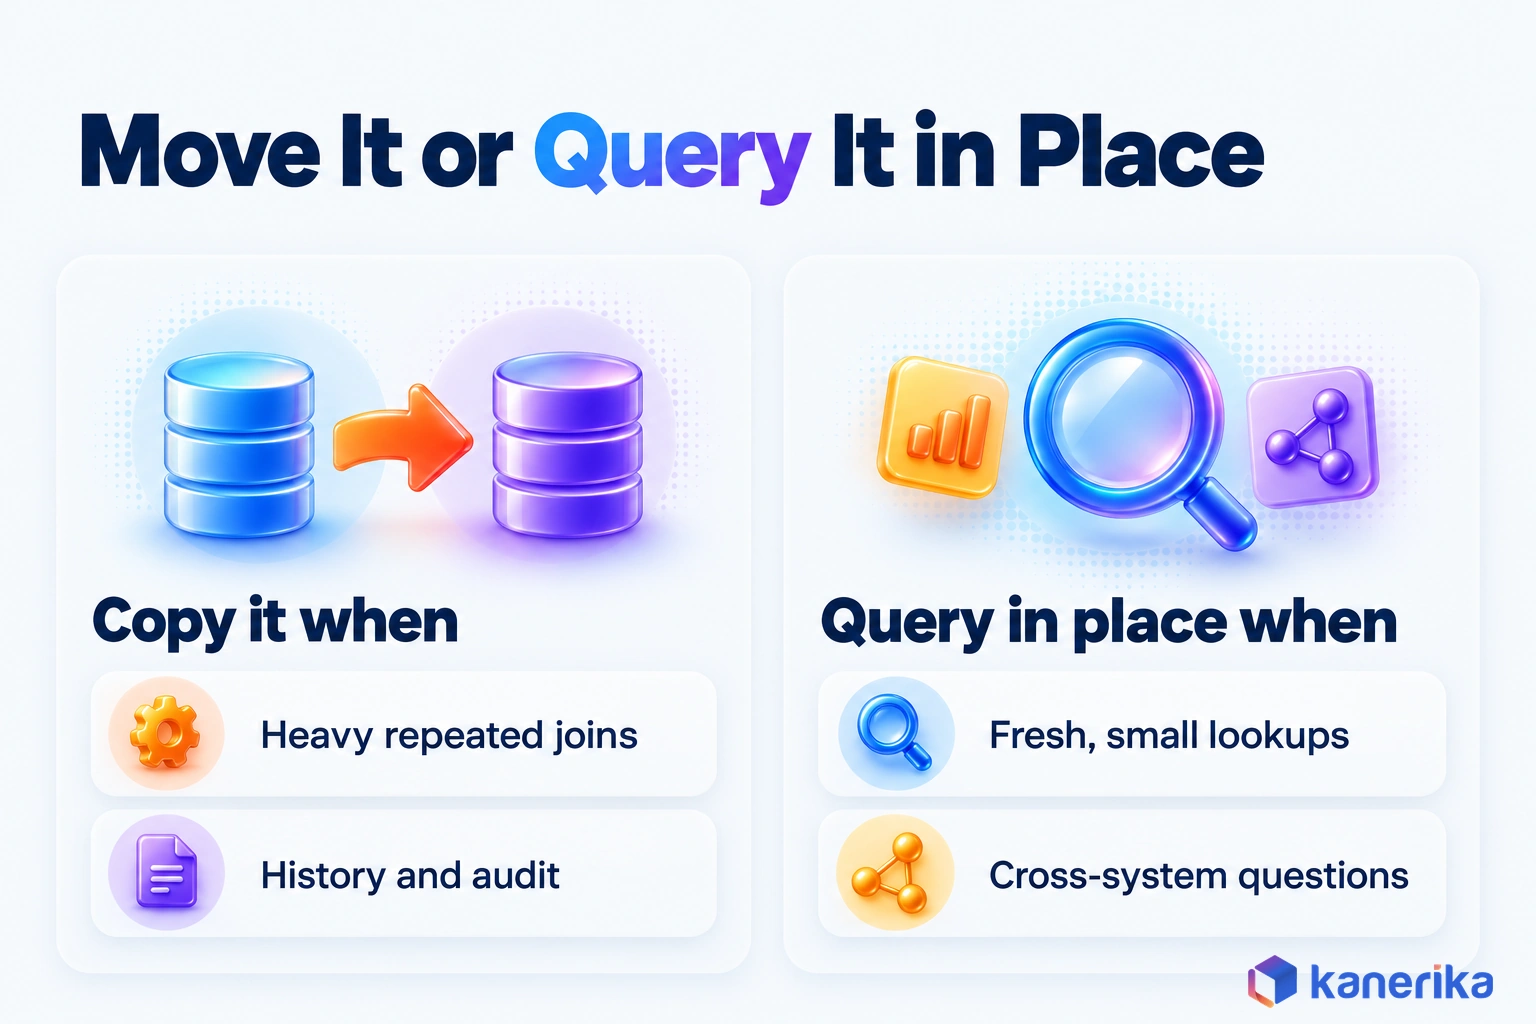
Where Each Architecture Performs Better
Workloads settle this comparison better than feature lists do. The same company can need a warehouse for one job and fabric capabilities for the next, so it helps to name the job first.
| Workload | Better fit | Why |
|---|
| Financial and regulatory reporting | Data warehouse | Reproducible figures, long history and one governed copy that auditors can trace |
| Cross-system 360 views of customers, suppliers or products | Data fabric | Joins records across CRM, ERP and files without a pipeline per source |
| Near-real-time operations | Data fabric, through in-place queries or mirroring | Reads current data instead of waiting for the next batch load |
| AI and RAG data access | Both | Models train on curated data, while agents need governed access to live context |
The first row explains why finance teams rarely give up their warehouse, because a quarter-end close needs the same answer every time. A governed copy with lineage provides exactly that.
The second and third rows explain why operations and customer teams ask for fabric capabilities. Their questions cross several systems, so they cannot wait for a new pipeline and model. Finally, the fourth row is the most interesting one, and it deserves its own section.
Is Data Fabric Better for AI and Machine Learning?
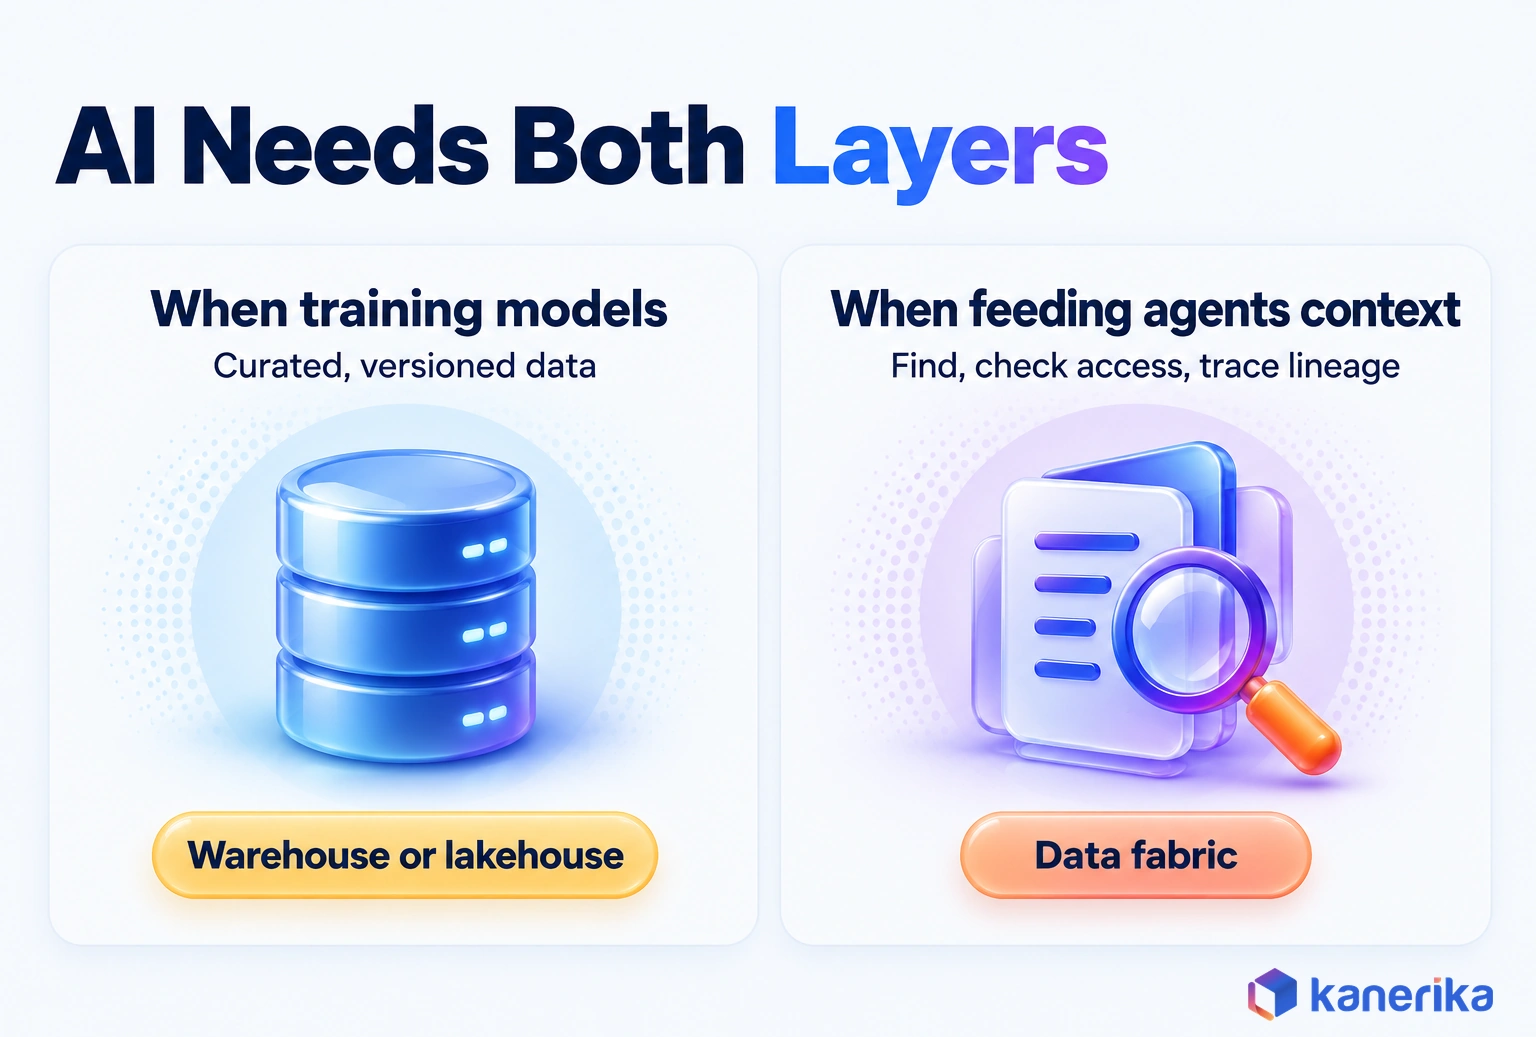
A data fabric helps AI, yet it does not replace the curated data that models learn from. The honest answer splits the AI workload in two: training models and feeding them context.
Training needs stable, cleaned and versioned data. If a churn model trains on a table that changes under it, you cannot reproduce the result or explain it to a risk team. That work still belongs in a warehouse or lakehouse, where snapshots and history are easy to keep, and where machine learning operations practices can version each training set.
Feeding context, on the other hand, is where a fabric earns its place. An AI agent or a retrieval-augmented generation (RAG) assistant must first find the right data. It also has to check that the user may see it and know where it came from.
A catalog, lineage and a policy layer give it exactly that, even across sources that never reached the warehouse. For example, a service agent could pull a customer’s open orders from the ERP and the contract terms from a document store. The same access policy then filters both.
The better question, then, is which part of the AI pipeline is failing. If models are weak because training data is messy, fix the warehouse or lakehouse first. If assistants are blocked because nobody can find or safely reach the data, a fabric layer is the faster fix.
Cost, Skills and Time to Value
Neither architecture is cheaper in every case, because each one makes you pay for different things. A useful comparison looks at what drives cost over time instead of a list price.
A warehouse spends on storage, compute and the pipelines that copy data in, and those costs grow with every new source and every duplicate table. The skills are familiar, though, since SQL developers and dimensional modelers are easy to find.
A fabric, on the other hand, spends less on copies and more on metadata tooling, integration software and the people who keep the catalog accurate. That stewardship work never really ends, and a catalog that nobody maintains loses value fast. Budget for named owners from the start, and a data governance maturity model helps you plan that ownership in stages.
| Cost driver | Data warehouse | Data fabric |
|---|
| Storage | Grows with every copy and history table | Lower, since most data stays in its source |
| Compute | Predictable and tuned for modeled queries | Variable, driven by in-place query load |
| Pipelines | One per source, built and maintained | Fewer, used only for data that must move |
| Tooling | Warehouse platform and ETL | Catalog, virtualization and policy tools |
Picture adding one more source, such as a new supplier portal, to see the difference. On the warehouse side, it needs a pipeline, a model change and test loads before anyone can report on it. Its history then adds storage every month.
On the fabric side, the team catalogs the portal, names an owner and sets an access policy, so analysts can query it much sooner. The catch, however, is that every heavy join against it adds load to the portal itself.
Using Both: A Data Fabric Around an Existing Warehouse
For most enterprises, the answer is a combination. Keep the warehouse as the curated core, and then wrap a fabric layer around it. The warehouse keeps doing what it does well, while the fabric covers the sources and questions it never reached.
A typical reference flow has four layers. Source systems such as ERP, CRM, SaaS apps and object storage sit at the bottom. Above them, the fabric layer holds the catalog, virtualization and access policies. Next, the warehouse holds curated marts for reporting, and BI tools and AI applications sit on top, drawing on both.
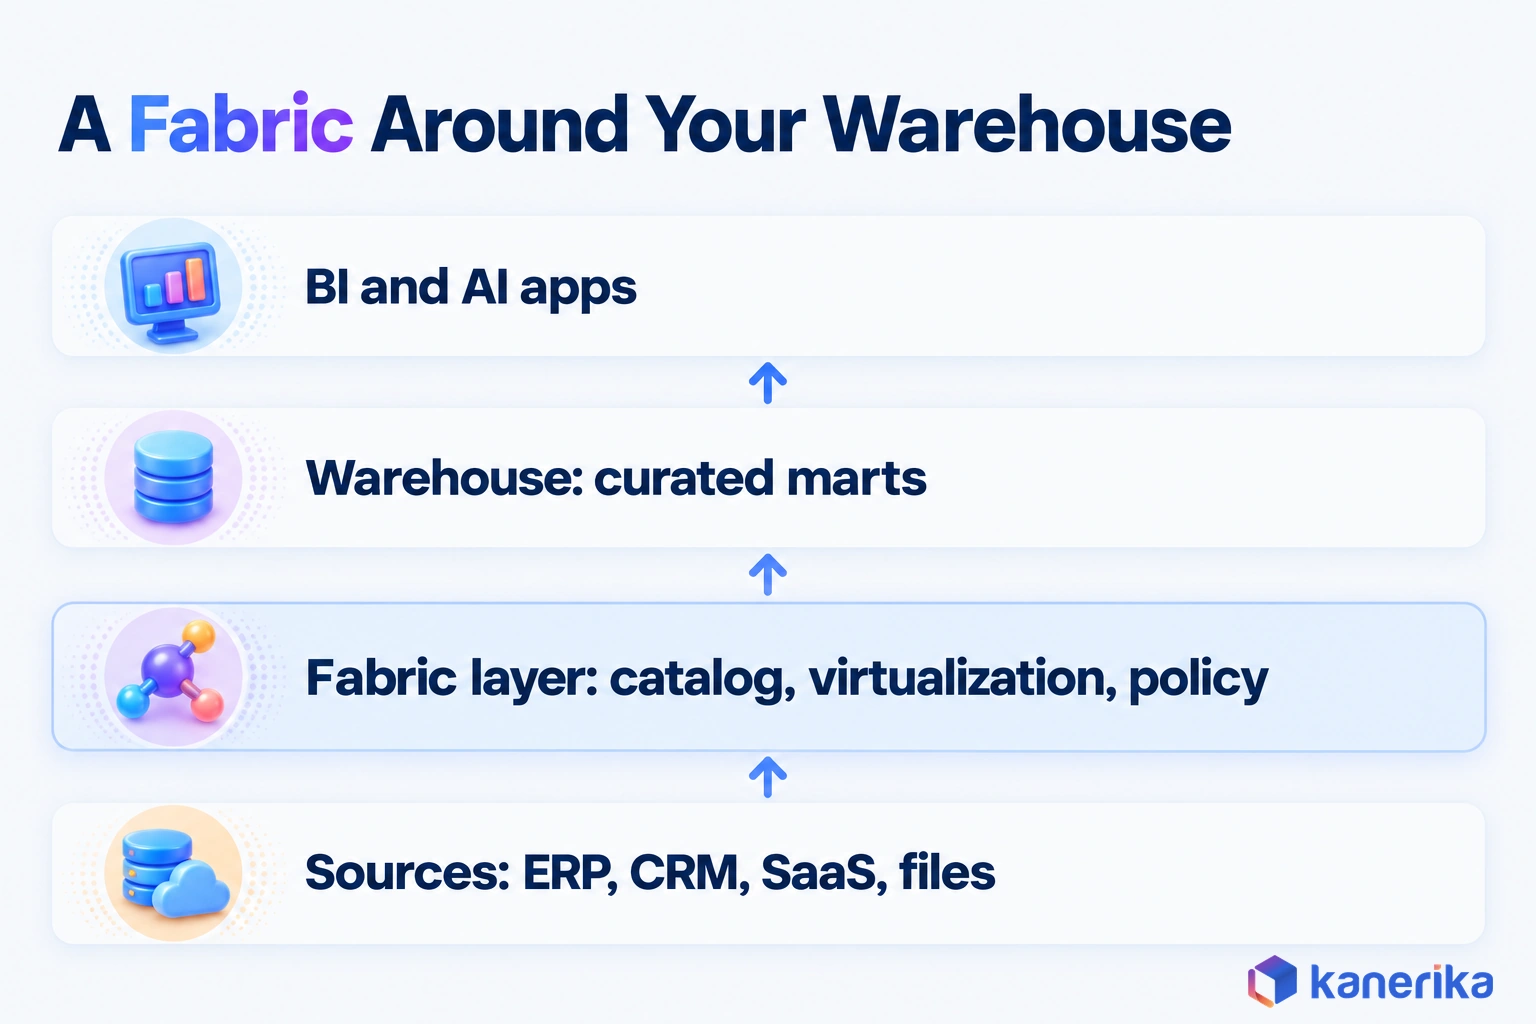
Microsoft Fabric packs this whole pattern into one platform, with the mirroring, shortcuts and warehouse covered in the Microsoft Fabric section above. Its pipelines come from Data Factory in Microsoft Fabric.
A phased roadmap keeps the risk low:
- Catalog first: inventory and classify your sources, assign owners and publish one business glossary.
- Virtualize low-volume joins: serve one-off and cross-system questions in place, so the warehouse backlog stops growing.
- Move hot paths into the warehouse: when a virtual query runs often enough to strain the sources, promote it to a modeled table.
- Govern across both: apply the same access policies and lineage to warehouse tables and fabric views, under one enterprise data governance program.
Each phase stands on its own. You can stop after the catalog and still be better off than before.
Tools by Architectural Role
Tools make more sense when you know the role they play. The table below groups common options by role instead of ranking them. For a ranked view, The Forrester Wave: Enterprise Data Fabric, Q1 2024, published February 28, 2024, scored 15 providers against 26 criteria. Our lists of data integration tools and data governance tools cover each category in more detail.
| Role | Example options | What it does in the stack |
|---|
| Cloud data warehouse | Snowflake, Google BigQuery, Amazon Redshift, Microsoft Fabric Data Warehouse | Stores and serves curated, modeled data for BI |
| In-place access | OneLake shortcuts | References external storage without copying it |
| Continuous replication | Fabric mirroring | Keeps a fresh copy of sources such as SQL Server, Oracle or Snowflake |
| Fabric architecture offering | IBM data fabric | Combines integration, catalog and governance under one fabric design |
| Catalog and governance | Microsoft Purview, Collibra, Alation | Metadata, lineage, classification and access policies |
| Data virtualization | Denodo, Starburst, Dremio | Federated queries across databases and files |
Whatever you choose, check one thing first. Can the tool read your metadata and apply your policies, or will it become one more silo?
Checklist
Data Integration Checklist
Check sources, pipelines, quality rules and access controls before you connect more systems to your warehouse or add a fabric layer around it.
Get the Checklist →
Where Data Mesh and Lakehouse Fit
Two other terms often join this debate, and they answer different questions. A lakehouse is a storage pattern that adds warehouse features, such as tables and transactions, to low-cost lake storage. Our comparison of data lake vs lakehouse explains it in full. A data mesh, meanwhile, is an ownership model where business domains publish their own data products. Our guide to data mesh vs data lake covers it.
A data fabric is the integration and governance layer that connects whatever storage and owners you have. The three can coexist, with a mesh running on a lakehouse and a fabric catalog and policy layer across it. For the ownership question in depth, read data fabric vs data mesh.
How to Choose: A Decision Guide
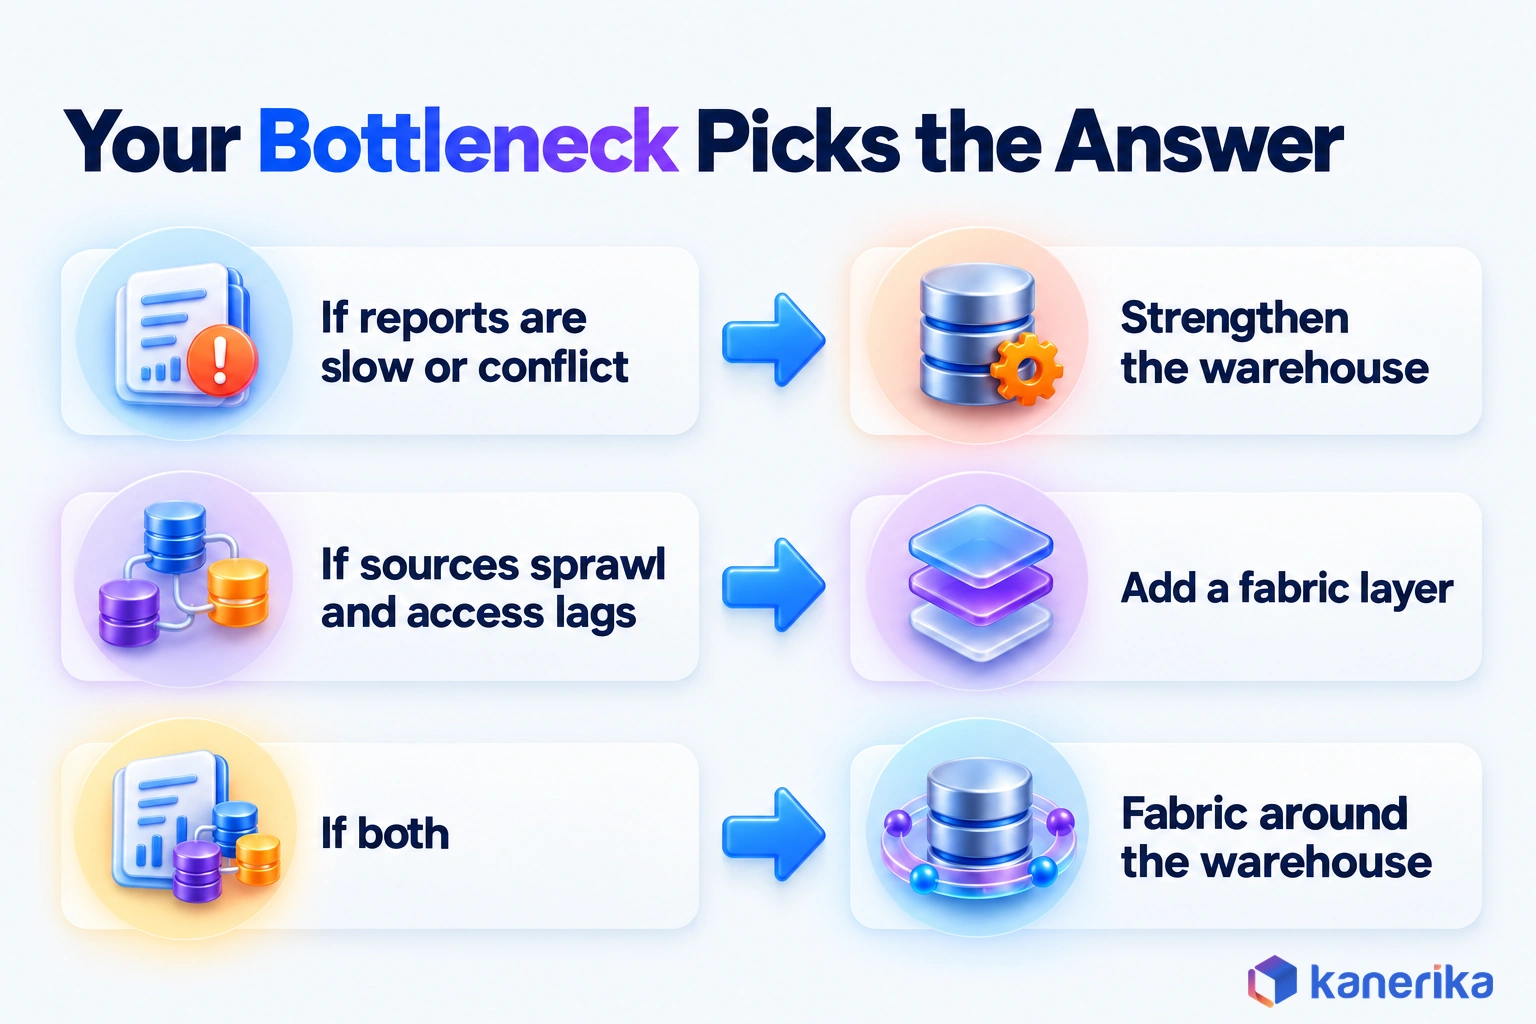
The choice depends less on technology than on where your stack hurts. Start with the scenarios below, then score your estate with six questions.
| Scenario | Better fit | First move |
|---|
| Reports are slow or dashboards disagree on the numbers | Data warehouse | Model the core subjects and fix the load pipelines |
| Questions span many systems and each new source takes months | Data fabric layer | Catalog sources and virtualize low-volume joins |
| Strict audit and regulatory reporting | Data warehouse | Keep governed, reproducible copies with lineage |
| AI assistants cannot find or safely reach data | Data fabric layer | Add a catalog, lineage and access policies |
| A working warehouse plus growing source sprawl | Both | Keep the warehouse and add fabric capabilities around it |
Then answer six questions about your estate:
- How many source systems feed your analytics? A handful favors the warehouse, while dozens across clouds favor a fabric layer.
- How fresh must answers be? Daily data suits a warehouse, and minutes point to in-place queries or mirroring.
- How regulated is the reporting? Audit-grade figures need governed copies with history.
- Where must the data reside? Residency rules can make querying in place safer than copying data across regions.
- What skills does the team have? SQL and modeling skills suit a warehouse, and a fabric also needs metadata and stewardship roles.
- How much have you invested in the warehouse? A working warehouse is an asset to wrap, so replacing it rarely pays.
If most answers point one way, you have your answer. If they split, however, the combined pattern from the previous section is the likely fit for your stack.
Common Mistakes to Avoid
A few avoidable mistakes cause much of the pain in these programs, although each one is easy to spot early.
- Buying a fabric to fix poor data quality: a fabric exposes bad data faster, but it does not clean it. Fix quality at the source or in the warehouse.
- Virtualizing heavy repeated joins: a large join that runs all day belongs in a modeled table, or it will slow both the query and the source.
- Skipping ownership and stewards: a catalog without named owners drifts out of date, and people stop trusting it. Our guide to data governance challenges covers how to close ownership gaps.
- Rebuilding a working warehouse: replacing a trusted reporting layer to go fabric adds risk and cost with no new capability, so wrap it instead.
How Kanerika Helps You Choose and Build the Right Architecture
Kanerika helps enterprises decide between a warehouse, a fabric layer or both, and then builds the choice. We are a Microsoft Solutions Partner for Data and AI. Our data architecture services also start with the same questions as the decision guide above.
The work runs in four stages:
- Assess the estate: map sources, data flows, freshness needs, regulations and skills.
- Design the target: decide which data moves into the warehouse or lakehouse and which stays in place behind a catalog and policies.
- Build one priority workload: deliver a single high-value use case end to end, so the design is proven on real data.
- Expand and govern: add sources in phases, with lineage and access policies applied across both layers.
The same pattern shapes our own data insights agent. Karl answers plain-language questions across SQL, NoSQL, cloud lakes and real-time streams, and it is available as a Microsoft Fabric workload. Every answer is grounded in metadata, lineage and a governance layer, and Karl inherits your existing access controls. During setup, our team connects Karl to your data stack and configures its metadata, lineage and access policies first.
A global pharmaceutical manufacturer shows what copying scattered data into one governed lakehouse, rather than a classic warehouse, can deliver. The company sells more than 500 SKUs in over 55 countries from more than 30 plants. Before the project, its data was scattered across Model N, SQL Server, SAP and SAP Vistex.
Kanerika centralized that data into a Microsoft Fabric Lakehouse with Power BI reports on top. The results were a 78% reduction in data-related errors, a 36% increase in decision-making efficiency and a 41% increase in data processing speed. When sources must stay where they are, our data integration services cover the connect-in-place side.
Case Study
78% Fewer Data Errors for Pharma with Microsoft Fabric
Kanerika centralized a global pharma company’s Model N, SQL Server, SAP and SAP Vistex data into a Microsoft Fabric Lakehouse, with a 36% increase in decision-making efficiency.
Read the Case Study →
Data Fabric vs Data Warehouse: Which Fits Your Stack?
A data warehouse fits your stack when the job is trusted, repeatable reporting on curated data with history. A data fabric fits when the job is finding, reaching and governing data spread across many systems. Most enterprises have both jobs, so the common answer is to keep the warehouse and add fabric capabilities around it, starting with a catalog.
Look at your bottleneck before you look at vendors. If queries are slow or numbers disagree, then strengthen the warehouse. If source sprawl and access requests slow every answer, a data fabric around that warehouse is what fits your stack next.
Frequently Asked Questions
What is the main difference between a data fabric and a data warehouse?
A data warehouse copies curated data from source systems into one governed store built for reporting and history. A data fabric leaves most data where it already lives and adds a layer that catalogs, connects and governs it. The warehouse moves data to the questions, while the fabric sends questions to the data.
Can a data fabric replace a data warehouse?
A data fabric rarely replaces a data warehouse. Finance, audit and heavy repeated reporting still need a curated, modeled copy with history, which is what a warehouse provides. A fabric usually wraps the warehouse instead, adding a catalog, in-place access and shared policies for the sources the warehouse never reached.
Is Microsoft Fabric PaaS or SaaS?
Microsoft Fabric is delivered as software as a service. Microsoft runs the infrastructure, and you work with workloads such as Data Factory, the lakehouse, the warehouse and Power BI through one service, all sharing OneLake storage. That means less setup than assembling separate platform services, although you still design your own data models, pipelines and governance.
Is ETL part of data warehousing?
Yes, ETL is a core part of data warehousing. Extract, transform and load is how data leaves source systems, gets cleaned and standardized, and lands in the warehouse tables that reports use. Many cloud warehouses use ELT instead, loading raw data first and transforming it inside the warehouse with SQL, which follows the same principle.
Is data warehousing dead?
Data warehousing is not dead, although it has changed shape. Cloud warehouses such as Snowflake, BigQuery and the Fabric Data Warehouse support open table formats and can read data held in external storage. Finance and audit reporting still need curated, modeled data with history, so the warehouse remains the trusted core of most analytics stacks.
Is data fabric better than a data warehouse for AI and machine learning?
Each helps a different part of AI. Models train best on curated, versioned data, which a warehouse or lakehouse keeps well. A data fabric helps AI assistants and agents find data, check access rights and trace lineage across many sources. If training data is messy, fix the warehouse first, and if access is the blocker, add a fabric.
Is a data fabric cheaper than a data warehouse?
Not automatically, because each one spends money in different places. A warehouse pays for storage, compute and the pipelines that copy data in, and those costs grow with every source. A fabric copies less but pays for metadata tooling, integration software and data stewardship. The cheaper option depends on how many sources you have and how often data is reused.
What is the difference between data fabric and data virtualization?
Data virtualization is one technique, while a data fabric is a whole architecture. Virtualization lets you query several sources as if they were one database, without copying the data. A data fabric uses virtualization alongside a catalog, active metadata, a semantic layer, governance policies and automation, so data can be found, trusted and reached across the estate.
How is a data fabric different from a data mesh?
A data fabric is an integration and governance layer that connects data across systems through metadata and automation. A data mesh is an ownership model in which business domains publish their own data as products. They answer different questions, so they can work together, with domain-owned data products made findable and governed through a shared fabric layer.
Is Snowflake a data warehouse or a data fabric?
Snowflake is a cloud data platform that most teams use as a data warehouse. It stores and serves curated, modeled data for analytics. Its Iceberg tables can also use an external volume that connects Snowflake to your own cloud storage, which reaches outside the warehouse, but on its own Snowflake is not a full data fabric.
Do companies need both a data fabric and a data warehouse?
Many enterprises end up using both. The warehouse stays the trusted core for reporting and history, and the fabric layer connects the sources, files and SaaS apps around it. You need the fabric once source sprawl and access requests, rather than query speed, become the main reason answers take too long.
Which is better for real-time analytics: data fabric or data warehouse?
A data fabric is usually better for near-real-time questions, because it can query sources in place or use replication instead of waiting for a batch load. A warehouse is only as fresh as its last load. For dashboards that refresh often but run heavy joins, a frequently loaded warehouse table can still be the faster option.
What are the main use cases of data fabric vs data warehouse?
A data warehouse suits financial reporting, regulatory reporting, trend analysis and other work that needs one governed copy with history. A data fabric suits cross-system customer or supplier views, near-real-time operational questions and governed data access for AI assistants and agents. Large companies often run both, matching each workload to the better architecture.
What is a data fabric example?
Picture a manufacturer whose orders sit in SAP, accounts in Salesforce and supplier files in Amazon S3. With a data fabric, an analyst searches one catalog, confirms she has access and joins those sources without a new pipeline. The finance reports still run from the warehouse, while the fabric makes the rest of the estate reachable.
Why is it called a data fabric?
The name describes data woven together across many systems. Like threads in a fabric, each source keeps its own place, while a shared layer of metadata, integration and policy ties them into one connected whole. The term stresses connection and coverage across the estate, instead of a single central store that holds every record.
Is Microsoft Fabric a data warehouse or a data fabric?
Microsoft Fabric is neither one exactly. It is a software-as-a-service analytics platform that includes a Fabric Data Warehouse built around T-SQL. It also offers fabric-style features, such as OneLake shortcuts that reference external storage and mirroring that replicates sources into OneLake. You can build data fabric patterns with it, but buying it is not a fabric.
Is Microsoft Fabric a lakehouse?
Microsoft Fabric includes a lakehouse, but it is broader than one. The platform is built on OneLake, a single logical data lake for all its workloads, and offers lakehouse, warehouse, data engineering, data integration and reporting experiences on top. Its warehouse also stores tables as Delta Parquet files, so both experiences share the same open storage.
Is Microsoft Fabric an ETL tool?
Microsoft Fabric includes ETL capabilities, but it is a full analytics platform as well. Its Data Factory experience handles pipelines and data movement, and Microsoft describes it as the next generation of Azure Data Factory, with about 90% of ADF activities available. Fabric also covers storage, warehousing, data science and reporting in the same service.














