TL;DR
The predictive AI examples worth copying predict a dated outcome someone acts on, so start with cash, demand or staffing. A finance team with years of ERP history should start with a daily cash-flow forecast. Multi-site operators should start with demand or staffing, and plants with maintenance if failure records exist. Lenders need explainable credit models with human review. In the EU, the AI Act’s high-risk rules for credit-scoring systems apply from December 2, 2027. Fund a pilot only when you have labeled history, an owner, a clear action and a KPI.
Key Takeaways
- Predictive AI learns from historical data to estimate a future outcome, such as a late payment, next week’s demand or a machine failure, early enough to act.
- An example is worth copying when it has a dated historical outcome, a named decision owner and an action that fits inside the forecast horizon.
- The 15 predictive AI examples below cover revenue, finance, supply chain, operations, risk, workforce, healthcare and IT, each with its data, KPI and common trap.
- Start with a forecast that feeds a daily decision, such as cash, demand or staffing, because it has labels, volume and a clear owner.
- Pair the model with rules and agents so a score turns into an action, and keep a person on high-impact or regulated decisions.
- Credit-scoring and CV-sorting systems fall under EU AI Act high-risk rules from December 2, 2027. US banks with over $30 billion in assets also have new model risk guidance in SR 26-2 (April 2026).
The 9 a.m. Funding Call
It is 8:40 on a Tuesday, so a bank’s treasury desk has twenty minutes left to size the day’s funding position. Two analysts are copying balances from several systems into a spreadsheet. They pad the estimate with a cash buffer, because being short costs more than sitting on idle money.
Every morning ends the same way. The number arrives late, nobody fully trusts it, and the padding quietly ties up cash that could earn a return.
A daily cash-flow forecast changes that call. The model predicts the day’s inflows and outflows from past patterns, so the analysts start from a number and spend their time on exceptions. That shift, from assembling data to judging a forecast, is what separates useful predictive AI from a demo.
This guide collects 15 predictive AI examples that follow the same pattern. Each one comes with the data it needs, a sensible first model, the KPI that proves it works and the trap that sinks it. The guide then closes with a simple way to decide which example to fund first.
What Predictive AI Is and What Makes an Example Worth Copying
Predictive AI is software that learns from historical data to estimate what will happen next, such as whether an invoice will be paid late. It returns a probability or a number, and a person or a system acts on it before the outcome arrives.
The definition is simple, and that simplicity is why so many lists of examples disappoint. Almost anything with a forecast can be called predictive AI, yet only some forecasts change a decision. A churn score that never leads to a call is only a report.
Three tests separate an example worth copying from a slide in a strategy deck:
- A dated historical outcome. You hold records of what actually happened and when, such as paid dates, failure dates or delivered quantities. Without them, the model has nothing to learn from.
- A named decision owner. One person or team is accountable for acting on the prediction, for example the collections lead or the plant maintenance manager.
- An action inside the forecast horizon. The prediction arrives early enough to change something. A seven-day stockout warning helps a buyer, while a two-hour warning only explains the empty shelf.
Generative AI is the term most often confused with it. A predictive model scores or forecasts one specific outcome, while a generative model produces new text, code or images. The two often work together, and the generative AI vs predictive AI comparison covers where each one fits.
The tests matter more than the algorithm, because a simple model that passes all three beats a clever one that fails any. If you would rather buy than build, Kanerika’s review of predictive analytics companies compares how vendors package these models.
15 Predictive AI Examples by Business Function
The fastest way to judge an example is to look at the decision it changes. Each row below names that decision first, then the data, a starting model, the KPI and the trap.
Here are the 15 at a glance, numbered as they appear in the tables:
- Customer churn risk
- Lead scoring
- Credit risk
- Cash-flow forecasting
- Fraud and claims-fraud detection
- Demand forecasting
- Inventory policy
- Predictive maintenance
- Delivery delay and ETA
- Quality and defect prediction
- Supplier risk
- Workforce and contact-center demand
- Patient deterioration risk
- Security alert risk scoring
- IT incident prediction
The starting-model column is deliberately modest, since gradient-boosted trees and logistic regression are common first choices for tabular business data. They train fast and show which inputs drive the score. Deep learning usually earns its place later, on images, free text or long sensor streams. For a fuller tour of model families and build steps, see machine learning in predictive analytics.
Examples 1-5: Revenue, Customer and Finance
Finance examples tend to have the cleanest labels, because money leaves a dated trail.
Table 1: Revenue, customer and finance use cases
| Example | Prediction and action | Data you need | Starting model | KPI to judge it | Common trap |
|---|---|---|---|---|---|
| 1. Customer churn risk | Chance an account leaves within 90 days, then the retention team calls the top tenth | Usage and billing, support tickets and contract dates | Gradient-boosted classifier | Retained revenue compared to a holdout group | Scoring accounts that are already gone, so there is no offer to make |
| 2. Lead scoring | Chance a new lead closes, so sales works the top band first | CRM history and firmographics, web and email activity | Logistic regression | Win rate and cycle time compared to unscored leads | Training only on leads sales chose to chase, because that repeats old bias |
| 3. Credit risk | Probability of default, then approve, price or refer to an underwriter | Application data, bureau data and repayment history | Scorecard or constrained gradient boosting | Default rate by score band and approval rate | A score that cannot give specific reasons when it declines someone |
| 4. Cash-flow forecasting | Daily inflows and outflows, so treasury can size funding and release idle cash | Bank balances and payment calendars, receivables and payables ledgers | Time-series model with calendar features | Forecast error compared to the spreadsheet and idle cash held | Ignoring holidays, month-end peaks and one-off payments |
| 5. Fraud and claims-fraud detection | Unusual transactions or claims, then a hold for investigator review | Transactions and claims, device and account history | Isolation Forest or autoencoder when labels are scarce | Losses prevented and investigator hit rate | Alert floods that bury investigators until they stop looking |
How the Fraud Row Played Out at an Insurer
The fraud row, for example, shows how far a modest start can go. Kanerika built Isolation Forest and autoencoder fraud models for a mid-sized US insurance company, which cut its financial losses by 33%. Both methods learn what normal activity looks like, so they work even when few past frauds carry a label.
Case Study
33% Lower Financial Losses with AI Fraud Detection
A mid-sized US insurance company used Isolation Forest and autoencoder models built by Kanerika to spot unusual claims and transactions, cutting financial losses by 33% and risk exposure by 25%.
Read the Case Study →Examples 6-8: Supply Chain, Manufacturing and Operations
Operations examples pay off through volume. A forecast that improves one replenishment order slightly is worth a lot when it runs across thousands of items every day. Kanerika’s guide to AI in supply chain covers the wider field.
Table 2: Supply chain, manufacturing and operations use cases
| Example | Prediction and action | Data you need | Starting model | KPI to judge it | Common trap |
|---|---|---|---|---|---|
| 6. Demand forecasting | Units by item, location and week, so planners can set orders and labor | Sales history, promotions, prices, calendar and stockout flags | Gradient boosting or hierarchical time series | Forecast error and bias compared to the current method | Reading stockout weeks as low demand when the shelf was simply empty |
| 7. Inventory policy | Reorder points and safety stock from the forecast, then the right order quantity | Demand forecast and lead times, coupled with service targets and holding costs | Forecast plus an optimization step | Service level and inventory days, at equal or lower cost | Stopping at the forecast instead of changing the order rule |
| 8. Predictive maintenance | Failure risk per asset, so repairs happen before a breakdown | Sensor readings, work orders and failure logs | Survival model or gradient boosting on sensor features | Unplanned downtime and maintenance cost per asset | Too few recorded failures to learn from, so the model guesses |
Examples 9-11: Delivery, Quality and Supplier Risk
These three rows sit between the warehouse and the customer. They pay off only when someone has the authority to act on the warning, such as a dispatcher, a line supervisor or a buyer.
Table 3: Delivery, quality and supplier use cases
| Example | Prediction and action | Data you need | Starting model | KPI to judge it | Common trap |
|---|---|---|---|---|---|
| 9. Delivery delay and ETA | Late shipments, then a reroute, an expedite or a customer warning | Shipment events, carrier, lane, weather and dock times | Gradient-boosted regression | On-time rate and ETA error in hours | Predicting delays when nobody has authority to fix them |
| 10. Quality and defect prediction | Defect risk by batch or unit, then inspect or adjust the line | Process parameters, machine settings and inspection results | Classifier on process data, with vision models for images | Scrap rate and escaped defects | Labels from manual inspection when each shift grades differently |
| 11. Supplier risk | Late or short delivery by supplier, so buyers dual-source or add safety stock | Purchase order history, delivery performance and supplier financials | Gradient-boosted classifier | Late-delivery rate on flagged suppliers compared to the rest | Scores refreshed quarterly while the decision is weekly |
Where the Operations Rows Go Deeper
Row 7 is the one teams skip most often. A demand forecast saves nothing until it changes how much you order, which is the core of AI inventory management. Retail teams will find more predictive analytics use cases in retail built on rows 6 and 7.
Row 8 has its own depth. The AI in predictive maintenance guide covers sensor setup and failure labels, and supply chain analytics covers the delivery data behind row 11. Both depend on history that someone recorded carefully for years.
Examples 12-15: Risk, Workforce, Healthcare and IT
The last group covers people, patients and systems, where an error carries more weight. These rows need the same data discipline, plus a clear rule about who reviews each score.
Table 4: Risk, workforce, healthcare and IT use cases
| Example | Prediction and action | Data you need | Starting model | KPI to judge it | Common trap |
|---|---|---|---|---|---|
| 12. Workforce and contact-center demand | Contact volume by interval, so planners set shifts and staffing | Contact history, channel mix and the marketing calendar | Time-series model by interval | Service level, overtime and idle hours | Forecasting volume but not handle time |
| 13. Patient deterioration risk | Risk of decline for inpatients, then an alert for care-team review | Vital signs, lab results and past events | Gradient boosting on vitals and labs, with clinician review | Time to intervention and alert precision | Alert fatigue, so staff start to ignore scores |
| 14. Security alert risk scoring | Likely real threats, so analysts triage the top band first | SIEM alerts, asset criticality and past incident outcomes | Gradient-boosted classifier | Time to respond and true positives in the top band | Labels that exist only when someone investigated the alert |
| 15. IT incident prediction | Outage risk from early signals, so teams act before users notice | Logs and metrics, together with change records and past incidents | Anomaly detection plus a classifier | Incidents avoided and minutes of downtime | Predicting incidents when there is no runbook to act on |
Row 13 sets the tone for high-stakes cases. The score informs a clinician, and the clinician decides. Rows 14 and 15 work the other way round, ranking a flood of alerts so that a small team looks at the right ones first.
Predictive AI Examples Beyond Retail and Banking
Published predictive AI examples lean heavily on retail and banking, because both sectors hold long, clean transaction histories. The same outcome, owner and action pattern works just as well in sectors that get less attention.
At first notice of loss, an insurer can run claims triage, scoring each new claim for complexity and fraud risk. Simple, low-risk claims go to fast-track payment, and complex ones go straight to an experienced adjuster. The KPI pairs cycle time on simple claims with leakage on complex ones.
Utilities use energy load forecasting to predict demand by hour and region from weather, calendar and past load. Grid operators then schedule generation and buy power ahead of time. Errors cost money in both directions.
For a telecom operator, the same customer data supports churn and network fault prediction. One model scores subscribers for churn risk, while another flags cell sites likely to fail. The network side pairs naturally with automated ticketing, and generative AI in telecom shows where the two kinds of AI meet in daily operations. In practice, the KPI pairs retention among contacted subscribers with faults fixed before customers report them.
Public agencies have a quieter version. A benefits office or court system can run caseload forecasting by week and office. The forecast sets staffing and backlog targets rather than judging any one person, so it avoids the fairness risks of scoring individuals.
Benefits of Predictive AI Examples That Work
The benefits of predictive AI come from acting earlier and spending scarce attention where it counts. They show up in the KPI column of each table rather than in a model score, which is why the owner test matters so much.
The first gain is time. A forecast moves the work from assembling numbers to judging exceptions, as in the 9 a.m. funding call. In the treasury case later in this guide, that shift came with a 20% rise in workforce productivity and 35% fewer processing delays.
Fewer losses come next, because a fraud or maintenance score triggers a hold or a repair before the cost lands. Better ranking is the third gain. Security, IT and patient-risk models do not replace analysts or clinicians, yet they put the most likely cases at the top of a long queue.
The last benefit compounds over time. Once one example runs on clean, dated data with a monitored pipeline, the next example reuses much of that work. A cash-flow forecast, for instance, shares ledgers and calendars with a late-payment model, so the second pilot starts with its core data already prepared.
How a Predictive AI Example Goes From Data to Decision
Every example in the tables follows the same four steps, whatever the industry. The steps are short to describe and easy to rush, and rushing them is how pilots fail.
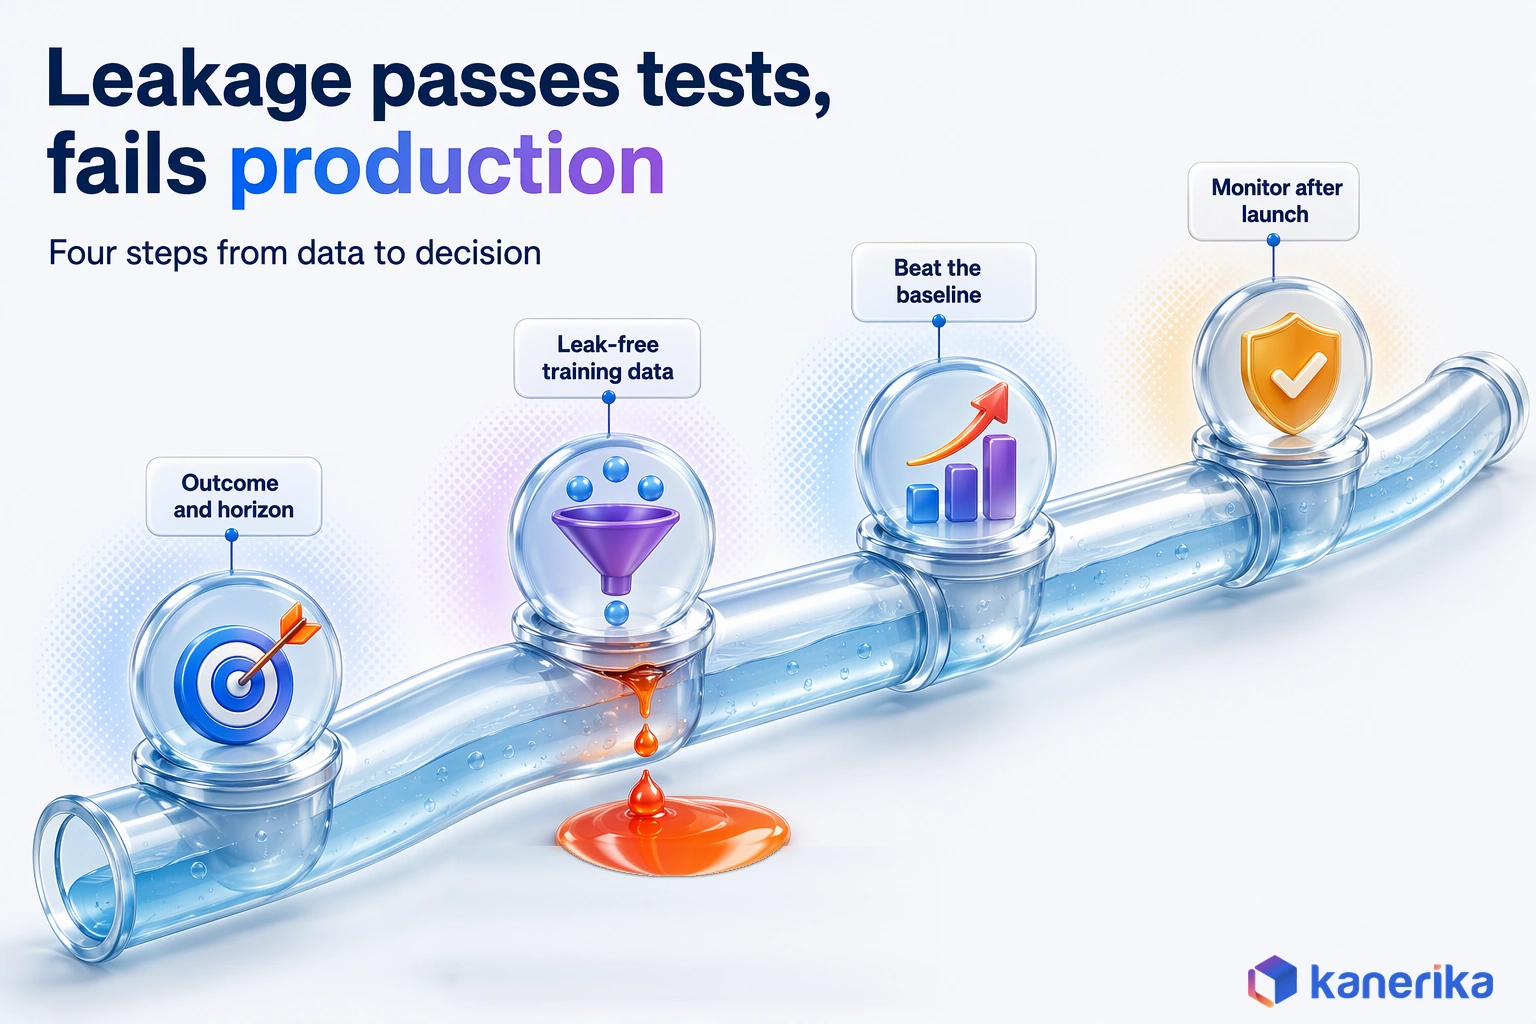
- Define the outcome and the horizon. Write down exactly what you predict and how far ahead, such as “invoice paid more than 15 days late, predicted at issue date.” The horizon must match the time the owner needs to act.
- Build leak-free training data. Use only information known at prediction time, and test on later periods than you trained on. Scikit-learn’s TimeSeriesSplit exists because ordinary cross-validation would train on future data and test on past data.
- Beat a baseline and set a threshold. Compare the model with the current method, such as last year’s average or the spreadsheet. Then pick the score where acting is worth the cost of a false alarm.
- Monitor after launch. Track accuracy, data drift and the business KPI every week. Agree in advance which level of decay triggers retraining or a rollback.
Step 2 causes the most silent failures. A late-payment model that sees a “days overdue” field during training will look brilliant in testing. It then fails in production, because that field does not exist on the day the invoice is issued.
Step 3 keeps the project honest. If the model cannot beat a simple rule on the same data, the rule wins and the project stops early. For deeper guidance on choosing an approach and rolling it out in stages, see AI predictive analytics.
Tools for Building and Tuning Predictive AI Examples
Most of the 15 examples run on ordinary tools, and the choice matters less than the discipline around them. The tools fall into two groups: open-source libraries your team codes against, and managed platforms that automate the model search.
On the library side, scikit-learn covers most tabular rows in this guide. It includes the gradient boosting, logistic regression and Isolation Forest models named in the starting-model column, together with time-ordered splits, calibration and threshold tuning.
Managed platforms trade some control for speed. Microsoft’s Azure Machine Learning automated ML handles classification, regression and time-series forecasting, and it tries many algorithms and parameters in parallel. Its forecasting options include holiday featurization, rolling-origin cross validation and configurable lags, so they suit rows 4, 6 and 12.
Kanerika Service
Predictive Analytics Services
Kanerika scopes, builds and runs predictive models on your own data, from readiness checks and pilots to monitored scoring inside the tools your teams already use.
Explore Predictive AnalyticsSetting the Decision Threshold From Costs
A score only becomes an action at a threshold, and the default is rarely the right one. Scikit-learn predicts the positive class when the probability exceeds 0.5, according to its threshold tuning guide. That cut-off ignores what each mistake costs you.
Take illustrative numbers for the late-payment example. Suppose a collector’s call costs $20 and a caught late payment saves $200. Acting then pays whenever the probability is above 20 divided by 200, or 0.1, far below 0.5. That rule holds only if the scores are calibrated, which is why trend 4 below matters.
Scikit-learn’s TunedThresholdClassifierCV searches for the threshold that maximizes a metric you choose, using internal cross-validation. The sketch below scores each threshold in net dollars and keeps time order in the splits, with the same illustrative costs.
from sklearn.ensemble import HistGradientBoostingClassifier
from sklearn.metrics import make_scorer
from sklearn.model_selection import TimeSeriesSplit, TunedThresholdClassifierCV

# Illustrative costs: $20 per call, $200 saved per caught late payment
def net_value(y_true, y_pred):
    caught = ((y_true == 1) & (y_pred == 1)).sum()
    calls = (y_pred == 1).sum()
    return 200 * caught - 20 * calls

# X, y: invoices sorted by issue date, features known at issue
model = TunedThresholdClassifierCV(
    HistGradientBoostingClassifier(),
    scoring=make_scorer(net_value),
    cv=TimeSeriesSplit(n_splits=5),
)
model.fit(X, y)
print(model.best_threshold_)
The scikit-learn guide adds one warning worth repeating: never tune the threshold on the same data you trained the model on. Whether you code the model or buy a platform, keep that split in place.
Predict, Then Act: Pairing Predictive Models With Agents and Generative AI
A prediction creates value only when something happens next, and the gap between score and action is where many examples stall. Pairing a predictive model with rules and an AI agent closes that gap.
Take a late-payment model in accounts receivable. Each morning it scores open invoices for the chance of paying more than 15 days late. A rule then sorts them, so low-risk invoices get a standard reminder and medium-risk ones get a personal email.
A collections agent drafts that email, pulling the invoice, the payment history and the account owner’s name. High-risk accounts, and any that involve a credit hold, go to a collector who reviews the draft and decides. The agent saves writing time, while the person keeps the decisions that shape the customer relationship.
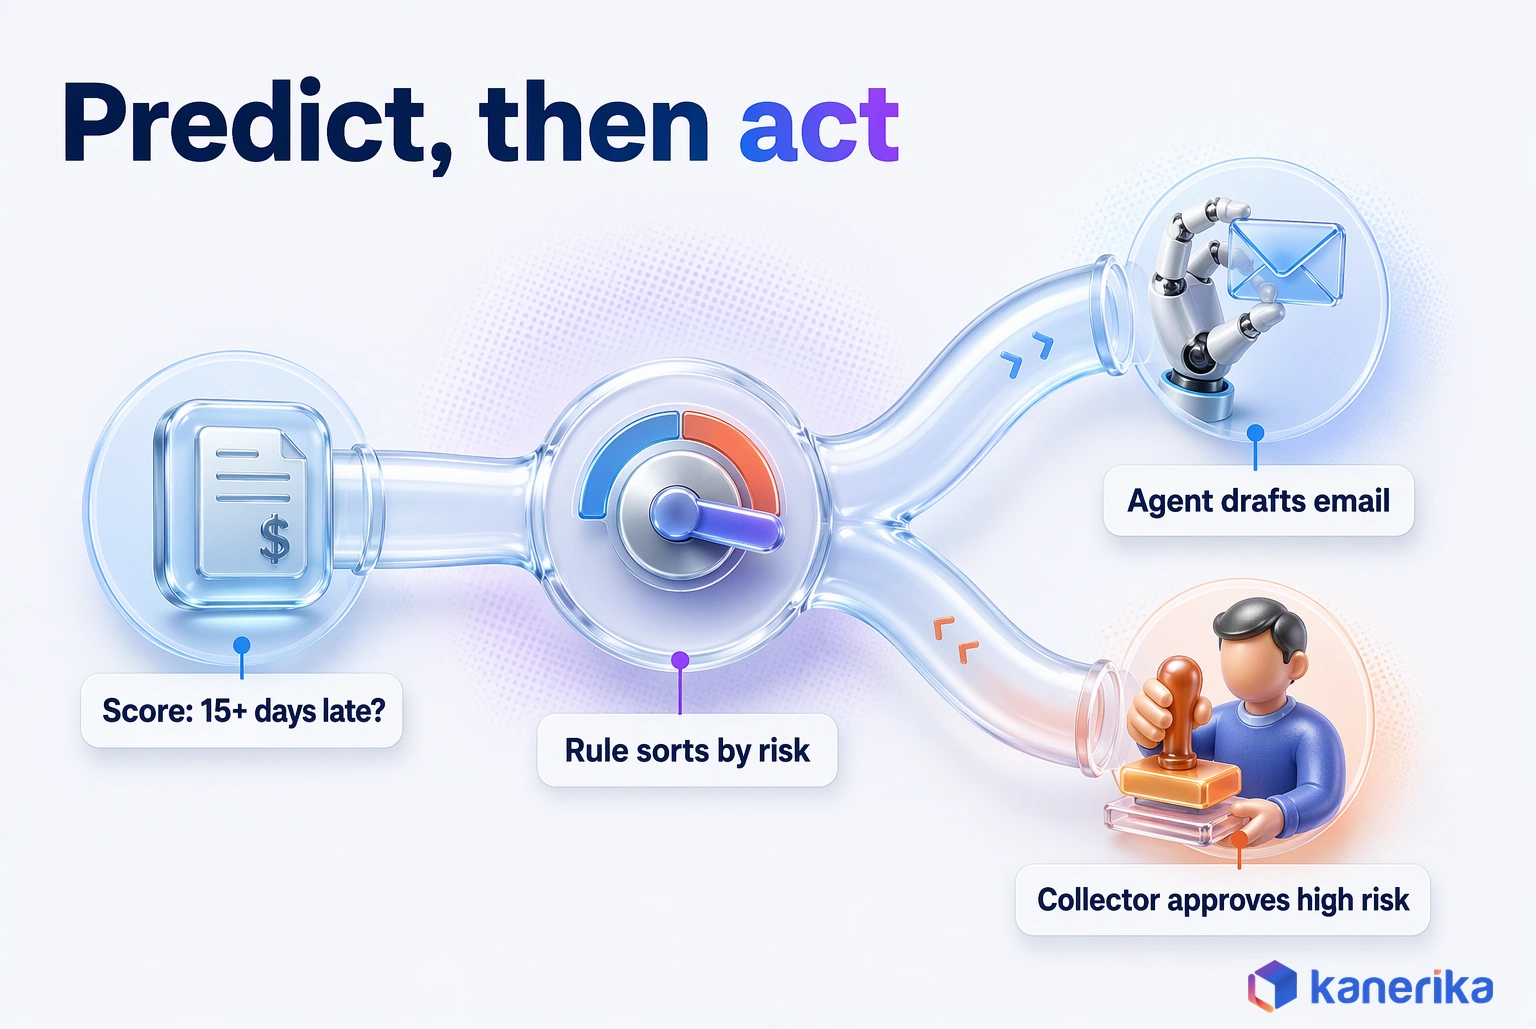
The pattern generalizes as score, threshold, drafted action and human approval for high-impact cases. It works because each part does what it is good at. The model ranks and the rule encodes policy, while the agent handles language and the person owns judgment.
Notice, though, what the generative part does not do. It does not decide who is risky, because a language model is not a calibrated forecaster. Keeping the score in a predictive model keeps it testable, explainable and auditable.
Predictive AI Trends That Change Which Examples Pay Off in 2026
A trend matters here only if it changes which example you fund or how you build it. Five shifts meet that bar in 2026, and each one touches specific rows in the tables above.
- EU AI Act high-risk timing moved. The European Commission lists credit scoring and CV sorting among high-risk uses. An amendment known as the AI Omnibus was agreed on May 7, 2026 and entered into force on July 27, 2026. It moved these Annex III rules to December 2, 2027, according to the Commission’s AI Act page. Row 3 and any hiring model are affected.
- US bank model risk guidance was replaced. The Federal Reserve issued SR 26-2 on April 17, 2026, together with the OCC and FDIC. It supersedes SR 11-7 from 2011 and SR 21-8, and it is most relevant to banks with more than $30 billion in assets. Banks running rows 3 and 5 should map their model inventory to it.
- Predict-then-act workflows. Agents that draft the follow-up raise the value of rows 1, 4 and 9, where the next step is a message or a booking.
- Calibrated probabilities instead of yes/no labels. A calibrated classifier’s 0.8 scores are right about 80% of the time, as the scikit-learn calibration guide explains. Calibration lets you set thresholds by expected value, which matters most for rows 3, 5 and 13. It is also what makes the cost-based threshold in the tools section work.
- Scoring inside the data platform. Running models where the data already lives cuts the delay between new data and a fresh score. That helps the near-real-time rows, such as 5, 9, 14 and 15.
Decision Framework: Which Predictive AI Example to Fund First
Choosing the first example is a portfolio decision. The right pick has the data, the owner and the payoff today, even if another example sounds more exciting in a steering meeting.
Five Gates Before You Fund a Pilot
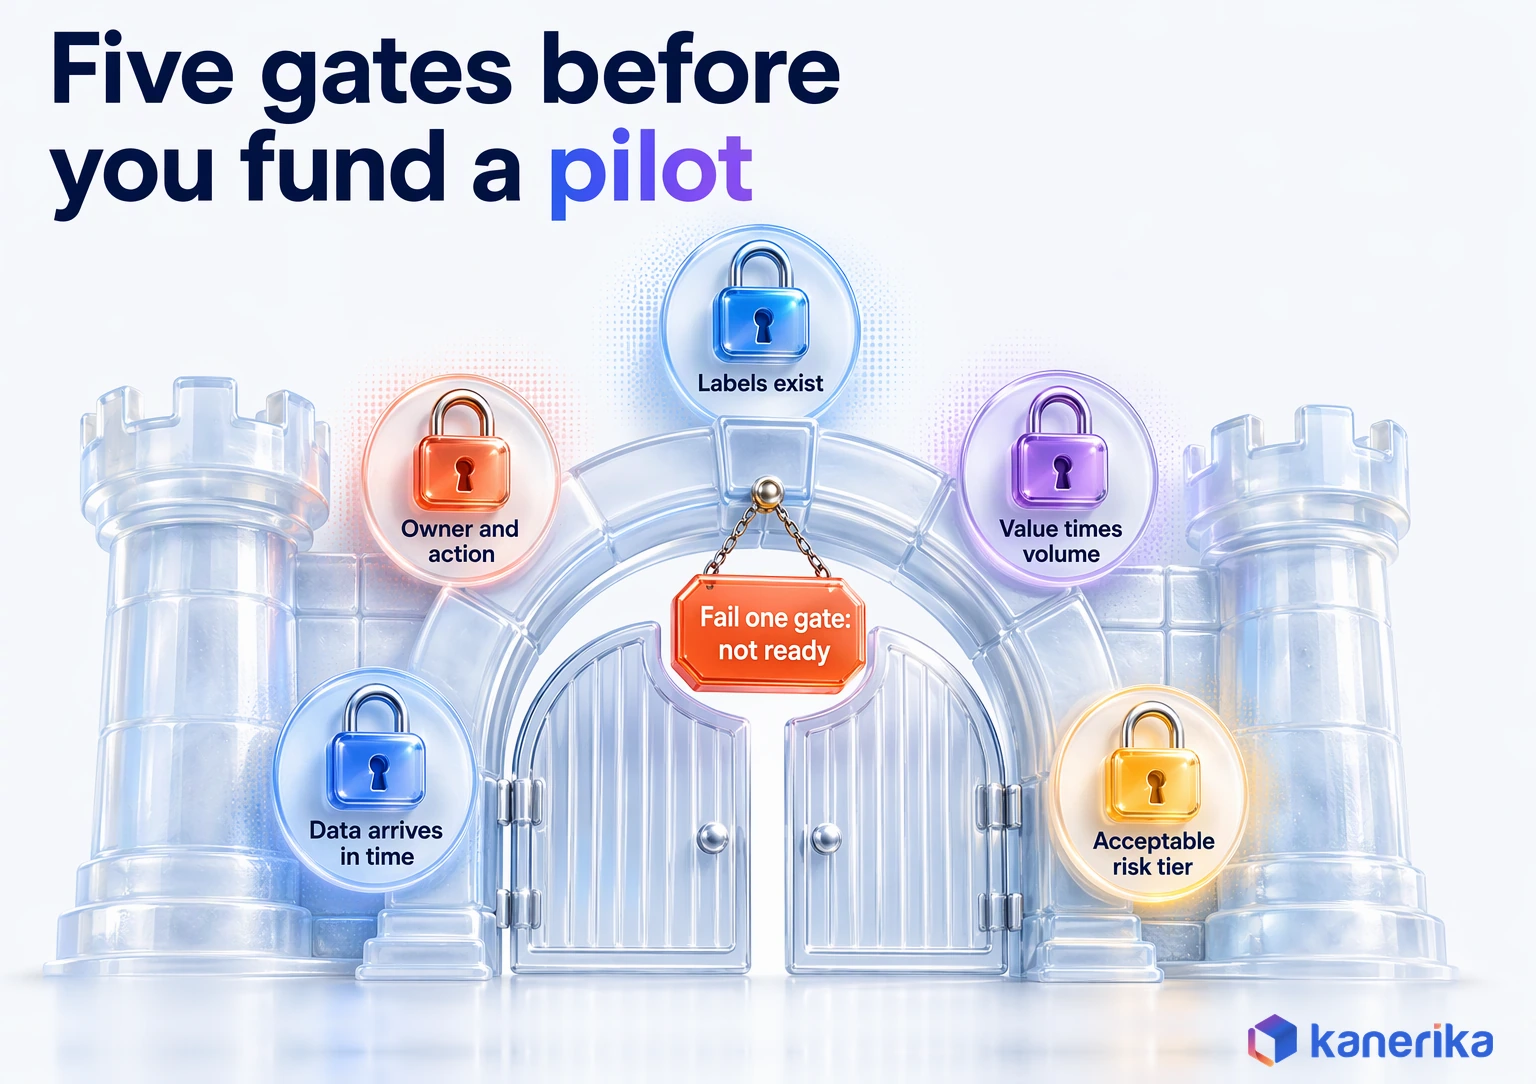
Run every candidate through five gates. An example that fails any one of them is not ready, however strong its business case looks on paper.
Table 5: Five gates for a predictive AI pilot
| Gate | Question to ask | Pass looks like | Fail looks like |
|---|---|---|---|
| 1. Labels exist | Do we hold dated records of the outcome? | History that covers full seasonal cycles and the cases you care about | Outcomes never recorded, or only for a small sample |
| 2. Action and owner | Who acts on the score, and how? | A named team with a set response for each score band | “The business will use it,” but nobody owns it |
| 3. Value times volume | What is one correct call worth, and how often does it happen? | A clear unit value and daily or weekly volume | Rare decisions that happen once |
| 4. Latency fits the horizon | Is the data fresh when the decision is made? | Data lands before the decision window opens | Data arrives once the decision is already taken |
| 5. Acceptable risk tier | Can we govern a wrong prediction? | Low or medium risk, or high risk when human review is in place | A high-risk decision, but no review planned |
Where Teams Trip on the Gates
Gate 1 is the one most often assumed rather than checked. Ask for the outcome field itself, with its dates, and count the positive cases in each year. A plant may hold years of sensor data yet only a dozen recorded failures, which is the trap row 8 warns about.
Gate 3 is where the arithmetic lives. A fraud model that catches one extra case a day can beat a churn model that saves one account a month. That stays true even when the churned account is larger, because volume multiplies small gains.
Gate 4 trips up more teams than they expect. Check when each source actually lands, not when it is scheduled to land. A weekly data feed cannot support a daily decision, however good the model is.
Picks by Enterprise Scenario
Different starting points lead to different first examples. The table pairs common enterprise situations with a pick, a delivery route and the move to avoid. Read it as a starting rule rather than a ranking. One company can fit two rows, such as a lender with a large finance team, and then the five gates break the tie.
Table 6: Which predictive AI example to start with, by scenario
| Scenario | Pick first | Build, buy or platform | Avoid |
|---|---|---|---|
| Finance team with years of ERP history | Daily cash-flow forecast (row 4) | Build on your data platform, although finance tools may cover the basics | Starting with a board-level revenue forecast before the basics work |
| Multi-site operations or retail | Demand forecast (row 6) or staffing forecast (row 12) | Buy a planning tool when your process is standard, but build when your drivers are unusual | Forecasting at a level nobody orders or schedules at |
| Asset-heavy plant | Predictive maintenance (row 8), but only if failure history exists | Platform route when sensor data already sits in the lakehouse | Buying sensors before checking failure labels |
| Regulated lender | Interpretable credit model (row 3) with human review | Build with model risk controls mapped to SR 26-2 | Opaque scores, because they cannot give specific decline reasons |
| Small labeled history | Anomaly detection (rows 5 and 15) | Platform or built-in tool features, so the build stays small | Supervised models trained on a handful of labels before more history exists |
For a side-by-side view of the products behind the build-or-buy column, see Kanerika’s guide to predictive analytics tools. The platform route sits between the two, because the model runs where the data already lives and your team still owns the features. Whichever route you choose, the five gates still apply before any money moves.
On-Demand Webinar
Custom vs Off-the-Shelf AI: Expert Insights on Choosing the Right Solution
Kanerika experts walk through when to build a custom model and when a packaged tool is enough, the same build-or-buy call the scenario table above asks you to make.
Watch the Webinar →Worked Example: Is a Cash-Flow Forecast Worth Funding?
Here is the cash-flow pick put through simple arithmetic. Every number below is an illustrative assumption for a mid-sized treasury, not a client result, so swap in your own figures.
Assume two analysts each spend three hours a day building the cash position, and the forecast cuts that to one hour each. That frees 2 hours, times 2 analysts, times 250 working days, or 1,000 hours a year. At a loaded cost of $75 an hour, that time is worth $75,000.
Assume also that better visibility lets treasury hold a cash buffer $10 million smaller. If that cash earns 4% instead of sitting idle, it returns $400,000 a year. On the cost side, assume $150,000 to build and $60,000 a year to run.
Table 7: Illustrative cash-flow forecast business case (assumptions, not client data)
| Line | Plan case | Half-accuracy case |
|---|---|---|
| Analyst time saved | $75,000 | $37,500 |
| Return on released cash | $400,000 | $200,000 |
| Year-one value | $475,000 | $237,500 |
| Year-one cost (build plus run) | $210,000 | $210,000 |
| Year-one net | $265,000 | $27,500 |
The half-accuracy column is the stress test. Even at half the planned gain, the model covers its first-year cost, and year two nets $177,500 once the build cost drops away. A sensible go/no-go rule is to fund the pilot only if the half-accuracy case still breaks even in year one.
AI Assessment
Is Your Organization Ready for a Predictive AI Pilot?
Score your AI maturity across data, governance and skills in a few minutes, and see which predictive use cases you can fund now and which need groundwork first.
Start Your AI Assessment →When Predictive AI Is the Wrong Tool
Some problems look predictive but are better solved another way. Spotting them early saves a pilot that was never going to pay off.
- No dated outcomes. If the result was never recorded, start capturing it now and revisit the model in a year.
- No lever to pull. A forecast nobody can act on, such as a price you cannot hedge, is just information.
- Events too rare to learn from. A handful of past failures will not train a reliable classifier, so use rules, engineering models or anomaly detection.
- A rule already works. If “reorder when stock falls below 40 units” performs well, a model adds cost and little gain.
- The outcome shifts faster than you can retrain. When the drivers change every few weeks, a model trained on last quarter keeps missing.
In each case the honest answer may be a dashboard, a business rule or better data capture. Those options cost less, and they often create the history a later model needs.
Risks, Governance and Common Mistakes
Governance for predictive AI should scale with the harm a wrong prediction can cause. A late-delivery estimate and a loan decline do not need the same controls, and treating them alike wastes effort on one and underprotects the other.
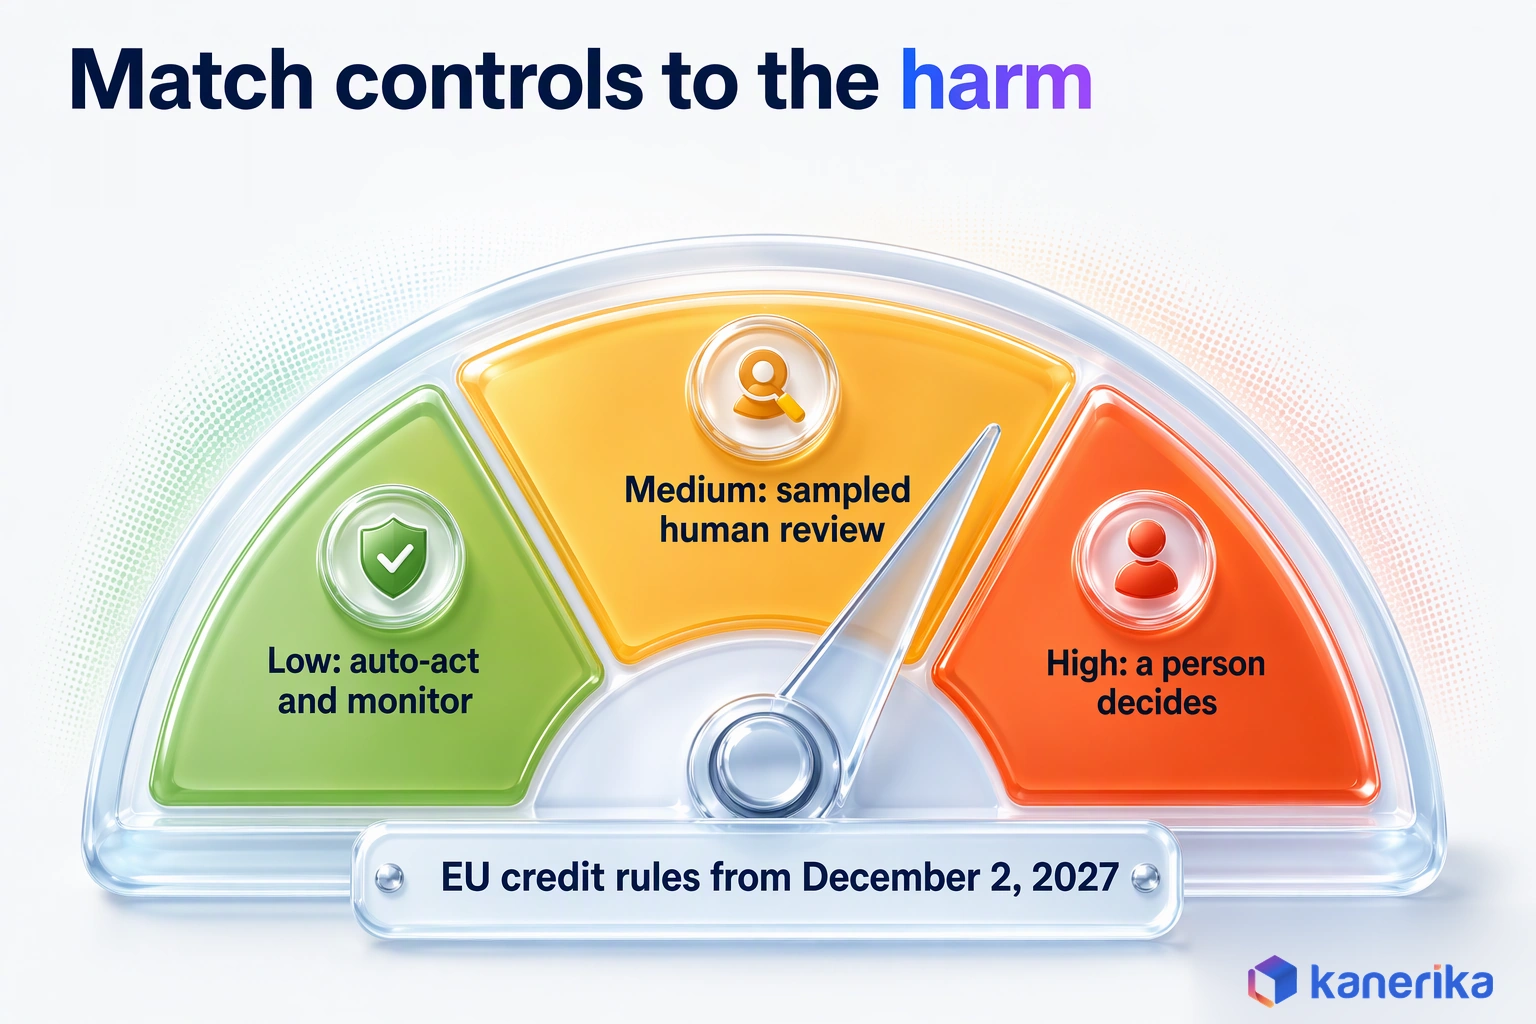
Table 8: Risk tier and the controls it needs
| Risk tier | Examples from this guide | Controls |
|---|---|---|
| Low | Demand forecast, IT incident prediction, contact volume | Automatic action within set limits, together with drift and accuracy monitoring |
| Medium | Lead scoring, supplier risk, claims triage | Score thresholds, sampled human review and logged overrides |
| High or regulated | Credit decisions, hiring, patient risk | A person makes the decision while the model supplies specific explanations, with subgroup testing and documented validation |
For regulated decisions, the rules are concrete. The EU AI Act, for instance, treats credit scoring and CV sorting as high-risk, with obligations from December 2, 2027. US consumer-credit rules also expect specific reasons for adverse decisions, even when the model behind them is complex.
NIST’s AI Risk Management Framework gives a voluntary structure for mapping, measuring and managing these risks across all three tiers. It was released on January 26, 2023, and NIST is now revising it under the White House AI Action Plan. Large US banks layer SR 26-2 on top for model validation and inventory.
Four mistakes cause most of the damage, whatever the tier:
- Leakage. Training on data that would not exist at prediction time, which inflates test accuracy.
- Uncalibrated scores. Reading a 0.9 as “90% likely” when the model was never calibrated.
- No owner. A score with nobody accountable for acting on it slowly gets ignored.
- No rollback. No plan for switching back to the old method when the model drifts.
Kanerika’s guide to responsible AI covers fairness testing, documentation and oversight in more depth.
How Kanerika Delivers a Predictive AI Use Case in Stages
Kanerika delivers predictive AI one use case at a time, with each stage earning the next. The aim is a model people use inside their daily tools.
Checklist
AI Governance Checklist
Check your model inventory, review steps and documentation against the controls risk teams and regulators expect before a credit, hiring or other high-risk model goes live.
Get the Checklist →- Use-case and data readiness check. We run the candidate through the five gates and check the data for labels, history and latency. That check also picks the model family, so scarce fraud labels point to unsupervised methods such as Isolation Forest.
- Baseline and pilot in one workflow. We beat the current method on one decision, with a clear KPI and a holdout group.
- Integration where people already work. Scores land in the portal, ERP or CRM the team already uses, not in a separate app. In the treasury case below, the forecast sits inside the bank’s Daily Funding Portal.
- Monitoring and expansion. We track drift and the business KPI, then reuse the data and pipelines for the next example.
The two client results in this guide show the range of outcomes. The insurer’s fraud models cut financial losses by 33% and risk exposure by 25%, while the treasury forecast lifted workforce productivity by 20%.
Kanerika’s predictive analytics services cover all four stages. The wider AI services team adds agents where a score needs a follow-up action.
Case Study: Daily Cash Forecasting for a Bank Treasury
A leading banking institution running daily funding operations forecast its cash positions by hand. Analysts pulled data from fragmented systems into spreadsheets, and surplus cash often sat idle.
Kanerika built a predictive model of daily inflows and outflows and embedded it in the bank’s Daily Funding Portal. It automated the split between cash to retain and surplus cash, and it gave the team one input layer instead of several.
The bank treasury forecasting case study reports three results:
- Workforce productivity rose by 20%.
- Processing delays fell by 35%.
- Use of AI tools and data rose by 40%.
Case Study
20% Productivity Lift for Bank Treasury with AI Forecasting
A leading banking institution replaced manual cash forecasting with a predictive model inside its Daily Funding Portal, cutting processing delays by 35% and lifting workforce productivity by 20%.
Read the Case Study →Which Predictive AI Example Should You Start With?
Start with the example that has labeled history, a decision made every day and an owner who wants the help. For most enterprises that means a finance or operations forecast, such as daily cash, item demand or contact-center staffing.
Leave credit, hiring and patient-risk models until review and explanation processes are in place. Treat churn, fraud and maintenance as strong second choices once the first pilot proves the pattern.
Of all the predictive AI examples in this guide, the right place to start is the forecast that changes tomorrow morning’s decision.
Frequently Asked Questions
What are some examples of predictive AI?
Common predictive AI examples include customer churn scoring, lead scoring, credit risk, cash-flow forecasting and fraud detection. Operations teams use demand forecasting, inventory planning, predictive maintenance and delivery-delay prediction. Other examples are contact-center staffing, patient deterioration alerts, security alert ranking and IT incident prediction. Each one predicts a dated outcome that a named owner can act on in time.
What does predictive AI mean?
Predictive AI means software that learns from historical data to estimate a future outcome. It returns a probability or a number, such as the chance an invoice is paid late or next week’s demand for an item. A person or a system then acts on that estimate before the outcome happens, which is what makes it useful.
What is the most used predictive model?
There is no official count, but linear and logistic regression are standard starting points because they are simple, fast and easy to explain. Gradient-boosted trees are a frequent choice for tabular data when more accuracy is needed. Time-series models lead in forecasting. The right model depends on the outcome, the data and how much explanation is required.
Which predictive AI use case should a company start with?
Start with a use case that has labeled history, a decision made every day and an owner who wants help. For most companies that is a finance or operations forecast, such as daily cash, demand or contact-center staffing. Leave credit, hiring and patient-risk models until review and explanation processes are ready to support them.
How much data do you need for predictive AI?
There is no fixed number, but you need enough dated outcomes to cover normal cycles and the cases you care about. Seasonal forecasts need several seasons of history. Classifiers need enough examples of the rare outcome, such as failures or frauds, not just a large number of total rows. When labels are scarce, start with anomaly detection instead.
Can predictive AI make decisions automatically?
Yes, for low-risk decisions such as reorder quantities or alert ranking, a model can act within set limits while teams monitor drift and accuracy. Medium-risk decisions need thresholds and sampled human review. High-risk or regulated decisions, such as credit, hiring or patient care, should keep a person making the final call with a clear explanation.
How accurate are predictive AI forecasts?
Accuracy depends on the data, the horizon and how stable the outcome is, so no general figure applies. The useful test is whether the model beats your current method over the same period. Check calibration too. A well-calibrated model’s 0.8 scores come true about 80% of the time, which makes thresholds and risk pricing dependable.
What is the difference between generative AI and predictive AI?
Predictive AI scores or forecasts one specific outcome, such as default risk or demand. Generative AI creates new content, such as text, code or images. Neither is better in general. Predictive AI suits decisions that need a testable, calibrated number, while generative AI suits language tasks. Many workflows use both, with the score deciding and an agent drafting.
Is ChatGPT generative or predictive AI?
ChatGPT is generative AI. It produces new text by predicting likely next words, but its purpose is to generate content rather than to forecast a business outcome. A predictive AI model instead estimates something specific, like churn or failure risk, and is tested against what actually happened. The two can work together in one workflow.
How is predictive AI used in different industries?
Banks use predictive AI for credit risk, fraud and cash forecasting. Retailers forecast demand and set inventory, while manufacturers predict equipment failure and defects. Insurers triage claims, utilities forecast electricity load and telecom operators predict churn and network faults. Hospitals use deterioration scores with clinician review, and IT teams rank security alerts and predict outages.
What are some predictive AI models?
Common predictive AI models include logistic regression, decision trees, random forests and gradient-boosted trees for tabular data. Time-series models handle forecasts such as demand and cash flow. Survival models estimate time to failure or churn. Isolation Forest and autoencoders detect anomalies when labels are scarce. Neural networks suit images, text and long sensor streams.
Which is the best predictive AI?
No single product or model is the best predictive AI. The best choice is the one that fits the decision, the data and the people who act on it. For tabular business data, gradient-boosted trees are a strong default to test first. Judge any option on whether it beats your current method on a clear KPI.
What is predictive intelligence?
Predictive intelligence is a broader term for using predictive models inside business workflows, so forecasts reach the people who make decisions. It usually combines data pipelines, models and dashboards or alerts. In practice it describes the same idea as applied predictive AI, with more emphasis on delivering each forecast where the work actually happens.
What is the difference between predictive AI and analytical AI?
Analytical AI looks at data to explain what happened and why, through reports, segmentation and root-cause analysis. Predictive AI goes a step further and estimates what will happen next. Analytics often comes first, because it shows which outcomes matter and whether the data is clean. Predictive models then build on that same data to forecast those outcomes.
What is the difference between predictive AI and discriminative AI?
Discriminative AI is a model type that learns the boundary between classes, such as fraud and not fraud. Predictive AI describes the business use, which is estimating a future outcome. Most predictive AI systems use discriminative models like logistic regression or gradient-boosted trees. The terms overlap, but one names a technique and the other names a purpose.