TL;DR
Predictive analytics in supply chain pays off fastest on demand if stockouts hurt, or on supplier delays if freight runs late. Seven use cases cover most of the value, from demand and stock levels to supplier delays, breakdowns and returns. Each one turns order, stock, shipping and supplier records into a forecast a planner can act on. Test every model against the rule you use today. Use built-in forecasting tools for standard needs, and custom models where your network is different. Fund a first pilot only when it has an owner, a known cost to beat and history that records what really happened.
Key Takeaways
- A supply chain prediction is useful only when it is tied to a named decision, a time horizon and an owner who can act on it.
- Seven use cases carry most of the value; demand forecasting and supplier lead-time risk usually pay off first.
- Data known at decision time, censored demand and clean master data decide accuracy more than the choice of algorithm.
- Judge every model against the rule you use today, and use bias and MASE rather than MAPE alone.
- Start with one bounded pilot that has a named owner, a priced baseline and a control group, then scale by decision pattern.
- Kanerika’s LSTM demand forecasting work for a perishable foods producer cut stockouts by 30% and order fulfillment time by 20%.
A Late Container Becomes an Inventory Decision
A planner at a home goods distributor opens her exception queue on a Monday. One line stands out: a container of kitchen storage bins from an Asian supplier now looks likely to arrive nine days late.
The ship has not even sailed yet. Still, the model saw the supplier’s recent late handoffs to the forwarder, a congested origin port and a booking that slipped twice. So it flagged the risk three weeks before the planned arrival date.
That lead time changes the options, because she still has time to act. So she splits the purchase order and pulls part of the quantity from a domestic supplier at a higher unit cost. She also moves safety stock toward the two stores that sell the bins fastest. Without the warning, the first sign of trouble would have been empty shelves instead.
That is the real job of predictive analytics. It does not run the supply chain on its own. It gives the decision owner enough notice and confidence to act while acting is still cheap. The rest of this guide covers where that works, how the models are built and judged, and also how to pick your first use case.
What Predictive Analytics in Supply Chain Means (and Where It Stops)
Predictive analytics in supply chain uses historical and live operating data to estimate what will happen next. The point is lead time, so a decision can still change. The output is a forecast, a probability or a predicted time. For example, a weekly demand forecast for each product and store is one output, while the chance that a purchase order lands late is another.
A prediction only earns its cost when three things are named up front. First comes the decision it feeds, such as how much to reorder. Next is the horizon, meaning how far ahead the answer must arrive to be useful. Finally, there is the owner, the planner or buyer who will act on it.
It also has limits worth stating plainly. For instance, a model can tell you a supplier is likely to be late. But it cannot tell you whether paying for air freight is worth it. That trade-off belongs to prescriptive tools and, in the end, to people, because cost and service priorities are business choices.
Descriptive, Predictive and Prescriptive Analytics Compared
The three kinds of analytics answer different questions, although most teams need all three in sequence. Our guide to supply chain analytics also covers the wider family in more depth. Our comparison of business intelligence vs predictive analytics explains where reporting ends and forecasting begins.
| Type | Question it answers | Typical output | Supply chain example |
|---|---|---|---|
| Descriptive | What happened? | Reports, dashboards, KPIs | Fill rate by distribution center last quarter |
| Predictive | What is likely to happen? | Forecasts, probabilities, predicted dates | Demand for each SKU and location over the next eight weeks |
| Prescriptive | What should we do about it? | Recommended actions within constraints | Order quantities that meet a service target at the lowest cost |
Checklist
Data Analytics Checklist
18 actions across decision mapping, data readiness and predictive analytics. Use it to find the gaps before you fund a predictive supply chain pilot.
Get the Checklist →Why Predictive Analytics in Supply Chain Matters in 2026
Supply chains now face shocks that historical averages do not capture well, especially in trade. US goods trade with China fell to $414.6 billion in 2025 from $583.6 billion in 2024, according to the US Census Bureau. That is a drop of about 29%, while imports alone fell from $440.3 billion to $308.7 billion.
A shift that size moves sourcing to new suppliers and new lanes. Their lead times have little history, so an average transit time from two years ago stops being a safe planning input. Prediction helps here because it can weigh recent signals more heavily than old averages.
Leaders also see the same pressure. The 2026 MHI and Deloitte report found that economic uncertainty, inflation and geopolitical risks top the list of trends for the year. In the same survey, 48% of respondents expect AI to have a significant or greater impact. That figure is up 25 points since 2025, and 24% also call AI transformational.
Budgets are following too. The report found that 56% of respondents expect to raise supply chain innovation spending. Of those surveyed, 52% plan to invest over $1 million and 17% over $10 million. Spending on AI is rising faster than the data foundations that make forecasts trustworthy, so the first dollars should go to a backtested use case.
What the Upside Looks Like
The upside can be large when the basics are in place. A 2022 McKinsey analysis estimates that AI-driven forecasting can cut errors by 20 to 50%. It can also reduce lost sales from product unavailability by up to 65%. No newer primary benchmark with a firm range has replaced it as of 2026. Read those figures as four-year-old estimates of what is possible, then test them against your own backtest rather than treating them as a promise. The table below shows where the gains tend to appear first.
| Benefit | Metric it moves | Where it shows up |
|---|---|---|
| Earlier warning of shortfalls | Stockout rate, fill rate | Stores, distribution centers, customer orders |
| Less excess stock | Days of inventory, write-offs | Working capital, warehouse space |
| Fewer expedites | Premium freight spend | Transport budget |
| More reliable promises | On-time in full, ETA error | Customer service, contracts |
| Less unplanned downtime | Asset availability | Plants, fleets, material handling |
7 Predictive Analytics Use Cases in Supply Chain
Each use case below predicts something different, so each needs different data and changes a different decision. The table gives the short view, then the sections after it explain how each one works in practice. For a broader catalog of AI applications beyond prediction, see our guide to AI in supply chain.
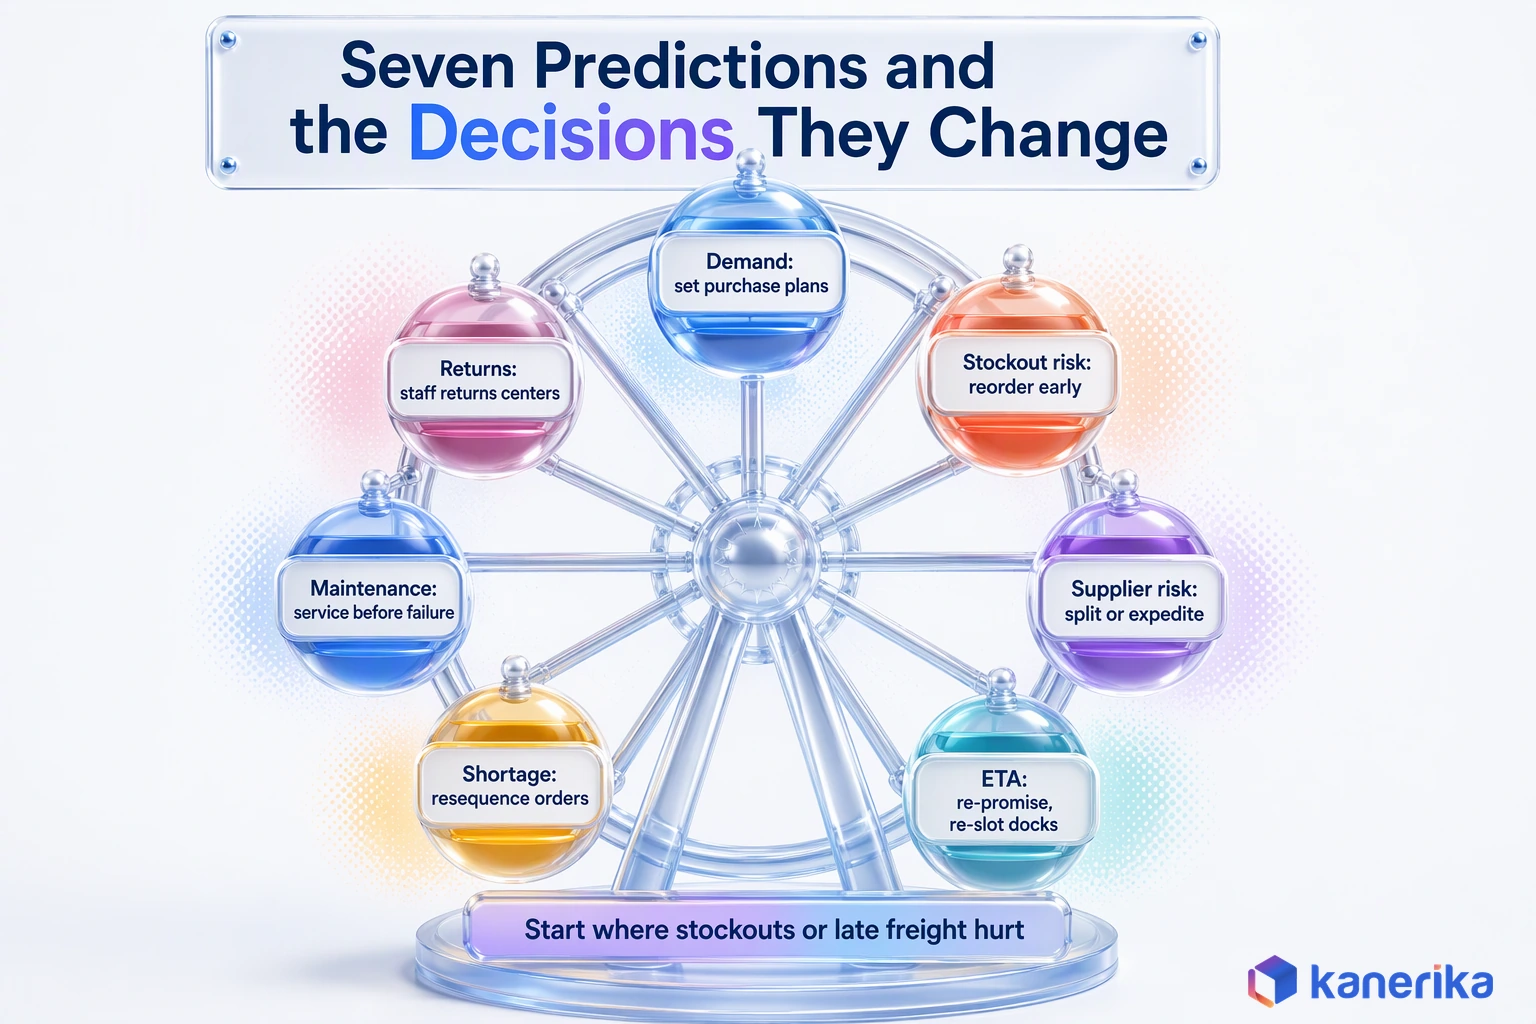
| Use case | Prediction target | Minimum data | Action enabled | Business metric | Caveat |
|---|---|---|---|---|---|
| Demand forecasting | Units per SKU, location and week | Sales history, promotions, prices, calendar | Set production and purchase plans | Forecast bias, fill rate | Sales understate demand when shelves were empty |
| Replenishment and stockout risk | Chance of a stockout before the next order arrives | Inventory positions, open orders, lead times | Reorder earlier or rebalance stock | Stockout rate, days of inventory | Needs accurate on-hand counts |
| Supplier lead-time risk | Days late per PO line | PO history, receipts, supplier events | Split orders, expedite, switch source | On-time receipts, expedite cost | New suppliers have little history |
| Transportation ETA | Arrival time per shipment | Carrier milestones, GPS, port and weather data | Re-promise, re-slot docks, reroute | ETA error, detention fees | Milestone feeds are often late or missing |
| Production disruption | Chance a material shortage stops a line | BOMs, schedules, inbound status | Resequence orders, substitute parts | Schedule adherence | BOM and routing data must be current |
| Predictive maintenance | Time to failure for an asset | Sensor readings, work orders, failure logs | Service before failure | Unplanned downtime | Failures are rare, so labels are thin |
| Returns forecasting | Return volume and reason by item | Returns history, product and order data | Staff returns centers, plan resale | Recovery value, handling cost | Returns lag sales by weeks |
Demand Forecasting and Demand Sensing
Demand forecasting estimates how many units of each product will sell in each place over the coming weeks or months. It is the most common starting point because almost every downstream plan depends on it, from production runs to purchase orders.
Two horizons matter here. A monthly forecast several months out feeds capacity and supplier commitments. Demand sensing, by contrast, works on a much shorter horizon, often days, and uses recent orders, point-of-sale data and weather to correct the near-term number. For a deeper look at the methods, read our post on AI in demand forecasting or the demand forecasting glossary entry.
The trap is history that hides real demand. When a product was out of stock, sales show zero even though shoppers wanted it. So a model trained on raw sales learns to under-forecast your best sellers.
Inventory Replenishment and Stockout Risk
Replenishment models predict whether stock will run out before the next delivery lands. They combine the demand forecast with on-hand inventory, open orders and the expected lead time, and score the risk for each item and location.
The output is usually a ranked list rather than a single number. For instance, a buyer sees the 50 items most likely to stock out in the next two weeks. She then decides which to reorder early or move between sites. Our guide to AI inventory management covers the replenishment side in more detail.
Inventory accuracy limits everything here. If the system thinks there are 200 units on the shelf but there are 120, no model will save the forecast.
Case Study
55% Fewer Stockouts with Real-Time Inventory Analytics
Kanerika helped a large fuel distributor cut stockouts 55% and improve forecasting accuracy 29% with Power BI real-time analytics.
Read the Case Study →Supplier Lead-Time and Delivery Risk
Supplier risk models predict how late each purchase order line will be. They learn from past receipts, the supplier’s recent behavior, the product, the lane and the time of year. The opening story is this use case: a predicted nine-day slip seen three weeks out.
Planners use the score to decide which orders need attention. For example, a high-risk line on a critical part might justify a call to the supplier, a split order or a second source. A low-risk line, by contrast, can be left alone, so the team stops chasing every PO.
New suppliers are the weak spot. Since they have little history, the model should fall back on lane and category averages and say so, rather than show false confidence.
Transportation ETA and Delay Prediction
ETA models predict when a shipment will actually arrive, rather than the date on the booking. They use carrier milestones, GPS pings, port congestion, weather and historical dwell times at each stop.
A better ETA pays off at the receiving end, because warehouses can schedule dock doors and labor around real arrivals. Customer service can also re-promise orders before the customer calls. Our post on AI in transportation goes further into fleet and carrier use cases.
The common failure is patchy data. Carrier milestone feeds often arrive late or not at all, so the model has to cope with gaps and flag when it is guessing.
Production Disruption and Material Shortage
For manufacturers, the costly event is a line stopping because one component did not arrive. Disruption models combine inbound shipment risk with the bill of materials and the production schedule. They predict which orders are likely to be short of parts.
Picture a plastics molder on a Thursday afternoon. The model sees that a resin shipment has slipped at the origin port. It flags three work orders that will be short of resin next Tuesday. The scheduler pulls forward a product that does not use resin, so the line keeps running while the shipment catches up.
The warning only helps if it lands before the schedule is frozen. That is why the horizon for this use case is set by the plant’s scheduling cycle, not by the shipment date. A shortage seen two days out still leaves room to resequence jobs or approve a substitute part. One seen at the start of a shift leaves only overtime or a stopped line.
The prediction is only as good as the BOM and routing data behind it, so plant data quality comes first. A BOM that still lists a retired part will flag false shortages, and schedulers soon learn to ignore the alerts. Our guide to business intelligence for manufacturing covers the reporting layer this work sits on.
Predictive Maintenance for Plant and Fleet Assets
Predictive maintenance estimates when a machine, a conveyor or a truck is likely to fail. The model matches sensor readings such as vibration, temperature and pressure against past work orders and failures to spot early warning patterns.
In a supply chain, the value is continuity. For example, a forklift fleet or packing line that fails at peak season creates a backlog that reaches customers.
Scoring often happens close to the machine. Our post on edge AI explains how models run on devices at the plant or in the vehicle. For the wider factory picture, see AI in manufacturing and the predictive maintenance glossary entry.
Failures are rare, so labels are thin. That is why many teams start with anomaly detection and add failure prediction once enough events are logged.
Returns Forecasting and Reverse Logistics
Returns forecasting predicts how many items will come back, when, and why. Product type, price, sales channel, size and past return rates all carry signal.
The volumes are large enough to plan for. In its October 2025 report, the National Retail Federation estimated that 15.8% of annual US retail sales would be returned in 2025, about $849.9 billion. Retailers in the same survey expected 17% of holiday sales to come back, and 43% planned to hire seasonal staff to handle them.
Take an illustrative apparel retailer whose returns peak two to four weeks after the holiday, so the returns center books extra staff for early January. The forecast also tells planners which sizes and styles will come back in resaleable condition. Planners can hold that stock for resale rather than reorder it.
Retail is where this matters most, and our guide to predictive analytics in retail covers the store and e-commerce side. One timing issue catches teams out: returns lag sales by weeks, so the latest sales data is never fully reflected in return rates.
How Predictive Analytics Works: From ERP Data to a Planner Decision
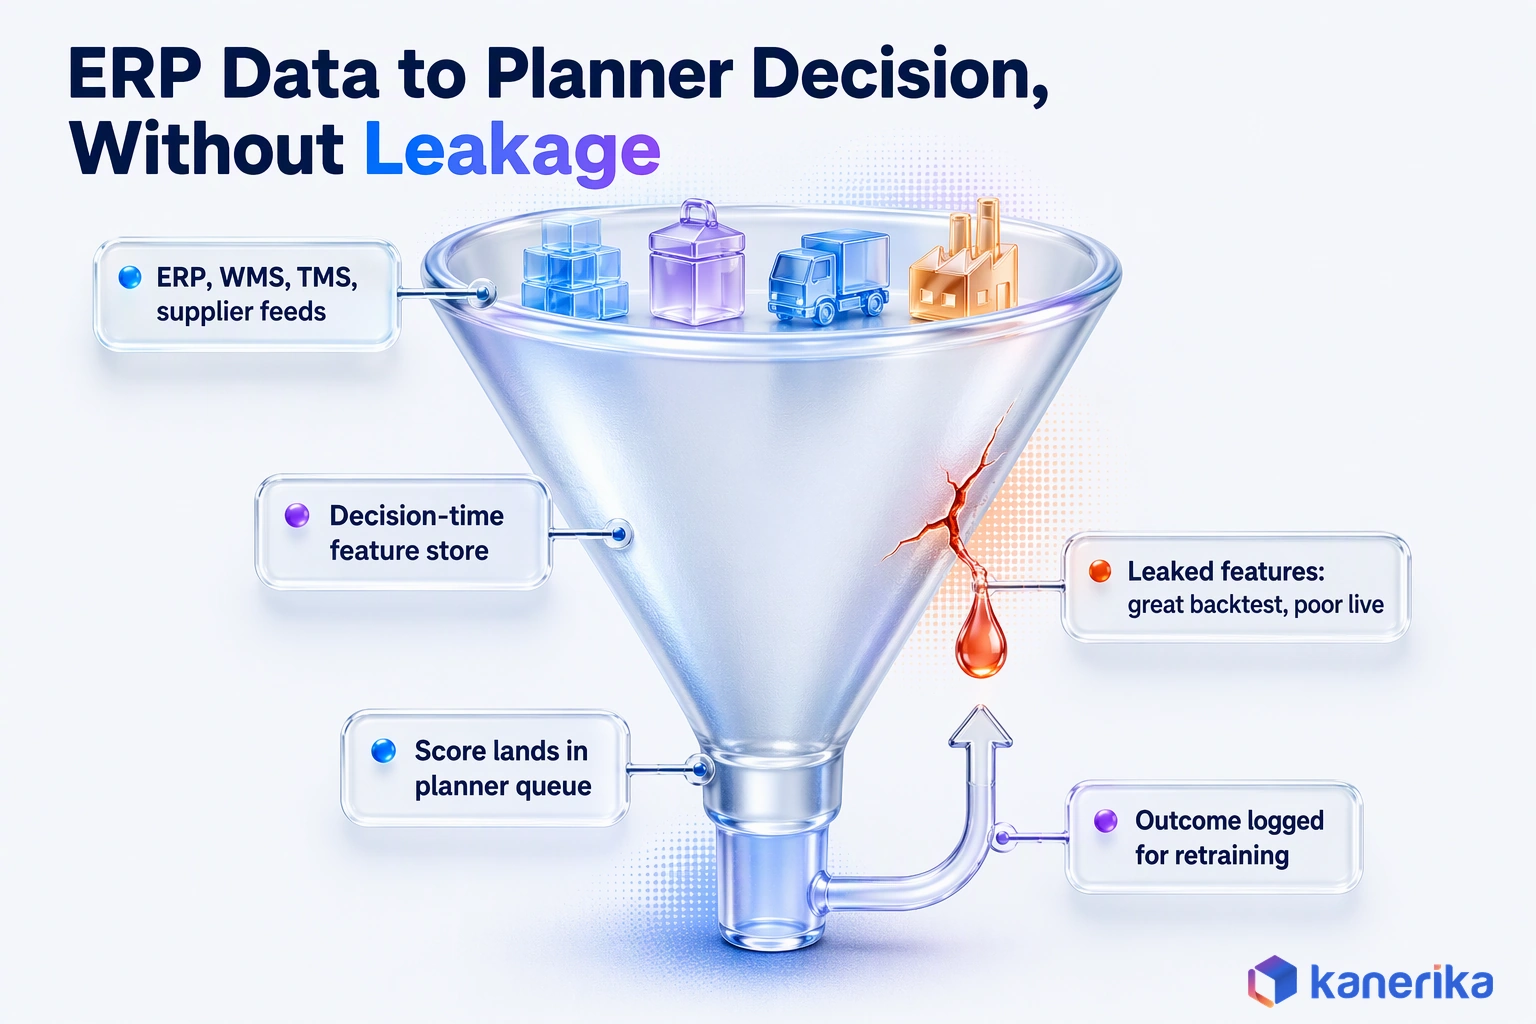
Every use case above follows the same path. First, data from the ERP, warehouse system, transport system and supplier feeds is joined into a feature store. Each feature is kept as it looked at each decision point.
Next, a model scores that data, and the result lands in a planner’s queue or back in the ERP. The outcome is then logged so the model can be judged and retrained.
The four steps below are where most projects succeed or stall, but none of them is about picking the cleverest algorithm.
Define the Decision, Grain and Horizon
Start with the decision, then pick the grain that matches it. A replenishment decision needs a forecast by SKU, location and week. A supplier decision needs a prediction per PO line, while a transport decision needs one per shipment.
The horizon then follows from the lead time. If a supplier needs six weeks to change an order, a two-week forecast is useless for that decision, however accurate it is.
Agree on the cost of being wrong in each direction too. For a perishable product, over-forecasting means waste, whereas for a critical spare part, under-forecasting means a stopped line. Those costs decide how the model should lean.
Build a Decision-Time Data Foundation
The most common silent error is leakage, which means training a model on information that was not known when the decision was made. For example, a receipt date entered after delivery can make a backtest look far better than live results will be. The fix is to store each feature as it was known at that moment, so you can ask what the planner could have seen.
Demand data also needs repair, since sales during stockouts understate true demand, so flag those periods and either exclude them or estimate the lost sales. Master data matters just as much, since product hierarchies, units of measure and supplier IDs must match across systems.
Data silos are the practical blocker here. Sales usually sit in one system, inventory in another, and supplier events arrive by email or EDI. As a result, a shared, governed data layer is usually the first real project. Our data engineering services page explains how Kanerika builds one. For wider context, see our post on big data and predictive analytics.
Backtest Against a Baseline and Pick the Right Error Metric
A model is only useful if it beats what you already do. So the test is a backtest that replays the past as if the model had been live, using only data known then. Work through it in this order, because each step builds on the one before:
- Reproduce the current rule. Rebuild today’s method, such as a moving average or a planner’s weeks-of-cover rule, so the model has a fair baseline.
- Run a rolling-origin backtest. Train on data up to a cutoff, forecast the next window, then move the cutoff forward and repeat. This is time series cross-validation, and it shows how the model behaves across seasons.
- Segment the results. Report accuracy by horizon, product class and location, because a good average can hide poor results on your most important items.
- Measure bias and scaled error. Bias shows whether the model leans high or low. MASE compares errors to a naive forecast, so a value under 1 means the model beats the naive method.
- Avoid MAPE alone on sparse items. MAPE is infinite or undefined when actual demand is zero, so it breaks on intermittent and slow-moving items.
- Check the intervals. If the model says it is 90% sure, about 90% of actuals should fall inside its range.
Only after the model beats the baseline in this test should it reach a planner. Results that look strong on one random split, however, often fade in a rolling backtest.
Talk to Kanerika
Want a Fair Backtest of Your Forecast?
Bring one SKU family and your current ordering rule. Kanerika will help rebuild the baseline, run a rolling backtest and show where a model would change the order.
Schedule a Demo →Put Predictions Where Planners Already Work
A forecast nobody sees changes nothing. So the best place for a prediction is inside the tool the planner already uses, often as a ranked exception queue. Planners should be able to override a number, and every override should also be logged with a reason. Over time, those logs show where the model is weak and where the planner knows something the data does not.
Keep a fallback too. When a data feed fails or the model drifts, the system should drop back to the old rule and say so.
Generative AI and agents now sit on top of this layer in some teams. They explain a forecast in plain language or route an exception to the right buyer. Still, they depend on the prediction underneath. Our post on generative AI in supply chain covers those uses.
Which Model Fits Which Supply Chain Prediction
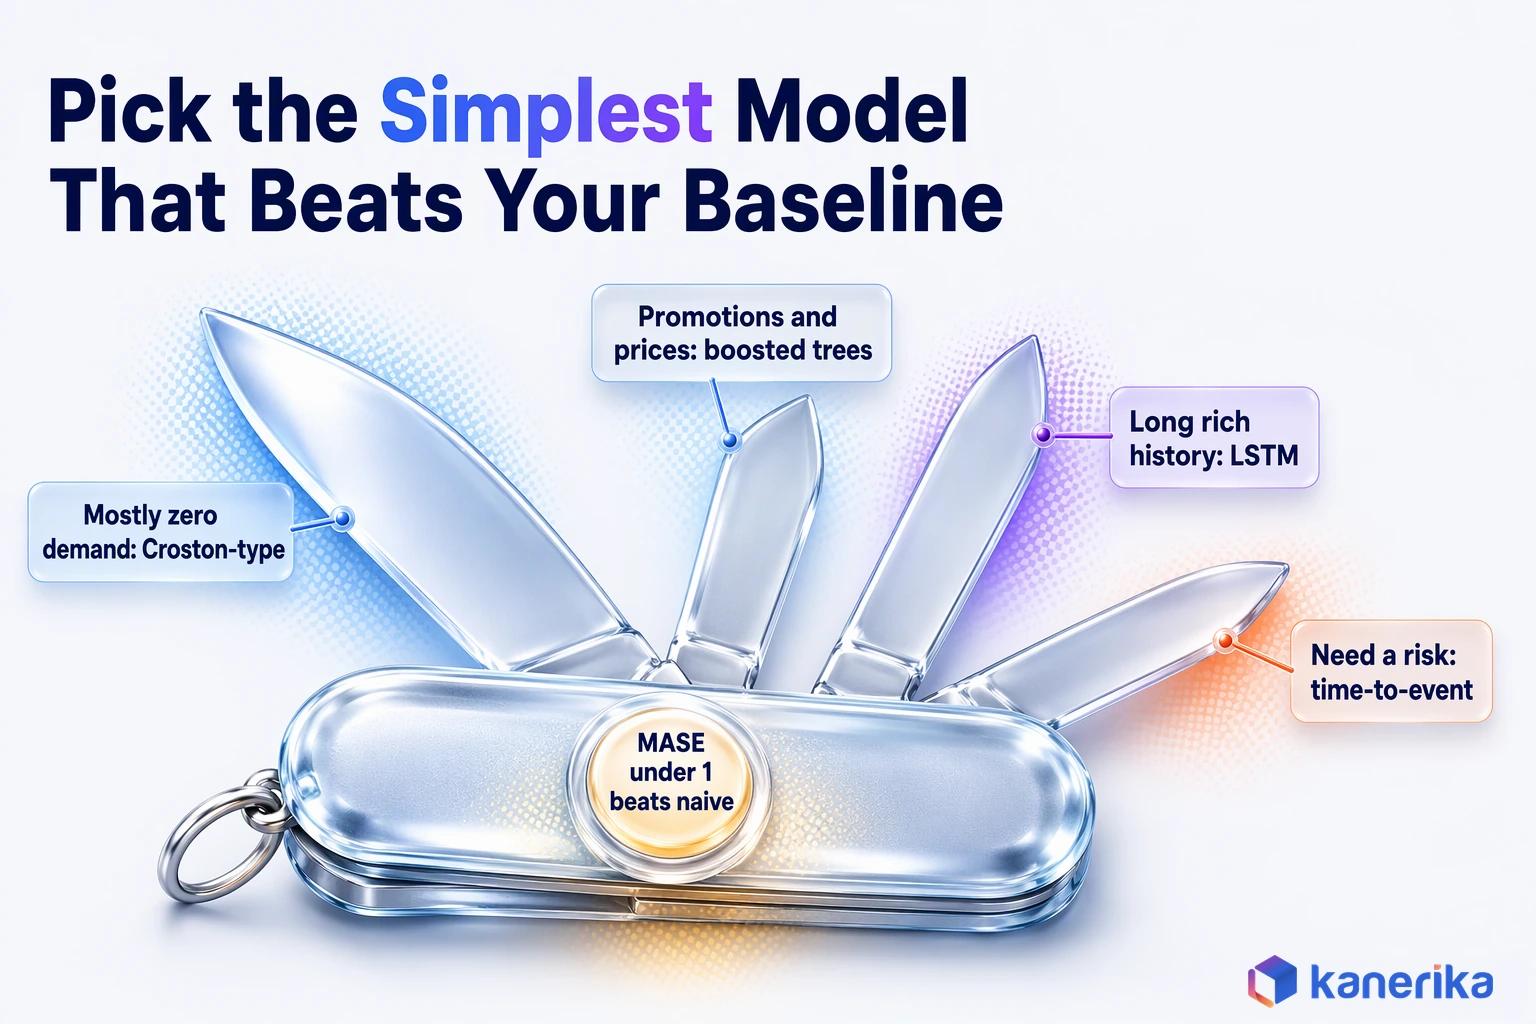
No single model wins every supply chain problem. The right choice depends on how much history you have and how regular the demand is. It also depends on whether you need a single number, a range or a time until an event. So start simple, and move up only when a more complex model beats the simpler one in the backtest. Our post on machine learning in predictive analytics explains the algorithms in more depth.
| Approach | Best starting fit | Strength | Limitation | Selection rule |
|---|---|---|---|---|
| Rules and statistical models (moving average, exponential smoothing, ARIMA) | Stable, regular demand | Fast, easy to explain | Miss promotions and outside signals | Always build first as the baseline |
| Intermittent-demand methods (Croston-type) | Spare parts, slow movers | Handle many zero periods | Little use for fast movers | Use when most periods show zero demand |
| Gradient-boosted trees | Demand with promotions, prices and calendar effects | Use many drivers at once | Need careful feature design | Move here when outside drivers matter |
| Hierarchical or global models | Thousands of related SKUs | Share patterns across items | Harder to explain one item | Use for large catalogs with short histories |
| Deep learning (LSTM and similar) | Long, rich histories with complex patterns | Capture long-range effects | Need more data and tuning | Adopt only if it beats trees in the backtest |
| Probabilistic and time-to-event models | Lead times, ETAs, asset failures | Give ranges and probabilities | Harder to communicate | Use when the decision needs a risk, not a point |
Matching the Model to the Business
The table is a starting map rather than a ranking, and the business decides where on it you land. A perishable foods producer with years of detailed sales data can justify deep learning, as the Kanerika case study near the end shows.
A spare-parts business with sparse demand would waste effort on the same approach. Most of its weeks show zero sales, and a Croston-type method handles that pattern directly. A carrier ETA model is a third case. The planner needs the chance a load arrives late and by how much. A time-to-event model that returns a range fits better than a single forecast date.
Public evidence points the same way for retail demand. In the M5 forecasting competition, teams forecast 42,840 Walmart sales series, and most of the methods examined used LightGBM, a gradient-boosted tree library. Only 415 teams, or 7.5%, beat the strongest exponential smoothing benchmark, which is why the simple baseline always comes first.
Planning Suite, Data Platform or Custom Models
Once the use case is clear, the next choice is where the model lives. There are three broad routes, although many companies end up using more than one. The planning suite you already own may cover standard forecasting. Your data platform may offer built-in forecasting functions. Custom models then fill the gaps where your network or products behave differently.
What the Platform Functions Do
The platform route has also become much easier. Snowflake ML Forecasting can forecast many series at once, accepts outside features and returns prediction intervals, with a default 95% range. Its default method ensembles Prophet, ARIMA, exponential smoothing and a gradient-boosted model.
On Databricks, the ai_forecast SQL table function is in Public Preview as Version 1, its default. Version 2 is in Beta, uses a time series foundation model and adds holidays and outside covariates. So check the release status before you depend on either version in production. Our list of predictive analytics tools and our roundup of supply chain analytics tools compare more options.
| Option | Choose when | Trade-off | Proof before commitment |
|---|---|---|---|
| Planning suite features (ERP or supply chain planning software) | Your needs are standard and planners already live in the suite | Limited control over features and model logic | Backtest the suite’s forecast against your current rule on your own data |
| Data platform functions (Snowflake ML Forecasting, Databricks ai_forecast) | Your data already sits in the platform and you want a fast first model | Less tuning; check preview or beta status | Run the function on two years of history and compare with the baseline |
| Custom models | Your network, products or decisions differ from the standard | Needs data science and MLOps capacity | A bounded pilot that beats both other routes on the same test |
On-Demand Webinar
Optimizing Supply Chain with AI Analytics
An on-demand session on applying AI analytics to supply chain planning, useful context before you choose between suite features, platform functions and custom models.
Watch the Webinar →Worked Example: Turning a Demand Forecast into a Purchase Recommendation
A forecast becomes useful only when it turns into an order. So this illustrative example uses round numbers to show the arithmetic for one SKU at one distribution center. Because the numbers are invented, it is not a client result.
- Forecast demand over the protection period. The model forecasts 1,000 units over the supplier lead time plus the review period.
- Add safety stock for uncertainty. Based on the forecast’s error range, safety stock is set at 200 units. The order-up-to target is 1,000 + 200 = 1,200 units.
- Calculate the inventory position. On hand is 400 units, on order is 300 and backorders are 50, so the position is 400 + 300 – 50 = 650 units.
- Size the order. The recommendation is 1,200 – 650 = 550 units.
- Compare with the current rule. The existing weeks-of-cover rule targets 1,400 units and would order 1,400 – 650 = 750. Treat the 200-unit gap as a hypothesis to test.
- Apply supplier constraints. If the supplier’s minimum order is 600 units, the order rounds up to 600, still 150 below the old rule.
- Simulate before switching. Replay several months of history with both rules and compare stockouts, average inventory and order counts.
The last step is the one teams skip. A smaller order looks like savings on paper, but only a rolling simulation shows whether it also causes more stockouts. If the simulation holds up across seasons and product classes, then the new rule has earned a live pilot.
Decision Framework: Choosing Your First Predictive Use Case
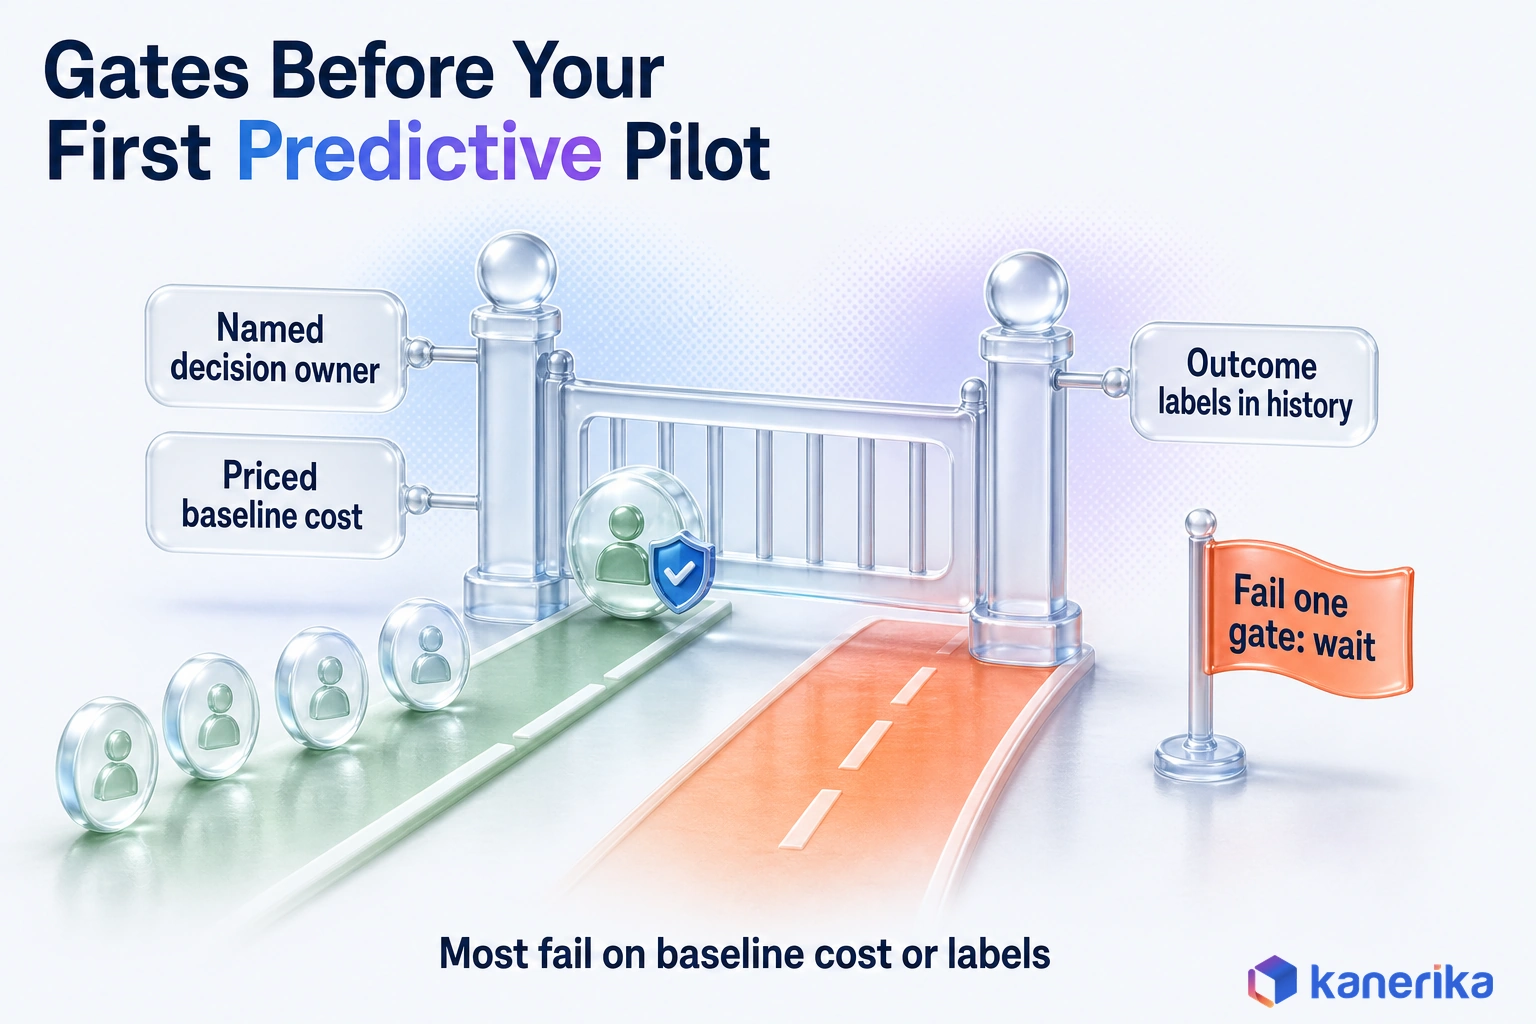
The first use case decides whether the program gets a second one. So pick the candidate with the best odds of a clear, measurable win. Run each candidate through six gates, and park any that fail one until the gap is fixed:
- A named decision owner. One person or team will act on the prediction and is accountable for the result.
- A measurable baseline cost. You can put a number on today’s stockouts, write-offs, expedites or downtime.
- Prediction before the deadline. The forecast can arrive before the last moment the decision can still change.
- Data with outcome labels. History covers enough periods and records what actually happened, such as receipt dates or true demand.
- A team that can act. Planners have the authority and the capacity to change orders when the model says so.
- One bounded pilot. The test covers a defined set of SKUs, sites or suppliers, with a control group that keeps the old rule.
Most candidates fail on gates two and four, because teams often cannot price today’s problem, or the history does not record what really happened. Even so, fixing those gaps is useful work in its own right, because it makes every later use case cheaper.
Where to Start by Scenario
If you are unsure which gate matters most, start from the cost you feel today, because the first win should be easy to see.
| Start here if | First use case | Why |
|---|---|---|
| Stockouts and lost sales drive most of your losses | Demand forecasting with replenishment risk | Directly moves fill rate and inventory, with plenty of history |
| Late inbound freight drives expedites and line stops | Supplier lead-time risk | Gives buyers weeks of warning on the orders that matter |
| Downtime on plants or fleets is the biggest cost | Predictive maintenance | Sensor data already exists and failures carry a clear price |
Measuring Value, Effort and Cost
A model can be accurate and still create no value. That is why you should measure results at four layers, from the prediction up to the money, so you can see where the chain breaks. For example, a forecast that improves MASE but never changes an order has failed at the decision layer.
| Layer | Example measures | Caution |
|---|---|---|
| Prediction | Bias, MASE, interval coverage | Report by segment, not one average |
| Decision | Share of recommendations accepted, override rate and reasons | High overrides point to trust or data gaps |
| Operations | Stockouts, days of inventory, expedites, on-time receipts | Compare with a control group, not the prior period |
| Economics | Working capital, lost margin, freight spend, write-offs | Count only changes the pilot can explain |
Cost is easier to estimate than most teams think, as long as you avoid market averages. After all, no reliable public figure tells you what a pilot costs for your network. Estimate person-weeks by workstream instead: data integration, feature building, modeling and backtesting, planner workflow, and production monitoring.
Price those weeks at your own internal or partner rates. Once you add platform compute and any planning-suite licenses, you have a budget you can defend. The data integration share is often the largest, which is why a strong data integration base pays off across every later use case.
AI Assessment
Is Your Data Ready for a Predictive Pilot?
Score your data, governance and skills in a few minutes and see whether demand, supplier risk or maintenance is the right first prediction for your team.
Start Your AI Assessment →Risks and Governance for Planner-Facing Predictions
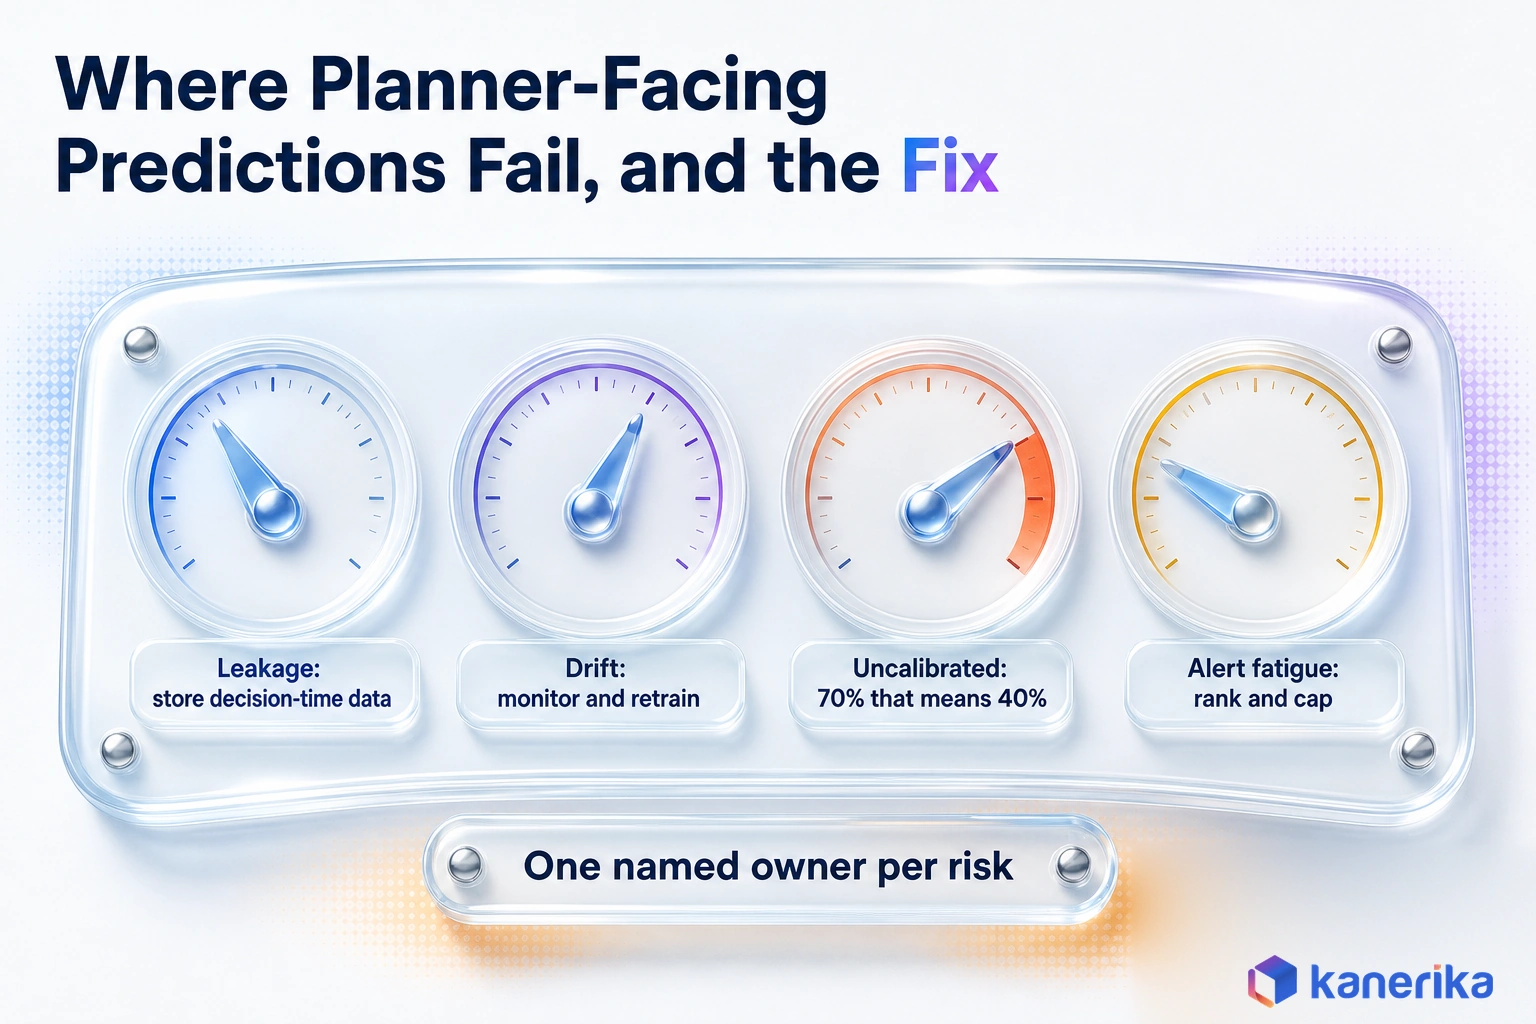
A prediction that planners act on is an operational control, so it needs the same care as any other control. The failures below are common but mostly avoidable. Each one also needs a named owner, because a risk that belongs to everyone is managed by no one.
| Failure mode | Consequence | Control | Owner |
|---|---|---|---|
| Data leakage | Backtest looks far better than live results | Store features as known at decision time | Data engineering lead |
| Censored demand | Chronic under-forecasting of best sellers | Flag stockout periods and estimate lost sales | Demand planning lead |
| Accuracy-only optimization | Better error scores with no business gain | Track decision and economic metrics too | Product owner |
| Model drift | Accuracy slips as markets and suppliers change | Monitor error by segment and retrain on a schedule | ML engineering lead |
| Uncalibrated scores | A “70% risk” that is really 40% | Check calibration in every backtest | Data science lead |
| Uncontrolled automation | Large orders placed without review | Approval limits and a fallback rule | Supply chain director |
| Alert fatigue | Planners ignore the queue | Rank by impact and cap daily alerts | Planning manager |
| Skipped change management | Planners keep using spreadsheets | Training, override logs and feedback sessions | Business sponsor |
Governance also covers the data itself. Who can change a supplier master record, how product hierarchies are versioned and how long history is kept all shape what the model learns. Kanerika’s data governance services set up those rules alongside the analytics work, so the model is not built on data nobody owns.
How Kanerika Delivers Predictive Supply Chain Analytics
Kanerika builds predictive models around the decisions planners make, on the data platform the client already runs. The work moves in stages, and each one has to prove itself before the next starts. That keeps the first pilot small and the path to scale clear.
- Decision discovery and baseline. Name the decision, owner and horizon, then price today’s cost of getting it wrong.
- Data readiness. Join ERP, WMS, TMS and supplier data on the client’s platform, with decision-time history and repaired demand.
- Baselines and challengers. Rebuild the current rule, then test statistical, tree-based and deep learning models against it in rolling backtests.
- Planner-in-the-loop pilot. Put predictions in the planners’ existing tools for a bounded set of items, with a control group.
- Production controls. Add monitoring, retraining, approval limits and a fallback rule.
- Scale by decision pattern. Reuse the same data and pipeline for the next decision of the same kind, such as moving from one product family to the next.
The same staged approach also underpins Kanerika’s predictive analytics services and its broader logistics and supply chain work. Teams that want the business view of these projects can also start from the supply chain function page.
Case Study: 30% Fewer Stockouts for a Perishable Foods Producer
The client is a leading producer of perishable foods serving domestic and international markets. It runs a global supply chain that must coordinate suppliers, manufacturers, distributors and retailers. Before the project, it had limited visibility into inventory and supplier performance, which led to stockouts and long lead times.
Delayed deliveries and uneven product quality made the problem worse. For perishable goods, both errors are expensive, because too little stock loses sales while too much spoils.
Kanerika built LSTM-based models covering demand forecasting, inventory analysis and risk mitigation. It then paired them with a Supply Chain Collaboration Platform that connected suppliers, manufacturers and distributors around the same forecast. Better forecasts fed planning and production scheduling, which shortened lead times. After rollout, the published results were:
- 30% fewer stockouts
- 20% shorter order fulfillment time
- 12% higher profitability
- 2% gain in market share
The full demand forecasting case study has the project detail. It also follows the pattern this guide recommends: one decision, a clear baseline problem, then shared data so every party acts on the same prediction.
Kanerika Service
Predictive Analytics Services
Kanerika builds demand, supplier and maintenance predictions on your own data platform, from decision discovery and baselines to planner pilots and production monitoring.
Explore Predictive AnalyticsWrapping Up
The seven use cases in this guide all share one shape. In each, a prediction arrives early enough to change a named decision, and a person who owns that decision acts on it.
The models matter, but they come later than most teams expect. Decision-time data, an honest baseline and the right error metric do more for results than any single algorithm. A worked example and a simulation turn a forecast into an order you can defend.
The practical answer is simple. To get value from predictive analytics in supply chain, start with one decision and prove it against today’s rule. Once it wins, scale it to the next decision of the same kind.
Frequently Asked Questions
What is predictive analytics in supply chain?
Predictive analytics in supply chain uses historical and live operating data to forecast what will happen next, such as demand, supplier delays or equipment failures. The output is a forecast, a probability or a predicted date. It is useful only when it reaches a named decision owner early enough to change an order, a schedule or a shipment plan.
How does predictive analytics improve demand forecasting?
It adds signals that simple averages miss, such as promotions, prices, holidays, weather and recent orders, and it learns how they interact across thousands of products. It also repairs history by flagging stockout periods, when sales understated real demand. The result is a forecast that reacts faster to change and can be checked against your current planning rule.
Which predictive model is best for supply chain forecasting?
No single model is best. Start with statistical baselines such as exponential smoothing, use Croston-type methods for intermittent demand, and move to gradient-boosted trees when promotions and prices matter. Global models suit large catalogs, LSTMs suit long and rich histories, and time-to-event models suit lead times and failures. Keep whichever wins your rolling backtest.
Should we use our ERP planning tools or build custom predictive models?
Use planning-suite features when your needs are standard and planners already work in the suite. Use data-platform forecasting functions for a fast first model on data you already hold. Build custom models where your network, products or decisions differ. In every case, backtest the option against your current rule on your own data before committing.
How do you measure ROI from supply chain predictive analytics?
Measure four layers: prediction quality such as bias and MASE, decision uptake such as accepted recommendations and overrides, operational results such as stockouts and expedites, and economics such as working capital and write-offs. Compare against a control group that keeps the old rule. Count only the changes the pilot can explain, then subtract the full project cost.
Can generative AI replace predictive supply chain models?
Not on its own. Generative AI and agents are good at explaining a forecast in plain language, summarizing exceptions and routing work to the right buyer. The numbers they talk about still come from forecasting and risk models trained on your operating data. Treat generative AI as a layer on top of prediction, not a replacement for it.
What are examples of predictive analytics in supply chain?
Seven common examples are demand forecasting, replenishment and stockout risk, supplier lead-time risk, transportation ETA prediction, production disruption and material shortage alerts, predictive maintenance for plant and fleet assets, and returns forecasting. Each predicts a different target, needs different data and changes a different decision, so teams usually start with one rather than all seven at once.
What data is needed for supply chain predictive analytics?
Most use cases need ERP sales and order history, inventory positions, purchase orders and receipts, and clean product, location and supplier master data. Transport and maintenance use cases add carrier milestones, GPS or sensor readings. The data must record what was known at each decision point, and it needs real outcome labels such as actual receipt dates or true demand.
What is the difference between predictive and prescriptive analytics in supply chain?
Predictive analytics estimates what is likely to happen, such as demand next month or the chance a shipment arrives late. Prescriptive analytics recommends what to do about it within constraints, such as order quantities that meet a service target at the lowest cost. Most teams need prediction first, because prescriptive tools depend on a reliable forecast.
How accurate is predictive analytics for demand forecasting?
Accuracy depends on the product, the horizon and the data, so no single percentage applies. The honest test is a rolling backtest against your current rule, measured by bias and MASE, which compares errors to a naive forecast. Avoid relying on MAPE alone, because it breaks when actual demand is zero, as with spare parts and slow movers.
How do you implement predictive analytics in supply chain operations?
Start by naming one decision, its owner and its horizon, then price today’s cost of getting it wrong. Build a data foundation that stores features as known at decision time. Rebuild the current rule as a baseline, backtest challenger models against it, run a bounded pilot with a control group, then add monitoring, fallbacks and retraining before scaling.
Can supply chain teams use predictive analytics without a large data science team?
Yes, for a first model. Snowflake ML Forecasting forecasts many series at once with prediction intervals, and Databricks provides the ai_forecast SQL function, with Version 1 in Public Preview and Version 2 in Beta. Planning suites also include standard forecasting. A small team still needs data engineering, a fair baseline and someone who owns the planner workflow.
Can predictive analytics reduce inventory without increasing stockouts?
It can, when better forecasts and error ranges let you set safety stock by item instead of using one blanket rule. Some items need more stock and many need less. The only way to prove it is a rolling simulation that compares stockouts, average inventory and order counts under the old and new rules across several seasons.
How can predictive analytics identify supplier delays?
A supplier risk model learns from past purchase orders and receipts, the supplier’s recent on-time record, the product, the shipping lane and the season. It scores each open PO line with the expected days late. Buyers then focus on high-risk lines for critical parts, where a call, a split order or a second source can still help.