TL;DR
Translytical Task Flows let Power BI reports write data back to the source database, turning static dashboards into tools where users can add records, update values, or trigger workflows without leaving the report — the right storage choice (SQL Database vs. Warehouse) depends on your existing data model and setup needs.
Power BI has traditionally been used as a read-only tool where users analyze data but cannot directly modify it. However, with the introduction of Translytical Task Flows in Microsoft Fabric, this limitation is changing. You can now write data back to your database directly from a Power BI report.
This capability allows users to move beyond static reporting and take action on data. For example, users can add new records, update existing values, or trigger workflows without leaving the report. As a result, Power BI becomes more interactive and supports real-time business operations.
Key Takeaways
- Choose the right storage based on your use case: SQL Database is simpler to start with, while Warehouse may require additional setup depending on your data model.
- Table design may differ between environments: Features like identity columns may not behave the same, so you may need alternative approaches for generating keys.
- Query structure can change slightly: Warehouse setups may require fully qualified table names, which affects how queries are written inside functions.
- Setup complexity varies: SQL Database is generally easier to configure, while Warehouse setups may involve more steps and adjustments.
- Testing and behavior can vary by environment: Some features may behave differently depending on the workspace or region, so validation is important before deployment.\
What Are Translytical Task Flows?
Translytical Task Flows combine analytical and transactional capabilities within Power BI. While traditional reports focus on insights, these flows allow users to perform actions on the data.
Instead of limiting users to viewing dashboards, Power BI now supports workflows where actions can trigger updates or external processes. As a result, reporting and operations can work together in a single environment. Translytical task flows suit quick edits inside a report, while full data-entry screens usually belong in Power Apps or a custom Fabric App.
Key Highlights
- Update data directly within reports: Users can modify or add data without leaving Power BI, which removes the need to export datasets or rely on external tools. As a result, updates become faster and more seamless within the reporting workflow.
- Turn reports into interactive interfaces: Instead of acting as static dashboards, reports can function like simple input forms. Users can enter values, submit changes, and trigger actions directly from the report, which makes the experience more engaging and practical.
- Keep backend systems in sync: When users submit data, the changes are written directly to the database. This ensures that the source system stays up to date, and all connected reports reflect the latest data after refresh

How Power BI Write-back Works
Power BI write-back works by linking user inputs in a report to backend functions using Microsoft Fabric. Instead of embedding SQL logic directly inside the report, the process uses User Data Functions to handle database operations in a controlled way. This ensures that all updates follow a structured flow and reduces the risk of errors.
As a result, when a user interacts with the report, their actions do not just change visuals but also trigger real updates in the underlying database. This makes the entire process reliable and suitable for real-world workflows.
Step 1: Capture user input
Users enter values using input elements such as text slicers or selection fields in the report. These inputs act as parameters that will be passed to the backend function.
Step 2: Trigger a function
A button is configured to call a Data Function. When the user clicks the button, it sends the captured input values to the function for processing.
Step 3: Execute backend logic
The function connects to the Fabric database using a predefined connection. It then runs SQL queries, such as insert or update, based on the input received.
Step 4: Commit changes to the database
After executing the query, the function saves the changes in the database. This ensures that the new or updated data becomes part of the source system.
Step 5: Refresh the report to view updates
Once the data is written, the report needs to be refreshed so that the latest changes are reflected in visuals. This allows users to immediately see the impact of their actions.

Prerequisites for Power BI Write-back
Before building a write-back solution, you need to configure a few essential components. These settings ensure that Power BI can connect to backend systems and execute data operations correctly. Without this setup, write-back features will either not appear or will fail during execution.
At the same time, each requirement plays a specific role in the overall flow. Some enable functionality, while others ensure that data can be stored and updated reliably. Therefore, it is important to complete all these steps before moving to implementation.
Required Setup
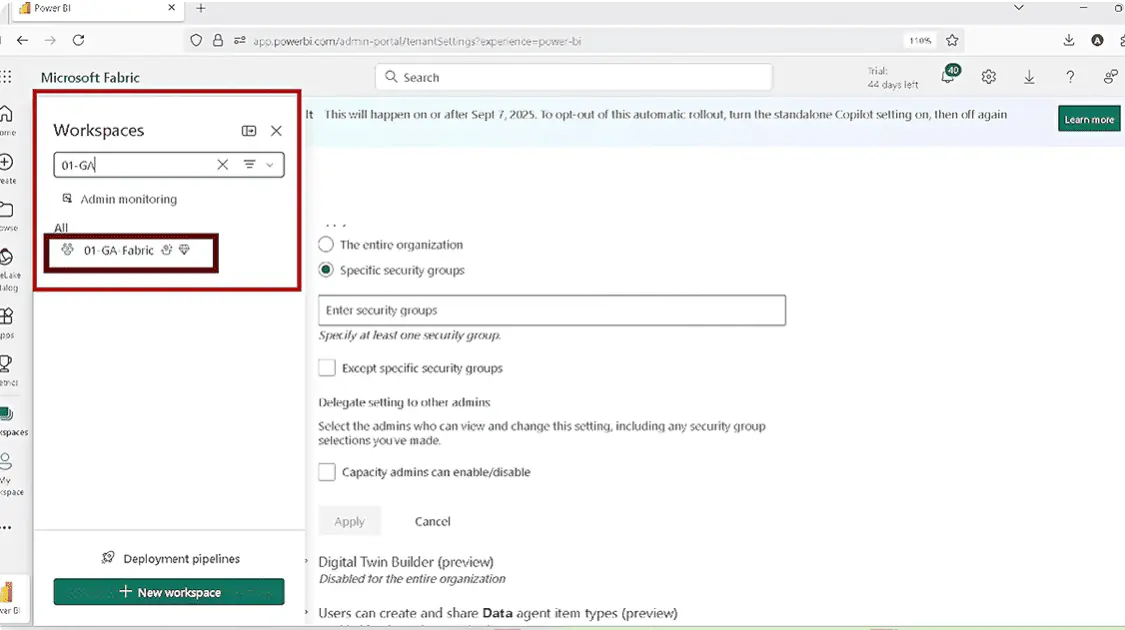
- Enable User Data Functions
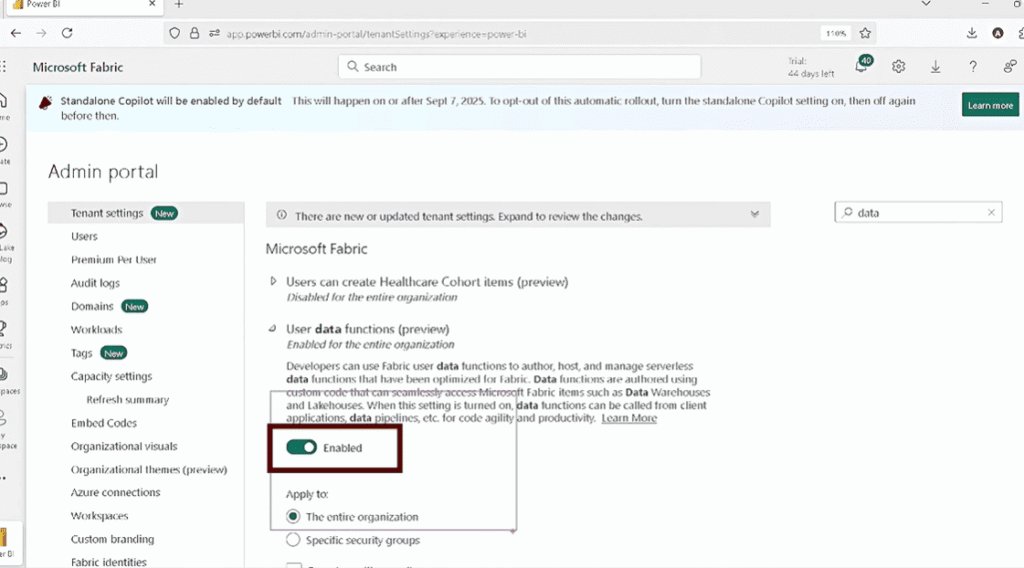
First, you need to enable User Data Functions in the Power BI Service under tenant settings. This feature allows you to create and run backend functions that handle operations such as insert and update. Without enabling this, Power BI will not be able to execute any write-back logic.
- Use a Fabric-enabled workspace
You must use a workspace that supports Microsoft Fabric. This is important because write-back relies on Fabric services such as SQL Database or Warehouse. If the workspace is not Fabric-enabled, the required features and connections will not be available.
- Prepare a database
Finally, you need a database where the data will be written. This can be a Fabric SQL Database or a Warehouse. The database should have the required tables and structure so that functions can insert or update records properly.
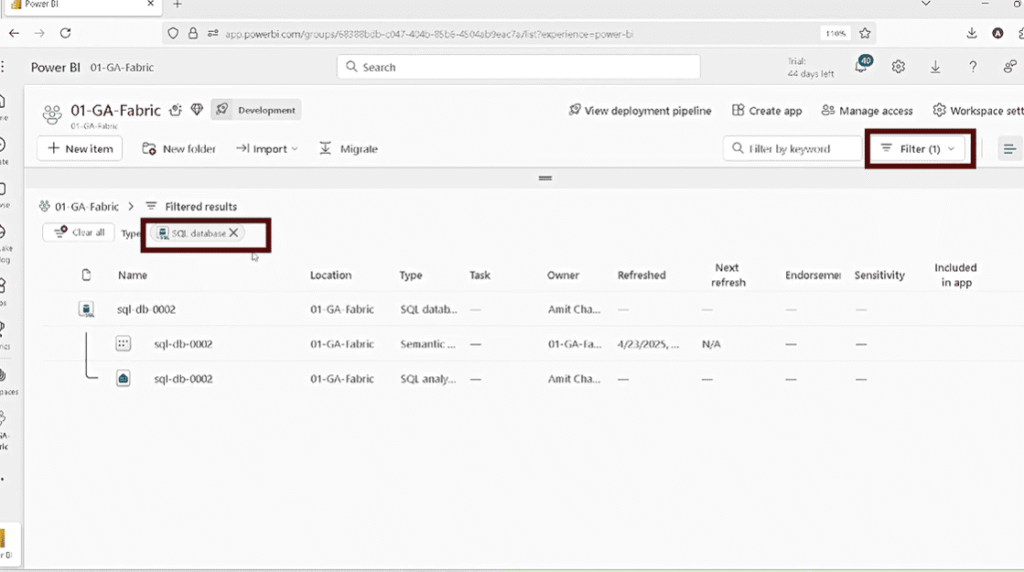
Below are the steps to enable data write-back in Power BI with translytical task flows.
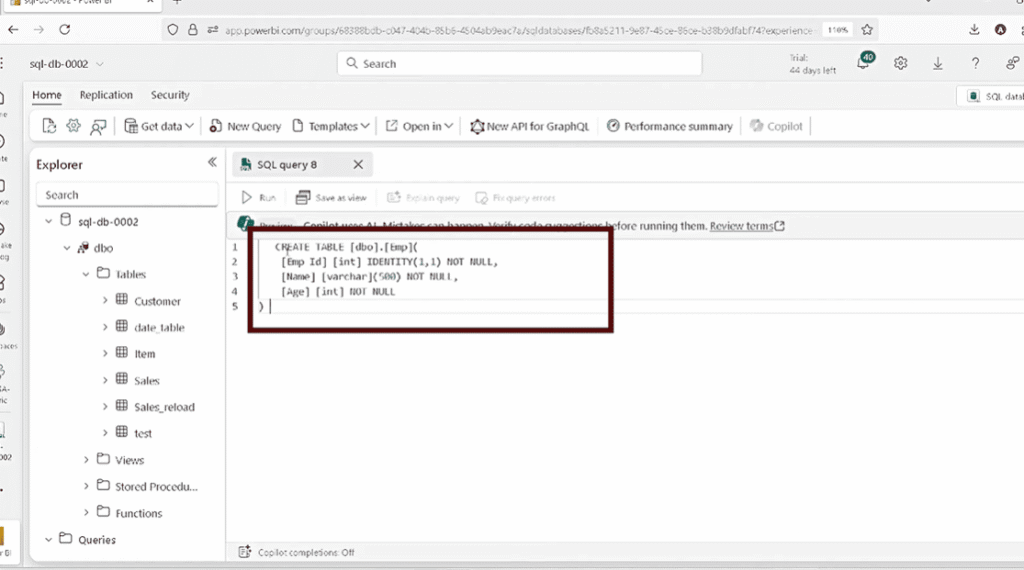
Step 1: Create the Database Table for Power BI Data Write-back
Before writing data, create a table that will store the records.
CREATE TABLE Employee (
    EmployeeID INT IDENTITY(1,1) PRIMARY KEY,
    Name VARCHAR(500),
    Age INT
)
In a SQL Database, the identity column automatically generates IDs. However, in a Warehouse, identity may not be supported. Therefore, you must generate IDs manually using logic such as:
SELECT COALESCE(MAX(EmployeeID),0) + 1
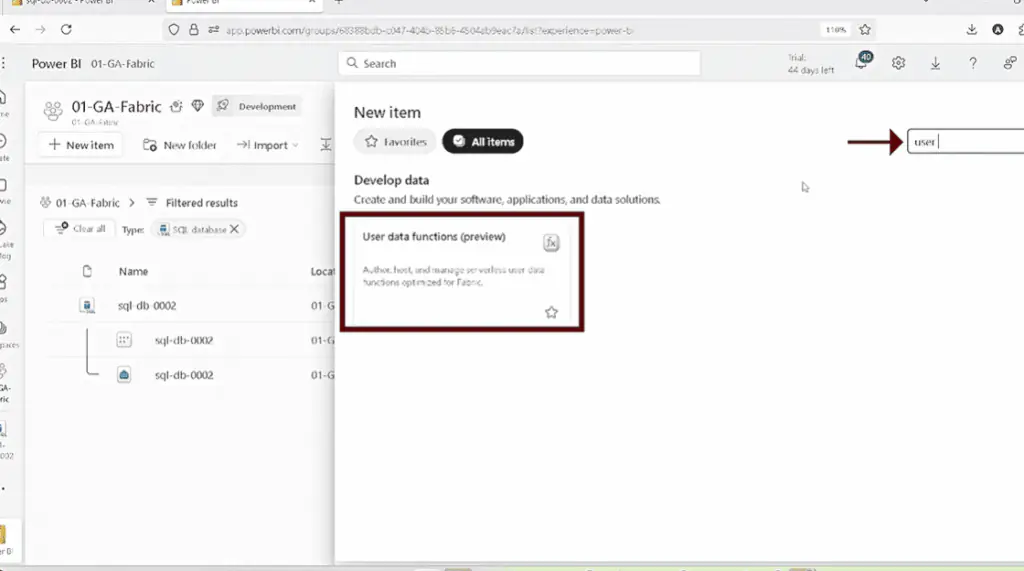
Step 2: Create a User Data Function for Power BI Data Write-back
Once the table is ready, the next step is to create a User Data Function. This function is the core component of Power BI Data Write-back, as it handles all backend operations such as inserting and updating data.
To create a function:
- Go to New Item → User Data Function
- Provide a meaningful name for your function set
- Open the function editor
- Add a new function
At this stage, you are setting up the environment where your write-back logic will reside. Instead of placing SQL logic inside Power BI, you define it inside this function. As a result, your architecture becomes more structured and easier to manage.
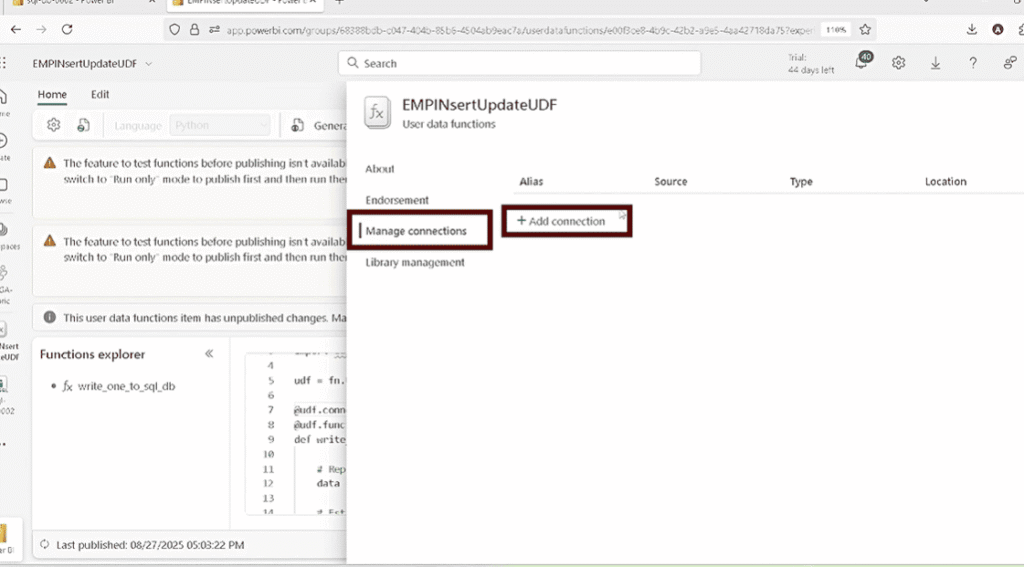
Step 3: Set Up Database Connection for Power BI Data Write-back
After creating the function, you need to connect it to your database. This step ensures that your function knows where to send and retrieve data.
To configure the connection:
- Open Manage Connections
- Add your SQL Database or Warehouse
- Assign an alias name
- Save and update the connection
The alias plays an important role because it is used inside your function code. Instead of writing full connection details repeatedly, you reference this alias. Consequently, your function remains clean and easier to maintain.
Without this connection, your function cannot execute any database operations, so this step is essential for Power BI Data Write-back.
Step 4: Write Function Logic for Power BI Data Write-back
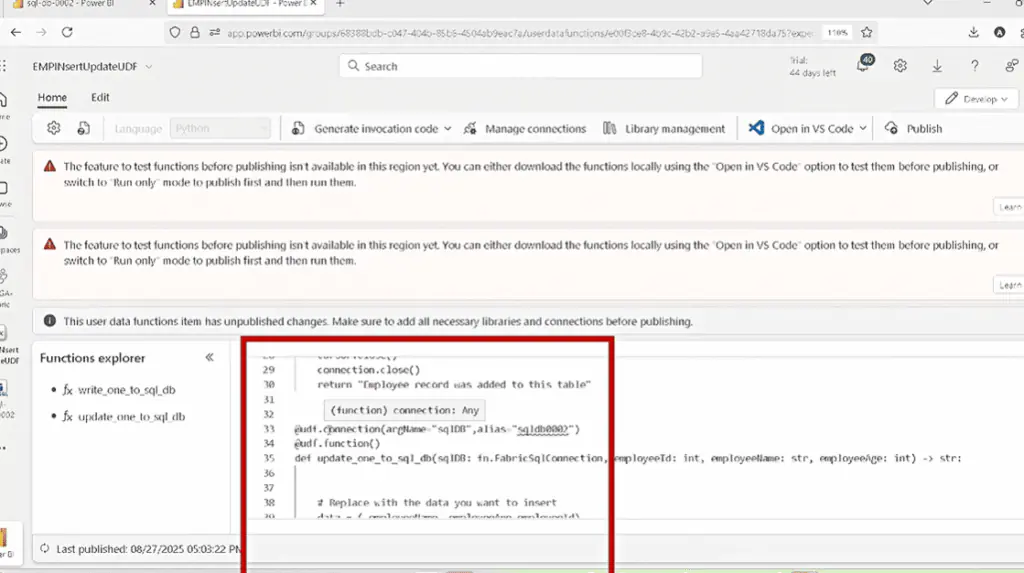
Now that the connection is ready, you can define the logic inside your User Data Function. This logic determines how data is inserted or updated in the database.
For insert operations, the function:
- Accepts input values such as Name and Age
- Connects to the database using the alias
- Executes an SQL INSERT query
- Commits the transaction
- Closes the connection
For update operations, the function:
- Accepts EmployeeID along with updated values
- Executes an SQL UPDATE query
- Saves the changes
- Returns a confirmation message
At this stage, the function acts as a bridge between Power BI and your database. Therefore, keeping this logic structured and accurate is critical for reliable write-back operations.
Step 5: Publish the Function for Power BI Data Write-back
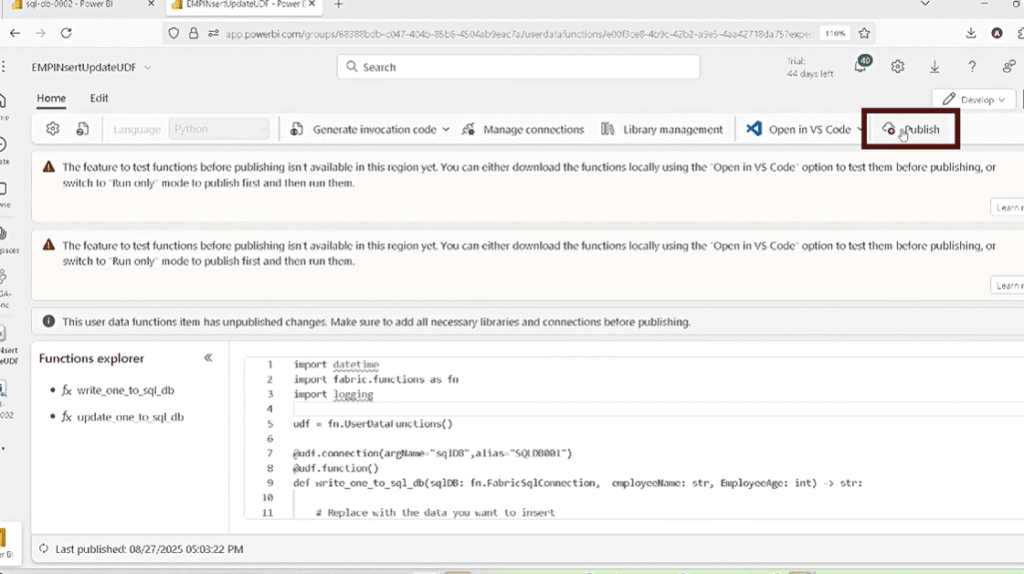
After writing the function logic, you must publish it. This is a critical step because Power BI can only access published functions.
To publish:
- Click the Publish button in the function editor
- Ensure there are no errors
- Confirm the function is successfully deployed
If you skip this step, your function will not appear in Power BI Desktop when configuring the button action. As a result, your write-back setup will not work even if everything else is correct.
Step 6: Create a Semantic Model for Power BI Data Write-back
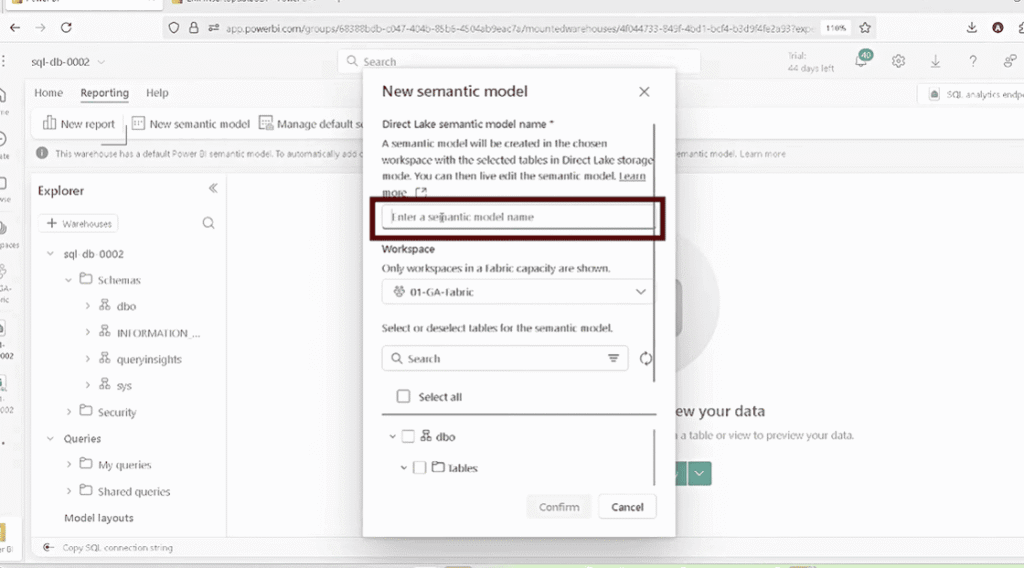
Next, you need to create a semantic model so that Power BI can access the data stored in your database. This model acts as the connection between your database and your report.
To create the model:
- Go to the SQL endpoint
- Select Create Semantic Model
- Choose the Employee table
- Set summarization (e.g., EmployeeID, Age) to None
This step ensures that your data behaves correctly inside Power BI visuals. In addition, it allows you to use the same dataset for both reporting and write-back operations.
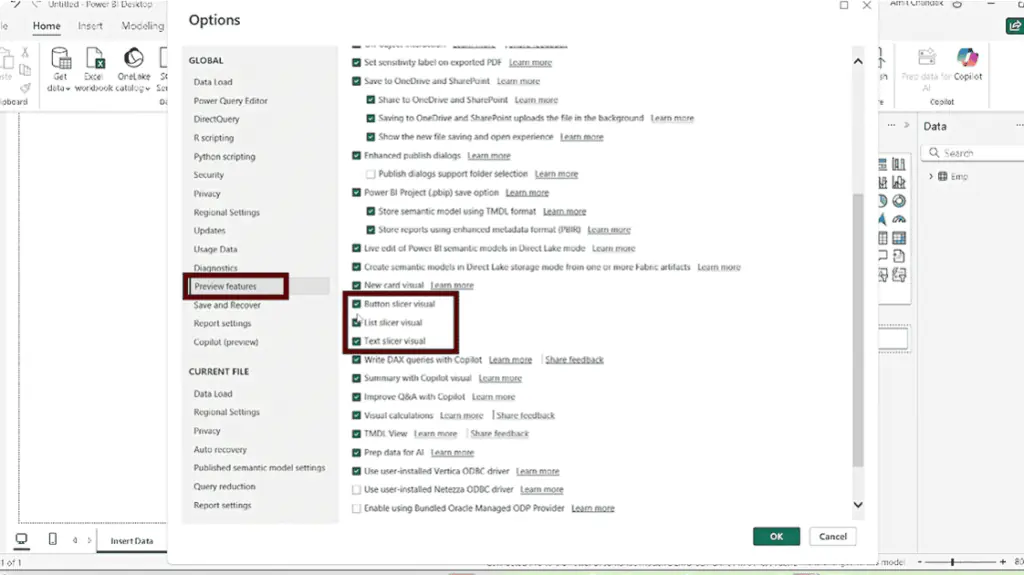
Step 7: Enable Required Features in Power BI Desktop
Before building the interface, you must enable certain preview features in Power BI Desktop. These features allow you to create input fields and trigger functions.
Go to:
File → Options → Preview Features
Enable the following:
- Text Slicer
- Button Slicer
- Translytical Task Flows
After enabling these options, restart Power BI Desktop if required. Once enabled, you can create interactive elements that support Power BI Data Write-back.
Step 8: Build the Power BI Interface for Data Write-back
Finally, create the report interface where users will interact with the data. This interface acts as the front-end layer of your Power BI Data Write-back solution.
Step 1: Add input fields
Start by adding input elements such as text slicers to capture values like Name and Age. These slicers act as input fields where users can enter or select values. Instead of using them only for filtering, you use them here to collect data that will be sent to the backend function.
Step 2: Add a button to trigger the function
Next, insert a button into the report and enable its action. Set the action type to Data Function and select the appropriate function from your workspace. This button acts as the trigger that sends user input to the backend when clicked.
Step 3: Link the button to the correct function
After adding the button, make sure it is connected to the correct User Data Function, such as insert or update. This ensures that when users click the button, the intended operation is executed in the database.
Step 4: Map input fields to function parameters
Now connect each input field to the corresponding parameter in the function. For example, map the Name slicer to the Name parameter and Age to Age. This step ensures that the data entered by the user is correctly passed to the backend logic.
Step 5: Validate parameter mapping
Before testing, verify that all inputs are mapped correctly and match the expected data types. For example, Age should be numeric and Name should be text. Proper validation helps avoid errors during execution.
Step 6: Improve user experience
Enhance the interface by enabling features such as auto-clear for input fields after submission. In addition, use clear labels for each field and organize the layout so that users can easily understand what to enter and what action to perform.

Choosing Between SQL Database and Warehouse
When implementing Power BI write-back, you can use either a Fabric SQL Database or a Fabric Warehouse as your backend. While both support data storage and updates, they differ in setup, behavior, and query handling. Understanding these differences helps you choose the right option and avoid issues during implementation.
| Aspect | SQL Database | Warehouse | What This Means in Practice |
|---|---|---|---|
| Table design & identity | Supports identity columns for auto-generating IDs | Limited or no identity support; may require manual ID handling | You may need to build custom logic for generating unique IDs in Warehouse |
| Query structure | Allows simpler table references | Requires fully qualified table names (schema + table) | Queries in functions may need adjustments depending on the environment |
| Setup complexity | Easier and quicker to configure | Slightly more complex, especially with existing models | SQL DB is better for quick setup; Warehouse needs more planning |
| Use case suitability | Best for transactional operations (insert/update) | Designed for analytical workloads and large datasets | Choose SQL DB for write-back forms, Warehouse for large-scale analytics |
| Performance behavior | Optimized for frequent small updates | Optimized for large data processing | SQL DB handles row-level updates better in write-back scenarios |
| Integration with Fabric | Works well for operational scenarios | Fits into broader Fabric analytics ecosystem | Warehouse is useful if your data pipeline already uses Fabric extensively |
| Testing & environment support | More straightforward testing | Behavior may vary depending on region/workspace | Always validate functionality before production deployment |
Kanerika: Your Trusted Partner for Power BI & Microsoft Fabric
Kanerika is a leading Data & AI solutions company specializing in Power BI, Microsoft Fabric, and AI-driven analytics. We empower businesses with purpose-built solutions designed to address unique challenges, enhance decision-making, and improve business intelligence.
With expertise across multiple industries, we have delivered impactful Power BI solutions that drive real value. Our team helps organizations transition from legacy and outdated data platforms to modern, scalable solutions like Power BI and Microsoft Fabric, ensuring faster insights and better efficiency.
We also develop custom automation solutions, streamlining data migration, reporting, and analytics to help businesses stay competitive in a data-driven world. Our solutions are designed for seamless integration, optimized performance, and future scalability.
Partner with Kanerika to harness the full potential of Power BI and Microsoft Fabric and transform your data strategy for long-term success. Let’s build the future of analytics together!

FAQs
Does Power BI support data write-back natively?
Yes, as of the May 2025 public preview, Power BI supports native data write-back through Translytical Task Flows. Before this, teams had to rely on third-party tools, Power Apps visuals, or Power Automate to push data back to a source system. Now, the entire flow from input to database update can happen inside the report itself. This removes the need for additional licenses or external integrations just to perform basic write operations.
What databases can I write back to from Power BI?
Power BI write-back currently supports Fabric SQL Database, Fabric Warehouse, and Lakehouse as backend data sources. For most write-back scenarios, Microsoft recommends Fabric SQL Database because it handles frequent small read and write operations more efficiently. Warehouse works well if your data pipeline is already built on Fabric and you need large-scale analytical workloads alongside write-back. The right choice depends on your existing data architecture and how often records will be updated.
What is a User Data Function in Microsoft Fabric?
A User Data Function is a Python-based backend function that lives inside Microsoft Fabric and handles database operations triggered from a Power BI report. When a user clicks a button in the report, the function receives the input values, connects to the database using a preconfigured alias, and executes the relevant SQL query such as insert, update, or delete. It acts as a controlled layer between the report interface and the underlying data, which reduces the risk of unstructured or direct database modifications. All logic stays in one place, making it easier to maintain and audit.
Do I need a Microsoft Fabric license for Translytical Task Flows?
Yes, Translytical Task Flows require a Fabric-enabled workspace, which means a standard Power BI Pro license alone is not sufficient. You need an active Fabric capacity or can start with a free Fabric trial to test the feature. The workspace must have Fabric features enabled, and the User Data Functions setting must be turned on at the tenant level in the admin portal. Without these in place, the required options will not appear in Power BI Desktop or the Fabric interface.
Why is my User Data Function not showing up in Power BI Desktop?
The most common reason is that the function has not been published after writing the logic. Publishing is a separate step from saving, and until it is done, the function will not appear in Power BI Desktop when you configure a button action. You should also check that the workspace selected in Power BI Desktop matches the one where the function was published. If the function still does not appear after publishing, refreshing the model in Power BI Desktop usually resolves the issue.
Can Translytical Task Flows call external APIs?
Yes, beyond database write-back, User Data Functions can be written to call external REST APIs directly from a Power BI report button. This means you can trigger actions like posting a message to Microsoft Teams, updating a record in a CRM, or sending a request to Azure OpenAI, all based on the current report context and user inputs. The function simply makes an outbound HTTP request using parameters passed from the report’s slicers or filter context. This opens up a wide range of automation scenarios that previously required Power Automate or separate integrations.