TL;DR
Before you build a generative AI tech stack, settle three things: what data the AI may read, which model suits each task, and who owns the monthly bill. The stack has eight layers. You can often reuse tools you already run, such as search, sign-in and your data platform. Model usage fees are usually smaller than the cost of connecting systems and testing answers. In the EU, most AI Act rules took effect on 2 August 2026, so plan logging and testing from day one. Start with one use case, a set of test questions and a named owner.
Key Takeaways
- A generative AI tech stack has eight layers, and each one needs a named owner before the pilot ends.
- Decide data access, model tier and security first, because those three choices are the hardest to change after a pilot.
- Reuse what you already run, such as search, identity and your lakehouse, before buying or building a new component.
- As of October 2026, balanced models such as Claude Sonnet 5.5 and gpt-6.1-sol cost $2 per million input tokens and $10 per million output tokens.
- Most EU AI Act rules have applied since 2 August 2026, and Annex III high-risk obligations follow on 2 December 2027.
- Start with one governed use case, an evaluation set and a named cost owner, then expand layer by layer.
Watch on YouTube
Document Intelligence Explained: OCR vs IDP vs LLMs, RAG, Tools, ROI & Security
A walkthrough of how LLMs, RAG and tooling turn enterprise documents into answers, and what security and ROI questions to settle along the way.
The Pilot Worked. Then Security Asked Where the Data Goes.
Picture an internal policy assistant that two engineers built on a laptop. It answers HR and travel questions from a shared folder of PDFs, so the demo lands well with the leadership team.
Then the review meetings start. Security asks which documents the model can read, and whether a contractor could pull up salary bands. Finance asks what the bill looks like when 1,000 people use it. Legal also wants audit logs and asks which European rules apply.
Nobody on the team can answer all three, so the pilot stalls. The model did its job. What stalled the pilot was a stack assembled in a hurry, where nobody had decided data access, cost or logging.
This scenario is illustrative, yet each of those questions maps to a layer that someone has to decide. This guide works through those decisions in order. It covers what to pick in each layer, how models and platforms compare, what the stack costs per month, and which governance dates shape it.
What Is a Generative AI Tech Stack?
The generative AI stack is the set of models, data, retrieval, orchestration, infrastructure and controls you use to build and run generative AI applications. Put simply, it is everything between a user’s question and an answer you can trust.
A classic web app has a database, an application server and a front end. A generative AI tech stack keeps those pieces and adds three more. First comes a model you usually rent rather than train. Then you need a way to feed that model your own data, as well as controls for output nobody can fully predict.
Take a claims team that wants summaries of incoming files, for example. The model writes the summary, but retrieval decides which pages it sees. Identity decides whether the reader may see those pages at all, while evaluation decides whether the summary is good enough to ship.
This guide assumes you are choosing components rather than learning the basics. If you need a primer on the models themselves, start with our overview of generative AI. When you want the common design shapes, such as a RAG assistant or an agent with tools, see our guide to generative AI architecture patterns.
How a Generative AI Stack Differs From a Traditional ML Stack
A traditional machine learning stack revolves around training. Teams gather labelled data, train a model for one narrow task, and then judge it on accuracy against a test set.
A generative AI stack flips that order. Most enterprises consume a pretrained model through an API, so the hard work moves to grounding it in company data. Cost moves too, since the bill now grows with every token a user sends.
| Dimension | Traditional ML stack | Generative AI stack |
|---|
| Where the model comes from | Trained in-house for one task | Consumed through an API, or else self-hosted as open weights |
| What the data does | Supplies labelled examples before training | Supplies grounding context when each request arrives |
| How quality gets judged | Accuracy, precision and recall on a test set | Scoring open-ended answers against a curated question set |
| How cost behaves | Spikes during each training run | Grows steadily with usage, since you pay per token |
| Main new risk | Model drift over time | Data leakage, prompt injection and unsafe actions |
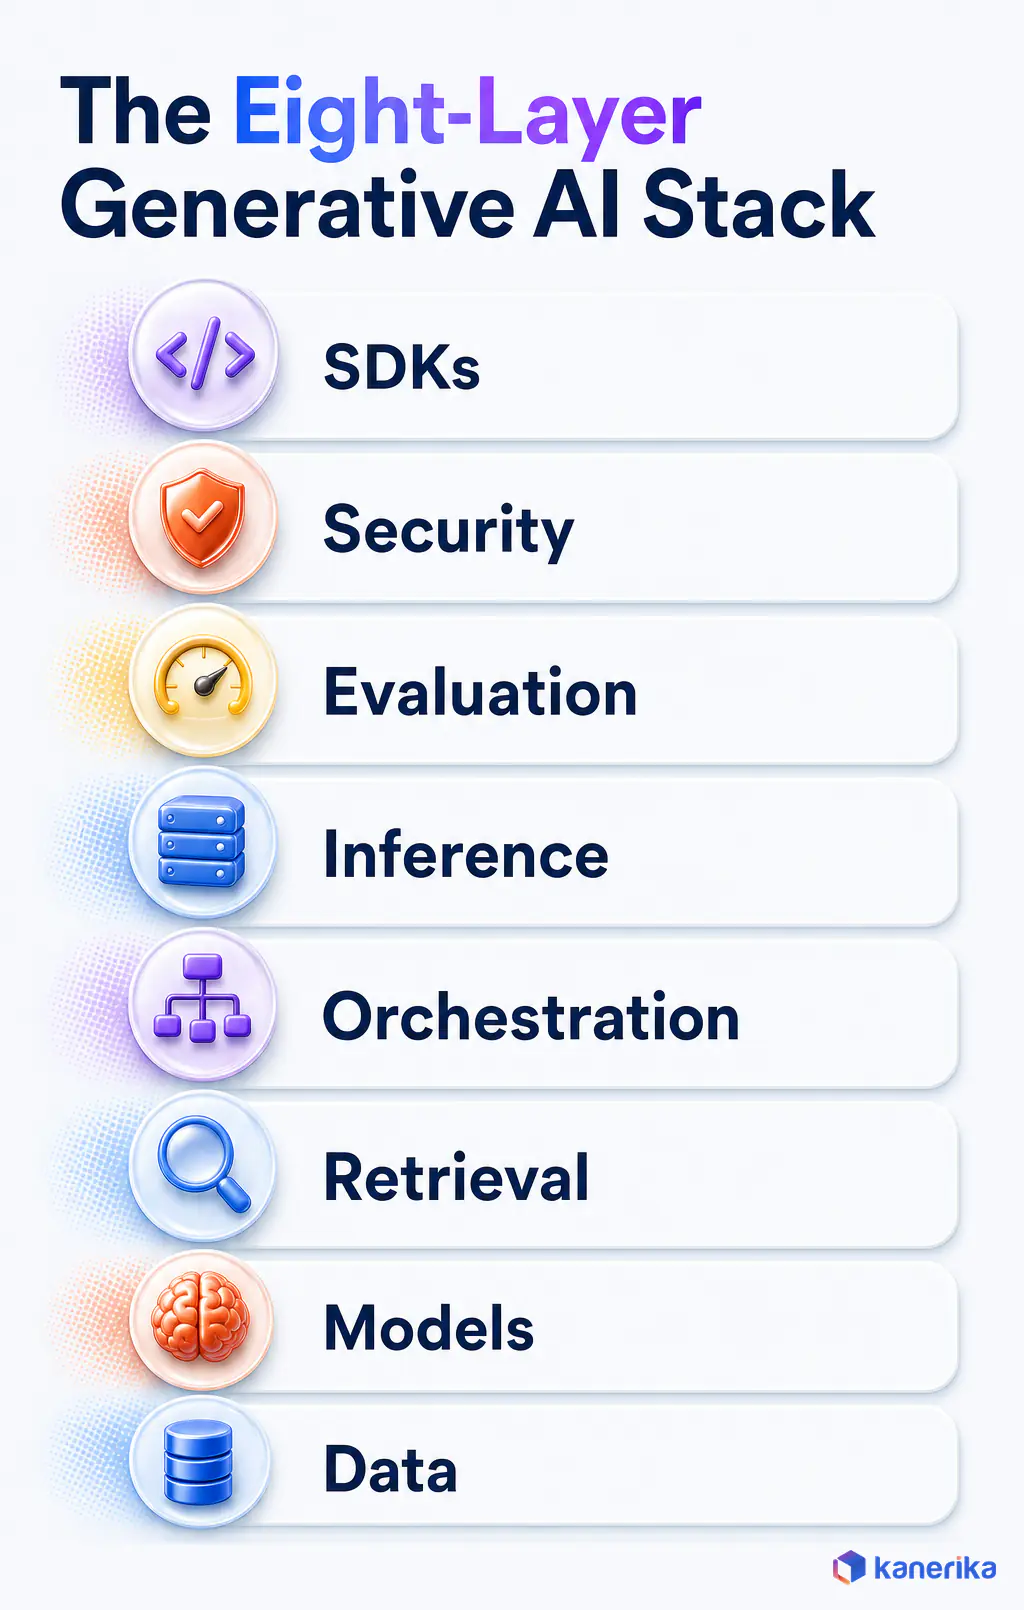
The Eight Layers of a Generative AI Tech Stack at a Glance
The stack is easiest to plan as eight layers, each with one job. You do not need a new product in every layer, because several layers often run on tools you already own.
Think of the layers as the questions a reviewer will ask. Where does the data live, which model answers, and how does it find the right context? Who checks the output? A good stack has a clear owner and a default answer for each question before the first user logs in.
What to Decide Before the Pilot Ends
The table below lists each layer with typical options as of October 2026. The last column says whether the choice belongs in the pilot or can safely wait. Readers who want to follow a single request from prompt to answer will find that flow in our guide to enterprise AI architecture.
| Layer | Job | Typical options (October 2026) | When to decide |
|---|
| 1. Data foundation and catalog | Store, label and govern the source data | Microsoft Fabric and OneLake, Databricks, Snowflake, Microsoft Purview | Before the pilot starts |
| 2. Foundation models | Generate text, code or images | Claude, OpenAI GPT models, Gemini, Llama, Mistral, Gemma | During the pilot |
| 3. Retrieval | Find the right context for each request | Existing enterprise search, pgvector, a dedicated vector database | During the pilot |
| 4. Orchestration and agents | Chain steps, call tools and hand off between agents | LangGraph, Microsoft Agent Framework, MCP, A2A | During the pilot when agents act; later otherwise |
| 5. Inference and hosting | Run the model with the right latency and residency | Managed APIs, Microsoft Foundry, Amazon Bedrock, vLLM self-hosting | Later, unless residency forces it early |
| 6. Evaluation and LLMOps | Measure quality, cost and drift | Offline eval sets, tracing, cost dashboards | Before the pilot starts |
| 7. Security and guardrails | Control access, inputs, outputs and audit | Identity-aware retrieval, guardrail services, audit logging | Before the pilot starts |
| 8. Languages and SDKs | Glue the layers into an application | Python, TypeScript, C#, Java | During the pilot |
Notice how few rows say “later”. That is deliberate, because choices that are cheap in week one get expensive once users depend on them.
What to Choose in Each Layer
Each layer choice comes down to three questions: what you can reuse, what to settle during the pilot, and which rule stops a bad choice spreading. Read the layers in order the first time, starting with data, because every later choice depends on what the model is allowed to read.
Data Foundation and Governance Catalog
The data layer holds the documents and tables your application will draw on, together with the labels that say who may see them. For most enterprises this is a lakehouse they already run, such as Microsoft Fabric with OneLake, Databricks or Snowflake.
The catalog matters as much as the storage. A tool like Microsoft Purview records where data sits, how sensitive it is and who owns it. Sensitivity labels applied there can then follow a document into the retrieval layer.
- Options: Microsoft Fabric and OneLake, Databricks or Snowflake for storage, together with Microsoft Purview or your platform’s catalog for labels and lineage.
- Decision rule: permissions travel with the data, so if a user cannot open the source file, the assistant must not quote it.
- When to defer: a full catalog rollout can wait, while labels for the pilot’s own sources cannot.
Teams that skip this step often discover the gap during a security review, which is exactly where the assistant in our opening scenario stalled. Our generative AI services team starts most engagements with this data and permissions check for that reason.
Kanerika Service
Generative AI Consulting and Development
Kanerika plans and builds generative AI applications on your data, from permissions and retrieval to evaluation, guardrails and cost controls.
Explore Generative AI Services
Foundation Models
The model layer is the part most people picture first, and it is also the easiest to swap later. You choose between closed models through an API, open-weight models you host yourself, and small models for fast, cheap tasks.
Closed models from Anthropic, OpenAI and Google give strong general reasoning with no hosting work. Open-weight families such as Llama, Mistral and Gemma give you full control over where the model runs. Small models, meanwhile, handle classification and extraction at a fraction of the price.
The rule here is to match the tier to the task rather than pick one model for everything. A routing step that sends easy requests to a small model often cuts the bill sharply. The model matrix further down compares prices and fit, and our guide on how LLMs work inside explains the internals.
Retrieval: Embeddings, Vector Search and RAG
Retrieval is how the model sees your data when a request arrives. Retrieval-augmented generation, or RAG, turns documents into searchable chunks, finds the chunks that match a question, and then passes them to the model as context.
This layer decides answer quality more than the model does. An assistant with a mid-tier model and sharp retrieval usually beats a frontier model fed the wrong pages. It is also where permissions must be enforced, since retrieval is the step that pulls documents out of storage.
Do you need a dedicated vector database? Often not at first. Start with the search you already run, or else with pgvector, an open-source vector similarity search extension for Postgres. Move to a dedicated vector database once you reach tens of millions of chunks or search latency starts to hurt users.
RAG also changes the fine-tuning question. Most enterprise assistants need fresh, permissioned facts, which retrieval supplies and fine-tuning does not. Our comparison of RAG vs fine-tuning covers when each one fits, while our vector database comparison helps once you outgrow the simple options.
Orchestration and the Agentic Layer
Orchestration is the code that turns a single model call into a workflow. It chains steps, calls tools such as a CRM lookup, and decides when to hand work to another agent or to a person.
Two open standards matter here, because they let agents built on different frameworks reach the same tools and each other. You write a connector once, rather than once per vendor. The first is the Model Context Protocol (MCP), an open-source standard for connecting AI applications to external systems. Its docs call it a “USB-C port for AI applications”. In December 2025 the Linux Foundation formed the Agentic AI Foundation, anchored by MCP, goose and AGENTS.md.
Watch on YouTube
MCP’s Biggest Update Yet
A short explainer on the latest Model Context Protocol update and what it means for the orchestration and tool layer of a generative AI stack, where agents connect to enterprise systems.
Another standard handles agents talking to each other. A2A is an open standard for agent-to-agent communication, developed by Google and later donated to the Linux Foundation. On the framework side, Microsoft Agent Framework is the direct successor to Semantic Kernel and AutoGen, built by the same teams.
| Component | What it does | Examples |
|---|
| Agent framework | Defines steps, state and multi-agent workflows | LangGraph, Microsoft Agent Framework |
| Tool protocol | Connects a model to data sources and actions | MCP servers for files, databases and SaaS apps |
| Agent-to-agent protocol | Lets agents from different vendors delegate work | A2A |
| Approval step | Pauses an action until a person signs off | Human-in-the-loop checkpoints in the framework |
The Decision Rule for Agents
The rule is simple. Give an agent read access freely, but put an approval step in front of every write until the evaluation data says it is safe. That caution has a cost basis too, because Gartner predicts over 40% of agentic AI projects will be canceled by the end of 2027. It cites escalating costs, unclear business value and inadequate risk controls.
When your first use case only answers questions, you can defer most of this layer. Our guides to AI agent frameworks, the Model Context Protocol and MCP and A2A go deeper once you are ready.
Inference, Hosting and Compute
Inference is where the model actually runs. You either call a managed API and pay per token, or you host an open-weight model on your own GPU capacity.
Managed APIs suit most first projects, because there is nothing to operate. Self-hosting makes sense when data cannot leave your environment or volume is high and steady. It also helps when you need a model the APIs do not offer. For that route, vLLM is an open-source serving engine that uses PagedAttention and continuous batching to push more requests through each GPU.
Data residency adds a price uplift on the managed route. As of October 2026, Anthropic charges 1.1 times the standard rate for US-only inference. OpenAI adds 10% for regional data residency endpoints on models released on or after 5 March 2026. So price those uplifts in early if your legal team requires them.
Evaluation, Observability and LLMOps
Evaluation is how you know the stack works, while observability is how you know it keeps working. Without both, every model upgrade or prompt change is a guess.
The practical setup has four parts, and the first one matters most. Build it before you pick a model, so that the choice rests on your own questions rather than public benchmarks.
- An offline evaluation set: 100 to 300 real questions with approved answers, scored whenever anything changes.
- Online tracing: a record of each request, the retrieved context, the tools called and the final answer.
- Cost and latency dashboards: spend per team, per use case and per model, together with alerts on spikes.
- Regression gates: a rule that blocks a release when the evaluation score drops below the last good version.
Our guides to LLM observability and the LLM evaluation framework cover tooling choices in detail.
Talk to Kanerika
Choosing Each Layer of Your Stack?
Bring one use case and its data sources. Kanerika will help you pick an option for each layer, build the evaluation set and add the controls that pass security review.
Book a Working Session →
Security, Identity and Guardrails
Security in a generative AI stack comes down to one question. Can the model reveal or do something the user could not? The answer has to be “no”, and the design itself has to guarantee it.
That means the controls sit in several layers at once. Identity flows from the user into retrieval, while input checks screen for prompt injection. Output filters then catch sensitive data before it leaves, and audit logs give legal the record it asked for in our opening scenario.
- Identity-aware retrieval: search runs as the user, so restricted files never reach the prompt.
- Prompt-injection checks: screen user input and retrieved content for instructions that try to override the system prompt.
- Output filters: block personal data, secrets and policy breaches before a response leaves.
- Audit logs: keep prompts, sources, tool calls and answers for as long as your regulators expect.
None of this should wait until production. Our AI security framework maps these controls to common threats.
Programming Languages and Frameworks
The language layer is the glue, and it is the least risky choice in the stack. Python stays the default, because nearly every model SDK, evaluation tool and agent framework ships for it first.
Enterprise teams do not have to switch languages, though. Microsoft Foundry offers SDKs in Python, C#, JavaScript and Java, so a .NET or Java shop can build in the language it already supports. TypeScript is also common for front ends and lighter agent services.
Deep learning frameworks such as PyTorch belong in the stack only if you train or fine-tune models yourself. Most enterprises that consume models through APIs never touch them.
Model Selection Matrix: Closed, Open-Weight and Small Models
Choosing a model is really choosing a tier, then a vendor within that tier. Price, speed and control move together, so the cheapest model for one task is the wrong model for another.
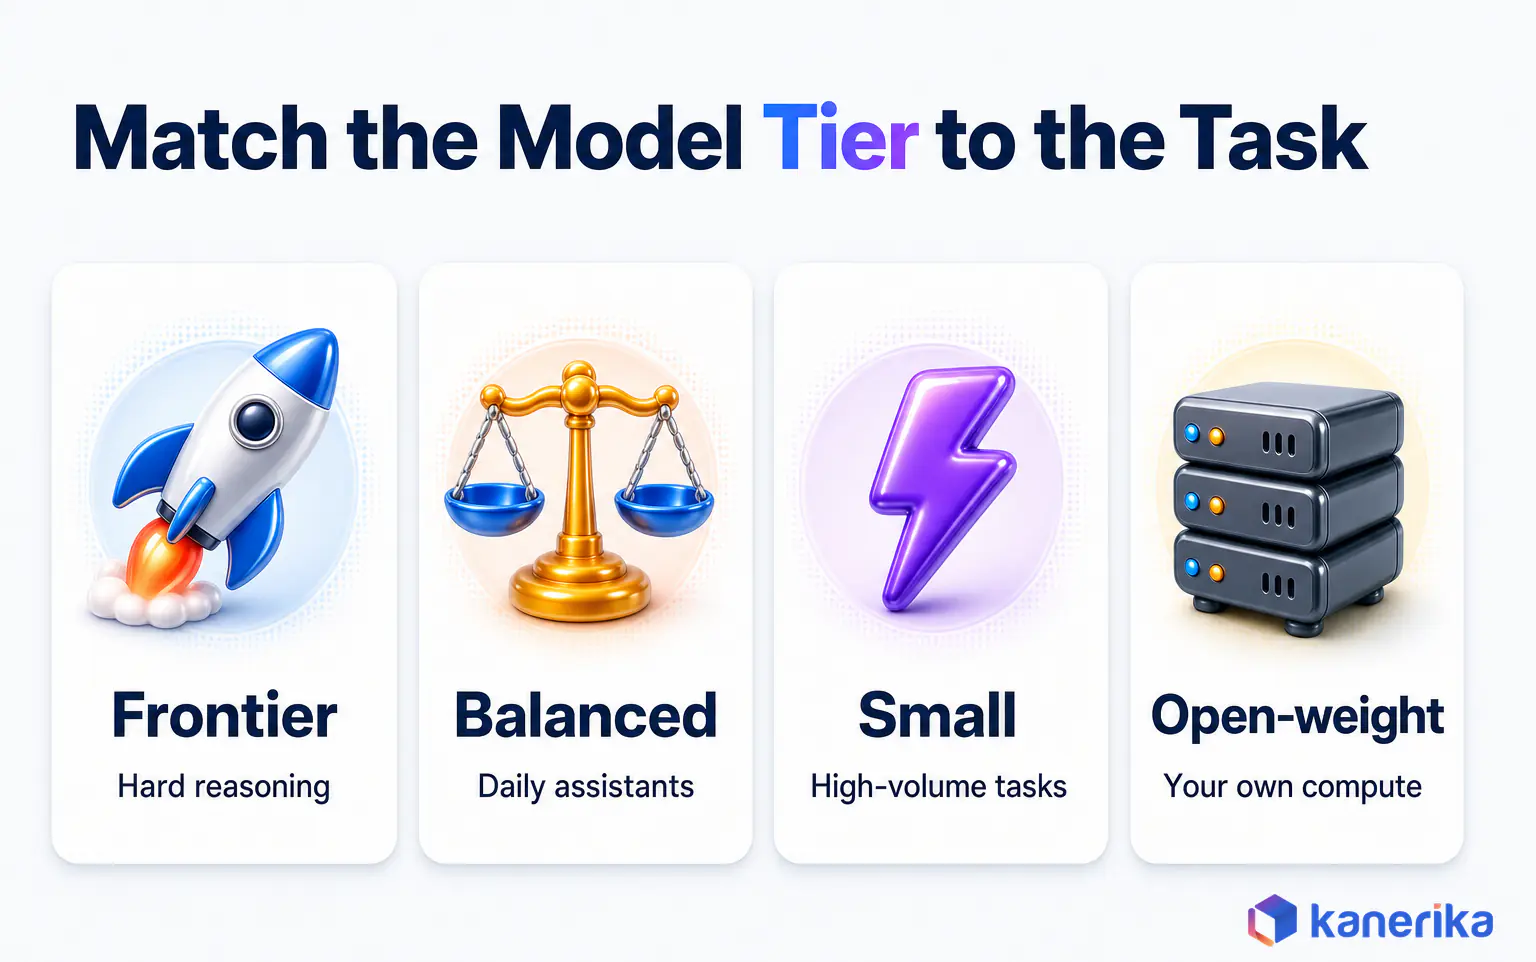
The matrix below uses list prices as of October 2026, per million tokens, input then output. Claude prices come from Anthropic’s pricing page, while OpenAI prices come from OpenAI’s API pricing page. Prices change often, so check both before you budget.
| Option | Examples | Cost per 1M tokens, in / out (Oct 2026) | Latency | Data control | Best fit |
|---|
| Frontier closed | Claude Fable 5.1, gpt-6-astra | $10 / $50 for both | Slower than the other tiers | Vendor cloud, with residency options at a premium | Hard reasoning, complex agents and low-volume expert work |
| Balanced closed | Claude Sonnet 5.5, gpt-6.1-sol | $2 / $10 for both | Moderate | Vendor cloud, with residency options at a premium | Most assistants, especially RAG and coding help |
| Small and fast closed | Claude Haiku 5.5, gpt-6-luna | $0.10 / $0.50 for both (Haiku 5.5 for prompts up to 100K tokens) | Faster than the other tiers | Vendor cloud | Classification, extraction and routing at high volume |
| Open-weight, self-hosted | Llama, Mistral and Gemma families | Your compute | Depends on your hardware | Full control inside your environment | Strict residency, steady high volume or custom tuning |
How to Read the Matrix
Two things stand out in that table. Both the frontier and balanced tiers are priced the same at the two vendors, so the choice comes down to quality on your own evaluation set. The small tier, meanwhile, costs a twentieth of the balanced tier, which is why routing pays off so quickly.
Open-weight models are not free, either. You trade a token bill for GPU capacity, engineers to run it, and the work of patching models yourself. Our guides on open-source LLMs and small language models compare the options in more depth.
A sensible default for a first build pairs a balanced model for answers with a small model for routing and extraction. Keep a frontier model in reserve until your evaluation set proves a task needs it. Anthropic’s Claude Opus 5.5, at $4 / $20, is a premium tier between the two if a task outgrows the balanced model.
Managed Platforms Compared: Microsoft Foundry, Amazon Bedrock and Google’s Gemini Platform
A managed AI platform bundles several layers, usually model access, agent tooling and evaluation, behind one bill and one security model. For most enterprises the right platform is the one that sits next to their data and identity system.
Each of the big three now covers similar ground. Microsoft Foundry describes itself as a platform that “unifies agents, models, and tools”, with tracing, monitoring and evaluations built in. Amazon Bedrock gives access to hundreds of foundation models, as well as Bedrock AgentCore for running agents with any framework and model.
Google now sells its offering as the Gemini platform, and the old cloud.google.com/vertex-ai address redirects there. Its Model Garden lists more than 200 models and tools, including Claude and Gemma.
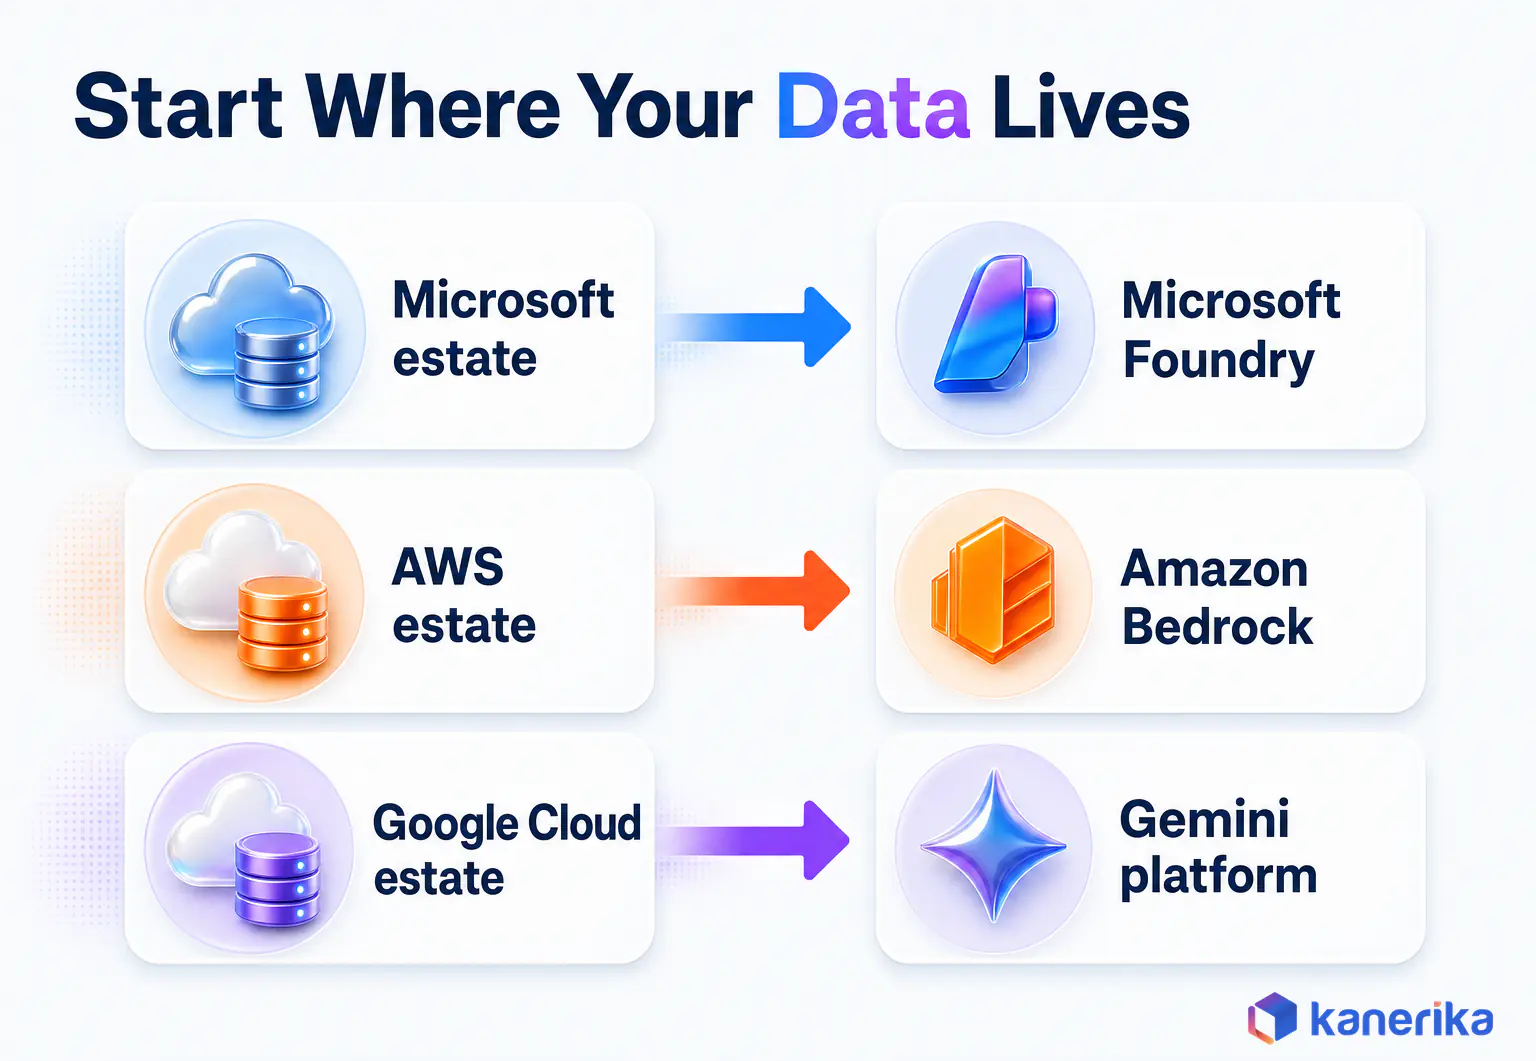
Which Platform Fits Your Estate
The table compares the three on the points that usually decide a shortlist. Read the last column first, since it tends to settle the choice before features do.
| Platform | Model access | Agent tooling | Evaluation and monitoring | Best fit when |
|---|
| Microsoft Foundry | More than 10,000 models from Microsoft, OpenAI, Anthropic, Meta and others | Foundry Agent Service, including hosted agents built with Microsoft Agent Framework, LangGraph or Semantic Kernel | Tracing, monitoring and evaluations built in | When you run Microsoft 365, Entra ID, Fabric or Azure |
| Amazon Bedrock | Hundreds of foundation models | Bedrock AgentCore, with any framework and model | Model evaluation tools, AgentCore tracing and evaluation, Guardrails | When your data and apps live mainly on AWS |
| Google’s Gemini platform | More than 200 models and tools in Model Garden | Agent building and deployment on the same platform | Model Evaluation service, plus model monitoring for input skew and drift | When your data sits in Google Cloud or BigQuery |
Pick the platform your data already lives on, and the security review gets much shorter. Multi-cloud estates can still use one platform for models while calling the others through MCP or plain APIs. If you are weighing Microsoft’s option in detail, our Azure AI Foundry guide covers setup and pricing.
Build, Buy, or Reuse Each Component
Every layer gives you three choices: reuse what you already run, buy a managed service, or build something custom. The cheapest stack is usually the one that reuses the most.
Reuse comes first because it inherits approvals you already have. Your identity provider, search index and lakehouse have passed security review once, so extending them is faster than onboarding a new vendor. Buy comes next for anything that needs constant upkeep, such as model hosting. Finally, build only where the component is your edge or no product fits.
| Layer | Reuse what you have | Buy managed | Build custom | Signal to build |
|---|
| Data and catalog | Existing lakehouse and catalog | Managed catalog add-ons | Rarely | When no catalog exists and none fits your sources |
| Models | Models already approved in your cloud | API access through a platform | Fine-tuned or self-hosted models | When residency is strict or a narrow task runs at huge volume |
| Retrieval | Enterprise search, or Postgres with pgvector | Managed vector or search service | Custom chunking and ranking | When answer quality stalls on your evaluation set |
| Orchestration | Workflow tools you already run | Platform agent services | Graph-based agent code | When workflows need approvals and state across many steps |
| Evaluation and LLMOps | Existing monitoring stack | Platform tracing and evals | Domain-specific scorers | When generic scores miss what your experts care about |
| Security | Identity provider, DLP and audit logging | Guardrail services | Custom policy checks | When regulated outputs need rules that no product covers |
One pattern shows up again and again. Teams build a custom vector store or agent runtime early, then spend months maintaining it. Starting with the boring option keeps the team focused on the use case until the evaluation set demands more. When you do need custom code, our AI application development team builds those pieces on top of the platform you already run.
When Agents Change the Build Decision
Agents raise the build question most sharply. A question-answering assistant can run almost entirely on bought and reused parts. An agent that files tickets, updates records or calls other agents, by contrast, usually needs custom workflow logic, approval steps and testing. That is the point where outside help tends to pay off.
How Much Does a Generative AI Tech Stack Cost?
The cost of a generative AI tech stack splits into a running bill and a build bill. The running bill is mostly tokens, while the build bill covers integration, evaluation and review work.
Leaders often fixate on token prices because they are published and easy to compare. In practice the token line is predictable and often modest. The harder costs are the weeks spent connecting systems, cleaning permissions and proving quality to reviewers.
What Drives the Bill
Six lines make up almost every generative AI budget. Some recur monthly, while others land once during the build.
- Tokens: input and output tokens across every model call, especially retrieved context.
- Retrieval and data prep: chunking, embedding and indexing, as well as keeping indexes fresh.
- Integration engineering: connectors to source systems, identity and the apps where users work.
- Evaluation and monitoring: building the evaluation set, then running tracing, dashboards and regression checks.
- Security reviews: threat modelling and penetration tests before legal sign-off.
- People: a product owner and engineers, together with subject experts who review answers.
Worked Example: Monthly Token Cost for an Internal Assistant
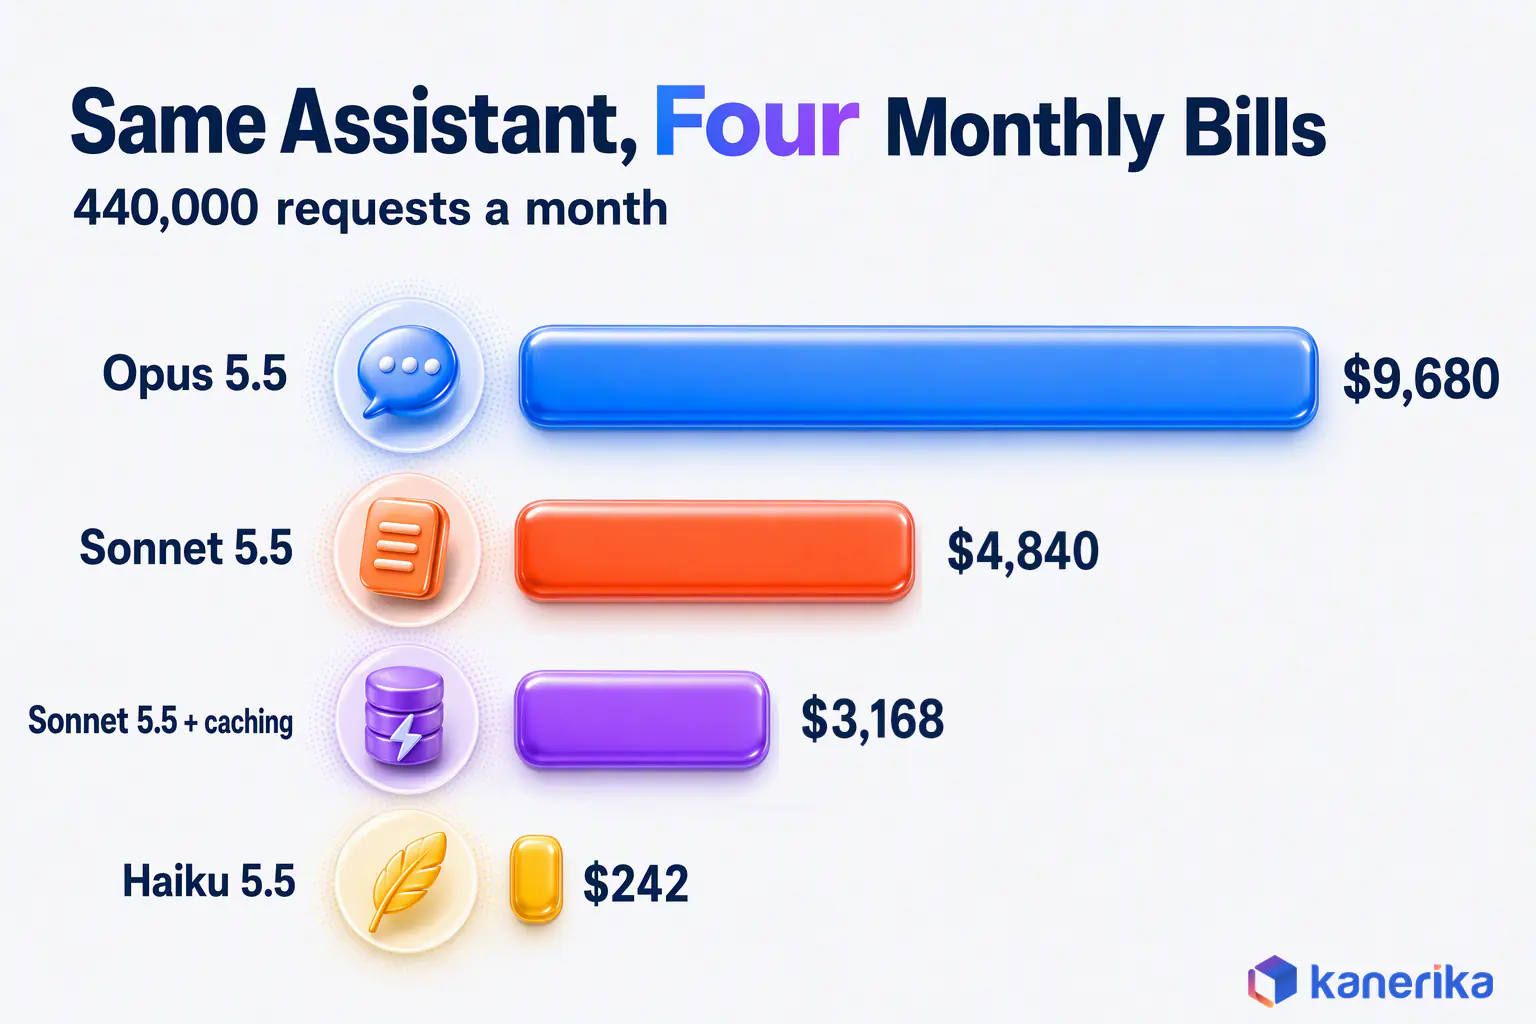
Here is the token bill for the policy assistant from our opening scenario. The assumptions are 1,000 users asking 20 questions each on 22 workdays, which gives 440,000 requests a month.
Each request carries 3,000 input tokens, mostly retrieved context, and returns 500 output tokens. That adds up to 1,320 million input tokens and 220 million output tokens per month. Prices are standard list prices as of October 2026.
| Model and option | Input cost | Output cost | Monthly total |
|---|
| Claude Opus 5.5, Anthropic’s premium tier ($4 / $20) | $5,280 | $4,400 | $9,680 |
| gpt-6-astra ($10 / $50) | $13,200 | $11,000 | $24,200 |
| Claude Sonnet 5.5 or gpt-6.1-sol ($2 / $10) | $2,640 | $2,200 | $4,840 |
| Sonnet 5.5 with a cached 2,000-token shared prefix | $968 | $2,200 | $3,168 |
| Sonnet 5.5 through the Batch API (offline jobs only) | $1,320 | $1,100 | $2,420 |
| Claude Haiku 5.5 or gpt-6-luna ($0.10 / $0.50) | $132 | $110 | $242 |
The caching row assumes 2,000 of the 3,000 input tokens are a shared prefix, such as system instructions and standard policy text. Cache hits on Sonnet 5.5 cost 5% of the input price, so input drops from $2,640 to $968. That figure excludes cache-write charges, which add a little on top.
The Batch API halves both prices, but only for work that can wait, such as overnight document summaries. Pinning Sonnet 5.5 to US-only inference at 1.1 times the rate would also lift the standard $4,840 to $5,324.
So a balanced-tier assistant for 1,000 people costs a few thousand dollars a month in tokens. In our experience that is usually not the biggest line. Integration and evaluation work typically outweigh it during the first year, so budget for them explicitly.
Five Ways to Keep Costs Under Control
Token bills grow quietly as usage spreads. These five habits keep them predictable without hurting answer quality.
- Route by task: send classification, extraction and simple questions to a small model, so larger tiers only see hard requests.
- Cache shared prompts: put stable instructions and reference text at the start of the prompt so that cache hits apply.
- Batch offline work: run summaries, tagging and reports through batch endpoints when they can wait, at half price.
- Cap context size: retrieve fewer, better chunks rather than stuffing the prompt, since input tokens dominate the bill.
- Set budgets per team: tag spend by team and use case, then alert the cost owner before a limit is reached.
Together, routing and caching usually matter more than the vendor choice. In the worked example, both balanced models cost the same, so switching between them saves nothing. Moving routine questions to the small tier and caching the shared prefix, by contrast, cuts the bill directly.
Governance Requirements That Shape the Stack
Governance rules decide parts of the stack before engineering does. They tell you which logs to keep, which disclosures to show users, and how much testing a use case needs.
EU AI Act Dates After the Digital Omnibus
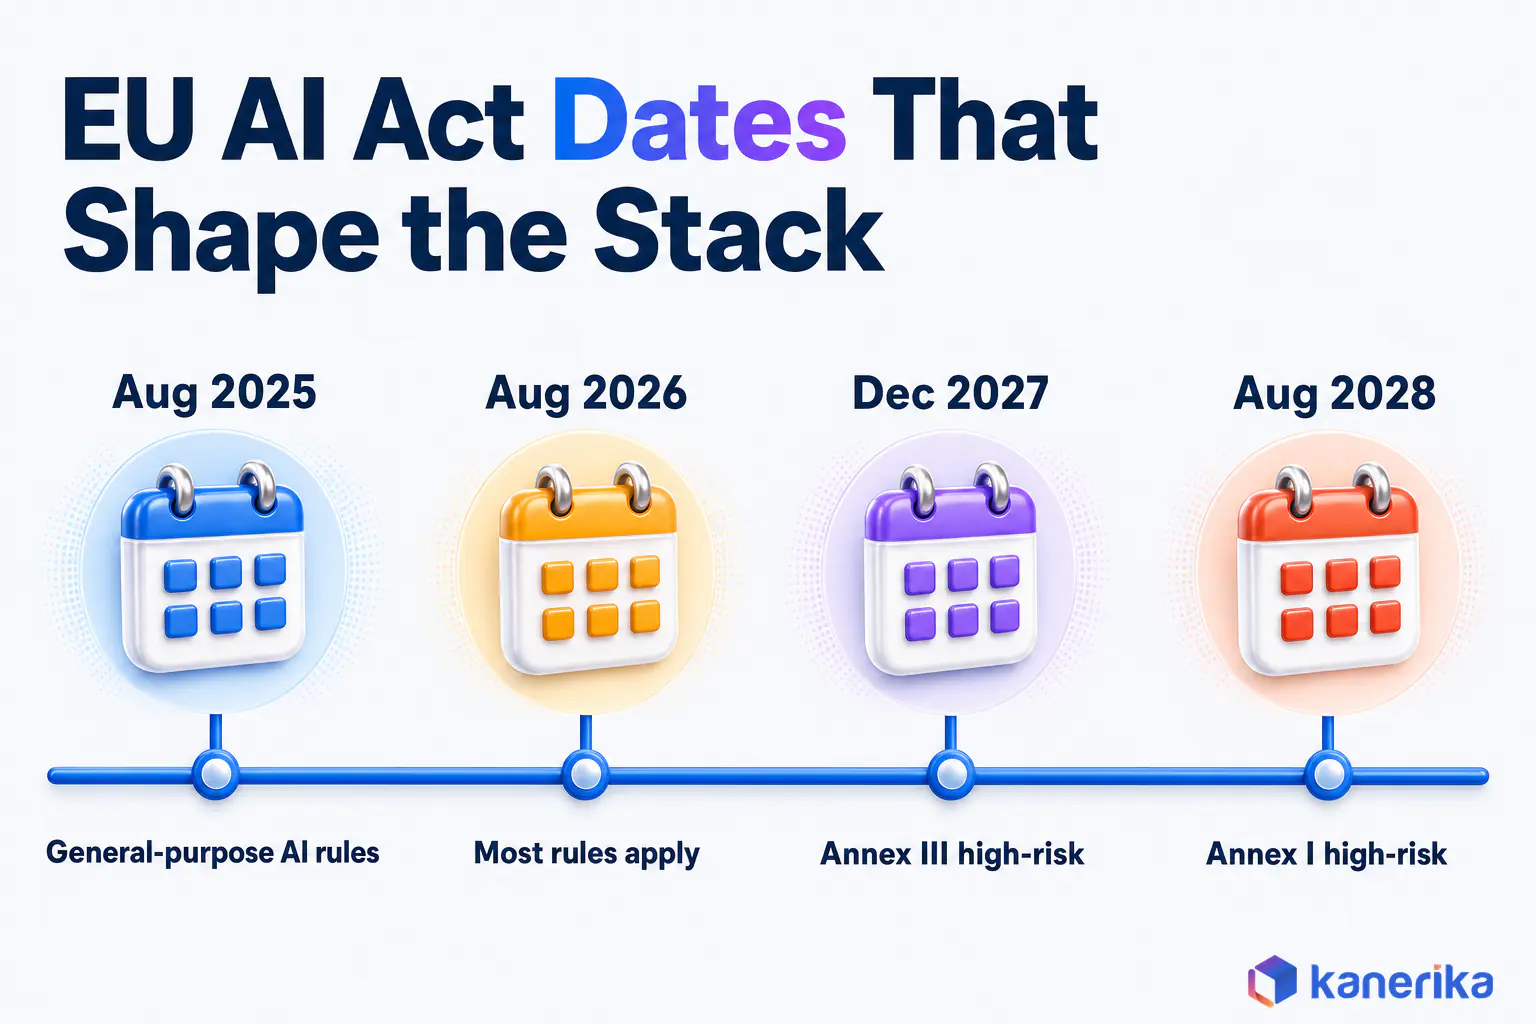
The dates are now concrete, which makes planning easier. Under the EU AI Act implementation timeline, rules for general-purpose AI models applied from 2 August 2025. The majority of the rules, including Article 50 transparency duties and enforcement, applied from 2 August 2026.
High-risk systems come later. Annex III high-risk obligations apply from 2 December 2027, while Annex I high-risk obligations follow on 2 August 2028. If your use case touches hiring, credit or essential services, plan your evaluation and logging layers around those dates now.
US Frameworks and ISO/IEC 42001
US buyers usually anchor on voluntary frameworks instead. NIST released the AI Risk Management Framework 1.0 on 26 January 2023, and then the NIST AI 600-1 Generative AI Profile on 26 July 2024. ISO/IEC 42001, published in December 2023, sets out a certifiable AI management system.
A common approach is to adopt the NIST profile as the internal policy baseline. Each of its controls then maps to a layer of the stack, so owners know what they are accountable for. NIST says AI RMF 1.0 is being revised under the White House AI Action Plan, so check for a newer version before you lock the baseline.
What Each Rule Changes in the Stack
| Requirement | Date or status | What it changes in the stack | Layer |
|---|
| EU AI Act general-purpose AI rules | Applied from 2 August 2025 | Ask model vendors for their documentation and policies before you sign | Models |
| EU AI Act Article 50 transparency and most rules | Applied from 2 August 2026 | Tell users when they are dealing with AI, and label generated content. Generative systems already on the market before 2 August 2026 have until 2 December 2026 to meet the Article 50(2) labelling duty | Application and security |
| EU AI Act Annex III high-risk | From 2 December 2027 | Risk management, logging and human oversight, as well as accuracy testing | Evaluation, security and orchestration |
| EU AI Act Annex I high-risk | From 2 August 2028 | The same duties for AI inside regulated products | All layers |
| NIST AI RMF and AI 600-1 | Voluntary, released in 2023 and 2024 | A shared language for mapping, measuring and managing risk | Evaluation and security |
| ISO/IEC 42001:2023 | Certifiable standard | Policies, roles and audits for the whole AI program | Governance across layers |
This section is a planning guide rather than legal advice, so confirm obligations with counsel. Our AI governance framework guide shows how to turn these rules into owners and controls.
The practical takeaway is that logging, evaluation and human oversight are not extras. An assistant that screens job applicants, for example, falls under Annex III. Its stack therefore needs logged decisions, documented testing and a person who can overrule it. Build these pieces into the pilot and you will not need to retrofit them when an auditor asks.
Checklist
AI Governance Checklist
A practical checklist for turning AI rules into owners, controls, logs and reviews before your generative AI stack goes live.
Get the Checklist →
Which Stack Fits Which Enterprise Scenario?
The right generative AI tech stack depends on what the application does, rather than on which vendor is fashionable. Four common scenarios show how the same layers get different settings.
Read across each row to see the pattern. The riskier the action, the more weight shifts from the model to orchestration and controls.
| Scenario | Model choice | Retrieval | Orchestration | Platform | Control that matters most |
|---|
| Internal knowledge assistant | Balanced tier, together with a small model for routing | Existing search or pgvector over policy documents | Simple chain with no write access | The platform next to your identity system | Identity-aware retrieval |
| Customer-support agent that takes actions | Balanced tier, then frontier for escalations | Knowledge base as well as order and account data | Agent framework with MCP tools and approvals | Platform with an agent runtime and tracing | Approval step before refunds or account changes |
| Regulated finance document review | Balanced or frontier tier, with residency pinned | Permissioned document store with sensitivity labels | Review workflow with human sign-off | Platform in your required region | Audit logs and evaluation evidence |
| High-volume classification and extraction | Small model, or open-weight when volume is steady | Usually none, since the input is the document | Batch pipeline | Batch API or self-hosted vLLM | Sampled accuracy checks and cost per item |
Notice that none of the four starts with “pick the best model”. Each starts with the data the application may touch and the action it may take. Model choice then follows from those two answers.
If your scenario mixes two rows, such as an assistant that sometimes files tickets, design for the riskier row. It is easier to relax a control later than to add one after users rely on the system.
Seven Stack Mistakes That Stall Production
Most stalled projects share the same few mistakes, and each one maps to a layer that was skipped. Spotting them early is cheaper than any tool purchase.
The layer sections above give the rule for each one. Below, each mistake is traced through the opening scenario’s policy assistant.
- Choosing a model before the data and permissions. The team picked a model first and pointed it at a shared folder. When security asked about salary bands, nobody knew, and the review stopped.
- Shipping without an evaluation set. When leadership asked whether a prompt change helped, the engineers could only show screenshots. Every later change waited on a manual re-test.
- Giving agents write access with no approval step. Had the assistant booked travel directly, one wrong answer would have become a wrong booking, and legal would have held the launch.
- Buying a vector database by default. A dedicated store adds a vendor to the security review and another copy of sensitive files. For one folder of policy PDFs, existing search or pgvector would have done the same job.
- Leaving the bill without an owner. Finance asked what 1,000 users would cost, and nobody held the usage figures. The budget request stalled until someone owned the estimate.
- Bolting security on after the pilot. Adding identity-aware retrieval later meant re-indexing every document with its permission labels, a bigger job than building it in.
- Locking into one vendor with no exit plan. Prompts tuned to one model and tools wired to one SDK leave little room when prices change. Keep prompts, evaluation sets and tool definitions portable, and use open protocols such as MCP.
Fixing even three of these before launch removes most of the questions that stalled the assistant.
How Kanerika Builds Generative AI Tech Stacks
Kanerika builds generative AI applications for enterprises that need them to pass security, finance and legal review as well as the demo. As a Microsoft partner, Kanerika works across Microsoft Foundry and Fabric, and the same method applies on AWS or Google Cloud.
Two Kanerika products cover common layers, so clients do not build them from scratch. KlarityIQ handles document intelligence over unstructured files, while Karl answers natural-language questions over structured databases. Both run inside the client’s environment with the client’s access rules.
Datasheet
KlarityIQ: Your Document Intelligence Agent
See how KlarityIQ reads, classifies and answers questions over enterprise documents with access rules applied, with scope and outcomes on one page.
View the Datasheet →
A Five-Stage Method That Keeps the Stack Small
The method keeps the stack as small as the use case allows. It also front-loads the decisions this guide covers, so that the hard questions get answered before engineering time is spent.
- Assess the workload and data: map the use case, its source systems and sensitivity labels, as well as who may see what.
- Pick the minimum stack: choose one option per layer, reusing existing search, identity and data platforms wherever possible.
- Run a controlled pilot: build the evaluation set first, then test models and retrieval against it with real users.
- Add production controls: identity-aware retrieval, guardrails, tracing, cost alerts and audit logs before wider release.
- Measure and expand: track quality, cost per answer and adoption, then add the next use case on the same stack.
Case Study: Governed Retrieval for an Investment Bank
A leading investment bank needed answers from two very different sources: unstructured documents such as RFI repositories, and structured enterprise databases. Access controls had sat outside the retrieval process. As a result, each new retrieval path reopened the same compliance questions.
Kanerika deployed KlarityIQ for the unstructured documents and Karl for the structured database queries. Role-based access was applied inside retrieval itself, so every answer respected the user’s permissions by design.
Together, these choices delivered 43% faster information retrieval across documents and databases and a 35% improvement in workforce efficiency. Because authorization sat inside the retrieval layer, the bank achieved 100% role-based compliance at the point of retrieval. The full story is in the investment bank AI document retrieval case study.
Case Study
43% Faster Document Retrieval for an Investment Bank
A leading investment bank applied role-based access inside retrieval with KlarityIQ and Karl, reaching 43% faster information retrieval, 100% role-based compliance and 35% higher workforce efficiency.
Read the Case Study →
If you are planning your own stack, Kanerika’s generative AI consulting team can review your data, model and governance choices with you. You can also book a working session to scope a first governed use case.
Wrapping Up
A generative AI tech stack is eight layers rather than one product, and most of the risk sits outside the model. Data access, retrieval quality, evaluation and security decide whether a pilot reaches production. Token prices matter, yet they are rarely the line that stalls a project.
So what should you know before you build? Decide which data the model may see and which model tier each task needs. Then name who owns the monthly bill and which governance rules apply, and build the smallest stack that answers all four.
Frequently Asked Questions
What is the tech stack of generative AI?
A generative AI tech stack is the set of layers used to build and run generative AI applications. It covers the data foundation, foundation models, retrieval, orchestration and agents, inference and hosting, evaluation and LLMOps, security and guardrails, and the programming languages and SDKs that connect them. Most enterprises reuse their existing data platform and identity system inside it.
What is full stack generative AI?
Full stack generative AI means owning every layer an application needs, from data and retrieval through the model, orchestration and user interface to monitoring and security. A full stack team can take a use case from raw documents to a governed production assistant. In practice most enterprises buy some layers, such as model hosting, and build the rest.
Should enterprises use open-source or commercial LLMs?
Most enterprises use both. Commercial models through an API give strong reasoning with no hosting work and suit most assistants. Open-weight models such as Llama, Mistral or Gemma suit strict data residency, steady high volume or custom tuning, but they move the cost to GPUs and engineers. Let your evaluation set and residency rules decide each task.
What is the best cloud platform for generative AI?
The best platform is usually the one next to your data and identity system. Microsoft Foundry suits Microsoft 365, Entra ID and Fabric estates, Amazon Bedrock suits AWS-centred teams, and Google’s Gemini platform suits Google Cloud users. All three offer many models and agent tooling, so security review speed often decides the choice.
What is LLMOps in a generative AI stack?
LLMOps is the operating discipline for language model applications. It covers an offline evaluation set scored on every change, tracing of prompts, retrieved context and tool calls, cost and latency dashboards, and regression gates that block a release when quality drops. LLMOps is how a team proves an assistant keeps working after launch and model upgrades.
How much does it cost to build a generative AI tech stack?
Costs split into a running token bill and a build bill. As of October 2026, an assistant serving 1,000 users with 440,000 requests a month costs about $4,840 on Claude Sonnet 5.5 or gpt-6.1-sol and $242 on the small tier. Integration, evaluation and security reviews usually cost more than tokens in the first year.
Can generative AI run on-premises?
Yes. Open-weight models such as Llama, Mistral and Gemma can run on your own GPU servers using a serving engine like vLLM. This keeps data inside your environment and suits strict residency rules. The trade-off is that you own capacity planning, patching and model upgrades, so many teams start with managed APIs and move later.
How do you secure a generative AI tech stack?
Secure it in layers. Run retrieval with the user’s identity so restricted files never reach the prompt, screen inputs and retrieved content for prompt injection, filter outputs for personal data and secrets, and keep audit logs of prompts, sources and answers. Put an approval step in front of any agent action that writes to business systems.
What is MCP and where does it fit in the generative AI stack?
The Model Context Protocol is an open-source standard for connecting AI applications to external systems such as files, databases and SaaS tools. It sits in the orchestration layer, where agents call tools. Since December 2025 it has been part of the Linux Foundation’s Agentic AI Foundation, which makes it a safer choice for avoiding vendor lock-in.
What is the difference between a generative AI framework and a model?
A model, such as Claude Sonnet 5.5 or Llama, is the trained network that generates text or code. A framework, such as LangGraph or Microsoft Agent Framework, is the code library you use to call models, manage state, connect tools and build multi-step workflows. You can usually swap the model without rewriting the framework code.
How long does it take to build an enterprise generative AI application?
It depends mostly on data readiness, integration work and approval cycles rather than model setup. A scoped pilot on clean, well-labelled data with an evaluation set can move in weeks. Production takes longer, because identity-aware retrieval, guardrails, audit logs and security and legal reviews all need to be in place before wider release.
What are generative AI tools?
Generative AI tools are applications and services that create text, code, images or audio from a prompt. They include chat assistants, coding assistants and image generators for end users, plus developer tools such as model APIs, agent frameworks, vector search and evaluation platforms. In a tech stack, the developer tools are the building blocks.
What are the three layers of the generative AI stack?
Many guides describe three layers. The infrastructure layer supplies compute and hosting, the model layer supplies foundation models, and the application layer turns them into products people use. That view is useful for a quick explanation, yet enterprise teams usually split it further into eight layers so data, retrieval, evaluation and security each get a clear owner.
Does generative AI use deep learning?
Yes. Modern generative AI models, including large language models and image generators, are deep neural networks trained on very large datasets. Most enterprises never train them, though. They consume pretrained models through an API or host open weights, so deep learning frameworks such as PyTorch only matter when you fine-tune or train models yourself.
Is ChatGPT an LLM or generative AI?
Both, in a sense. ChatGPT is a generative AI application, a chatbot product built on top of OpenAI’s large language models. The LLM is the underlying model that generates text, while ChatGPT adds the interface, memory, tools and safety layers. Many enterprise chatbots follow the same pattern with their own data and controls.
What is the difference between an AI tech stack and an LLM stack?
An AI tech stack is the broad term for every tool used to build AI systems, including classic machine learning for forecasting or fraud scoring. An LLM stack is the subset built around large language models, with retrieval, prompt orchestration, evaluation of open-ended answers and guardrails. A generative AI tech stack is closest to the LLM stack.
What is the infrastructure layer of generative AI?
The infrastructure layer is where models actually run. It includes managed model APIs, cloud AI platforms such as Microsoft Foundry or Amazon Bedrock, and GPU capacity for teams that host open-weight models themselves with a serving engine like vLLM. Data residency, latency and steady volume decide whether you rent inference through an API or run it yourself.
How is a generative AI stack different from a traditional machine learning stack?
A traditional machine learning stack trains a model on labelled data for one task and judges it on accuracy. A generative AI stack usually consumes a pretrained model, grounds it in company data at request time, and evaluates open-ended answers. Cost also shifts from occasional training runs to a steady bill that grows with every token processed.
Which programming language is best for a generative AI tech stack?
Python is the default because most model SDKs, evaluation tools and agent frameworks support it first. Enterprises do not have to switch, though. Microsoft Foundry offers SDKs in Python, C#, JavaScript and Java, and TypeScript is common for front ends and light agent services. Choose the language your team already maintains in production.
Do you need a vector database for generative AI?
Not always. Many pilots work well with the enterprise search you already run or with pgvector, an open-source vector search extension for Postgres. A dedicated vector database makes sense once you hold tens of millions of chunks, need heavy filtering at scale, or see search latency hurt users. Decide based on measured retrieval quality and speed.
Is RAG part of the generative AI tech stack?
Yes. Retrieval-augmented generation sits in the retrieval layer and is how most enterprise assistants use company data. It splits documents into chunks, finds the ones that match a question and passes them to the model as context. RAG is also where permissions must be enforced, because retrieval is the step that pulls documents out of storage.
What is the difference between RAG and fine-tuning?
RAG gives a model fresh facts at request time by retrieving relevant documents, so answers stay current and respect access rules. Fine-tuning changes the model’s weights to teach a style, format or narrow task, and it does not keep facts up to date. Most enterprise assistants start with RAG and fine-tune only when evaluation shows a clear need.














