TL;DR
Google Gemini AI fits teams on Google Cloud or Workspace best: use Gemini 3.8 Flash by default and Gemini 4 Argon for hard reasoning. Argon lists at $2 input and $10 output per million tokens through November 30, 2026, then $4 and $20 from December 1. Gemini 3.8 Flash costs $0.75 and $3.75 through December 31, 2026, and doubles on January 1, 2027. Individuals can start on the free app or Google AI Pro at $19.99 a month, which includes Argon. Businesses get firmer data terms on Gemini Enterprise from $21 per seat, or on the paid API, where prompts do not improve Google’s products. Keep customer data off the free API tier, test both models on your own tasks, and budget on the later prices.
Key Takeaways
- Google Gemini AI is three things at once: a model family, a consumer app and a developer and enterprise platform built by Google DeepMind.
- Gemini 3.8 Flash is the sensible default, while Gemini 4 Argon is the flagship for hard reasoning, with a 1M-token shared context window.
- Two price steps are already scheduled, since Argon doubles on December 1, 2026 and 3.8 Flash on January 1, 2027.
- Google’s free API tier may use prompts to improve its products, while the paid tier and business plans do not.
- Gemini 4 Argon’s November price of $2 and $10 per million tokens equals GPT-6.1 Sol and Claude Sonnet 5.5, so fit and data terms decide.
- Adopt in four steps: one workload with a metric, a head-to-head model test, a capped pilot, then monitored production.
A Gemini Budget That Doubles in Four Weeks
Picture a product team that sized its first Gemini pilot on November 3, 2026. At first the workload looks modest: 10 million input tokens and 2 million output tokens a month on Gemini 4 Argon.
The November bill comes to $40. On December 1 the same traffic costs $80, with no code change and no new users. Nothing broke, and the team still has a budget problem.
That small example also captures what a buyer needs to know about Google Gemini AI in late 2026. The models are strong and the access paths are many, yet prices, model names and data terms all move on published dates. This guide lays out each date, so you can pick a model, a plan and a rollout path with real numbers.
What Is Google Gemini AI?
Google Gemini AI is the name Google uses for its family of large models and for the products built on them. Google DeepMind builds the models, while the same name also covers a chat app, features inside Workspace and a paid API for developers.
That overlap often confuses first-time buyers, especially in procurement. A marketing lead who says “we use Gemini” may mean a $19.99 personal plan, while an engineer means API calls billed per token. Both are correct, but they carry very different costs and data terms.
Gemini sits inside the wider field of generative AI, where models produce text, code, images and audio from a prompt. What sets Google’s family apart, though, is how tightly it connects to Search, Maps, Workspace and Google Cloud.
Gemini the App, the Models and the Platform
The simplest way to sort the name, then, is by who touches it. Consumers and office staff use the app and Workspace features, while developers and IT teams work with the models through an API.
The table below separates the three layers, so you can tell them apart. Keep it in mind whenever a vendor proposal or a colleague says “Gemini” without saying which one.
| Layer | What it is | Who uses it | Where you find it |
|---|---|---|---|
| The app | A chat assistant for questions, writing, images and research | Individuals and office staff | gemini.google.com and mobile apps |
| The models | Gemini 4 Argon, 3.8 Flash, 3.5 Flash-Lite, 3.8 Live and image models | Developers and data teams | Gemini API and Google AI Studio |
| The platform | Gemini Enterprise, Workspace features and Vertex AI on Google Cloud | IT, security and business units | Google Cloud and Workspace admin consoles |
From Bard to Gemini 4: A Dated Timeline
Gemini has changed names and versions quickly, and old articles still describe models that are long gone. So a dated timeline is the fastest way to tell current facts from history.
- February 8, 2024: Google renamed Bard to Gemini and moved the assistant onto the Gemini brand.
- July 21, 2026: Gemini 3.6 Flash and Gemini 3.5 Flash-Lite reached the API.
- September 2, 2026: Gemini 3.8 Flash was released and became the fast default for most work.
- September 15, 2026: Gemini 3.8 Live arrived for real-time audio and voice agents.
- October 13, 2026: Google DeepMind published the Gemini 4 Argon model card, with the model id gemini-4-argon.
- October 2026: Google announced Gemini 4 Carbon, without a price, a model id or an availability date.
Anything older than this list, such as Bard-era features, is history. Treat it that way when you read older comparisons or vendor slides.
The Gemini Model Lineup in November 2026
Choosing a Gemini model comes down to three questions: how hard is the task, how fast must it answer, and how often will it run. Each model in the lineup answers them differently, so the right choice changes from task to task.
Gemini 4 Argon is the flagship and is live on the API. It carries a 1M-token shared context window and can produce long outputs of up to 1M tokens, according to Google’s Gemini models page. Argon has no free tier, and its thinking tokens are also billed as output.
Gemini 3.8 Flash, on the other hand, is the workhorse. It handles drafting, summarizing, extraction and most agent steps at a fraction of Argon’s price, and it also keeps a free tier for testing.
Gemini 3.5 Flash-Lite, meanwhile, is the volume model for classification, routing and simple transforms. Gemini 3.8 Live serves real-time voice, while the Nano Banana models handle image generation and editing. For a broader primer on models that mix text, images and sound, see our guide to multimodal AI.
Prices, Free Tiers and Release Dates
The table below puts the lineup side by side, so you can compare price, free access and age at a glance.
| Model | Best for | Input / output per 1M tokens | Free tier | Released |
|---|---|---|---|---|
| Gemini 4 Argon | Hard reasoning, long documents, complex agents | $2 / $10 through Nov 30, 2026; $4 / $20 from Dec 1 | No | Model card Oct 13, 2026 |
| Gemini 3.8 Flash | Default for chat, drafting, extraction and agent steps | $0.75 / $3.75 through Dec 31, 2026; $1.50 / $7.50 from Jan 1, 2027 | Yes | Sep 2, 2026 |
| Gemini 3.5 Flash-Lite | High-volume classification and routing | $0.30 / $2.50 | Yes | Jul 21, 2026 |
| Gemini 3.8 Live | Real-time voice and audio agents | Text $0.75 / $4.50; audio $3.00 / $12.00 | Yes | Sep 15, 2026 |
| Nano Banana image models | Image generation and editing | See the pricing page | See pricing page | Not covered here |
| Gemini 4 Carbon | Announced only | No price published | No availability published | Announced Oct 2026 |
Prices come from Google’s Gemini API pricing page and release dates from the Gemini deprecations page, both checked on November 3, 2026.
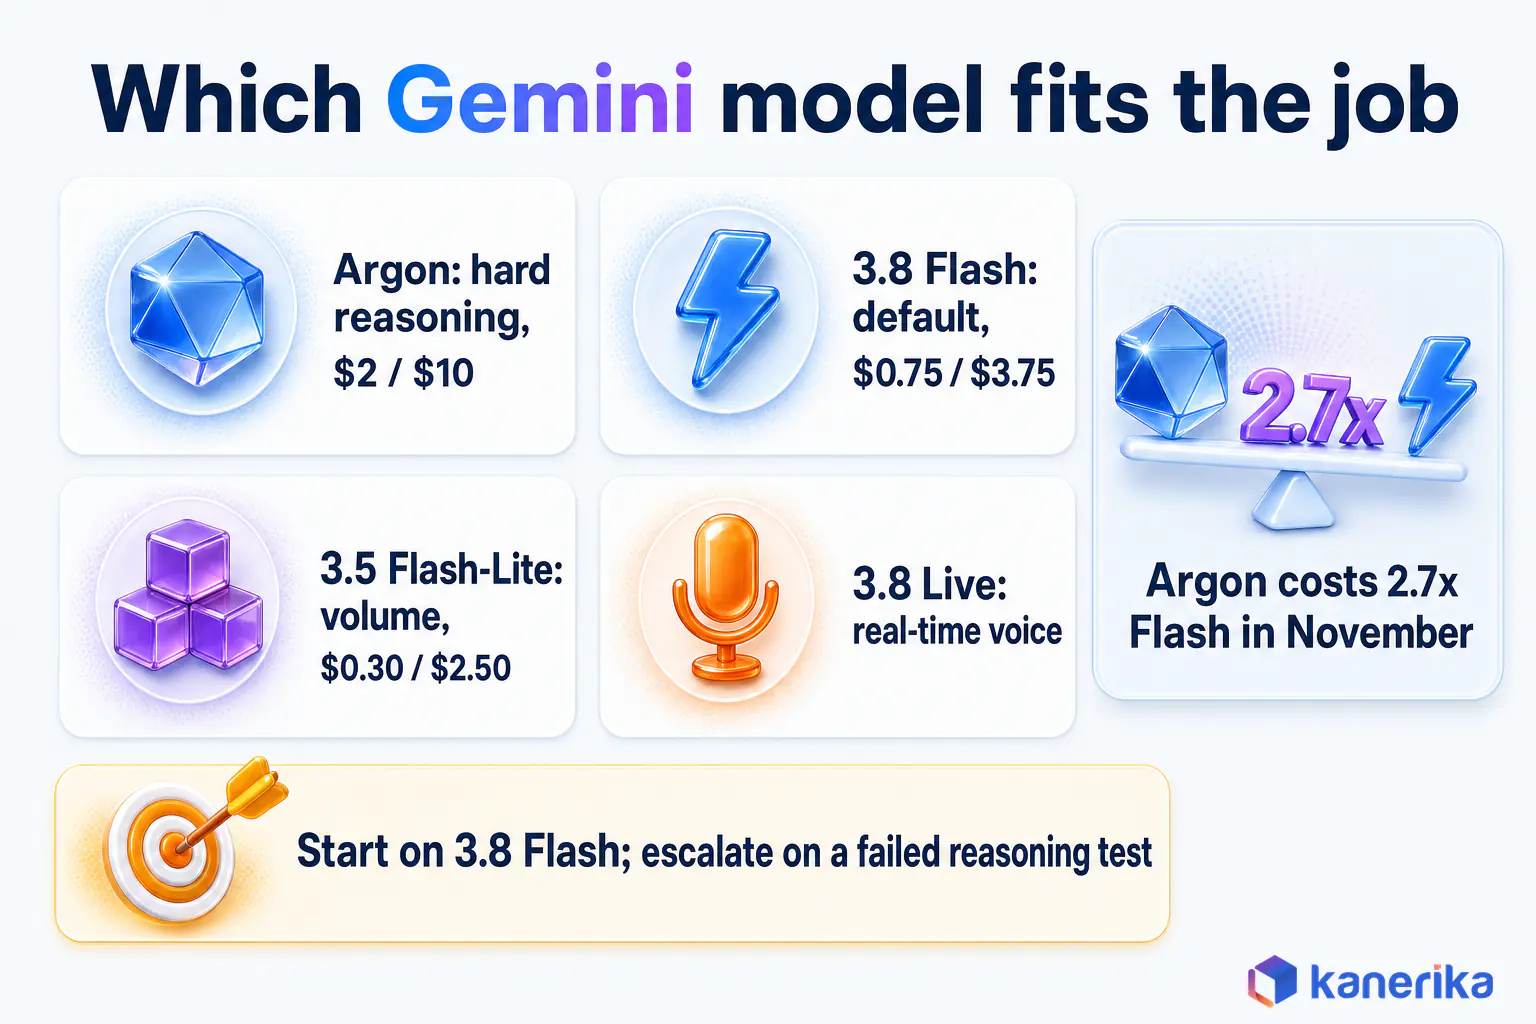
The price gap explains the rule that follows. In November, Argon’s input price of $2 is about 2.7 times Flash’s $0.75, and its output price is 2.7 times as well.
The decision rule is short. Default to Gemini 3.8 Flash, and escalate to Argon only when a task fails your reasoning test. Drop to Flash-Lite when volume matters more than nuance.
What Google Gemini AI Can Do
Gemini’s abilities fall into four groups: it reads many input types, it holds long context, it calls tools, and it translates across languages. Each group matters because it serves a different kind of business task.
Multimodal Input: Text, Images, Audio, Video and PDFs
Gemini models accept text, images, audio, video and PDF files in the same request. For example, a claims team can send a damage photo, the adjuster’s voice note and the policy PDF together. The team can then ask for one summary.
Video works the same way. A training team can upload a recorded product demo, for instance. Gemini then returns a step list, feature timestamps and a short quiz for new hires.
This matters because real business evidence rarely arrives as clean text. Scanned forms, screenshots, recorded calls and slide decks all go in directly, so nobody runs a separate conversion step.
Gemini 3.8 Live extends this to live audio, so an agent can listen and answer in real time. Google’s research on always-on assistants that see and hear is covered in our piece on Google’s Project Astra agent research.
Long Context and Reasoning
Gemini 4 Argon works across a 1M-token shared context window. As a result, a full contract set, a long codebase or hours of transcripts can sit in one prompt.
Argon also supports long decodes of up to 1M tokens, so it can write long reports or large code changes in one pass. Its thinking tokens, the internal reasoning steps, are billed, which makes hard prompts cost more than their visible output suggests.
Long context is useful, but it is not free. A team that pastes every document into every prompt pays for those tokens on each call, so retrieval of the relevant passages still saves money.
Tools: Search and Maps Grounding, Function Calling and Code Execution
Gemini can also call tools during a response. Grounding with Google Search lets the model cite current web results, and grounding with Google Maps adds place data too.
Function calling, for example, lets the model trigger your own APIs, such as a stock lookup or a ticket update. Code execution lets it run code to check a calculation before it answers.
Grounding also has its own price. On paid tiers, Google gives 5,000 free search requests a month, shared across Gemini 3 and newer models. After that it charges $14 per 1,000 requests, up to a daily cap of 1,500 requests.
Real-Time Translation Across Languages
Translation is one of the most practical everyday uses of Gemini. The app can translate typed text, speech and the words in a photo, such as street signs, product labels or a menu.
For travelers and global teams, the camera-based version especially saves time. You point the phone at the text, then read the result in your own language.
Example: While traveling abroad, you could point your phone camera at a restaurant menu with unfamiliar characters. Gemini could instantly translate the menu into your preferred language, making ordering a breeze.
The same ability also helps business teams read supplier documents, customer emails and support chats written in other languages. A reviewer still checks anything contractual, since a translation can miss legal nuance.
Where You Use Gemini: App, Workspace, Gemini Enterprise, API and Vertex AI
Gemini reaches users through five doors, and the right one depends on who will use it and what data goes in. Picking the wrong door is the most common early mistake, because each one carries different prices and data terms.
For example, a single analyst who wants help drafting reports needs a personal plan. Similarly, a support team that wants an agent answering customers needs the API or Gemini Enterprise. Regulated workloads that must sit inside a governed cloud project belong on Vertex AI.
The table below maps each path to its buyer. Prices and terms come from Google’s Gemini subscriptions page and the pricing page, checked on November 3, 2026.
| Path | For whom | Starting price | Data terms | Pick it when |
|---|---|---|---|---|
| Gemini app | Individuals | Free; AI Plus $4.99/month; AI Pro $19.99/month | Personal account terms | One person needs help with writing, research or images |
| Gemini in Workspace | Teams already on Google Workspace | Business plans | Not used for training outside your domain without permission | Staff work in Gmail, Docs, Sheets and Meet every day |
| Gemini Enterprise | Teams deploying agents company-wide | Business from $21/seat/month; Standard and Plus from $30 | Prompts, outputs and tuning never used to train Google models | You want governed agents without building from scratch |
| Gemini API | Developers building apps | Free tier, then per-token pricing | Free tier may improve Google products; paid tier does not | You are building a product or internal tool |
| Vertex AI | Platform and data teams | Usage-based Google Cloud billing | Google Cloud project controls | The workload needs cloud-level governance and integration |
Gemini Enterprise also adds one control that finance teams like. Google’s Gemini Enterprise page describes a budget cap per project, so an agent pauses instead of overspending.
Running Several Paths at Once
Many organizations use more than one path at once. For instance, office staff get Gemini in Workspace, a few analysts get Google AI Pro, and customer apps run on the paid API.
That mix is fine as long as each path has an owner and a policy. The risk comes from staff pasting company data into personal accounts because nobody told them which door to use.
Kanerika Service
Generative AI Development
Kanerika designs and builds generative AI applications on your data, from model choice and retrieval to governance, cost control and production monitoring.
Vertex AI makes most sense when your data platform already runs on Google Cloud. If you are still choosing a cloud, our AWS vs Azure vs Google Cloud comparison covers that wider decision.
Google Gemini Pricing in November 2026
Gemini pricing has two parts: flat monthly plans for people, and per-token API rates for software. Most organizations end up paying for both, so it helps to read them separately.
The consumer and business plans are simple monthly fees, so they are easy to forecast. Google AI Pro at $19.99 a month includes Gemini 4 Argon, so one person can try the flagship without an API account.
| Plan | Price | Who it suits |
|---|---|---|
| Free | $0 | Anyone trying the app |
| Google AI Plus | $4.99/month | Light personal use |
| Google AI Pro | $19.99/month, includes Argon | Power users and individual professionals |
| Google AI Ultra | From $99.99/month | Heavy individual users |
| Gemini Enterprise Business | From $21 per seat/month | Smaller business teams |
| Gemini Enterprise Standard and Plus | From $30 per seat/month | Larger organizations |
API Prices and the Two Price Steps
API pricing is where budgets move, because the rates change on published dates. Two main models carry introductory rates with fixed end dates. So the price you test with is lower than the price you will run on.
| Model | Input / output per 1M tokens now | Input / output per 1M tokens later |
|---|---|---|
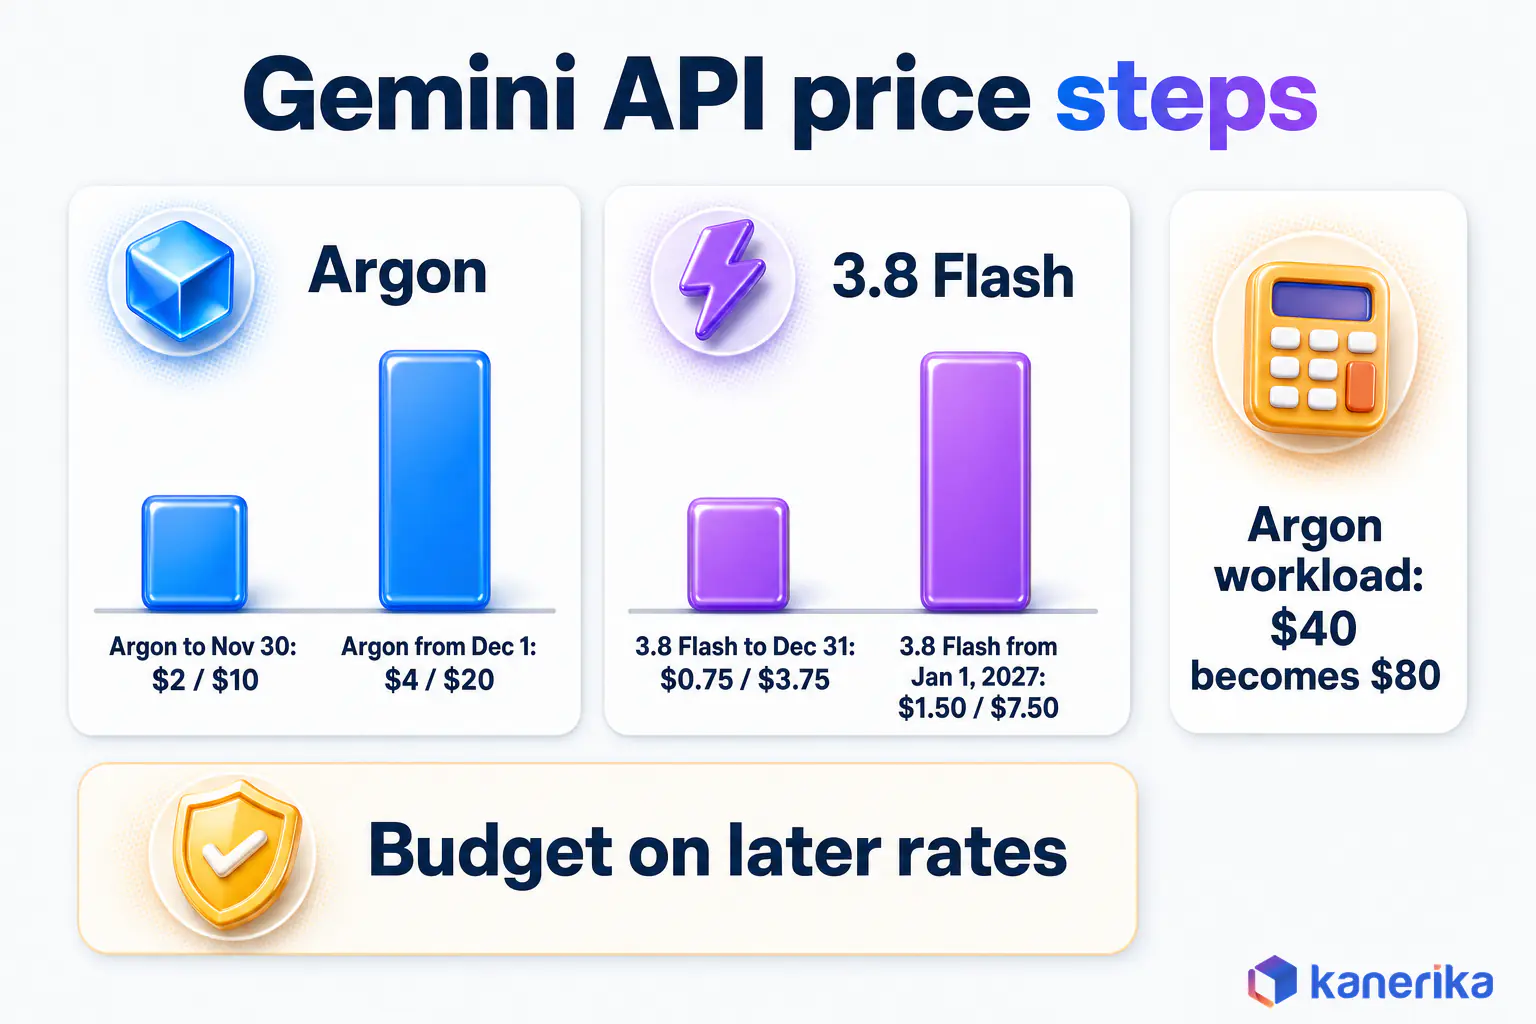
| Gemini 4 Argon | $2 / $10 through Nov 30, 2026 | $4 / $20 from Dec 1, 2026 |
| Gemini 3.8 Flash | $0.75 / $3.75 through Dec 31, 2026 | $1.50 / $7.50 from Jan 1, 2027 |
| Gemini 3.5 Flash-Lite | $0.30 / $2.50 | No change published |
| Gemini 3.8 Live | Text $0.75 / $4.50; audio $3.00 / $12.00 | No change published |
A worked example makes the steps concrete. Take the workload from the opening, 10 million input tokens and 2 million output tokens a month.
That workload costs $40 on Argon in November and $80 from December 1. On Gemini 3.8 Flash, by comparison, it costs $15 through December 31 and $30 from January 1, 2027. On Flash-Lite it costs $8.
Two smaller items also land on the bill. Argon’s thinking tokens count as output, and Search grounding costs $14 per 1,000 requests after the 5,000 free monthly requests.
How to Estimate Your Own Gemini Bill
A monthly token total is hard to guess, but a cost per task is easy to measure. Start from one task, price it, then multiply by volume.
- Measure one task. Run ten real examples and record the average input and output tokens.
- Price it on both rates. Multiply by the current price and by the later price for the same model.
- Multiply by monthly volume. Use the busiest month you expect, not the average.
- Add tool charges. Count grounding requests above the 5,000 free monthly requests at $14 per 1,000.
- Add headroom for thinking tokens. On Argon, hard prompts produce billed reasoning tokens you never see in the answer.
Here is the method on a support summary task. Assume 4,000 input tokens and 500 output tokens per ticket, 100,000 tickets a month and no thinking tokens.
On Gemini 3.8 Flash each ticket costs about $0.0049, or roughly $488 a month through December 31. From January 1, 2027, however, the same volume costs about $975.
On Argon each ticket costs $0.013, so the month runs $1,300 in November and $2,600 from December 1. That gap is why the default model choice matters more than any discount.
How to Build With the Gemini API
Building on Gemini starts in Google AI Studio and can move to Vertex AI later, once a workload needs governance. The first working call takes minutes, while the work that matters is testing and controls.
The steps below follow Google’s Gemini API quickstart, checked on November 3, 2026. They especially suit a developer prototyping an internal tool.
- Get an API key in Google AI Studio, tied to a project you control.
- Store it as an environment variable named GEMINI_API_KEY, never in source code.
- Install the SDK with pip install -U google-genai.
- Make a first call to gemini-3.8-flash, as in the snippet below.
- Add tools such as function calling or Search grounding, and watch the grounding charges.
- Evaluate outputs against a fixed test set before anyone relies on them.
- Move to Vertex AI when the workload needs cloud-level access controls, logging and data residency.
from google import genai
client = genai.Client()
interaction = client.interactions.create(
    model="gemini-3.8-flash",
    input="Summarize this contract clause in two sentences.",
)
The client reads GEMINI_API_KEY from the environment, so the snippet carries no secret. Swap the model id for gemini-4-argon when a task needs deeper reasoning, and compare the two on the same inputs.
Checklist
Generative AI Checklist
Work through data readiness, model choice, security and governance questions before you move a Gemini prototype into production.
Developers who already build on OpenAI will also find the shape familiar, and our OpenAI API guide covers that side. For coding agents in the terminal, see Gemini CLI vs Claude Code.
Moving From Prototype to Vertex AI
A prototype in Google AI Studio proves the idea works. Production, though, asks harder questions about who can call the model, where logs go and how spend is controlled.
Vertex AI answers those questions inside a Google Cloud project. Access runs through cloud identity and roles, calls can be logged with the rest of your cloud activity, and billing joins your existing account.
The application logic stays largely the same, so the code change is usually small. Confirm first that the model you tested is offered on Vertex AI in your region. The bigger work is agreeing which team owns the project, the budget and the evaluation results.
A short readiness check helps before the move. Confirm that the evaluation set passes, that the paid tier is in use, and that someone is named to review cost each week.
Prompting Gemini Well
Gemini responds best to prompts that read like a clear brief to a new colleague. Vague prompts get generic answers, while structured prompts get usable ones.
- Set a role: tell the model who it is acting as, such as a contracts analyst.
- Give context: paste the document or data it should use, and say what to ignore.
- Order the steps: list the steps in sequence when the task has more than one.
- Fix the output format: ask for a table, JSON or a word limit.
- Show examples: include one or two good answers so the model can copy the pattern.
These habits also apply across vendors. Our prompt engineering best practices guide goes deeper on each one.
Enterprise Use Cases by Business Function
Enterprises get the most from Gemini when work involves reading, writing or searching large volumes of mixed content. The examples below are organized by the team that owns the work.
Each use case pairs a Gemini strength with a control. The control matters as much as the model, because it decides whether the output can be trusted in production.
Software Engineering
Engineering teams use Gemini to explain unfamiliar code, draft tests, write migration scripts and review pull requests. Argon’s long context also lets it read a large module in one pass.
The guardrail is simple: generated code goes through the same review and tests as human code. Teams comparing coding agents can read our Google Antigravity vs Claude Code breakdown.
Document Intelligence and RAG
Legal, procurement and finance teams sit on contracts, invoices and policies that nobody has time to read twice. Gemini can extract fields and compare clauses, then answer questions with citations to the source page.
The reliable pattern is retrieval: fetch the relevant passages first, then ask the model to answer only from them. Our guides on document intelligence and multimodal RAG explain how to build it.
Data Analytics and Reporting
Analysts use Gemini to turn plain-English questions into SQL, summarize dashboards and draft commentary for monthly reports. It can also read unstructured market reports and pull out themes.
A good test is whether the model shows its query and its source. An answer without a visible query is hard to audit, so require both before numbers reach a leadership deck.
Customer Service Agents
Support teams use Gemini to draft replies, summarize long ticket threads and power agents that answer common questions. Gemini 3.8 Live adds voice, so the same logic can serve a phone line.
The guardrail is a clear handoff to a human for refunds, complaints and anything the agent cannot verify. More patterns are in our guide to AI agents for customer support.
Real-Time Translation for Global Teams
Global companies use Gemini to translate internal updates, supplier emails and support chats. Meetings with mixed languages get faster when notes arrive in each reader’s language.
Translation works well for understanding, especially for internal messages. For contracts, safety notices and regulated text, a qualified human still signs off on the final wording.
Use Cases by Industry
Industry rules change how far you can let a model act on its own. So the table pairs one common use with one guardrail for each sector.
| Industry | Common Gemini use | Guardrail to set first |
|---|---|---|
| Healthcare | Summarizing clinical notes for staff review | No patient data on the free tier; clinician sign-off |
| Banking | Reading loan files and flagging missing documents | Human decision on every credit outcome |
| Retail | Writing product descriptions in many languages | Brand and pricing review before publishing |
| Manufacturing | Searching maintenance manuals by photo or question | Safety steps checked against the official manual |
| Education | Drafting lesson materials and practice questions | Teacher review for accuracy and age fit |
| Legal | Comparing clauses across contract versions | Citations to the source page; lawyer approval |
| Media | Transcribing and summarizing interviews and video | Fact check before anything is published |
For a longer list of ideas across functions, see our roundup of generative AI use cases.
Case Study
55% Less Manual Effort with Generative AI Reporting
A global conglomerate automated analysis of unstructured market reports with NLP, machine learning and sentiment models, cutting manual analysis effort by 55% and raising accurate decision-making by 30%.
Data Privacy, Security and Governance
The first question a security team asks about Gemini is simple: can Google train on our data? The answer depends on which tier you use, so it needs to be settled before anyone sends a real document.
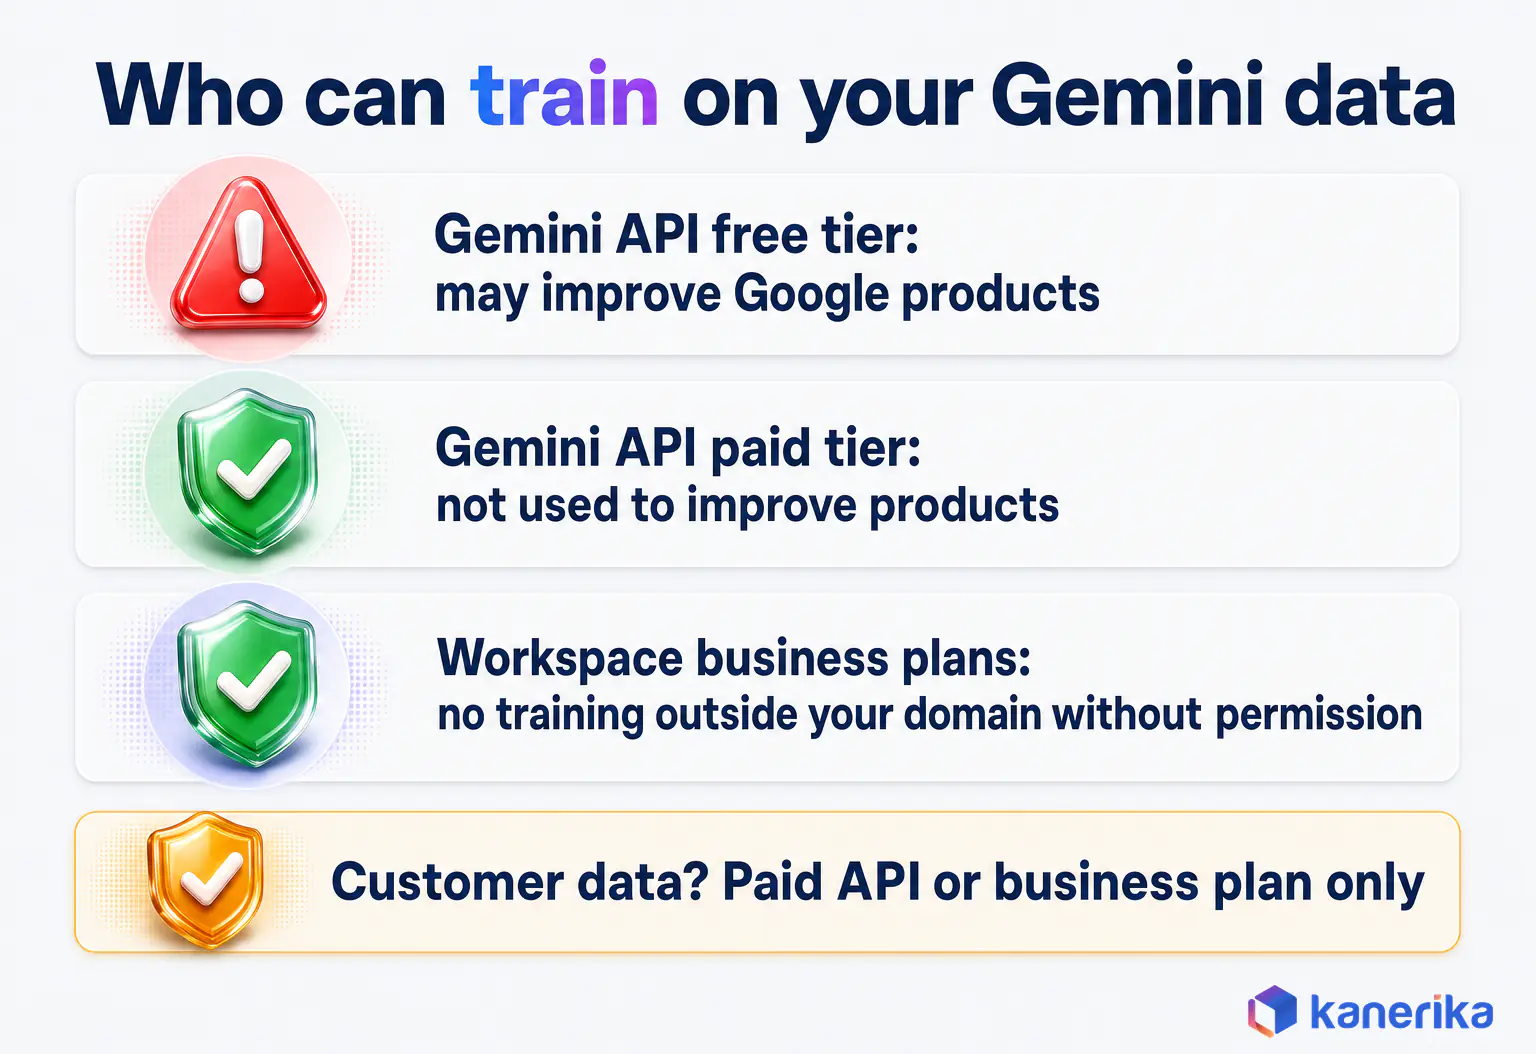
On the Gemini API, the pricing page answers it directly. The free tier is marked as “used to improve our products,” while the paid tier is not.
Business plans also carry their own terms. Google’s Workspace privacy hub states that content is not human reviewed or used for model training outside your domain without permission.
| Tier | Used to improve Google products? | Source |
|---|---|---|
| Gemini API, free tier | Yes | Gemini API pricing page |
| Gemini API, paid tier | No | Gemini API pricing page |
| Workspace and Gemini on business plans | No training outside your domain without permission | Google Workspace privacy hub |
The working rule therefore follows from that table. Send customer data only through the paid API or business plans, and block personal accounts for company work.
Data terms are only one layer of security. Prompt injection, data leakage through outputs and over-broad tool access all need controls as well, which our guide to generative AI security covers. Privacy rules for personal data are in our AI privacy article.
A simple test shows whether those controls exist. Ask a new team member which Gemini tier their app uses, who approved it and where its logs live.
If any answer takes more than a day to find, fix that gap before the pilot grows. The same three questions work for every model vendor you add later.
Mapping Gemini to the NIST AI RMF
Governance ties these controls into a program. The NIST AI Risk Management Framework 1.0, released January 26, 2023, is a common reference.
NIST added the Generative AI Profile, NIST-AI-600-1, on July 26, 2024. Mapping Gemini controls to it gives auditors a familiar structure; see our AI governance framework guide for a template.
Security Controls to Set Before Launch
A short list of controls covers most of the risk in a first Gemini deployment. Each one is cheap to set up early and expensive to add after an incident.
The list assumes the paid API or a business plan is already in place. So the data terms in the table above apply to every call.
- Tier control: block free-tier API keys and personal accounts for company data.
- Access by role: give each app and team only the models and tools it needs.
- Logging: record prompts, outputs and tool calls, with retention set by your own policy.
- Output checks: scan responses for personal data and confidential terms before they leave the system.
- Human review: require sign-off on any action that moves money, changes records or reaches a customer.
- Cost caps: set a budget per project so a runaway agent stops instead of spending.
Most of these controls live outside the model itself. They sit in your identity system, your gateway and your logging stack, so they keep working when you switch models.
Review the list again before each new workload goes live. A control that fits a document summarizer may be too loose for an agent that updates customer records or sends emails on its own.
Write each control down against the NIST Generative AI Profile. An auditor can then trace every risk to a named owner and a named check.
Checklist
AI Governance Checklist
Check access, logging, data terms, human review and audit evidence before Gemini agents touch customer data.
Google Gemini vs ChatGPT vs Claude
Most buyers shortlist Gemini against OpenAI’s GPT models and Anthropic’s Claude. At list price the mid tiers now cost the same, so the decision turns on fit, context and data terms.
The table uses published list prices only, checked on November 2 and 3, 2026. It compares API models, since chatbot seats and API usage are separate purchases.
| Model | Input / output per 1M tokens | Context | Consumer plan |
|---|---|---|---|
| Gemini 4 Argon | $2 / $10 through Nov 30, 2026; $4 / $20 from Dec 1 | 1M shared | Google AI Pro, $19.99/month |
| GPT-6.1 Sol | $2 / $10; prompts over 272K bill 2x input and 1.5x output | 1,050,000 | ChatGPT Plus, $20/month |
| Claude Sonnet 5.5 | $2 / $10 | 1M, 128K output | Not covered here |
| Claude Opus 5.5 | $4 / $20 | 1M, 128K output | Not covered here |
Pick Gemini when your data and staff already live in Google Cloud or Workspace, or when answers need Search and Maps grounding. Still, budget on Argon’s December price of $4 and $20, which equals Claude Opus 5.5’s list price.
Pick GPT-6.1 Sol when your apps already run on OpenAI and most prompts stay under 272K tokens. Past that size, though, input bills at twice the base rate.
Pick Claude Sonnet 5.5 when your stack already runs on Anthropic. Anthropic lists a flat $2 and $10 rate, with no dated price step as of November 2, 2026. The full three-way breakdown is in our ChatGPT vs Gemini vs Claude guide.
Vendor strategy matters too. Our OpenAI vs Anthropic comparison covers the two other labs, and you can also read how Gemini compares with Manus, GenSpark and Gemma.
Limitations and Risks of Google Gemini AI
Every model family has weak spots, and Gemini’s are mostly about accuracy, cost drift and change. So knowing them in advance turns surprises into planned work.
One risk grows as agents start to act on their own: control. The episode below discusses how enterprises keep AI agents in check.
- Hallucination: Gemini can state wrong facts with confidence, so high-stakes answers need retrieval and citations. Our guide to LLM hallucination explains the causes.
- Introductory pricing that doubles: Argon doubles on December 1, 2026 and 3.8 Flash on January 1, 2027, so budgets built on test bills fall short.
- Automatic model routing: from December 1, 2026, calls to gemini-2.5-pro route to gemini-3.8-flash and bill at 3.8 Flash rates. Calls to gemini-2.5-flash route to gemini-3.5-flash-lite the same day. Output quality may shift without a code change.
- No free tier for Argon: teams cannot prototype on the flagship for free, so early tests often run on 3.8 Flash and miss Argon’s behavior.
- Grounding caps: paid Search grounding stops at 1,500 requests a day, which can block a busy agent at peak hours.
- Announced-only models: Gemini 4 Carbon has no price, id or availability date, so it cannot anchor a plan.
A practical defense, therefore, is a routing layer between your apps and the models. An LLM gateway lets you pin model versions, set spend limits and switch providers without rewriting each app.
What Google Has Announced Next
Google announced Gemini 4 Carbon in October 2026. As of November 3, 2026, Google had published no price, model id or availability date for it.
Treat Carbon as a signal that the lineup will keep changing. Design your evaluation set now, so you can test any new model in a day when it arrives.
How to Adopt Gemini in an Enterprise: A Four-Step Plan
Successful Gemini rollouts start small, measure everything and expand only when the numbers hold. The four steps below keep cost and risk visible at each stage.
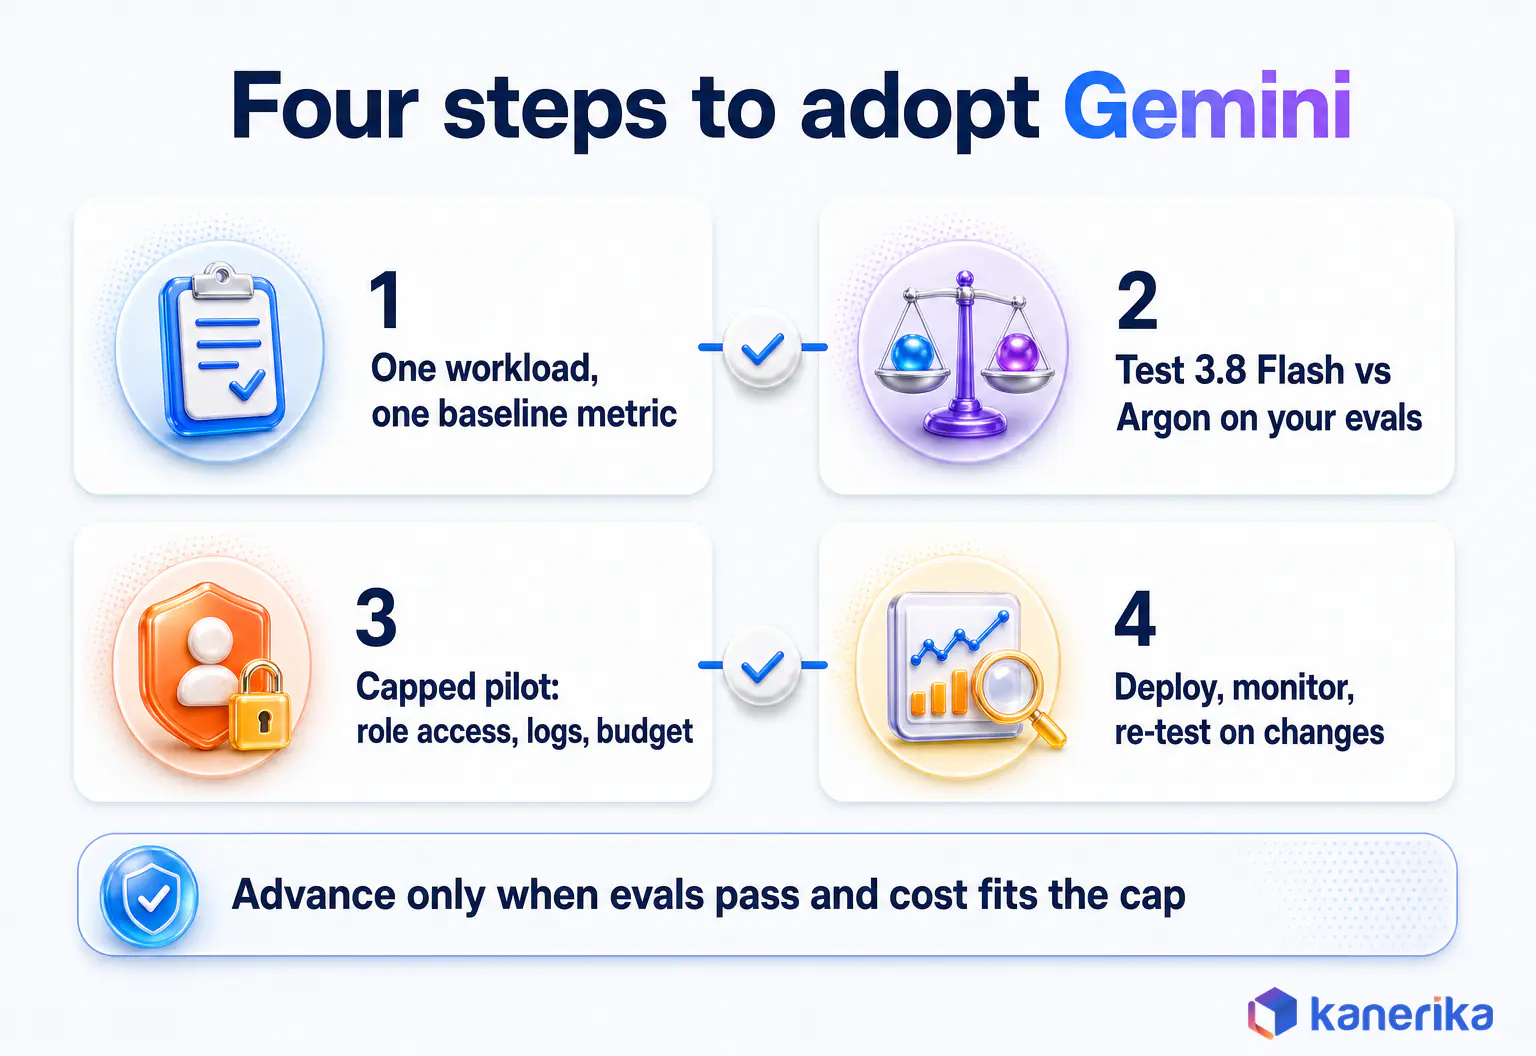
- Pick one workload with a metric. Choose a task with a clear measure, such as minutes per contract review or tickets closed per hour.
- Test 3.8 Flash against Argon on your own evaluation set. Score accuracy, cost per task and latency on real examples.
- Run a controlled proof of concept. Limit access by role, log every call and set a cost cap per project.
- Deploy, monitor and plan for upgrades. Track quality and spend weekly, and re-test whenever Google changes a model or price.
Step one sounds obvious, but it is the step teams skip most often. A pilot without a baseline number cannot prove value, so record how long the task takes today before anyone writes a prompt.
Step two is where most of the learning happens. A shared LLM evaluation framework keeps the scoring consistent across models and releases.
Step three is where cost and access controls get tested for real. Give the pilot a fixed group of users, a fixed budget and a fixed end date, then review the logs together.
Step four never really ends. Model routing and price changes are on the calendar already, so production needs enterprise LLM practices for versioning and rollback.
For the wider program around these steps, our AI implementation roadmap covers sponsorship, skills and phasing. Move to the next step only when the evaluation set passes and the cost per task sits inside the cap.
How Kanerika Deploys Gemini in Production
Kanerika approaches a Gemini project as a data project first and a model project second. A model can only answer as well as the data it reads, so the work starts there.
A typical engagement moves through four stages, each with a checkpoint before the next begins. The stages below describe how the work is organized, while the results depend on each client’s data and goals.
The first stage is data readiness. Kanerika’s FLIP platform handles ingestion, quality checks and pipelines, so the model reads clean and current data.
The second stage is retrieval with citations. KlarityIQ answers questions over a customer’s documents, while Karl turns natural-language questions into database queries.
The third stage is model routing. Gemini 3.8 Flash handles most requests, Argon takes the hard reasoning cases, and cost caps plus evaluation sets keep both honest. Finally, the fourth stage is governance: role-based access, logging and human review, delivered through Kanerika’s AI governance services.
Each stage ends with a review against the client’s own evaluation set and cost cap. A stage that misses either one is fixed before the next begins, which keeps surprises out of production.
Case Study: Generative AI Reporting
The same pattern also shows up in Kanerika’s generative AI reporting work. A global conglomerate spanning electrical, automobile, construction and FMCG businesses automated the analysis of unstructured market reports.
The solution combined NLP, machine learning and sentiment models with the company’s structured data. As a result, it cut manual analysis effort by 55%, raised accurate decision-making by 30% and improved identification of customer needs by 37%.
That case study did not name a model vendor, so it is not presented here as a Gemini project. Instead, it shows the reporting pattern a Gemini build follows. Teams planning one can start with Kanerika’s generative AI services.
So what does this mean for a buyer in 2026? Google Gemini AI is a strong, fairly priced choice for enterprises on Google, provided you budget on the December and January prices.
Talk to Kanerika
Planning a Gemini Rollout?
Kanerika scopes the first workload, the model test and the controls with your team, so a Gemini pilot starts with a metric, a budget and a governance plan.
Frequently Asked Questions
What is Google Gemini AI used for?
Google Gemini AI is used for writing, research, coding, document analysis, translation and customer service. Individuals use the Gemini app for everyday questions and drafts. Businesses use Gemini in Workspace and Gemini Enterprise for office work and agents. Developers call the models through the Gemini API to build apps that read text, images, audio, video and PDFs.
Is Google Gemini better than ChatGPT?
Neither wins every task, so test both on your own work. At list price Gemini 4 Argon and GPT-6.1 Sol both cost $2 input and $10 output per million tokens in November 2026. Argon rises to $4 and $20 on December 1. Gemini suits teams on Google Cloud and Workspace, while ChatGPT suits teams already on OpenAI.
What is Gemini's context window?
Gemini 4 Argon has a 1 million token shared context window, according to Google’s models page in November 2026. It also supports long outputs of up to 1 million tokens. That is enough for a large contract set, a long codebase or hours of transcripts in one prompt. Large prompts still cost money on every call.
How much does Gemini cost for API and enterprise use?
Gemini 4 Argon costs $2 input and $10 output per million tokens through November 30, 2026, then $4 and $20 from December 1. Gemini 3.8 Flash costs $0.75 and $3.75 through December 31, then $1.50 and $7.50. Gemini Enterprise Business starts at $21 per seat a month, and Standard or Plus from $30.
What is the difference between the Gemini app and the Gemini API?
The Gemini app is a chat assistant that people use directly, paid for with a free or monthly plan. The Gemini API lets developers call the same model family from their own software, billed per million tokens. Data terms differ too. The free API tier may improve Google products, while the paid API tier does not.
What is Gemini Enterprise?
Gemini Enterprise is Google’s business product for deploying Gemini assistants and agents across a company. The Business edition starts at $21 per seat a month, and Standard and Plus start at $30. It includes a budget cap per project, so an agent pauses instead of overspending. It suits teams that want governed agents without building everything themselves.
What file types does Gemini support?
Gemini accepts plain text, images, audio files, video files and PDF documents, and one request can combine several types. That covers scanned forms, screenshots, recorded calls, product demos and long reports. For large or sensitive files, use the paid API or a business plan, and retrieve only the relevant pages to keep token costs down.
Can Gemini process images, audio, and video?
Yes. Gemini models accept text, images, audio, video and PDF files, and a single request can mix several of them. A team can send a photo, a voice note and a policy document together and ask for one summary. Gemini 3.8 Live adds real-time audio, so voice agents can listen and reply during a conversation.
How do enterprises deploy Gemini in production?
Enterprises usually start with one workload and a clear metric, then test Gemini 3.8 Flash against Gemini 4 Argon on real examples. A controlled pilot follows, with role-based access, logging and a cost cap per project. Production workloads often move to Vertex AI on Google Cloud, where identity, logging and billing join the rest of the cloud estate.
How to access Google Gemini AI?
There are five main ways to access Google Gemini AI. Individuals use the Gemini app on the web or mobile. Workspace customers use Gemini inside Gmail, Docs and Sheets. Businesses can buy Gemini Enterprise seats. Developers get an API key in Google AI Studio, and platform teams use the same models through Vertex AI on Google Cloud.
Is Gemini AI safe?
Gemini is safe for business use when you pick the right tier and add controls. Google’s free API tier may use prompts to improve its products, and the paid tier does not. Workspace business plans keep content from training outside your domain without permission. Add access controls, logging and human review, because any model can still produce wrong answers.
Is Google Gemini free?
Partly. The Gemini app has a free plan, and the Gemini API has a free tier for models such as Gemini 3.8 Flash. Gemini 4 Argon has no free API tier. Paid personal plans include Google AI Plus at $4.99 a month and Google AI Pro at $19.99 a month, which includes Argon. Business seats start at $21.
Who owns Gemini AI?
Google owns Gemini, and the models are built by Google DeepMind, its AI research lab. Google introduced the assistant as Bard and renamed it Gemini on February 8, 2024. The same Gemini name now covers the model family, the consumer app, the features inside Workspace and the developer API sold through Google AI Studio and Google Cloud.
How can I use Google Gemini?
You can use Google Gemini to draft emails and reports, summarize long documents, translate text and photos, analyze data and write code. Start in the free Gemini app to try it. Move to Google AI Pro for heavier personal use, Gemini Enterprise for teams, or the Gemini API when you want to build Gemini into your own software.
What is the latest Google Gemini model in 2026?
As of November 3, 2026, the newest Gemini model on the API is Gemini 4 Argon, whose model card was published on October 13, 2026. It is the flagship for hard reasoning. Google has also announced Gemini 4 Carbon, but it has no published price, model id or availability date, so there is nothing to plan on yet.